


ENVR 370 - GEOGRAPHIC
INFORMATION SYSTEMS (GIS) -
Spatial data analysis and modeling
Question Bank - Set 3
Liberty University
Question 1
Question
Consider a dataset containing the locations of 100 different species of birds in
a forest. The dataset includes the coordinates (latitude and longitude) of each
bird’s sighting location.
If you were tasked with analyzing the spatial distribution of these bird species
within the forest, outline the steps you would take to perform spatial data
analysis and modeling.
Solution
To analyze the spatial distribution of the bird species within the forest, several
steps must be taken in spatial data analysis and modeling.
Step 1: Data Cleaning and Exploration
Check for any missing or erroneous data points.
Plot the coordinates of bird sightings on a map to visualize the spatial
distribution.
Step 2: Spatial Autocorrelation Analysis
Use statistical tests to detect spatial autocorrelation, which indicates whether
the distribution of bird species is clustered, dispersed, or random.
Step 3: Spatial Interpolation
Use spatial interpolation techniques (e.g., kriging, IDW) to predict the
distribution of bird species across the entire forest based on the observed
data points.
Step 4: Spatial Clustering
Apply clustering algorithms (e.g., K-means, DBSCAN) to identify spatial
clusters of bird species with similar distribution patterns.
Step 5: Spatial Regression Modeling
Develop spatial regression models to investigate the relationship between
environmental variables (e.g., vegetation cover, elevation) and the distri-
bution of bird species.
Step 6: Model Validation
Validate the spatial models using cross-validation techniques to assess
their accuracy and reliability in predicting the distribution of bird species.
By following these steps in spatial data analysis and modeling, researchers
can gain valuable insights into the spatial distribution and environmental rela-
tionships of bird species within the forest.
Question 2
Question
Suppose you are given a dataset consisting of the spatial coordinates (longitude
and latitude) of earthquake epicenters in a certain region. You are interested
in modeling the spatial distribution of earthquake occurrence in the region.
Describe the steps you would take to analyze and model this spatial data.
Solution
To analyze and model the spatial distribution of earthquake occurrence using
the given dataset, the following steps can be taken:
Step 1: Data Preprocessing - Examine the dataset for any missing val-
ues or outliers. - Transform the spatial coordinates into a suitable coordinate
reference system if necessary. - Perform any necessary data cleaning, such as
removing duplicates or irrelevant attributes.
Step 2: Exploratory Data Analysis (EDA) - Visualize the spatial
distribution of earthquake epicenters using techniques such as scatter plots or
heatmaps. - Calculate summary statistics to understand the central tendency
and variability of the data. - Conduct spatial autocorrelation analysis to identify
any spatial patterns in the data.
Step 3: Spatial Interpolation - Choose an appropriate spatial interpo-
lation method to estimate earthquake occurrence at unmeasured locations. -
Common methods include kriging, inverse distance weighting, and spline in-
terpolation. - Evaluate the accuracy of the interpolation method using cross-
validation techniques.
2
Step 4: Spatial Clustering - Apply spatial clustering algorithms such
as K-means or DBSCAN to identify spatial clusters or hotspots of earthquake
occurrence. - Evaluate the results of the clustering analysis using clustering
validity indices.
Step 5: Spatial Modeling - Utilize spatial regression techniques such as
geographically weighted regression (GWR) or spatial autoregressive models to
model the relationship between earthquake occurrence and spatial covariates.
- Incorporate environmental or geological factors as covariates in the spatial
model. - Validate the spatial model using goodness-of-fit measures and spatial
diagnostics.
Step 6: Model Interpretation and Validation - Interpret the results
of the spatial model in the context of earthquake occurrence in the region.
- Validate the model’s predictive performance using techniques such as cross-
validation or holdout samples. - Communicate the findings of the spatial analysis
and modeling in a clear and concise manner.
By following these steps, you can effectively analyze and model the spatial
distribution of earthquake occurrence using the given dataset.
Question 3
Question
Let f(x, y)=3x2+y2−4x−2yrepresent a surface in three-dimensional space.
Determine the critical points of f.
Solution
Step 1: Calculate the partial derivatives of f(x, y) with respect to xand y.
∂f
∂x = 6x−4 and ∂f
∂y = 2y−2
Step 2: Set the partial derivatives equal to zero to find critical points.
(6x−4=0
2y−2=0
Step 3: Solve the system of equations to find the critical points.
(6x= 4
2y= 2 ⇒(x=2
3
y= 1
Thus, the critical point of fis (2
3,1).
3

Question 4
Question
Consider a dataset containing information about the location of trees in a park.
You are interested in analyzing the spatial distribution of tree species across the
park. Discuss how you would approach this spatial data analysis and modeling
task.
Solution
To analyze the spatial distribution of tree species in the park, we can follow
these steps:
Step 1: Data Collection and Preparation - Collect data on the location
of trees in the park, including the species of each tree. - Pre-process the data
to ensure that it is clean and formatted correctly for spatial analysis.
Step 2: Exploratory Data Analysis (EDA) - Conduct a preliminary
analysis of the data to understand the distribution of tree species across the
park. - Use visualizations such as scatter plots or spatial maps to identify any
patterns or clusters.
Step 3: Spatial Autocorrelation Analysis - Perform spatial autocor-
relation analysis to determine if tree species tend to cluster together or are
randomly distributed across the park. - Calculate measures such as Moran’s I
to quantify spatial autocorrelation.
Step 4: Spatial Interpolation - Use spatial interpolation techniques to
estimate the distribution of tree species in areas where data is missing or sparse.
- Popular interpolation methods include Inverse Distance Weighting (IDW) or
Kriging.
Step 5: Spatial Clustering Analysis - Apply spatial clustering tech-
niques such as K-means clustering or DBSCAN to identify groups of trees with
similar characteristics. - Analyze the resulting clusters to understand the spatial
patterns of tree species distribution.
Step 6: Spatial Modeling - Develop spatial models to predict the distri-
bution of tree species based on environmental variables or other relevant factors.
- Evaluate the accuracy of the models using techniques such as cross-validation.
By following these steps, we can gain valuable insights into the spatial distri-
bution of tree species in the park and develop models to support decision-making
and management strategies.
Question 5
Question
Consider a dataset containing information on the locations of 100 different
species of plants in a forest. You are interested in analyzing the spatial patterns
4

of these plant species to determine if there are any clusters or spatial dependen-
cies present. Explain how you would approach this spatial data analysis and
modeling problem.
Solution
To analyze the spatial patterns of plant species in the forest dataset, we can
follow these steps in spatial data analysis and modeling:
Step 1: Data Exploration - Begin by visualizing the spatial distribution
of the 100 plant species in the forest using scatter plots or maps. - Look for
any visible patterns, clusters, or spatial dependencies that may be present in
the data.
Step 2: Spatial Autocorrelation Analysis - Conduct spatial autocor-
relation analysis to determine if there is a significant spatial pattern in the
distribution of plant species. - Calculate Moran’s I statistic to quantify spatial
autocorrelation, where values close to 1 indicate positive spatial autocorrela-
tion (clustering) and values close to -1 indicate negative spatial autocorrelation
(dispersion). - Perform a significance test to determine if the spatial pattern is
statistically significant.
Step 3: Spatial Clustering Analysis - Apply spatial clustering tech-
niques such as Moran’s I clustering or Getis-Ord Gi* to identify clusters of
plant species in the forest. - Determine the locations of significant clusters and
analyze their characteristics.
Step 4: Spatial Interpolation - Use spatial interpolation methods such
as kriging or inverse distance weighting to estimate the distribution of plant
species between sampled points. - Generate interpolated surfaces to visualize
the spatial variation of plant species across the forest.
Step 5: Spatial Regression Modeling - Perform spatial regression anal-
ysis to investigate the relationship between environmental variables (e.g., soil
type, sunlight exposure) and the distribution of plant species. - Build regression
models that account for spatial dependencies using techniques like spatial lag
models or spatial error models.
By following these steps in spatial data analysis and modeling, we can gain
insights into the spatial patterns of plant species in the forest dataset and un-
derstand the underlying processes driving their distribution.
Question 6
Question
A researcher is interested in analyzing the spatial distribution of a certain species
of plants across a forest. The researcher collects data on the number of plants
observed at various locations within the forest. Given the dataset, the researcher
wants to create a spatial interpolation model to estimate the plant density at
5

unsampled locations. Explain the steps the researcher should follow to perform
spatial data analysis and modeling for this scenario.
Solution
To perform spatial data analysis and modeling for this scenario, the researcher
should follow the steps outlined below:
Step 1: Data Collection - Collect data on the number of plants observed
at various locations within the forest. - Ensure that the data is georeferenced
with spatial coordinates for each observation point.
Step 2: Data Exploration - Conduct exploratory data analysis to under-
stand the distribution and patterns of plant density within the forest. - Use
tools such as scatter plots, histograms, and spatial autocorrelation analysis to
identify any trends or spatial dependencies in the data.
Step 3: Spatial Interpolation - Choose an appropriate spatial inter-
polation method to estimate plant density at unsampled locations. Common
methods include kriging, inverse distance weighting, and spline interpolation.
- Perform the spatial interpolation using the selected method to generate a
continuous surface representing plant density across the entire forest.
Step 4: Model Validation - Validate the accuracy of the spatial interpo-
lation model by comparing the predicted plant densities to the observed values
at sampled locations. - Use statistical measures such as root mean square error
(RMSE) or cross-validation techniques to assess the model performance.
Step 5: Model Refinement - Refine the spatial interpolation model by
adjusting parameters or exploring alternative interpolation methods to improve
the accuracy of plant density estimates. - Iteratively validate and refine the
model until satisfactory results are achieved.
Step 6: Interpretation and Visualization - Interpret the results of the
spatial data analysis and modeling to gain insights into the spatial distribution
of the plant species within the forest. - Visualize the interpolated plant density
surface using maps or contour plots to communicate the findings effectively.
By following these steps, the researcher can effectively analyze the spatial
distribution of the plant species and create a reliable spatial interpolation model
for estimating plant density across the forest.
Question 7
Question
Suppose you are given a dataset consisting of locations (x, y) and corresponding
measurements (z) for a particular variable. You would like to fit a spatial model
to this data in order to make predictions at unsampled locations. Explain the
process of fitting a spatial model and demonstrate this by fitting a simple spatial
model (e.g. Kriging) to the provided dataset.
6
Solution
To fit a spatial model to a dataset, we typically follow these steps: Step 1:
Visualize the data to understand its spatial distribution and detect any patterns
or trends. Step 2: Choose a spatial model (e.g., variogram model) that captures
the spatial dependence structure in the data. Step 3: Fit the chosen model to the
data using a fitting method (e.g., method of moments, maximum likelihood).
Step 4: Validate the fitted model to assess its performance in capturing the
spatial variation. Step 5: Make predictions at unsampled locations using the
fitted model.
Let’s demonstrate this process by fitting a simple spatial model (Kriging) to
the provided dataset.
Question 8
Question
Suppose you are given a dataset consisting of the spatial coordinates of various
earthquake occurrences in a region. You are asked to perform a spatial data
analysis and modeling to identify any underlying patterns or trends in the data.
Explain the steps you would take to carry out this analysis.
Solution
To perform a spatial data analysis and modeling on the earthquake dataset, you
can follow these steps:
Step 1: Data Exploration
Begin by exploring the dataset to understand its structure and contents.
Look for any missing values, outliers, or inconsistencies in the spatial
coordinates.
Generate descriptive statistics to summarize the data distribution.
Step 2: Visualization
Create visual representations of the spatial data using maps, scatter plots,
or kernel density estimation plots.
Identify any clusters or patterns in the earthquake occurrences.
Step 3: Spatial Autocorrelation Analysis
Conduct a spatial autocorrelation analysis to examine the degree of spatial
dependence among the earthquake events.
Check if there is any clustering, randomness, or dispersion in the data.
Step 4: Spatial Interpolation
7
Use spatial interpolation techniques such as kriging or inverse distance
weighting to estimate earthquake occurrences at unsampled locations.
Evaluate the accuracy of the interpolation method used.
Step 5: Spatial Regression Modeling
Perform spatial regression analysis to model the relationship between
earthquake events and potential explanatory variables (e.g., geological fea-
tures, fault lines).
Assess the significance and strength of the spatial relationships in the
model.
Step 6: Model Validation
Validate the spatial regression model using goodness-of-fit measures and
diagnostic tests.
Assess the reliability of the model for predicting future earthquake occur-
rences.
By following these steps, you can conduct a comprehensive spatial data
analysis and modeling of the earthquake dataset to uncover underlying patterns
and relationships in the data.
Question 9
Question
Let X1and X2be two random variables representing the longitude and latitude
coordinates of a point on Earth. Suppose X1follows a normal distribution with
mean 0 and variance 4, and X2follows a normal distribution with mean 0 and
variance 9. Calculate the probability that the point lies within a circular region
of radius 5 units centered at the origin.
Solution
Step 1: Find the joint probability distribution of X1and X2. Since X1and X2
are independent, the joint probability density function is the product of their
individual probability density functions:
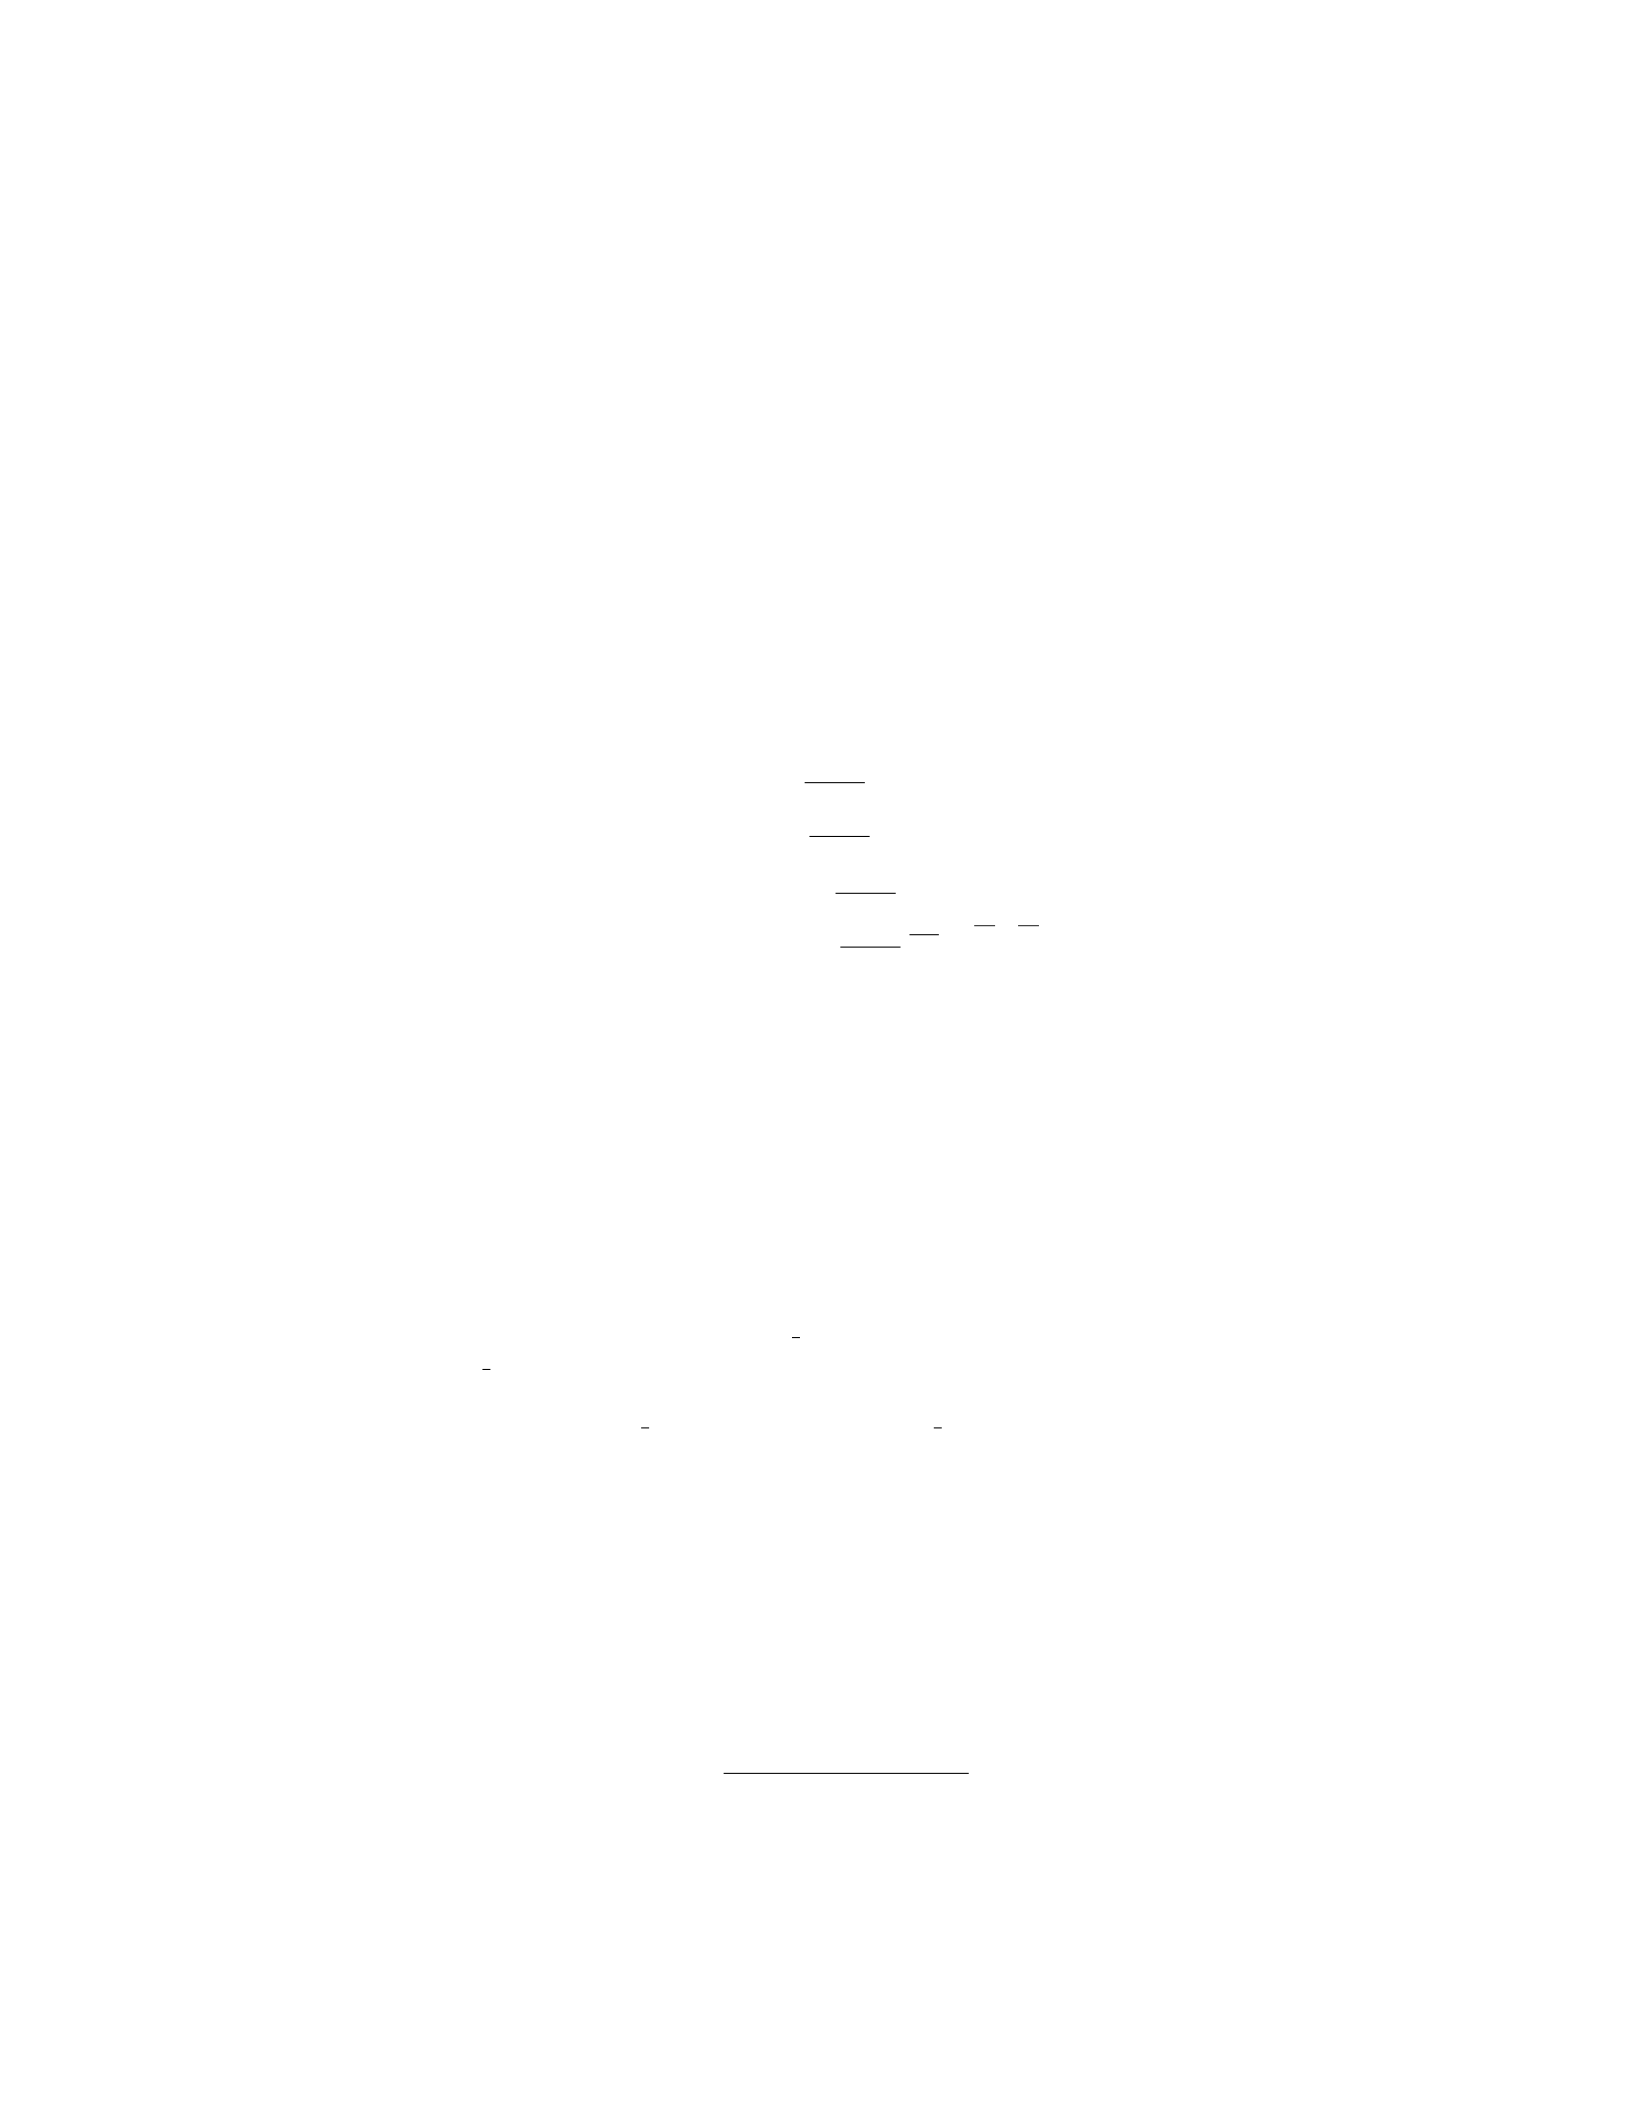
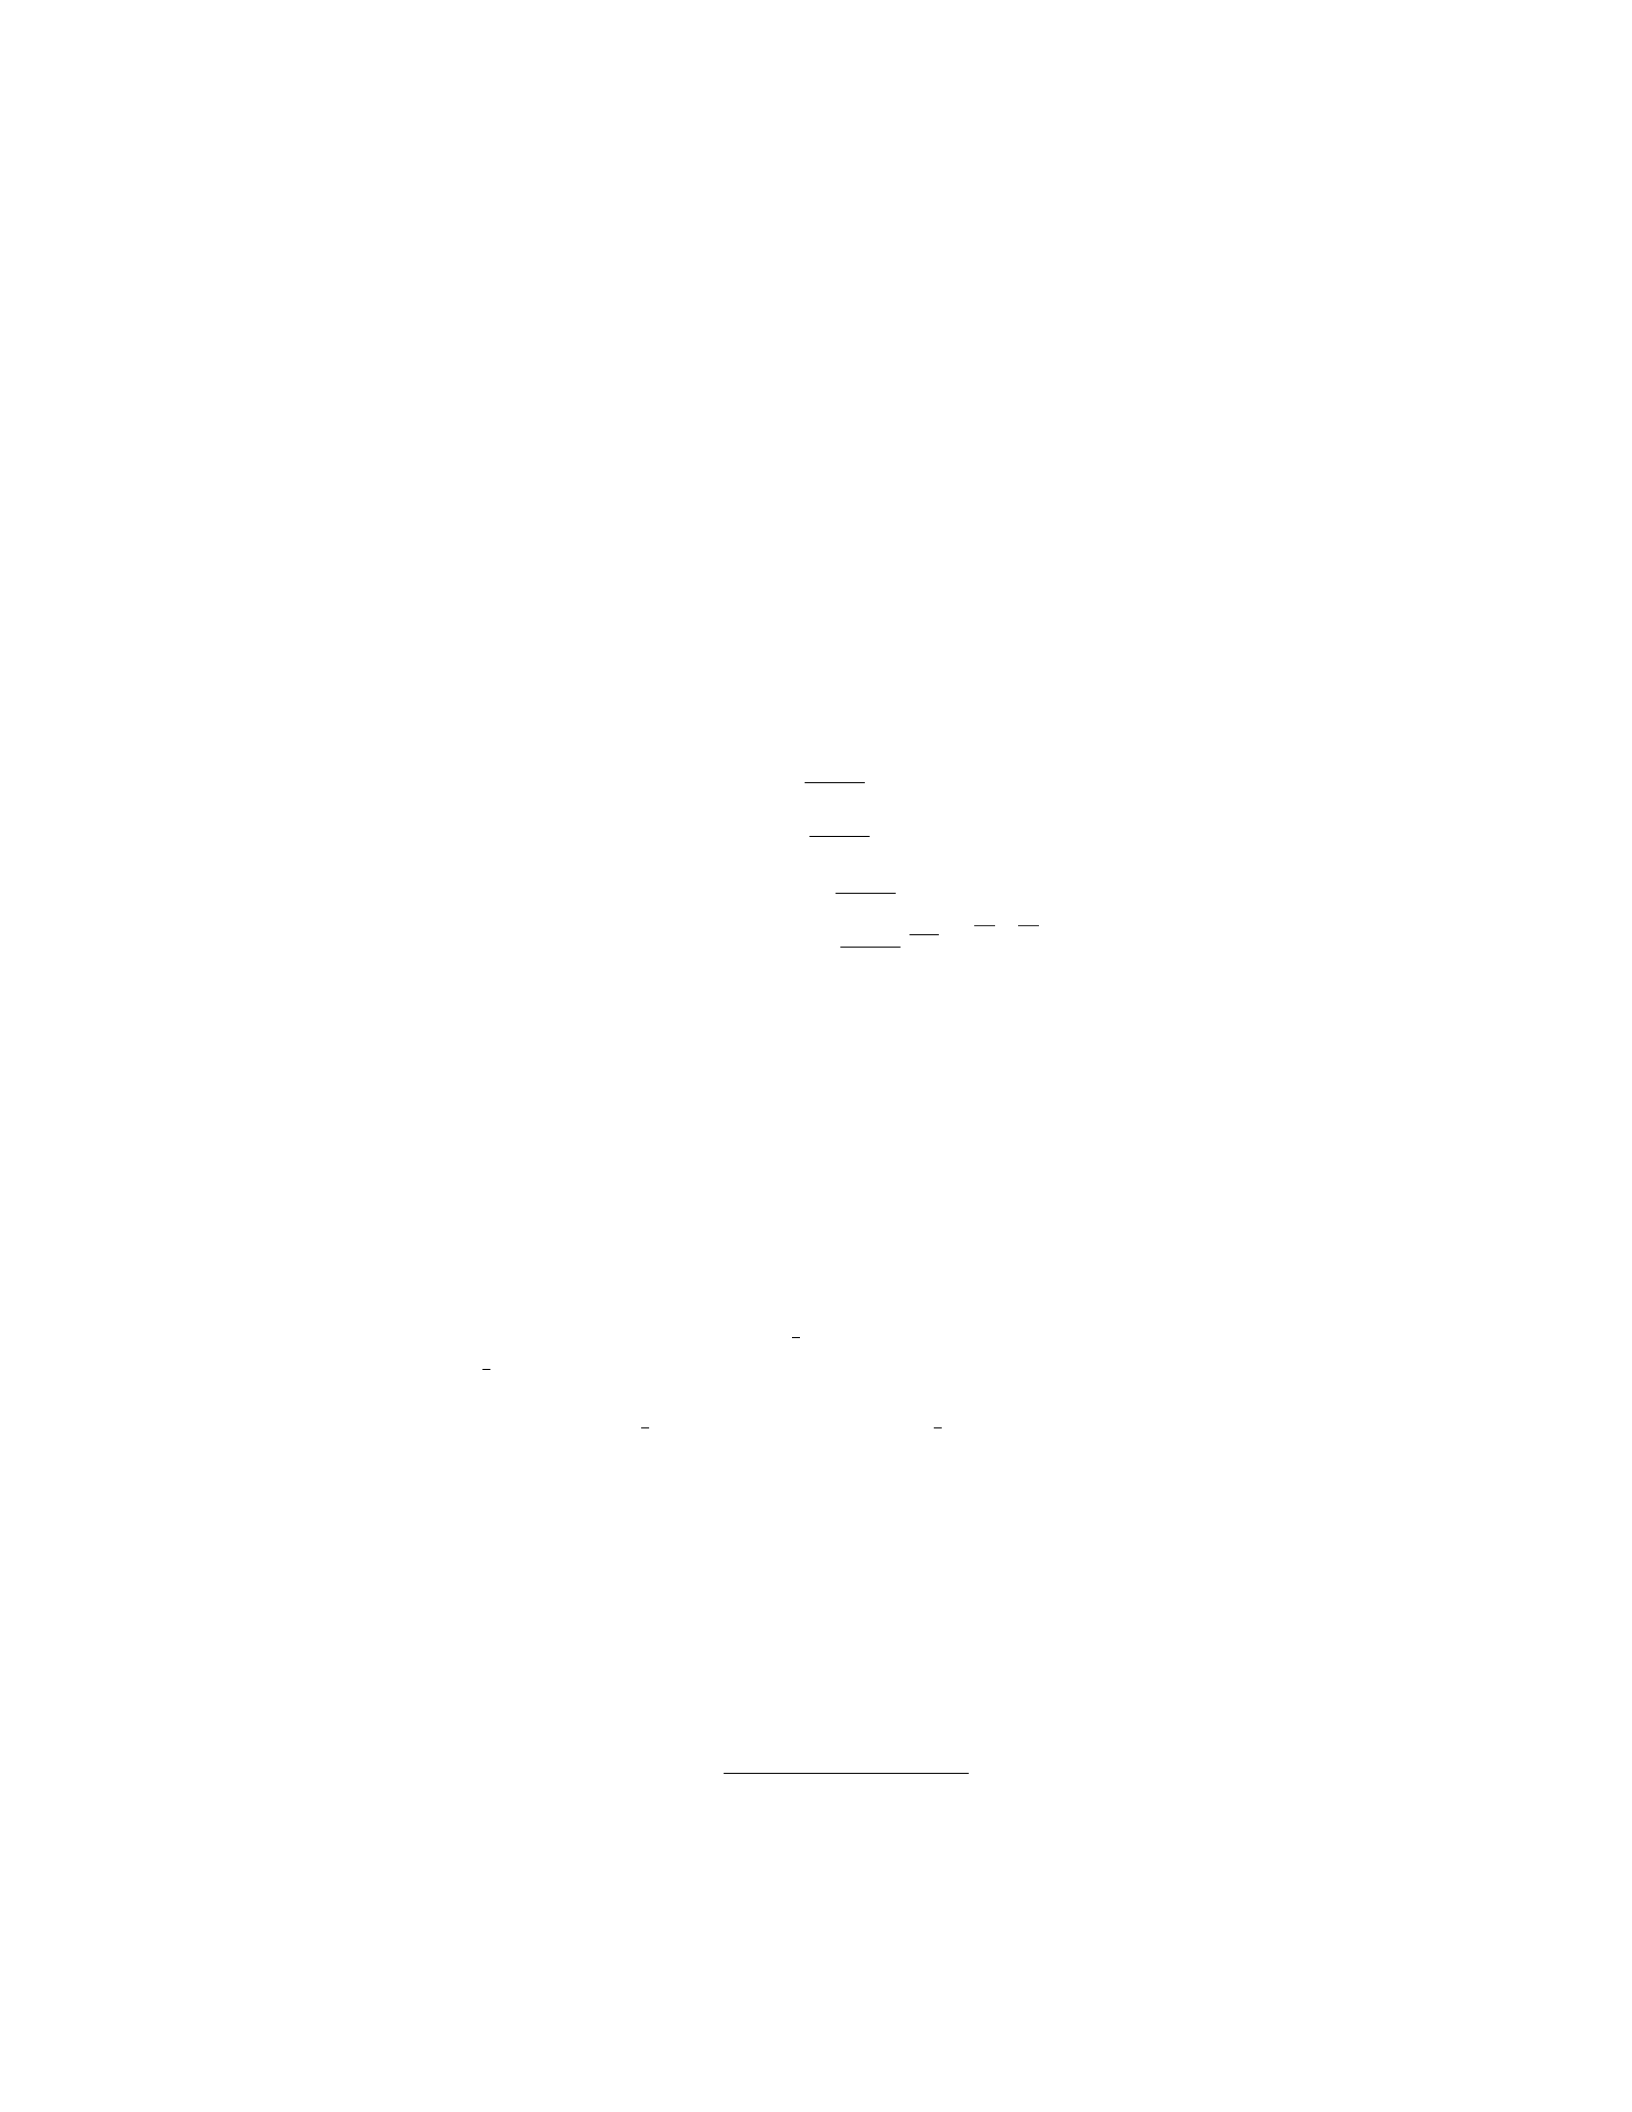
fX1,X2(x1, x2) = fX1(x1)·fX2(x2)
Given:
fX1(x1) = 1
2√2πe−
x2
1
8for − ∞ < x1<∞
fX2(x2) = 1
3√2πe−
x2
2
18 for − ∞ < x2<∞
8
Step 2: Calculate the probability that the point lies within the circular region
of radius 5 units. The probability that the point lies within the circular region
can be expressed as:
P(X2
1+X2
2<25)
This probability can be calculated by integrating the joint probability density
function over the region inside the circle:
P(X2
1+X2
2<25) = ZZx2
1+x2
2<25
fX1,X2(x1, x2)dx1dx2
Step 3: Substitute the joint PDF and solve the double integral. Substitute
fX1,X2(x1, x2) = fX1(x1)·fX2(x2) into the double integral and solve the integral
over the circular region:
P(X2
1+X2
2<25) = Z5
−5Z√25−x2
1
−√25−x2
1
fX1(x1)·fX2(x2)dx2dx1
P(X2
1+X2
2<25) = Z5
−5Z√25−x2
1
−√25−x2
1
1
6πe−
x2
1
8
−
x2
2
18 dx2dx1
Step 4: Evaluate the integral to find the probability. Perform the integration
and evaluate the probability that the point lies within the circular region of
radius 5 units centered at the origin.
Question 10
Question
Consider a dataset containing the coordinates (x, y) of 20 different urban loca-
tions. You are tasked with fitting a spatial model to analyze the relationship
between the population density (pop density) and the distance to the nearest
park (park dist). The model under consideration is given by:
pop density =β0+β1·park dist +ϵ
where ϵ∼N(0, σ2) represents the error term.
Given the dataset and the model, perform the necessary steps to estimate
the coefficients β0and β1using the method of least squares.
Solution
Step 1: Write the least squares estimation equations for β0and β1. The least
squares estimation equations for β0and β1are:
β1=Pn
i=1(xi−¯x)(yi−¯y)
Pn
i=1(xi−¯x)2
9
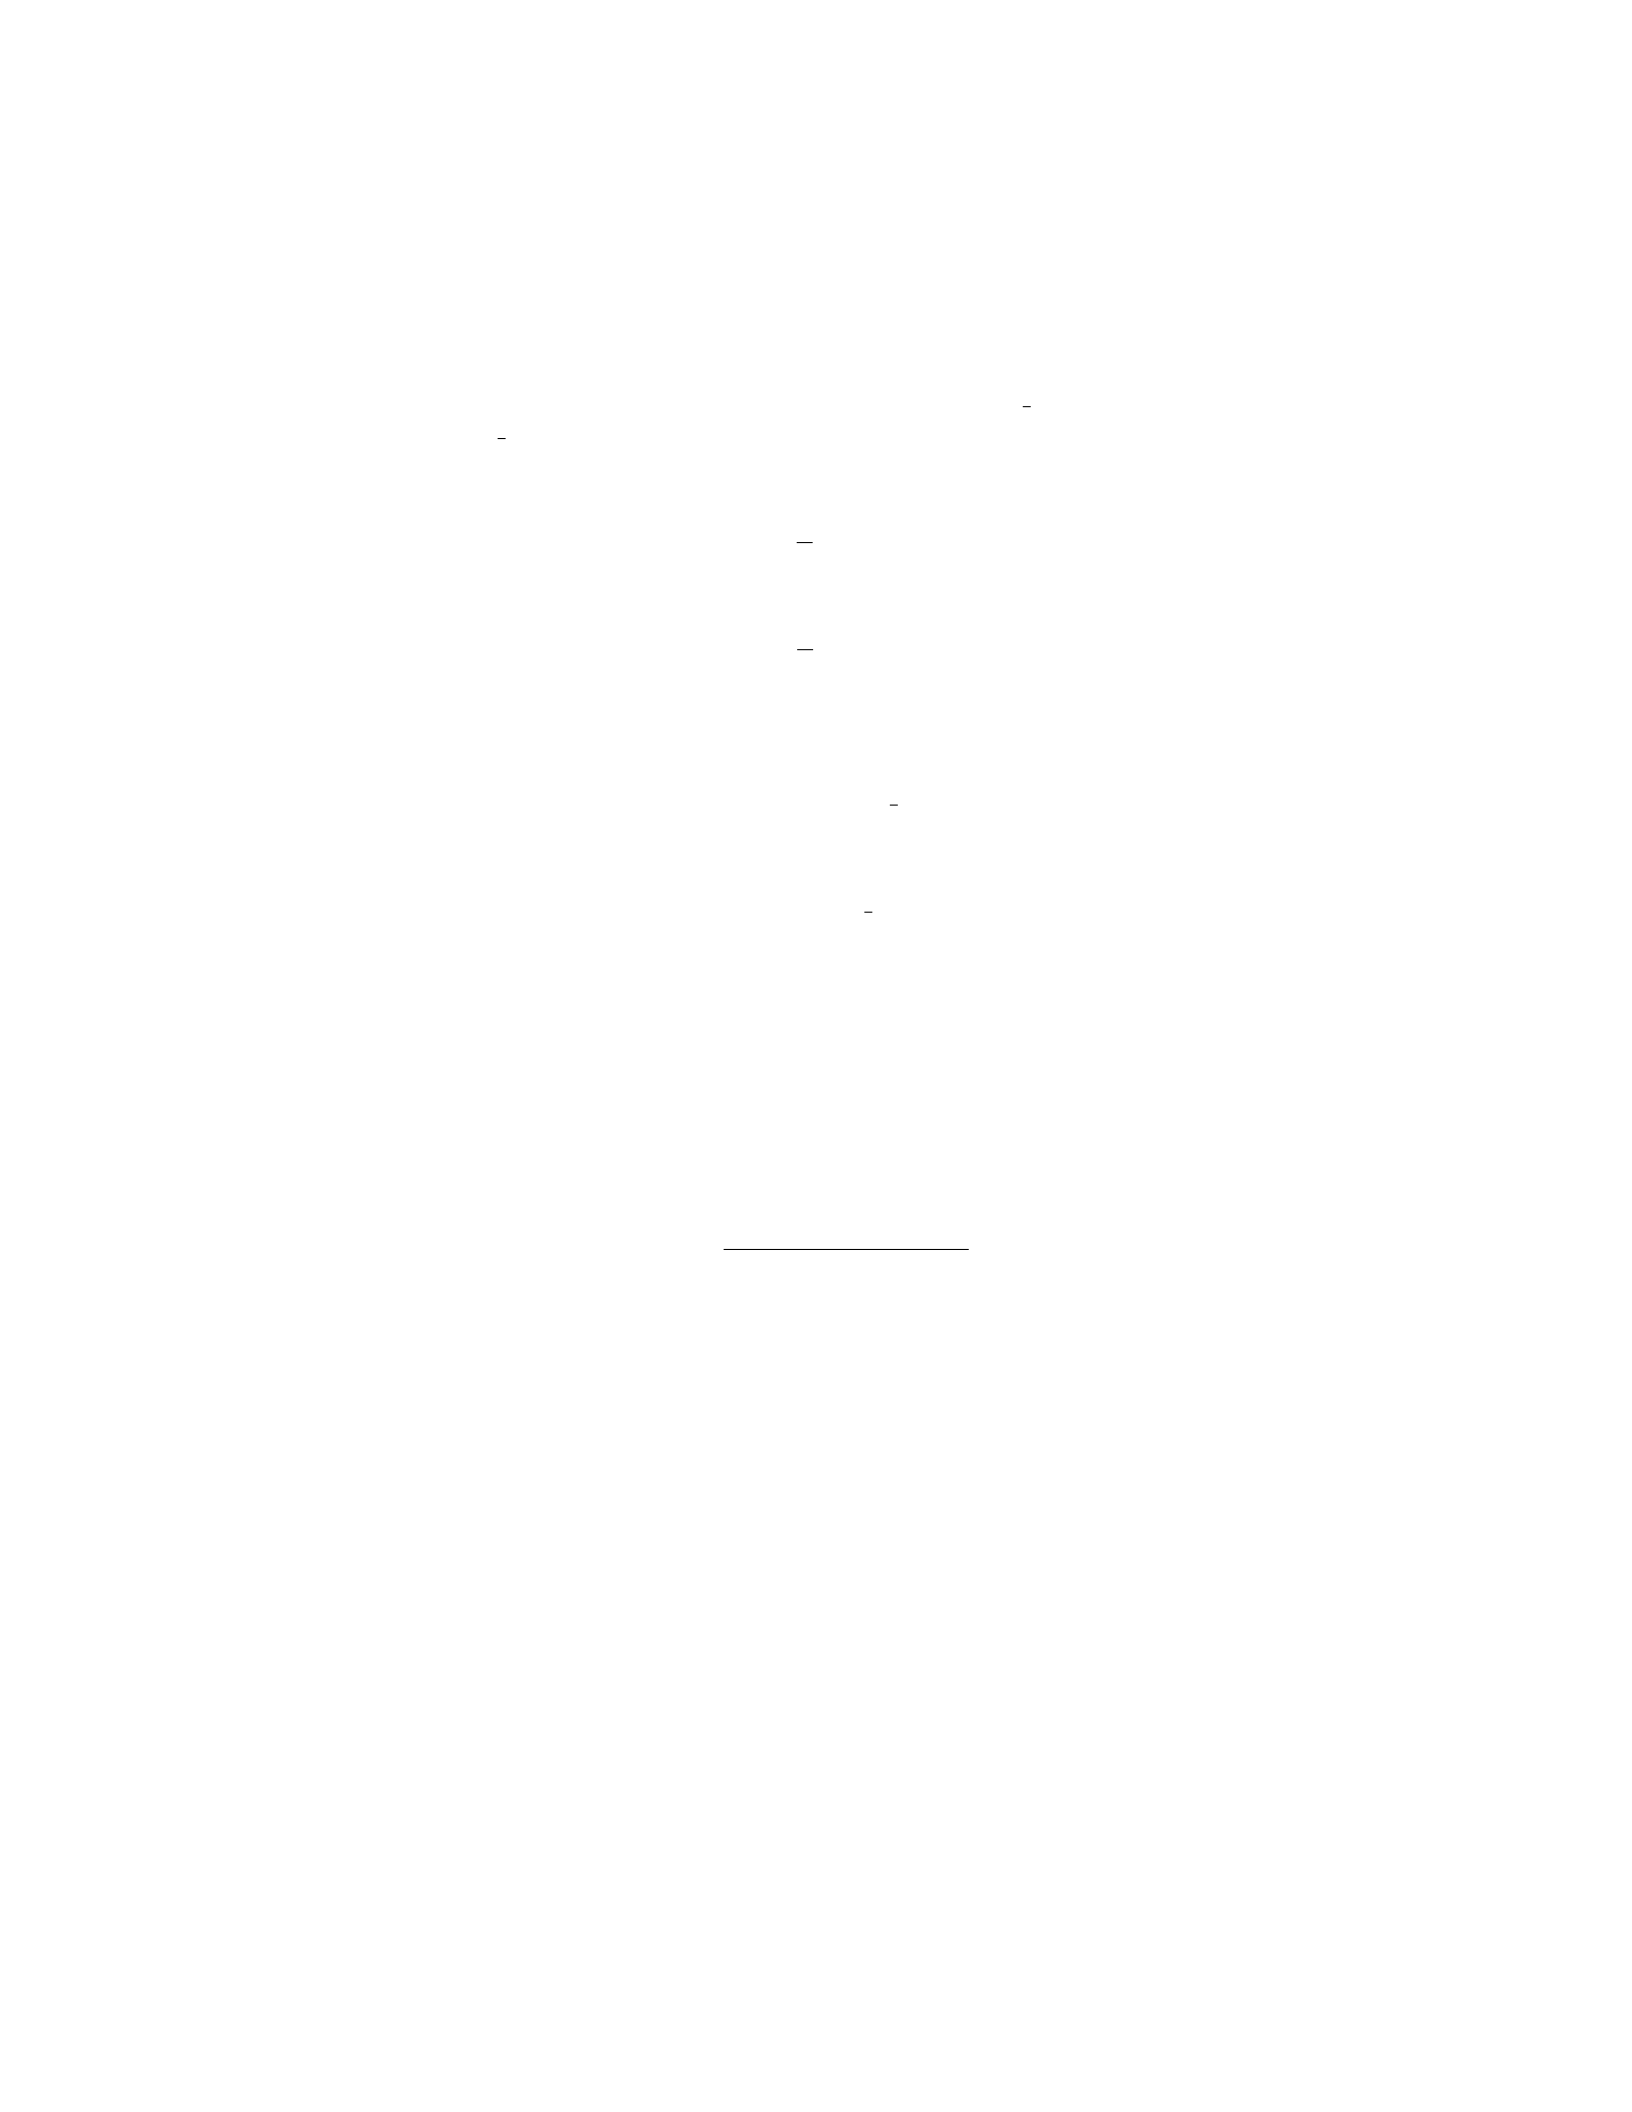
β0= ¯y−β1·¯x
where ¯xand ¯yare the means of the predictor variable park dist and the response
variable pop density respectively.
Step 2: Calculate the means ¯xand ¯y.
¯x=1
n
n
X
i=1
xi
¯y=1
n
n
X
i=1
yi
Step 3: Calculate the necessary sums.
n
X
i=1
xi= sum of all park dist values
n
X
i=1
yi= sum of all pop density values
n
X
i=1
(xi−¯x)(yi−¯y) = sum of(xi−¯x)·(yi−¯y)
n
X
i=1
(xi−¯x)2= sum of(xi−¯x)2
Step 4: Substitute the calculated values into the equations to find β0and
β1.
β1=Pn
i=1(xi−¯x)(yi−¯y)
Pn
i=1(xi−¯x)2
β0= ¯y−β1·¯x
Step 5: Interpret the estimated coefficients β0and β1in the context of the
problem.
Question 11
Question
Consider a dataset containing spatial data on the distribution of a rare plant
species across a region. The dataset includes the coordinates of each observed
plant specimen.
Given this dataset, explain how you would conduct spatial data analysis
and modeling to identify areas with high species richness and potential habitat
areas for the rare plant species. Make sure to describe the steps involved in the
process.
10

Solution
To conduct spatial data analysis and modeling to identify areas with high species
richness and potential habitat areas for the rare plant species, you can follow
the steps outlined below:
Step 1: Data Preprocessing - Import the spatial dataset containing the
coordinates of the observed plant specimens. - Convert the dataset into a spatial
points dataset.
Step 2: Exploratory Data Analysis - Conduct exploratory data anal-
ysis to understand the spatial distribution of the plant specimens. - Create
basic visualizations such as scatter plots or density plots to visualize the spatial
patterns.
Step 3: Spatial Autocorrelation Analysis - Perform spatial autocorre-
lation analysis to determine if there is a spatial pattern in the distribution of
the plant species. - Use tools like Moran’s I or Geary’s C to quantify spatial
autocorrelation.
Step 4: Species Richness Analysis - Use methods like kernel density
estimation or hotspot analysis to identify areas with high species richness. -
Calculate species richness indices for different spatial units (e.g., grid cells) to
identify hotspots.
Step 5: Habitat Suitability Modeling - Utilize habitat suitability mod-
eling techniques such as MaxEnt, GAM, or ENFA to predict potential habitat
areas for the rare plant species. - Use environmental variables (e.g., tempera-
ture, soil type) as predictors in the modeling process.
Step 6: Model Validation - Validate the habitat suitability model using
techniques like cross-validation or independent validation. - Assess the accuracy
of the model in predicting known occurrences of the rare plant species.
Step 7: Spatial Prediction - Generate spatial predictions of potential
habitat areas based on the habitat suitability model. - Map the predicted habi-
tat areas to visualize the potential distribution of the rare plant species across
the region.
By following these steps, you can effectively conduct spatial data analysis
and modeling to identify areas with high species richness and potential habitat
areas for the rare plant species.
Question 12
Question
Suppose you are given a dataset with spatial coordinates for various cities in a
country. You are interested in analyzing the spatial distribution of population
density across these cities. Develop a spatial model to predict the population
density at a new location based on the population densities of neighboring cities.
11
Solution
To develop a spatial model for predicting population density at a new location
based on neighboring cities, we can use spatial interpolation techniques. One
common technique is Inverse Distance Weighting (IDW) interpolation.
Step 1: Define the Problem We want to predict the population density
at a new location using the population densities of neighboring cities. This
involves estimating the population density at the new location based on the
known values at surrounding locations.
Step 2: Select Neighboring Cities Identify the neighboring cities sur-
rounding the new location for which population density values are known. These
neighboring cities will be used to estimate the population density at the new
location.
Step 3: Calculate Weights Calculate the weights for each neighboring
city based on their distances from the new location. Closer cities should have
more influence on the prediction than farther cities. One common method is to
use inverse distance weighting, where the weight for each city is determined by
the inverse of the distance to that city.
Step 4: Perform Interpolation Use the calculated weights and popula-
tion densities of neighboring cities to predict the population density at the new
location. The predicted value can be calculated as a weighted average of the
neighboring city population densities, where the weights are based on distance.
Step 5: Validate the Model Validate the spatial model by comparing
the predicted population density at known locations with the actual values.
Use statistical measures such as Root Mean Square Error (RMSE) to assess the
accuracy of the model.
Step 6: Apply the Model Once the model is validated, apply it to predict
population density at new locations where the actual values are unavailable.
Monitor the model performance and make adjustments as needed based on the
prediction accuracy.
Question 13
Question
Let X1, X2, . . . , Xnbe a random sample from a bivariate normal distribution
with means µ1= 2, µ2= 3, variances σ2
1= 4, σ2
2= 9, and correlation coefficient
ρ= 0.5. Compute the 95
Solution
Step 1: Compute the sample correlation coefficient rusing the formula
r=Pn
i=1(X1i−¯
X1)(X2i−¯
X2)
qPn
i=1(X1i−¯
X1)2Pn
i=1(X2i−¯
X2)2
12
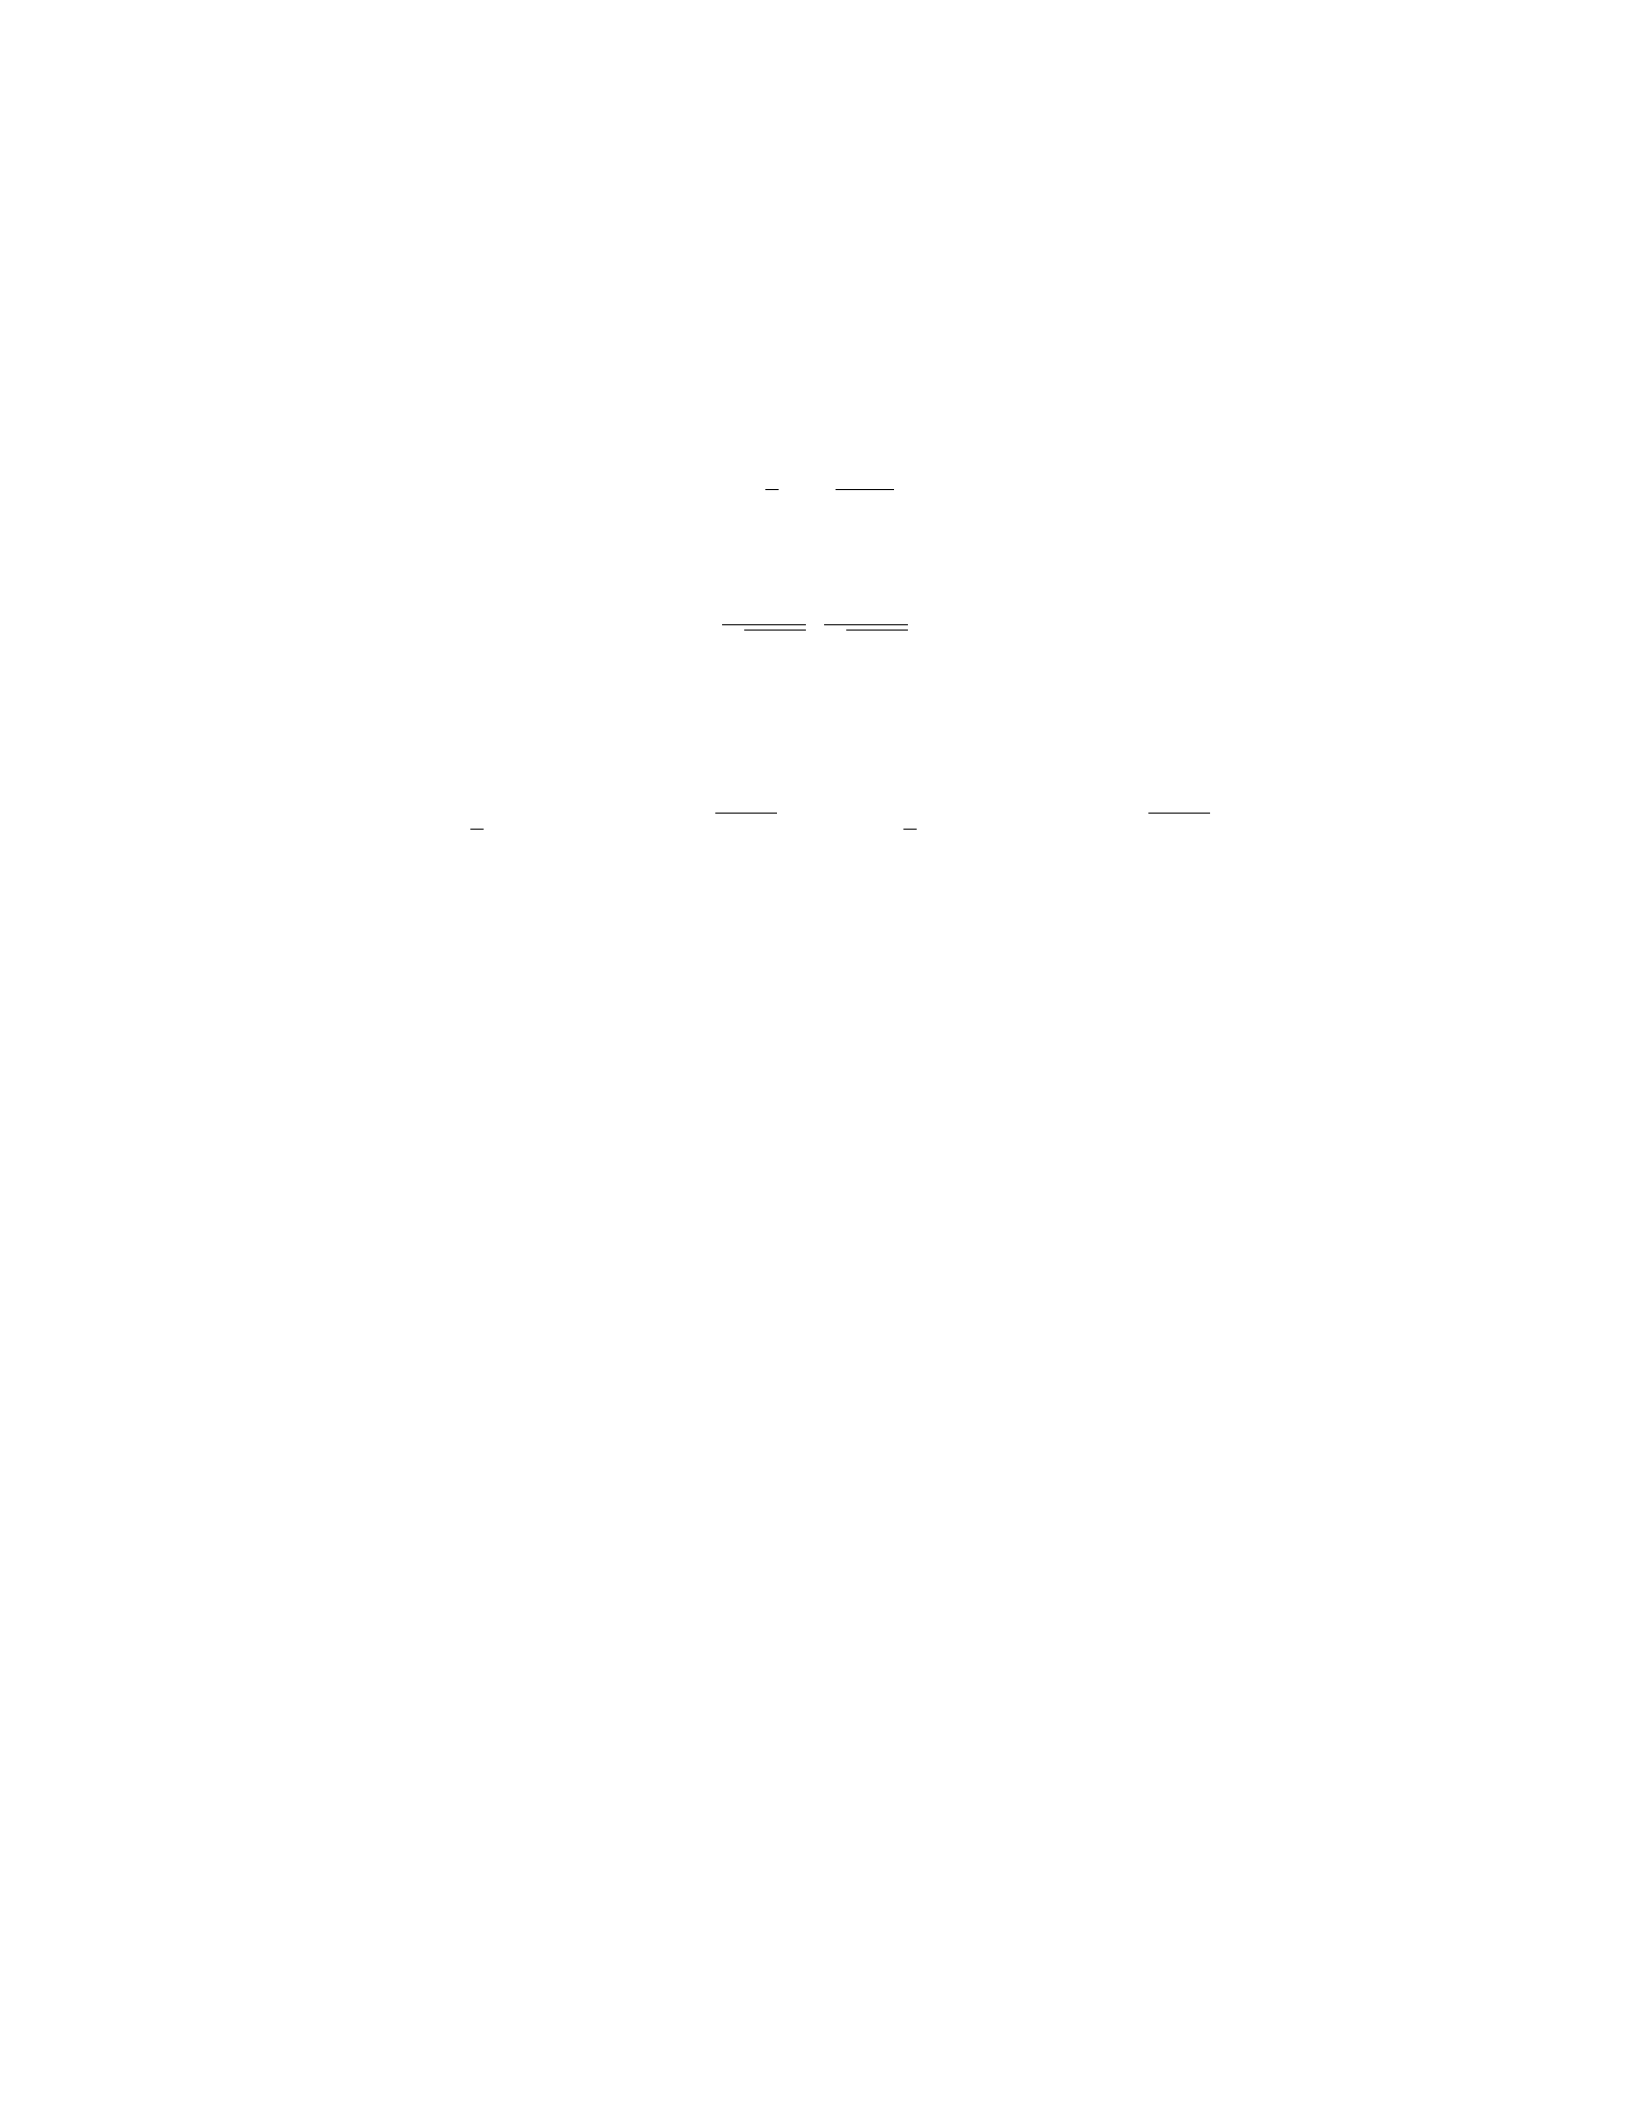
where ¯
X1and ¯
X2are the sample means.
Step 2: The sampling distribution of the sample correlation coefficient r
can be approximated by a normal distribution, which can be transformed using
Fisher’s z-transformation:
z=1
2ln 1 + r
1−r
Step 3: Compute the 95
z
√n−3,z
√n−3
Step 4: Transform the confidence interval for zback to the original scale
to obtain the confidence interval for the correlation coefficient rby using the
inverse z-transformation:
tanh 1
2(ln(1 + r)−zα/2/√n−3),tanh 1
2(ln(1 + r) + zα/2/√n−3)
Step 5: Substitute the sample correlation coefficient r, the sample size n,
and the value of zα/2for a 95
Question 14
Question
Let Z(s) = X(s) + Y(s) be a spatial process defined on a rectangular region
D⊂R2, where X(s) and Y(s) are independent Gaussian processes with means
0 and variances σ2
Xand σ2
Yrespectively. Calculate the variance of Z(s) in terms
of σ2
Xand σ2
Y.
Solution
Step 1: First, recall that the variance of a sum of two random variables is equal
to the sum of their variances if the random variables are independent.
Step 2: Since X(s) and Y(s) are independent Gaussian processes, we have
V ar[Z(s)] = V ar[X(s)] + V ar[Y(s)].
Step 3: Given that V ar[X(s)] = σ2
Xand V ar[Y(s)] = σ2
Y, we can substitute
these values into the equation.
Step 4: Therefore, the variance of Z(s) is:
V ar[Z(s)] = σ2
X+σ2
Y
Step 5: Thus, the variance of Z(s) in terms of σ2
Xand σ2
Yis σ2
X+σ2
Y.
13

Question 15
Question
Consider a dataset containing information on the locations and population den-
sities of various cities in a country.
A researcher wants to analyze the spatial patterns of population density
using spatial data analysis and modeling techniques.
Explain how the researcher can approach this analysis, including the steps
involved in preprocessing the data and selecting the appropriate spatial analysis
techniques.
Solution
To analyze the spatial patterns of population density in the dataset, the re-
searcher can follow these steps:
Step 1: Data Preprocessing - Clean and preprocess the dataset by re-
moving any missing or erroneous data. - Convert the location data (latitude
and longitude) into spatial coordinates or a spatial object. - Normalize the
population density values to account for any scale differences.
Step 2: Exploratory Spatial Data Analysis (ESDA) - Conduct ex-
ploratory spatial data analysis to examine the spatial distribution of population
density. - Calculate global spatial autocorrelation measures, such as Moran’s I,
to determine if there is spatial clustering or dispersion of population density. -
Create spatial plots, such as spatial maps or spatial correlograms, to visualize
spatial relationships.
Step 3: Spatial Interpolation - Use spatial interpolation techniques, such
as kriging or inverse distance weighting, to estimate population density values
at unsampled locations. - Evaluate the accuracy of the spatial interpolation by
comparing the interpolated values with observed values.
Step 4: Spatial Regression Modeling - Perform spatial regression analy-
sis to model the relationship between population density and relevant covariates,
such as land use types or infrastructure. - Consider spatial autocorrelation in
the regression model, using techniques like spatial lag or spatial error models.
Step 5: Cluster Analysis - Apply cluster analysis methods, such as spatial
clustering algorithms or hot spot analysis, to identify spatial clusters of high
or low population density. - Evaluate the statistical significance of identified
clusters using appropriate tests.
By following these steps and applying spatial data analysis and modeling
techniques, the researcher can gain valuable insights into the spatial patterns of
population density in the dataset.
14

Question 16
Question
Let X1and X2be two independent spatial processes with covariance functions
γ1(h) and γ2(h), respectively. Consider the linear combination Y=aX1+bX2,
where aand bare constants. Determine the covariance function γY(h) for the
process Yin terms of γ1(h), γ2(h), a, and b.
Solution
A spatial process Z(s) has a covariance function γ(s, t) defined as γ(s, t) =
Cov[Z(s), Z(t)] for all locations sand tin the domain of the process.
Given two independent spatial processes X1and X2with covariance func-
tions γ1(h) and γ2(h), respectively, the covariance function of the linear combi-
nation Y=aX1+bX2can be determined as follows:
Step 1: Calculate the covariance function of YThe covariance function
of Yis defined as:
γY(h) = Cov[Y(s), Y (t)]
=Cov[aX1(s) + bX2(s), aX1(t) + bX2(t)]
=a2Cov[X1(s), X1(t)] + b2Cov[X2(s), X2(t)]
+abCov[X1(s), X2(t)] + abCov[X2(s), X1(t)]
Step 2: Simplify the expression using the covariance functions
γ1(h)and γ2(h) By substituting the covariance functions γ1(h) and γ2(h) for
Cov[X1(s), X1(t)] and Cov[X2(s), X2(t)], and noting that X1and X2are inde-
pendent processes:
γY(h) = a2γ1(h) + b2γ2(h)
Therefore, the covariance function of the linear combination Y=aX1+bX2
is γY(h) = a2γ1(h) + b2γ2(h).
Question 17
Question
Consider a dataset containing the locations of earthquakes recorded over a year
in a particular region. The dataset consists of latitude and longitude values for
each earthquake. You are tasked with analyzing this spatial data to identify
any patterns or clustering of earthquakes. Describe a suitable spatial analysis
technique for this task and explain how you would apply it to the dataset.
Solution
Step 1: One suitable spatial analysis technique for analyzing the distribution of
earthquakes is the Kernel Density Estimation (KDE) method.
15

Step 2: To apply the KDE method to the earthquake dataset, follow these
steps:
1. Data Preprocessing: Load the dataset containing the latitude and lon-
gitude values of each earthquake.
2. Density Estimation: For each earthquake location, create a small,
smooth circular or elliptical ”kernel” around it. The KDE method cal-
culates the density of earthquakes at any given point by summing up the
influence of all kernels placed on that point.
3. Bandwidth Selection: Choose an appropriate bandwidth parameter
that controls the size of the kernels. A larger bandwidth results in a
smoother density estimation, while a smaller bandwidth captures more
localized patterns.
4. Visualization: Generate a heatmap or contour plot to visualize the KDE
results. Areas with higher density values indicate regions with a higher
frequency of earthquakes.
5. Interpretation: Analyze the KDE output to identify any clustering or
spatial patterns in earthquake occurrences. Pay attention to hotspots or
areas with significantly higher density values, as they may indicate areas
of high seismic activity.
By following these steps and applying the Kernel Density Estimation method
to the earthquake dataset, you can effectively analyze the spatial distribution
of earthquakes and identify any patterns or clustering present in the data.
Question 18
Question
Consider a dataset containing spatial coordinates and pollution levels at various
locations in a city. You are tasked with analyzing the spatial distribution of
pollution levels and creating a model to predict pollution levels at unmeasured
locations.
Given the dataset, describe the steps you would take to analyze the spatial
distribution of pollution levels and develop a model for predicting pollution
levels.
Solution
To analyze the spatial distribution of pollution levels and create a model for
predicting pollution levels at unmeasured locations, we can follow these steps:
Step 1: **Exploratory Data Analysis (EDA)** - Begin by performing ex-
ploratory data analysis to understand the characteristics of the dataset. - Ex-
amine summary statistics, distribution of pollution levels, and spatial patterns.
16

- Create visualizations such as scatter plots, histograms, and spatial maps to
identify trends and patterns in the data.
Step 2: **Spatial Autocorrelation Analysis** - Conduct spatial autocorre-
lation analysis to determine if pollution levels exhibit spatial dependence. -
Calculate Moran’s I statistic to assess the degree of spatial autocorrelation in
pollution levels. - Interpret the Moran’s I value to understand the spatial pat-
tern of pollution levels (e.g., clustered, dispersed, random).
Step 3: **Spatial Interpolation** - Use spatial interpolation techniques (e.g.,
Inverse Distance Weighting, Ordinary Kriging) to interpolate pollution levels at
unmeasured locations. - Compare different interpolation methods and select the
most suitable one based on validation metrics and the spatial characteristics of
pollution levels.
Step 4: **Spatial Regression Modeling** - Develop a spatial regression
model to predict pollution levels based on various spatially explicit predictors
(e.g., distance to highways, land use characteristics). - Incorporate spatial au-
tocorrelation terms (e.g., spatial lag, spatial error) to account for spatial depen-
dence in the data. - Evaluate the model’s performance using metrics such as
R-squared, AIC, and cross-validation.
Step 5: **Model Validation and Interpretation** - Validate the spatial re-
gression model by checking for assumptions violations and model fit. - Interpret
the coefficients of the model to understand the relationships between predictors
and pollution levels. - Use diagnostic tests to assess model residuals and identify
areas for model improvement.
By following these steps, we can effectively analyze the spatial distribution
of pollution levels and develop a predictive model for estimating pollution levels
at unmeasured locations.
Question 19
Question
For a study on urban land use, a researcher collected spatial data on population
density, average income, and land value for different neighborhoods in a city.
The researcher wants to develop a regression model to predict land value based
on population density and average income. Given the spatial nature of the
data, explain how the researcher can account for spatial autocorrelation in the
modeling process.
Solution
To account for spatial autocorrelation in the modeling process, the researcher
can use spatial regression techniques that consider the spatial relationships be-
tween observations. One common approach is to use spatial lag models or spatial
error models.
17

Step 1: Spatial Lag Model A spatial lag model includes a spatially lagged
dependent variable to capture the impact of neighboring observations on each
other. The model can be represented as:
y=ρW y +Xβ +ε
where: - yis the dependent variable (land value), - ρis the spatial auto-
correlation coefficient, - Wis a spatial weights matrix representing the spatial
relationships between observations, - Xis a matrix of independent variables
(population density, average income), - βis a vector of coefficients, - εis the
error term.
Step 2: Spatial Error Model A spatial error model assumes that the
errors in the regression model are spatially correlated. The model can be rep-
resented as:
y=Xβ +λW ε
where: - y,X, and βhave the same meanings as in the spatial lag model, -
λis a parameter that captures the spatial autocorrelation in the error term, - ε
is the error term.
Step 3: Moran’s I Test Before choosing between a spatial lag model
and a spatial error model, the researcher should conduct a Moran’s I test to
assess the presence of spatial autocorrelation in the data. If the Moran’s I test
indicates significant spatial autocorrelation, the researcher can proceed with
fitting a spatial regression model.
By using spatial regression techniques like the spatial lag model or spatial
error model, the researcher can effectively account for spatial autocorrelation in
the modeling process when analyzing urban land use data.
Question 20
Question
Consider a dataset consisting of the locations of 100 bus stops in a city, repre-
sented by their latitude and longitude coordinates. You are tasked with analyz-
ing the spatial distribution of these bus stops to identify any clustering patterns
that may exist. Explain how you would approach this spatial data analysis and
modeling problem.
Solution
To analyze the spatial distribution of the bus stops and identify clustering pat-
terns, we can follow these steps:
Step 1: Data Preparation - Obtain the dataset containing the latitude
and longitude coordinates of the bus stops. - Check for any missing or erroneous
data points and clean the dataset if necessary. - Consider transforming the
coordinates into a spatial object format suitable for analysis.
18

Step 2: Exploratory Data Analysis (EDA) - Conduct exploratory data
analysis by plotting the bus stop locations on a map to visualize the spatial
distribution. - Use spatial visualization techniques such as heat maps or scatter
plots to identify any clustering patterns. - Calculate basic descriptive statistics
such as mean center, standard distance, and spatial autocorrelation to gain
insights into the data distribution.
Step 3: Spatial Analysis Techniques - Apply spatial analysis techniques
such as cluster analysis (e.g., K-means clustering, DBSCAN) to identify specific
clusters of bus stops based on their proximity. - Utilize spatial statistics tools
to analyze the spatial autocorrelation and spatial patterns of the bus stop lo-
cations. - Consider performing point pattern analysis to determine if the bus
stops exhibit any significant clustering or dispersion patterns.
Step 4: Spatial Modeling - Develop spatial models to predict the likeli-
hood of new bus stops being located in certain areas based on existing spatial
patterns. - Use geostatistical modeling techniques to interpolate and predict
the spatial distribution of bus stops across the city. - Validate the spatial mod-
els using cross-validation techniques and assess their accuracy in predicting bus
stop locations.
By following these steps, we can effectively analyze the spatial distribution
of bus stops and model clustering patterns to inform urban planning and trans-
portation decision-making processes.
Question 21
Question
Consider a dataset consisting of geographical coordinates (latitude and longi-
tude) of 100 different locations. The dataset also includes a continuous variable
representing the temperature at each location.
If you were to model the relationship between temperature and location
coordinates, discuss the steps you would take for spatial data analysis and mod-
eling.
Solution
To model the relationship between temperature and location coordinates, we
can follow these steps for spatial data analysis and modeling:
Step 1: Data Exploration - Explore the dataset by plotting the temper-
ature values on a map using latitude and longitude coordinates. - Check for
any spatial patterns or clusters in the data that might indicate a relationship
between temperature and location.
Step 2: Spatial Autocorrelation Analysis - Conduct spatial autocorre-
lation analysis to determine if there is any spatial dependence between tempera-
ture values at different locations. - Use tools like Moran’s I statistic to quantify
spatial autocorrelation and assess its significance.
19

Step 3: Spatial Interpolation - Use spatial interpolation techniques (such
as Kriging or Inverse Distance Weighting) to estimate temperature values at
locations where data is missing or incomplete. - Interpolated values can help
fill in gaps and provide a more complete spatial dataset for modeling.
Step 4: Spatial Regression Modeling - Perform spatial regression anal-
ysis to model the relationship between temperature and location coordinates.
- Account for spatial dependencies in the data by including spatial weights in
the regression model. - Evaluate the model’s performance using metrics like
R-squared, AIC, BIC, etc.
Step 5: Model Validation - Validate the spatial regression model by
checking for spatial autocorrelation in the residuals. - Use cross-validation tech-
niques to assess the model’s predictive accuracy and generalizability.
Step 6: Interpretation and Inference - Interpret the results of the spa-
tial regression model to understand how temperature is influenced by location
coordinates. - Draw meaningful inferences about the relationship between tem-
perature and spatial factors based on the model output.
Question 22
Question
Consider a dataset containing information about housing prices in a city, with
spatial coordinates for each house. You are tasked with performing spatial data
analysis and modeling to predict housing prices in a new area of the city based
on the available data.
Explain the steps you would take to: 1. Clean and preprocess the data. 2.
Explore the spatial distribution of housing prices. 3. Build a spatial regression
model to predict housing prices in the new area.
Solution
1. Clean and preprocess the data: Step 1: Check for missing values and
outliers in the dataset. Remove or impute missing values, and address any
outliers appropriately.
Step 2: Standardize or normalize numerical features in the dataset to ensure
that all variables are on a similar scale and to improve model performance.
Step 3: Encode categorical variables using techniques like one-hot encoding
to convert them into a numerical format that can be used for modeling.
2. Explore the spatial distribution of housing prices: Step 1: Visual-
ize the spatial distribution of housing prices using techniques like scatter plots
or heat maps to identify any patterns or trends.
Step 2: Conduct spatial autocorrelation analysis to determine if housing
prices exhibit spatial dependence, which is crucial for spatial modeling.
Step 3: Use spatial interpolation methods, such as kriging or inverse dis-
tance weighting, to estimate housing prices at unsampled locations based on
20

surrounding data points.
3. Build a spatial regression model to predict housing prices: Step
1: Select an appropriate spatial regression model, such as spatial lag or spatial
error models, that accounts for spatial autocorrelation in the data.
Step 2: Split the dataset into training and testing sets to evaluate the model’s
performance.
Step 3: Fit the spatial regression model to the training data and evaluate
its predictive ability using metrics like R-squared, AIC, or BIC.
Step 4: Validate the model by comparing predicted housing prices to actual
values in the testing set and assess the model’s accuracy and robustness.
By following these steps, you can effectively clean, explore, and model spatial
data to predict housing prices in a new area of the city.
Question 23
Question
A city wants to analyze the spatial distribution of air quality across its neighbor-
hoods to identify areas with poor air quality that may require intervention. The
city collects air quality data from various monitoring stations located through-
out the city. Describe the steps involved in conducting spatial data analysis and
modeling to achieve this goal.
Solution
To analyze the spatial distribution of air quality across neighborhoods, the city
can follow these steps:
Step 1: Data Collection - Collect air quality data from monitoring stations
located throughout the city. - Ensure the data includes variables such as pol-
lutant concentrations, timestamps, and geographical coordinates of monitoring
stations.
Step 2: Data Preprocessing - Clean the data by addressing missing values,
outliers, and inconsistencies. - Perform data transformations if required, such
as normalization or standardization.
Step 3: Spatial Data Analysis - Use Geographic Information System (GIS)
tools to visualize the spatial distribution of air quality data on a map. - Calculate
descriptive statistics to understand the central tendency and variability across
neighborhoods.
Step 4: Spatial Autocorrelation Analysis - Conduct spatial autocor-
relation analysis to identify if air quality values in nearby neighborhoods are
similar (positive spatial autocorrelation) or dissimilar (negative spatial auto-
correlation). - Test for statistical significance using measures like Moran’s I or
Geary’s C.
Step 5: Spatial Data Modeling - Develop a spatial regression model to
analyze the relationship between air quality and potential explanatory variables
21

such as proximity to industrial areas, traffic volume, or vegetation cover. -
Use techniques like Ordinary Least Squares (OLS) or Geographically Weighted
Regression (GWR) to account for spatial heterogeneity.
Step 6: Prediction and Visualization - Use the spatial regression model
to make predictions of air quality across all neighborhoods. - Visualize the
predicted air quality values on a map to identify areas with poor air quality
that may require intervention.
By following these steps, the city can effectively analyze the spatial distribu-
tion of air quality across neighborhoods and make informed decisions to improve
air quality in the city.
Question 24
Question
Let Yirepresent the number of reported crimes in a specific region i, and let
Xirepresent the population density in the same region. A spatial data anal-
ysis is conducted to model the relationship between the number of crimes and
population density using the following model:
Yi=β0+β1Xi+ϵi
where β0and β1are regression coefficients, and ϵirepresents the error term.
Given the spatial autocorrelation present in the data, how would you modify
the model to account for spatial effects?
Solution
Step 1: Incorporating a Spatial Lag of the Dependent Variable
To account for spatial autocorrelation, we can modify the model by incorpo-
rating a spatial lag of the dependent variable Yi. The modified model is as
follows:
Yi=β0+β1Xi+ρW Y +ϵi
where Wis a spatial weight matrix, ρis a spatial autoregressive coefficient,
and W Y represents the spatial lag of Yi.
Step 2: Assessing Model Fit
We can use model fit statistics such as Akaike Information Criterion (AIC) or
Bayesian Information Criterion (BIC) to compare the original model without
spatial effects to the modified model with spatial effects. Lower values of AIC
or BIC indicate better model fit.
Step 3: Spatial Diagnostic Tests
Performing spatial diagnostic tests such as Moran’s I test or Geary’s C test can
help in examining the presence of spatial autocorrelation in the residuals of the
model. If significant spatial autocorrelation is detected, it confirms the need to
include spatial effects in the model.
22

Step 4: Spatial Weight Matrix Specification
Careful selection of the spatial weight matrix Wis crucial in capturing the spa-
tial connectivity between regions. Common weight matrix specifications include
rook, queen, distance-based weights, or contiguity-based weights.
Step 5: Interpreting Spatial Autoregressive Coefficient (ρ)
The spatial autoregressive coefficient ρcaptures the spatial dependency in the
response variable. A positive ρindicates positive spatial autocorrelation, mean-
ing that regions with high crime rates are surrounded by regions with high crime
rates as well. Conversely, a negative ρsuggests negative spatial autocorrelation.
By following these steps and modifying the original model to account for
spatial effects, we can build a spatial data analysis model that better captures
the spatial patterns and relationships in the data.
Question 25
Question
Consider a dataset containing spatial data on the distribution of a species across
a region. The dataset includes the latitude and longitude coordinates of each
observation, as well as information on the population density of the species at
each location.
Using spatial data analysis and modeling techniques, discuss how you would
approach the following tasks: 1. Visualizing the spatial distribution of the
species population density. 2. Assessing the spatial autocorrelation of the pop-
ulation density values. 3. Building a spatial regression model to predict the
population density at unobserved locations. 4. Validating the spatial regression
model.
Solution
1. Visualizing the spatial distribution of the species population den-
sity: Step 1: One way to visualize the spatial distribution of the species popula-
tion density is to create a spatial density plot. This can be done by plotting the
population density values on a map of the region, with color-coding to represent
different density levels.
Step 2: Another option is to create a spatial interpolation map using tech-
niques such as kriging or inverse distance weighting to predict population density
values at unobserved locations based on the observed data points.
2. Assessing the spatial autocorrelation of the population density
values: Step 1: Calculate the spatial autocorrelation of the population density
values using a spatial autocorrelation statistic such as Moran’s I or Geary’s C.
These statistics measure the degree of similarity between neighboring locations
in terms of their population density values.
Step 2: Interpret the spatial autocorrelation statistic to determine whether
23

there is spatial clustering (positive autocorrelation) or dispersion (negative au-
tocorrelation) of the population density values across the region.
3. Building a spatial regression model to predict the population
density at unobserved locations: Step 1: Choose an appropriate spatial
regression model such as spatial autoregressive model, spatial error model, or
spatial lag model based on the characteristics of the dataset and the results of
the spatial autocorrelation analysis.
Step 2: Fit the chosen spatial regression model using the observed population
density values and the spatial coordinates of each location as predictors. This
will allow you to estimate the relationship between the population density and
the spatial predictors.
4. Validating the spatial regression model: Step 1: Validate the spatial
regression model by assessing its predictive performance using techniques such
as cross-validation, residual analysis, and measures of model fit like R-squared
and root mean square error.
Step 2: Compare the predicted population density values from the spatial
regression model with the observed values to evaluate the model’s accuracy and
generalization to unobserved locations. Adjust the model if necessary based on
the validation results.
Question 26
Question
Consider a dataset consisting of spatial data points representing the elevation
above sea level at various locations on a mountain. The dataset contains some
outliers that need to be identified and removed before conducting any spatial
analysis. Explain how you would approach this task using spatial data analysis
and modeling techniques.
Solution
To identify and remove outliers in spatial data representing elevation above sea
level on a mountain, we can follow these steps:
Step 1: Visualize the data using a scatter plot or a spatial map to identify
any unusual patterns, gaps, or extreme values that may indicate outliers.
Step 2: Calculate summary statistics such as mean, median, standard devi-
ation, and range to get a better understanding of the distribution of elevation
values.
Step 3: Perform spatial autocorrelation analysis to identify any spatial pat-
terns or clustering of outlier values. This can be done using techniques such as
Moran’s I or Geary’s C statistics.
Step 4: Use spatial interpolation techniques, such as kriging or inverse dis-
tance weighting, to impute missing values or smooth out extreme values that
may be outliers.
24

Step 5: Apply outlier detection algorithms specific to spatial data, such
as Local Outlier Factor (LOF) or Spatial Significance Detection Algorithm
(SISDA), to identify and flag potential outliers based on their spatial relation-
ships with neighboring data points.
Step 6: Evaluate the identified outliers based on domain knowledge and
decide whether to remove them from the dataset or adjust their values based
on the analysis conducted.
By following these steps, we can effectively identify and deal with outliers
in spatial data representing elevation above sea level on a mountain before
proceeding with any spatial analysis and modeling tasks.
Question 27
Question
Consider a dataset containing information on the population density and average
income of different regions within a country. You are tasked with analyzing the
relationship between population density and average income to understand how
they influence each other.
Using spatial data analysis and modeling techniques, explain how you would
approach this problem.
Solution
To analyze the relationship between population density and average income
using spatial data analysis and modeling techniques, we can follow these steps:
Step 1: Data Collection and Preparation - Collect the spatial dataset
containing information on population density, average income, and the geo-
graphical coordinates of each region. - Preprocess the data by checking for
missing values, outliers, and ensuring the data is in a suitable format for spatial
analysis.
Step 2: Exploratory Data Analysis - Conduct exploratory data analysis
to understand the distribution of population density and average income across
different regions. - Use visualizations such as scatter plots, histograms, and
maps to explore the relationship between the two variables.
Step 3: Spatial Autocorrelation Analysis - Use spatial autocorrelation
analysis to examine whether population density and average income values ex-
hibit spatial clustering or patterns. - Calculate spatial autocorrelation measures
such as Moran’s I to quantify the spatial dependency between the variables.
Step 4: Spatial Regression Modeling - Perform spatial regression model-
ing to analyze the relationship between population density and average income
while accounting for spatial dependencies. - Use techniques such as spatial lag
models or spatial error models to incorporate spatial effects into the regression
analysis.
25
Step 5: Model Evaluation and Interpretation - Evaluate the spatial
regression model to assess its goodness of fit and interpret the coefficients of
the variables. - Examine the spatial autocorrelation of the model residuals to
ensure that there are no remaining spatial patterns.
By following these steps, we can effectively analyze the relationship between
population density and average income using spatial data analysis and modeling
techniques.
Question 28
Question
Consider a dataset consisting of the locations of houses in a neighborhood. The
dataset includes the coordinates of each house (latitude and longitude), as well
as the number of bedrooms and bathrooms in each house.
Given this dataset, perform the following spatial analysis and modeling tasks:
1. Calculate the pairwise Euclidean distances between all pairs of houses in
the dataset.
2. Create a spatial weight matrix using a contiguity-based approach (e.g.,
Queen’s contiguity).
3. Determine if there are any spatial clusters of houses with a higher-than-
average number of bedrooms.
4. Develop a spatial regression model to predict the number of bathrooms in
a house based on its neighbors’ characteristics.
Solution
Step 1: Calculate pairwise Euclidean distances To calculate the pairwise
Euclidean distances between all pairs of houses, we can use the formula for
Euclidean distance in a 2D space:
Euclidean distance = p(x2−x1)2+ (y2−y1)2
where (x1, y1) and (x2, y2) are the coordinates of two houses.
Step 2: Create spatial weight matrix To create a spatial weight matrix
using a contiguity-based approach, we can define neighbors based on the Queen’s
contiguity, which considers houses that share an edge or a vertex as neighbors.
Step 3: Identify spatial clusters To identify spatial clusters of houses
with a higher-than-average number of bedrooms, we can use spatial cluster
analysis techniques such as Getis-Ord Gi* statistic or Local Moran’s I.
Step 4: Develop spatial regression model To develop a spatial regres-
sion model to predict the number of bathrooms in a house based on its neighbors’
characteristics, we can use spatial regression techniques like Spatial Lag or Spa-
tial Error regression models. These models account for spatial autocorrelation
in the data which arises due to the spatial proximity of houses.
26
Question 29
Question
Consider a dataset containing the locations of 100 different species of trees in
a forest. The dataset includes the coordinates (latitude and longitude) of each
tree. You are tasked with analyzing the spatial distribution of these trees and
creating a model to predict the presence of certain species based on environ-
mental variables such as soil type, sunlight exposure, and elevation.
Describe the steps you would take to perform spatial data analysis and
modeling on this dataset. Include the key techniques and considerations involved
in each step.
Solution
To perform spatial data analysis and modeling on the dataset of tree locations
in the forest, the following steps can be taken:
Step 1: Data Preprocessing
Clean the dataset by removing any duplicate or erroneous entries.
Check for missing values in both the tree locations and environmental
variables.
Convert the latitude and longitude coordinates into a suitable coordinate
reference system for spatial analysis.
Step 2: Exploratory Spatial Data Analysis (ESDA)
Use spatial visualization techniques like scatter plots, histograms, and
spatial autocorrelation plots to explore the spatial distribution of tree
species.
Perform hotspot analysis to identify clusters or spatial patterns in the
distribution of certain species.
Step 3: Spatial Statistical Analysis
Conduct spatial autocorrelation analysis to assess the degree of spatial
dependence among the tree species.
Employ spatial regression models to understand the relationship between
the presence of tree species and environmental variables like soil type,
sunlight exposure, and elevation.
Step 4: Model Building
Utilize techniques such as spatial interpolation, kriging, or machine learn-
ing algorithms to predict the presence of tree species at unsampled loca-
tions based on the environmental variables.
27
Evaluate the model performance using metrics like accuracy, precision,
and recall.
Step 5: Model Interpretation and Validation
Interpret the model results to understand the factors influencing the dis-
tribution of tree species in the forest.
Validate the model by comparing the predicted species distribution with
actual field observations.
Question 30
Question
Consider a dataset consisting of temperature measurements at different loca-
tions across a region. The data points are spatially correlated, with higher
temperatures in one location likely corresponding to higher temperatures in
neighboring locations.
Given this dataset, discuss the importance of spatial autocorrelation in spa-
tial data analysis and modeling. Additionally, explain how spatial autocorrela-
tion can impact the reliability and interpretation of statistical inferences drawn
from the dataset.
Solution
Step 1: Importance of Spatial Autocorrelation Spatial autocorrelation
refers to the phenomenon where nearby locations are more likely to have similar
values compared to locations that are farther apart. Understanding the pres-
ence of spatial autocorrelation is crucial in spatial data analysis and modeling
for several reasons: - It allows us to take into account the spatial structure
of the data and incorporate this information into our analysis. - Spatial au-
tocorrelation helps in identifying clusters or patterns in the dataset, providing
insights into underlying processes that may be influencing the observed values.
- Considering spatial autocorrelation can lead to more accurate modeling and
prediction of values at unsampled locations.
Step 2: Impact on Reliability of Statistical Inferences Spatial auto-
correlation can affect the reliability and interpretation of statistical inferences in
the following ways: - Ignoring spatial autocorrelation may lead to biased param-
eter estimates and inflated standard errors, affecting the validity of statistical
tests. - It can violate the assumption of independence of observations, which is
critical for many statistical methods. Failure to account for spatial autocorre-
lation can result in incorrect conclusions about relationships between variables.
- Spatial autocorrelation can influence the spatial distribution of residuals in a
model, impacting the model’s goodness of fit and the accuracy of predictions.
In conclusion, recognizing and addressing spatial autocorrelation in spatial
data analysis is essential for improving the reliability of statistical inferences,
28

Question 4
Question
Consider a dataset containing information about the location of trees in a park.
You are interested in analyzing the spatial distribution of tree species across the
park. Discuss how you would approach this spatial data analysis and modeling
task.
Solution
To analyze the spatial distribution of tree species in the park, we can follow
these steps:
Step 1: Data Collection and Preparation - Collect data on the location
of trees in the park, including the species of each tree. - Pre-process the data
to ensure that it is clean and formatted correctly for spatial analysis.
Step 2: Exploratory Data Analysis (EDA) - Conduct a preliminary
analysis of the data to understand the distribution of tree species across the
park. - Use visualizations such as scatter plots or spatial maps to identify any
patterns or clusters.
Step 3: Spatial Autocorrelation Analysis - Perform spatial autocor-
relation analysis to determine if tree species tend to cluster together or are
randomly distributed across the park. - Calculate measures such as Moran’s I
to quantify spatial autocorrelation.
Step 4: Spatial Interpolation - Use spatial interpolation techniques to
estimate the distribution of tree species in areas where data is missing or sparse.
- Popular interpolation methods include Inverse Distance Weighting (IDW) or
Kriging.
Step 5: Spatial Clustering Analysis - Apply spatial clustering tech-
niques such as K-means clustering or DBSCAN to identify groups of trees with
similar characteristics. - Analyze the resulting clusters to understand the spatial
patterns of tree species distribution.
Step 6: Spatial Modeling - Develop spatial models to predict the distri-
bution of tree species based on environmental variables or other relevant factors.
- Evaluate the accuracy of the models using techniques such as cross-validation.
By following these steps, we can gain valuable insights into the spatial distri-
bution of tree species in the park and develop models to support decision-making
and management strategies.
Question 5
Question
Consider a dataset containing information on the locations of 100 different
species of plants in a forest. You are interested in analyzing the spatial patterns
4

of these plant species to determine if there are any clusters or spatial dependen-
cies present. Explain how you would approach this spatial data analysis and
modeling problem.
Solution
To analyze the spatial patterns of plant species in the forest dataset, we can
follow these steps in spatial data analysis and modeling:
Step 1: Data Exploration - Begin by visualizing the spatial distribution
of the 100 plant species in the forest using scatter plots or maps. - Look for
any visible patterns, clusters, or spatial dependencies that may be present in
the data.
Step 2: Spatial Autocorrelation Analysis - Conduct spatial autocor-
relation analysis to determine if there is a significant spatial pattern in the
distribution of plant species. - Calculate Moran’s I statistic to quantify spatial
autocorrelation, where values close to 1 indicate positive spatial autocorrela-
tion (clustering) and values close to -1 indicate negative spatial autocorrelation
(dispersion). - Perform a significance test to determine if the spatial pattern is
statistically significant.
Step 3: Spatial Clustering Analysis - Apply spatial clustering tech-
niques such as Moran’s I clustering or Getis-Ord Gi* to identify clusters of
plant species in the forest. - Determine the locations of significant clusters and
analyze their characteristics.
Step 4: Spatial Interpolation - Use spatial interpolation methods such
as kriging or inverse distance weighting to estimate the distribution of plant
species between sampled points. - Generate interpolated surfaces to visualize
the spatial variation of plant species across the forest.
Step 5: Spatial Regression Modeling - Perform spatial regression anal-
ysis to investigate the relationship between environmental variables (e.g., soil
type, sunlight exposure) and the distribution of plant species. - Build regression
models that account for spatial dependencies using techniques like spatial lag
models or spatial error models.
By following these steps in spatial data analysis and modeling, we can gain
insights into the spatial patterns of plant species in the forest dataset and un-
derstand the underlying processes driving their distribution.
Question 6
Question
A researcher is interested in analyzing the spatial distribution of a certain species
of plants across a forest. The researcher collects data on the number of plants
observed at various locations within the forest. Given the dataset, the researcher
wants to create a spatial interpolation model to estimate the plant density at
5

unsampled locations. Explain the steps the researcher should follow to perform
spatial data analysis and modeling for this scenario.
Solution
To perform spatial data analysis and modeling for this scenario, the researcher
should follow the steps outlined below:
Step 1: Data Collection - Collect data on the number of plants observed
at various locations within the forest. - Ensure that the data is georeferenced
with spatial coordinates for each observation point.
Step 2: Data Exploration - Conduct exploratory data analysis to under-
stand the distribution and patterns of plant density within the forest. - Use
tools such as scatter plots, histograms, and spatial autocorrelation analysis to
identify any trends or spatial dependencies in the data.
Step 3: Spatial Interpolation - Choose an appropriate spatial inter-
polation method to estimate plant density at unsampled locations. Common
methods include kriging, inverse distance weighting, and spline interpolation.
- Perform the spatial interpolation using the selected method to generate a
continuous surface representing plant density across the entire forest.
Step 4: Model Validation - Validate the accuracy of the spatial interpo-
lation model by comparing the predicted plant densities to the observed values
at sampled locations. - Use statistical measures such as root mean square error
(RMSE) or cross-validation techniques to assess the model performance.
Step 5: Model Refinement - Refine the spatial interpolation model by
adjusting parameters or exploring alternative interpolation methods to improve
the accuracy of plant density estimates. - Iteratively validate and refine the
model until satisfactory results are achieved.
Step 6: Interpretation and Visualization - Interpret the results of the
spatial data analysis and modeling to gain insights into the spatial distribution
of the plant species within the forest. - Visualize the interpolated plant density
surface using maps or contour plots to communicate the findings effectively.
By following these steps, the researcher can effectively analyze the spatial
distribution of the plant species and create a reliable spatial interpolation model
for estimating plant density across the forest.
Question 7
Question
Suppose you are given a dataset consisting of locations (x, y) and corresponding
measurements (z) for a particular variable. You would like to fit a spatial model
to this data in order to make predictions at unsampled locations. Explain the
process of fitting a spatial model and demonstrate this by fitting a simple spatial
model (e.g. Kriging) to the provided dataset.
6
Solution
To fit a spatial model to a dataset, we typically follow these steps: Step 1:
Visualize the data to understand its spatial distribution and detect any patterns
or trends. Step 2: Choose a spatial model (e.g., variogram model) that captures
the spatial dependence structure in the data. Step 3: Fit the chosen model to the
data using a fitting method (e.g., method of moments, maximum likelihood).
Step 4: Validate the fitted model to assess its performance in capturing the
spatial variation. Step 5: Make predictions at unsampled locations using the
fitted model.
Let’s demonstrate this process by fitting a simple spatial model (Kriging) to
the provided dataset.
Question 8
Question
Suppose you are given a dataset consisting of the spatial coordinates of various
earthquake occurrences in a region. You are asked to perform a spatial data
analysis and modeling to identify any underlying patterns or trends in the data.
Explain the steps you would take to carry out this analysis.
Solution
To perform a spatial data analysis and modeling on the earthquake dataset, you
can follow these steps:
Step 1: Data Exploration
Begin by exploring the dataset to understand its structure and contents.
Look for any missing values, outliers, or inconsistencies in the spatial
coordinates.
Generate descriptive statistics to summarize the data distribution.
Step 2: Visualization
Create visual representations of the spatial data using maps, scatter plots,
or kernel density estimation plots.
Identify any clusters or patterns in the earthquake occurrences.
Step 3: Spatial Autocorrelation Analysis
Conduct a spatial autocorrelation analysis to examine the degree of spatial
dependence among the earthquake events.
Check if there is any clustering, randomness, or dispersion in the data.
Step 4: Spatial Interpolation
7
Use spatial interpolation techniques such as kriging or inverse distance
weighting to estimate earthquake occurrences at unsampled locations.
Evaluate the accuracy of the interpolation method used.
Step 5: Spatial Regression Modeling
Perform spatial regression analysis to model the relationship between
earthquake events and potential explanatory variables (e.g., geological fea-
tures, fault lines).
Assess the significance and strength of the spatial relationships in the
model.
Step 6: Model Validation
Validate the spatial regression model using goodness-of-fit measures and
diagnostic tests.
Assess the reliability of the model for predicting future earthquake occur-
rences.
By following these steps, you can conduct a comprehensive spatial data
analysis and modeling of the earthquake dataset to uncover underlying patterns
and relationships in the data.
Question 9
Question
Let X1and X2be two random variables representing the longitude and latitude
coordinates of a point on Earth. Suppose X1follows a normal distribution with
mean 0 and variance 4, and X2follows a normal distribution with mean 0 and
variance 9. Calculate the probability that the point lies within a circular region
of radius 5 units centered at the origin.
Solution
Step 1: Find the joint probability distribution of X1and X2. Since X1and X2
are independent, the joint probability density function is the product of their
individual probability density functions:
fX1,X2(x1, x2) = fX1(x1)·fX2(x2)
Given:
fX1(x1) = 1
2√2πe−
x2
1
8for − ∞ < x1<∞
fX2(x2) = 1
3√2πe−
x2
2
18 for − ∞ < x2<∞
8
Step 2: Calculate the probability that the point lies within the circular region
of radius 5 units. The probability that the point lies within the circular region
can be expressed as:
P(X2
1+X2
2<25)
This probability can be calculated by integrating the joint probability density
function over the region inside the circle:
P(X2
1+X2
2<25) = ZZx2
1+x2
2<25
fX1,X2(x1, x2)dx1dx2
Step 3: Substitute the joint PDF and solve the double integral. Substitute
fX1,X2(x1, x2) = fX1(x1)·fX2(x2) into the double integral and solve the integral
over the circular region:
P(X2
1+X2
2<25) = Z5
−5Z√25−x2
1
−√25−x2
1
fX1(x1)·fX2(x2)dx2dx1
P(X2
1+X2
2<25) = Z5
−5Z√25−x2
1
−√25−x2
1
1
6πe−
x2
1
8
−
x2
2
18 dx2dx1
Step 4: Evaluate the integral to find the probability. Perform the integration
and evaluate the probability that the point lies within the circular region of
radius 5 units centered at the origin.
Question 10
Question
Consider a dataset containing the coordinates (x, y) of 20 different urban loca-
tions. You are tasked with fitting a spatial model to analyze the relationship
between the population density (pop density) and the distance to the nearest
park (park dist). The model under consideration is given by:
pop density =β0+β1·park dist +ϵ
where ϵ∼N(0, σ2) represents the error term.
Given the dataset and the model, perform the necessary steps to estimate
the coefficients β0and β1using the method of least squares.
Solution
Step 1: Write the least squares estimation equations for β0and β1. The least
squares estimation equations for β0and β1are:
β1=Pn
i=1(xi−¯x)(yi−¯y)
Pn
i=1(xi−¯x)2
9
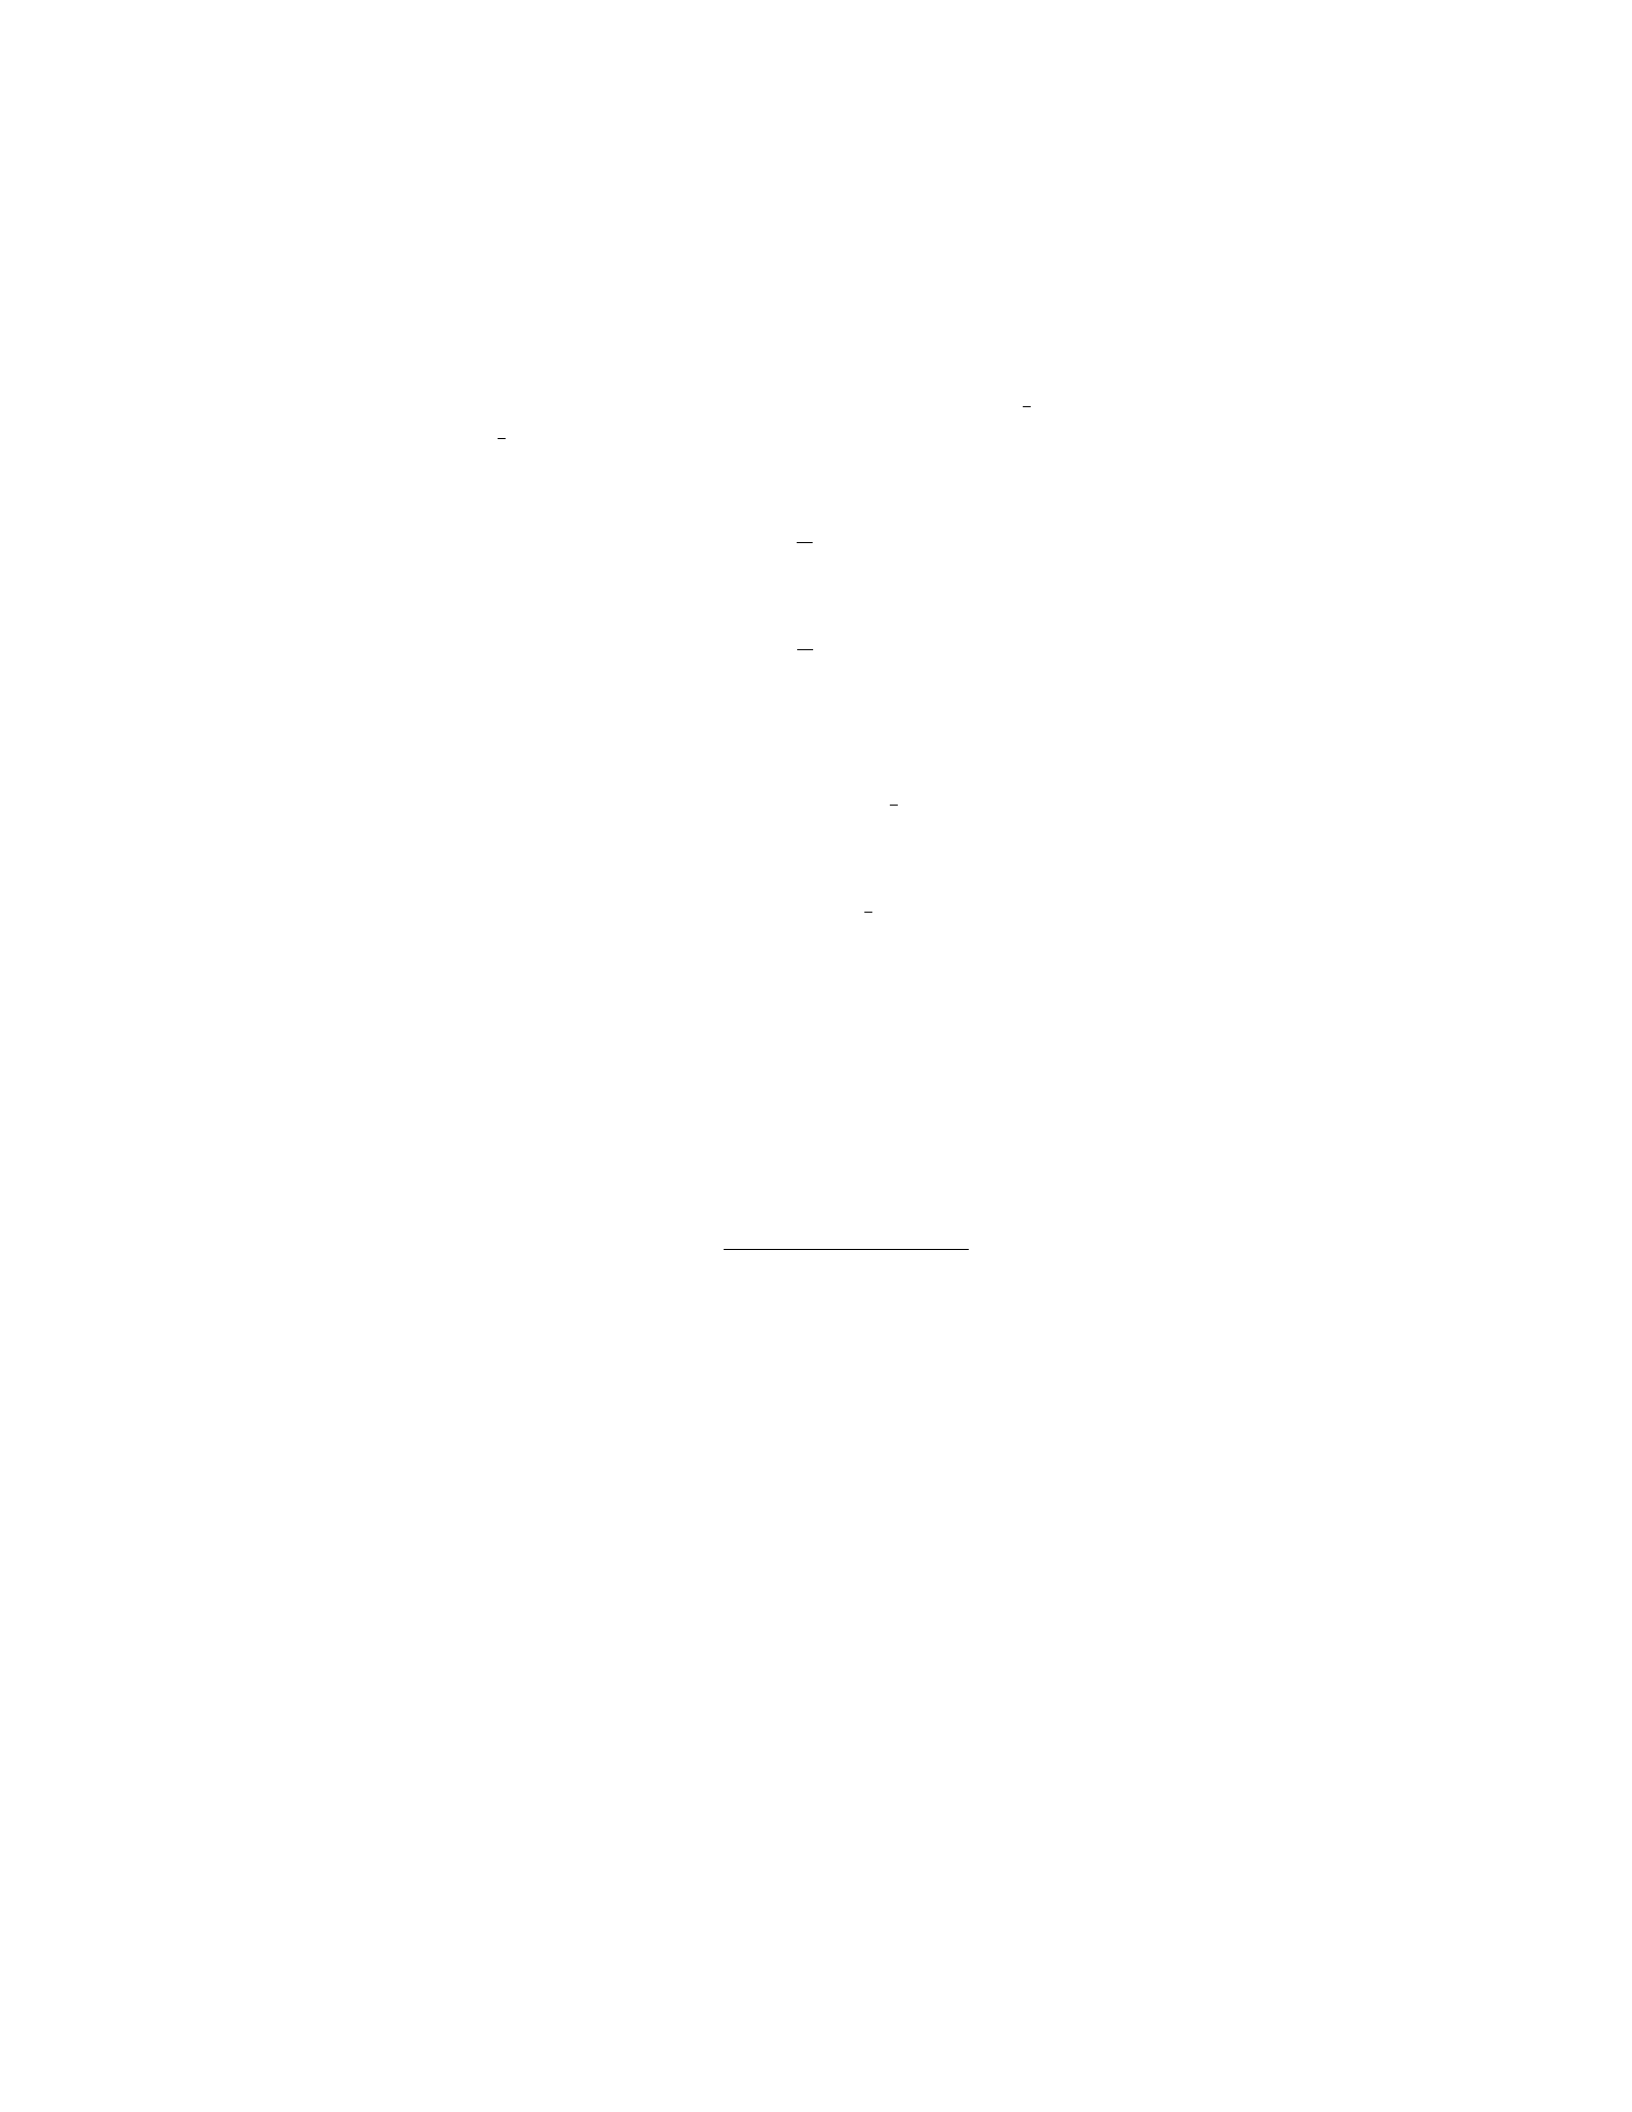
β0= ¯y−β1·¯x
where ¯xand ¯yare the means of the predictor variable park dist and the response
variable pop density respectively.
Step 2: Calculate the means ¯xand ¯y.
¯x=1
n
n
X
i=1
xi
¯y=1
n
n
X
i=1
yi
Step 3: Calculate the necessary sums.
n
X
i=1
xi= sum of all park dist values
n
X
i=1
yi= sum of all pop density values
n
X
i=1
(xi−¯x)(yi−¯y) = sum of(xi−¯x)·(yi−¯y)
n
X
i=1
(xi−¯x)2= sum of(xi−¯x)2
Step 4: Substitute the calculated values into the equations to find β0and
β1.
β1=Pn
i=1(xi−¯x)(yi−¯y)
Pn
i=1(xi−¯x)2
β0= ¯y−β1·¯x
Step 5: Interpret the estimated coefficients β0and β1in the context of the
problem.
Question 11
Question
Consider a dataset containing spatial data on the distribution of a rare plant
species across a region. The dataset includes the coordinates of each observed
plant specimen.
Given this dataset, explain how you would conduct spatial data analysis
and modeling to identify areas with high species richness and potential habitat
areas for the rare plant species. Make sure to describe the steps involved in the
process.
10

Solution
To conduct spatial data analysis and modeling to identify areas with high species
richness and potential habitat areas for the rare plant species, you can follow
the steps outlined below:
Step 1: Data Preprocessing - Import the spatial dataset containing the
coordinates of the observed plant specimens. - Convert the dataset into a spatial
points dataset.
Step 2: Exploratory Data Analysis - Conduct exploratory data anal-
ysis to understand the spatial distribution of the plant specimens. - Create
basic visualizations such as scatter plots or density plots to visualize the spatial
patterns.
Step 3: Spatial Autocorrelation Analysis - Perform spatial autocorre-
lation analysis to determine if there is a spatial pattern in the distribution of
the plant species. - Use tools like Moran’s I or Geary’s C to quantify spatial
autocorrelation.
Step 4: Species Richness Analysis - Use methods like kernel density
estimation or hotspot analysis to identify areas with high species richness. -
Calculate species richness indices for different spatial units (e.g., grid cells) to
identify hotspots.
Step 5: Habitat Suitability Modeling - Utilize habitat suitability mod-
eling techniques such as MaxEnt, GAM, or ENFA to predict potential habitat
areas for the rare plant species. - Use environmental variables (e.g., tempera-
ture, soil type) as predictors in the modeling process.
Step 6: Model Validation - Validate the habitat suitability model using
techniques like cross-validation or independent validation. - Assess the accuracy
of the model in predicting known occurrences of the rare plant species.
Step 7: Spatial Prediction - Generate spatial predictions of potential
habitat areas based on the habitat suitability model. - Map the predicted habi-
tat areas to visualize the potential distribution of the rare plant species across
the region.
By following these steps, you can effectively conduct spatial data analysis
and modeling to identify areas with high species richness and potential habitat
areas for the rare plant species.
Question 12
Question
Suppose you are given a dataset with spatial coordinates for various cities in a
country. You are interested in analyzing the spatial distribution of population
density across these cities. Develop a spatial model to predict the population
density at a new location based on the population densities of neighboring cities.
11
Solution
To develop a spatial model for predicting population density at a new location
based on neighboring cities, we can use spatial interpolation techniques. One
common technique is Inverse Distance Weighting (IDW) interpolation.
Step 1: Define the Problem We want to predict the population density
at a new location using the population densities of neighboring cities. This
involves estimating the population density at the new location based on the
known values at surrounding locations.
Step 2: Select Neighboring Cities Identify the neighboring cities sur-
rounding the new location for which population density values are known. These
neighboring cities will be used to estimate the population density at the new
location.
Step 3: Calculate Weights Calculate the weights for each neighboring
city based on their distances from the new location. Closer cities should have
more influence on the prediction than farther cities. One common method is to
use inverse distance weighting, where the weight for each city is determined by
the inverse of the distance to that city.
Step 4: Perform Interpolation Use the calculated weights and popula-
tion densities of neighboring cities to predict the population density at the new
location. The predicted value can be calculated as a weighted average of the
neighboring city population densities, where the weights are based on distance.
Step 5: Validate the Model Validate the spatial model by comparing
the predicted population density at known locations with the actual values.
Use statistical measures such as Root Mean Square Error (RMSE) to assess the
accuracy of the model.
Step 6: Apply the Model Once the model is validated, apply it to predict
population density at new locations where the actual values are unavailable.
Monitor the model performance and make adjustments as needed based on the
prediction accuracy.
Question 13
Question
Let X1, X2, . . . , Xnbe a random sample from a bivariate normal distribution
with means µ1= 2, µ2= 3, variances σ2
1= 4, σ2
2= 9, and correlation coefficient
ρ= 0.5. Compute the 95
Solution
Step 1: Compute the sample correlation coefficient rusing the formula
r=Pn
i=1(X1i−¯
X1)(X2i−¯
X2)
qPn
i=1(X1i−¯
X1)2Pn
i=1(X2i−¯
X2)2
12
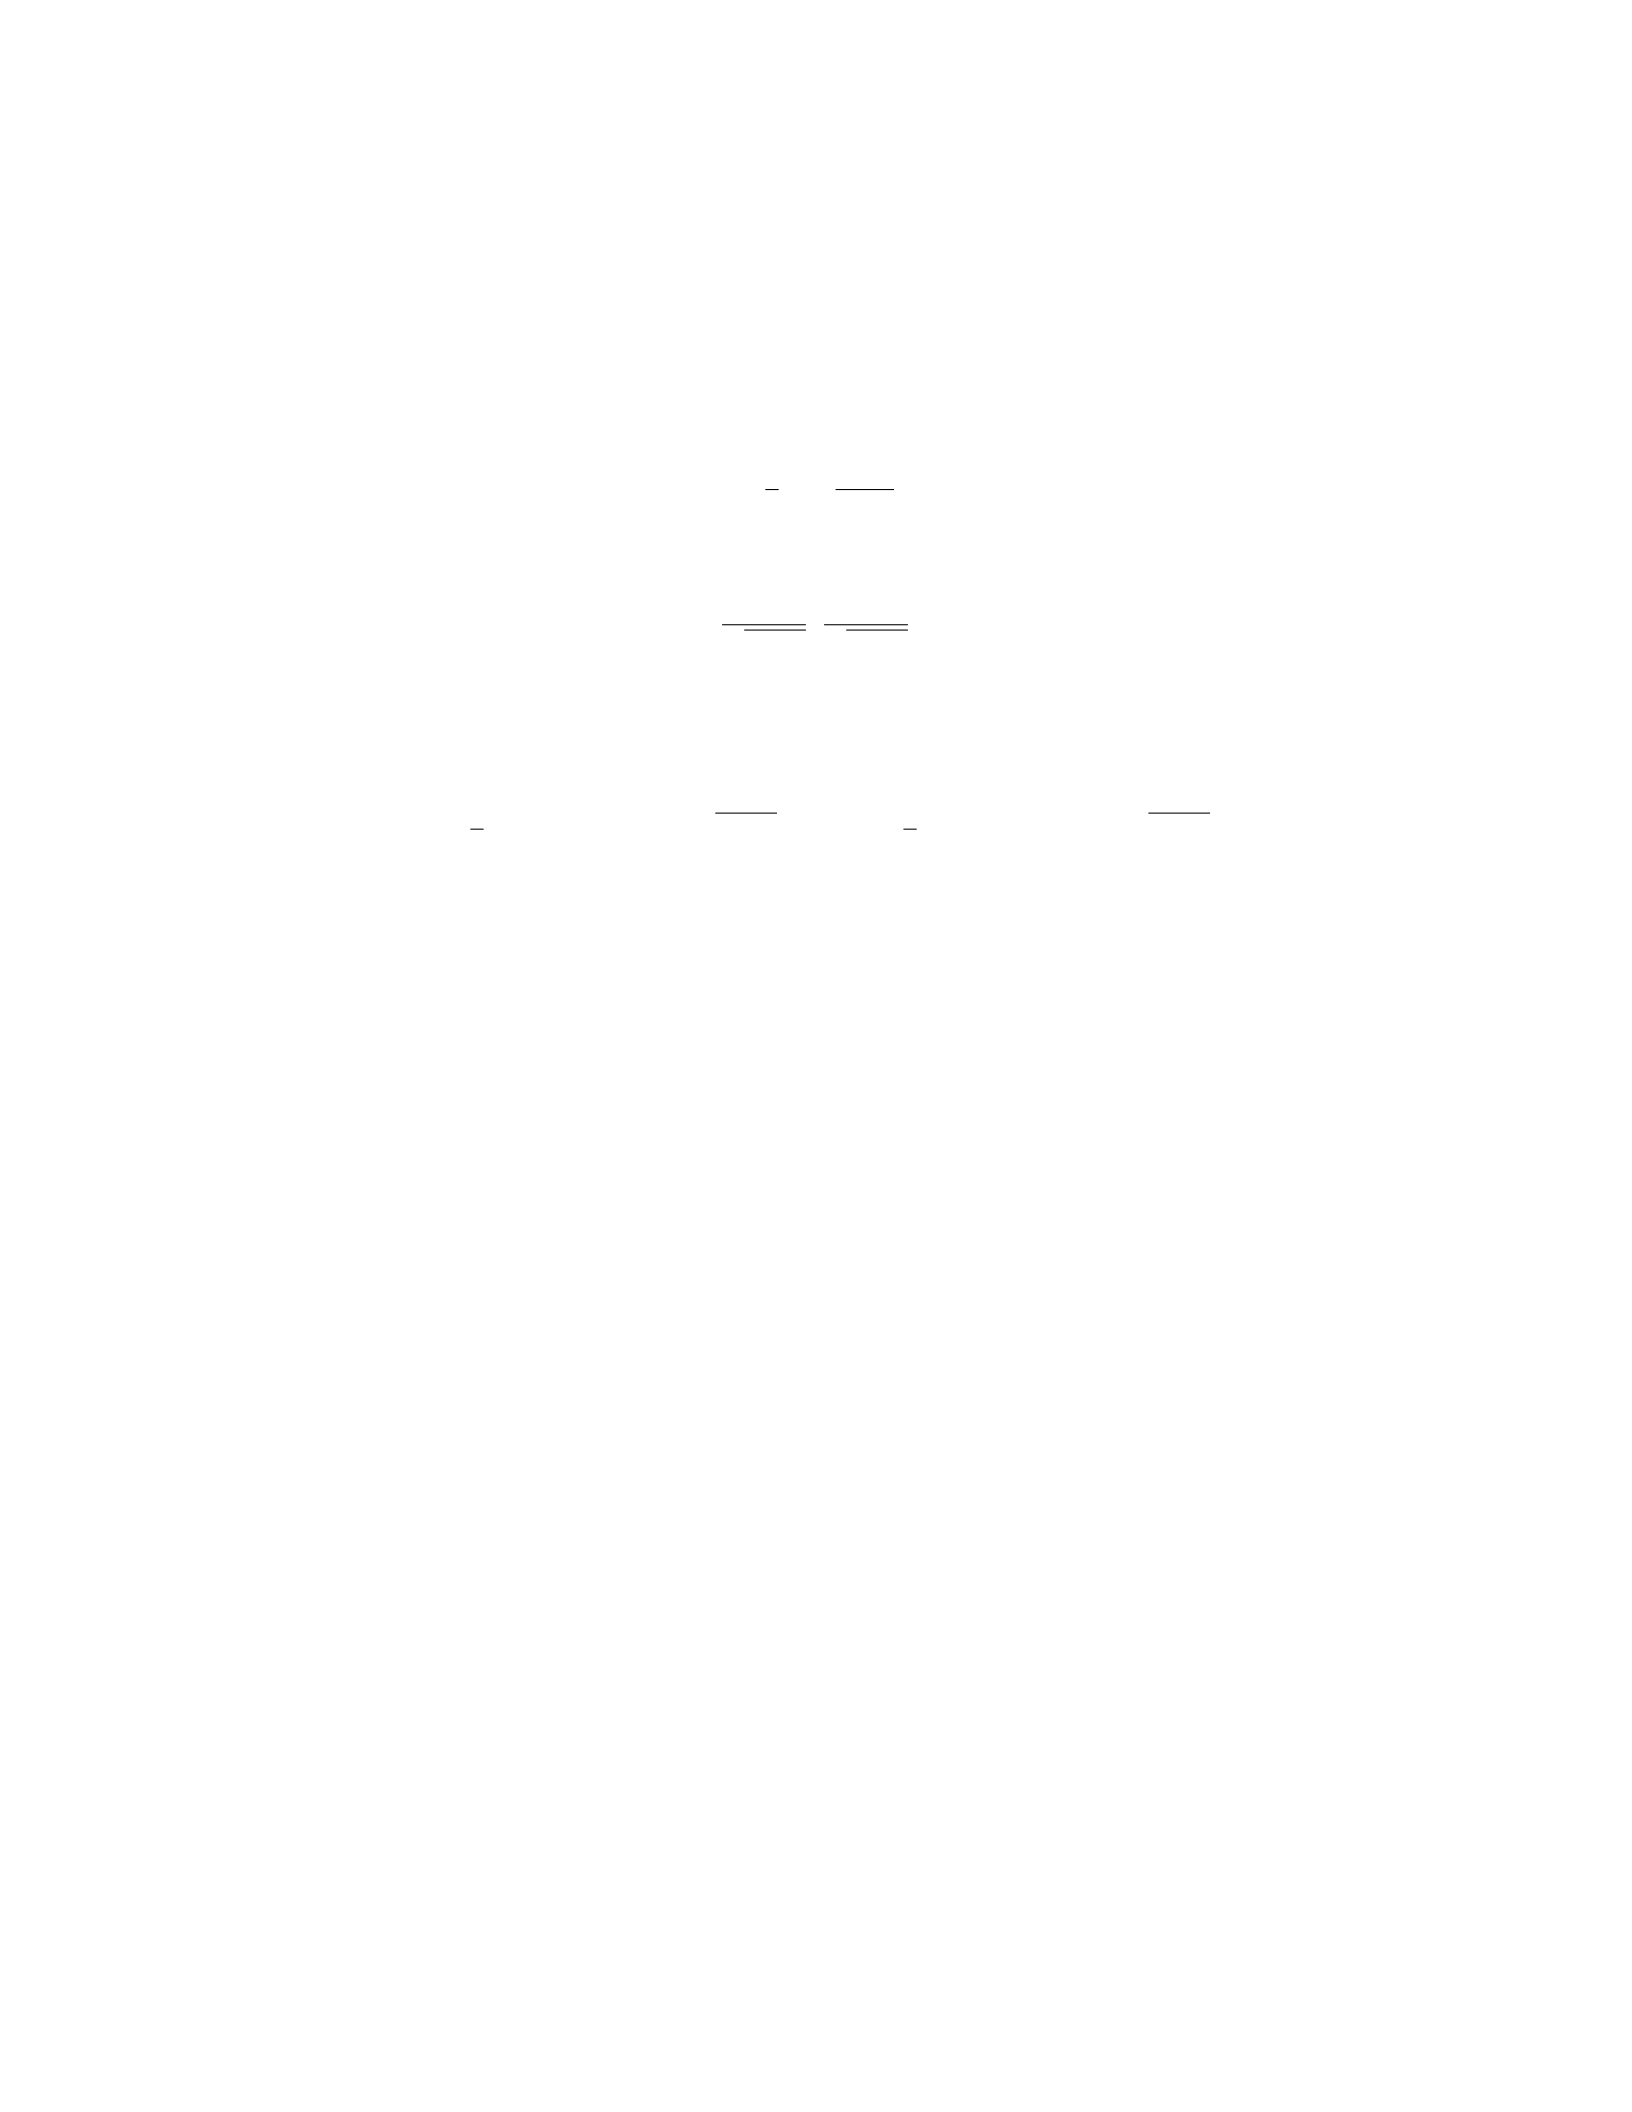
where ¯
X1and ¯
X2are the sample means.
Step 2: The sampling distribution of the sample correlation coefficient r
can be approximated by a normal distribution, which can be transformed using
Fisher’s z-transformation:
z=1
2ln 1 + r
1−r
Step 3: Compute the 95
z
√n−3,z
√n−3
Step 4: Transform the confidence interval for zback to the original scale
to obtain the confidence interval for the correlation coefficient rby using the
inverse z-transformation:
tanh 1
2(ln(1 + r)−zα/2/√n−3),tanh 1
2(ln(1 + r) + zα/2/√n−3)
Step 5: Substitute the sample correlation coefficient r, the sample size n,
and the value of zα/2for a 95
Question 14
Question
Let Z(s) = X(s) + Y(s) be a spatial process defined on a rectangular region
D⊂R2, where X(s) and Y(s) are independent Gaussian processes with means
0 and variances σ2
Xand σ2
Yrespectively. Calculate the variance of Z(s) in terms
of σ2
Xand σ2
Y.
Solution
Step 1: First, recall that the variance of a sum of two random variables is equal
to the sum of their variances if the random variables are independent.
Step 2: Since X(s) and Y(s) are independent Gaussian processes, we have
V ar[Z(s)] = V ar[X(s)] + V ar[Y(s)].
Step 3: Given that V ar[X(s)] = σ2
Xand V ar[Y(s)] = σ2
Y, we can substitute
these values into the equation.
Step 4: Therefore, the variance of Z(s) is:
V ar[Z(s)] = σ2
X+σ2
Y
Step 5: Thus, the variance of Z(s) in terms of σ2
Xand σ2
Yis σ2
X+σ2
Y.
13

Question 15
Question
Consider a dataset containing information on the locations and population den-
sities of various cities in a country.
A researcher wants to analyze the spatial patterns of population density
using spatial data analysis and modeling techniques.
Explain how the researcher can approach this analysis, including the steps
involved in preprocessing the data and selecting the appropriate spatial analysis
techniques.
Solution
To analyze the spatial patterns of population density in the dataset, the re-
searcher can follow these steps:
Step 1: Data Preprocessing - Clean and preprocess the dataset by re-
moving any missing or erroneous data. - Convert the location data (latitude
and longitude) into spatial coordinates or a spatial object. - Normalize the
population density values to account for any scale differences.
Step 2: Exploratory Spatial Data Analysis (ESDA) - Conduct ex-
ploratory spatial data analysis to examine the spatial distribution of population
density. - Calculate global spatial autocorrelation measures, such as Moran’s I,
to determine if there is spatial clustering or dispersion of population density. -
Create spatial plots, such as spatial maps or spatial correlograms, to visualize
spatial relationships.
Step 3: Spatial Interpolation - Use spatial interpolation techniques, such
as kriging or inverse distance weighting, to estimate population density values
at unsampled locations. - Evaluate the accuracy of the spatial interpolation by
comparing the interpolated values with observed values.
Step 4: Spatial Regression Modeling - Perform spatial regression analy-
sis to model the relationship between population density and relevant covariates,
such as land use types or infrastructure. - Consider spatial autocorrelation in
the regression model, using techniques like spatial lag or spatial error models.
Step 5: Cluster Analysis - Apply cluster analysis methods, such as spatial
clustering algorithms or hot spot analysis, to identify spatial clusters of high
or low population density. - Evaluate the statistical significance of identified
clusters using appropriate tests.
By following these steps and applying spatial data analysis and modeling
techniques, the researcher can gain valuable insights into the spatial patterns of
population density in the dataset.
14

Question 16
Question
Let X1and X2be two independent spatial processes with covariance functions
γ1(h) and γ2(h), respectively. Consider the linear combination Y=aX1+bX2,
where aand bare constants. Determine the covariance function γY(h) for the
process Yin terms of γ1(h), γ2(h), a, and b.
Solution
A spatial process Z(s) has a covariance function γ(s, t) defined as γ(s, t) =
Cov[Z(s), Z(t)] for all locations sand tin the domain of the process.
Given two independent spatial processes X1and X2with covariance func-
tions γ1(h) and γ2(h), respectively, the covariance function of the linear combi-
nation Y=aX1+bX2can be determined as follows:
Step 1: Calculate the covariance function of YThe covariance function
of Yis defined as:
γY(h) = Cov[Y(s), Y (t)]
=Cov[aX1(s) + bX2(s), aX1(t) + bX2(t)]
=a2Cov[X1(s), X1(t)] + b2Cov[X2(s), X2(t)]
+abCov[X1(s), X2(t)] + abCov[X2(s), X1(t)]
Step 2: Simplify the expression using the covariance functions
γ1(h)and γ2(h) By substituting the covariance functions γ1(h) and γ2(h) for
Cov[X1(s), X1(t)] and Cov[X2(s), X2(t)], and noting that X1and X2are inde-
pendent processes:
γY(h) = a2γ1(h) + b2γ2(h)
Therefore, the covariance function of the linear combination Y=aX1+bX2
is γY(h) = a2γ1(h) + b2γ2(h).
Question 17
Question
Consider a dataset containing the locations of earthquakes recorded over a year
in a particular region. The dataset consists of latitude and longitude values for
each earthquake. You are tasked with analyzing this spatial data to identify
any patterns or clustering of earthquakes. Describe a suitable spatial analysis
technique for this task and explain how you would apply it to the dataset.
Solution
Step 1: One suitable spatial analysis technique for analyzing the distribution of
earthquakes is the Kernel Density Estimation (KDE) method.
15

Step 2: To apply the KDE method to the earthquake dataset, follow these
steps:
1. Data Preprocessing: Load the dataset containing the latitude and lon-
gitude values of each earthquake.
2. Density Estimation: For each earthquake location, create a small,
smooth circular or elliptical ”kernel” around it. The KDE method cal-
culates the density of earthquakes at any given point by summing up the
influence of all kernels placed on that point.
3. Bandwidth Selection: Choose an appropriate bandwidth parameter
that controls the size of the kernels. A larger bandwidth results in a
smoother density estimation, while a smaller bandwidth captures more
localized patterns.
4. Visualization: Generate a heatmap or contour plot to visualize the KDE
results. Areas with higher density values indicate regions with a higher
frequency of earthquakes.
5. Interpretation: Analyze the KDE output to identify any clustering or
spatial patterns in earthquake occurrences. Pay attention to hotspots or
areas with significantly higher density values, as they may indicate areas
of high seismic activity.
By following these steps and applying the Kernel Density Estimation method
to the earthquake dataset, you can effectively analyze the spatial distribution
of earthquakes and identify any patterns or clustering present in the data.
Question 18
Question
Consider a dataset containing spatial coordinates and pollution levels at various
locations in a city. You are tasked with analyzing the spatial distribution of
pollution levels and creating a model to predict pollution levels at unmeasured
locations.
Given the dataset, describe the steps you would take to analyze the spatial
distribution of pollution levels and develop a model for predicting pollution
levels.
Solution
To analyze the spatial distribution of pollution levels and create a model for
predicting pollution levels at unmeasured locations, we can follow these steps:
Step 1: **Exploratory Data Analysis (EDA)** - Begin by performing ex-
ploratory data analysis to understand the characteristics of the dataset. - Ex-
amine summary statistics, distribution of pollution levels, and spatial patterns.
16

- Create visualizations such as scatter plots, histograms, and spatial maps to
identify trends and patterns in the data.
Step 2: **Spatial Autocorrelation Analysis** - Conduct spatial autocorre-
lation analysis to determine if pollution levels exhibit spatial dependence. -
Calculate Moran’s I statistic to assess the degree of spatial autocorrelation in
pollution levels. - Interpret the Moran’s I value to understand the spatial pat-
tern of pollution levels (e.g., clustered, dispersed, random).
Step 3: **Spatial Interpolation** - Use spatial interpolation techniques (e.g.,
Inverse Distance Weighting, Ordinary Kriging) to interpolate pollution levels at
unmeasured locations. - Compare different interpolation methods and select the
most suitable one based on validation metrics and the spatial characteristics of
pollution levels.
Step 4: **Spatial Regression Modeling** - Develop a spatial regression
model to predict pollution levels based on various spatially explicit predictors
(e.g., distance to highways, land use characteristics). - Incorporate spatial au-
tocorrelation terms (e.g., spatial lag, spatial error) to account for spatial depen-
dence in the data. - Evaluate the model’s performance using metrics such as
R-squared, AIC, and cross-validation.
Step 5: **Model Validation and Interpretation** - Validate the spatial re-
gression model by checking for assumptions violations and model fit. - Interpret
the coefficients of the model to understand the relationships between predictors
and pollution levels. - Use diagnostic tests to assess model residuals and identify
areas for model improvement.
By following these steps, we can effectively analyze the spatial distribution
of pollution levels and develop a predictive model for estimating pollution levels
at unmeasured locations.
Question 19
Question
For a study on urban land use, a researcher collected spatial data on population
density, average income, and land value for different neighborhoods in a city.
The researcher wants to develop a regression model to predict land value based
on population density and average income. Given the spatial nature of the
data, explain how the researcher can account for spatial autocorrelation in the
modeling process.
Solution
To account for spatial autocorrelation in the modeling process, the researcher
can use spatial regression techniques that consider the spatial relationships be-
tween observations. One common approach is to use spatial lag models or spatial
error models.
17

Step 1: Spatial Lag Model A spatial lag model includes a spatially lagged
dependent variable to capture the impact of neighboring observations on each
other. The model can be represented as:
y=ρW y +Xβ +ε
where: - yis the dependent variable (land value), - ρis the spatial auto-
correlation coefficient, - Wis a spatial weights matrix representing the spatial
relationships between observations, - Xis a matrix of independent variables
(population density, average income), - βis a vector of coefficients, - εis the
error term.
Step 2: Spatial Error Model A spatial error model assumes that the
errors in the regression model are spatially correlated. The model can be rep-
resented as:
y=Xβ +λW ε
where: - y,X, and βhave the same meanings as in the spatial lag model, -
λis a parameter that captures the spatial autocorrelation in the error term, - ε
is the error term.
Step 3: Moran’s I Test Before choosing between a spatial lag model
and a spatial error model, the researcher should conduct a Moran’s I test to
assess the presence of spatial autocorrelation in the data. If the Moran’s I test
indicates significant spatial autocorrelation, the researcher can proceed with
fitting a spatial regression model.
By using spatial regression techniques like the spatial lag model or spatial
error model, the researcher can effectively account for spatial autocorrelation in
the modeling process when analyzing urban land use data.
Question 20
Question
Consider a dataset consisting of the locations of 100 bus stops in a city, repre-
sented by their latitude and longitude coordinates. You are tasked with analyz-
ing the spatial distribution of these bus stops to identify any clustering patterns
that may exist. Explain how you would approach this spatial data analysis and
modeling problem.
Solution
To analyze the spatial distribution of the bus stops and identify clustering pat-
terns, we can follow these steps:
Step 1: Data Preparation - Obtain the dataset containing the latitude
and longitude coordinates of the bus stops. - Check for any missing or erroneous
data points and clean the dataset if necessary. - Consider transforming the
coordinates into a spatial object format suitable for analysis.
18

Step 2: Exploratory Data Analysis (EDA) - Conduct exploratory data
analysis by plotting the bus stop locations on a map to visualize the spatial
distribution. - Use spatial visualization techniques such as heat maps or scatter
plots to identify any clustering patterns. - Calculate basic descriptive statistics
such as mean center, standard distance, and spatial autocorrelation to gain
insights into the data distribution.
Step 3: Spatial Analysis Techniques - Apply spatial analysis techniques
such as cluster analysis (e.g., K-means clustering, DBSCAN) to identify specific
clusters of bus stops based on their proximity. - Utilize spatial statistics tools
to analyze the spatial autocorrelation and spatial patterns of the bus stop lo-
cations. - Consider performing point pattern analysis to determine if the bus
stops exhibit any significant clustering or dispersion patterns.
Step 4: Spatial Modeling - Develop spatial models to predict the likeli-
hood of new bus stops being located in certain areas based on existing spatial
patterns. - Use geostatistical modeling techniques to interpolate and predict
the spatial distribution of bus stops across the city. - Validate the spatial mod-
els using cross-validation techniques and assess their accuracy in predicting bus
stop locations.
By following these steps, we can effectively analyze the spatial distribution
of bus stops and model clustering patterns to inform urban planning and trans-
portation decision-making processes.
Question 21
Question
Consider a dataset consisting of geographical coordinates (latitude and longi-
tude) of 100 different locations. The dataset also includes a continuous variable
representing the temperature at each location.
If you were to model the relationship between temperature and location
coordinates, discuss the steps you would take for spatial data analysis and mod-
eling.
Solution
To model the relationship between temperature and location coordinates, we
can follow these steps for spatial data analysis and modeling:
Step 1: Data Exploration - Explore the dataset by plotting the temper-
ature values on a map using latitude and longitude coordinates. - Check for
any spatial patterns or clusters in the data that might indicate a relationship
between temperature and location.
Step 2: Spatial Autocorrelation Analysis - Conduct spatial autocorre-
lation analysis to determine if there is any spatial dependence between tempera-
ture values at different locations. - Use tools like Moran’s I statistic to quantify
spatial autocorrelation and assess its significance.
19

Step 3: Spatial Interpolation - Use spatial interpolation techniques (such
as Kriging or Inverse Distance Weighting) to estimate temperature values at
locations where data is missing or incomplete. - Interpolated values can help
fill in gaps and provide a more complete spatial dataset for modeling.
Step 4: Spatial Regression Modeling - Perform spatial regression anal-
ysis to model the relationship between temperature and location coordinates.
- Account for spatial dependencies in the data by including spatial weights in
the regression model. - Evaluate the model’s performance using metrics like
R-squared, AIC, BIC, etc.
Step 5: Model Validation - Validate the spatial regression model by
checking for spatial autocorrelation in the residuals. - Use cross-validation tech-
niques to assess the model’s predictive accuracy and generalizability.
Step 6: Interpretation and Inference - Interpret the results of the spa-
tial regression model to understand how temperature is influenced by location
coordinates. - Draw meaningful inferences about the relationship between tem-
perature and spatial factors based on the model output.
Question 22
Question
Consider a dataset containing information about housing prices in a city, with
spatial coordinates for each house. You are tasked with performing spatial data
analysis and modeling to predict housing prices in a new area of the city based
on the available data.
Explain the steps you would take to: 1. Clean and preprocess the data. 2.
Explore the spatial distribution of housing prices. 3. Build a spatial regression
model to predict housing prices in the new area.
Solution
1. Clean and preprocess the data: Step 1: Check for missing values and
outliers in the dataset. Remove or impute missing values, and address any
outliers appropriately.
Step 2: Standardize or normalize numerical features in the dataset to ensure
that all variables are on a similar scale and to improve model performance.
Step 3: Encode categorical variables using techniques like one-hot encoding
to convert them into a numerical format that can be used for modeling.
2. Explore the spatial distribution of housing prices: Step 1: Visual-
ize the spatial distribution of housing prices using techniques like scatter plots
or heat maps to identify any patterns or trends.
Step 2: Conduct spatial autocorrelation analysis to determine if housing
prices exhibit spatial dependence, which is crucial for spatial modeling.
Step 3: Use spatial interpolation methods, such as kriging or inverse dis-
tance weighting, to estimate housing prices at unsampled locations based on
20

surrounding data points.
3. Build a spatial regression model to predict housing prices: Step
1: Select an appropriate spatial regression model, such as spatial lag or spatial
error models, that accounts for spatial autocorrelation in the data.
Step 2: Split the dataset into training and testing sets to evaluate the model’s
performance.
Step 3: Fit the spatial regression model to the training data and evaluate
its predictive ability using metrics like R-squared, AIC, or BIC.
Step 4: Validate the model by comparing predicted housing prices to actual
values in the testing set and assess the model’s accuracy and robustness.
By following these steps, you can effectively clean, explore, and model spatial
data to predict housing prices in a new area of the city.
Question 23
Question
A city wants to analyze the spatial distribution of air quality across its neighbor-
hoods to identify areas with poor air quality that may require intervention. The
city collects air quality data from various monitoring stations located through-
out the city. Describe the steps involved in conducting spatial data analysis and
modeling to achieve this goal.
Solution
To analyze the spatial distribution of air quality across neighborhoods, the city
can follow these steps:
Step 1: Data Collection - Collect air quality data from monitoring stations
located throughout the city. - Ensure the data includes variables such as pol-
lutant concentrations, timestamps, and geographical coordinates of monitoring
stations.
Step 2: Data Preprocessing - Clean the data by addressing missing values,
outliers, and inconsistencies. - Perform data transformations if required, such
as normalization or standardization.
Step 3: Spatial Data Analysis - Use Geographic Information System (GIS)
tools to visualize the spatial distribution of air quality data on a map. - Calculate
descriptive statistics to understand the central tendency and variability across
neighborhoods.
Step 4: Spatial Autocorrelation Analysis - Conduct spatial autocor-
relation analysis to identify if air quality values in nearby neighborhoods are
similar (positive spatial autocorrelation) or dissimilar (negative spatial auto-
correlation). - Test for statistical significance using measures like Moran’s I or
Geary’s C.
Step 5: Spatial Data Modeling - Develop a spatial regression model to
analyze the relationship between air quality and potential explanatory variables
21

such as proximity to industrial areas, traffic volume, or vegetation cover. -
Use techniques like Ordinary Least Squares (OLS) or Geographically Weighted
Regression (GWR) to account for spatial heterogeneity.
Step 6: Prediction and Visualization - Use the spatial regression model
to make predictions of air quality across all neighborhoods. - Visualize the
predicted air quality values on a map to identify areas with poor air quality
that may require intervention.
By following these steps, the city can effectively analyze the spatial distribu-
tion of air quality across neighborhoods and make informed decisions to improve
air quality in the city.
Question 24
Question
Let Yirepresent the number of reported crimes in a specific region i, and let
Xirepresent the population density in the same region. A spatial data anal-
ysis is conducted to model the relationship between the number of crimes and
population density using the following model:
Yi=β0+β1Xi+ϵi
where β0and β1are regression coefficients, and ϵirepresents the error term.
Given the spatial autocorrelation present in the data, how would you modify
the model to account for spatial effects?
Solution
Step 1: Incorporating a Spatial Lag of the Dependent Variable
To account for spatial autocorrelation, we can modify the model by incorpo-
rating a spatial lag of the dependent variable Yi. The modified model is as
follows:
Yi=β0+β1Xi+ρW Y +ϵi
where Wis a spatial weight matrix, ρis a spatial autoregressive coefficient,
and W Y represents the spatial lag of Yi.
Step 2: Assessing Model Fit
We can use model fit statistics such as Akaike Information Criterion (AIC) or
Bayesian Information Criterion (BIC) to compare the original model without
spatial effects to the modified model with spatial effects. Lower values of AIC
or BIC indicate better model fit.
Step 3: Spatial Diagnostic Tests
Performing spatial diagnostic tests such as Moran’s I test or Geary’s C test can
help in examining the presence of spatial autocorrelation in the residuals of the
model. If significant spatial autocorrelation is detected, it confirms the need to
include spatial effects in the model.
22

Step 4: Spatial Weight Matrix Specification
Careful selection of the spatial weight matrix Wis crucial in capturing the spa-
tial connectivity between regions. Common weight matrix specifications include
rook, queen, distance-based weights, or contiguity-based weights.
Step 5: Interpreting Spatial Autoregressive Coefficient (ρ)
The spatial autoregressive coefficient ρcaptures the spatial dependency in the
response variable. A positive ρindicates positive spatial autocorrelation, mean-
ing that regions with high crime rates are surrounded by regions with high crime
rates as well. Conversely, a negative ρsuggests negative spatial autocorrelation.
By following these steps and modifying the original model to account for
spatial effects, we can build a spatial data analysis model that better captures
the spatial patterns and relationships in the data.
Question 25
Question
Consider a dataset containing spatial data on the distribution of a species across
a region. The dataset includes the latitude and longitude coordinates of each
observation, as well as information on the population density of the species at
each location.
Using spatial data analysis and modeling techniques, discuss how you would
approach the following tasks: 1. Visualizing the spatial distribution of the
species population density. 2. Assessing the spatial autocorrelation of the pop-
ulation density values. 3. Building a spatial regression model to predict the
population density at unobserved locations. 4. Validating the spatial regression
model.
Solution
1. Visualizing the spatial distribution of the species population den-
sity: Step 1: One way to visualize the spatial distribution of the species popula-
tion density is to create a spatial density plot. This can be done by plotting the
population density values on a map of the region, with color-coding to represent
different density levels.
Step 2: Another option is to create a spatial interpolation map using tech-
niques such as kriging or inverse distance weighting to predict population density
values at unobserved locations based on the observed data points.
2. Assessing the spatial autocorrelation of the population density
values: Step 1: Calculate the spatial autocorrelation of the population density
values using a spatial autocorrelation statistic such as Moran’s I or Geary’s C.
These statistics measure the degree of similarity between neighboring locations
in terms of their population density values.
Step 2: Interpret the spatial autocorrelation statistic to determine whether
23

there is spatial clustering (positive autocorrelation) or dispersion (negative au-
tocorrelation) of the population density values across the region.
3. Building a spatial regression model to predict the population
density at unobserved locations: Step 1: Choose an appropriate spatial
regression model such as spatial autoregressive model, spatial error model, or
spatial lag model based on the characteristics of the dataset and the results of
the spatial autocorrelation analysis.
Step 2: Fit the chosen spatial regression model using the observed population
density values and the spatial coordinates of each location as predictors. This
will allow you to estimate the relationship between the population density and
the spatial predictors.
4. Validating the spatial regression model: Step 1: Validate the spatial
regression model by assessing its predictive performance using techniques such
as cross-validation, residual analysis, and measures of model fit like R-squared
and root mean square error.
Step 2: Compare the predicted population density values from the spatial
regression model with the observed values to evaluate the model’s accuracy and
generalization to unobserved locations. Adjust the model if necessary based on
the validation results.
Question 26
Question
Consider a dataset consisting of spatial data points representing the elevation
above sea level at various locations on a mountain. The dataset contains some
outliers that need to be identified and removed before conducting any spatial
analysis. Explain how you would approach this task using spatial data analysis
and modeling techniques.
Solution
To identify and remove outliers in spatial data representing elevation above sea
level on a mountain, we can follow these steps:
Step 1: Visualize the data using a scatter plot or a spatial map to identify
any unusual patterns, gaps, or extreme values that may indicate outliers.
Step 2: Calculate summary statistics such as mean, median, standard devi-
ation, and range to get a better understanding of the distribution of elevation
values.
Step 3: Perform spatial autocorrelation analysis to identify any spatial pat-
terns or clustering of outlier values. This can be done using techniques such as
Moran’s I or Geary’s C statistics.
Step 4: Use spatial interpolation techniques, such as kriging or inverse dis-
tance weighting, to impute missing values or smooth out extreme values that
may be outliers.
24

Step 5: Apply outlier detection algorithms specific to spatial data, such
as Local Outlier Factor (LOF) or Spatial Significance Detection Algorithm
(SISDA), to identify and flag potential outliers based on their spatial relation-
ships with neighboring data points.
Step 6: Evaluate the identified outliers based on domain knowledge and
decide whether to remove them from the dataset or adjust their values based
on the analysis conducted.
By following these steps, we can effectively identify and deal with outliers
in spatial data representing elevation above sea level on a mountain before
proceeding with any spatial analysis and modeling tasks.
Question 27
Question
Consider a dataset containing information on the population density and average
income of different regions within a country. You are tasked with analyzing the
relationship between population density and average income to understand how
they influence each other.
Using spatial data analysis and modeling techniques, explain how you would
approach this problem.
Solution
To analyze the relationship between population density and average income
using spatial data analysis and modeling techniques, we can follow these steps:
Step 1: Data Collection and Preparation - Collect the spatial dataset
containing information on population density, average income, and the geo-
graphical coordinates of each region. - Preprocess the data by checking for
missing values, outliers, and ensuring the data is in a suitable format for spatial
analysis.
Step 2: Exploratory Data Analysis - Conduct exploratory data analysis
to understand the distribution of population density and average income across
different regions. - Use visualizations such as scatter plots, histograms, and
maps to explore the relationship between the two variables.
Step 3: Spatial Autocorrelation Analysis - Use spatial autocorrelation
analysis to examine whether population density and average income values ex-
hibit spatial clustering or patterns. - Calculate spatial autocorrelation measures
such as Moran’s I to quantify the spatial dependency between the variables.
Step 4: Spatial Regression Modeling - Perform spatial regression model-
ing to analyze the relationship between population density and average income
while accounting for spatial dependencies. - Use techniques such as spatial lag
models or spatial error models to incorporate spatial effects into the regression
analysis.
25
Step 5: Model Evaluation and Interpretation - Evaluate the spatial
regression model to assess its goodness of fit and interpret the coefficients of
the variables. - Examine the spatial autocorrelation of the model residuals to
ensure that there are no remaining spatial patterns.
By following these steps, we can effectively analyze the relationship between
population density and average income using spatial data analysis and modeling
techniques.
Question 28
Question
Consider a dataset consisting of the locations of houses in a neighborhood. The
dataset includes the coordinates of each house (latitude and longitude), as well
as the number of bedrooms and bathrooms in each house.
Given this dataset, perform the following spatial analysis and modeling tasks:
1. Calculate the pairwise Euclidean distances between all pairs of houses in
the dataset.
2. Create a spatial weight matrix using a contiguity-based approach (e.g.,
Queen’s contiguity).
3. Determine if there are any spatial clusters of houses with a higher-than-
average number of bedrooms.
4. Develop a spatial regression model to predict the number of bathrooms in
a house based on its neighbors’ characteristics.
Solution
Step 1: Calculate pairwise Euclidean distances To calculate the pairwise
Euclidean distances between all pairs of houses, we can use the formula for
Euclidean distance in a 2D space:
Euclidean distance = p(x2−x1)2+ (y2−y1)2
where (x1, y1) and (x2, y2) are the coordinates of two houses.
Step 2: Create spatial weight matrix To create a spatial weight matrix
using a contiguity-based approach, we can define neighbors based on the Queen’s
contiguity, which considers houses that share an edge or a vertex as neighbors.
Step 3: Identify spatial clusters To identify spatial clusters of houses
with a higher-than-average number of bedrooms, we can use spatial cluster
analysis techniques such as Getis-Ord Gi* statistic or Local Moran’s I.
Step 4: Develop spatial regression model To develop a spatial regres-
sion model to predict the number of bathrooms in a house based on its neighbors’
characteristics, we can use spatial regression techniques like Spatial Lag or Spa-
tial Error regression models. These models account for spatial autocorrelation
in the data which arises due to the spatial proximity of houses.
26
Question 29
Question
Consider a dataset containing the locations of 100 different species of trees in
a forest. The dataset includes the coordinates (latitude and longitude) of each
tree. You are tasked with analyzing the spatial distribution of these trees and
creating a model to predict the presence of certain species based on environ-
mental variables such as soil type, sunlight exposure, and elevation.
Describe the steps you would take to perform spatial data analysis and
modeling on this dataset. Include the key techniques and considerations involved
in each step.
Solution
To perform spatial data analysis and modeling on the dataset of tree locations
in the forest, the following steps can be taken:
Step 1: Data Preprocessing
Clean the dataset by removing any duplicate or erroneous entries.
Check for missing values in both the tree locations and environmental
variables.
Convert the latitude and longitude coordinates into a suitable coordinate
reference system for spatial analysis.
Step 2: Exploratory Spatial Data Analysis (ESDA)
Use spatial visualization techniques like scatter plots, histograms, and
spatial autocorrelation plots to explore the spatial distribution of tree
species.
Perform hotspot analysis to identify clusters or spatial patterns in the
distribution of certain species.
Step 3: Spatial Statistical Analysis
Conduct spatial autocorrelation analysis to assess the degree of spatial
dependence among the tree species.
Employ spatial regression models to understand the relationship between
the presence of tree species and environmental variables like soil type,
sunlight exposure, and elevation.
Step 4: Model Building
Utilize techniques such as spatial interpolation, kriging, or machine learn-
ing algorithms to predict the presence of tree species at unsampled loca-
tions based on the environmental variables.
27
Evaluate the model performance using metrics like accuracy, precision,
and recall.
Step 5: Model Interpretation and Validation
Interpret the model results to understand the factors influencing the dis-
tribution of tree species in the forest.
Validate the model by comparing the predicted species distribution with
actual field observations.
Question 30
Question
Consider a dataset consisting of temperature measurements at different loca-
tions across a region. The data points are spatially correlated, with higher
temperatures in one location likely corresponding to higher temperatures in
neighboring locations.
Given this dataset, discuss the importance of spatial autocorrelation in spa-
tial data analysis and modeling. Additionally, explain how spatial autocorrela-
tion can impact the reliability and interpretation of statistical inferences drawn
from the dataset.
Solution
Step 1: Importance of Spatial Autocorrelation Spatial autocorrelation
refers to the phenomenon where nearby locations are more likely to have similar
values compared to locations that are farther apart. Understanding the pres-
ence of spatial autocorrelation is crucial in spatial data analysis and modeling
for several reasons: - It allows us to take into account the spatial structure
of the data and incorporate this information into our analysis. - Spatial au-
tocorrelation helps in identifying clusters or patterns in the dataset, providing
insights into underlying processes that may be influencing the observed values.
- Considering spatial autocorrelation can lead to more accurate modeling and
prediction of values at unsampled locations.
Step 2: Impact on Reliability of Statistical Inferences Spatial auto-
correlation can affect the reliability and interpretation of statistical inferences in
the following ways: - Ignoring spatial autocorrelation may lead to biased param-
eter estimates and inflated standard errors, affecting the validity of statistical
tests. - It can violate the assumption of independence of observations, which is
critical for many statistical methods. Failure to account for spatial autocorre-
lation can result in incorrect conclusions about relationships between variables.
- Spatial autocorrelation can influence the spatial distribution of residuals in a
model, impacting the model’s goodness of fit and the accuracy of predictions.
In conclusion, recognizing and addressing spatial autocorrelation in spatial
data analysis is essential for improving the reliability of statistical inferences,
28

enhancing model performance, and gaining a deeper understanding of spatial
processes.
29

