


Twins and Twin Genetics Twins have intrigued human
Twins have intrigued human beings for centuries. The sameness exhibited by twins is
fascinating, although the dissimilarities and manifestation of those differences are often even
more compelling. Numerous literary texts and philosophical publications have drawn inspiration
from and capitalized on the intriguing nature of twins. Some of those works highlight the unique
and uncanny similarities of identical twins (e.g., The Comedy of Errors by William
Shakespeare). In contrast, others emphasize the divergent appearance and behaviors of fraternal
twins (e.g., Twelfth Night by William Shakespeare and biblical accounts of Jacob and Esau in the
Book of Genesis).
Whether identical or fraternal, the defining characteristics of twins have also piqued the
interest of scientists. For one, twins exemplify a form of a ‘natural experiment,’ in which the
degree of genetic and environmental sharing are known or controlled for in varying amounts. In
this way, twins are valuable study subjects when control for genetic background and early
environmental influences is desired. Informed study designs utilize twins to estimate the
contribution of genetic factors to disease, trait, or phenotype variation. Secondly, the biological
and endocrinological processes fostering the twinning process also have great medical and
scientific relevance. Enhanced understanding of the regulatory mechanisms underlying ovarian
function, follicular growth, and maintenance of a multiple gestation pregnancy represent critical
research areas on women’s health and female (in)fertility. Our knowledge of the etiology of the
twinning process has vastly improved in recent years, although a comprehensive understanding
of identical and fraternal twins remains elusive.
Two kinds of twins exist - identical or monozygotic (MZ) twins and fraternal
(nonidentical) or dizygotic (DZ) twins. Both types of twins share prenatal and early

3
environmental influences. The distinction of twin type is based on the number of independently
fertilized zygotes during a single pregnancy; hence, the nomenclature monozygotic (i.e., one
zygote) and dizygotic (i.e., two zygotes). MZ twins result from a postzygotic splitting event of a
single fertilized zygote early in gestation resulting in a separation of cells into two or more
embryos. MZ twins are therefore matched for genetic background. Alternatively, DZ twins derive
from the release of two eggs, which are then independently fertilized by two sperm. Thus, DZ
twins share the same amount of genetic material as ordinary siblings.
The difference in the number of fertilized zygotes dictates whether the twin pair is MZ or
DZ. The universally accepted model for the generation of MZ twins is the ‘fission model,’ which
conceptually defines the splitting of an embryo into two distinct entities within the first two
weeks of development. The stage at which the splitting occurs is thought to determine membrane
anatomy (chorionicity and amnionicity). Though widely adopted, the fission conjecture has been
critically challenged, and alternative models have been proposed (i.e., the ‘fusion model’ – refer
to chapter 2 for more details) [1]. The debate and remaining uncertainty around these hypotheses
reiterate that the biological processes fundamental to the generation of MZ twins are still largely
undetermined.
Regarding DZ twins, much more is understood concerning genetic and biological
mechanisms leading to the development of two independent zygotes. Biologically, DZ twins
arise from mechanisms that operate on the selection of developing ovarian follicles, where two
follicles mature instead of one, releasing two oocytes that are then subsequently fertilized. A
myriad of maternal factors are involved, including genetic disposition, hormonal (dys)regulation
and coordination, as well as anatomical and physiological support. Despite the genetic influence
on DZ twinning, it is still not possible to define the risk of having twins at an individual level.

Knowledge gaps of the twinning process persist, yet it is well understood that there are
distinguishing characteristics in the mechanisms leading to MZ and DZ twins. Also evident is
variation in the occurrence of MZ and DZ twins across worldwide populations. In general, MZ
twinning seems to be a random yet consistent event, occurring in roughly 3 out of every 1000
maternities. Alternatively, rates of DZ twinning seem to fluctuate considerably with geography
and time. Variation in DZ twinning rates have been studied extensively, with the highest rates
observed in Sub-Saharan Africa (~23-40 per 1000 maternities), intermediate rates in Europe
(1020 per 1000 maternities), and the lowest rates occurring in Asia (~5-6 per 1000 maternities)
[2, 3].
The various characteristics of twins and twin genetics are a central theme to this thesis. In
chapter 2, an extensive review of the biology and genetics of MZ and DZ twinning is presented,
highlighting what is known about twinning based on historical observations, epidemiological and
clinical studies, and more recent molecular investigations. Chapter 3 overviews a molecular
genetic analysis of DZ twinning in a large, multigenerational pedigree with multiple mothers of
DZ twins. Chapter 4 utilizes genetic data from globally diverse twin-family populations to
establish the degree of interpopulation genetic similarity using a custom-designed genotyping
microarray, including genetic markers specific to DZ twinning and female fertility.
Twins are representative of the general population as participants in research projects
since they tend to be born in all strata of society [4]. However, the inclusion of twin data into
research projects raises additional questions. For example, to what extent can findings from
genetic association studies of birth weight in singletons be generalized to twins? And can twins
be included to boost sample sizes? Accordingly, chapter 4 focuses on the genetics underlying

5
birth weight, a complex phenotype with maternal and fetal contributions, in twins compared to
singletons.
Increasingly, data collection efforts for twin studies include (nuclear) family members in
addition to the twin pair. Such family-based study designs offer advanced options for research
and provide advantages over population-based approaches. Chapter 5 explores genetic ancestry
estimates in twins and their family members as determined by popular bioinformatic methods.
1.2 The Netherlands Twin Register at Vrije Universiteit
Scientific studies have exploited the differential genetic relatedness between twins by
incorporating them in their designs since the early 1900s [5, 6]. Following the seminal twin
studies, more elaborate study designs have been employed to partition trait variation or disease
susceptibility into genetic and environmental components. The scientific merit of studies
featuring twins was quickly realized, necessitating concerted efforts for gathering genetic and
phenotypic data from twins and their family members.
Twin registries have increasingly become attractive resources for promoting twin and
epidemiological studies by collecting biological samples and longitudinal data. The Netherlands
Twin Register (NTR), maintained by the Department of Biological Psychology at Vrije
Universiteit, is one example among global twin registers. Initiated in 1987 [7], the NTR has
invited twins and their family members to enroll and participate in a wide variety of research
studies related to behavior, development, and health. A primary research goal of the NTR is to
analyze genetic and phenotypic data obtained from twins to disentangle the genetic and
environmental contributions to cognitive and emotional development in childhood and
adolescence as well as adult behavior, health, and well-being.

For more than thirty years [8], the NTR has curated a rich data resource for assessing genetic
and nongenetic trait influences and contributing to gene-finding initiatives for complex human
traits. Since its inception, more than 120,000 twins have enrolled in the twin register with nearly
equal representation of their family members. Most twins and their families have participated in
survey studies, with subsets generously donating some form of biological material. Longitudinal
phenotyping, biological sample collection, and extended pedigrees with multigenerational
representation have enabled research initiatives aimed at gene discovery, modeling causality,
determining genetic inheritance, and studying population genetics.
An ongoing effort of the NTR is to collect biological samples from individuals who have
provided phenotypic information. Whole blood samples are collected from adult twins to
measure metabolic and immunological markers and extract genetic material (DNA and RNA)
used in molecular genetic studies. In addition, adult twins and NTR participants who do not take
part in biobank studies are asked to provide a swab of buccal epithelial cells, a far less invasive
sample collection method. Buccal swabs are also the primary DNA collection method for young
twins, their siblings, and parents. Large-scale sample collection is a primary motivation of the
NTR, for which the scientific benefits are evident, especially when coupled with survey data. For
twin participants themselves, receiving information on their zygosity is an extra incentive.
A primary interest of this thesis is the measurement of genetic variation from extracted DNA
of the supplied biomaterial by NTR participants. Recent technological developments have
enabled the direct measurement of hundreds of thousands of genetic variants at the DNA level at
an affordable cost. The genetic variants, most often single nucleotide polymorphisms (SNPs), can
be directly measured with polymerase chain reaction (PCR), microarray genotyping, or whole-

7
genome sequencing. Regardless of the chosen technology, knowledge of an individual’s genetic
composition is attained.
Creating an extensive database of genetic measures linked with survey responses has
established the NTR as a data-rich resource for studying human traits and diseases. Accordingly,
the NTR has contributed to gene-discovery efforts for a considerable number of human
phenotypes. In many of these studies, the NTR represents a single contribution to a concerted
effort of many population-based twin registers from around the globe. Often, these efforts are
organized by consortia dedicated to unraveling the genetic contributions to a particular trait or
disease.
In this thesis, several aspects of the value of NTR genetic and phenotypic data are discussed.
In chapter 3, a large, multigenerational Dutch pedigree with a rich history of DZ twinning is
investigated using genotype and whole-genome sequence data. In chapter 4, population genetics
of NTR participants are compared to other European ancestry-based populations for which data
are routinely combined via consortia-led projects for gene discovery. In chapter 5, genetic data
and birth weight information from twins enrolled in the NTR, and other worldwide twin registers
were used to conduct a genome-wide association meta-analysis (GWAMA) on birth weight in
twins. In chapter 6, genetic information from NTR participants was utilized to compare
bioinformatic estimates of genetic ancestry in twins and their families.
1.3 The Avera Twin Register – a Midwestern American twin cohort
Twin registers from around the world, especially prominent entities such as the NTR, have
established the immense scientific importance of combined genetic and phenotypic data. The
often-limited geographical scope of twin registers allows for meaningful comparisons of

genetrait associations between and within populations. Thus, an added incentive for establishing
a population-based twin register is the opportunity to contribute to joint genetic analyses for gene
discovery organized by global consortia.
The Avera Institute for Human Genetics (AIHG) in Sioux Falls, South Dakota, established
the Avera Twin Register (ATR) in May of 2016 [9, 10]. The ATR is the first and only twin
register in South Dakota. The primary goal of the ATR is to study the genetic and environmental
influences on health, disease, and complex traits by harnessing the power of longitudinal
biological sample collection and survey correspondence. Although twins and their family
members have enrolled from across all United States regions, a majority come from Midwestern
states, including South Dakota, North Dakota, Minnesota, Iowa, and Nebraska. In addition to
serving as a prime research model for studying health and disease in a regional setting, another
core goal of the ATR is to contribute to consortia-driven large-scale genetic studies focusing on
the genetic underpinnings of complex traits. Furthermore, as a division of the molecular genetics
lab at AIHG, the ATR prioritizes extensions of the twin design with advanced molecular assays
of DNA, human microchimerism [11, 12], epigenetics (e.g., methylation) [13, 14], telomere
repeat mass [15], and the gut microbiome [16, 17].
Chapter 4 assesses the degree of genetic similarity between the Midwestern American
population exemplified by the ATR and global twin-family populations originating from the NTR
and Australia. The work presented in chapter 4 represents the first application of genetic data
collected on enrolled and consented participants of the ATR. Moreover, paired genotypic and
phenotypic data for ATR participants were analyzed in chapter 5 to contribute to a global effort
of gene discovery for birth weight in twins. This application represents the first usage of
phenotypic data collected by the ATR.

9
1.4 The NTR-Avera Collaboration
Large-scale genetic investigations of complex traits have demonstrated the need for a
collaborative research model to achieve the required sample sizes for answering complicated
genetic questions. Often institutions/facilities are not fully equipped with both the laboratory
instrumentation to systematically measure genetic variation and the computational equipment
necessary to process and analyze the generated data. The disparity is exacerbated by the need for
specialized knowledge and skill sets relevant to the laboratory setting and downstream
bioinformatic/statistical analyses. Leveraging their expertise in wet-lab and dry-lab application,
respectively, the AIHG and the NTR initiated collaboration in 2008 with the establishment of a
formal agreement in May 2015. To this end, the molecular genetics laboratory at the AIHG has
supplied the expertise and infrastructure necessary for performing a multitude of molecular
genetic experiments.
An essential component of the collaborative agreement between the AIHG and the NTR is
generating and analyzing genetic data and combining these data with health, lifestyle, and
behavioral assessments to further gene discovery and contribute to projects aimed at improving
physical and mental health. Microarray technologies have been the preferred method for directly
measuring genetic variation. For the most part, the allure is due to the cost-effectiveness of
microarrays compared to whole-genome sequencing. While not as comprehensive as
sequencingbased approaches, microarrays provide genetic information in a more selective
manner. Microarrays directly assay sites or regions of the human genome that are known to vary
among individuals. The AIHG has offered the capability of generating genotype data with three
primary microarray platforms, namely Affymetrix SNP 6.0, Affymetrix Axiom, and the Illumina

Global Screening Array (GSA). Data from all three genotyping platforms were fundamental to
NTR and ATR studies presented in chapters 3, 4, 5, and 6.
The NTR-Avera collaborative genotyping initiative has been extremely successful since its
inception. The productive partnership has inspired fruitful contributions to several large-scale
association studies spanning various human traits and disorders. Examples include aggression
[18, 19], attention problems [20-25], brain structure and volume [26-29], depression [30-34],
exercise behavior [35, 36], female fertility and twinning [37, 38], intelligence [39], substance use
[40-42], personality [43], and a variety of others [44-47].
Exploiting the pertinent expertise of scientists at the AIHG and the NTR, the NTR-Avera
partnership further enabled the design of customized DNA microarrays. The arrays were
designed to enhance coverage of the human genome by utilizing suitable whole-genome
reference sequences obtained from the Genome of the Netherlands project [48]. Additionally, the
custom genotyping solutions were designed to include markers specific to pharmacogenomic
responsiveness, cardiometabolic disease, psychiatric disorders, and other traits of particular
interest, including fertility and twinning. The portfolio of custom-designed microarrays includes
the Affymetrix Axiom-NL array [49] and its successor, the Illumina GSA. A detailed description
of the GSA design and its first research application is provided in chapter 4.
In addition to DNA genotyping, the AIHG excels in performing additional molecular genetic
methods, including, but not limited to, measurements of epigenetic signatures (i.e., DNA
methylation) and whole-genome sequencing. The cost of sequencing has decreased by orders of
magnitude since the completion of the Human Genome Project, reflecting Moore’s Law
(https://www.genome.gov/about-genomics/fact-sheets/Sequencing-Human-Genome-cost). The
more affordable price, together with the ever-growing desire to discover trait-associated genetic

11
variants extending beyond those identified through SNP-based association studies, fosters novel
research ideas that necessitate whole-genome sequence data. For example, detecting rare and
functional variants associated with the DZ twinning process that cannot be identified through
traditional common variant association studies. In chapter 3, the first results of a whole-genome
sequencing project on a large Dutch pedigree with a rich history of DZ twinning are presented.
The NTR ascertained the large pedigree for multiple mothers of spontaneous DZ twins with
subsequent whole-genome sequencing at the AIHG on an Illumina Hi-Seq 2500. To date, this
project represents the first NTR-Avera collaborative human whole-genome sequencing project.
1.5 SNP Genotyping
The human genome is enormous, comprising about three billion base pairs of DNA. The
amount of biochemical individuality, or genetic variation, between any two humans is estimated
at around 0.1% [50, 51]. On average, this means that about one base pair out of 1,000 will vary
between any two individuals, equating to approximately 3 million total differences. However, the
estimate may be higher if more complex forms of variation (e.g., copy-number variants) are
considered. Given the vast number of potential genetic differences between humans, there exists
a need for automated procedures to measure and analyze genetic variation. DNA microarray
technologies have done just that, allowing for the assessment of thousands or even millions of
genetic variants (i.e., SNPs) in a single experiment. Information obtained from these genotyping
experiments is routinely utilized in population genetics, studies of pharmacogenomics, and
precision medicine research.
Whereas the exact order of DNA base pairs can be determined in a targeted or wholegenome
approach with sequencing methodologies, SNP genotyping more selectively defines which

specific genetic variants an individual possesses. Given that greater than 10 million common
genetic variants are likely to exist [52], SNP genotyping aims to measure a fraction of these
variants directly, often between 100,000 and 1,000,000. Thus, these methods rely upon knowing
where key variation exists within the genome. Identifying the minimal set of SNPs needed to
genotype the entire human genome was the driving force behind establishing the International
HapMap project [53].
Concerted whole-genome sequencing efforts like the 1000 Genomes Project [54] and the
Genome of the Netherlands [48] have been invaluable for providing a genetic ‘roadmap’ of the
human genome, highlighting important areas of genetic variation that exist between individuals
and populations. These large-scale initiatives represent genetic reference databases used to help
design and enable content selection for SNP genotyping microarrays. Additionally, these genetic
reference panels indirectly enhance the information obtained from SNP genotyping experiments
through a process called imputation. Imputation allows for the statistical inference of genotypes
not directly measured. As a result, SNP genotyping followed by imputation yields datasets
mimicking whole-genome sequencing experiments, but at a fraction of the cost.
While direct genotyping of SNPs throughout the genome provides a snapshot of the genetic
variation per individual, it by no means is a comprehensive evaluation. Imputation of genotypic
data is a commonly employed technique for bolstering the amount of genetic information that
can be gleaned from a SNP genotyping experiment. A fundamental principle of imputation is the
occurrence of non-random association of alleles at different locations within the genome, termed
linkage disequilibrium (LD). Because of linked allelic information, direct measurement of all
genetic markers is not necessary. Imputation leverages the direct measurement of carefully
selected genetic variants in regions of little recombination, known as LD or haplotype blocks.

13
Measurement of selected variants coupled with knowledge of associated alleles allows one to
infer information about the genetic variants not directly assayed. The most informative markers
constitute a core ‘backbone’ of genetic variants used for imputation in this context. The backbone
is based on commonly utilized reference panels so that the remainder of genetic variants can be
inferred from large population databases of whole-genome sequence data.
The technique of imputation has become an essential tool for geneticists performing
genomewide association studies. Imputation increases the power of genome-wide association
scans by enhancing the number of genetic variants for association testing. Furthermore,
imputation is particularly useful when aggregating genetic data obtained from different
genotyping platforms comprised of other SNP markers, a persistent occurrence in the era of
modern association studies. The studies described in chapters 4 and 5 were reliant upon genotype
imputation.
Creating trustworthy technologies and accurate methods for interrogating regions of genetic
variation is pivotal for obtaining reliable genotypes. Opposed to generating numerous reads per
base in whole-genome sequencing (i.e., coverage depth), any given marker on a genotyping array
is usually only measured once unless probes for a particular variant exist in replicate. Thus, the
array design and experiment chemistry must be robust to provide accurate results. Fortuitously,
pioneering biotechnology companies, such as Affymetrix (now part of Thermo Fisher Scientific),
Illumina, and others, have devoted years of scientific expertise to optimizing genotyping
solutions. The AIHG has routinely employed these products to facilitate large-scale genotyping
projects. Furthermore, through the NTR-Avera collaborative partnership, scientists have worked
hand-in-hand with biotechnology companies to design population-optimized custom genotyping
arrays, such as the Axiom-NL array [49] and a customized Illumina Global Screening Array

(described in chapter 4). These SNP microarrays were carefully designed to possess a core
imputation backbone and additional content related to phenotypes of interest.
Design of a customized SNP genotyping microarray involves providing the array
manufacturer with a list of targets in the form of genomic coordinates (i.e., the chromosome
number with start and end base pair positions), SNP reference numbers (i.e., rsIDs), or gene
regions (i.e., gene names and the number of bases upstream/downstream). The user-supplied
targets dictate probe design by the manufacturer. Probes are short synthetically made DNA
molecules, known as oligonucleotides, that interrogate a specific molecular region or site through
complementary binding. Genomic target information is typically entered via a web application,
which subsequently reports metrics regarding the likely predictive performance of each probe
given the supplied target. Estimated probe performance is a function of the region that flanks the
target and how difficult it is to design probes that will uniquely and reliably bind.
During array manufacturing, probe sequences complementary to the target are spotted or
synthesized directly onto an immobilized glass or silicon surface (e.g., silica microbeads) using
various technologies, including photolithography. The resulting product is a SNP microarray that
somewhat resembles a microscope slide, capable of assaying hundreds of thousands or millions
of genotypes per individual at once. Often the microarrays are combined into a bead chip or plate
format, enabling the simultaneous genotyping of many individuals (e.g., 24 for Illumina GSA
bead chips, 96 for Axiom-NL array plates).
Regardless of the array manufacturer, a SNP genotyping experiment typically involves six
primary steps. Shown in Figure 1.1 is an example SNP genotyping workflow with the Axiom
array. In a first step, high-quality DNA is extracted and amplified to make copies of the genetic
material. Secondly, the whole genome amplified DNA is subjected to enzymatic or mechanical

15
fragmentation procedures to cleave the DNA into pieces. In a third step, the fragmented DNA is
precipitated. Fourthly, the precipitated fragmented DNA is resuspended. In the fifth step, DNA is
hybridized to the microarray containing the probes, or complementary oligonucleotides. Washing
removes any non-complementary DNA that does not bind. Lastly, in a final ligation/extension
and staining step, DNA successfully hybridizing to the array will emit fluorescent signals that are
imaged with sophisticated instrumentation. The fluorescent signals are then analyzed and
converted into raw genotype calls for downstream analysis using array-specific, and often
proprietary software.
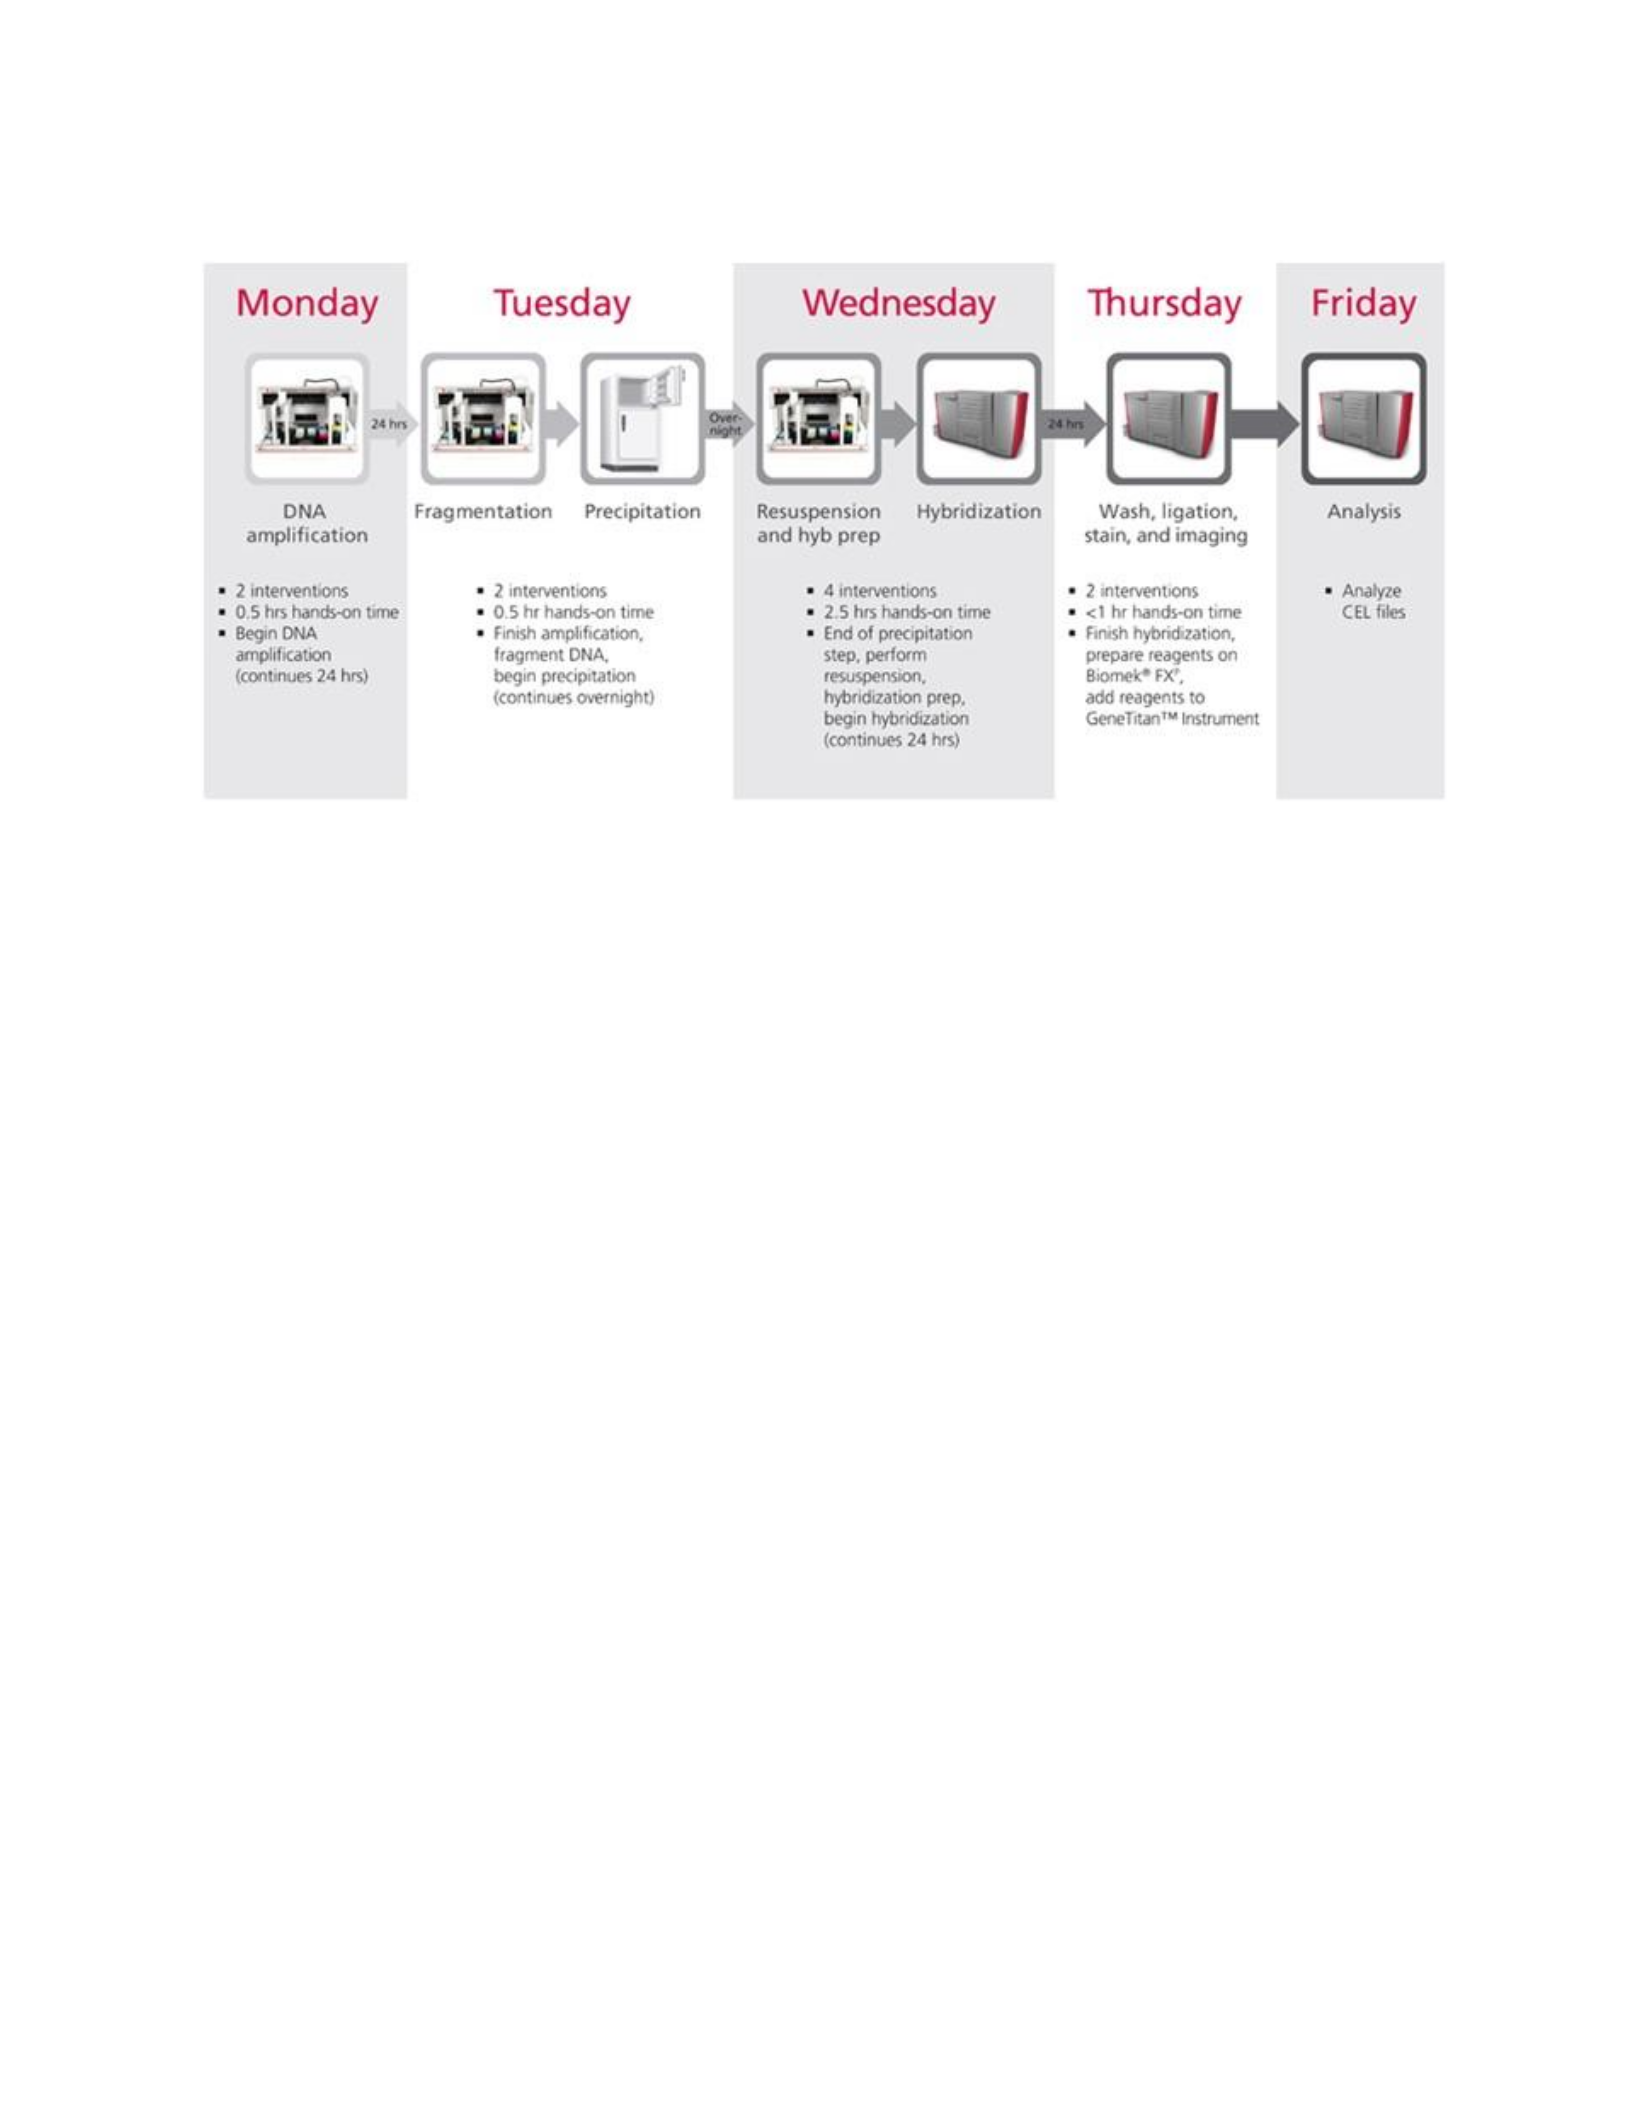
Figure 1.1 – Workflow for the Axiom array
Image obtained from:
https://www.affymetrix.com/products_services/instruments/specific/axiom_atp.affx

17
Several aspects of SNP genotyping and the data obtained from the experiments were
fundamental to the work presented in this thesis. During the first two years of my Ph.D.
trajectory, I spent considerable time performing SNP genotyping experiments with the AxiomNL
array on thousands of NTR participants. As the principal performer of these genotyping
experiments, I gained an immense understanding of the SNP genotyping process by
troubleshooting and optimizing high-throughput strategies. The extensive genotyping effort
produced substantial datasets that were integral to many elements of this thesis. In chapter 2, the
genetics of twins are described, in which SNP genotyping is discussed as the most reliable
strategy for determining the zygosity status of same-sex twin pairs. Also, chapter 2 provides an
overview of research identifying the first genetic variants associated with DZ twinning, which
were established through SNP genotyping experiments and subsequent imputation. In chapter 3,
SNP genotype data were used to locate genetic regions co-segregating with being a mother of DZ
twins. In chapter 4, a detailed description of the Illumina GSA design and its implementation is
provided. Chapter 5 details the first genome-wide association study in the ATR and the findings
of a GWAMA of twin birth weight, which utilized imputed and harmonized SNP genotype data
on 42,212 twins from eight global population cohorts. Lastly, chapter 6 presents an empirical
evaluation of ancestry estimation in twins and families based on genetic data from three distinct
SNP genotyping arrays. The NTR has uniquely generated SNP genotype data on both members
of a MZ twin pair.
1.6 Genome-Wide Association Studies
Over the years, significant scientific interest has been devoted to identifying associations
between genotype and phenotype. Ultimately, these studies' underlying goal is to better

understand trait or disease etiology to improve prediction, prevention, or treatment. Although
there is a long history of study designs and strategies for elucidating genotype-phenotype
associations (e.g., candidate gene studies, linkage studies in multi-generation pedigrees and
sibling pairs), much of the effort in the last 10-15 years can be ascribed to genome-wide
association studies (GWAS). In part, this is due to what is sometimes called the hypothesis-free
nature underlying the GWAS design. GWAS do not require a priori knowledge or selection of
interesting genetic variants related to a particular trait. However, they do test the hypothesis that
a variant or multiple variants are associated with a trait. As opposed to candidate-gene driven
approaches, a benefit of GWAS is that findings can often yield results that otherwise would not
have been considered. This characteristic of GWAS has made it a popular and astonishingly
successful study design, with greater than 270,000 trait-variant associations described in more
than 5,000 publications to date (https://www.ebi.ac.uk/gwas/ ).
Despite the success and remarkable range of discoveries made by GWAS in recent years,
challenges are still encountered when dealing with intrinsic limitations. Methodologically,
GWAS utilize large samples of human genetic data (millions of SNPs) and phenotypic
information to detect association by simultaneously testing the effect of genetic variants on a
particular phenotype [55-58]. In this manner, the practice of performing millions of concurrent
statistical tests necessitates stringent statistical correction to account for multiple testing and the
potential for false positives. Thus, an omnipresent concern for GWAS is adequate statistical
power to account for these corrections and the potentially small effects of individual SNPs.
The power to detect the associations between genetic variants and a trait depends on the
chosen significance level, the experimental sample size, the effect size of the variant(s), the
measurement of the phenotype, and several other factors. A genome-wide significance P-value

19
threshold of 5x10⁻⁸ has become the standard in GWAS to account for the vast number of
statistical tests being done [59, 60]. Although widely adopted, even more stringent thresholds
have been suggested for studies using lower frequency genetic variants [61]. Thus, increasing
sample sizes can enhance the power for detection. One sensible approach is to aggregate relevant
data from as many resources as possible. In doing so, concerns are raised regarding systematic
differences in allele frequencies that can occur by incorporating individuals from various
(sub)populations, leading to spurious results and false positives. This phenomenon is termed
population stratification and represents an important source of confounding that must be
appropriately addressed in any GWAS [62].
GWAS and the essential concepts underlying their design represent a substantial portion of
the work presented in this thesis. Broadly, the idea of population data aggregation for achieving
adequate statistical power in a GWAS is empirically evaluated in chapter 4. Furthermore, a
metaanalysis of GWAS results on birth weight in twins from worldwide twin registers is
described in chapter 5. Chapter 6 utilizes genetic data to compare estimates of genetic ancestry,
which are commonly employed steps in association studies and important indicators of
population structure.
1.7 Principal Component Analysis
In genetic association studies, principal component analysis (PCA) is an important method
for summarizing genetic variation. PCA is a very general mathematical approach commonly
utilized for dimensionality reduction of large data sets. PCA works by transforming many
variables into a smaller group of uncorrelated variables containing all the information in the
original data. The (much) smaller set of variables preserve most of the variation in the data and

are called principal components (PCs). In general, PCA summarizes the most prominent patterns
of variation in a data set containing numerous measurements.
In genetics, PCA condenses many individuals' genetic variation (typically tens or hundreds of
thousands of genetic markers) into a relatively small number (often around 10) of PCs. The
patterns of variation defined by PCA from genetic datasets of global populations have been
shown to reflect ancestry differences and correlate with geography [63]. However, if
implemented incorrectly, the validity of these relationships can be biased [64]. Regardless, PCA
has been increasingly utilized to infer population (sub)structure from genetic data since its first
adaptation for human genomic data in 1963 [65]. PCA is valuable in GWAS for adequately
accounting for population structure. In practice, the PCs summarizing ancestry and other
variation in the genotype data are used as covariates in association models.
In this thesis, PCA was instrumental for the work presented in several chapters. In chapter 4,
PCA of Australian, Dutch, and Midwestern American individuals genotyped at the AIHG on the
Illumina GSA was performed to visualize and compare population structure. PCA was also
utilized to project study samples onto PCs calculated by a global reference set acquired from the
Human Genome Diversity Project. The projection procedure allowed for a broader resolution
assessment of the genetic similarity of the populations of interest. Chapter 5 utilized PCA and
PCs to correct for cohort-specific metrics (e.g., genetic ancestry, genotyping platform,
genotyping batch) in each GWAS of birth weight that contributed to the overall meta-analysis.
Genomic PCs were also used as covariates in the predictive model of birth weight with polygenic
scores. Chapter 6 applied PCA as a primary method for inferring genetic ancestry, in which
comparisons of the resultant PCs were evaluated within twins and family members.

21
1.8 Hypothesis and Objectives of the Dissertation
This dissertation broadly examines the genetics of the twinning phenomenon, twins, global
twin-family populations, and the representativeness of twins in GWAS by employing various
analytical approaches and study designs.
The second chapter of this thesis provides background information on the biology and
genetics of twins. This chapter describes what is well understood and what remains mysterious
regarding our scientific understanding of the twinning process. Key distinctions are made
between the two types of twins, monozygotic (MZ) and dizygotic (DZ). The chapter’s central
theme is the unique characteristics of MZ and DZ twins, specifically differentiating their
respective biology, epidemiology, genetics, and incidence. Moreover, twins and the processes
underlying twinning have been extensively studied for years, yet a complete understanding of the
mechanisms and contributory factors is still lacking. With that in mind, substantially more is
known about the etiology of DZ twinning in part due to recent advances in molecular
technologies and the illuminating power of gene discovery afforded by genetic association
studies. Despite these developments and numerous scientific efforts, the processes underlying
MZ twinning remain largely unresolved. Regardless of the lingering uncertainties, twins remain a
precious resource for studying genetics and complex traits, especially in the ‘omics’ era [66].
In chapters 3 through 6, specific scientific questions related to twinning and the broader field
of human genetics are addressed with data from twins, their families, and the populations they
represent. The feasibility of these studies was contingent on the availability of sizable genotypic
data sets from worldwide twin and family cohorts.
The focus of chapter 3 is the genetic influences of DZ twinning. Throughout many years’
worth of twin studies on behavioral traits, many researchers realized the strong tendency for DZ

twinning to run in families. This recognition prompted many segregation and pedigree analyses
to illuminate the genetics of DZ twinning. Here, we expand upon these studies by identifying a
multigenerational pedigree with many mothers of DZ twins to further uncover genetic factors
associated with DZ twinning. The study's objective was to use pedigree-based genotypic and
sequence data to identify genetic variants influencing a mother’s propensity to conceive DZ
twins. The project intended to discover novel rare/structural variants extending beyond the
common variants with established DZ twinning associations. We hypothesized that we could
identify large genetic regions of interest co-segregating in mothers of DZ twins by analyzing
genetic data from available family members through linkage analysis. Furthermore, we expected
that the common areas would harbor rare variants of large effect and that substantially influence
DZ twinning. More broadly, determining whether the identified variants are pedigree specific or
possessed by a larger group of mothers of DZ twins necessitated evaluation against
populationmatched controls.
Chapter 4 leverages the vast amount of information contained within genotypic data to
evaluate the genetic similarity of global populations. First, I provide a detailed description of the
design of a genotyping microarray that facilitated the work in this chapter and much of the
remaining thesis content. Implementation of the microarray enabled the generation of a wealth of
genotypic data representative of individuals from three globally distinct populations, namely
Australian, Dutch, and Americans from the Midwestern region of the United States. We
hypothesized to find comparable estimates of genetic similarity among the populations since they
each have ancestral origins from Europe. Comparisons were augmented with worldwide
reference data and an auxiliary genetic dataset generated from the same microarray obtained
from a Nigerian population.

23
Chapter 5 builds on the findings of the previous chapter in that genetic data from European
ancestry-based populations were aggregated to investigate the genetics of birth weight in twins.
Birth weight is an important indicator of overall health, and critical links between low birth
weight and higher risks of perinatal morbidity and mortality have been established [67-71].
Furthermore, a wealth of evidence has demonstrated an impact of birth weight and diseases in
adulthood [72], including type 2 diabetes [73], cardiovascular disease [74, 75], high blood
pressure [76-79], psychological distress [80], and body mass index [81, 82]. For these reasons,
birth weight has been studied extensively and is known to be influenced by genetic and
environmental factors [83]. Genetically, variation in birth weight is complicated by the effects of
fetal and maternal genes [84-86]. Although complex, most of what is understood about birth
weight genetics has been established by studies of singletons. Twins are often excluded due to
their, on average, lower birth weight and the uncertainty of differing genetic influences when
compared to singletons. There has only been one published GWAS of the genetics of birth weight
in twins, precisely 4,593 female twins from the United Kingdom, in which one genomewide
significant signal was identified [87]. While the findings provided the first insight into the
genetic factors influencing birth weight in twins, much remained to be determined concerning
how the genetic component of birth weight compares in twins and singletons. While differences
in average birth weight between twins and singletons exist, we hypothesized that the common
genetic effects influencing birth weight are similar between the groups. We additionally aimed to
identify novel genetic variants associated with birth weight in twins by meta-analyzing GWAS
results supplied by eight twin cohorts. An indication of the genetic overlap was determined by
comparing meta-analysis results to those previously reported for singletons.

Chapter 6 analyzes genetic information from NTR twins and family members to examine
estimates of genetic ancestry. Ancestry inference is pivotal in association studies since systematic
differences between groups can confound real association signals leading to spurious results.
Therefore, ancestry estimation strategies are routinely employed to mitigate or eliminate the
effects of population stratification by including ancestry-specific covariates in the association
models or excluding outliers. Another method for diminishing the impact of population
stratification is to employ a family-based design in which genetic relatedness is accounted for,
and ancestry is essentially under control. However, remaining ambiguities surround this approach
in that a comprehensive assessment of genetic ancestry estimation has not been performed within
families and between sets of twins. We utilized genotypic data of many NTR participants to
address this uncertainty, including independently genotyped MZ twins, DZ twins, siblings, and
parents to estimate genetic ancestry within families. For this project, genotypic data was supplied
by three different microarrays (Affymetrix 6, Affymetrix Axiom-NL, and Illumina GSA),
enabling additional evaluation as a function of the genotyping platform. This aspect of the study
is particularly relevant in studies where data are combined across study cohorts and genotyping
platforms. The array differences have the potential to impact ancestry estimates. We aimed to
address this concern by estimating genetic ancestry using standard algorithmic (i.e., PCA) and
model-based approaches. Both methods have their inherent benefits and limitations, and the
resulting estimates reflect different parameterizations of genetic ancestry. The hypothesis that
genetic ancestry estimates would show fewer differences between more closely related family
members, independent of the genotyping array, was thoroughly tested in this manner.
Chapter 7 summarizes the main findings of the preceding chapters and provides overall
conclusions of the work. In what follows, I present my perspective on the future of twin studies

25
and population genetics. Finally, in chapter 8, I offer concise summaries of the studies presented
in chapters 2-6.
1.9 References
1. Herranz, G., The timing of monozygotic twinning: a criticism of the common model.
Zygote, 2013. 23(1): p. 27-40.
2. Bulmer, M.G., The Biology of Twinning in Man. 1970: Clarendon. 206.
3. Hall, J.G., Twinning. Lancet, 2003. 362(9385): p. 735-43.
4. Martin, N., D. Boomsma, and G. Machin, A twin-pronged attack on complex traits. Nat
Genet, 1997. 17(4): p. 387-92.
5. Poll, H., Über Zwillingsforschung als Hilfsmittel menschlicher Erbkunde. Zeitschrift für
Ethnologie, 1914. 46: p. 87-105.
6. Siemens, H.W., Die Zwillingspathologie. Mol. Gen. Genet., 1924. 35: p. 311-312.
7. Boomsma, D.I., J.F. Orlebeke, and G.C. van Baal, The Dutch Twin Register: growth data
on weight and height. Behav Genet, 1992. 22(2): p. 247-51.
8. Ligthart, L., et al., The Netherlands Twin Register: Longitudinal Research Based on Twin
and Twin-Family Designs. Twin Res Hum Genet, 2019. 22(6): p. 623-636.
9. Kittelsrud, J., et al., Avera Twin Register: Growing through Online Consenting and
Survey Collection. Twin Research and Human Genetics, 2019(Special Issue on Twin
Registers).
10. Kittelsrud, J., et al., Establishment of the Avera Twin Register in the Midwest USA. Twin
Res Hum Genet, 2017. 20(5): p. 414-418.
11. Peters, H.E., et al., Low prevalence of male microchimerism in women with
MayerRokitansky-Kuster-Hauser syndrome. Hum Reprod, 2019. 34(6): p. 1117-1125.
12. Johnson, B.N., et al., Male microchimerism in females: a quantitative study of twin
pedigrees to investigate mechanisms. Hum Reprod, 2021.
13. Odintsova, V.V., et al., Predicting complex traits and exposures from polygenic scores
and blood and buccal DNA methylation profiles. Frontiers in Psychiatry, 2021. 12: p.
1141.
14. van Dongen, J., et al., Identical twins carry a persistent epigenetic signature of early
genome programming. Nature Communications, In press.
15. Finnicum, C.T., et al., Relative Telomere Repeat Mass in Buccal and Leukocyte-Derived
DNA. PLoS One, 2017. 12(1): p. e0170765.
16. Finnicum, C.T., et al., Cohabitation is associated with a greater resemblance in gut
microbiota which can impact cardiometabolic and inflammatory risk. BMC Microbiol,
2019. 19(1): p. 230.
17. Finnicum, C.T., et al., Metataxonomic Analysis of Individuals at BMI Extremes and
Monozygotic Twins Discordant for BMI. Twin Res Hum Genet, 2018. 21(3): p. 203-213.
18. Pappa, I., et al., A genome-wide approach to children's aggressive behavior: The EAGLE
consortium. Am J Med Genet B Neuropsychiatr Genet, 2016. 171(5): p. 562-72.

19. Ip, H.F., et al., Genetic Association Study of Childhood Aggression across raters,
instruments and age. bioRxiv, 2021: p. 854927.
20. Ehli, E.A., et al., De novo and inherited CNVs in MZ twin pairs selected for discordance
and concordance on Attention Problems. Eur J Hum Genet, 2012. 20(10): p. 1037-43. 21.
Groen-Blokhuis, M.M., et al., A prospective study of the effects of breastfeeding
and FADS2 polymorphisms on cognition and hyperactivity/attention problems. Am J Med
Genet B Neuropsychiatr Genet, 2013. 162B(5): p. 457-65.
22. de Zeeuw, E.L., et al., Polygenic scores associated with educational attainment in adults
predict educational achievement and ADHD symptoms in children. Am J Med Genet B
Neuropsychiatr Genet, 2014. 165B(6): p. 510-20.
23. Abdellaoui, A., et al., CNV Concordance in 1,097 MZ Twin Pairs. Twin Res Hum Genet,
2015. 18(1): p. 1-12.
24. Middeldorp, C.M., et al., A Genome-Wide Association Meta-Analysis of
AttentionDeficit/Hyperactivity Disorder Symptoms in Population-Based Pediatric
Cohorts. J Am Acad Child Adolesc Psychiatry, 2016. 55(10): p. 896-905 e6.
25. Demontis, D., et al., Discovery of the first genome-wide significant risk loci for attention
deficit/hyperactivity disorder. Nat Genet, 2019. 51(1): p. 63-75.
26. Hibar, D.P., et al., Common genetic variants influence human subcortical brain
structures. Nature, 2015. 520(7546): p. 224-9.
27. Adams, H.H., et al., Novel genetic loci underlying human intracranial volume identified
through genome-wide association. Nat Neurosci, 2016. 19(12): p. 1569-1582.
28. Hibar, D.P., et al., Novel genetic loci associated with hippocampal volume. Nat Commun,
2017. 8: p. 13624.
29. Satizabal, C.L., et al., Genetic architecture of subcortical brain structures in 38,851
individuals. Nat Genet, 2019. 51(11): p. 1624-1636.
30. Middeldorp, C.M., et al., The genetic association between personality and major
depression or bipolar disorder. A polygenic score analysis using genome-wide
association data. Transl Psychiatry, 2011. 1: p. e50.
31. Benke, K.S., et al., A genome-wide association meta-analysis of preschool internalizing
problems. J Am Acad Child Adolesc Psychiatry, 2014. 53(6): p. 667-676 e7.
32. Okbay, A., et al., Genetic variants associated with subjective well-being, depressive
symptoms, and neuroticism identified through genome-wide analyses. Nat Genet, 2016.
33. Mbarek, H., et al., Genome-Wide Significance for PCLO as a Gene for Major Depressive
Disorder. Twin Res Hum Genet, 2017. 20(4): p. 267-270.
34. Wray, N.R., et al., Genome-wide association analyses identify 44 risk variants and refine
the genetic architecture of major depression. Nat Genet, 2018. 50(5): p. 668-681.
35. Huppertz, C., et al., A twin-sibling study on the relationship between exercise attitudes
and exercise behavior. Behav Genet, 2014. 44(1): p. 45-55.
36. Mee, D.J.v.d., et al., Dopaminergic Genetic Variants and Voluntary Externally Paced
Exercise Behavior. Medicine & Science in Sports & Exercise, 2018. 50: p. 70P 708.
37. Barban, N., et al., Genome-wide analysis identifies 12 loci influencing human
reproductive behavior. Nat Genet, 2016.
38. Mbarek, H., et al., Identification of Common Genetic Variants Influencing Spontaneous
Dizygotic Twinning and Female Fertility. Am J Hum Genet, 2016. 98(5): p. 898-908.

27
39. Franic, S., et al., Intelligence: shared genetic basis between Mendelian disorders and a
polygenic trait. Eur J Hum Genet, 2015. 23(10): p. 1378-83.
40. Baumert, J., et al., No evidence for genome-wide interactions on plasma fibrinogen by
smoking, alcohol consumption and body mass index: results from meta-analyses of
80,607 subjects. PLoS One, 2014. 9(12): p. e111156.
41. Minica, C.C., et al., Genome-wide association meta-analysis of age at first cannabis use.
Addiction, 2018. 113(11): p. 2073-2086.
42. Liu, M., et al., Association studies of up to 1.2 million individuals yield new insights into
the genetic etiology of tobacco and alcohol use. Nat Genet, 2019. 51(2): p. 237-244.
43. van den Berg, S.M., et al., Meta-analysis of Genome-Wide Association Studies for
Extraversion: Findings from the Genetics of Personality Consortium. Behav Genet, 2016.
46(2): p. 170-82.
44. Gieger, C., et al., New gene functions in megakaryopoiesis and platelet formation.
Nature, 2011. 480(7376): p. 201-8.
45. Ibrahim-Verbaas, C.A., et al., GWAS for executive function and processing speed suggests
involvement of the CADM2 gene. Mol Psychiatry, 2016. 21(2): p. 189-197.
46. Sabater-Lleal, M., et al., Multiethnic meta-analysis of genome-wide association studies in
>100 000 subjects identifies 23 fibrinogen-associated Loci but no strong evidence of a
causal association between circulating fibrinogen and cardiovascular disease.
Circulation, 2013. 128(12): p. 1310-24.
47. Wain, L.V., et al., Genome-wide association study identifies six new loci influencing pulse
pressure and mean arterial pressure. Nat Genet, 2011. 43(10): p. 1005-11.
48. Genome of the Netherlands, C., Whole-genome sequence variation, population structure
and demographic history of the Dutch population. Nat Genet, 2014. 46(8): p. 818-25.
49. Ehli, E.A., et al., A method to customize population-specific arrays for genome-wide
association testing. Eur J Hum Genet, 2017. 25(2): p. 267-270.
50. Feuk, L., A.R. Carson, and S.W. Scherer, Structural variation in the human genome.
Nature Reviews Genetics, 2006. 7(2): p. 85-97.
51. Ku, C.S., et al., The discovery of human genetic variations and their use as disease
markers: past, present and future. J Hum Genet, 2010. 55(7): p. 403-15.
52. International HapMap, C., et al., A second generation human haplotype map of over 3.1
million SNPs. Nature, 2007. 449(7164): p. 851-61.
53. International HapMap, C., The International HapMap Project. Nature, 2003. 426(6968):
p. 789-96.
54. Auton, A., et al., A global reference for human genetic variation. Nature, 2015. 526: p. 68
- 74.
55. Visscher, P.M. and G.W. Montgomery, Genome-wide association studies and human
disease: from trickle to flood. JAMA, 2009. 302(18): p. 2028-9.
56. Visscher, P.M., et al., Five years of GWAS discovery. Am J Hum Genet, 2012. 90(1): p. 7-
24.
57. Visscher, P.M., et al., 10 Years of GWAS Discovery: Biology, Function, and Translation.
Am J Hum Genet, 2017. 101(1): p. 5-22.
58. Claussnitzer, M., et al., A brief history of human disease genetics. Nature, 2020.
577(7789): p. 179-189.

59. Pe'er, I., et al., Estimation of the multiple testing burden for genomewide association
studies of nearly all common variants. Genet Epidemiol, 2008. 32(4): p. 381-5.
60. International HapMap, C., A haplotype map of the human genome. Nature, 2005.
437(7063): p. 1299-320.
61. Fadista, J., et al., The (in)famous GWAS P-value threshold revisited and updated for
lowfrequency variants. Eur J Hum Genet, 2016. 24(8): p. 1202-5.
62. Price, A.L., et al., New approaches to population stratification in genome-wide
association studies. Nat Rev Genet, 2010. 11(7): p. 459-63.
63. Novembre, J., et al., Genes mirror geography within Europe. Nature, 2008. 456(7218): p.
98-101.
64. Elhaik, E., Why most Principal Component Analyses (PCA) in population genetic studies
are wrong. bioRxiv, 2021: p. 2021.04.11.439381.
65. Cavalli-Sforza, L.L. and A.W.F. Edwards. Analysis of Human Evolution. in Genetics
Today, Proceedings of the 11th International Congress of Genetics. 1963. the Hague, the
Netherlands: Pergamon, New York.
66. van Dongen, J., et al., The continuing value of twin studies in the omics era. Nat Rev
Genet, 2012. 13(9): p. 640-53.
67. Battaglia, F.C. and L.O. Lubchenco, A practical classification of newborn infants by
weight and gestational age. J Pediatr, 1967. 71(2): p. 159-63.
68. Wilcox, A.J. and I.T. Russell, Birthweight and perinatal mortality: II. On weight-specific
mortality. Int J Epidemiol, 1983. 12(3): p. 319-25.
69. Wilcox, A.J., Birth weight and perinatal mortality: the effect of maternal smoking. Am J
Epidemiol, 1993. 137(10): p. 1098-104.
70. McIntire, D.D., et al., Birth weight in relation to morbidity and mortality among newborn
infants. N Engl J Med, 1999. 340(16): p. 1234-8.
71. Wilcox, A.J., On the importance--and the unimportance--of birthweight. Int J Epidemiol,
2001. 30(6): p. 1233-41.
72. Barker, D.J. and P.M. Clark, Fetal undernutrition and disease in later life. Rev Reprod,
1997. 2(2): p. 105-12.
73. Whincup, P.H., et al., Birth weight and risk of type 2 diabetes: a systematic review.
JAMA, 2008. 300(24): p. 2886-97.
74. Eriksson, M., et al., Birth weight and cardiovascular risk factors in a cohort followed
until 80 years of age: the study of men born in 1913. J Intern Med, 2004. 255(2): p.
23646.
75. Wang, S.F., et al., Birth weight and risk of coronary heart disease in adults: a
metaanalysis of prospective cohort studies. J Dev Orig Health Dis, 2014. 5(6): p. 408-19.
76. Law, C.M. and A.W. Shiell, Is blood pressure inversely related to birth weight? The
strength of evidence from a systematic review of the literature. J Hypertens, 1996. 14(8):
p. 935-41.
77. RG, I.J., C.D. Stehouwer, and D.I. Boomsma, Evidence for genetic factors explaining the
birth weight-blood pressure relation. Analysis in twins. Hypertension, 2000. 36(6): p.
1008-12.
78. Jarvelin, M.R., et al., Early life factors and blood pressure at age 31 years in the 1966
northern Finland birth cohort. Hypertension, 2004. 44(6): p. 838-46.

29
79. Gamborg, M., et al., Birth weight and systolic blood pressure in adolescence and
adulthood: meta-regression analysis of sex- and age-specific results from 20 Nordic
studies. Am J Epidemiol, 2007. 166(6): p. 634-45.
80. Cheung, Y.B., et al., Birthweight and psychological distress in adult twins: a longitudinal
study. Acta Paediatr, 2004. 93(7): p. 965-8.
81. Sorensen, H.T., et al., Relation between weight and length at birth and body mass index
in young adulthood: cohort study. BMJ, 1997. 315(7116): p. 1137.
82. Johansson, M. and F. Rasmussen, Birthweight and body mass index in young adulthood:
the Swedish young male twins study. Twin Res, 2001. 4(5): p. 400-5.
83. Yokoyama, Y., et al., Genetic and environmental factors affecting birth size variation: a
pooled individual-based analysis of secular trends and global geographical differences
using 26 twin cohorts. Int J Epidemiol, 2018. 47(4): p. 1195-1206.
84. Warrington, N.M., et al., Maternal and fetal genetic effects on birth weight and their
relevance to cardio-metabolic risk factors. Nat Genet, 2019. 51(5): p. 804-814.
85. Moen, G.H., et al., Mendelian randomization study of maternal influences on birthweight
and future cardiometabolic risk in the HUNT cohort. Nat Commun, 2020. 11(1): p. 5404.
86. Srivastava, A.K., et al., Haplotype-based heritability estimations reveal gestational
duration as a maternal trait and fetal size measurements at birth as fetal traits in human
pregnancy. bioRxiv, 2020: p. 2020.05.12.079863.
87. Metrustry, S.J., et al., Variants close to NTRK2 gene are associated with birth weight in
female twins. Twin research and human genetics : the official journal of the International
Society for Twin Studies, 2014. 17(4): p. 254-61.

CHAPTER 2 – BIOLOGY AND GENETICS OF DIZYGOTIC AND MONOZYGOTIC
TWINNING
Published as:
Beck, J.J., Bruins, S., Mbarek, H., Davies, G.E., Boomsma, D.I. (2021)
Biology and Genetics of Dizygotic and Monozygotic Twinning. In: Khalil, A., Lewi, L.,
Lopriore, E. (Eds) Twin and higher-order pregnancies, Springer Nature, doi.org 10.1007/978-
3030-47652-6

31
2.1 Abstract
This chapter summarizes what is known and what remains unknown about the human
twinning process. The interest of this chapter is a description of the processes underlying
twinning, with a specific focus on the biological and genetic aspects. While the mechanisms and
contributory factors to dizygotic twinning are becoming well established, much remains
unknown about the etiology of monozygotic twinning. Here we provide an overview of the
incidence of twinning across the globe and present what is known about the influences of
twinning based on the findings of historical, epidemiological, and more recent molecular studies.
Keywords: dizygotic twins, monozygotic twins, genetics, assisted reproductive technologies,
twinning rates
Definitions:
1. Zygosity – The number of zygotes that become fertilized leading to a multiple birth, or
the genetic makeup of the pregnancy.
2. Dizygotic twins – Non-identical or fraternal twins that are the result of two independent
ova that are fertilized by two separate spermatozoa.
3. Monozygotic twins – Identical twins that arise from a single fertilized ovum.
Learning Objectives:
1. Define and differentiate between the biological mechanisms that give rise to monozygotic
and dizygotic twins.

2. Compare and contrast the composition of fetal membranes of monozygotic and dizygotic
twins.
3. Describe the genetic and non-genetic factors that are associated with spontaneous
dizygotic twinning events.
4. Explain the strengths and weaknesses of zygosity assessment methods.
5. Describe the differences in rates of monozygotic and dizygotic twins.
6. Introduce the first genome-wide association study of dizygotic twinning.
2.2 Introduction
Twins and higher-order multiples have piqued the interest of humankind for many
centuries. The remarkable similar resemblance often ascribed to twins has been observed in
many literary texts and philosophical works. Twins with similar outward appearances but with
noticeable personality differences have been well characterized throughout history. Observations
of twins are noted as far back in time as the Biblical accounts of Jacob and Esau, by philosophers
Augustine of Hippo and Aristotle, and by poets like Shakespeare (e.g., The Comedy of Errors and
Twelfth Night).
From a scientific perspective, it was in the nineteenth century that the Scottish
obstetrician J Matthews Duncan recognized and documented that two types of twins existed, now
commonly referred to as identical and fraternal (non-identical) twins [1]. Sir Francis Galton was
the first the recognize the value of studying twins to elucidate the genetic contribution to
variation in human traits [2]; however, he was not aware of the distinction between monozygotic
(MZ or identical) and dizygotic (DZ or fraternal) twins. Even in the early twentieth century, the
existence of two types of twins was debated. The famous statistician Sir Ronald Fisher (who was

33
the second of twins himself) proved mathematically that it was highly unlikely that there was
more than one type of twin [3]. Nevertheless, the idea put forth by Galton was to compare trait
concordance in twins in an attempt at disentangling the genetic (nature) and environmental
(nurture) influences. Galton’s proposal laid the foundation for modern era twin studies aimed at
discerning the genetic contribution of complex traits and etiology of disease.
The theoretical basis of quantitative genetics proved to be fundamental to the creation and
application of the classical twin design, which builds on the – by now firmly established –
differential genetic relatedness of MZ and DZ twin pairs. Realizing the enormous potential of
quantitative genetic theory to studies that apply the classical twin design for studying human
traits, large twin registries were established in the 1950s [4], although studies of twins had
already been done in Russia [5-7] and elsewhere. The first scientific studies of twins in medicine
were by Poll [8] and Siemens, who investigated the different levels of similarity between MZ and
DZ twins for mole counts. Findings from their work suggested that MZ twin pairs were nearly
genetically identical, whereas DZ twin pairs shared on average 50% of their genetic variation;
this was reflected in the twice as large resemblance for mole counts in MZ than in DZ twin pairs.
By now, twin registries are increasingly popular and have proven strengths in longitudinal data
collection and inclusion of biological samples to evaluate the genetic variation in susceptibility to
disease.
Remarkably, despite the rapid gain in knowledge about the importance of genetic
variation due to advancements in genotyping technology combined with the development of
powerful linkage and genetic association studies, there is no comprehensive understanding of the
twinning process. For example, there are no estimates for the heritability of twinning. A number
of factors influencing the DZ twinning process are well described, and the first genetic factors

for DZ twinning have been characterized [10]. However, the heritability of DZ twinning remains
unknown, and the knowledge regarding the etiology of MZ twinning is even more limited.
This chapter summarizes the current body of knowledge surrounding the epidemiological,
biological, and genetic aspects of human twinning. Included are explanations of the biological
mechanisms of twinning, descriptions of the underlying genetic contributions to the twinning
process, and details on the frequency of twinning within populations.
2.3 Zygosity, Choriocity, Placentation of Twinning
Zygosity refers to the genetic makeup of the pregnancy or the number of zygotes that
become fertilized leading to a multiple birth. Twins, in rarer cases, triplets, quadruplets (four),
quintuplets (five) arising from a single fertilized ovum are termed monozygotic (MZ). The first
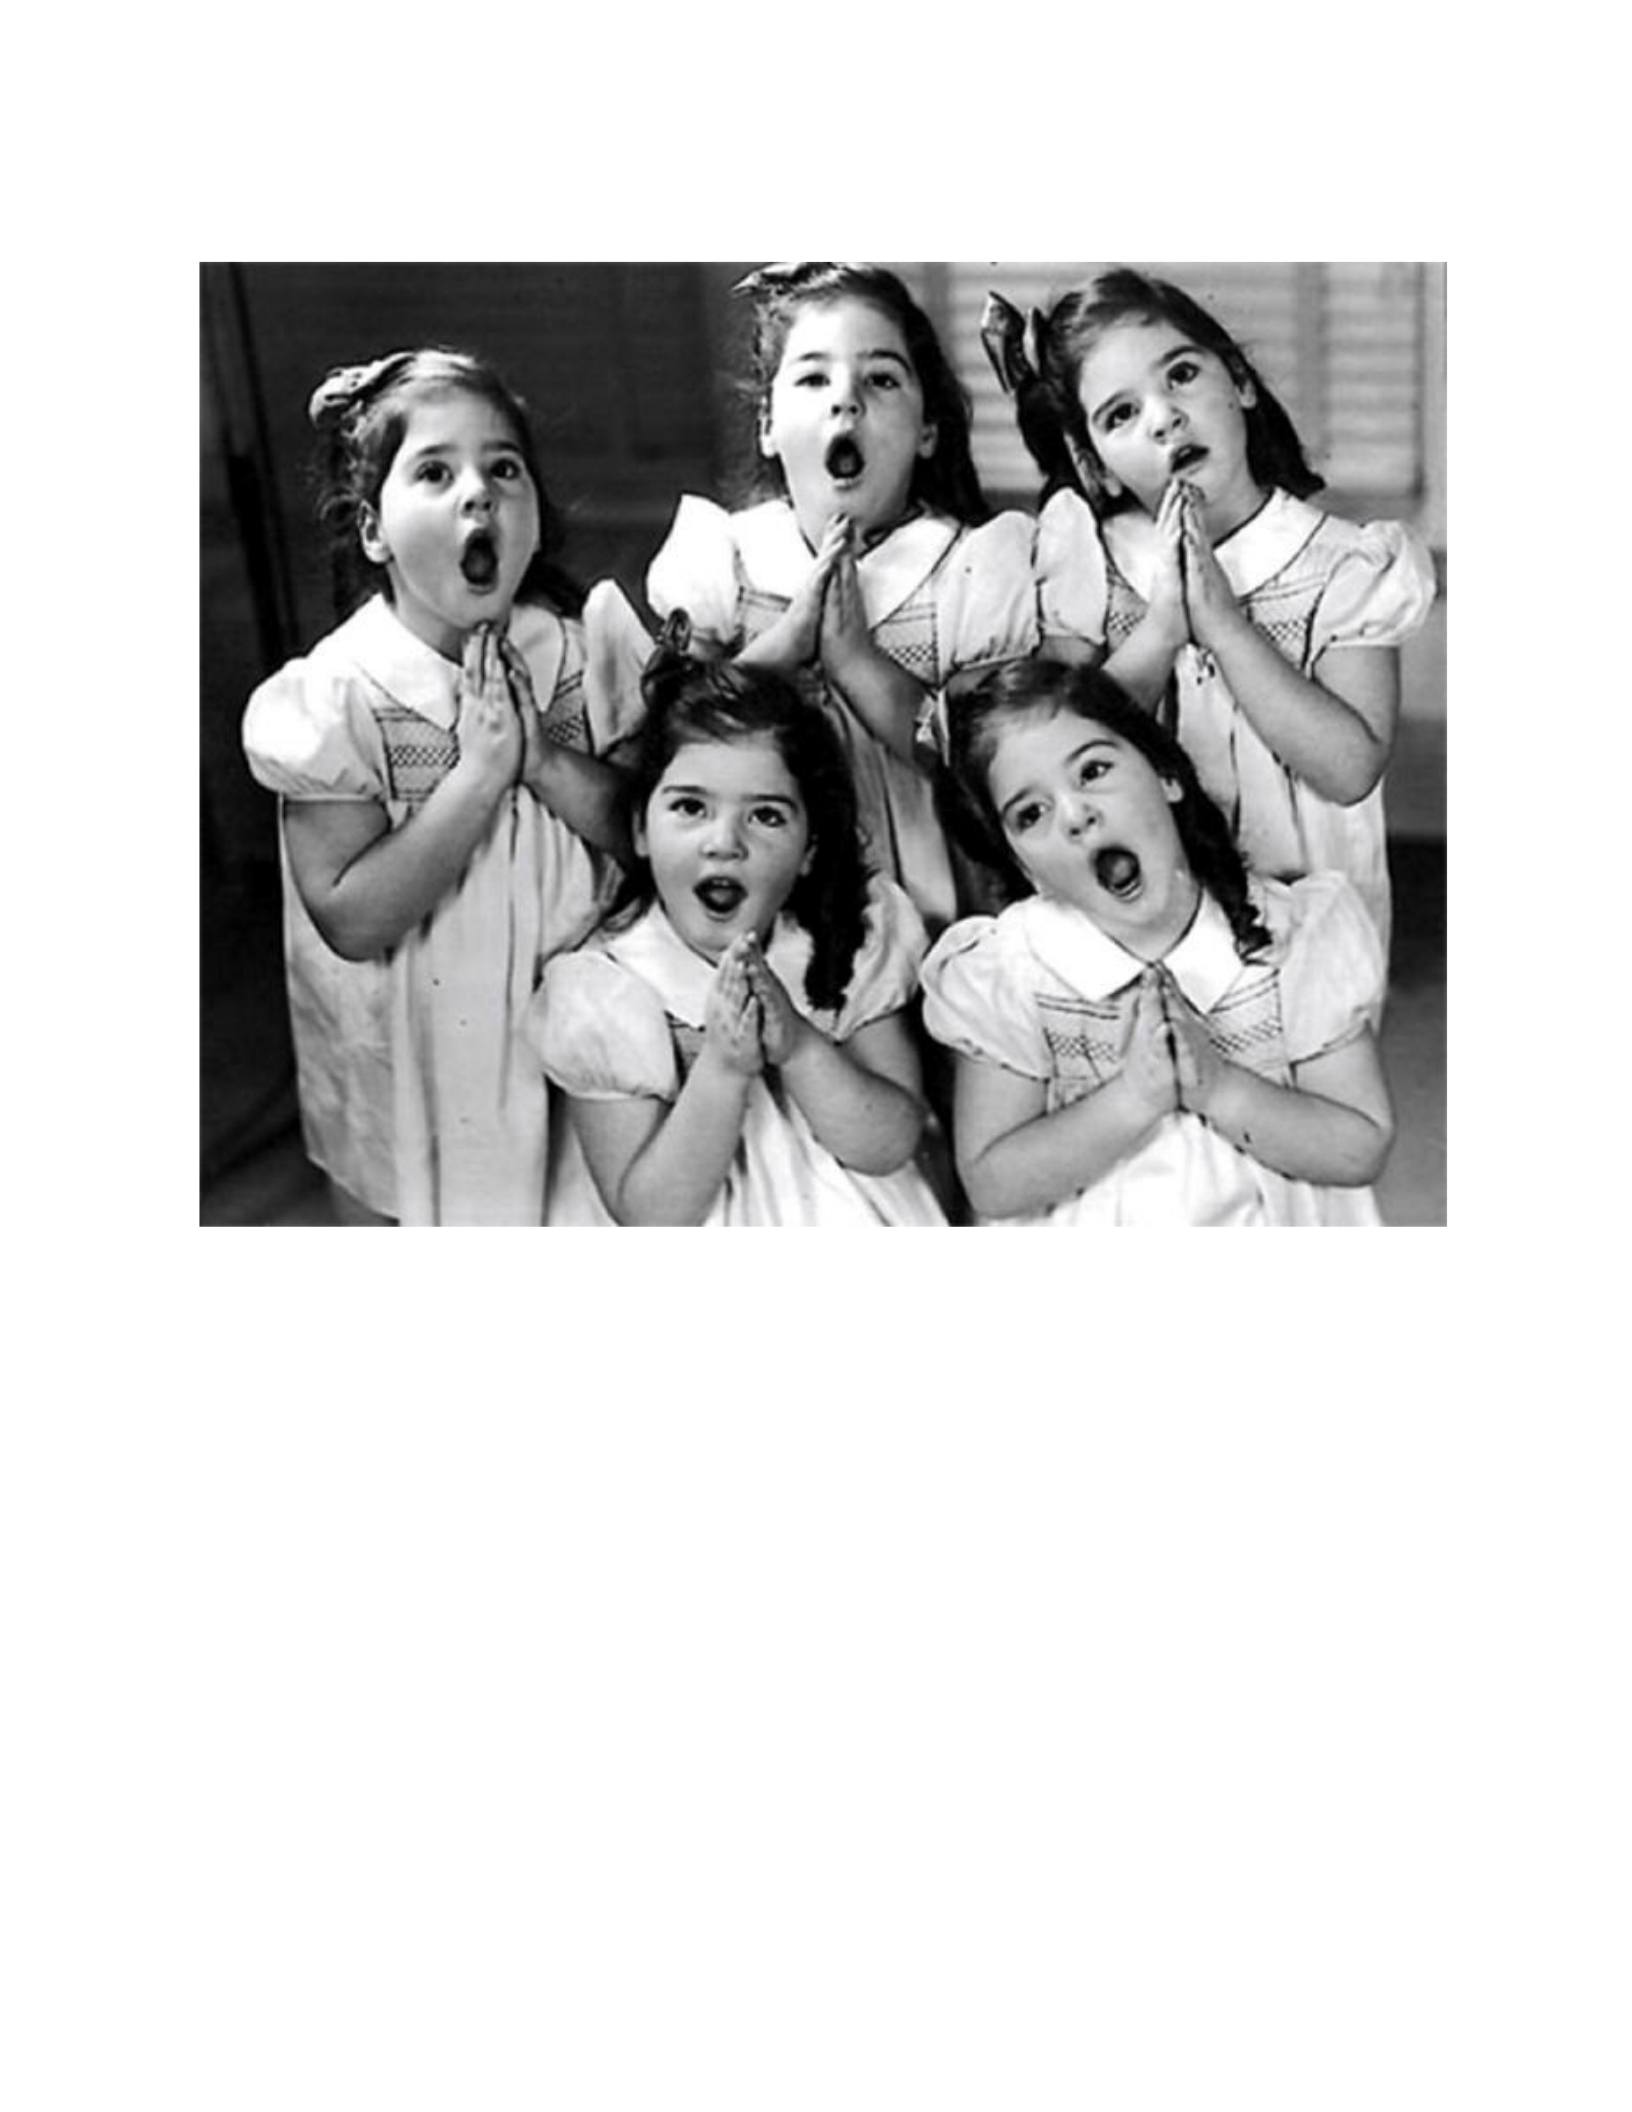
identical quintuplets known to have survived their infancy were the Canadian Dionne
quintuplets, all five of which survived to adulthood (Figure 2.1). Alternatively, twins or multiples
originating from two or more ova that are fertilized by separate spermatozoa are called dizygotic
(DZ) [11] or trizygotic in the case of triplets. Nowadays, higher-order births of nonidentical twins
often are the result of assisted reproductive technologies (ART).
35
Figure 2.1 – The Dionne quintuplets
The Dionne quintuplets, born May 28, 1934, outside of Callander, Ontario, Canada. Despite
being born 2 months premature, all five quintuplets survived to adulthood. Image obtained from:
https://commons.wikimedia.org/wiki/File:Dionne_quintuplets.jpg
Multiple gestation pregnancies are inherently high risk to both the mother and the
developing fetuses. Certain twin pregnancies, specifically those possessing a single chorion
(monochorionic), exhibit an even higher risk for numerous pre- and perinatal complications.
Therefore, information about the status of the developing fetal membranes is helpful for
monitoring and improving the outcome of a multiple gestation pregnancy.

In early-stage human development, the membranes of the placenta begin to form around
day 4. Examination of placental membranes by ultrasound imaging serves as a non-invasive
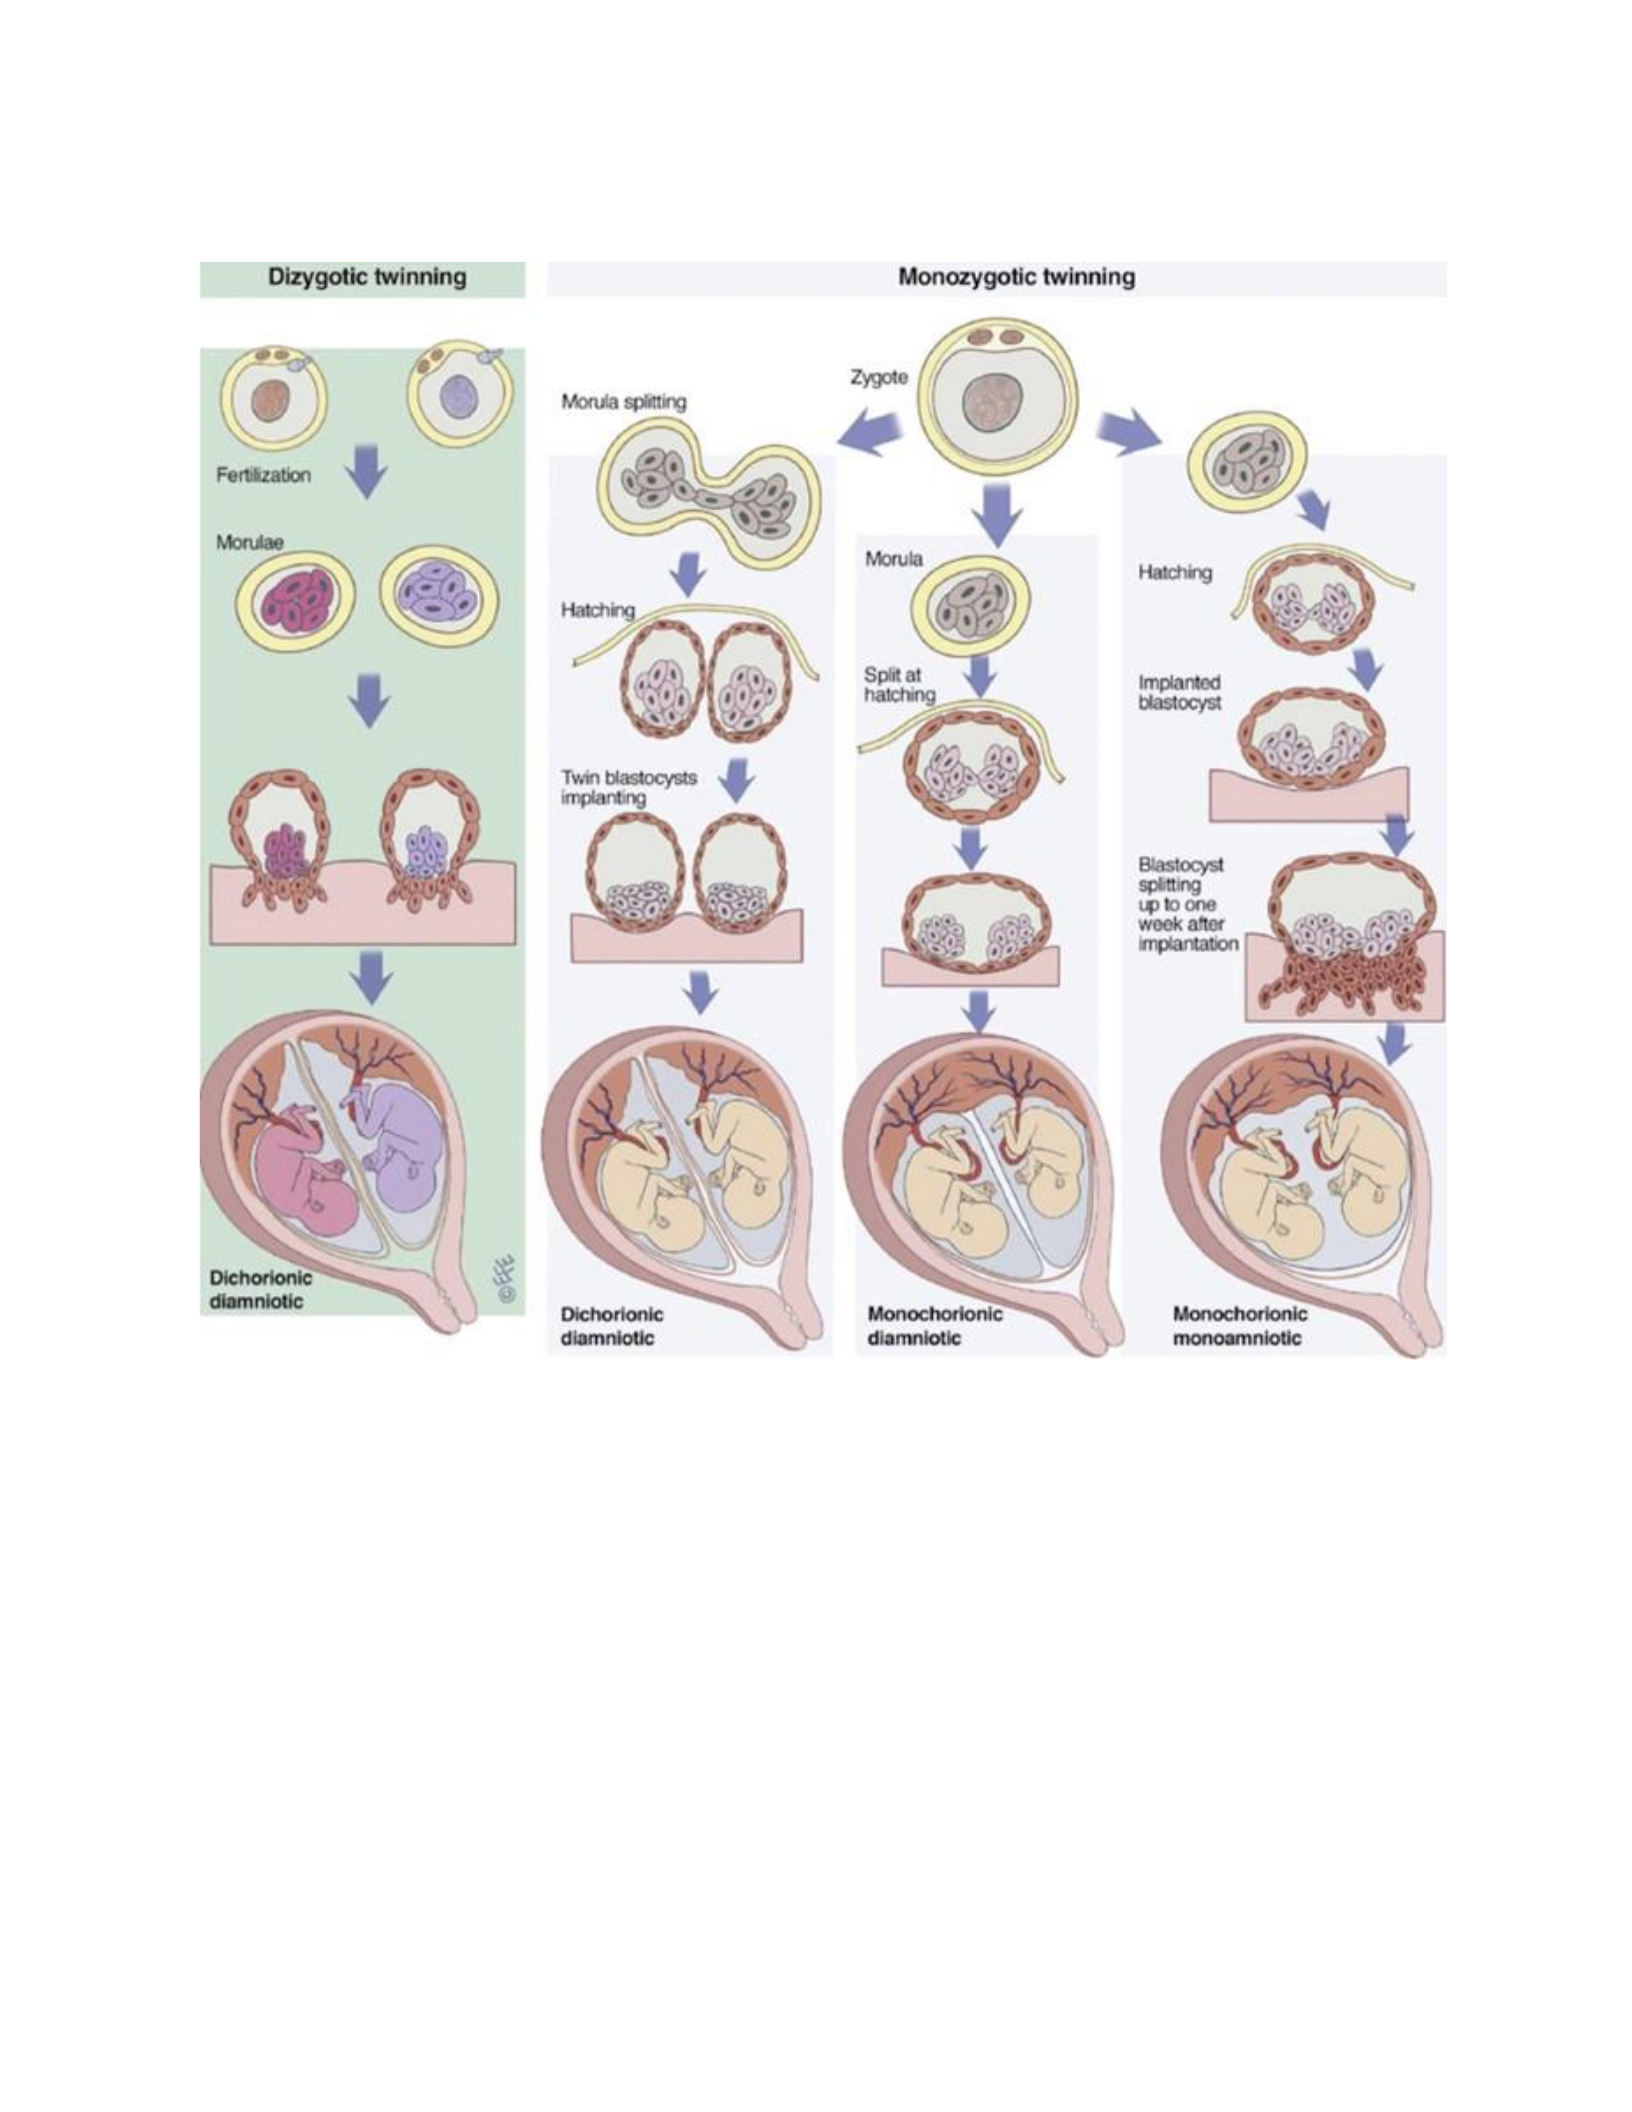
method for determining zygosity/twin status [12-15]. According to the traditional models of
twinning (Figure 2.2), DZ twins have distinct placentas and fetal membranes and are therefore
dichorionic diamniotic, although fused membranes are possible. Approximately two-thirds of all
MZ twins share one placenta with monochorionic diamniotic membranes, while roughly onethird
have completely distinct placentas and membranes (dichorionic diamniotic). Only about 1% of
MZ twins have one set of membranes and one placenta, making them monochorionic
monoamniotic. The latter case poses the highest risk for pre- and perinatal morbidity and
mortality.
The placenta and membranes of a multiple gestation pregnancy represent the first means
of identifying some MZ twins due to the presence of a single chorion. Although MZ twins will be
of the same sex, not all same-sex twins are MZ. Therefore, for all same-sex twin pairs, DNA
typing is the most useful and reliable method for determining zygosity [17]. Challenging the
assumption that a single chorion indicates monozygosity, it is also possible for DZ twins to
possess monochorionic diamniotic placentas. Thus, the dogma of a single chorion being
synonymous with monozygosity is no longer proper due to chimeric DZ twins [18], a
phenomenon in which one individual is composed of cells from two or more zygotes.
37
Figure 2.2 – The traditional model of twinning
The formation of the two main types of twins according to the traditional model of twinning. DZ
twins are the result of two distinct fertilization events and are dichorionic and diamniotic. MZ
twins result from the postzygotic splitting of a single embryo early in gestation with varying
numbers of fetal membranes depending on the timing of embryo splitting. Figure obtained from
McNamara et al. [16].
In normal embryogenesis, the chorionic membrane begins to form at about day 3. It is
believed that if zygote separation takes place early, typically between day 1 and day 3, the result
is MZ twins with separate placentas and membranes (dichorionic diamniotic). Alternatively,

monochorionic diamniotic MZ twins result after the chorion has formed (day 3) but before the
amnion has formed (typically between day 6 and day 8). Therefore, postzygotic splitting
resulting in monochorionic diamniotic MZ twins typically occurs between day 3 and day 8. MZ
twins with monochorionic monoamniotic membranes likely arise by splitting between day 8 and
day 13. Conjoined twins are thought to arise after the beginning of the formation of the primitive
streak, likely after day 14. However, the timing and mechanism(s) are not clear and empirical
evidence is rare.
2.4 Zygosity Determination
2.4.1 Physical Appearance
For research purposes, twin zygosity is often and most easily determined from
questionnaires regarding the similarity of physical characteristics. For instance, twins that are
equal on most physical features and frequently confused for one another are typically judged to
be MZ. Alternatively, twins that differ on two or more physical characteristics and/or are not
often mistaken for one another are often classified as DZ. As a whole, zygosity assessment from
survey responses of physical traits corresponds rather well with zygosity determination through
DNA typing [19, 20]. Apart from DNA testing, other basic rules routinely employed for zygosity
determination are if the twins are opposite-sex – DZ, of discordant blood groups – DZ, or
possess a single, non-fused, placenta – MZ (please note the presence of two placentas does not
imply DZ).

39
2.4.2 Placentation
Placental examination of a twin birth is common to establish the type of chorion and infer
zygosity. DZ twins, except for chimeric twins, have two placentas with two chorions and two
amnions. Thus, most DZ twins have dichorionic diamniotic placentation. Although the placentas
of DZ twins can sometimes appear fused, yet they are functionally independent and with no
inter-placental communication. Placentation in MZ twins is thought to vary depending on the
timing of postzygotic splitting following a single fertilization event. Dichorionic diamniotic MZ
twins (~33%) are formed if the split occurs early, on days 1–3, up to the morula stage.
Monochorionic diamniotic MZ twins (~66%) result if the split happens between days 3 and 8,
during which blastocyst hatching starts. Monochorionic monoamniotic MZ twins (~1%) occur if
the split occurs between days 8 and 13. If no split has occurred by day 13, conjoined twins form
[11, 16]. Examples of varying numbers of fetal membranes are also observed in triplets and
higher-order multiples, as shown in Figure 2.3 (images adapted from Lamb et al. [21]).
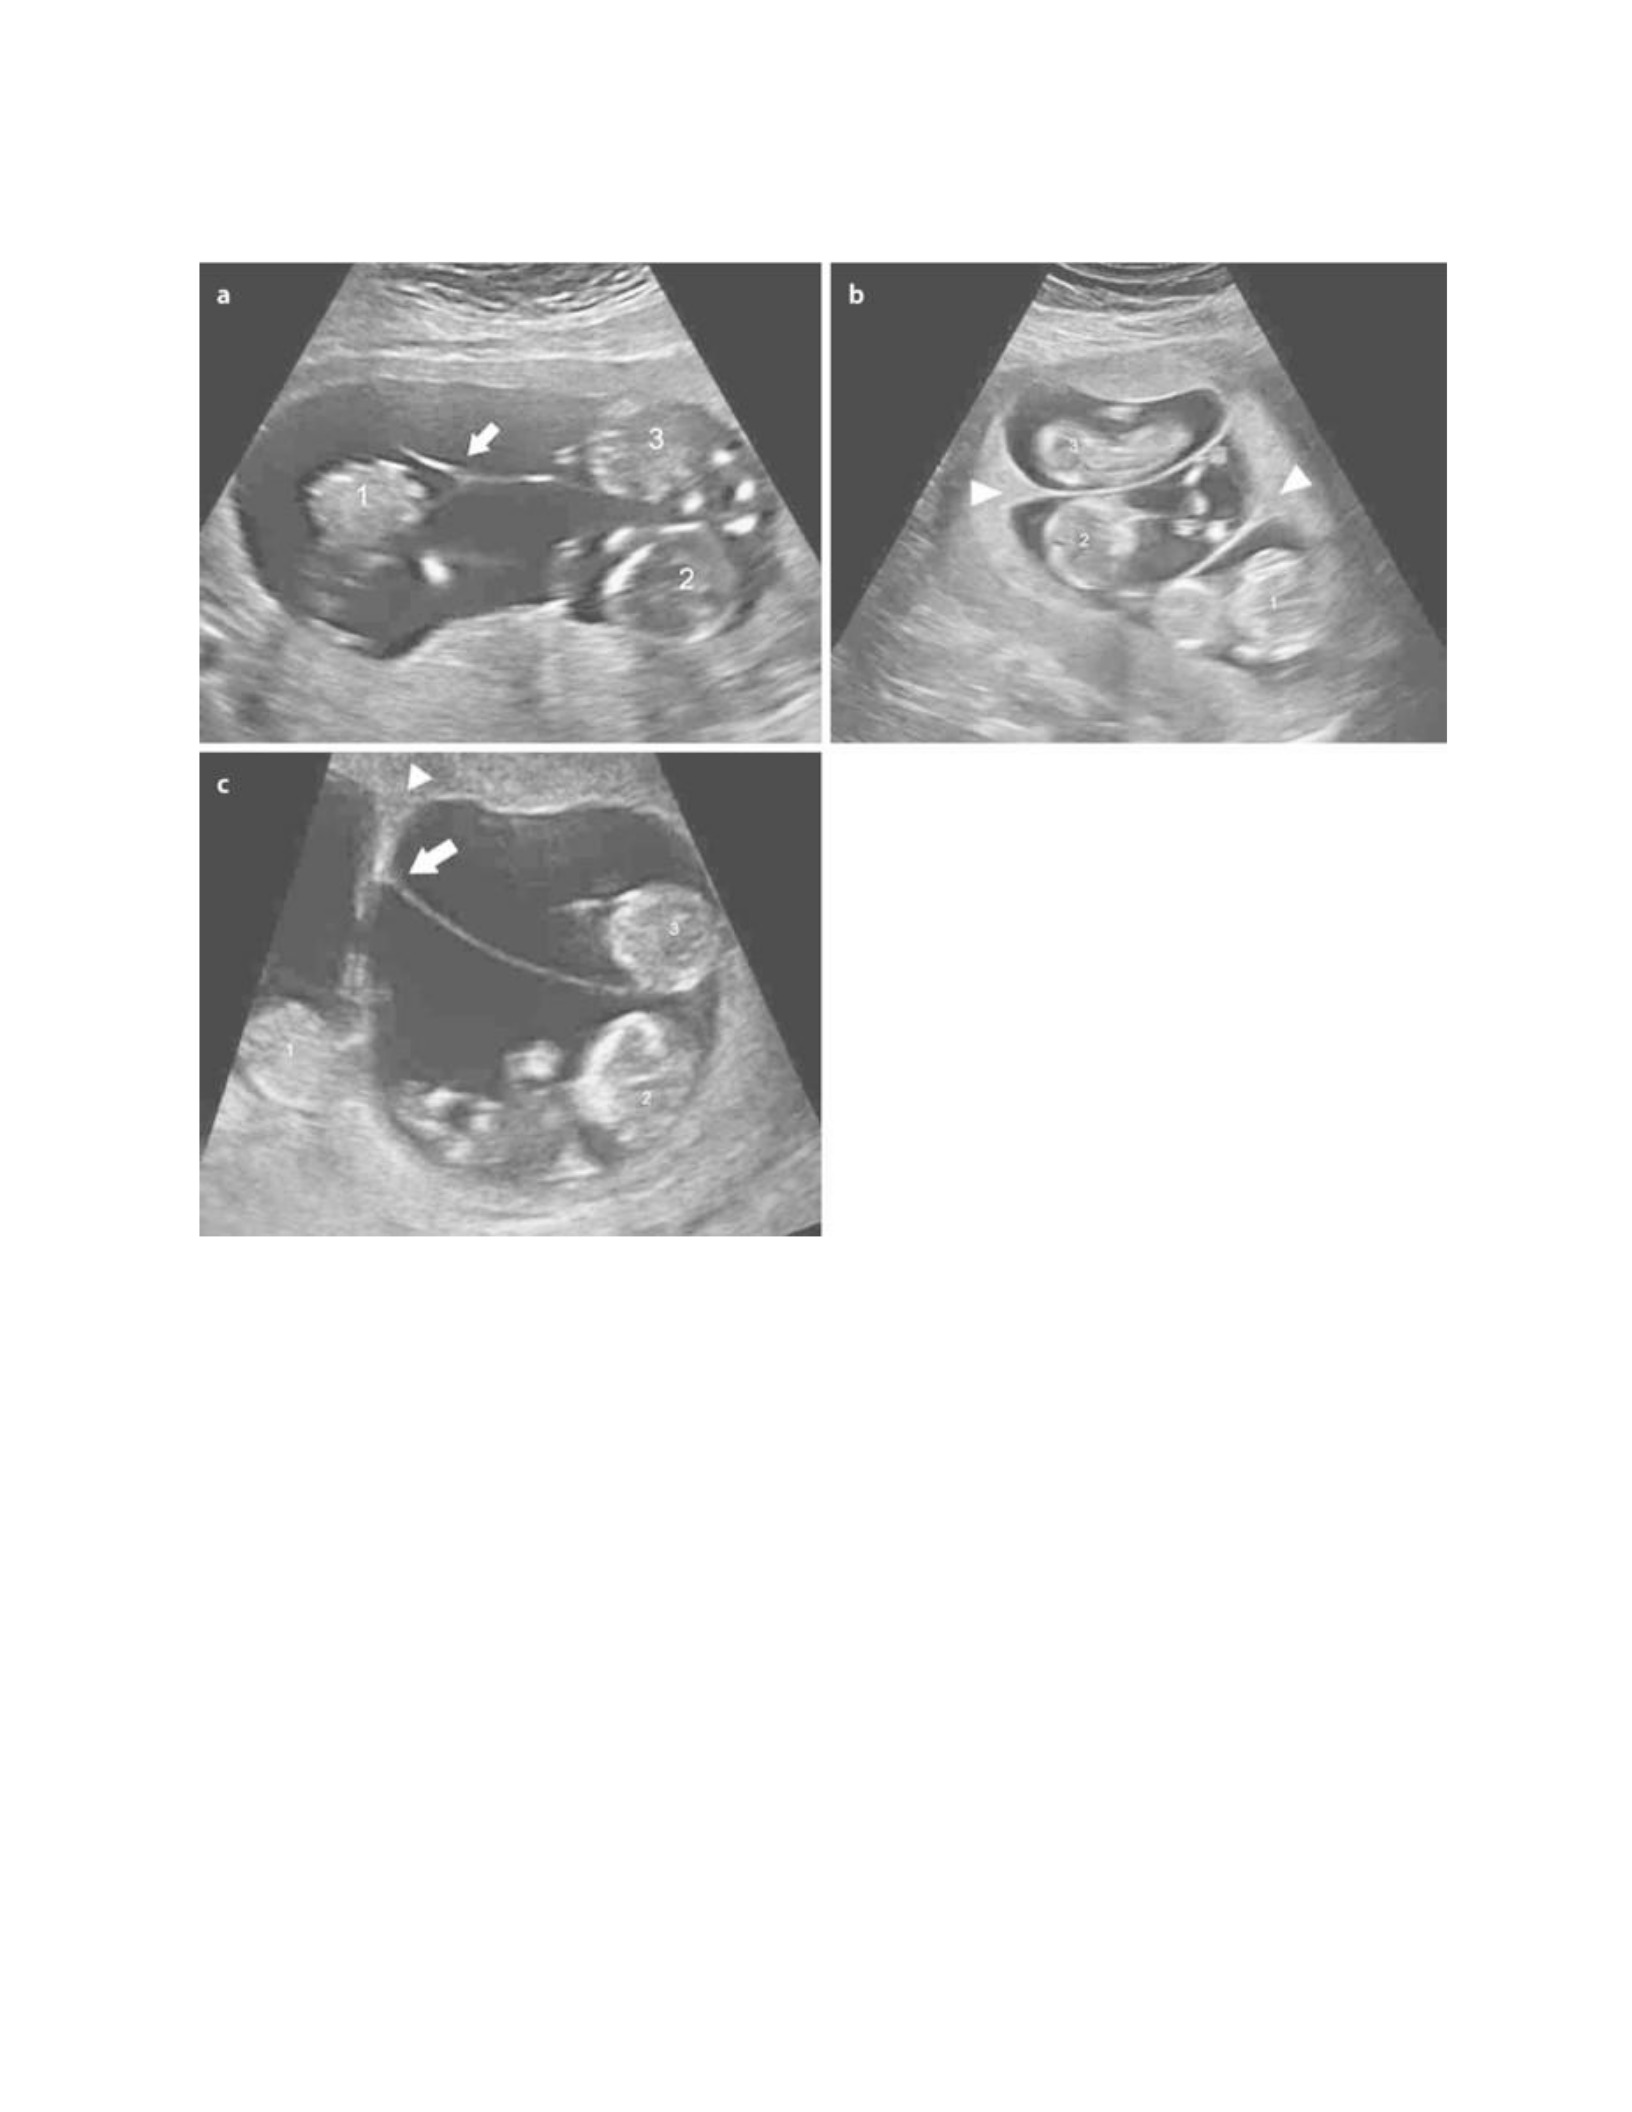
Figure 2.3 – Ultrasound images of triplets with varying numbers of fetal membranes
(a) Monochorionic and therefore monozygotic triplets at 12 weeks of gestational age. The arrow
indicates the meeting point of three amniotic membranes. Numbers indicate the three fetuses. (b)
Trichorionic triplets at 12 weeks gestational age. The arrowheads indicate the separation between
each fetus. These three fetuses do not share their placentas. This set of triplets can be trizygotic,
dizygotic (one identical pair), or monozygotic. Numbers indicate the three fetuses. (c)
Dichorionic, triamniotic triplets at 13 weeks gestational age. The arrowhead indicates the
separation of the chorionic membranes, which proves that this fetus does not share a placenta
with fetuses 2 or 3. The arrow indicates the amniotic membranes of fetuses 2 and 3, which are a
monozygotic pair. At this point in time, it is unsure if fetus 1 shares zygosity with fetuses 2 and
3. Numbers indicate the three fetuses. Figure adapted from Lamb et al. [21] with written
permission from Cambridge University Press.

41
2.4.3 DNA Typing
The most robust and reliable way of determining zygosity is by DNA typing. The advent
of cost-effective DNA genotyping has allowed for the opportunity to accurately determine
zygosity through quantitative measures of allele sharing between twins when biological samples
are available [22, 23]. Genetically, MZ twins will share (close to) 100% of their alleles, and on
average, DZ twins will share 50% of their alleles: similar to the allele sharing pattern of siblings.
The recommended minimum number of single nucleotide polymorphisms (SNPs) needed to
assess zygosity is around 50 [23]; however, utilization of approximately 20,000–30,000 SNPs
bolsters confidence in zygosity determination. Procedurally, after genotyping and quality control,
an optimal number of SNPs are selected, and allele sharing in all pairs is determined. Sharing is
reported as a proportion of markers for which a pair shares zero alleles (Z0), one allele (Z1), and
two alleles (Z2). From the proportions, total allele sharing (represented by 𝜋) is calculated with
the following formula: 𝜋 = Z2 + 0.5 * Z1. MZ pairs are identified by finding pairs with a 𝜋 >
0.90, allowing for some measurement error. DZ pairs are defined as pairs with a 𝜋 and Z1
between ~0.30 and ~0.70 [22].
2.5 Etiology of Twinning
2.5.1 Genetic Causes of MZ Twins
There have been several reports of families in which MZ twinning occurs more frequently
than expected [24-29], although there is no compelling evidence to support an underlying genetic
contribution to MZ twinning. Instances of familial MZ twinning from both maternal and paternal
lineages have been documented, yet it has also been suggested that independent of the sex of the

parent transmitting the gene, a single gene is responsible for MZ twinning [28, 30]. Additional
evidence suggests that there is no paternal effect on familial MZ twinning [31].
More recently, a gene thought to likely play a role in MZ twinning is PITX2. The PITX2
gene was found as a candidate for monozygotic twinning in a molecular screening of an
“experimental twinning” model in chickens [32]. PITX2 encodes a protein that acts as a
transcription factor, regulating the expression of genes involved with the formation of the
embryonic axis.
2.5.2 Generation of MZ Twins
The universally accepted model of MZ twinning, frequently referred to as the “fission
model,” rests on the hypothesis of postzygotic splitting of the conceptus within the first 2 weeks
of development [16]. As exemplified by the model, the number of fetuses, chorions, and amnions
results from the timing of embryo division. An alternative model of MZ twinning, sometimes
called the “fusion model,” challenges the traditional postzygotic splitting conjecture. The fusion
model has been suggested due to criticisms of the traditional model lacking scientific evidence
and the lack of specification of cleavage initiating factors [33]. The proposed alternate theory is
based on two premises: (1) – MZ twinning occurs during the first cleavage division, resulting in
twin zygotes, and (2) – the structure of the fetal membranes is dependent on the various modes of
fusion of the fetal membranes within the zona pellucida. Despite the two theories, the
embryological processes that govern MZ twinning are still largely unknown and up for debate
[34].

43
2.5.3 Genetic Causes of DZ Twins
DZ twinning is a complex trait that is likely under the influence of multiple genes. In the
last decade, astonishing progress in characterizing the genes responsible for DZ twinning has
been made. However, a comprehensive understanding of the genetic factors underlying the
human tendency to conceive DZ twins is still lacking. Bearing this in mind, there are a number of
genes with known roles in ovulation, female fertility, and DZ twinning in humans [35]. For
example, mutations resulting in amino acid changes of the follicle-stimulating hormone receptor
(FSHR) protein have been shown to influence DZ twinning [36]. Additionally, a variant within
the promoter region of the FSHR gene was found to segregate with DZ twinning in a large family
[37]; however, other studies have not replicated the involvement of this gene [38]. Several other
candidate gene studies have provided evidence suggesting the involvement of other genes in the
DZ twinning process, namely, serpin family A member 1 (SERPINA1) commonly referred to as
alpha-1-antitrypsin [39, 40], peroxisome proliferator-activated receptor gamma (PPARG) [41],
and the fragile X “premutation” (FRAXA) [42, 43], although results were not replicated in future
studies.
Linkage studies in family-based study designs have not provided evidence of enhanced
genetic sharing among affected family members over chromosomal regions harboring the
previously described candidate genes [37, 44]. However, linkage studies have indicated
chromosomal regions that may possess novel candidate genes for DZ twinning [37, 44, 45]. For
example, a study of 525 Australian and Dutch families of DZ twinning demonstrated the
presence of new candidate DZ twinning genes on chromosomes 6, 12, and 20 [37]. The results
reaffirmed the notion that DZ twinning is a complex phenotype influenced by numerous genes.

Mutations in growth differentiation factor-9 (GDF9) appear to influence DZ twinning in humans,
albeit such mutations appear to be rare. Screening in large numbers of families with a rich history
of DZ twinning revealed a two-base deletion in GDF9 in heterozygous form resulting in a loss-of-
function mutation in three families [46, 47]. It was also discovered that overall genetic variation in
GDF9 is more prevalent in mothers of DZ twins compared to controls [47]. Findings from non-
human studies (e.g., sheep) of DZ twinning have implicated bone morphogenetic protein 15
(BMP15) and bone morphogenetic protein receptor 1B (BMPR1B) in the DZ twinning process;
however, similar effects have not been found when studying BMP15 [48] or BMPR1B [49] in
humans. Both GDF9 and BMP15 are expressed in the oocyte and are essential for follicular
development, and have been implicated in premature ovarian failure [50]. BMPR1B is expressed
in multiple cell types of the ovary and is the cognate receptor for BMP15. Surprisingly, while
heterozygous mutations (one copy present) in GDF9 and BMP15 increase twinning rates,
homozygous mutations (two copies present) result in female infertility.
More recently, genome-wide association studies (GWAS) have made it possible to scan
the entire human genome for SNPs associated with a trait of interest in humans (e.g., twinning).
In 2016, the first meta-analysis of GWAS in European-ancestry populations (Netherlands,
Australia, Minnesota [United States of America]) identified the first common genetic variants
associated with spontaneous DZ twinning [51]. Three statistically significant SNPs were found:
in the upstream region of the follicle-stimulating hormone beta subunit (FSHB) gene, within an
intron of the mothers against decapentaplegic homolog 3 (SMAD3) gene, and in an intergenic
region on chromosome 1. The two SNPs near FSHB and within SMAD3 were replicated in an
independent Icelandic cohort. The former encodes the beta subunit of FSH, while the gene
product of the latter is a transcription factor involved in gonadal responsiveness to FSH.

45
Sixtythree candidate genes of DZ twinning [52] were also tested, but only FSHB was associated
with DZ twinning in gene-based tests. Interestingly, the replicated SNPs associated with twinning
were also found to be associated with higher serum FSH levels, and with multiple aspects of
female fertility, including earlier age at menarche, earlier age at first child, higher lifetime parity,
earlier age at menopause, and later age at last child. Polygenic risk scores for DZ twinning were
found to be significantly associated with DZ twinning in the independent Icelandic cohort, with a
higher likelihood of having children, higher lifetime number of children, and an earlier age at
first child. Together these findings corroborate the link between fertility and DZ twinning.
2.5.4 Generation of DZ Twins
Mechanisms leading to dizygotic twins operate on the selection of developing follicles
within the ovary when instead of one ovum being released mid-cycle, two follicles mature, and
both oocytes are released for fertilization. The subsequent fertilization of two eggs by two sperm
during a pregnancy results in DZ twins. The processes of ovarian folliculogenesis and dominant
follicle selection are governed by both circulating and intra-ovarian concentrations of FSH.
Spontaneous DZ twinning tends to run in families and is associated with elevated concentrations
of FSH in the mother [53]. FSH amounts seem to vary with geography, season, ethnic origin, and
increasing parity, and are increased in tall, heavy, and older mothers with a peak at around 37
years of age [54]. Following this logic, it has been proposed that age-dependent twinning may
also be due to natural selection favoring double ovulation events in response to declining fertility
with increasing age [55]. It has also been documented that mothers of DZ twins have an
increased number of FSH pulses during the early follicular phase, without a concurrent
luteinizing hormone (LH) pulse [56].

It is well known that improved nutrition is a contributing factor for increases in multiple
ovulation (i.e., twinning frequency) in other species [57, 58], yet this has not been demonstrated
in humans. In fact, human twinning rates do not appear to reflect the average nutritional status as
established from longitudinal studies of countries experiencing extended periods of starvation,
such as the Dutch hunger winter [59]. In general, above a specific yet undetermined threshold,
nutrition seems to be of minimal importance for twinning and reproduction in general.
2.6 Incidence of Twins
In the early twentieth century, Wilhelm Weinberg postulated a method, referred to as the
“Weinberg differential rule,” for approximating population estimates of the number of MZ versus
DZ twins [60]. Weinberg’s proposal assumed that all MZ twins and half of DZ twins would be of
the same sex, with the other half of DZ twins being of the opposite sex. Therefore, he suggested
multiplying the number of opposite-sex twins by two, which served as an estimate for the total
number of DZ twins. The excess of same-sex twins would then be the number of MZ twins.
Thought of in a different way, subtracting the total number of opposite-sex twins from the
number of same-sex twins would yield an estimate of the number of MZ twins. Weinberg’s
calculation has been widely adopted because it serves as a simple method for estimating twinning
frequency in populations; however, it rests on the assumption that the frequency of same-sex
twins is the same as that of opposite-sex twin pairs, which may not always be the case [61, 62].
The rate of twinning includes stillbirths (≥28 weeks) and live births and is defined as the
number of twin maternities per 1000 maternities. Differences in twinning rates between
geographical regions have been studied extensively. In the 1970s, Bulmer studied twinning
frequencies in three distinct geographical regions: Europe/North Africa, Sub-Saharan Africa, and
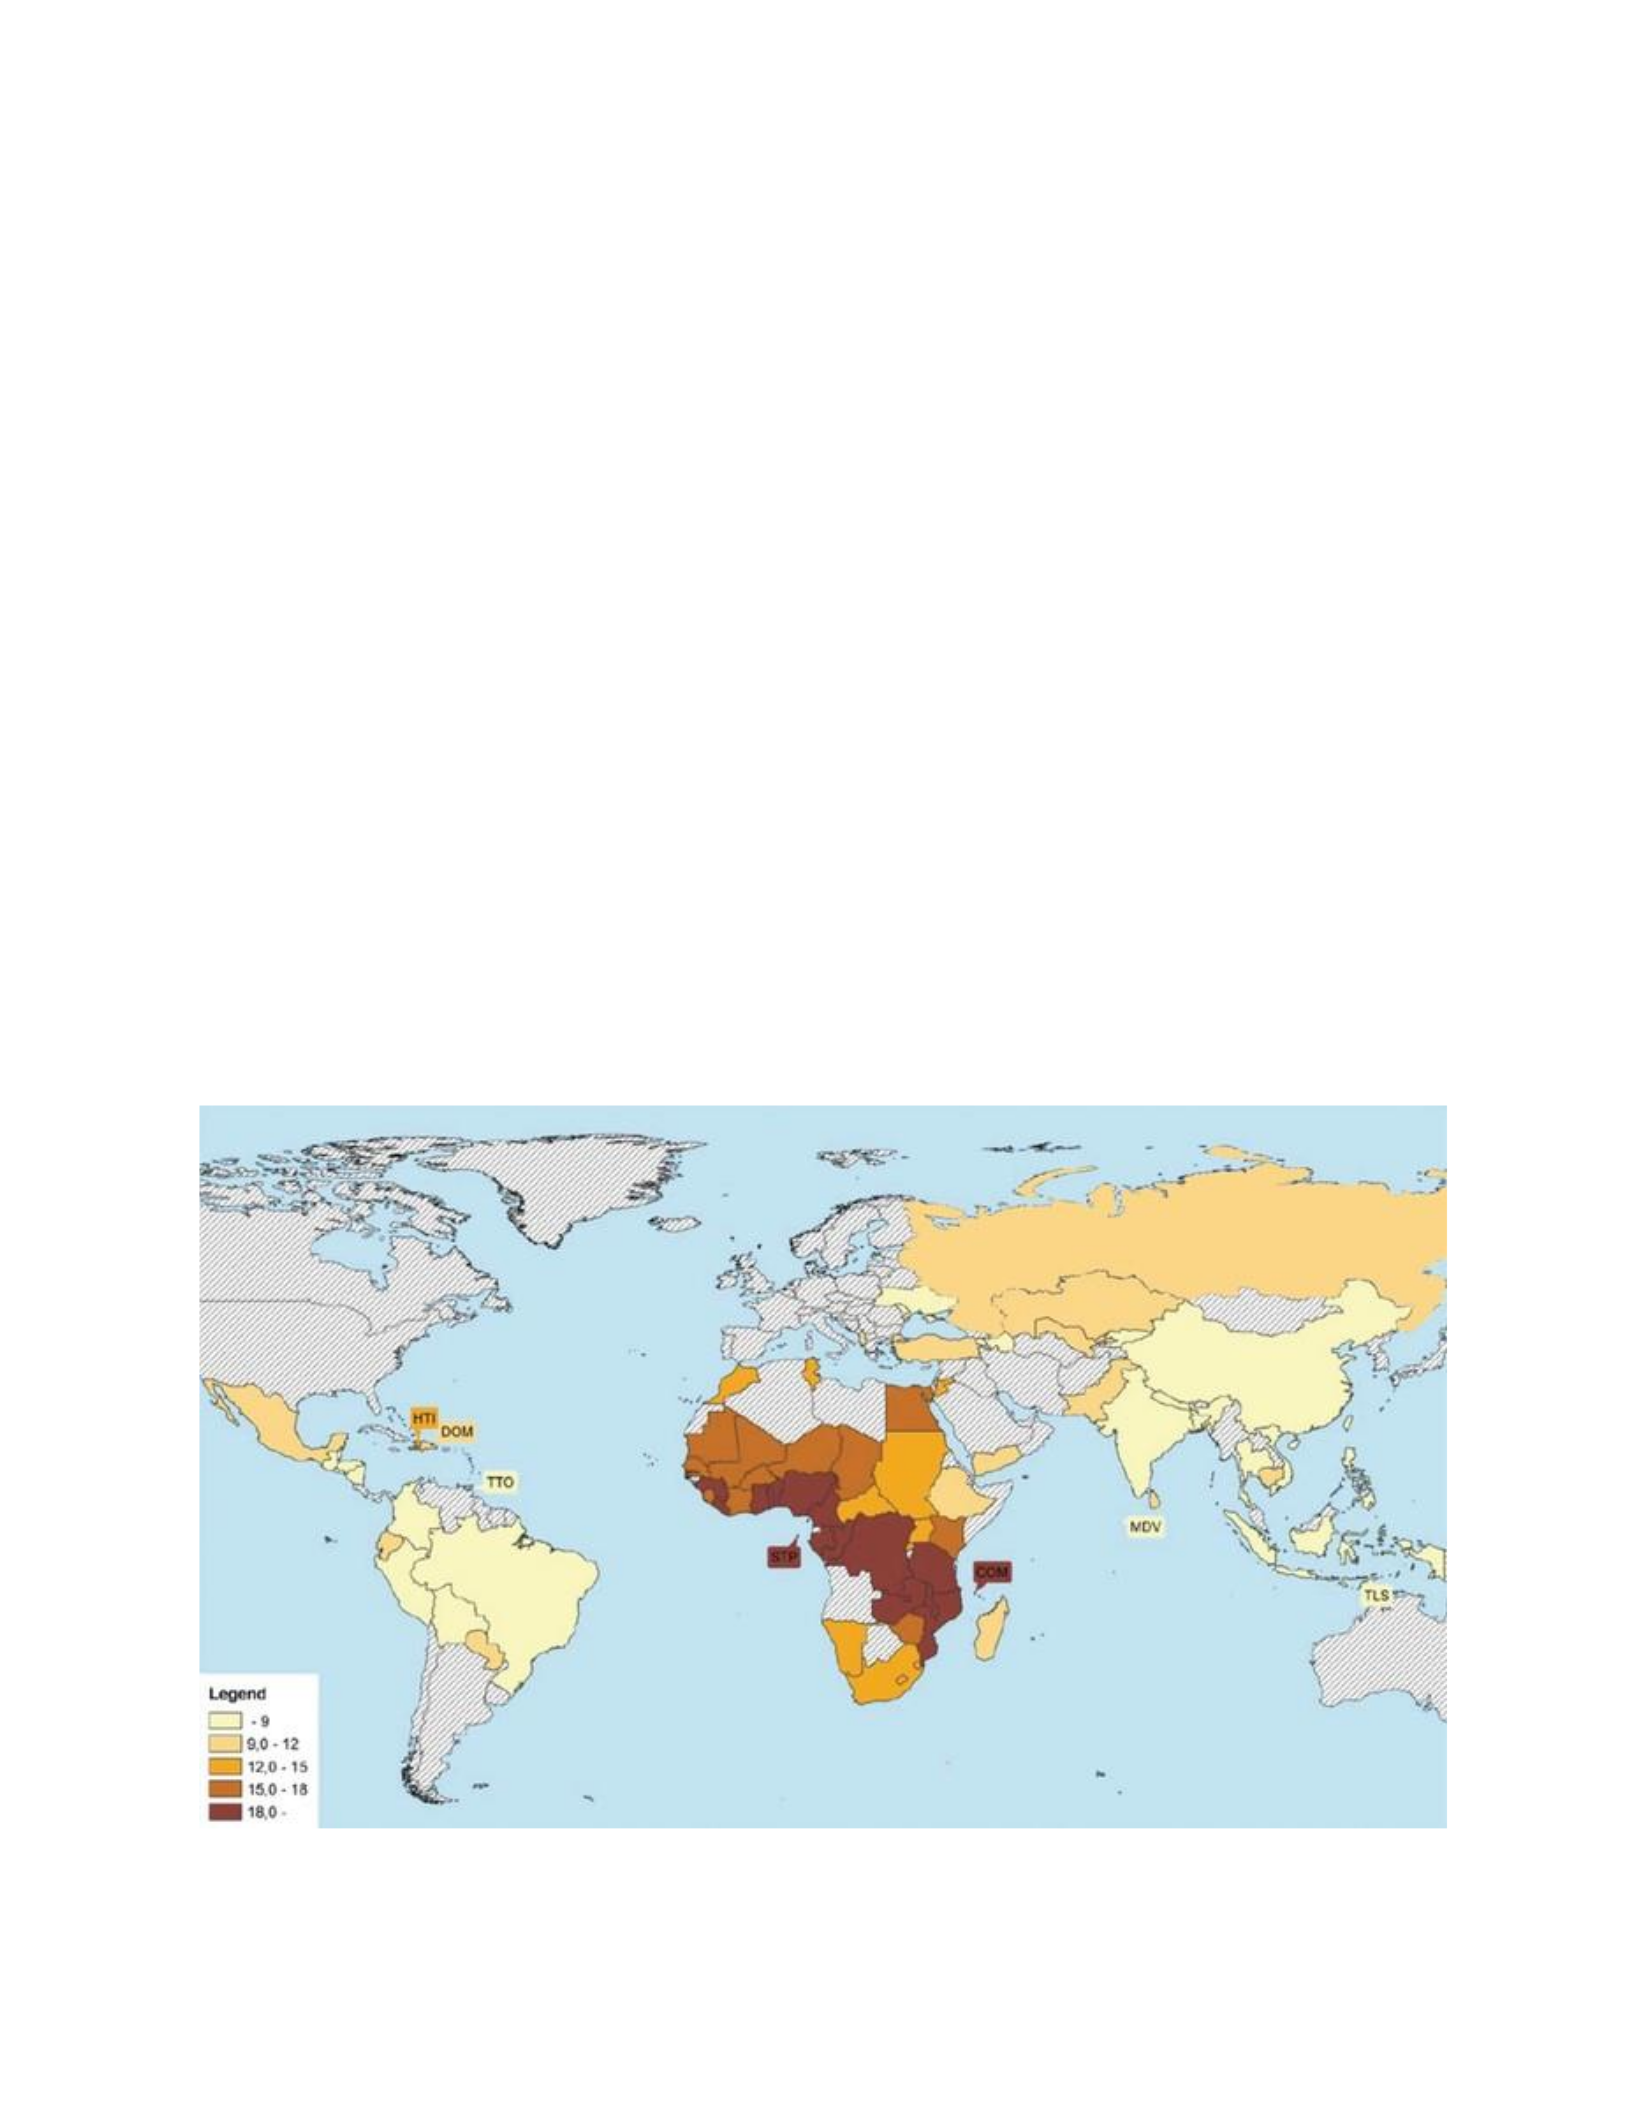
47
Asia [63]. Bulmer found that the highest rate of twinning occurred in Sub-Saharan Africa (~23
per 1000 maternities), while the lowest rate occurred in Asia (~5–6 per 1000 maternities).
Twinning rates exhibit considerable temporal and spatial variation (see Figure 2.4). Provided that
the MZ twinning rate is known to be fairly constant around the world, the variation in the overall
twinning rate is generally attributed to the variation in DZ twinning rates.
Global twinning rates have predominantly been reported from Western countries, with
less known about twinning rates in Eastern countries. In 2017, data received from open resources
of national statistics of the Ministry of Health of the Russian Federation reported a multiple birth
rate of 12.27 births per 1000 deliveries (alive or stillbirth) as seen in Table 2.1 [65]. The overall
twinning rate during this time was reported to be 12.09 per 1000, and the rate of higher-order
multiples occurred at a rate of 0.18 per 1000.
Figure 2.4 – Rates of twinning worldwide

Heatmap showing the number of twins per 1000 births in 77 countries. Huge variation in
twinning rates can be observed across the different regions of the developing world. Figure
adapted from Smits and Monden [64] by Veronika Odintsova to include 2011 Russian twinning
rates.
‘[s9]
sonsiyeys
[euoTeU
URISssNy
UO
paseq
BAOSUIPO
eyIUOIaA
Aq
poprAoid
pue
poyeolo
sem
[°Z
9[qR:
8T'0
60'%7E
LEU
20°0
TZ'T EZ'T
LOE
S66
-GEZ‘0Z
28L'609'T
»
eiseny
Japio Japio
)
Japio
d1U1]9
apis}no
Jayziy
pue
e
Jayziy
pue
e
Jaysziy
pue
e
usog
Sulpnyoul
s}9|diL
SUIML
aidtinwy
sj3a|diu
SUIML
aiddinyy
sya|dUL
SUIML
aidtinw
‘SOLIDAIAP
IV
OOOT
Jed
aze
yg
SOMaAap
jje
Ul
UOIOdOlg
Jaquunu
|e}0L
LIOZ
Ul
UOHeASpay
UvIssNY
UT
sypATg
afd!
-
[°Z
F148)
49

2.6.1 Incidence of MZ Twins
Worldwide and across all races, MZ twin birth rates occur at a constant rate of
approximately 4 in every 1000 pregnancies [66]. The remarkable consistency in MZ twinning
rates among all populations suggests that identical twinning is an occurrence that is not
influenced by genetics. Unlike DZ twinning, the incidence of MZ twins is independent of
maternal age, height, weight, or parity [67]. Although MZ twinning appears to be a sporadic
event, instances of familial MZ twinning of varying modes of inheritance have been reported,
with one report of autosomal dominant inheritance with variable penetrance [68]. The
introduction of assisted reproductive technologies (ART) greatly enhances rates of DZ twinning
and, to some extent, MZ twinning [69]. The increase in MZ twinning rates due to ART has been
attributed to mechanical forces affecting the zona pellucida or to the effects of incubation media
and late implantation in in vitro fertilization procedures [70-72].
2.6.2 Incidence of DZ Twins
DZ twinning is common, yet large regional differences in DZ twinning rates exist around
the world. The rate of DZ twins ranges from approximately 6 per 1000 maternities in Asia to 10–
20 per 1000 in Europe and the United States, to as high as 40 per 1000 in certain regions of
Africa [11]. DZ twinning rates also vary substantially over time. In the United States, the
observed incidence of twin births increased by a factor of 1.9 between 1971 and 2009 [73]. A
considerable portion of the increase is attributable to fertility treatments, with an estimated 36%
of all twins born in the United States in 2011 resulting from ART [73, 74]. DZ twinning rates
peaked in the mid-2000s, following the number of ART pregnancies. In developed countries,
with technological advancements and careful monitoring, DZ twinning rates due to ART have

51
dropped substantially. In contrast to MZ twinning, spontaneous (i.e., no ART) DZ twinning is
also very dependent on many maternal factors, including age, nationality, parity, height, weight,
and family history [35, 54].
2.6.3 Triplets and Higher-Order Multiples
The pattern of variation in triplet rates across the world is remarkably similar to that
observed for twin births. That is, rates of triplet births are highest in African countries,
intermediate in European populations, and lowest in Asian countries. More generally, the rate of
triplets is in accordance with Hellin’s law [75], which states that there is on average one twin
maternity per N singleton maternities and that there is one X-tuplet maternity per N(X–1) [76, 77].
Thus, if the number of twin maternities is one in N singleton maternities, then the number of
triplets is one in N(3-1). It follows that quadruplets (see Figure 2.5) would occur at a rate of N(4-1).
According to this logic, if there is one twin in every 80.05 births, this predicts that triplets occur
at a rate of about 1 in every 6408 births, which is only 4% higher than the incidence actually
observed [64].
Figure 2.5 – Painting of Dutch quadruplets
“Vierling Costerus” – Painting of quadruplets born on June 9, 1621, in Dordrecht, the
Netherlands. Remarkably, the birth of the first (Pieter) and the last (Maria) was separated by 53
hours, indicating an extremely difficult birthing process. Prior to the quad birth of one boy and
three girls as pictured here, the parents mentioned the birth of twins 7 years before. Sadly, due to
the high infant mortality rate in the seventeenth century, about 40–50% of children did not reach
the age of 18, and the chance of survival was even smaller for multiple births. In the case of the
quadruplets pictured here, one died an hour and a half after birth (Elisabet), and two others
deceased within the first year. Figure obtained by written permission from the Dordrecht
Museum. The Noordbrabants Museum in ‘s-Hertogenbosch received this painting as a gift in
1925 and presented it on loan to the Dordrechts Museum in 1986. Painter and client are
unknown.
2.7 Factors Affecting Twinning
Many of the risk factors for DZ twinning are rather well established and include assisted
reproductive technologies (ART), higher maternal age, parity, body composition, and smoking
[11, 35, 78]. For MZ twinning, there is little to no agreement regarding the involved risk factors

53
and/or causes [79]. Given that the two types of twinning are biologically distinct phenomena, it is
not surprising that many of the factors involved in DZ twinning are not, or to a lesser extent,
found in MZ twinning. Below we describe established risk factors involved in multiple
pregnancy and multiple birth.
2.7.1 Assisted Reproductive Technologies
Assisted reproductive technologies, especially in vitro fertilization (IVF) and ovulation
induction (OI), are well-established risk factors for DZ and, to some extent, MZ twinning [79].
Ovulation-inducing agents such as clomiphene citrate, human pituitary gonadotropins, and
human menopausal gonadotropins are known to increase ovulation rate and hence the probability
of multiple pregnancy [80]. In the case of IVF, increased multiple pregnancy and multiple birth
are due to the transfer of multiple embryos [11, 81]. Although less well understood, there is also a
slight increase in MZ twinning after IVF and other ART, with estimates ranging from a two- to
12-fold increase in MZ twinning rate after ART procedures [79] and a two- to fivefold increase in
MZ twinning following IVF [82, 83]. Notably, OI agents are often used in concert with IVF;
thus, the increased chance of multiple pregnancy following IVF cannot be merely attributed to
multiple embryo transfer [35].
2.7.2 Other Risk Factors
Higher maternal age is another well-established risk factor for DZ twinning [35, 63];
however, conflicting reports have been made for MZ twinning [63, 84, 85]. Paradoxically, while
fertility decreases with age, the spontaneous twinning rate increases. Both polyovulation and
embryonic survival rates increase with maternal age, suggesting that increased ovulation rate and

decreased spontaneous abortion of potentially unhealthy offspring could act together as an
insurance system to produce one last round of reproduction, with twinning being merely a
byproduct [55, 86]. Additionally, increased parity (the number of maternities prior to twin
pregnancy) is associated with a higher risk of DZ, but not MZ twinning [11, 87], independent of
maternal age [35, 88]. Moreover, maternal body composition has been reported rather
consistently in relation to DZ twinning, with both obesity and tall stature increasing the risk of
DZ twinning [53, 85, 89]. Furthermore, an unexpected relation between maternal smoking and a
higher probability of DZ twinning is sometimes observed, although the mechanism behind this
observation remains unclear [78, 90, 91].
2.8 Endocrinology of DZ Twinning
Mothers of spontaneous DZ twins have a predisposition to multiple ovulation events due
to interference with the selection of a single dominant follicle. Multiple follicle growth and
subsequent multiple ovulation events have been observed in mothers of hereditary dizygotic
twins [92, 93]. Follicular recruitment, selection, and dominance is controlled by a complex
regulatory network within the hypothalamic-pituitary-ovarian axis (Figure 2.6). The two main
pituitary-derived hormones essential for reproductive function are FSH and LH and are secreted
in response to the pulsatile secretion of gonadotropin-releasing hormone. FSH is the main
hormone controlling follicular growth, and its secretion is controlled by the main secretory
products of the large dominant follicle(s), namely, estradiol and inhibin. Circulating
concentrations of FSH, other intra-ovarian factors (e.g., GDF9 and BMP15), and their cognate
receptors physiologically regulate ovarian folliculogenesis and ovulation quota. Transcriptional
regulators of FSH, such as SMAD3, also regulate gonadal responsiveness to FSH. Ongoing
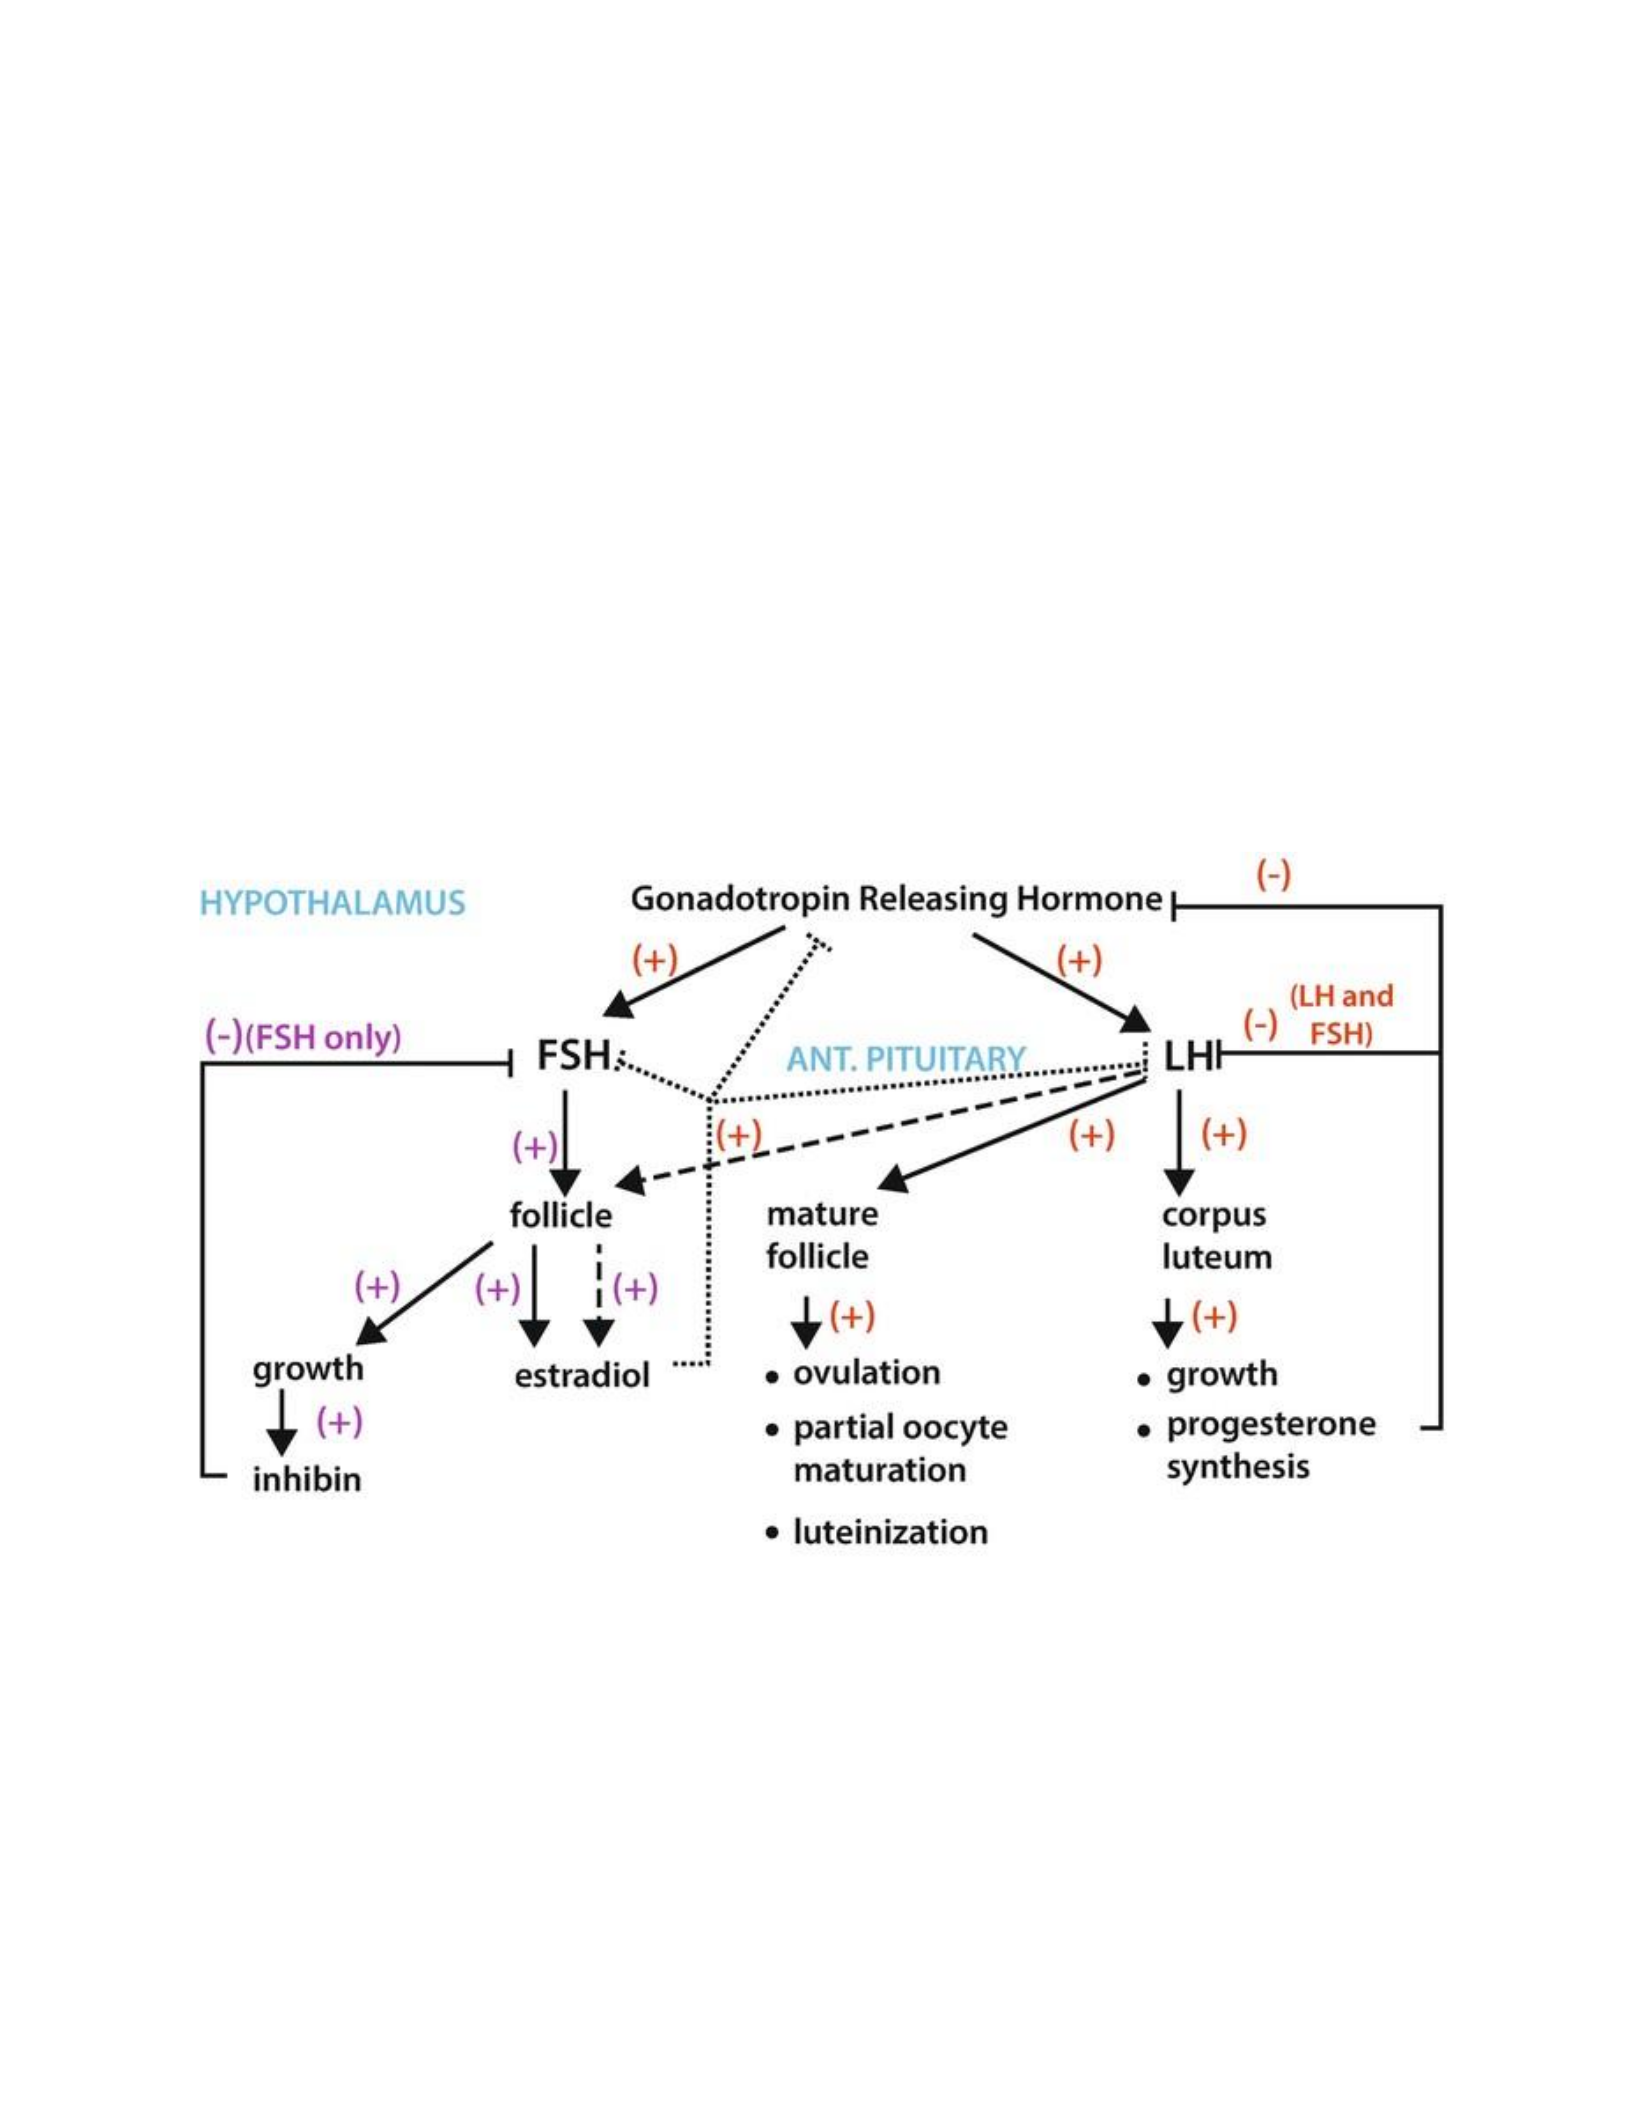
55
development of a single follicle takes place when a certain threshold level of plasma FSH is
marginally exceeded [94, 95]. When FSH levels are much higher than the threshold level or
exceed the threshold for an extended duration, multiple follicle growth can result [96]. In
accordance with the endocrine model of dizygotic twinning [97], high levels of pituitary
gonadotropins (i.e., FSH) are responsible for increased multiple ovulation in mothers of DZ
twins. A number of studies, but not all [92], have shown increased levels of plasma
gonadotropins in mothers of DZ twins [56, 98-100].
Figure 2.6 – Hormonal feedback and endocrine regulation of female reproductive
physiology
+ signs denote positive feedback, whereas blunted arrows indicate negative feedback. Figure
obtained by written permission from the lecture materials of Dr. Kathleen Eyster (University of
South Dakota, United States).

2.9 Non-human Twinning
Studies of non-human species have revealed several genes that contribute to DZ twinning.
For example, in sheep, which are typically uniparous, certain breeds have higher incidences of
multiple births [101]. Several genes, namely, GDF9, BMP15, and BMPR1B, have been
confirmed to influence twinning rates in sheep by increasing follicle development and oocyte
maturation [49, 102-104]. Major genes that increase ovulation rate and litter size in sheep and
humans have been shown to have implications in other species. Evidence exists for genetic
effects on twinning in cattle [105], the marmoset monkey [106], and hormone-induced ovulation
rate in mice [107].
Genes specific to MZ twinning remain elusive. Animal studies (originally in rabbit and
roe deer) have suggested that MZ twinning results from disturbances to developmental thresholds
and that delayed fertilization/implantation play a role [63]. These hypotheses have been further
tested in nine-banded armadillos (Dasypus novemcinctus), which bear obligate MZ quadruplets
each and every time they breed [108-111].
2.10 Sex Ratio
The sex ratio is defined as the ratio of males to total births. For DZ twins and singletons,
the ratio is 0.514, meaning a slight excess of males [63, 112]. For spontaneous MZ twins, triplets,
and quadruplets, the sex ratio is lower (0.496) due to a slight excess of females [62, 112]. The
value is even lower for monoamniotic twins, including conjoined twins, with a sex ratio of 0.2
[112]. There does not seem to be an excess of males in aborted twins. Dichorionic MZ twins
exhibit the smallest increase in females, whereas monochorionic diamniotic MZ twins show the
largest increase; thus, the rise may be due to later twinning events. Monochorionic

57
monoamniotic twins and conjoined twins show an even greater increase in the number of
females.
2.11 Discussion and Conclusion
Twinning is a common and multifactorial phenomenon, and elements of the twinning
process remain poorly characterized. Improved understanding of the underlying biological and
genetic aspects of MZ and DZ twins and of the twinning process as a whole has been enhanced
by the development of molecular and cytogenetic techniques. The influences on DZ twinning are
well studied, including contributions of numerous maternal (age, height, weight, parity, family
history), environmental (ART), and associated genetic factors (most notably common variants
near FSHB and within SMAD3). However, despite the robust associations with DZ twinning, the
ability to predict DZ twinning events remains imprecise due to the myriad of genetic and
nongenetic contributions. Likewise, comprehensive models of MZ twinning lack compelling
evidence and are challenged by instances of atypical twinning. MZ twinning is likely influenced
by some equivocal combination of non-genetic and genetic factors that likely result in delayed
fertilization, embryo development, implantation, or some form of mechanical disruption of the
early embryo. Further elucidation of the mechanisms by which twinning processes occur will
have significant merit for predicting, managing, and improving the outcomes of multiple
gestation pregnancies.
2.11.1 Review Questions
1. What are the etiological similarities and differences of monozygotic and dizygotic twins?

2. What is the role played by assisted reproductive technologies in the incidence of twinning over
time?
2.11.2 Multiple-Choice Questions
1. What is the most conclusive method for determining the zygosity status of twins?
(a) Examination of placentation
(b) Sex status (same or opposite sex)
(c) Evaluation of survey responses
(d) DNA testing
(e) Assessment of outward physical appearance
Answer: (d). Although the other methods are convenient and relatively robust approaches for
determining the zygosity status of twins, only DNA testing provides a quantitative and accurate
assessment of allele sharing for all twins, including same-sex twin pairs.
2. What is another term for dizygotic twins?
(a) Identical twins
(b) Fraternal twins
(c) Typical twins
(d) Atypical twins
Answer: (b). Dizygotic, or non-identical twins, develop from separate ova and are therefore
genetically distinct. Thus, because their genetic relatedness is the same as other sibling pairs,
dizygotic twins are commonly referred to as fraternal twins.
3. The rarest form of monozygotic twins (with the exception of conjoined twins) exhibit which of
the following fetal membrane states?
(a) Dichorionic diamniotic
(b) Dichorionic monoamniotic
(c) Monochorionic diamniotic
(d) Monochorionic monoamniotic
Answer: (d). Monochorionic monoamniotic monozygotic twins represent about 1% of all twin
pregnancies. Approximately 66% of monozygotic twins are monochorionic diamniotic, whereas
33% are dichorionic diamniotic.

59
4. Genome-wide association studies have identified common genetic variants associated with
spontaneous dizygotic twinning and female fertility in which genes?
(a) FSHB and SMAD3
(b) GDF9 and BMP15
(c) BMP4 and WFIKKN1
(d) FSHR and BMPR1B
Answer: (a). Single nucleotide polymorphisms near FSHB and within SMAD3 are significantly
associated with a higher rate of spontaneous dizygotic twinning and several other aspects of
female fertility (e.g., earlier age at menarche, earlier age at first child, and higher lifetime parity).
5. In order of highest to lowest incidence, which of the following captures the large regional
differences observed for dizygotic twinning?
(a) Asia, Africa, Europe
(b) Africa, Europe, Asia
(c) Europe, Asia, Africa
(d) Europe, Africa, Asia
Answer: (b). Whereas monozygotic twinning rates are relatively constant worldwide (~3 per
1000 births), large regional differences exist in dizygotic twinning rates with the highest
incidence in African populations (~40 per 1000 births), followed by European populations (~10–
20 per 1000 births), and the lowest incidence in Asian populations (~6 per 1000 births).
6. Which of the following is not a known non-genetic risk factor for spontaneous dizygotic
twinning?
(a) Parity
(b) Maternal age
(c) Nutritional status (d) Smoking status
(e) Body mass index
(f) Height
Answer: (c). Spontaneous dizygotic twinning is associated with parity, as well as increased
maternal age, increased body mass index, increased height, and smoking status prior to
pregnancy. Nutritional status is not known to be a direct contributor to dizygotic twinning, as
longitudinal studies in countries that experienced periods of starvation demonstrated consistent
rates of twinning (e.g., Dutch hunger winter [59]).

2.12 Acknowledgements
We are grateful to Veronika Odintsova for the generous contribution of the multiple birth data
from the Russian Federation, which was obtained from the Federal Research Institute for Health
Organization and Informatics, Ministry of Health of Russian Federation, Moscow, Russia.
2.13 References
1. Duncan, J.M., Fertility, Sterility and Allied Topics. Second ed. 1871, New York: William
Wood and Co. 498.
2. Galton, F., The History of Twins, as a Criterion of the Relative Powers of Nature and
Nurture, in Fraser’s Magazine. 1875. p. 566-576.
3. Fisher, R.A., The Genesis of Twins. Genetics, 1919. 4(5): p. 489-99.
4. Skytthe, A., et al., The Danish Twin Registry. Scand J Public Health, 2011. 39(7 Suppl):
p. 75-8.
5. Levit, S.G., Twin investigations in the U.S.S.R. Character and Personality, 1935. 3: p.
188-193.
6. Sukhanov, S., Opsihozah u bliznetsov [On psychosis in twins]. Klinicheskij jurnal, 1900.
4: p. 341-352.
7. Yudin, T.I., O shodstve psihoza u bratjev i sester. [On similarity of psychosis in brothers
and sisters]. Sovremennaya psihiatria, 1907. 10: p. 337-342.
8. Poll, H., Über Zwillingsforschung als Hilfsmittel menschlicher Erbkunde. Zeitschrift für
Ethnologie, 1914. 46: p. 87-105.
9. Siemens, H.W., Die Zwillingspathologie. Mol. Gen. Genet., 1924. 35: p. 311-312.
10. Mbarek, H., et al., Identification of Common Genetic Variants Influencing Spontaneous
Dizygotic Twinning and Female Fertility. Am J Hum Genet, 2016. 98(5): p. 898-908.
11. Hall, J.G., Twinning. Lancet, 2003. 362(9385): p. 735-43.
12. Benirschke, K., The placenta in twin gestation. Clin Obstet Gynecol, 1990. 33(1): p. 18-
31.
13. Benirschke, K. and C.K. Kim, Multiple pregnancy. 1. N Engl J Med, 1973. 288(24): p.
1276-84.
14. Benirschke, K. and C.K. Kim, Multiple pregnancy. 2. N Engl J Med, 1973. 288(25): p.
1329-36.
15. Benirschke, K. and E. Masliah, The placenta in multiple pregnancy: outstanding issues.
Reprod Fertil Dev, 2001. 13(7-8): p. 615-22.
16. McNamara, H.C., et al., A review of the mechanisms and evidence for typical and
atypical twinning. Am J Obstet Gynecol, 2016. 214(2): p. 172-191.
17. Cutler, T.L., et al., Why Accurate Knowledge of Zygosity is Important to Twins. Twin Res
Hum Genet, 2015. 18(3): p. 298-305.

61
18. Umstad, M.P., et al., Chimaeric twins: why monochorionicity does not guarantee
monozygosity. Aust N Z J Obstet Gynaecol, 2012. 52(3): p. 305-7.
19. Wray, N.R., et al., Genome-wide association analyses identify 44 risk variants and refine
the genetic architecture of major depression. Nat Genet, 2018. 50(5): p. 668-681.
20. Forget-Dubois, N., et al., Diagnosing zygosity in infant twins: physical similarity,
genotyping, and chorionicity. Twin Res, 2003. 6(6): p. 479-85.
21. Lamb, D.J., et al., Effects of chorionicity and zygosity on triplet birth weight. Twin Res
Hum Genet, 2012. 15(2): p. 149-57.
22. Odintsova, V.V., et al., Establishing a Twin Register: An Invaluable Resource for
(Behavior) Genetic, Epidemiological, Biomarker, and 'Omics' Studies. Twin Res Hum
Genet, 2018. 21(3): p. 239-252.
23. Hannelius, U., et al., Large-scale zygosity testing using single nucleotide polymorphisms.
Twin Res Hum Genet, 2007. 10(4): p. 604-25.
24. Cyranoski, D., Developmental biology: Two by two. Nature, 2009. 458(7240): p. 826-9.
25. Barban, N., et al., Genome-wide analysis identifies 12 loci influencing human
reproductive behavior. Nat Genet, 2016.
26. Machin, G., Familial monozygotic twinning: a report of seven pedigrees. Am J Med
Genet C Semin Med Genet, 2009. 151C(2): p. 152-4.
27. Shapiro, L.R., L. Zemek, and M.J. Shulman, Familial monozygotic twinning: an
autosomal dominant form of monozygotic twinning with variable penetrance. Prog Clin
Biol Res, 1978. 24 Pt B: p. 61-3.
28. Shapiro, L.R., L. Zemek, and M.J. Shulman, Genetic etiology for monozygotic twinning.
Birth Defects Orig Artic Ser, 1978. 14(6A): p. 219-22.
29. St Clair, J.B. and M.D. Golubovsky, Paternally derived twinning: a two century
examination of records of one Scottish name. Twin Res, 2002. 5(4): p. 294-307.
30. Michels, V.V. and V.M. Riccardi, Twin recurrence and amniocentesis: male and MZ
heritability factors. Birth Defects Orig Artic Ser, 1978. 14(6A): p. 201-11.
31. Lichtenstein, P., B. Kallen, and M. Koster, No paternal effect on monozygotic twinning in
the Swedish Twin Registry. Twin Res, 1998. 1(4): p. 212-5.
32. Torlopp, A., et al., The transcription factor Pitx2 positions the embryonic axis and
regulates twinning. Elife, 2014. 3: p. e03743.
33. Herranz, G., The timing of monozygotic twinning: a criticism of the common model.
Zygote, 2013. 23(1): p. 27-40.
34. Denker, H.W., Comment on G. Herranz: The timing of monozygotic twinning: a criticism
of the common model. Zygote (2013). Zygote, 2013. 23(2): p. 312-4.
35. Hoekstra, C., et al., Dizygotic twinning. Hum Reprod Update, 2008. 14(1): p. 37-47.
36. Al-Hendy, A., et al., Association between mutations of the follicle-stimulating-hormone
receptor and repeated twinning. Lancet, 2000. 356(9233): p. 914.
37. Painter, J.N., et al., A genome wide linkage scan for dizygotic twinning in 525 families of
mothers of dizygotic twins. Hum Reprod, 2010. 25(6): p. 1569-80.
38. Montgomery, G.W., et al., Mutations in the follicle-stimulating hormone receptor and
familial dizygotic twinning. Lancet, 2001. 357(9258): p. 773-4.
39. Boomsma, D.I., et al., Protease inhibitor (Pi) locus, fertility and twinning. Hum Genet,
1992. 89(3): p. 329-32.

40. Lieberman, J., N.O. Borhani, and M. Feinleib, Twinning as a heterozygous advantage for
alpha1-antitrypsin deficiency. Prog Clin Biol Res, 1978. 24 Pt B: p. 45-54.
41. Duffy, D., et al., IBD sharing around the PPARG locus is not increased in dizygotic twins
or their mothers. Nat Genet, 2001. 28(4): p. 315.
42. Fryns, J.P., The female and the fragile X. A study of 144 obligate female carriers. Am J
Med Genet, 1986. 23(1-2): p. 157-69.
43. Kenneson, A. and S.T. Warren, The female and the fragile X reviewed. Semin Reprod
Med, 2001. 19(2): p. 159-65.
44. Derom, C., et al., Genome-wide linkage scan for spontaneous DZ twinning. Eur J Hum
Genet, 2006. 14(1): p. 117-22.
45. Busjahn, A., et al., A region on chromosome 3 is linked to dizygotic twinning. Nat Genet,
2000. 26(4): p. 398-9.
46. Montgomery, G.W., et al., A deletion mutation in GDF9 in sisters with spontaneous DZ
twins. Twin Res, 2004. 7(6): p. 548-55.
47. Palmer, J.S., et al., Novel variants in growth differentiation factor 9 in mothers of
dizygotic twins. J Clin Endocrinol Metab, 2006. 91(11): p. 4713-6.
48. Zhao, Z.Z., et al., Variation in bone morphogenetic protein 15 is not associated with
spontaneous human dizygotic twinning. Hum Reprod, 2008. 23(10): p. 2372-9.
49. Luong, H.T., et al., Variation in BMPR1B, TGFRB1 and BMPR2 and control of dizygotic
twinning. Twin Res Hum Genet, 2011. 14(5): p. 408-16.
50. Dixit, H., et al., Genes governing premature ovarian failure. Reprod Biomed Online,
2010. 20(6): p. 724-40.
51. Mbarek, H., C.V. Dolan, and D.I. Boomsma, Two SNPs Associated With Spontaneous
Dizygotic Twinning: Effect Sizes and How We Communicate Them. Twin Res Hum Genet,
2016. 19(5): p. 418-21.
52. Harris, R.A., et al., Evolutionary genetics and implications of small size and twinning in
callitrichine primates. Proc Natl Acad Sci U S A, 2014. 111(4): p. 1467-72.
53. Nylander, P.P., The factors that influence twinning rates. Acta Genet Med Gemellol
(Roma), 1981. 30(3): p. 189-202.
54. Campbell, D.M., A.J. Campbell, and I. MacGillivray, Maternal characteristics of women
having twin pregnancies. J Biosoc Sci, 1974. 6(4): p. 463-70.
55. Hazel, W.N., et al., An age-dependent ovulatory strategy explains the evolution of
dizygotic twinning in humans. Nat Ecol Evol, 2020.
56. Lambalk, C.B., et al., Increased levels and pulsatility of follicle-stimulating hormone in
mothers of hereditary dizygotic twins. J Clin Endocrinol Metab, 1998. 83(2): p. 481-6.
57. Montgomery, G.W. and H. Hawker, Seasonal reproduction in ewes selected on seasonal
changes in wool growth. J Reprod Fertil, 1987. 79(1): p. 207-13.
58. Hunter, M.G., et al., Endocrine and paracrine control of follicular development and
ovulation rate in farm species. Anim Reprod Sci, 2004. 82-83: p. 461-77.
59. Eriksson, A.W., et al., Twinning rate in Scandinavia, Germany and The Netherlands
during years of privation. Acta Genet Med Gemellol (Roma), 1988. 37(3-4): p. 277-97.
60. Weinberg, W., Beiträge zur physiologie und der pathologie der mehrlingsgeburten beim
menschen. Arch Physiol, 1902. 88: p. 346-30.
61. Cameron, A.H., The Birmingham twin survey. Proc R Soc Med, 1968. 61(3): p. 229-34.

63
62. James, W.H., Excess of like sexed pairs of dizygotic twins. Nature, 1971. 232(5308): p.
277-8.
63. Bulmer, M.G., The Biology of Twinning in Man. 1970: Clarendon. 206.
64. Smits, J. and C. Monden, Twinning across the Developing World. PLoS One, 2011. 6(9):
p. e25239.
65. Polikarpov A.V., A.G.A., Golubev N.A., Turina E.M., Ogryzko E.V., Shelepova, E.A.,
Key Indicators of the Health of the Mother and Child, the Activities of the Service for
Childhood and Obstetrics in the Russian Federation. Moscow: The Ministry of Health of
the Russian Federation, 2018: p. 164.
66. Tong, S., D. Caddy, and R.V. Short, Use of dizygotic to monozygotic twinning ratio as a
measure of fertility. Lancet, 1997. 349(9055): p. 843-5.
67. Bressers, W.M., et al., Increasing trend in the monozygotic twinning rate. Acta Genet
Med Gemellol (Roma), 1987. 36(3): p. 397-408.
68. Harvey, M.A., R.M. Huntley, and D.W. Smith, Familial monozygotic twinning. J Pediatr,
1977. 90(2): p. 246-7.
69. Alikani, M., et al., Monozygotic twinning following assisted conception: an analysis of 81
consecutive cases. Hum Reprod, 2003. 18(9): p. 1937-43.
70. Abusheikha, N., et al., Monozygotic twinning and IVF/ICSI treatment: a report of 11
cases and review of literature. Hum Reprod Update, 2000. 6(4): p. 396-403.
71. Milki, A.A., et al., Incidence of monozygotic twinning with blastocyst transfer compared
to cleavage-stage transfer. Fertil Steril, 2003. 79(3): p. 503-6.
72. Steinman, G., Mechanisms of twinning. VI. Genetics and the etiology of monozygotic
twinning in in vitro fertilization. J Reprod Med, 2003. 48(8): p. 583-90.
73. Kulkarni, A.D., et al., Fertility treatments and multiple births in the United States. N Engl
J Med, 2013. 369(23): p. 2218-25.
74. Fauser, B.C., P. Devroey, and N.S. Macklon, Multiple birth resulting from ovarian
stimulation for subfertility treatment. Lancet, 2005. 365(9473): p. 1807-16.
75. Hellin, D., Die Ursache der Multiparitat der uniparen Tiere uberhaupt und der
Zwillingsschwangerschaft beim Menschen insbesondere (The causes ofmultiple
maternities among uniparous animals and in man). Seitz & Schauer, 1895.
76. Fellman, J. and A.W. Eriksson, On the history of Hellin's law. Twin Res Hum Genet,
2009. 12(2): p. 183-90.
77. Fellman, J. and A.W. Eriksson, Statistical analyses of Hellin's law. Twin Res Hum Genet,
2009. 12(2): p. 191-200.
78. Hoekstra, C., et al., Body composition, smoking, and spontaneous dizygotic twinning.
Fertil Steril, 2010. 93(3): p. 885-93.
79. Aston, K.I., C.M. Peterson, and D.T. Carrell, Monozygotic twinning associated with
assisted reproductive technologies: a review. Reproduction, 2008. 136(4): p. 377-86.
80. Lamont, J.A., Twin pregnancies following induction of ovulation: a literature review.
Acta Genet Med Gemellol (Roma), 1982. 31(3-4): p. 247-53.
81. Ananth, C.V. and S.P. Chauhan, Epidemiology of twinning in developed countries. Semin
Perinatol, 2012. 36(3): p. 156-61.

82. Sills, E.S., M.J. Tucker, and G.D. Palermo, Assisted reproductive technologies and
monozygous twins: implications for future study and clinical practice. Twin Res, 2000.
3(4): p. 217-23.
83. Edwards, R.G., L. Mettler, and D.E. Walters, Identical twins and in vitro fertilization. J In
Vitro Fert Embryo Transf, 1986. 3(2): p. 114-7.
84. Steinman, G., Mechanisms of twinning. II. Laterality and intercellular bonding in
monozygotic twinning. J Reprod Med, 2001. 46(5): p. 473-9.
85. Bortolus, R., et al., The epidemiology of multiple births. Hum Reprod Update, 1999. 5(2):
p. 179-87.
86. Varella, M., Fernandes, E., Arantes, J., Acquaviva, T., Lucci, T., Hsu, R., David, V.,
Bussah, V., Valentova, J., Segal, N., Otta, E., Twinning as an Evolved Age-dependent
Physiological Mechanism: Evidence from Large Brazilian Samples, in Multiple
Pregnancy (New Challenges). 2018, United Kingdom: IntechOpen.
87. Hankins, G.V. and G.R. Saade, Factors influencing twins and zygosity. Paediatr Perinat
Epidemiol, 2005. 19 Suppl 1: p. 8-9.
88. Tong, S. and R.V. Short, Dizygotic twinning as a measure of human fertility. Hum
Reprod, 1998. 13(1): p. 95-8.
89. Basso, O., et al., Risk of twinning as a function of maternal height and body mass index.
JAMA, 2004. 291(13): p. 1564-6.
90. Olsen, J., B. Bonnelykke, and J. Nielsen, Tobacco smoking and twinning. Acta Med
Scand, 1988. 224(5): p. 491-4.
91. Parazzini, F., et al., Coffee and alcohol intake, smoking and risk of multiple pregnancy.
Hum Reprod, 1996. 11(10): p. 2306-9.
92. Gilfillan, C.P., et al., The control of ovulation in mothers of dizygotic twins. J Clin
Endocrinol Metab, 1996. 81(4): p. 1557-62.
93. Martin, N.G., et al., Excessive follicular recruitment and growth in mothers of
spontaneous dizygotic twins. Acta Genet Med Gemellol (Roma), 1991. 40(3-4): p.
291301.
94. Schoemaker, J., et al., The FSH threshold concept in clinical ovulation induction.
Baillieres Clin Obstet Gynaecol, 1993. 7(2): p. 297-308.
95. Brown, J.B., Pituitary control of ovarian function--concepts derived from gonadotrophin
therapy. Aust N Z J Obstet Gynaecol, 1978. 18(1): p. 46-54.
96. Baird, D.T., A model for follicular selection and ovulation: lessons from superovulation. J
Steroid Biochem, 1987. 27(1-3): p. 15-23.
97. Milham, S., Jr., Pituitary Gonadotrophin and Dizygotic Twinning. Lancet, 1964. 2(7359):
p. 566.
98. Martin, N.G., et al., Pituitary-ovarian function in mothers who have had two sets of
dizygotic twins. Fertil Steril, 1984. 41(6): p. 878-80.
99. Martin, N.G., et al., Elevation of follicular phase inhibin and luteinizing hormone levels
in mothers of dizygotic twins suggests nonovarian control of human multiple ovulation.
Fertil Steril, 1991. 56(3): p. 469-74.
100. Nylander, P.P., Serum levels of gonadotrophins in relation to multiple pregnancy in
Nigeria. J Obstet Gynaecol Br Commonw, 1973. 80(7): p. 651-3.

65
101. Montgomery, G.W., K.P. McNatty, and G.H. Davis, Physiology and molecular genetics of
mutations that increase ovulation rate in sheep. Endocr Rev, 1992. 13(2): p. 309-28.
102. Demars, J., et al., Genome-wide association studies identify two novel BMP15 mutations
responsible for an atypical hyperprolificacy phenotype in sheep. PLoS Genet, 2013. 9(4):
p. e1003482.
103. Reader, K.L., et al., Booroola BMPR1B mutation alters early follicular development and
oocyte ultrastructure in sheep. Reprod Fertil Dev, 2012. 24(2): p. 353-61.
104. Vage, D.I., et al., A missense mutation in growth differentiation factor 9 (GDF9) is
strongly associated with litter size in sheep. BMC Genet, 2013. 14: p. 1.
105. Komisarek, J. and Z. Dorynek, Genetic aspects of twinning in cattle. J Appl Genet, 2002.
43(1): p. 55-68.
106. Marmoset Genome, S. and C. Analysis, The common marmoset genome provides insight
into primate biology and evolution. Nat Genet, 2014. 46(8): p. 850-7.
107. Spearow, J.L., Major genes control hormone-induced ovulation rate in mice. J Reprod
Fertil, 1988. 82(2): p. 787-97.
108. Enders, A.C., Implantation in the nine-banded armadillo: how does a single blastocyst
form four embryos? Placenta, 2002. 23(1): p. 71-85.
109. Prodohl, P.A., et al., Molecular documentation of polyembryony and the micro-spatial
dispersion of clonal sibships in the nine-banded armadillo, Dasypus novemcinctus. Proc
Biol Sci, 1996. 263(1377): p. 1643-9.
110. Storrs, E.E. and R.J. Williams, A study of monozygous quadruplet armadillos in relation
to mammalian inheritance. Proc Natl Acad Sci U S A, 1968. 60(3): p. 910-4.
111. Blickstein, I. and L.G. Keith, On the possible cause of monozygotic twinning: lessons
from the 9-banded armadillo and from assisted reproduction. Twin Res Hum Genet,
2007. 10(2): p. 394-9.
112. James, W.H., Sex ratio and placentation in twins. Ann Hum Biol, 1980. 7(3): p. 273-6.

CHAPTER 3 – PEDIGREE BASED ANALYSIS OF HUMAN DIZYGOTIC TWINNING
USING WHOLE GENOME SEQUENCE DATA
This chapter summarizes an ongoing project.

67
3.1 Abstract
Spontaneous human dizygotic (DZ) twinning runs in families and is known to be
influenced by numerous genetic and non-genetic factors, though the physiological pathways and
complete genetic origin are unknown. Genetic data from large trait-rich pedigrees may enhance
the ability to identify novel variants associated with DZ twinning. In this manner, we analyzed
whole-genome genotype and sequence data from selected members of a large multigenerational
pedigree with a rich history of DZ twinning to identify rare/functional variants underlying the
trait. Non-parametric linkage analysis was performed to define genomic regions co-segregating
with being a mother of DZ twins, but no strong linkage peaks were observed. Haplotypes were
estimated and combined with genetic variants from whole-genome sequence data of selected
mothers of DZ twins revealing large shared genomic regions on chromosomes 1, 3, 6, 11. We
hypothesize that these areas are regions of interest containing rare variants with substantive
effects on DZ twinning. Whether the variants are pedigree-specific or characteristic of a larger
cohort of population-matched mothers of DZ twins will necessitate screening and further
examination. In addition to contributions of common variants associated with DZ twinning, rare
variant identification has the potential to elucidate novel genetic biomarkers indexing fertility
and the prediction of DZ twinning.
Keywords: dizygotic twinning, whole-genome sequencing, genotyping, pedigree analysis
3.2 Introduction
Human spontaneous dizygotic (DZ) twinning occurs when two or more oocytes are
released and fertilized during a single pregnancy. DZ twinning is considered a complex trait

influenced by environmental and genetic factors. DZ twinning is common, affecting
approximately 1-4% of women worldwide, and tends to run in families [1]. In addition to family
history, increased parity and gravidity also increase the risk of spontaneous DZ twinning [2, 3].
Mothers of DZ twins (MoDZT) are taller, have increased BMI, are often overweight, and smoke
more frequently before the twin pregnancy [4]. Rates of DZ twinning vary considerably with
geographic location and time. Regionally, large prevalence differences exist, with the lowest and
highest rates reported in Asia (~5-6 per 1000 maternities) and Sub-Saharan Africa (~23 per 1000
maternities), respectively [2, 3, 5, 6]. Together, these observations suggest DZ twinning is a
heritable trait with an underlying polygenic inheritance. Over the years, many have attempted to
illuminate the genetic basis of DZ twinning through hormone and ultrasound studies, segregation
and pedigree analyses, candidate-gene approaches, and linkage projects [reviewed in ref 7]. In
the end, only portions of the genetic complexity of DZ twinning have been explained, providing
the opportunity to explore its genetic origin with innovative study designs.
Bulmer initially postulated that DZ twinning was due to a recessive gene with low
penetrance and a gene frequency of 50% [2]. Results from subsequent pedigree-based analysis
contradicted the recessive model, stating that the phenotype of ‘having DZ twins’ is consistent
with an autosomal monogenic dominant model with a gene frequency of 3.5% and a female
lifetime penetrance of 10% [8]. Subsequent linkage scans for DZ twinning parameterized their
models accordingly and, in the end, concluded that the mode of inheritance is more complex than
originally expected [9]. Further evidence for complex inheritance was demonstrated by expanded
linkage efforts of affected sister pairs (at least two sisters who were both mothers of spontaneous
DZ twins) from over 500 families from Australia, New Zealand, Utah, and the Netherlands,
which did not return any strong linkage signals [10]. Others have added that various non-genetic

69
factors also influence DZ twinning [3, 4], fostering additional support for the hypothesis that the
mode of inheritance of DZ twinning is likely complex and unlikely to be a simple dominant or
recessive trait.
The ongoing search for common genetic variants explaining DZ twinning inheritance was
propelled forward by the feasibility of quantifying genetic variation at a large scale with SNP
microarrays. A landmark meta-analysis of genome-wide association studies of 1,908 mothers of
DZ twins and 12,953 controls identified and replicated an association of DZ twinning with
common genetic variants in FSHB and SMAD3 [11]. Since, additional efforts have demonstrated
replication of these associations and have extended the search to uncover the genetics of multiple
births [12]. Still, identification of rare and low-frequency genetic variants with substantial effect,
accounting for more than a tiny fraction of variation in DZ twinning, has remained elusive [13].
Opposed to the common genetic variation captured by microarrays and imputed datasets, one
approach for rare variant identification is to analyze whole-genome sequence data. Sequence data
obtained from large informative pedigrees can be examined to search for possible highly
penetrant driver variants.
Here, we employed such a design to identify rare and/or functional variants associated
with DZ twinning using combined within-family linkage information and whole-genome
sequence data. We identified a large pedigree with a rich history of DZ twinning, containing 18
MoDZT. With DNA extracted from samples provided by 17 individuals (4 males, 13 females [11
of which are MoDZT]), we performed genotyping and whole-genome sequencing experiments to
generate datasets for linkage analysis and variant identification. We reasoned that large genetic
regions shared by the most distantly affected MoDZT contain novel variants with considerable

effect, leading to an enhanced understanding of biological pathways important for the DZ
twinning process.
3.2 Methods
3.2.1 Pedigree Description
A large Dutch pedigree with a rich history of spontaneous DZ twinning (i.e., no use of
assisted reproductive technologies) was ascertained. There are 21 sets of DZ twins and 18
MoDZT spanning multiple generations (Figure 3.1). Samples were collected from 17 individuals
(4 males and 13 females). Of the four male samples, two were part of a same-sex DZ twin pair.
Of the 13 females, 11 are MoDZT, one of which is part of an opposite-sex DZ twin pair. Two of
the MoDZT gave birth to two sets of DZ twins. DNA was extracted in the Netherlands and sent
to the Avera Institute for Human Genetics (AIHG) for SNP genotyping and sequencing.
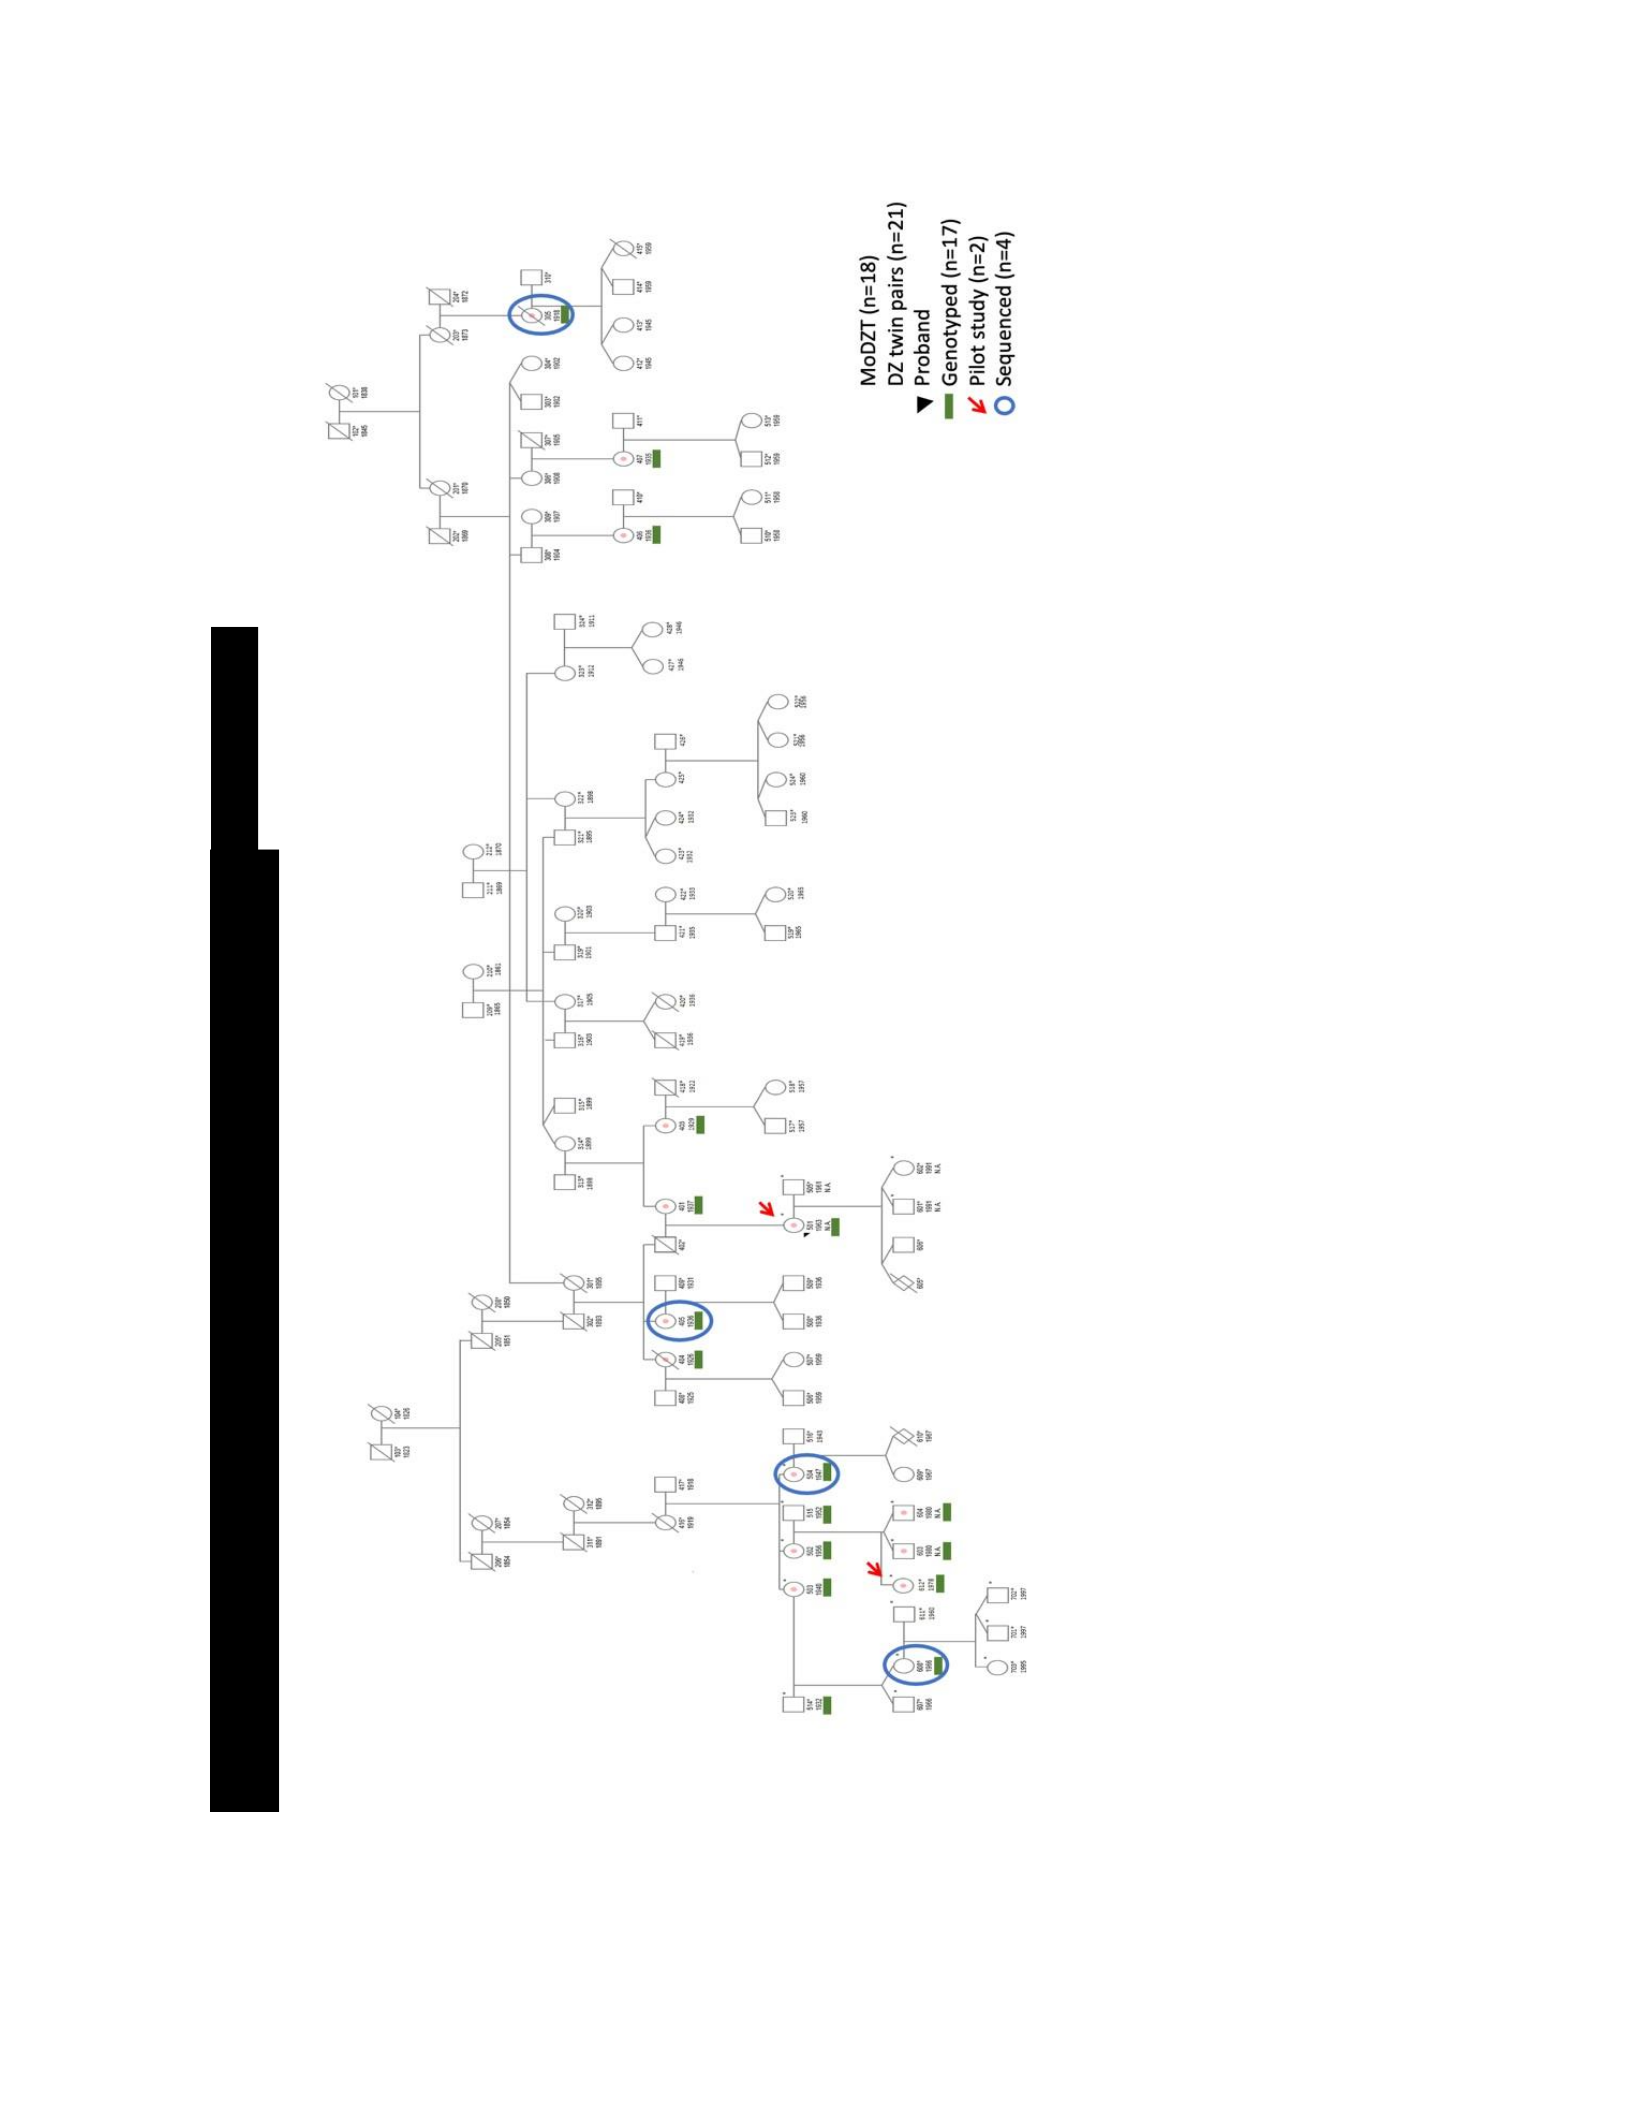
71

3.2.2 Sample Quality Control and Genotyping
Briefly, DNA purity was assessed with a Nanodrop spectrophotometer. DNA quantity was
measured with a double-stranded DNA dye method using a Qubit Fluorometer. All samples were
of sufficient quality and quantity for downstream genotyping and were normalized to a
concentration of 50ng/uL. SNP genotyping was done on the Illumina GSA according to the
manufacturer’s protocol. Input for sample target preparation was 200ng of high-quality genomic
DNA. Genotype calls were made with GenomeStudio2.0 and exported in PLINK file format for
downstream analysis.
We observed more than expected allele sharing between individual 305 and many of the
genotyped MoDZT from the far left-hand side (paternal side from proband) of the pedigree.
Individual 305 is related to the individuals in that cluster only through a marriage of individuals
302 and 301, so would be expected to show minimal allele sharing with any member of that
cluster, akin to the allele sharing of two unrelated individuals. We extracted a subset of SNPs
from the whole-genome sequence data of individual 305 to re-calculate genome-wide IBD
sharing. The same pattern of allele sharing was observed.
3.2.3 Linkage Analysis
Analysis was performed with Merlin software [18] with a grid size of 0.1. SNPs with
Mendelian inconsistencies, minor allele frequency (MAF)<0.01, and substantial deviation from
Hardy-Weinberg Equilibrium (p<0.00001) were excluded prior to analysis. Genotypes for key
individuals for which samples were unavailable were set to missing. Mothers without twins were
assigned an unknown status rather than unaffected because it is possible that these mothers
73
possess the genetic regions of interest but did not (yet) express the trait. For this reason, mothers
without twins could not definitively be specified as unaffected.
In the pedigree, two subfamilies were defined with respect to the proband (sample
number 501 marked by the black triangle in Figure 3.1). The first cluster contained individuals
202, 201, 302, 301, 308, 309, 306, 307, 313, 314, 401, 403, 404, 405, 402, 406, 407, 501. The
second cluster was represented by individuals 416, 417, 514, 503, 502, 515, 504, 608, 147, 603,
604. Sample 305 was omitted because of absent genetic relations with individuals on the left side
of the pedigree.
3.2.4 Whole-Genome Sequencing
Pilot study: two samples (individuals 501 and 612) were sequenced as a part of a pilot
study to validate the performance of a sequencing library-preparation kit initially designed for
cell-free DNA (DNA fragments) and that had not previously been used at the AIHG. The two
samples were selected strictly based on having abundant high-quality genomic material
available. The samples were sequenced to evaluate sequencing quality with the library
preparation kit. The two samples were included on an available lane of a flow cell as part of
another sequencing project. Though low read coverage (~5X) was expected, quality could still be
assessed.
Sample selection - Four MoDZT were selected for whole-genome sequencing.
Individuals 608, 504, 405, and 305 were selected based on being the most distantly affected in
the pedigree. Sequencing experiments were designed to obtain quality data of sufficient coverage
(~30X) for rare variant identification.

Sample preparation – DNA was first fragmented via sonication to a 300 base-pair (bp)
target size with a Covaris M220 Focused ultrasonicator. DNA fragment size was confirmed with
an Agilent 2100 Bioanalyzer.
Library preparation – Sequencing libraries were generated from the fragmented DNA
with ThruPLEX Plasma-seq chemistry (Rubicon Genomics). Positive and negative controls were
included, in the form of a known reference genomic DNA sample and a non-template control
(water in TE buffer), respectively. Index read sequencing primers of 6bp were included for
multiplex sequencing. Compatibility of indices was determined with Illumina Experiment
Manager. Libraries were purified with Agencourt AMPure XP beads. Prepared libraries were then
assessed via Agilent 2100 Bioanalyzer to verify the addition of sequencing adaptors and indices
(~140bp increase).
Library pooling – Libraries were pooled, purified, and quantified via quantitative
polymerase chain reaction (PCR) with a KAPA Library Quantification Kit. Libraries were then
denatured with 0.1 N NaOH and diluted to 15 pM for optimal cluster generation. Flow cell
clustering was performed with an Illumina cBot 2 system.
Sequencing – Pooled libraries were sequenced on an Illumina Hi-Seq 2500 instrument
using a high-output, 2x101 paired-end sequencing run with 1% PhiX spike-in serving as a
control to aid in experiment troubleshooting.
3.2.5 Whole-Genome Sequence Analysis
Sequence data were analyzed locally on a Linux workstation (OS: Ubuntu, Intel Core i7
6900 8 Core, 128 GB RAM) at AIHG in a stepwise manner. Initial quality was assessed with

75
MultiQC [19] on raw FASTQ files. Pre-processing and variant discovery and identification of
germline short variants (SNPs, insertions, deletions) were performed with the germline best
practices workflow of the Genome Analysis Toolkit (GATK version 3.8) [15, 20, 21] (Figure
3.2). Reads were mapped to the reference human genome (GRCh37) with BWA-mem (v0.7.17).
All reference variant databases were obtained from the GATK resource bundle. Duplicated
alignments were marked with Picard tools (v2.14.1) (http://broadinstitute. github.io/picard/).
Alignment scores were recalibrated with the Base Quality Score Recalibration (BQSR) module
in GATK. Variants were called with HaplotypeCaller in GVCF mode for each sample and were
then consolidated for joint calling to obtain raw variants. Variant quality scores were recalibrated
with the Variant Quality Score Recalibration (VQSR) module.
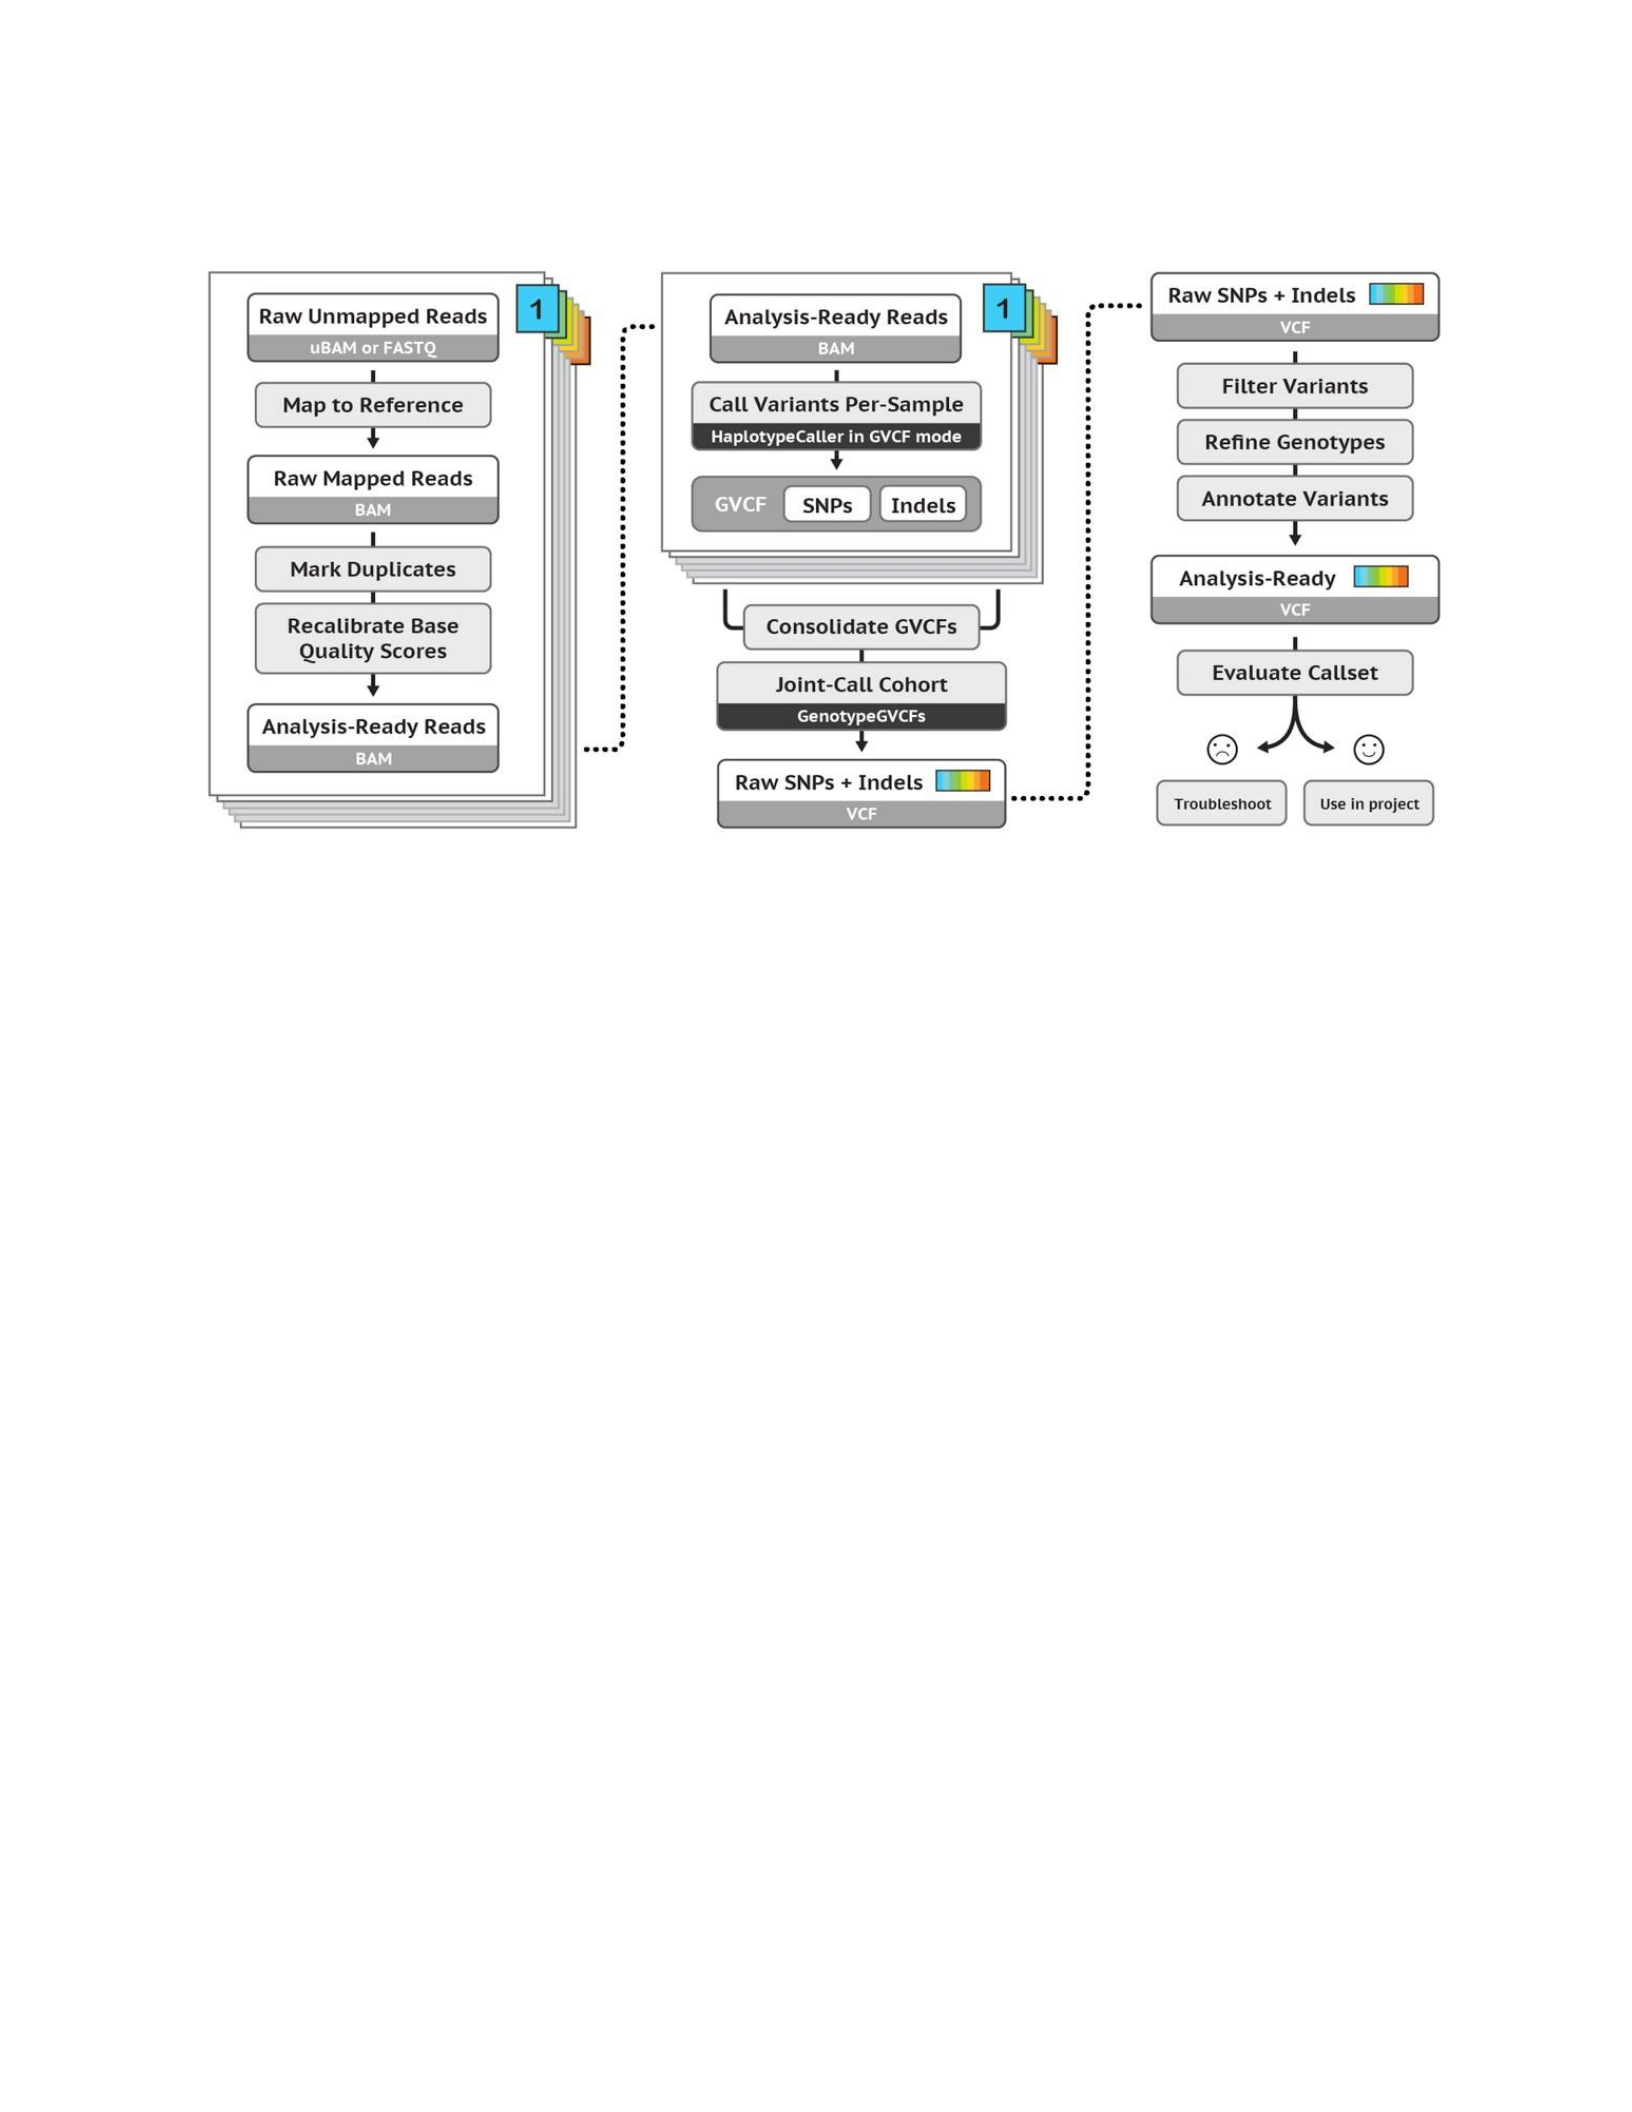
Figure 3.2 – Complete GATK best practices workflow
Image obtained from: https://gatk.broadinstitute.org/hc/en-us

77
3.2.6 Identification of Shared Genomic Regions
Shared genomic regions were identified with Olorin [22], a Java package designed to
combine within-family linkage analysis with sequence data (Figure 3.3). Olorin integrates
patterns of gene flow estimated by Merlin to identify genomic regions shared by selected (i.e.,
affected) individuals in large pedigrees. This information can then be combined with
wholegenome sequence data (single VCF file) to analyze variants within the shared regions.
Variants can further be refined with filtering tools in Olorin. For example, a user may define the
minimum number of individuals required to share a segment, enabling the search for variants of
incomplete penetrance. We adjusted this option to search for variants possessed by two, three, or
all four selected MoDZT. Additionally, Olorin supports the processing of ‘consequence’ strings in
the information field of the VCF file for predicting variant effects. Consequence information can
be obtained from Variant Effect Predictor (VEP).
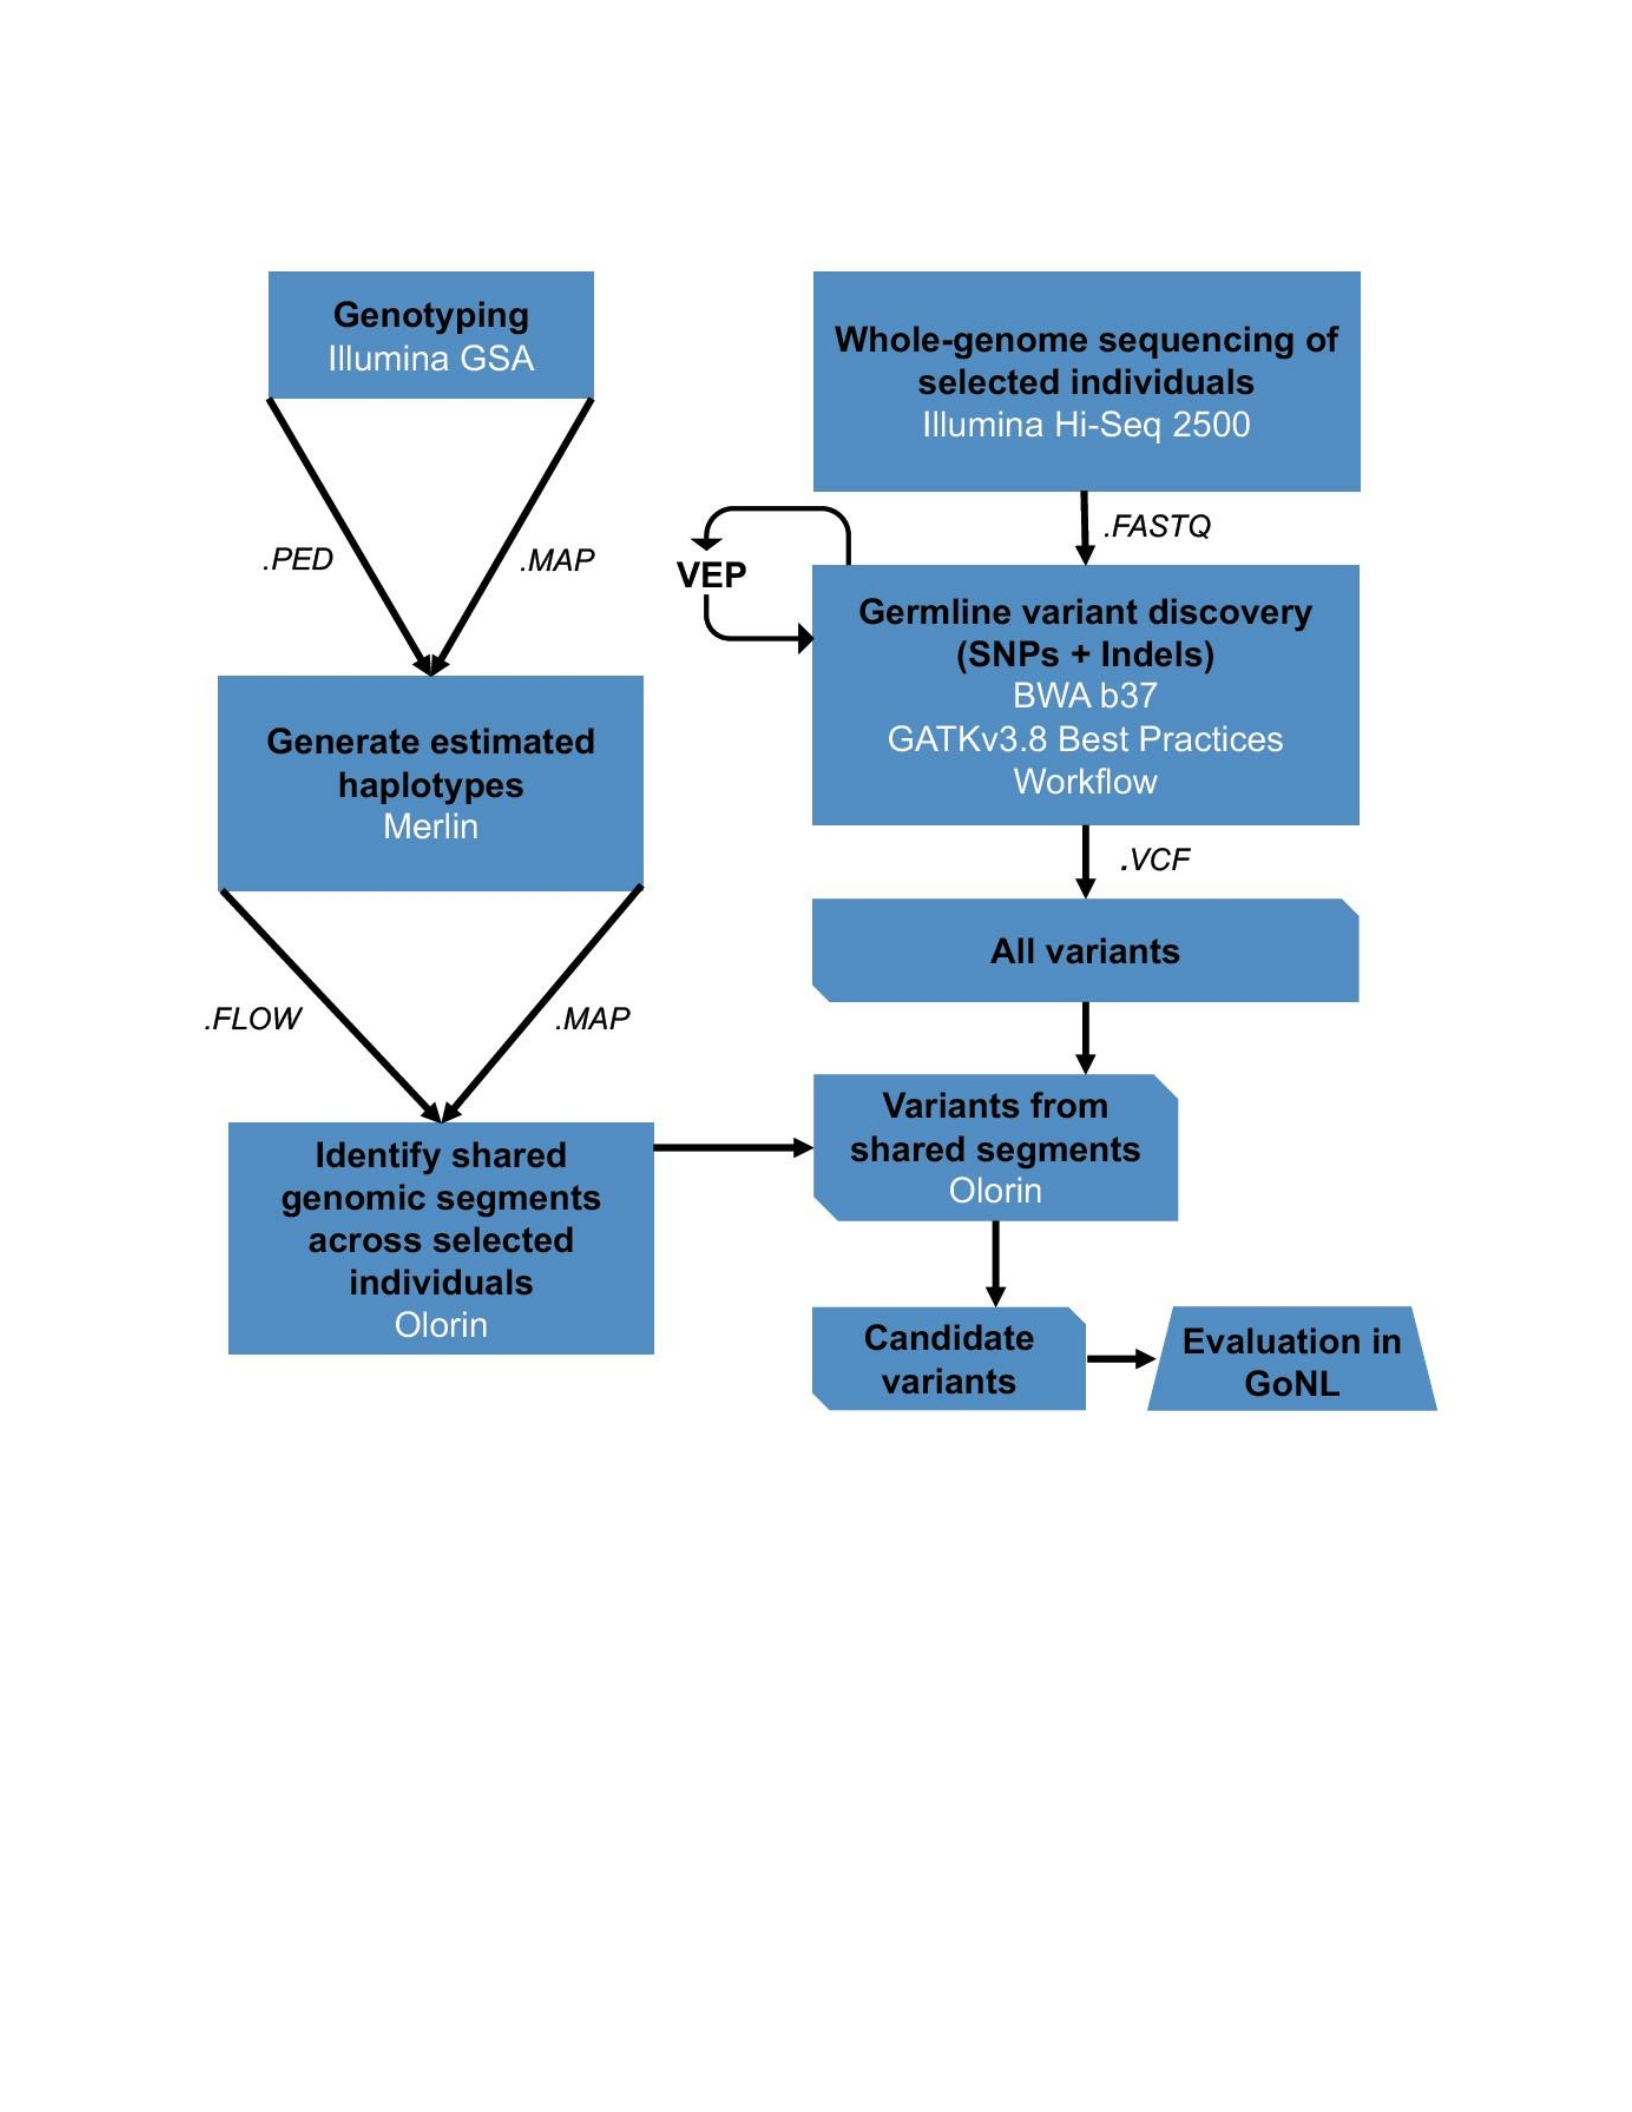
Figure 3.3 – Diagram of the Olorin workflow
3.3 Results
3.3.1 Linkage
The DZ twinning pedigree (Figure 3.1) was previously analyzed by Dr. Hamdi Mbarek
with custom identity-by-descent (IBD) mapping programs written in Wolfram Mathematica

79
software. The pedigree was split into three clusters, two on the paternal side of the proband and
one on the maternal side. Numerous large (>1Mb) shared regions were identified, depending on
the selected individuals included in the analysis. A 1Mb region on chromosome 12 was shared by
11 MoDZT and one grandmother of DZ twins from the maternal and paternal sides of the
proband. IBD regions shared by seven of the MoDZT on the paternal side of the proband were on
chromosomes 15, 16, and 17.
Due to the complexity of the phenotype and uncertainty of the mode of inheritance, we
employed non-parametric linkage analysis with an affected-only model to test for the
cosegregation of chromosomal regions and being a MoDZT. Under the null hypothesis, the
average Logarithm of Odds scores (LODs) should be zero in non-parametric linkage analysis.
Negative non-parametric LODs imply less than expected allele sharing among the group of
individuals and suggest that linkage is less likely. An excess of negative LODs indicates that the
data contain genotyping errors and/or misspecification of familial relationships. Positive non-
parametric LODs indicate excess allele sharing among affected individuals and favors the
presence of linkage. By convention, LODs greater than 3 are considered strong evidence of
linkage since they represent 1000 to 1 odds that a trait gene is linked to a genetic marker. LODs
less than -2 are generally considered evidence to exclude linkage.
The goal of the non-parametric analysis was to identify large, shared regions indicated by
broad peaks or plateaus in LODs plots. Per chromosome LODs are shown in Figure 3.4. The top
hit was found on chromosome 5 (maximum LOD score=1.21, p=0.009). Maximum LOD scores
were positive for all chromosomes, except for chromosome 21 (maximum LOD score=-0.01,
p=0.6).

Aside from the complexity of the pedigree structure and the absence of genetic data for
key individuals, issues related to impossible recombination were experienced in
Merlin. Impossible recombination patterns resulted in one of the three family clusters being
discarded. The origin of this issue is an obligate recombination event between two markers that
are mapped to the same position, or very close to each other, or that have a recombination
probability of zero given the genetic recombination map used. Another reason for this may be a
possible point mutation or genotype error. A subset of markers (N=18,555) was excluded in the
quality control step before analysis to resolve issues caused by the impossible recombination
patterns.
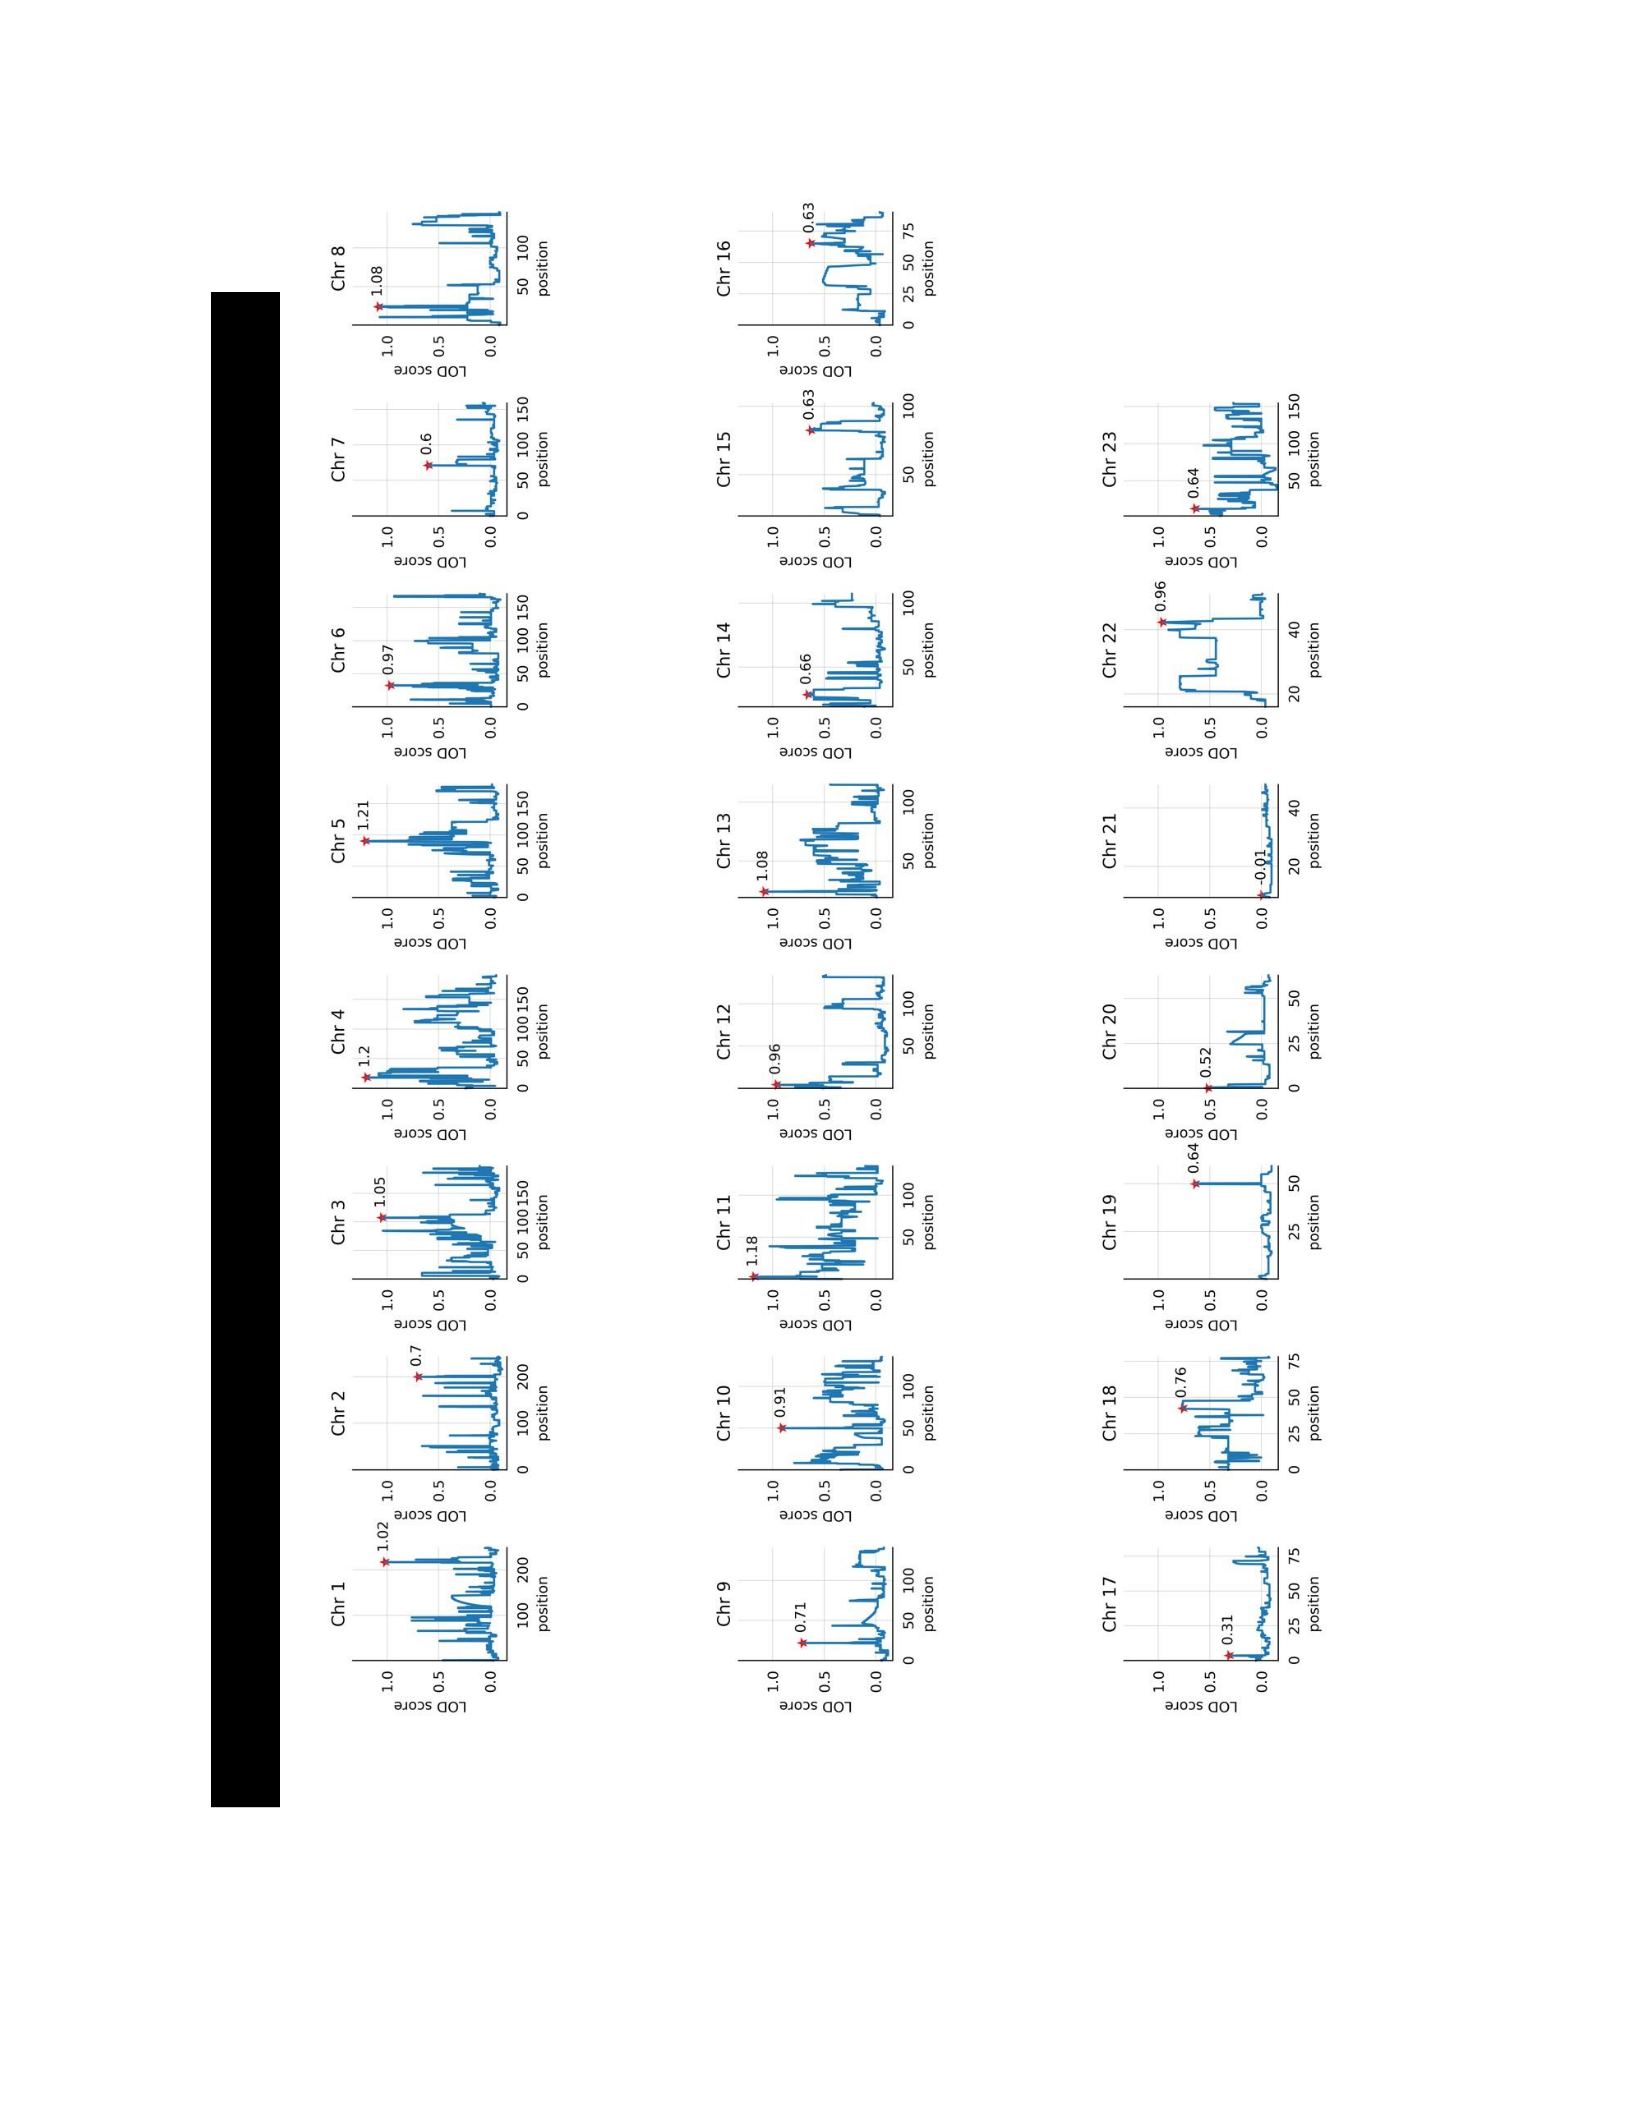
81
3.3.2 Whole-Genome Sequence Data Quality and Analysis
Pilot study: The initial library preparation and sequencing of samples 501 and 612
demonstrated that high-quality sequence data could be generated with the ThruPLEX Plasmaseq
chemistry, originally designed for fragmented, cell-free DNA. The pilot study results confirmed
the application of this library preparation kit for the whole-genome sequencing experiment on
selected MoDZT.
Whole-genome sequencing was performed on four of the most distantly affected MoDZT
in the pedigree. The sequence data from the four selected MoDZT were of high quality. The high
output run yielded 343.63Gbp of data, with an average raw error rate of 0.301%. The average
cluster density was ~790 K/mm2 per flow cell lane (samples were pooled across all eight lanes).
A vast majority of bases (94.21%) had Phred Quality Scores above Q30, indicating a base call
accuracy of 99.9% for those bases. The mean GC content of reads for each sample was roughly
normally distributed and was consistent with the mean value in the human genome of 41% [14].
Although the sequence data were of high quality, the yield (343.63Gb) was less than
projected for obtaining the desired ~30X coverage for confidently identifying rare variants.
Sequencing instruments (identical instruments within the same lab or between labs) are known to
vary in sequencing yield, provided a given input library concentration. Historical data from
sequencing projects on the Illumina Hi-Seq 2500 at the AIHG suggested 15 pM as the optimal
concentration for clustering and achieving the desired coverage. Lower data output can be due to
over- or under-clustering. Over-clustering tends to result in poor image resolution, lower Q30
scores, and reduced data output. Alternatively, under-clustering usually maintains data quality but
with lower overall data output. Given the robust quality results, the under-clustering scenario
most likely reflects the lower-than-expected average coverage depth of 18.60X (range 17.37X to
83
19.51X) for the four sequenced samples following alignment and initial quality control.
A summary of the variants identified by GATKv3.8 is shown in Table 3.1. The results are
shown for all four selected MoDZT. For a whole-genome sequencing experiment, roughly 4.4
million variants per individual are expected for human germline data (estimates from GATKv4).
In total, nearly 7 million total variants were identified. We expected fewer total variants given the
small number of sequenced individuals, the degree of relatedness amongst them, and strict
variant filtering to avoid false positives. Our results were consistent with the known effects of
sample size, filtering strictness, sample ethnicity, and state of the variant calling algorithm on
variant discovery and identification with GATKv3.8.
The transition/transversion (Ti/Tv) ratio of 2.05 falls in line with a reported ratio of 2.02.2
for humans across the entire genome [15], indicating very few false positives and no bias due to
artifactual variants. The bias avoidance is also supported by the insertion/deletion ratio of 0.83
(expected to be ~1) for common SNPs
(https://gatk.broadinstitute.org/hc/enus/articles/360035531572-Evaluating-the-quality-of-a-
germline-short-variant-callset).
Table 3.1- Summary of variants after filtering
Category
dbSNP (b37)
Novel
Total
Ti/Tv Ratio
2.10
1.88
2.05
SNPs:
N (% total)
4,793,188 (80.07%)
1,192,935 (19.93%)
5,986,123
Insertions:
N (% total)
238,787 (54.29%)
201,013 (45.71%)
439,800
Deletions:
N (% total)
287,568 (52.05%)
264,927 (47.95%)
552,495
Insertion/Deletion Ratio
0.83
0.76
0.80
Ti/Tv is the transition to transversion ratio.


85
3.3.3 Identification of Shared Genomic Regions
Estimated haplotypes were first generated in Merlin with SNP genotype data. The gene
flow output was used to identify shared genomic regions of MoDZT. In the form of a VCF file,
analyzed sequence data were then combined to identify variants within the shared segments.
Individuals with sequence information were specified with the interactive features of Olorin and
the information in the required pedigree file (Figure 3.5).
Additional filtering was performed to identify shared genomic segments in two, three, or
four sequenced MoDZT. The results are shown in the ideograms in Figure 3.6. Any two MoDZT
shared large regions of all chromosomes. Regions shared by all four MoDZT were found on
chromosomes 1-7, 10, 11, 16, 17 and were variable in size. The largest continuous regions were
on chromosomes 11, 1, 3, and 6, respectively. Of the regions shared by all four MoDZT, none
contained the previously identified and replicated SNPs near FSHB (rs11031006; Chr11;
GRCh37 position 30,226,528) and within SMAD3 (rs17293443; Chr15; GRCh37 position
67,437,863) [11]. The closest segment to rs11031006 was 18.2Mb upstream. No segments shared
by all four MoDZT were found on chromosome 15. The shared regions did not overlap with an
identified but not replicated intergenic SNP, rs12064669 (Chr1, GRCh37 position 230,688,643).
The closest shared segment was 2.4Mb downstream. Assessment of the largest segments shared
by three MoDZT revealed a region on chromosome 11 containing the FSHB associated SNP
rs11031006. The region was rather large, spanning 30.9Mb (17,663,444 start; 48,581,765 end),
and was shared by individuals 305, 608, and 504. Individual 305 possessed 14 of the 15 largest
shared segments possessed by any 3 MoDZT.
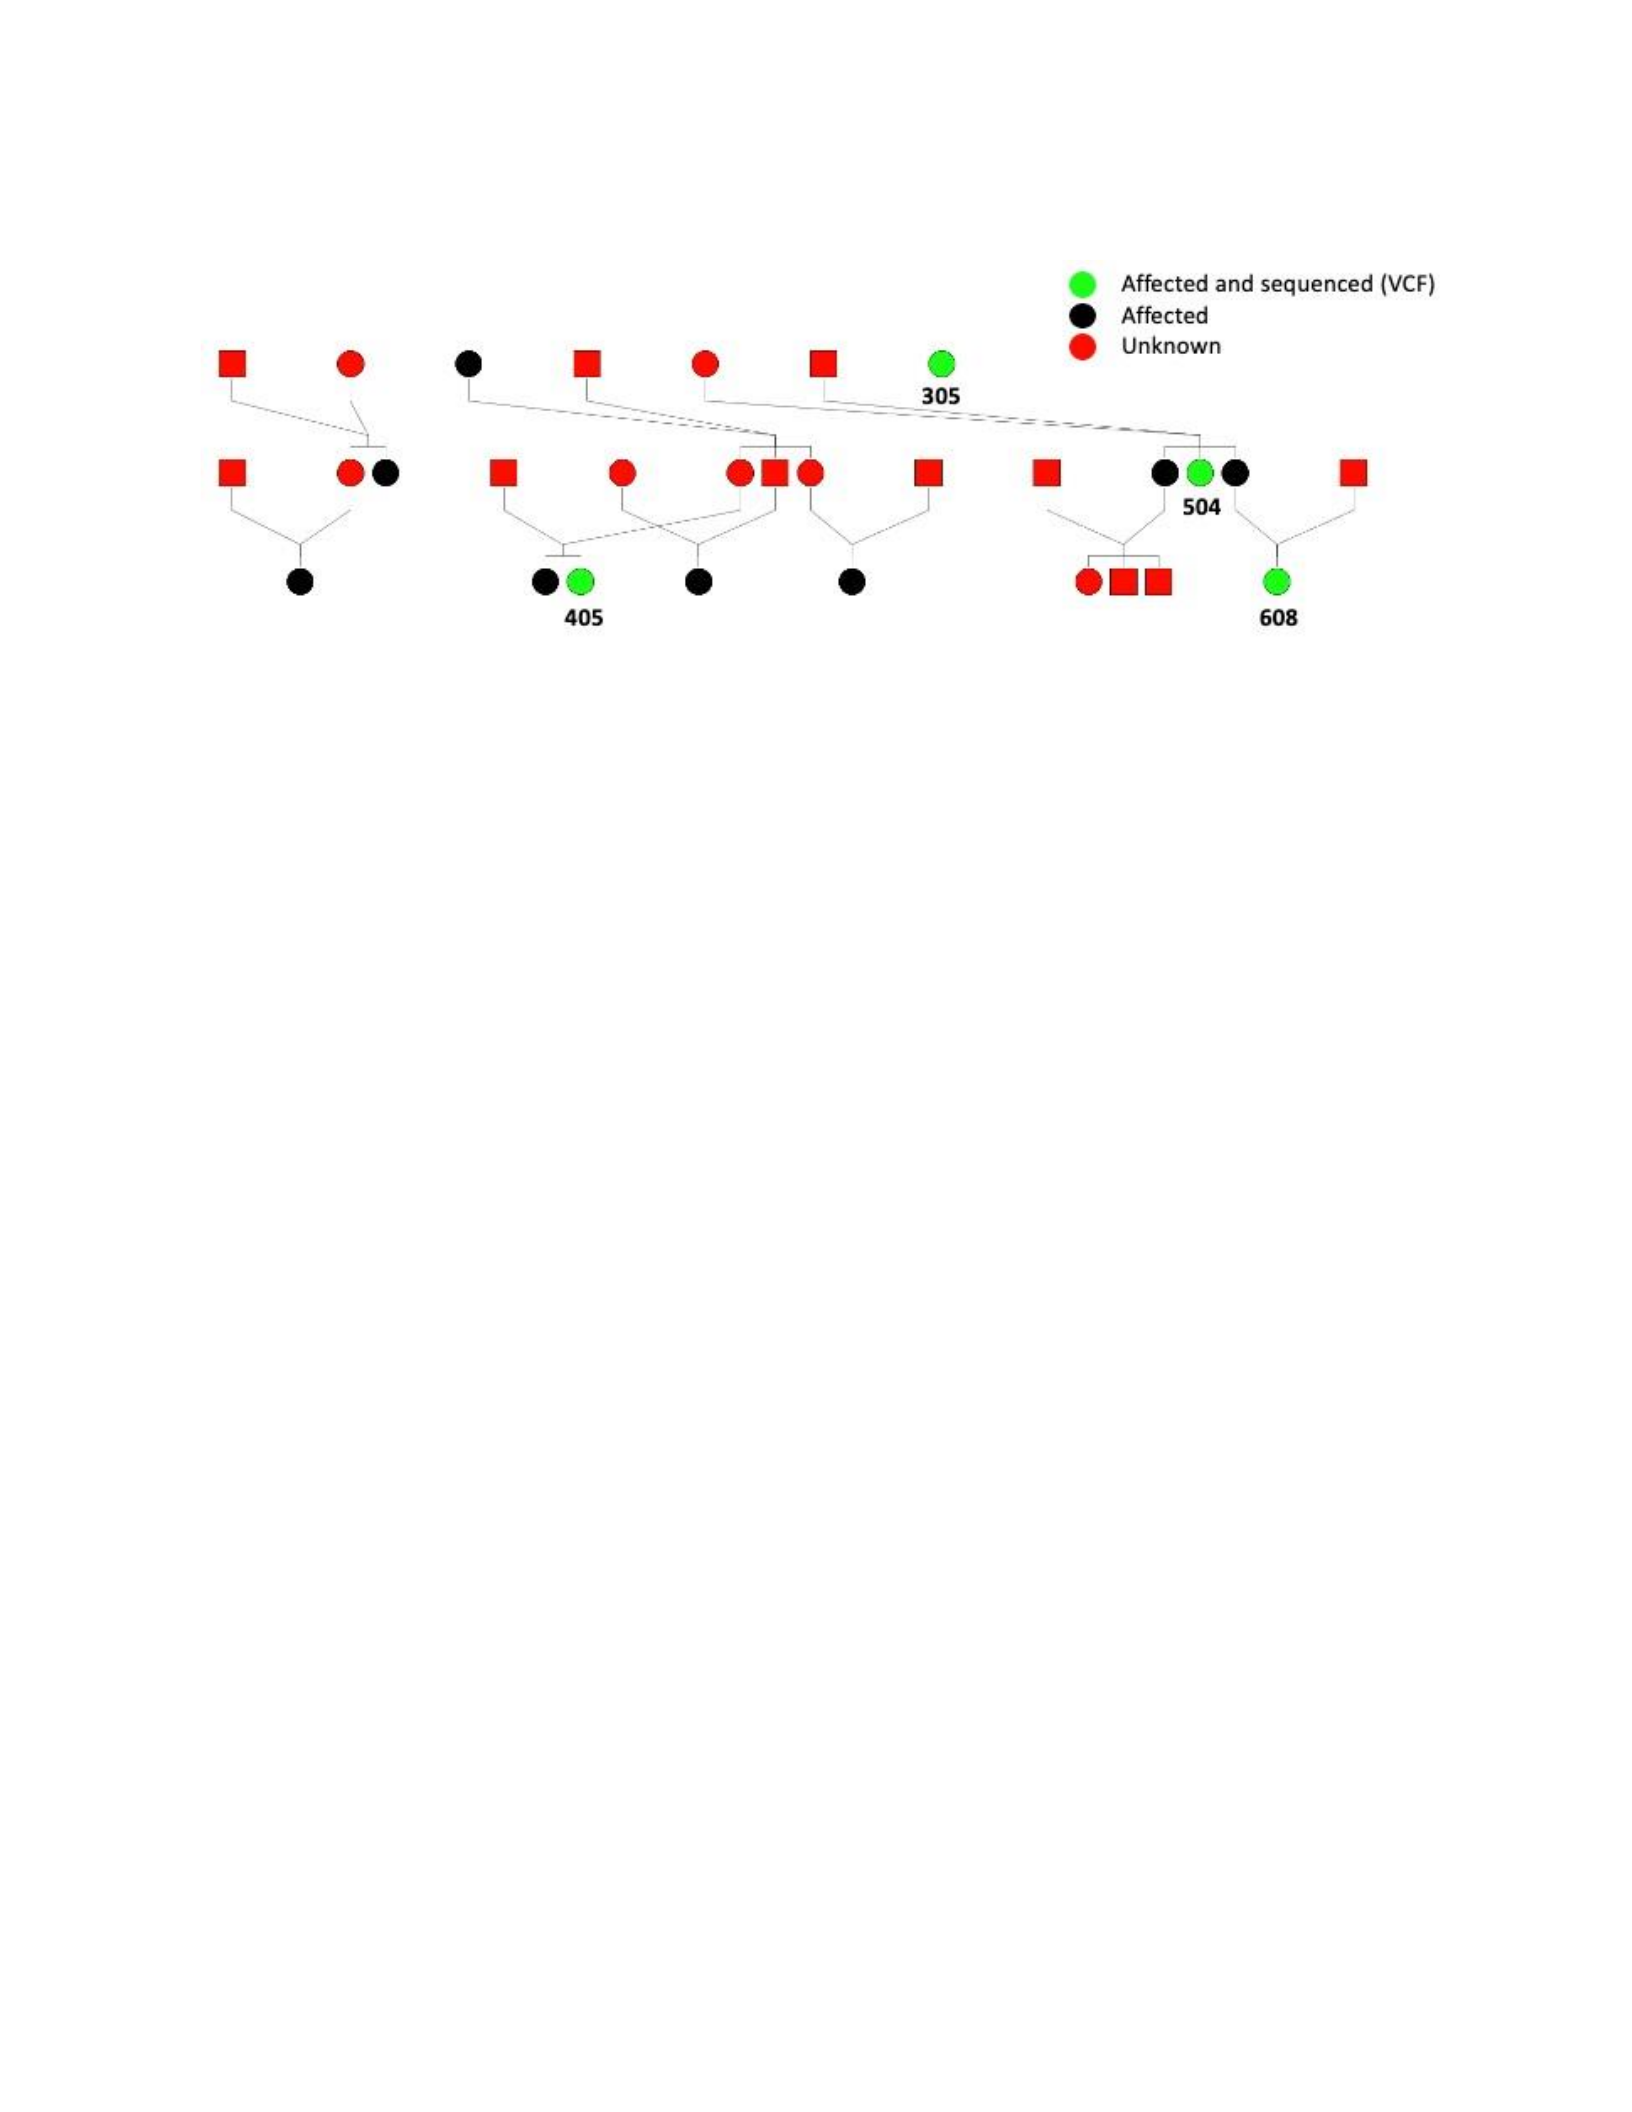
Figure 3.5 – Pedigree as defined in Olorin
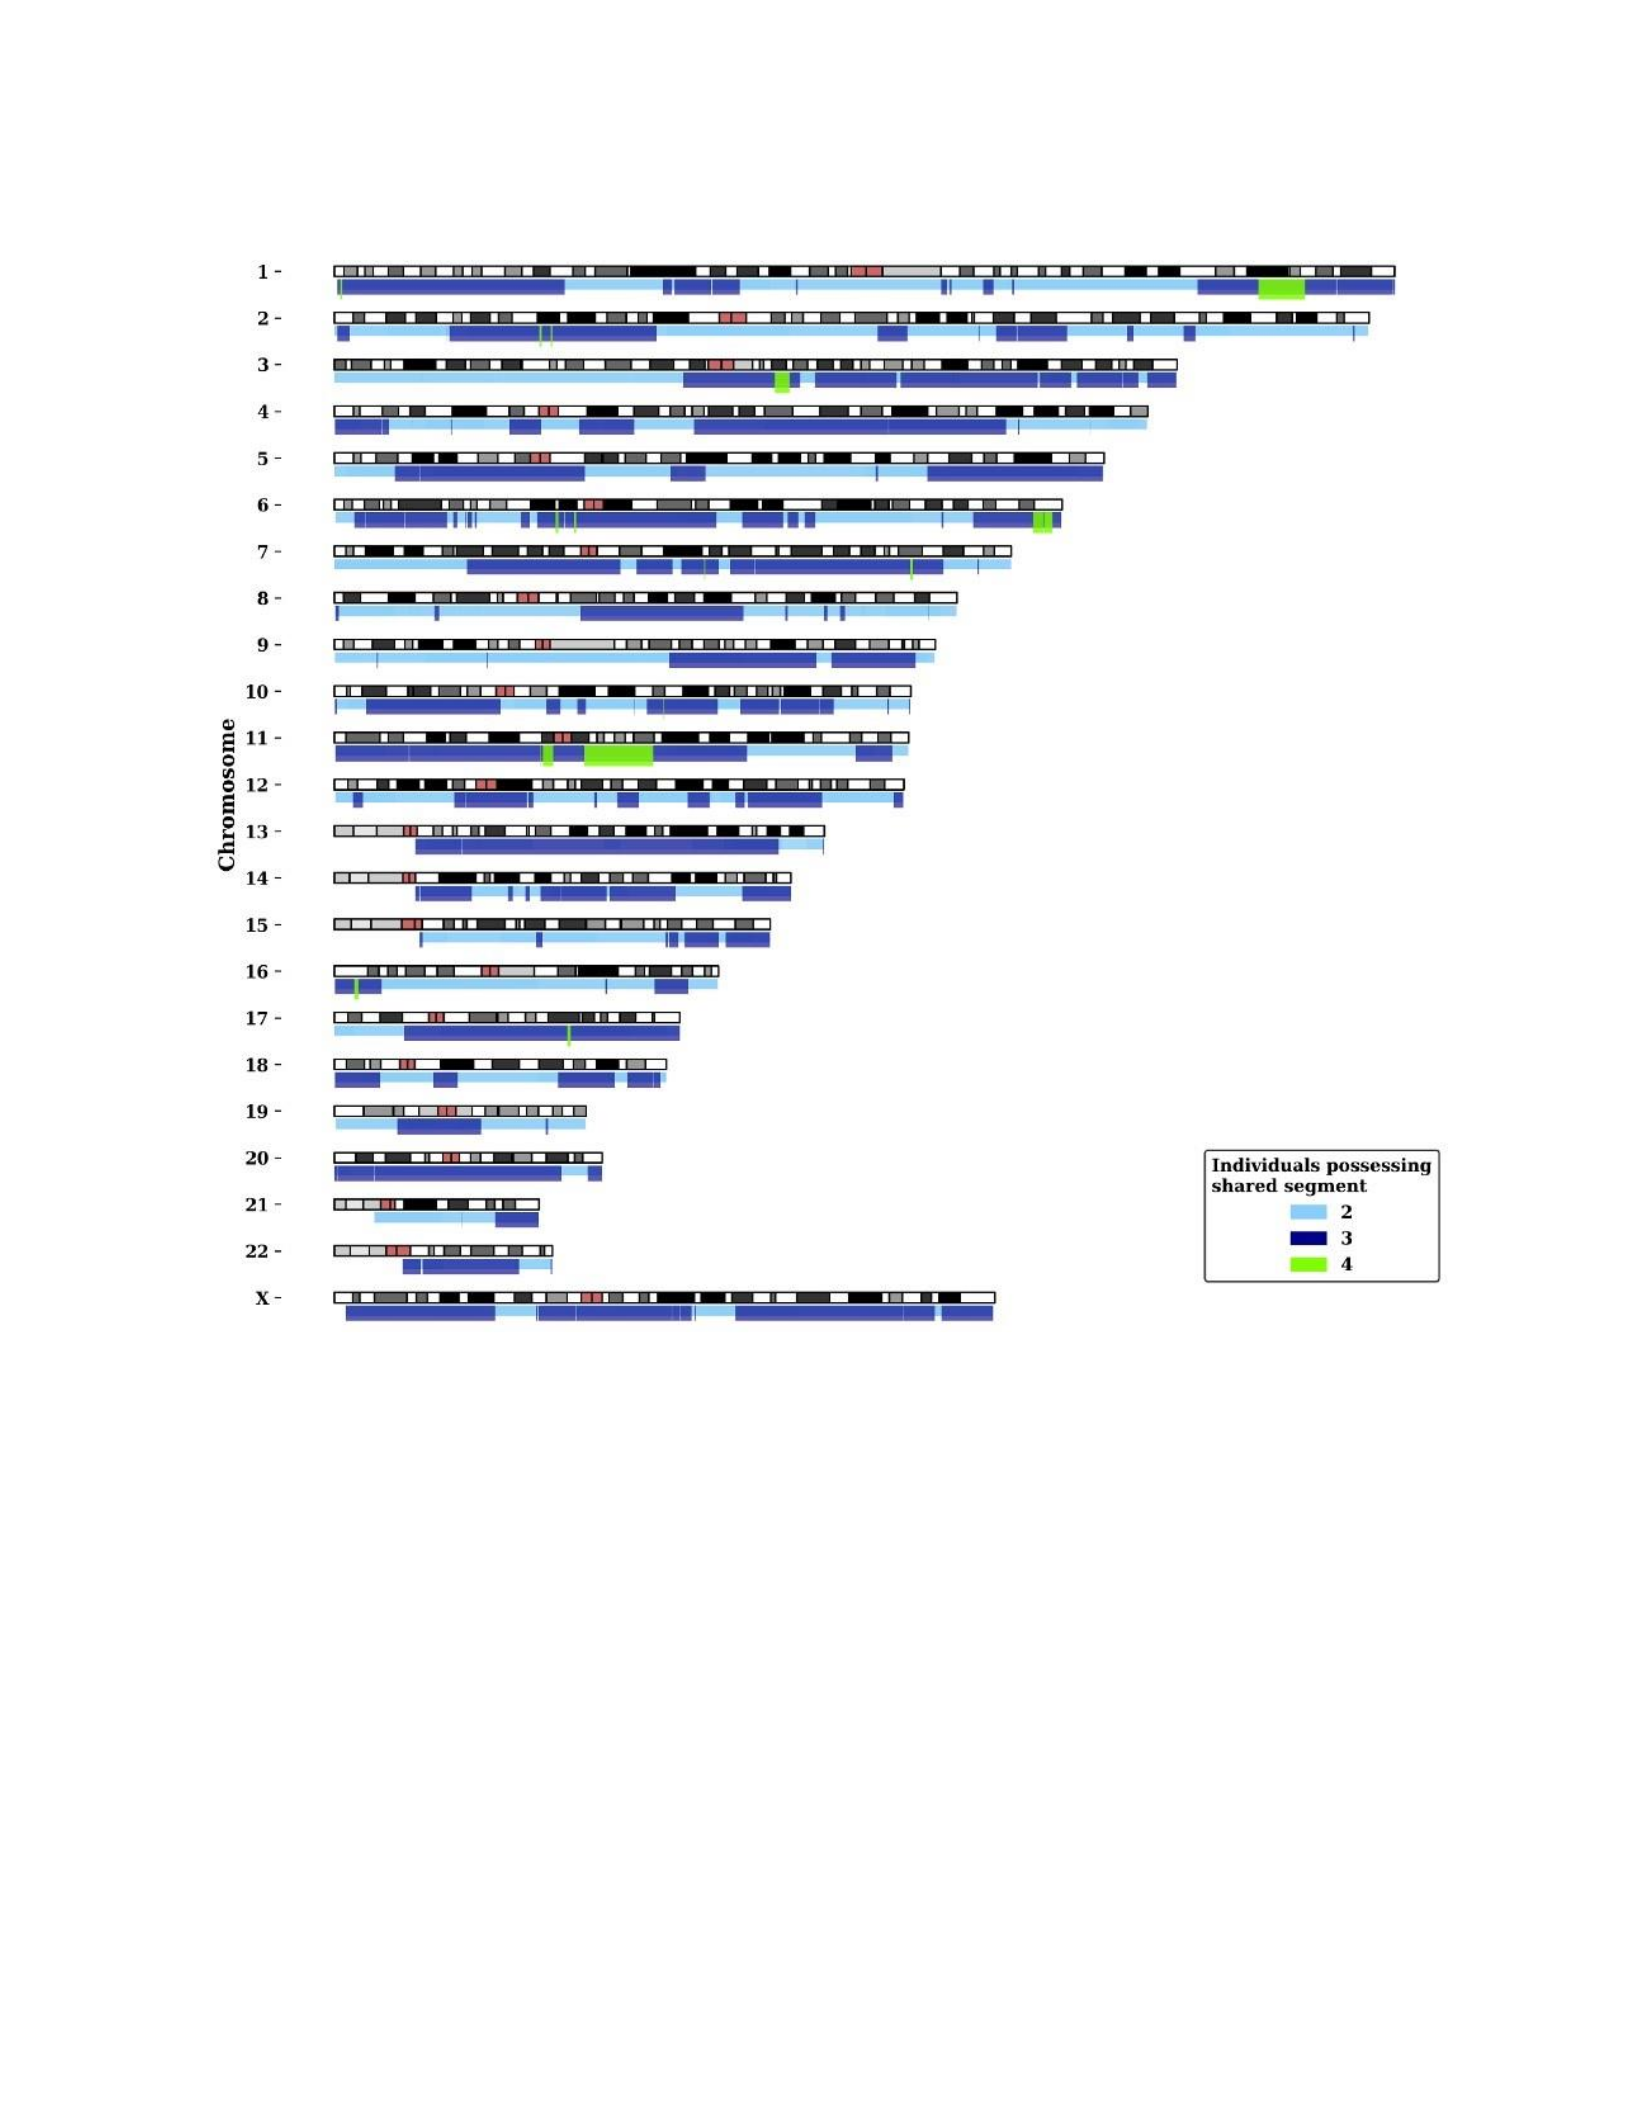
87
Figure 3.6 – Ideograms of shared genomic segments
Banding patterns of chromosomes are shown in grayscale, with the centromere colored in red.
Note: segments smaller than ~50kb are extremely difficult to visualize due to their size relative
to each chromosome. For example, on chromosome 4, the first segment shared by 3 mothers has
a small gap, corresponding to a 4,677 base-pair region shared by 4 mothers.
3.4 Conclusions and Future Directions
The enduring objective of this project is to use whole-genome sequencing as a follow-up
approach to previous linkage and association studies of DZ twinning to identify new genetic
biomarkers related to fertility measures and for the prediction of DZ twinning.

Based on previous work, variants affecting multiple ovulation rates (i.e., DZ twinning
events) are most likely to occur in genes and pathways that control the synthesis and release of
Follicle Stimulating Hormone (FSH), pathways in the ovary that control response to FSH, or
pathways involved in growth and development of the dominant follicle. Results from
wholegenome sequencing may implicate new pathways or novel routes for regulating known
pathways, ultimately enabling new opportunities for treating infertility or fine-tuning assisted
reproductive strategies.
We have identified genomic regions of interest with combined genotype and
wholegenome sequence data, but considerable effort is still required to pinpoint specific (rare)
variants with meaningful biological effects. In a first step, preliminary results of Olorin can be
further analyzed to determine the functional consequence of particular variants, which will
require analyzing the currently available VCF with Variant Effect Predictor (VEP) to obtain
functional consequence information. The resulting VCF can then be reanalyzed in Olorin with
subsequent filtering to help prioritize variants for further investigation.
Another useful strategy for evaluating the results is to screen the shared segments/variants
possessed by the MoDZT from the pedigree against the genomes of 46 MoDZT from the
Genome of the Netherlands project. This strategy will highlight and differentiate between
variants possessed only by mothers in the pedigree and variants prevalent among all MoDZT
from a population-matched cohort. Given global differences of DZ twinning [5, 6], it would be of
further interest to investigate variants across MoDZT from diverse populations as sequence data
become available.
Varying the unaffected status for specific individuals in the pedigree to an unknown status
may also aid in identifying promising candidate regions in linkage analysis. However, these

89
modifications and subsequent interpretation will need to be done with extreme and deliberate
care.
Attention should also be given to the reference genome/resource bundle used for variant
discovery and identification. The developers of GATK have recently transitioned all tool
development and support to GRCh38 since retiring the GRCh37 resource bundle. The GRCh38
assembly is an improved version of the human genome reference [16], so it would be diligent to
repeat all analyses employing this reference. This idea is supported by a recent study that found
significant variant calling discrepancies due to the intrinsic differences between GRCh37 and
GRCh38 [17]. Implementation of the GRCh38 reference would necessitate that genotype
coordinates be converted (i.e., lifted over) to a consistent build for reanalysis with Olorin.
Overall, the overlapping portions represent regions of interest for identifying rare and
highly penetrant variants or deleterious mutations. Rare variant identification for DZ twinning
may elucidate novel genetic biomarkers for fertility and improve the ability to predict twinning
events. Findings from this work have the potential to improve the outcomes of multiple gestation
pregnancies and the reproductive capacity of infertile couples.
3.5 References
1. Hoekstra, C., et al., Familial twinning and fertility in Dutch mothers of twins. Am J Med
Genet A, 2008. 146A(24): p. 3147-56.
2. Bulmer, M.G., The Biology of Twinning in Man. 1970: Clarendon. 206.
3. Hoekstra, C., et al., Dizygotic twinning. Hum Reprod Update, 2008. 14(1): p. 37-47.
4. Hoekstra, C., et al., Body composition, smoking, and spontaneous dizygotic twinning.
Fertil Steril, 2010. 93(3): p. 885-93.
5. Monden, C., G. Pison, and J. Smits, Twin Peaks: more twinning in humans than ever
before. Hum Reprod, 2021.
6. Smits, J. and C. Monden, Twinning across the Developing World. PLoS One, 2011. 6(9):
p. e25239.

7. Boomsma, D.I., The Genetics of Human DZ Twinning. Twin Res Hum Genet, 2020.
23(2): p. 74-76.
8. Meulemans, W.J., et al., Genetic modelling of dizygotic twinning in pedigrees of
spontaneous dizygotic twins. Am J Med Genet, 1996. 61(3): p. 258-63.
9. Derom, C., et al., Genome-wide linkage scan for spontaneous DZ twinning. Eur J Hum
Genet, 2006. 14(1): p. 117-22.
10. Painter, J.N., et al., A genome wide linkage scan for dizygotic twinning in 525 families of
mothers of dizygotic twins. Hum Reprod, 2010. 25(6): p. 1569-80.
11. Mbarek, H., et al., Identification of Common Genetic Variants Influencing Spontaneous
Dizygotic Twinning and Female Fertility. Am J Hum Genet, 2016. 98(5): p. 898-908.
12. Mbarek, H., et al., Biological insights into multiple birth: genetic findings from UK
Biobank. Eur J Hum Genet, 2019. 27(6): p. 970-979.
13. Gajbhiye, R., J.N. Fung, and G.W. Montgomery, Complex genetics of female fertility.
NPJ Genom Med, 2018. 3: p. 29.
14. Lander, E.S., et al., Initial sequencing and analysis of the human genome. Nature, 2001.
409(6822): p. 860-921.
15. DePristo, M.A., et al., A framework for variation discovery and genotyping using
nextgeneration DNA sequencing data. Nat Genet, 2011. 43(5): p. 491-8.
16. Schneider, V.A., et al., Evaluation of GRCh38 and de novo haploid genome assemblies
demonstrates the enduring quality of the reference assembly. Genome Res, 2017. 27(5):
p. 849-864.
17. Li, H., et al., Exome variant discrepancies due to reference-genome differences. Am J
Hum Genet, 2021. 108(7): p. 1239-1250.
18. Abecasis, G.R., et al., Merlin--rapid analysis of dense genetic maps using sparse gene
flow trees. Nat Genet, 2002. 30(1): p. 97-101.
19. Ewels, P., et al., MultiQC: summarize analysis results for multiple tools and samples in a
single report. Bioinformatics, 2016. 32(19): p. 3047-8.
20. McKenna, A., et al., The Genome Analysis Toolkit: a MapReduce framework for
analyzing next-generation DNA sequencing data. Genome Res, 2010. 20(9): p. 1297-303.
21. Van der Auwera, G.A., et al., From FastQ data to high confidence variant calls: the
Genome Analysis Toolkit best practices pipeline. Curr Protoc Bioinformatics, 2013. 43: p.
11 10 1-33.
22. Morris, J.A. and J.C. Barrett, Olorin: combining gene flow with exome sequencing in
large family studies of complex disease. Bioinformatics, 2012. 28(24): p. 3320-1.

CHAPTER 4 – GENETIC SIMILARITY ASSESSMENT OF TWIN-FAMILY
POPULATIONS BY CUSTOM-DESIGNED GENOTYPING ARRAY
Published as:
Beck, J.J., Hottenga, J.J., Mbarek, H., Finnicum, C.T., Ehli, E.A., Hur, Y.M., Martin, N.G., de
Geus, E.J.C., Boomsma, D.I. and Davies, G.E. (2019)
Genetic Similarity Assessment of Twin-Family Populations by Custom-Designed Genotyping
Array. Twin Res Hum Genet, 22, 210-219.

92
92
4.1 Abstract
Twin registries often take part in large collaborative projects and are major contributors to
genome-wide association (GWA) meta-analysis studies. In this article, we describe genotyping of
twin-family populations from Australia, the Midwestern USA (Avera Twin
Register), the Netherlands (Netherlands Twin Register), as well as a sample of mothers of twins
from Nigeria to assess the extent, if any, of genetic differences between them. Genotyping in all
cohorts was done using a custom-designed Illumina Global Screening Array (GSA), optimized to
improve imputation quality for population-specific GWA studies. We investigated the degree of
genetic similarity between the populations using several measures of population variation with
genotype data generated from the GSA. Visualization of principal components analysis (PCA)
revealed that Australian, Dutch, and Midwestern American populations exhibit negligible
interpopulation stratification when compared to each other, to a reference European population,
and to globally distant populations. Estimations of fixation indices (FST values) between the
Australian, Midwestern American, and Netherlands populations suggest minimal genetic
differentiation compared to the estimates between each population and a genetically distinct
cohort (i.e., samples from Nigeria genotyped on GSA). Thus, results from this study demonstrate
that genotype data from Australian, Dutch, and Midwestern American twin-family populations
can be reasonably combined for joint-genetic analysis.
Keywords: genetic similarity assessment, genotyping microarray, population genetics, population
structure, principal component analysis, twin

93
4.2 Introduction
Scientific investigations aimed at disentangling the contribution of genetic factors
underlying complex and polygenic traits have demonstrated the necessity of large sample sizes
[1, 2]. Only when sample sizes are vast is it possible to estimate the contribution of each locus
influencing a complex trait [3-5]. It is both difficult and financially challenging for a single site
to accrue large enough sample sizes to achieve adequate statistical power. Therefore, one
pragmatic approach for obtaining the large numbers of samples required is to aggregate samples
collected by different groups, either through meta- or mega-analysis. Currently, twin registers
from around the world routinely employ this strategy for genotypic and phenotypic data [6, 7].
This approach is powerful if genetic heterogeneity (e.g., as a result of dissimilar population
ancestry and demographic histories) is not an issue or is appropriately accounted for. Here, we
explore the degree of genetic similarity between multiple twin cohorts and indicate whether it is
appropriate to combine data from these cohorts for joint-genetic analysis.
In 2006, a study by Sullivan et al. empirically showed that samples from Australian and
Netherlands Twin Registers could be reasonably combined for joint-genetic analyses by
estimating the proportion of total genetic variability attributable to the genetic difference between
cohorts [8]. The calculation of the genetic variability attributable to genetic differences between
cohorts, measured by Wright’s fixation index (FST value), was estimated using analysis of
molecular variance on 359 short tandem repeat polymorphism markers. The estimated FST
between Australia (N=519) and the Netherlands (N=549) was found to be 0.30%, a value smaller
than between many other European groups. The FST estimates suggested that it is reasonable to
combine samples from Australian and Dutch cohorts but admittedly based on calculations in
samples of modest size. Here we evaluate the genetic similarity in larger numbers of samples and
augment the comparison by adding a third cohort of samples obtained from the Avera Twin

94
Register (ATR), a representative population sampling of the Midwestern region of the United
States. In this study, we test the genetic variation within and between three populations of interest
- Australian, Dutch, and Midwestern American - by employing genomic data from a custom-
designed genome-wide single nucleotide polymorphism (SNP) array. To further explore the
genetic similarity across the cohorts under study, we incorporated genetic data from a globally
and genetically distinct population - samples from Nigeria genotyped on the Global Screening
Array (GSA) at the Avera Institute for Human Genetics (AIHG).
In collaboration with the Netherlands Twin Register [9-12], the AIHG (Sioux Falls, SD,
USA) created the ATR in May 2016 [13]. The goal of the ATR is to study the genetic and
environmental influences on health, disease, and complex traits by harnessing the power of
longitudinal biological sample collection and survey correspondence. Participants have enrolled
from across all regions of the USA, the great majority coming from Midwestern states, including
South Dakota, North Dakota, Minnesota, Iowa, and Nebraska. In addition to serving as a prime
research model for studying health and disease in a regional setting, another important role of the
ATR is to contribute to consortia-driven large-scale genetic studies focusing on the genetic
underpinnings of complex traits. Therefore, it is of interest to recognize the degree of genetic
similarity between the Midwestern Americans comprising the ATR and the cohorts for which the
genetic data are to be combined.
As long-established twin registers, the Netherlands and Australian Twin Registers have
served as models for newly formed twin registers from around the world. As is the case for the
ATR, the Netherlands and the Australian Twin Registers are population-based, with recruitment
focused on the presence of twins or higher-order multiples in the family. Through this
collaborative initiative, we included 100 saliva samples from Nigerian mothers of twins to use as
a genetic contrast group to Australian, Dutch, and Midwestern American populations. The

95
incorporation of genetically distinct samples further enhances the cross-ethnic comparisons that
we describe here.
The AIHG recently joined the Illumina-initiated GSA consortium. Broadly, the goal of the
consortium is to enable a variety of genotyping applications for biobanks, disease research,
translational research, consumer genomics, and population genetic studies. Specifically, the GSA
has been optimized for high-throughput population-scale studies at a lower cost than previous
genotyping platforms. Participation of the AIHG in the GSA consortium has allowed for the
unique opportunity to design a customized high-density SNP genotyping microarray. A similar
strategy for designing population-specific arrays for genome-wide association (GWA) testing has
already been described, albeit for a different genotyping platform [14].
Here, we report on the design and initial validation of the array, as assessed by the
evaluation of concordance, coverage, and imputation quality of the core backbone against the
Genome of the Netherlands (GoNL) reference set [15, 16]. Additionally, we provide evidence to
suggest that the custom-selected content generally enhances imputation quality and provides
robust genotype calls for population- and disease-relevant SNPs. Furthermore, we demonstrate
that the GSA can be utilized to generate high-quality SNP data from multiple tissue sources,
namely blood, buccal epithelial brushings, and saliva.
With high-density SNP genotype data obtained from the GSA run at AIHG, we assessed
the level of genetic similarity across population cohorts of interest: Australian, Dutch, and
Midwestern American. To facilitate the assessment of population genetic structure, we leveraged
the power of state-of-the-art software capable of ingesting genome-wide SNP data obtained from
the GSA. Population genetic variation was summarized by uncorrelated principal components
(PCs) through principal components analysis (PCA) and estimations of FST values. Furthermore,
we projected the PCs estimated from the samples onto data from the Human Genome Diversity

96
Project (HGDP) [17]. Projection of calculated PCs onto the diverse populations comprising the
HGDP fostered a global illustration of genetic relatedness between the populations of interest.
4.3 Materials and Methods
4.3.1 Participants and Sample Collection
Australian subjects were from the QIMR Berghofer Medical Research Institute (N=1922)
[18, 19]. Other subjects were registered participants of the Netherlands (NTR, N=10,226) [10]
and Avera (ATR, Sioux Falls, SD, USA, N=602) [13] Twin Registers, and the Nigerian Twin and
Sibling Registry (NTSR, N=100) [20] (see Table 4.1).
Representative samples of the Midwestern American population were obtained from the
ATR. Enrolled participants include twins, multiples, siblings, and their parents. Participants
complete surveys and questionnaires and provide a cheek swab (buccal brushing) for zygosity
testing and genotyping. The majority of the enrolled participants are located in the Midwestern
region of the United States, with most being from South Dakota, Minnesota, and Iowa.
"JOS
poyeporUN
94}
Wo
poyodal
st
sajdures
oTeud}
JO
93vUDNIN
gy,
SUIM}
JO
SjuorTed
—
sjuored
‘sSul][qis
=
sqIs
‘suLM}
O1}03AZIp
xos-oyIsoddo
jo
sioyjowW
=
ZQSOW
‘SUM
7q
Jo
SIOyJOW
=
TZCONW
‘suimy
osn0s8Azip
=
ZC
‘Sumy
snosAzouow
=
ZI
‘sodwies
Jo
Joquinu
=
NY
{1djSIsOY
UIM,
S,PULTIOUION
=
ULN
‘Abiy
surusaog
[eqo[H
=
VSD
ajdwes
TZ6Z
0S8‘ZT
[2301
BAI|ES
96
ZQsSOW
OOT
OOT
elasIN
UeLasIN
poo|q
8vrT
1ZQ0W
OOT
CC6L
BIJEASNY
UBI/EAISNY
Jesong
sqis
‘sjuaied
‘7q
‘ZIN
T606
SPUCLYOYION
YLN
6€T9
VSS
poo|d
sqis
‘syuased
‘7q
‘ZN
SeTT
SPUCLYOYION
YLN
Jesong
BEC
sqis
‘sjuaied
‘7q
‘ZN
v'99
cO09
vsn
Jasiday
UM,
e1aAy
anssiL
S|ENPIAIPU]
pazeja1uU/)
uonisodwo,)
4
(%)
ajeway
N
uIZIIC
4o
Asjuno>
yoyo)
onssy
pue
3.10409
19d
WS
Uo
podAjoues
sojduies
Jo
soysl19}9vIvYD
—
['p
IQR],
97

98
Samples from the QIMR Berghofer Medical Research Institute (Australia) are a
combination of a number of different studies, conducted in many countries over many decades,
focused on the genetics of dizygotic twinning [21]. Samples from mothers of dizygotic twins
(MODZT) were collected from Australia and New Zealand and were shipped to the AIHG for
genotyping on the GSA regardless of if they were ungenotyped or previously genotyped on an
earlier SNP array. Included in the shipment were two small cohorts of special interest: (1) a
Belgian sample of 40 MODZT from 14 multiplex families collected in the 1990s; (2) a sample of
10 MODZT from two multiplex families from the Utah Mormon Database collected in 1994. For
the purposes of the study presented here, samples from Belgium and Utah were excluded from
the Australian cohort.
The Nigerian sample in the present study was drawn from the NTSR, which included
over 3000 adolescent monozygotic and dizygotic twins, their parents, and siblings collected
mainly from public schools in Lagos State and Abuja, Federal Capital Territory in Nigeria.
Participants of the NTSR completed questionnaires and provided saliva or buccal samples for
genotyping. The sample used in the present study consisted of 100 mothers of opposite-sex twins
attending public schools in Lagos State, collected for the purpose of a pilot study to understand
the genetic underpinnings of dizygotic twinning. Lagos State is located in the southwestern
geopolitical zone of Nigeria and is one of the most populous urban areas in Nigeria. Although
residents of Lagos State are ethnically diverse, they are mainly members of the Yoruba group.
Participants from the NTR included twins, their parents, and other relatives (mainly
siblings of twins). NTR participants take part in surveys and other research projects and provide
blood or buccal samples for DNA isolation and genotyping.
99
4.3.2 DNA Extraction and Genotyping
DNA was isolated from whole blood, buccal epithelial cells [22], and saliva using
standard protocols for downstream SNP genotyping. High-density SNP genotyping for all
samples was done at the AIHG (Sioux Falls, SD) using a custom-designed Illumina GSA
according to the manufacturer’s protocol.
4.3.3 Design of a Customized Genotyping Array and Generation of Genotype Data
The GSA employed for this study was designed following a previously defined strategy for
designing population-specific customized genotyping arrays [14]. Specifically, the GSA was
custom-designed to contain a core imputation backbone (approximately 660,000 markers) based
on commonly utilized reference panels, such as the GoNL [15] and the 1000 Genomes Project [23].
In addition to the core backbone, the array includes approximately 30,000 additional markers for
fine mapping to further enhance imputation quality and 8000 markers of interest associated with a
variety of conditions, disorders, and traits, including neuropsychiatric disorders, drug metabolism,
fertility, and twinning (Table 4.2). In total, the GSA contains 697,486 markers.
Table 4.2 – Content and marker selection categories of the custom-designed Illumina GSA
Marker Type
Number of SNPs (N=697,486)
GSA Core Backbone
Total ~660,000
Sex Chromosomes
17,880 X; 1480 Y; 578 PAR
ADME Genes/Exons
6668; 2787
ClinVar
17,020
MHC
9797
Ancestry Informative
3212
Fine Mapping Content (candidate genes and additional markers for
imputation)
Total ~30,000
Custom Markers
Total ~8000
100
Fertility and Twinning
Body Stature (height, BMI) and Sports and Exercise Behavior
Mental State and Health (happiness, depression, schizophrenia)
Chromosome X (imputation)
Educational attainment
Pharmacogenomics
GSA = Global Screening Array; ADME = Absorption, distribution, metabolism, excretion; BMI
= body mass index; ClinVar = NCBI archive for interpretations of clinical significance of genetic
variants; MHC = major histocompatibility complex; PAR = pseudoautosomal region
Prior to the design of the array, initial validation of the GSA content for imputation was
assessed by checking concordance, coverage, and imputation quality using an extracted subset of
markers resembling the GSA (683,937 markers). In brief, a dataset mimicking the content on the
GSA was curated from 249 unrelated female individuals of the GoNL project. Males from the
GoNL were excluded as the tools used for assessment of genotyping array coverage could not
properly handle a homozygous X chromosome. GSA-mimicked markers were quality controlled
and retained if minor allele frequency (MAF) was >0.01, missingness per individual was <10%,
missingness per SNP was <5%, and if there was no statistically significant deviation from Hardy-
Weinberg Equilibrium (p > 10-5). Quality control and filtering reduced the number of markers to
617,340. Extracted and quality-controlled markers were then selected if they were present in the
1000 Genomes (1000G) reference panel [23] (616,961 markers). The extracted set was phased
with SHAPEIT [24] and imputed against the 1000G reference panel phase 3 using
IMPUTE2 [25]. For the ~12.1 million overlapping markers, concordance was calculated in
PLINK [26, 27] by comparing the 1000G best-guess genotypes to the original GoNL genotypes.
Genotype calls from the GSA were made using Illumina GenomeStudio2.0 and
customcurated cluster files. In short, cluster positions were defined using genotype data on 1254
samples run on GSA at AIHG by a variety of technicians and across many batches (i.e., reagent

101
and bead-chip lots) to account for as much sample variation as possible. Initial assessment of
sample-dependent and sample-independent controls, preliminary call rates, and percentile
distributions of GenCall scores (a quality metric indicating the reliability of genotype calls)
yielded a final sample set of 1199 samples for defining cluster positions. Samples were grouped
into males and females so that Y chromosome (1480 markers) and X chromosome (17,880)
clusters could be generated using subsamples of the appropriate sex. Due to the behavior of the
GenomeStudio clustering algorithm, only male samples were used for defining Y chromosome
clusters. Similarly, only female samples were used for generating X chromosome clusters since
males are not expected to be heterozygotes for X-linked markers. Therefore, X and Y markers
were clustered and evaluated, taking gender into account. All samples were used to cluster
autosomal SNPs (670,744 markers), including XY and mitochondrial markers.
Following initial clustering, cluster positions were evaluated and edited based on a
sequential assessment of several cluster metrics. Cluster positions were zeroed (resulting in no
genotype calls for a locus) based on low cluster separation (£0.27), low call frequency (<0.96),
low mean normalized intensity values for the heterozygote genotypes (£0.2), extreme mean
normalized theta values of the heterozygote cluster (<0.2 or >0.825), Mendelian inconsistencies,
ambiguous clusters, excessive numbers of reproducibility errors, and excessive heterozygote
calls relative to expectations based on Hardy-Weinberg Equilibrium (>0.2). Markers on X and Y
chromosomes were manually evaluated and edited on a per-marker-basis.
4.3.4 Data Management, Quality Control, and Relationship Inference
Individual samples were removed if they had a missing rate greater than 10% or excess
genome-wide inbreeding levels/heterozygosity (as calculated in PLINK, F coefficient <-0.10 or

102
>0.10). Reported sex was compared with inferred sex from the genotype data. Sex mismatches
were investigated, resolved, and subsequently replaced in the dataset.
From each population sample, we selected the largest group of unrelated individuals
(shown in Table 4.1). Unrelated individuals were identified with KING software [28] using the ‘-
unrelated’ option. In brief, related individuals (estimated kinship coefficient <0.088) were
clustered into families. Within each connected group, individuals were ranked according to the
count of unrelated family members, corresponding to an estimated kinship coefficient <0.022. A
set of unrelated individuals was then made by selecting the individuals with the largest count of
unrelated individuals within the respective family group. Additional unrelated individuals were
obtained by taking the individuals with the next most unrelated family members, only if that
individual was not related to any of the previously selected unrelated individuals. The final
selection contained no pairs of individuals with a 1st or 2nd-degree relationship, reducing the
sample size to 7921 subjects. Following quality control, the number of samples was reduced to
7782.
4.3.5 SNP Quality Control and 1000G Alignment
All autosomal SNPs that passed quality control and filtering were analyzed. PLINK was
used to perform quality control. A selection of high-performing markers (N=564,020) was used
for subsequent quality control and analyses. Specifically, SNPs were removed if they were not in
the 1000G reference panel (phase 3 version 5) or if they were palindromic SNPs with an allele
frequency of 0.40-0.60. Polymorphic SNPs with more than two alleles were also excluded. SNP
marker names were adjusted for congruity with 1000G, and strand flip issues were resolved.
SNPs were removed if their call rate was less than 95% and if they differed significantly from
Hardy-Weinberg Equilibrium (p < 10-5).

103
4.3.6 Principal Component Analysis
PCA was performed with smartpca of the EIGENSOFT package [29] with its default
parameter settings. PCA was used to compute 10 PCs for the populations under study. Initial
ancestry outliers were determined by merging each independent dataset with 1000G data to
project ethnicity with smartpca. Ancestry outliers, based on non-European ancestry, were
visually identified and subsequently removed.
Cleaned and 1000G aligned data for each population were filtered to retain SNPs having
a MAF >0.05, linkage disequilibrium (LD) pruned and filtered to exclude confounding SNPs in
long-range LD, as previously described [30, 31]. Filtering and exclusion of long-range LD
regions reduced the number of autosomal SNPs from 564,020 to 109,702 SNPs. This number of
SNPs was used for comparisons between samples genotyped on GSA, namely those from
Australian, Midwestern American, Dutch, and Nigerian cohorts.
We also calculated if there were statistically significant pairwise differences between the
Australian, Dutch, and Midwestern American populations and representative European
populations from the HGDP using smartpca. For each pair of populations, ANOVA statistics
along each eigenvector were summed across all 10 eigenvectors.
4.3.7 HGDP Data Management and Projection
To establish genetic similarity on a global scale, PCs of the Australian, Dutch,
Midwestern American, and Nigerian populations were projected onto samples obtained from the
HGDP [17, 32]. The HGDP data comprises genotypes (660,918 SNPs) from 1,043 fully
consenting individuals representing 54 global populations from sub-Saharan Africa, North

104
Africa, Europe, the Middle East, Central and South Asia, East Asia, Oceania, and the Americas
and provide a representative sampling of worldwide genetic variation (available at:
https://www.hagsc.org/hgdp/files.html).
Raw genetic data from the HGDP (sample call rate > 98.5%) were reformatted for PLINK
using command line tools. Markers with greater than 5% missingness were removed. Following
the same procedures as previously described, unrelated individuals were identified in the HGDP
dataset and retained using the program KING. Removal of related individuals reduced the sample
size from 1,043 to 857. To be consistent with GSA, HGDP data were converted from Build 36.1
coordinates to Build 37/hg19 using the University of California, Santa Cruz (UCSC’s) batch
coordinate conversion tool, liftOver [33, 34]. Overlapping markers between HGDP and GSA
(prior to MAF filter, LD pruning, and exclusion of long-range LD) were identified in the variant
information files (.map) using R [35]. Of the 133,833 common markers between the datasets,
there were 21,667 multi-allelic variants due to strand inconsistencies. Strand flips were resolved,
and data from the HGDP were merged with cleaned and filtered GSA data using PLINK. The
merged set was filtered to remove markers with a MAF < 0.05, pruned for LD, and excluded
SNPs in long-range LD. Quality control and filtering reduced the final number of markers to
54,820.
Ten principal components were calculated using smartpca within EIGENSOFT with
default parameters. All HGDP populations were specified as reference populations for the PC
projection.
4.3.8 Case-Control GWA Study
We performed a case-control GWA study (GWAS) between Midwestern American,
Australian, and Dutch populations to gain insight into the degree of genetic relatedness between

105
them. To avoid false positives, we excluded variants with a MAF < 0.10 in the quality-controlled
and filtered data on unrelated individuals. Simple association testing was done in PLINK with the
‘--assoc’ command. Two GWASs were performed, both with the Midwestern American
population defined as cases and with Dutch and Australian samples serving as controls.
Manhattan plots and quantile-quantile (QQ) plots were created to visualize regions of the genome
that appeared statistically significant.
4.3.9 Calculation of FST Estimates
To quantify measures of structure in populations, we estimated FST values between
Midwest American, Australian, Dutch, and Nigerian cohorts. Weir and Cockerham [36] and
Hudson [37] estimators were calculated using two different software programs: popstats [38] and
scikit.allel [39], implemented in Python.
4.4 Results
4.4.1 Validation of the GSA
Imputation quality metrics, quantified by R2 values, are presented in Table 4.3. For all
1000G imputed autosomal SNPs, including those present in African and Asian populations, the
median R2 values for the GSA are 0.02 for MAF>0.000-0.001, 0.69 for MAF>0.001-0.01, 0.97
for MAF>0.01-0.05, and 0.99 for MAF>0.05. For the selection of autosomal SNPs that were
present in both the GoNL and 1000G reference data, indicative of true genetic variants in the
Dutch population, the results demonstrate improved imputation quality compared to all SNPs
present in 1000G. The median R2 values of the SNPs in the GoNL and 1000G reference set are
for 0.04 MAF>0.000-0.001, 0.80 for MAF>0.001-0.01, 0.97 for MAF>0.01-0.05, and 0.99 for
MAF>0.05. Here, the improved imputation quality, captured by both median and mean scores, is
106
mainly the result of the exclusion of a large number of rare SNPs (i.e., SNPs in African and Asian
populations - captured by the full 1000G set), which are likely absent from the Dutch population.
Table 4.3 – Imputation quality metrics per minor allele frequency bin for the GSA
Selected SNPs
Chr
MAF range
N SNPs
Median R2
Mean R2
SD
1000G All SNPsa
1-22
>0.000-0.001
21,373,838
0.02
0.05
0.08
>0.001-0.01
6,853,643
0.69
0.64
0.28
>0.01-0.05
2,863,052
0.97
0.91
0.13
>0.05
6,974,825
0.99
0.96
0.08
GoNL and 1000Gb
1-22
>0.000-0.001
1,003,022
0.04
0.08
0.10
>0.001-0.01
2,736,096
0.80
0.74
0.24
>0.01-0.05
2,461,024
0.97
0.92
0.12
>0.05
5,874,328
0.99
0.97
0.07
GSA = Global Screening Array; Chr = chromosome; MAF = minor allele frequency; N SNPs =
number of SNPs; SD = standard deviation; GoNL = Genome of the Netherlands a Denotes full
1000G imputation with Asian/African/other SNPs not present in the Dutch population
b Denotes overlapping SNPs between GoNL and 1000G
All monomorphic SNPs were excluded, thus only polymorphic SNPs were selected for each
comparison.

107
Concordance of the genotyped GoNL SNPs that were reimputed with a 1000G imputation
reference panel was high for most SNPs in the genome, as can be seen in Table 4.4. In the
imputed data, of the 12,074,470 polymorphic variants with a MAF>0, up to 62.2% can be
reimputed with very high quality. At lower levels of quality (below 80% concordant), 1.95% of
the genome is not well covered.
108
Table 4.4 – Genotype concordance for GSA-mimicked, genotyped GoNL SNPs that were
reimputed with 1000G reference panel
Concordance (%)
N SNPs
Percent
> 99
7,506,660
62.17
> 95-99
3,470,030
28.74
> 80-95
861,745
7.14
> 50-80
221,831
1.84
£ 50
14,204
0.11
Note: Total number of 1000G SNPs that were reimputed, polymorphic and present in GoNL =
12,074,470.
GSA = Global Screening Array; GoNL = Genome of the Netherlands; N SNPs =number of SNPs

109
4.4.2 Principal Component Analysis
We performed a fine-scale PCA of unrelated subjects from Australian, Dutch, and
Midwestern American populations to investigate the degree of genetic relatedness of these
populations independent of other global populations. The PCA utilized 109,702 autosomal SNPs
after stringent quality control, filtering, pruning, and exclusion of long-range LD regions. As seen
in Figure 4.1, results of the PCA suggest that the Midwest American, Australian, and Dutch
populations are not genetically distinct from one another since the clusters moderately overlap.
The Midwest American cluster partially superimposes both Australian and Dutch clusters, which
themselves also show a small degree of overlap. Visualization of PCs from the PCA on
Australian, Dutch, and Midwestern Americans demonstrates the commonality of population
clusters, thereby suggesting a high degree of genetic similarity between these populations.
Provided the unique opportunity to genotype Nigerian mothers of twins on the GSA, a
PCA was performed with the inclusion of these globally distinct samples to serve as a genetic
contrast group to the populations under study. Thus, to enhance the investigation of the genetic
similarity of Australian, Dutch, and Midwestern American populations on a broader scale, we
performed a PCA on all samples genotyped on GSA at AIHG, including those from Nigeria. The
results of the PCA are depicted in Figure 4.2. The inclusion of a geographically and genetically
distant population resulted in the distinct separation of European-ancestry-based populations and
the Nigerian cohort, indicative of population stratification and genetic dissimilarities.

110
Figure 4.1 – Genetic ancestry of Midwestern American, Australian, and Dutch subjects
Shown are the results from PCA using autosomal genotyped SNPs after quality control, filtering,
pruning, and exclusion of long-range LD (109,702 markers). Ancestry outliers were removed
prior to performing PCA. PC1 and PC2 represent the first and second PCs and account for
18.864% and 11.919% of the variation, respectively.
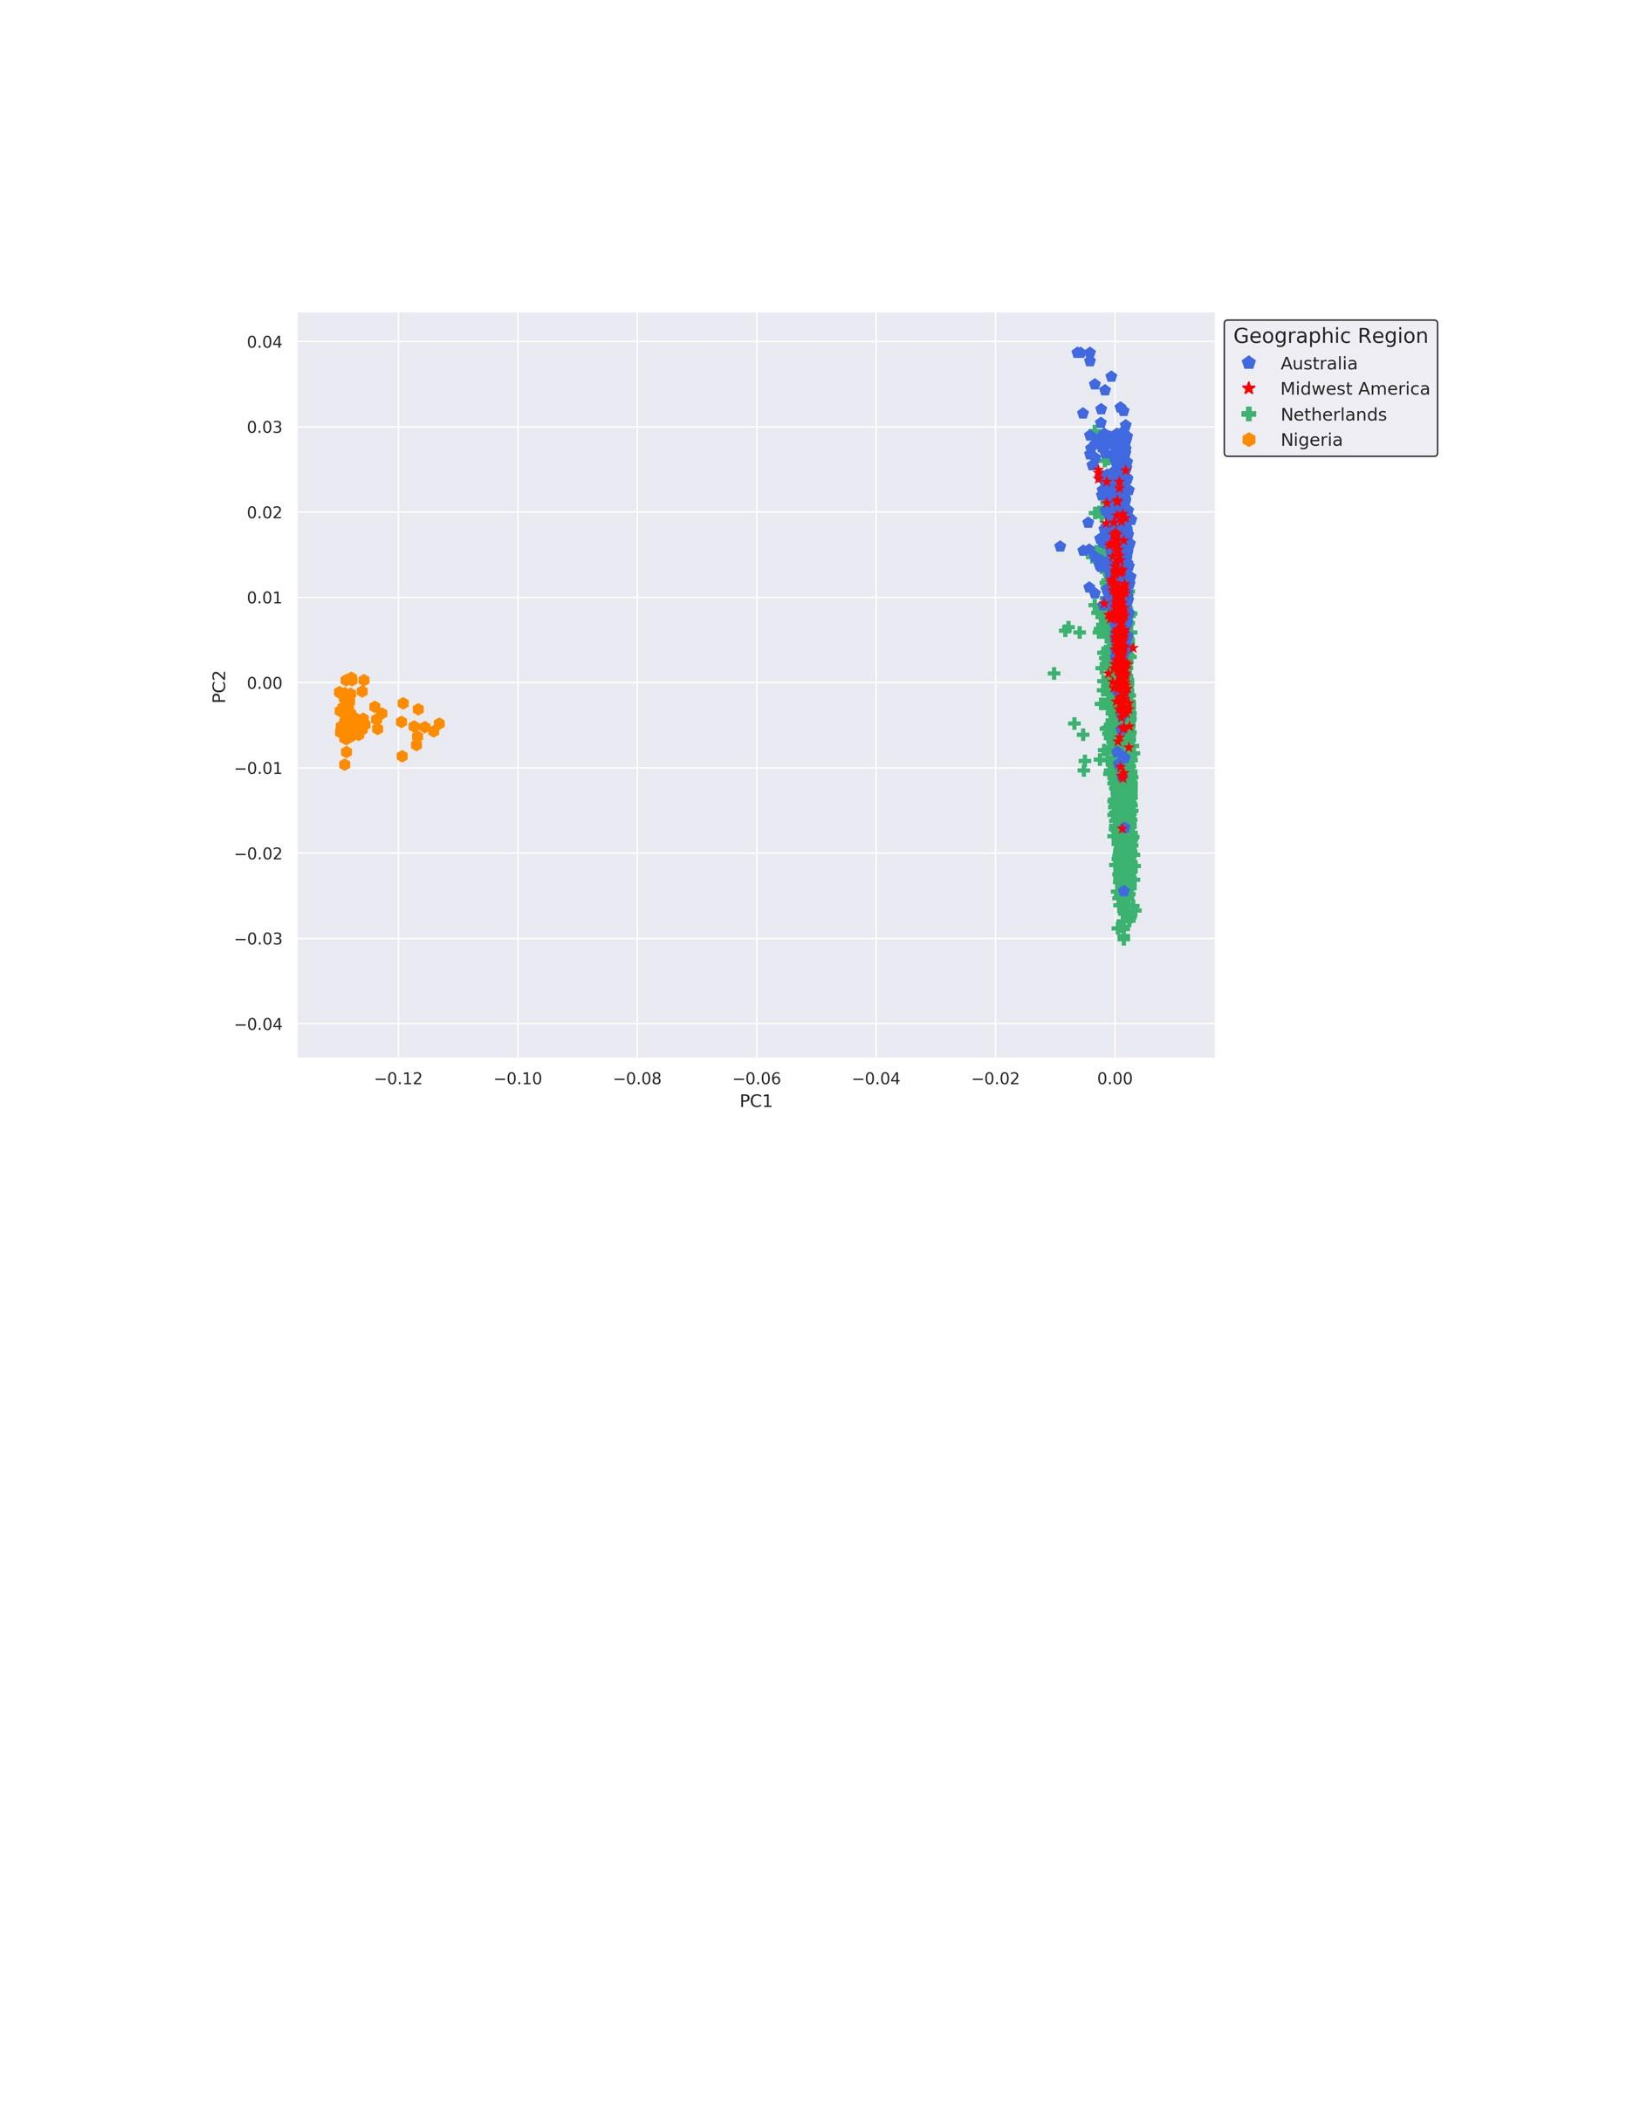
111
Figure 4.2 – Genetic ancestry of Midwestern American, Australian, Dutch, and Nigerian
subjects
Shown are the results from the PCA using all autosomal genotyped SNPs after quality control,
filtering, pruning, and exclusion of long-range LD (109,702 markers). Ancestry outliers were
removed prior to performing PCA. PC1 and PC2 represent the first and second PCs and account
for 67.765% and 6.568% of the variation, respectively.
Projection of PCs from all samples genotyped on GSA onto those from the HGDP
allowed for visualization of populations on a globally diverse scale. Results of the PCA using the
HGDP as reference populations showed clear layering of the Australian, Dutch, and Midwestern
American populations on the representative European HGDP cohort (Figure 4.3). The HGDP
European population is comprised of samples collected from France, Italy, Italy-Bergamo,
Orkney Islands, Russia, and Russia-Caucasus. At the global level, the Australian, Dutch, and
Midwestern American samples showed strong distinction from African and Asian populations.
Alternatively, the PCs of the cross-ethnic comparison demonstrated strong overlap between the
Nigerian samples and the representative African population from HGDP. The HGDP African
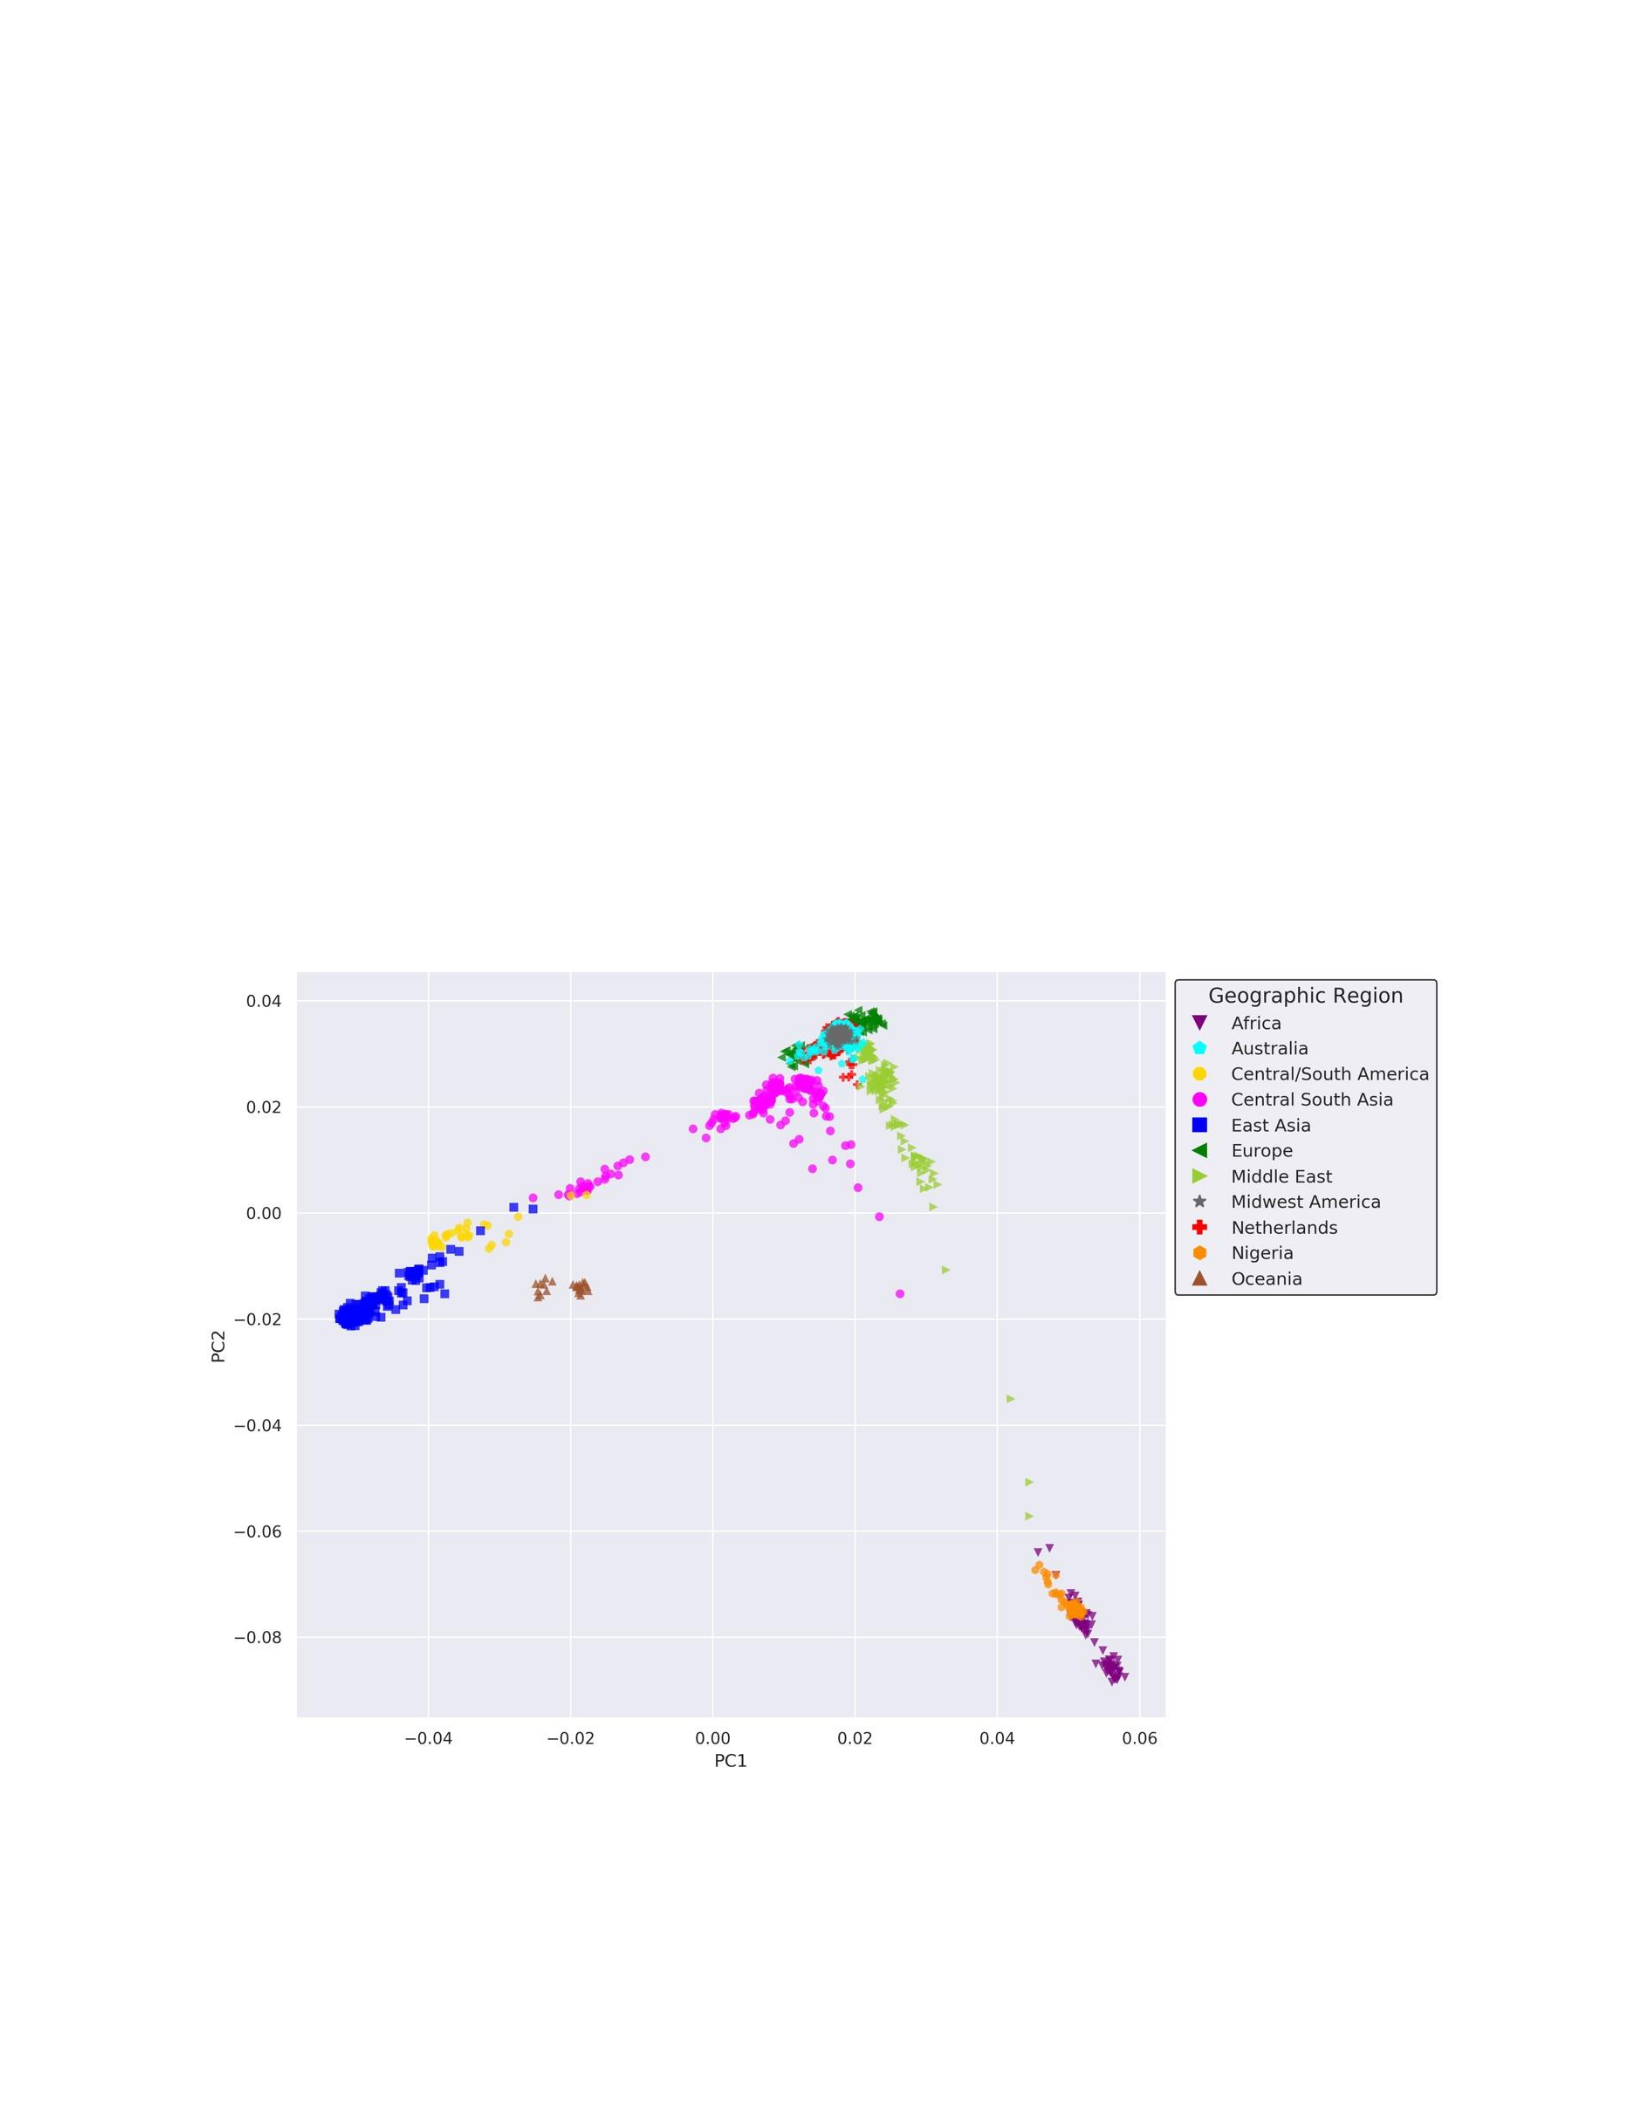
112
population was made up of samples obtained from Angola, Botswana, Central African Republic,
Congo, Kenya, Lesotho, Namibia, Nigeria, Senegal, South Africa, and Sudan. The results suggest
that global genetic diversity can be observed by plotting PCs and that Australian, Dutch, and
Midwestern American populations show nearest genetic relatedness to European populations.
In order to provide a quantitative estimate of relationships between populations in a
pairwise fashion, we used smartpca to sum ANOVA statistics across all eigenvectors (parameter
default of 10 eigenvectors). The results of the pairwise comparisons of Australian, Dutch, and
Midwestern Americans are shown in Table 4.5. Statistically significant differences were observed
for each pairwise comparison, suggesting the existence of population stratification.
Figure 4.3 – Projection of PCs for Midwestern American, Australian, Dutch, and Nigerian
subjects onto HGDP populations.
Shown are the results from the PCA using autosomal genotyped SNPs that were in common with
HGDP after quality control, filtering, and exclusion of long-range LD (54,820 markers).
Ancestry outliers were removed prior to performing the PCA. PC1 and PC2 represent the first
and second PCs and account for 38.048% and 28.811% of the variation, respectively.
113
Table 4.5 – Statistical significance of differences between populations
Population 1
Population 2
Chi-square
P-value
Midwestern American
Netherlands
457.171
6.169x10-92
Midwestern American
Australian
660.324
2.053x10-135
Australian
Netherlands
7121.469
0
Note: For each pair of populations, ANOVA statistics along each eigenvector were summed
across eigenvectors. Degrees of freedom are equal to 10, the default number of eigenvectors.

114
To put in context the genetic differences between Australian, Dutch, and Midwestern
Americans, we tested for significant differences between them, the samples obtained from
Nigeria, and all HGDP populations, including representative European populations
(Supplementary Materials Tables 4.1 and 4.2). All comparisons between Australian, Dutch, and
Midwestern American and HGDP European populations were statistically significant, with the
comparison between Australian and the Orkney Islands populations being least significant. More
generally, for each cohort, the statistical comparison with the Orkney Islands resulted in the least
significant difference.
4.4.3 Case-Control GWAS
We performed two case-control GWAS between Midwestern American (cases) and
Australian (controls) and Dutch (controls) populations using only common variants. A MAF
filter (MAF>0.10) was employed to avoid false positives due to minor allele frequencies. The
GWAS between Midwestern American (227 ‘cases’) and Australian (1354 ‘controls’) utilized
228,166 variants after MAF filtering. Results of the case-control GWAS between the two
populations are visualized in a Manhattan plot (Figure 4.4c). Four chromosomal regions
exhibited genome-wide significant differences (p<5x10⁻⁸). The dbSNP ID numbers for the
significant SNPs are: rs6420020 (chromosome 5, p=1.571x10⁻¹⁵), rs10817415 (chromosome 9,
p=3.832x10⁻¹⁵), rs11599284 (chromosome 10, p=5.387x10⁻¹⁴), rs78611721 (chromosome 20,
p=2.164x10⁻¹⁴). The frequency of these SNPs was much greater in Australians than in American
individuals. The QQ-plot (Figure 4.4d) of genome-wide p-values showed a modest deviation
from the null hypothesis of no association. The overall GWAS genomic control statistic (l) was
1.153, indicating slight inflation due to population structure, driven by a small number of
polygenic variants, between the Midwestern American and Australian populations.

115
The second case-control GWAS was performed between Midwestern American (227
‘cases’) and Dutch (6139 ‘controls’) using 228,025 common variants after MAF>0.10 filtering.
The results of the case-control GWAS between the two populations are presented in the
Manhattan plot in Figure 4.4a. No statistically significant variants exceeded the genome-wide
significance threshold (p<5x10⁻⁸). The QQ-plot (Figure 4.4b) shows slight genomic inflation
across the entire range of p-values. The GWAS genomic control statistic (l) was 1.159, again
indicating slight inflation due to population structure differences between the Midwestern
American and Dutch populations.
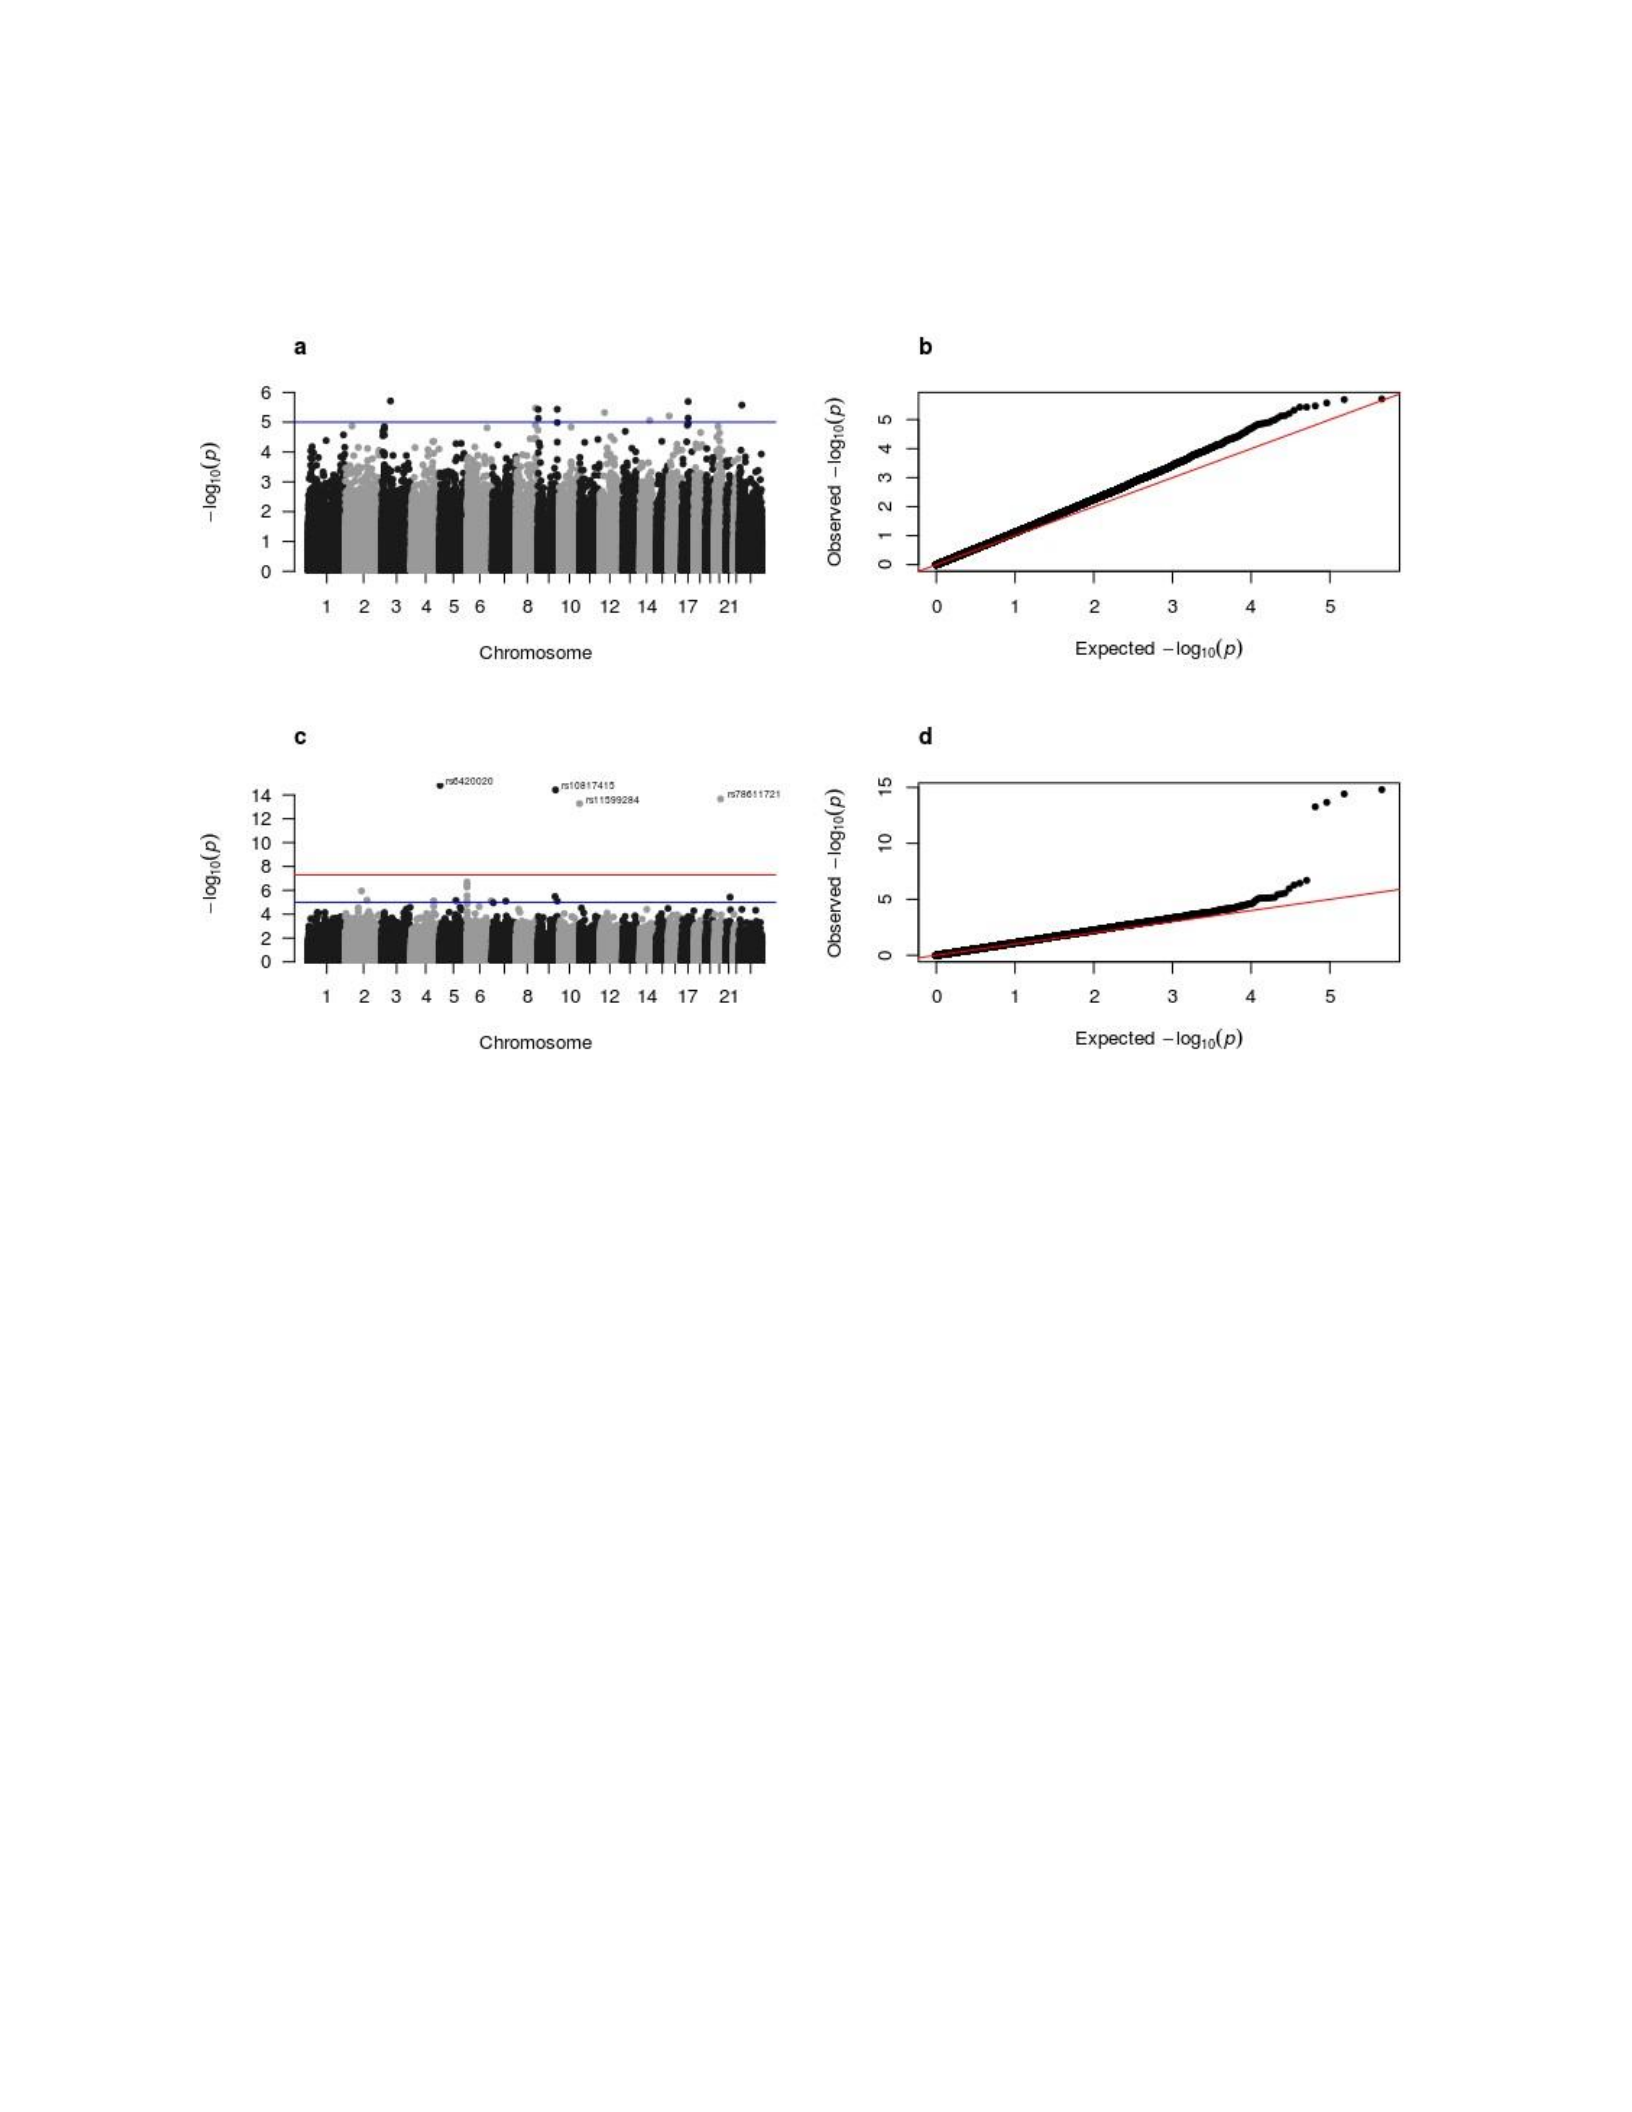
116
Figure 4.4 – Results of the case-control GWAS between Midwestern American (cases),
Australian (controls), and Dutch (controls) populations
(a) Manhattan plot of the case-control GWAS of Midwestern Americans (227 cases) and Dutch
(6139 controls) using 228,025 variants after MAF>0.10 filter. (b) QQ plot of observed vs.
expected p-values of the association results between Midwestern American and Dutch
populations (l= 1.159). (c) Manhattan plot of the case-control GWAS of Midwestern Americans
(227 cases) and Australians (1581 controls) using 228,166 variants after MAF>0.10 filter. (d)
QQ plot of observed vs. expected p-values of the association results between Midwestern
American and Australian populations (l= 1.153). Shown in each Manhattan plot is a blue line
depicting a suggestive level of statistical significance (p=1x10⁻⁵). In panel (c), the red line
represents a genome-wide level of statistical significance (p = 5x10⁻⁸). The rs numbers point to
the chromosomal region that reached the genome-wide significance level. Variants with a
MAF<0.10 were excluded. All related individuals and ancestry outliers were removed prior to
performing the associations.
4.4.4 FST Estimates
FST values were calculated as a measure of genetic differentiation between populations.
We generated FST values using two approaches, namely Weir and Cockerham [36] and Hudson
[37] estimators. As demonstrated in 2013 by Bhatia et al., the Weir and Cockerham estimator is
dependent on the ratio of sample sizes comprising each population [40]. Therefore, an alternative

117
approach is to use the Hudson estimator, which can be implemented as a strategy independent of
sample sizes, even when FST is not uniform across populations. The result produced by the
Hudson estimator is a simple average of the population-specific estimators originally defined by
Weir and Hill [41]. Ultimately the Hudson estimator was recommended by Bhatia et al. for
estimating FST for pairs of populations with unequal sample sizes.
The FST estimates from both the Weir and Cockerham and Hudson estimators are shown
in Table 4.6 and are relatively close to previously reported estimates from the HapMap
consortium [42] and GoNL project (see Supplementary Table 5 of ref[16]). Regardless of the
estimator, smaller FST estimates are observed between Australian, Dutch, and Midwestern
American populations than between each population compared to the Nigerian cohort. Consistent
with the work of Bhatia et al., it is important to note that the choice of the estimator made an
impact on the resulting FST estimate.
118

119
4.5 Discussion
To gain insight into the routine practice of aggregating genomic datasets from twin
registers from around the world, we investigated interpopulation genetic variation with
genomewide data generated on GSA from Australian, Dutch, and Midwestern American
populations. Here, we report on the inception and initial validation of a custom-designed Illumina
GSA and its implementation in studying population genetic variation. Through quantitative
measures and visualization of PCs, results of work presented here suggest a high level of genetic
similarity between the Australian, Dutch, and Midwestern American populations, albeit with
small yet statistically significant differences existing between them.
The custom-designed GSA provides a genotyping platform initially optimized for
imputation containing a core imputation backbone supplemented with additional fine-mapping
content to bolster imputation quality and genome-wide coverage. Also featured on the GSA are
custom-selected markers specific to phenotypes of interest, notably for fertility and twinning.
With the use of the GoNL reference set and a selection of markers mimicking the GSA,
we demonstrated that we can reimpute genotypes with a high degree of confidence. Exceptions
are made for rare alleles (MAF<0.0001), which are never well imputed [43]. A limitation to the
validation of the GSA is that we utilized the sequences of only 249 samples; therefore, the
imputation and presence of alleles with a MAF<0.01 was likely less than ideal. However, by
comparing the validation results of the Illumina GSA to other commercially available genotyping
platforms, the imputation quality of the GSA is well in line with other genotyping products (refer
to Table 1 and Table 2 in [14]). Additionally, the method of testing the coverage using two
reference datasets to check concordance between genotyped and reimputed SNPs utilizes SNPs
in union with both reference panels. Thus, we inherently assume that SNPs specific to a
population – for example, those SNPs only appearing in GoNL – are covered and imputed in

120
such a manner. Nevertheless, the GSA has been instrumental in generating high-quality genotype
data from cohorts around the world for use in population genetic studies of complex traits.
PCs often show a remarkable correlation with geography, a manifestation of decreasing
genetic similarity with increasing geographic distance. Thus, we performed PCA and visualized
PCs to elucidate the degree of genetic resemblance among Australian, Dutch, and Midwestern
American populations. Visualization of PCs for the three populations under study shows a high
degree of overlap between PCs 1 and 2. The similarity observed between Midwestern American
and Dutch populations is consistent with estimates of 4.1 million Americans (1.28% of the USA
population in 2017) claiming total or partial Dutch heritage [44]. In large part, the majority of
inhabitants of Midwest America have ancestral origins rooted in Northwestern Europe because of
common migratory routes. Lending additional support to the Midwestern American and Dutch
similarity is the fact that the majority of the Dutch Americans reside in Michigan, California,
Montana, Minnesota, New York, Wisconsin, Idaho, Utah, Iowa, Ohio, West Virginia, and
Pennsylvania. Together, it is apparent that there is strong Dutch influence and saturation in the
Midwestern region, which is reflected in the genetic profiles of these populations.
Broad-scale comparison to diverse populations from around the world, such as those
represented by the HGDP, further portrayed similarity among Australian, Dutch, and Midwestern
American and with European populations more generally. The close resemblance of Australian
and European populations is consistent with prior empirical results [45] and the fact that
immigrants from Northern Europe colonized Australia (mainly from Britain and Ireland) and
America. Incorporation of genotype data from a globally distinct population (i.e., Nigerian
samples genotyped on GSA) facilitated the projection of the PCs onto the HGDP and
recapitulated worldwide genetic diversity.

121
Quantitative measures of population similarity, as measured by summed ANOVA
statistics over eigenvectors, revealed small yet statistically significant differences among
Australian, Dutch, and Midwestern American populations. Additional comparisons of each
population to individual HGDP European cohorts further demonstrated significant differences
suggestive of population stratification. Likewise, patterns of FST estimations were consistent with
the geographical clustering observed in PCA and with previous FST estimates of global
population genetic differentiation. Altogether, it is likely that the observed population genetic
dissimilarities are due to systematic allele frequency differences resulting from migration,
adaptation, drift, and selection.
In general, large GWAS efforts aimed at discerning the genetic contributions to complex
traits typically rely on meta-analyses of multiple cohorts of relatively homogeneous populations.
Thus, to assess the level of homogeneity among Midwestern American, Australian, and Dutch
cohorts, we performed case-control association testing between populations. Case-control
GWAS of Midwestern American and Australian populations yielded results to suggest that only
small genetic differences exist between the populations under study. We hesitate to interpret the
few differences observed between the Australian and Midwestern American populations,
although we note that it is possible that the genome-wide significant SNPs (rs6420020,
rs10817415, rs78611721, and rs11599284) could be implicated in the dizygotic twinning
phenotype given that the genotyped Australian group consisted of MODZT. Between Australian
and Midwestern American populations, genomic inflation appeared to be primarily driven by a
small number of highly polymorphic SNPs, while the remainder of the genome appears
comparable. In a similar fashion, the results of the GWAS of Midwestern American and Dutch
populations suggested moderate genetic differences between the two populations without
genome-wide significant loci.

122
Twin families are major contributors of phenotype and genotype data to collaborative
research initiatives. Twins are often motivated to take part because of information on their
zygosity [46]. The results from work presented here are encouraging for ongoing collaborative
projects, including the genetics of twinning. Collaborative efforts of the Australian, Netherlands,
and other twin registers have contributed to many landmark genetic studies, including the
identification of two genetic variants associated with dizygotic twinning [47]. Participation of
twin cohorts and their families from geographically distinct regions such as Nigeria will
undoubtedly help facilitate the elucidation of additional genetic variants underlying complex
traits, including dizygotic twinning, due to the large regional differences in twinning rates [4850].
4.6 Acknowledgements
We would like to acknowledge and thank the individuals and scientists who participated in the
Genome of the Netherlands project and the Human Genome Diversity Project. We would also
like to extend our gratitude to all of the enrolled participants of the twin registers represented in
this study.
4.7 Financial Support
The Avera Twin Register is supported by Avera Health, Avera McKennan Hospital, and Avera
Institute for Human Genetics. The collaboration between the Netherlands and the Avera Twin
Register arose through NIMH Grant: 1RC2MH089995-01: Genomics of Developmental
Trajectories in Twins.
4.8 Conflict of Interest
The authors declare no conflict of interest.

123
4.9 Ethical Standards
All participants provided informed consent. This study was conducted under Institutional Review
Board approval at all study sites. Netherlands Twin Register (Dutch cohort): The study was
approved by the Central Ethics Committee on Research Involving Human Subjects of the VU
University Medical Centre, Amsterdam, an Institutional Review Board certified by the U.S.
Office of Human Research Protections (IRB number IRB00002991 under Federal-wide
Assurance- FWA00017598; IRB/institute codes, NTR 03-180). Avera Twin Register
(Midwestern American cohort): The study was approved by the Avera Institutional Review Board
and the Avera Department of Human Subject’s protection. Australia: The project was approved
by the Queensland Institute of Medical Research Human Research Ethics Committee.
4.10 References
1. Evangelou, E., et al., Genetic analysis of over 1 million people identifies 535 new loci
associated with blood pressure traits. Nat Genet, 2018. 50(10): p. 1412-1425.
2. Wray, N.R., et al., Genome-wide association analyses identify 44 risk variants and refine
the genetic architecture of major depression. Nat Genet, 2018. 50(5): p. 668-681.
3. Visscher, P.M., et al., Five years of GWAS discovery. Am J Hum Genet, 2012. 90(1): p. 7-
24.
4. Visscher, P.M., et al., 10 Years of GWAS Discovery: Biology, Function, and Translation.
Am J Hum Genet, 2017. 101(1): p. 5-22.
5. Tam, V., et al., Benefits and limitations of genome-wide association studies. Nat Rev
Genet, 2019.
6. Silventoinen, K., et al., Genetic and environmental effects on body mass index from
infancy to the onset of adulthood: an individual-based pooled analysis of 45 twin cohorts
participating in the COllaborative project of Development of Anthropometrical measures
in Twins (CODATwins) study. Am J Clin Nutr, 2016. 104(2): p. 371-9.
7. Silventoinen, K., et al., The CODATwins Project: The Cohort Description of
Collaborative Project of Development of Anthropometrical Measures in Twins to Study
Macro-Environmental Variation in Genetic and Environmental Effects on Anthropometric
Traits. Twin Res Hum Genet, 2015. 18(4): p. 348-60.
8. Sullivan, P.F., et al., Empirical evaluation of the genetic similarity of samples from twin
registries in Australia and the Netherlands using 359 STRP markers. Twin Res Hum
Genet, 2006. 9(4): p. 600-2.
9. Boomsma, D.I., et al., Netherlands Twin Register: a focus on longitudinal research. Twin
Res, 2002. 5(5): p. 401-6.

124
10. Boomsma, D.I., et al., Netherlands Twin Register: from twins to twin families. Twin Res
Hum Genet, 2006. 9(6): p. 849-57.
11. Willemsen, G., et al., The Netherlands Twin Register biobank: a resource for genetic
epidemiological studies. Twin Res Hum Genet, 2010. 13(3): p. 231-45.
12. Willemsen, G., et al., The Adult Netherlands Twin Register: twenty-five years of survey
and biological data collection. Twin Res Hum Genet, 2013. 16(1): p. 271-81.
13. Kittelsrud, J., et al., Establishment of the Avera Twin Register in the Midwest USA. Twin
Res Hum Genet, 2017. 20(5): p. 414-418.
14. Ehli, E.A., et al., A method to customize population-specific arrays for genome-wide
association testing. Eur J Hum Genet, 2017. 25(2): p. 267-270.
15. Boomsma, D.I., et al., The Genome of the Netherlands: design, and project goals. Eur J
Hum Genet, 2014. 22(2): p. 221-7.
16. Genome of the Netherlands, C., Whole-genome sequence variation, population structure
and demographic history of the Dutch population. Nat Genet, 2014. 46(8): p. 818-25.
17. Cann, H.M., et al., A human genome diversity cell line panel. Science, 2002. 296(5566):
p. 261-2.
18. Hopper, J.L., et al., Australian Twin Registry: a nationally funded resource for medical
and scientific research, incorporating match and WATCH. Twin Res Hum Genet, 2006.
9(6): p. 707-11.
19. Hopper, J.L., The Australian Twin Registry. Twin Res, 2002. 5(5): p. 329-36.
20. Hur, Y.M., et al., The Nigerian Twin and Sibling Registry. Twin Res Hum Genet, 2013.
16(1): p. 282-4.
21. Painter, J.N., et al., A genome wide linkage scan for dizygotic twinning in 525 families of
mothers of dizygotic twins. Hum Reprod, 2010. 25(6): p. 1569-80.
22. Min, J.L., et al., High microsatellite and SNP genotyping success rates established in a
large number of genomic DNA samples extracted from mouth swabs and genotypes. Twin
Res Hum Genet, 2006. 9(4): p. 501-6.
23. Genomes Project, C., et al., A global reference for human genetic variation. Nature, 2015.
526(7571): p. 68-74.
24. Delaneau, O., J. Marchini, and J.F. Zagury, A linear complexity phasing method for
thousands of genomes. Nat Methods, 2011. 9(2): p. 179-81.
25. Howie, B.N., P. Donnelly, and J. Marchini, A flexible and accurate genotype imputation
method for the next generation of genome-wide association studies. PLoS Genet, 2009.
5(6): p. e1000529.
26. Chang, C.C., et al., Second-generation PLINK: rising to the challenge of larger and
richer datasets. Gigascience, 2015. 4: p. 7.
27. Purcell, S., et al., PLINK: a tool set for whole-genome association and population-based
linkage analyses. Am J Hum Genet, 2007. 81(3): p. 559-75.
28. Manichaikul, A., et al., Population structure of Hispanics in the United States: the
multiethnic study of atherosclerosis. PLoS Genet, 2012. 8(4): p. e1002640.
29. Price, A.L., et al., Principal components analysis corrects for stratification in
genomewide association studies. Nat Genet, 2006. 38(8): p. 904-9.
30. Abdellaoui, A., et al., Population structure, migration, and diversifying selection in the
Netherlands. European journal of human genetics : EJHG, 2013. 21(11): p. 1277-85.
31. Price, A.L., et al., Long-range LD can confound genome scans in admixed populations.
Am J Hum Genet, 2008. 83(1): p. 132-5; author reply 135-9.

125
32. Rosenberg, N.A., Standardized subsets of the HGDP-CEPH Human Genome Diversity
Cell Line Panel, accounting for atypical and duplicated samples and pairs of close
relatives. Ann Hum Genet, 2006. 70(Pt 6): p. 841-7.
33. Kent, W.J., et al., The human genome browser at UCSC. Genome Res, 2002. 12(6): p.
996-1006.
34. Haeussler, M., et al., The UCSC Genome Browser database: 2019 update. Nucleic Acids
Res, 2019. 47(D1): p. D853-D858.
35. R Core Team, R: A Language and Environment for Statistical Computing. 2018.
36. Weir, B.S. and C.C. Cockerham, Estimating F-Statistics for the Analysis of Population
Structure. Evolution, 1984. 38(6): p. 1358-1370.
37. Hudson, R.R., M. Slatkin, and W.P. Maddison, Estimation of levels of gene flow from
DNA sequence data. Genetics, 1992. 132(2): p. 583-9.
38. Skoglund, P., et al., Genetic evidence for two founding populations of the Americas.
Nature, 2015. 525(7567): p. 104-8.
39. Miles, A., Harding, N., scikit-allel - Explore and analyze genetic variation. 1.2.0 edn.
Github, 2018.
40. Bhatia, G., et al., Estimating and interpreting FST: the impact of rare variants. Genome
Res, 2013. 23(9): p. 1514-21.
41. Weir, B.S. and W.G. Hill, Estimating F-statistics. Annu Rev Genet, 2002. 36: p. 721-50.
42. International HapMap, C., et al., Integrating common and rare genetic variation in
diverse human populations. Nature, 2010. 467(7311): p. 52-8.
43. Zheng, H.F., et al., Performance of genotype imputation for low frequency and rare
variants from the 1000 genomes. PLoS One, 2015. 10(1): p. e0116487.
44. Data Access and Dissemination Systems. U.S. Census Bureau, 2013-2017 American
Community Survey 5-Year Estimates. 2017 [cited 2019; Available from:
https://factfinder.census.gov/faces/tableservices/jsf/pages/productview.xhtml?pid=ACS_
13_5YR_B04006&prodType=table.
45. Stankovich, J., et al., On the utility of data from the International HapMap Project for
Australian association studies. Hum Genet, 2006. 119(1-2): p. 220-2.
46. Odintsova, V.V., et al., Establishing a Twin Register: An Invaluable Resource for
(Behavior) Genetic, Epidemiological, Biomarker, and 'Omics' Studies. Twin Res Hum
Genet, 2018. 21(3): p. 239-252.
47. Mbarek, H., et al., Identification of Common Genetic Variants Influencing Spontaneous
Dizygotic Twinning and Female Fertility. Am J Hum Genet, 2016. 98(5): p. 898-908.
48. Hall, J.G., Twinning. Lancet, 2003. 362(9385): p. 735-43.
49. Hoekstra, C., et al., Dizygotic twinning. Hum Reprod Update, 2008. 14(1): p. 37-47.
50. Smits, J. and C. Monden, Twinning across the Developing World. PLoS One, 2011. 6(9):
p. e25239.
126
4.11 Supplementary Materials
Supplementary Table 4.1 – Population codes and sampling information for HGDP and study
populations
PopulationCode PopulationName SamplingLocation GeographicRegionOfPopulation
3 MidwestAmerican MidwestAmerica MIDWESTAMERICA
4 NTR Netherlands NETHERLANDS
5 Australian Australia AUSTRALIA
6 Nigerian Nigeria NIGERIA
20 Orcadian OrkneyIslands EUROPE
21 Adygei Russia-Caucasus EUROPE
22 Russian Russia EUROPE
24 Basque France EUROPE
25 French France EUROPE
27 Italian Italy-Bergamo EUROPE
28 Sardinian Italy EUROPE
29 Tuscan Italy EUROPE
34 Mozabite Algeria-Mzab MIDDLE_EAST
36 Bedouin Israel-Negev MIDDLE_EAST
37 Druze Israel-Carmel MIDDLE_EAST
38 Palestinian Israel-Central MIDDLE_EAST
50 Balochi Pakistan CENTRAL_SOUTH_ASIA
51 Brahui Pakistan CENTRAL_SOUTH_ASIA
52 Burusho Pakistan CENTRAL_SOUTH_ASIA
54 Hazara Pakistan CENTRAL_SOUTH_ASIA
56 Kalash Pakistan CENTRAL_SOUTH_ASIA
57 Makrani Pakistan CENTRAL_SOUTH_ASIA
58 Pathan Pakistan CENTRAL_SOUTH_ASIA
59 Sindhi Pakistan CENTRAL_SOUTH_ASIA
71 Melanesian Bougainville OCEANIA
75 Papuan NewGuinea OCEANIA
81 Colombian Colombia AMERICA
82 Karitiana Brazil AMERICA
83 Surui Brazil AMERICA
86 Maya Mexico AMERICA
87 Pima Mexico AMERICA
430 BantuSouthAfrica Angola AFRICA
430 BantuSouthAfrica BotswanaOrNamibia AFRICA
430 BantuSouthAfrica Lesotho AFRICA
430 BantuSouthAfrica SouthAfrica AFRICA
441 BantuKenya Kenya AFRICA
127
457 Nilote Sudan AFRICA
464 Mandenka Senegal AFRICA
465 Yoruba Nigeria AFRICA
488 BiakaPygmy CentralAfricanRepublic AFRICA
489 MbutiPygmy Congo AFRICA
494 San Namibia AFRICA
601 Han China EAST_ASIA
602 Han-NChina China EAST_ASIA
606 Dai China EAST_ASIA
607 Daur China EAST_ASIA
608 Hezhen China EAST_ASIA
611 Lahu China EAST_ASIA
612 Miao China EAST_ASIA
613 Oroqen China EAST_ASIA
615 She China EAST_ASIA
616 Tujia China EAST_ASIA
617 Tu China EAST_ASIA
618 Xibo China EAST_ASIA
619 Yi China EAST_ASIA
622 Mongola China EAST_ASIA
625 Naxi China EAST_ASIA
629 Uygur China CENTRAL_SOUTH_ASIA
677 Cambodian Cambodia EAST_ASIA
684 Japanese Japan EAST_ASIA 699 Yakut Siberia EAST_ASIA
Supplementary Table 4.2 – Statistical significance of differences between populations For
each pair of populations, the ANOVA statistics are summed across eigenvectors. The result is
approximately chisq with degrees of freedom equal to the number of eigenvectors.
pop1 pop2 chisq p-value
3
4
749.816
1.26E-154
3
6
6156.44
0
5
3
429.224
5.62E-86
5
4
8857.501
0
5
6
22000.876
0
6
4
67639.754
0
20
3
63.894
6.59E-10
20
4
173.691
4.77E-32
20
5
20.734
0.0230255
20
6
1547.751
0
21
3
1852.742
0
21
4
6332.92
0

128
21
5
3420.913
0
21
6
2075.942
0
22
3
1460.048
1.07E-307
22
4
3904.679
0
22
5
2256.011
0
22
6
2150.141
0
24
3
1254.616
2.38E-263
24
4
2703.947
0
24
5
1662.729
0
24
6
2225.43
0
25
3
463.033
3.46E-93
25
4
1022.616
2.51E-213
25
5
438.795
5.12E-88
25
6
2132.711
0
27
3
876.529
7.16E-182
27
4
1597.523
0
27
5
1095.659
4.55E-229
27
6
1645.343
0
28
3
2907.991
0
28
4
9829.624
0
28
5
5965.776
0
28
6
2745.004
0
29
3
822.826
2.55E-170

0
0
129
29
4
1440.327
1.95E-303
29
5
983.13
8.05E-205
29
6
1455.056
1.28E-306
34
3
4139.525
0
34
4
36146.567
0
34
5
14510.285
0
34
6
2149.688
0
36
3
4010.109
0
36
4
33415.963
0
36
5
14381.805
0
36
6
2129.977
0
37
3
4597.353
0
37
4
20079.444
0
37
5
10717.317
0
37
6
2979.874
0
38
3
4779.207
0
38
4
24397.496
0
38
5
12236.738
0
38
6
2860.238
0
50
3
3860.641
0
50
4
22453.506
0
50
5
10992.391
0
50
6
2305.417
0
51
3
3975.99
0
51
4
23144.328
0
51
5
11360.598
0
51
6
2426.446
0
52
3
4479.567
0
52
4
26946.201
0
52
5
12402.601
0
52
6
2344.274
0
54
3
3076.783
0

0
0
0
0
0
0
130
54
4
25022.76
0
54
5
9306.791
0
54
6
1954.409
0
56
3
5192.329
0
56
4
31342.826
0
56
5
14830.511
56
6
2486.114
57 3 3335.635
57 4 20108.585 57 5 9648.131
57 6 2109.805
58 3 3950.296 0
58 4 20866.105 0
58 5 10379.845 0
58 6 2219.71 0
59 3 4167.409 0
59 4 24455.961 0
59 5 11762.972 0
59 6 2249.503 0
71 3 5364.411 0
71 4 44101.355 0
71 5 16727.68 0
71 6 2239.247 0
75 3 6307.217 0
75 4 68348.873 0
75 5 22851.259 0
75 6 2411.932 0
81 3 4503.517 0
81 4 38298.986 0
81 5 14528.519 0

0
0
0
0
0
0
131
81 6 1764.309 0
82 3 4622.311 0
82 4 36008.124 0
82 5 14049.373 0
82 6 1813.536 0
83 3 3780.704 0
83 4 24068.937 0
83 5 10410.769 0
83 6 1466.692 0.00E+00
86 3 5221.223 0
86 4 59233.304 0
86 5 19676.868 0
86 6 2246.835 0
87 3 5026.309 0
87 4 44523.395
87 5 16322.743
87
6
1972.15
430
3
2964.017
430
4
33881.662
430
5
10520.31
430
6
302.222
5.27E-59
441
3
2899.047
0
441
4
33603.643
0
441
5
10584.149
0
441
6
335.485
4.78E-66
464
3
4456.269
0
464
4
46124.527
0

0
0
0
0
0
0
132
464
5
15217.264
0
464
6
73.328
1.01E-11
465
3
4810.955
0
465
4
49644.327
0
465
5
16405.907
0
465
6
22.846
0.0113302
488
3
5880.655
0
488
4
58992.567
0
488
5
20445.876
0
488
6
1311.773
1.10E-275
489
3
5613.946
0
489
4
54929.362
0
489
5
19602.729
0
489
6
1298.928
6.52E-273
494
3
4513.962
0
494
4
37823.504
0
494
5
14633.924
0
494
6
1037.472
1.58E-216
601
3
5536.788
0
601
4
56925.041
0
601
5
19025.951
0
601
6
2317.258
0
602
3
3685.594
0
602
4
33528.694
0
602
5
11589.288
0
602
6
1388.798
2.60E-292
606
3
4229.327
606
4
37671.301

0
0
0
0
0
133
606
5
13638.214
606
6
1701.07
607
3
3925.066
607
4
32743.208
607
5
11813.288
0
607
6
1561.917
0
608
3
3448.338
0
608
4
29294.408
0
608
5
10473.989
0
608
6
1264.536
1.72E-265
611
3
3504.831
0
611
4
28452.012
0
611
5
10623.786
0
611
6
1354.066
8.19E-285
612
3
4160.859
0
612
4
36172.518
0
612
5
13036.093
0
612
6
1560.632
0
613
3
3785.704
0
613
4
34250.576
0
613
5
12199.557
0
613
6
1447.572
5.30E-305
615
3
4078.076
0
615
4
34889.792
0
615
5
12620.541
0
615
6
1486.517
2.05866e-313
616
3
4036.471
0

134
616
4
35419.931
0
616
5
12586.382
0
616
6
1491.838
1.46004e-314
617
3
3288.939
0
617
4
31307.943
0
617
5
10636.539
0
617
6
1243.201
6.90E-261
618
3
3232.679
0
618
4
30324.36
0
618
5
10469.472
0
618
6
1330.962
7.95E-280
619
3
3582.878
619
4
33312.243
619
5
11452.352
619
6
1337.158
3.65E-281
622
3
3293.957
0
622
4
31949.858
0
622
5
10962.64
0
622
6
1311.818
1.08E-275
625
3
3257.196
0
625
4
28526.449
0
625
5
10033.39
0
625
6
1184.153
3.77E-248
629
3
2447.635
0
629
4
19025.266
0
629
5
7116.367
0
629
6
1571.626
0
677
3
3738.917
0
677
4
33689.003
0
677
5
12256.31
0
677
6
1595.084
0
684
3
4778.618
0
684
4
48812.379
0
684
5
15973.221
0
684
6
1998.414
0
699
3
4371.196
0

0
0
135
699
4
51285.367
0
699
5
16835.329
0
699
6
2275.401
0
CHAPTER 5 – GENETIC META-ANALYSIS OF TWIN BIRTH WEIGHT SHOWS
HIGH GENETIC CORRELATION WITH SINGLETON BIRTH WEIGHT
Published as:
Beck, J.J., Pool, R., van de Weijer, M., Chen, X., Krapohl, E., Gordon, S.D., Nygaard, M.,
Debrabant, B., Palviainen, T., van der Zee, M.D., Baselmans, B., Finnicum, C.T., Yi, L.,
Lundström, S., van Beijsterveldt, T., Christiansen, L., Heikkilä, K., Loukola, A., Ollikainen, M.,
Christensen, K., Martin, N.G., Plomin, R., Nivard, M., Bartels, M., Dolan, C., Willemsen, G.,
de
Geus, E., Almqvist, C., Magnuson, P.K.E., Mbarek, H., Ehli, E.A., Boomsma, D.I., Hottenga,
J.J. (2021) Genetic Meta-Analysis of Twin Birth Weight Shows High Genetic Correlation with
Singleton Birth Weight. Human Molecular Genetics, 30, 1894-1905.

136
5.1 Abstract
Birth weight (BW) is an important predictor of newborn survival and health and has
associations with many adult health outcomes, including cardiometabolic disorders, autoimmune
diseases, and mental health. On average, twins have a lower BW than singletons as a result of a
different pattern of fetal growth and shorter gestational duration. Therefore, investigations into
the genetics of BW often exclude data from twins, leading to a reduction in sample size and
remaining ambiguities concerning the genetic contribution to BW in twins. In this study, we
carried out a genome-wide association meta-analysis of BW in 42212 twin individuals and
found a positive correlation of beta values (Pearson’s r = 0.66, 95% confidence interval [CI]:
0.47– 0.77) with 150 previously reported genome-wide significant variants for singleton BW.
We identified strong positive genetic correlations between BW in twins and numerous
anthropometric traits, most notably with BW in singletons (genetic correlation [rg] = 0.92, 95%
CI: 0.66–1.18). Genetic correlations of BW in twins with a series of health-related traits closely
resembled those previously observed for BW in singletons. Polygenic scores constructed from a
genome-wide association study on BW in the UK Biobank demonstrated strong predictive
power in a target sample of Dutch twins and singletons. Together, our results indicate that a
similar genetic architecture underlies BW in twins and singletons and that future genome-wide
studies might benefit from including data from large twin registers.
Keywords: birth weight, genome, twins, genetics, genome-wide association study, biobanks

137
5.2 Introduction
Birth weight (BW) is a powerful predictor of infant and newborn survival, with
lowerweight infants being at higher risk of mortality [1-3]. BW is also associated with a wide
array of health-related variables in later life [4], with varying effect sizes, including adult body
mass index (BMI) [5, 6], cardiovascular disease [7, 8], type 2 diabetes [9], hypertension [10-12]
and psychological distress [13]. Our knowledge of the biological pathways underlying BW is
growing with the rapidly increasing number of genetic variants identified in genome-wide
association (GWA) studies. Yet, these investigations mainly focus on BW in singletons and tend
to exclude data from twins in the discovery analysis. Therefore, knowledge about the genetic
overlap between BW in singletons and twins is limited, and it is not clear to what degree
findings in singletons can be generalized to twins and to what extent data from twins can
contribute to gene discovery for BW. This knowledge would be useful as a considerable genetic
overlap would indicate that data from singletons and twins could be combined for attaining
larger sample sizes.
BW is a complex and multifactorial trait [14, 15]. Maternal and fetal genomes conjointly
determine fetal size, making estimations of the heritability of BW challenging as offspring and
maternal genomes are not independent. In twins, BW is different from BW in singleton births
because of their lower gestational age. The main factor explaining lower gestational age is
uterine overdistension [16]. Still, twin and family studies suggest similar heritability estimates
for BW, ranging from 10% to 40% [17-20], indicating a moderate contribution of genetic factors
to BW variation. Of interest for our quest is a study from the Netherlands in which heritability
was estimated from data on parents and their singleton offspring and from data on mono- and

138
dizygotic twins [19]. The heritability estimates for BW and height were all around 0.3 and
highly comparable in both groups.
The number of genetic variants identified for BW is growing based on findings from
GWA studies (GWAS). In a 2010 study by Freathy et al. [21], two variants, in ADCY5 and near
CCNL1, were found to influence variation in BW in singletons. The number of associated
variants increased to seven in 2013 with an expanded meta-analysis study of over 69000
European individuals [22]. In a multi-ancestry GWA meta-analysis (GWAMA) by Horikoshi and
colleagues [23], BW and genotype data were collected for 153781 singletons. The result of this
effort was the identification of 59 independent signals, capturing approximately 15% of the
variance in BW. Beaumont and colleagues [24] also examined the contribution of fetal versus
maternal genetic effects and identified ten maternal loci influencing offspring birthweight.
Additional GWA efforts have been undertaken to ascertain the maternal and fetal genetic effects
on BW and their relation to cardiometabolic risk, in which 190 independent associations were
discovered [25]. To date, only one GWA study has been performed on BW in twins (4593 female
twins from the UK), which identified one variant on chromosome 9, close to the NTRK2 gene
[26].
The Developmental Origins of Health and Disease (DOHaD) hypothesis is based on
observations that adverse influences early in development, particularly in the intrauterine
environment, result in permanent physiological and metabolomic changes leading to increased
risk of disease in adulthood [27-29]. One hypothesis, postulated by Barker in the 1990s,
proposed that intrauterine growth restriction, low BW, and premature birth have a causal
relationship to hypertension, coronary heart disease, and non-insulin-dependent diabetes in later
life. Barker and colleagues traced infant mortality rates in England during the early 1900s and

139
found strong geographical relations between infant death and high rates of mortality resulting
from coronary heart disease years later [27]. They postulated that the geographic associations of
infant mortality and adult death rates ‘reflects variations in nutrition in early life, which are
expressed pathologically on exposure to later dietary influences’ (p.1081). At the time, the
typical certified cause of death in newborn babies was low BW. Thus, the hypothesis was that
low BW babies surviving infancy suffered from fetal undernutrition, exhibiting
noncommunicable changes in metabolism and physiology, in turn increasing coronary heart
disease risk in adulthood [30]. Low BW can serve as a proxy for a suboptimal intrauterine
environment and is not only associated with cardiovascular disease [31] but also with respiratory
disease [32], various psychiatric disorders [33], as well as mental health, cognitive and
socioeconomic outcomes [34].
In general, the DOHaD and the Barker hypotheses are environmentally based. That is,
the existence of an adverse intrauterine environment leads to decreased BW and long-term
cardiometabolic sequelae in offspring. Alternatively, strong genetic correlations between low
singleton BW and indicators of metabolic and cardiovascular health, as described in the
metaanalysis by Horikoshi and colleagues [23], correspond more closely to the Fetal Insulin
Hypothesis [35]. In this context, the correlations between BW and cardiometabolic disorders are
driven by the transmission of maternal genes to the offspring. However, genetic correlations
between BW and the cardiometabolic traits could be driven through the fetal and/or the maternal
genome. The latter is broadly consistent with the DOHaD/Barker hypothesis since the maternal
genome defines the intrauterine environment, whereas the former more likely reflects
mechanisms of the Fetal Insulin Hypothesis [36]. Recent studies have investigated these

140
differences in hopes of disentangling the relative contributions of fetal and maternal effects on
BW and later life cardiometabolic disease [25, 37].
On average, twins have lower BW than singletons since twin pregnancy is characterized
by a shorter gestational duration [16] and because fetal growth slows down after approximately
32 weeks of gestation [38-41]. Therefore, investigations into the genetic architecture of BW and
other birth-related characteristics often exclude twins, even though this may lead to a significant
decrease in sample size. Concerning the DOHaD hypothesis, there is no evidence that the
relation between BW and later-life disease differs between twins and singletons as demonstrated
for blood pressure or anti-hypertensive drug use [42-44] and diabetes [45, 46].
This study aimed to search for common genetic variants underlying BW in twins by
carrying out a meta-analysis of genetic association studies in twins and comparing the results to
those for BW in singletons. To this end, four approaches were employed: 1) A meta-analysis of
combined GWA results from five European twin cohorts, UK Biobank, one Australian twin
cohort, and one twin cohort from the Midwestern region of the United States of America. 2) An
assessment of the genetic correlations between BW in twins and BW in singletons. 3) The
evaluation of the genetic correlations between BW in twins and a range of traits and diseases in
later life, including anthropometric and neuropsychiatric characteristics. 4) An assessment of the
predictive performance of BW polygenic scores in twins and singletons.
5.3 Results

141
5.3.1 Meta-Analysis
We carried out a GWAMA for BW in 42212 twins. The meta-analysis QQ-plot, showing
the expected distribution of genome-wide P-values compared to the observed values across
SNPs, can be found in Supplementary Material, Figure 5.1. The Manhattan plot for the
metaanalysis is shown in Figure 5.1. There were no genome-wide significant SNPs at the
defined minimum P-value for lead SNPs (P<5x10⁻⁸); however, two lead SNPs had an
association signal of P<5x10⁻⁷. These SNPs were located on chromosome 1 (rs10800682, hg19
position
1:200198946, P=2.92x10⁻⁷) and chromosome 3 (rs3845913, hg19 position 3:123100606,
P=2.93x10⁻⁷). rs10800682 is independent (>12Mb, EUR r2<0.05) of all genome-wide significant
loci found by Horikoshi and colleagues [23]. rs3845913 is an intronic variant of ADCY5 and is
~31kb downstream of rs11719201 (EUR r2 0.154), one of 60 loci previously associated with BW
[23].
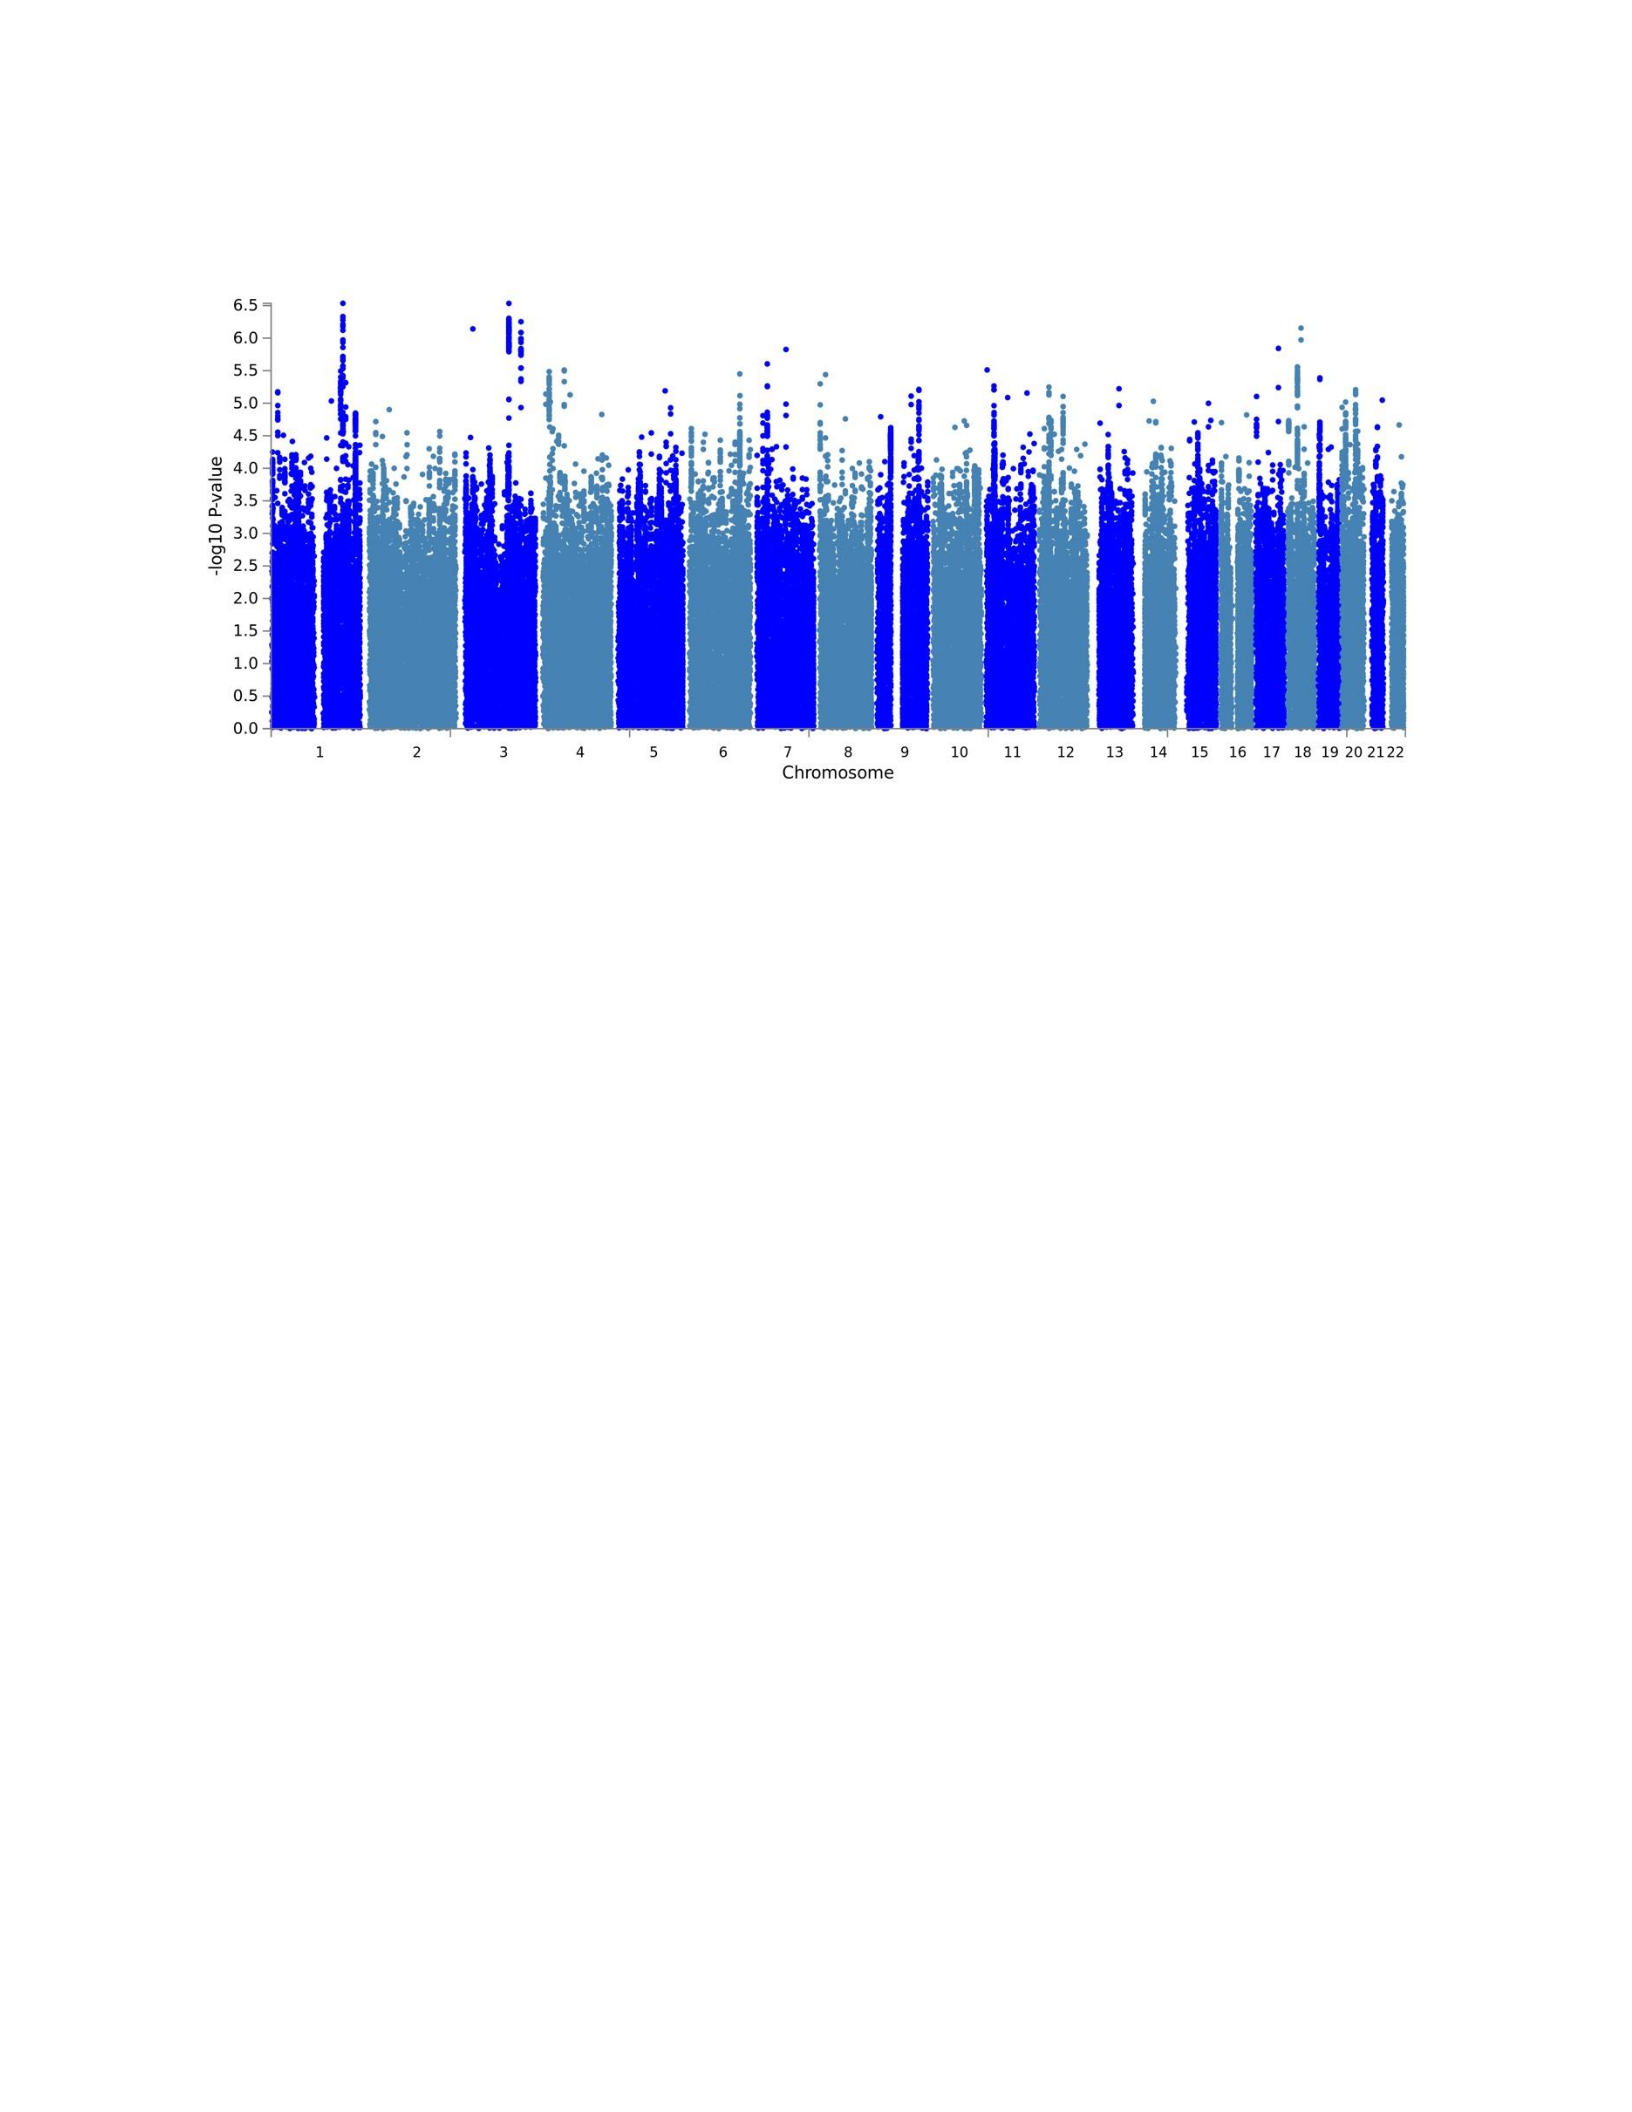
142
Figure 5.1 Manhattan plot from the genome-wide association meta-analysis for BW
The association P-value (on -log10 scale) for each of up to 7,692,335 SNPs (y-axis) is plotted
against the genomic position according to NCBI Build 37 (x-axis). For plotting purposes,
overlapping data points are not drawn for filtered SNPs with a P-value³1x10⁻⁵.

–
143
5.3.2 Replication of Previous Association Results
Though no genome-wide significant SNPs were identified, we evaluated the performance
of SNPs in the current study with the genome-wide significant SNPs signals (P<6.6x10⁻⁹)
recently identified by Warrington et al., 2019 [25] in a GWAS of own BW. Of the significant
SNPs, 150 overlapped with the current study after retention of markers present in greater than
70% of all study participants. As shown in Figure 5.2, following the alignment of effect alleles,
the beta estimates between overlapping markers are highly correlated (Pearson’s r=0.66, 95% CI:
0.47-0.77). Summary statistics of the 150 overlapping variants are presented in Supplementary
Material, Table 5.1. Overall, the positive linear relationship indicates that the previously reported
significant variants behave in a similar fashion between singletons and twins.
Additionally, since gestational age was not available in all cohorts, we assessed
heterogeneity of the overlapping SNPs mentioned above (i.e., 150) using METAL (implemented
as Cochran’s Q-test). No significant heterogeneity in allelic effects was observed after Bonferroni
correction (P>0.00033). The smallest reported P-value of heterogeneity statistics in the current
study was 0.002, which is in line with the smallest reported P-value of the genomewide
significant variants reported in Warrington et al., 2019 of 0.004 (Supplementary Material, Table
5.1).
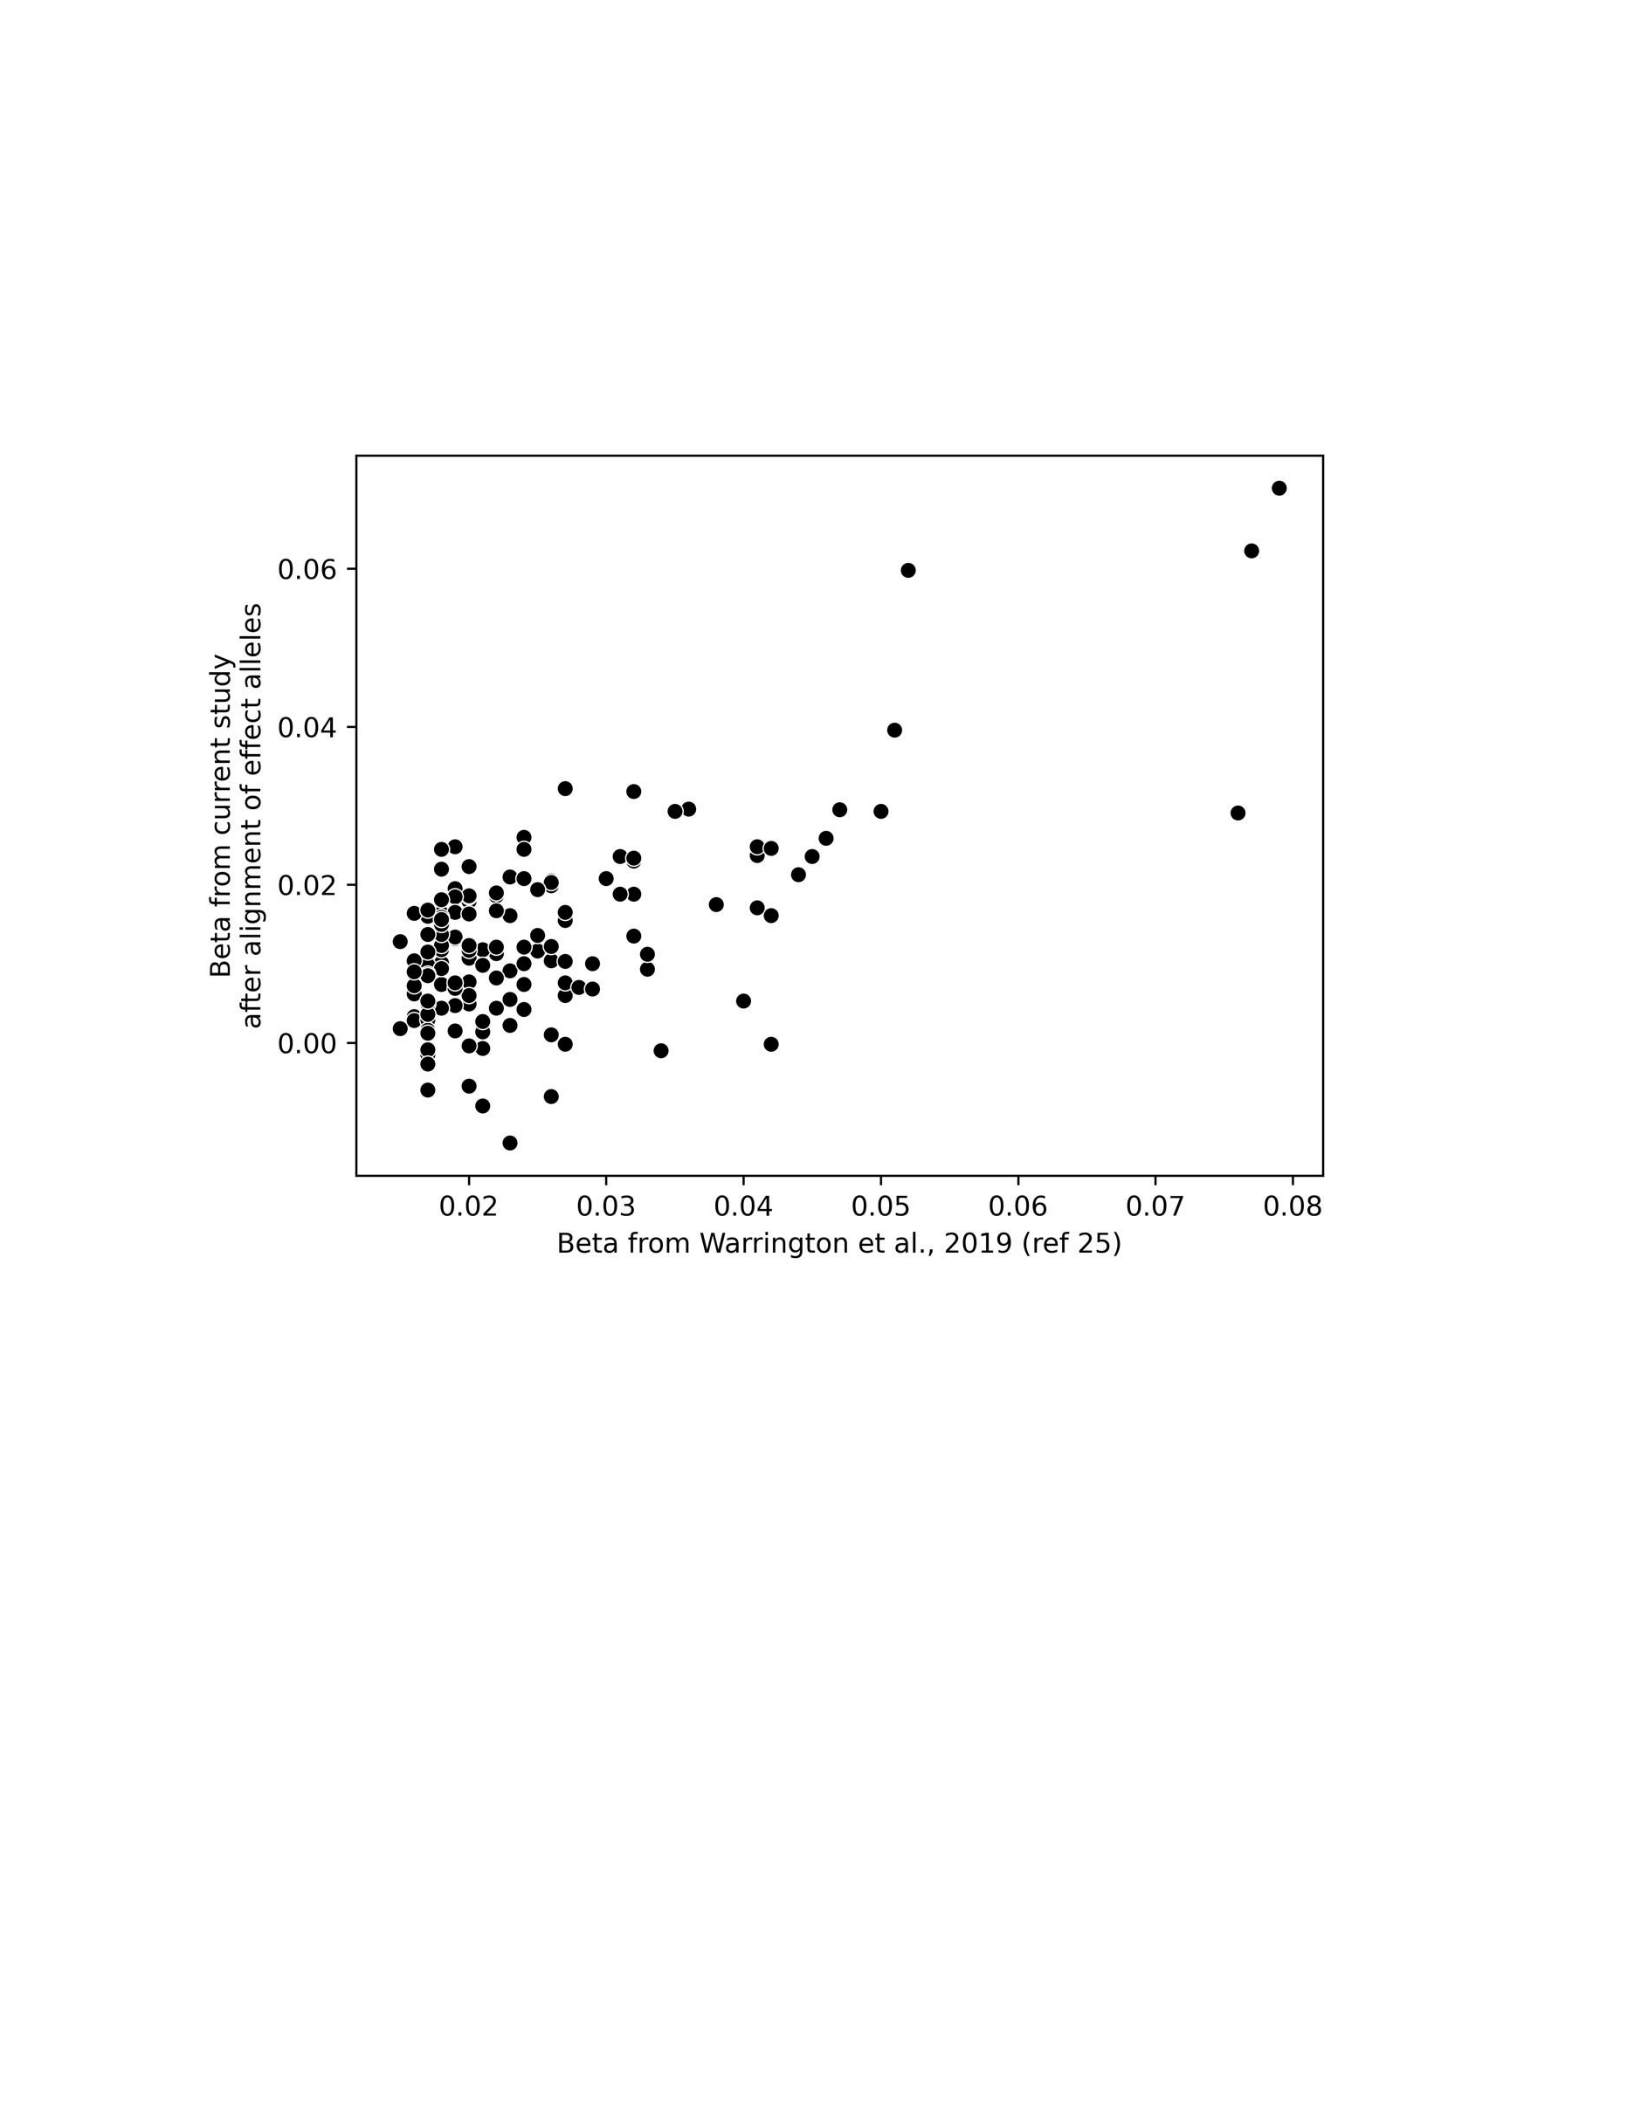
144
Figure 5.2 Scatter plot of the beta estimates from the overlapping SNPs between the
current study and those reported in Warrington et al., 2019 (25) for the GWAS on own BW
(P<6.6x10⁻⁹)
Of the significant SNPs, 150 overlapped with the current study.
5.3.3 Genetic Correlations
The results from the genetic correlation analyses of BW in twins can be found in Figure
5.3 and Supplementary Material, Table 5.2. In general, the strongest genetic correlations were
with anthropometric traits, specifically BW-related phenotypes. Previous studies have
investigated and attempted to partition maternal and fetal genetic effects on BW, allowing for
comparisons to individual and parental effects in this study.

–
145
The strongest genetic correlation was with 'child birth weight' (i.e., the individual’s own
genetic effect on their BW) (genetic correlation [rg]=0.98, 95% confidence interval [CI]:
0.621.33) based on a discovery GWAS of 26836 European individuals [22]. Similarly, robust
positive correlations were found with other phenotypes of the individuals own genetic effect on
their BW, including UK Biobank birth weight (data field 20022) (rg=0.95, 95% CI: 0.71-1.19),
'own birth weight' (rg=0.92, 95% CI: 0.66-1.18) derived from an expanded GWAS of 286870
European individuals [25], and 'birth weight' (rg= 0.91, 95% CI: 0.65-1.17) in 143677 European
individuals [23]. It is important to note that genetic correlations referenced above are from three
studies that are not entirely independent. Sequential studies (in chronological order, references
[22, 23, 25]) used a core set of samples obtained by the Early Growth Genetics Consortium
(EGG), which were expanded upon with new releases of the UK Biobank.
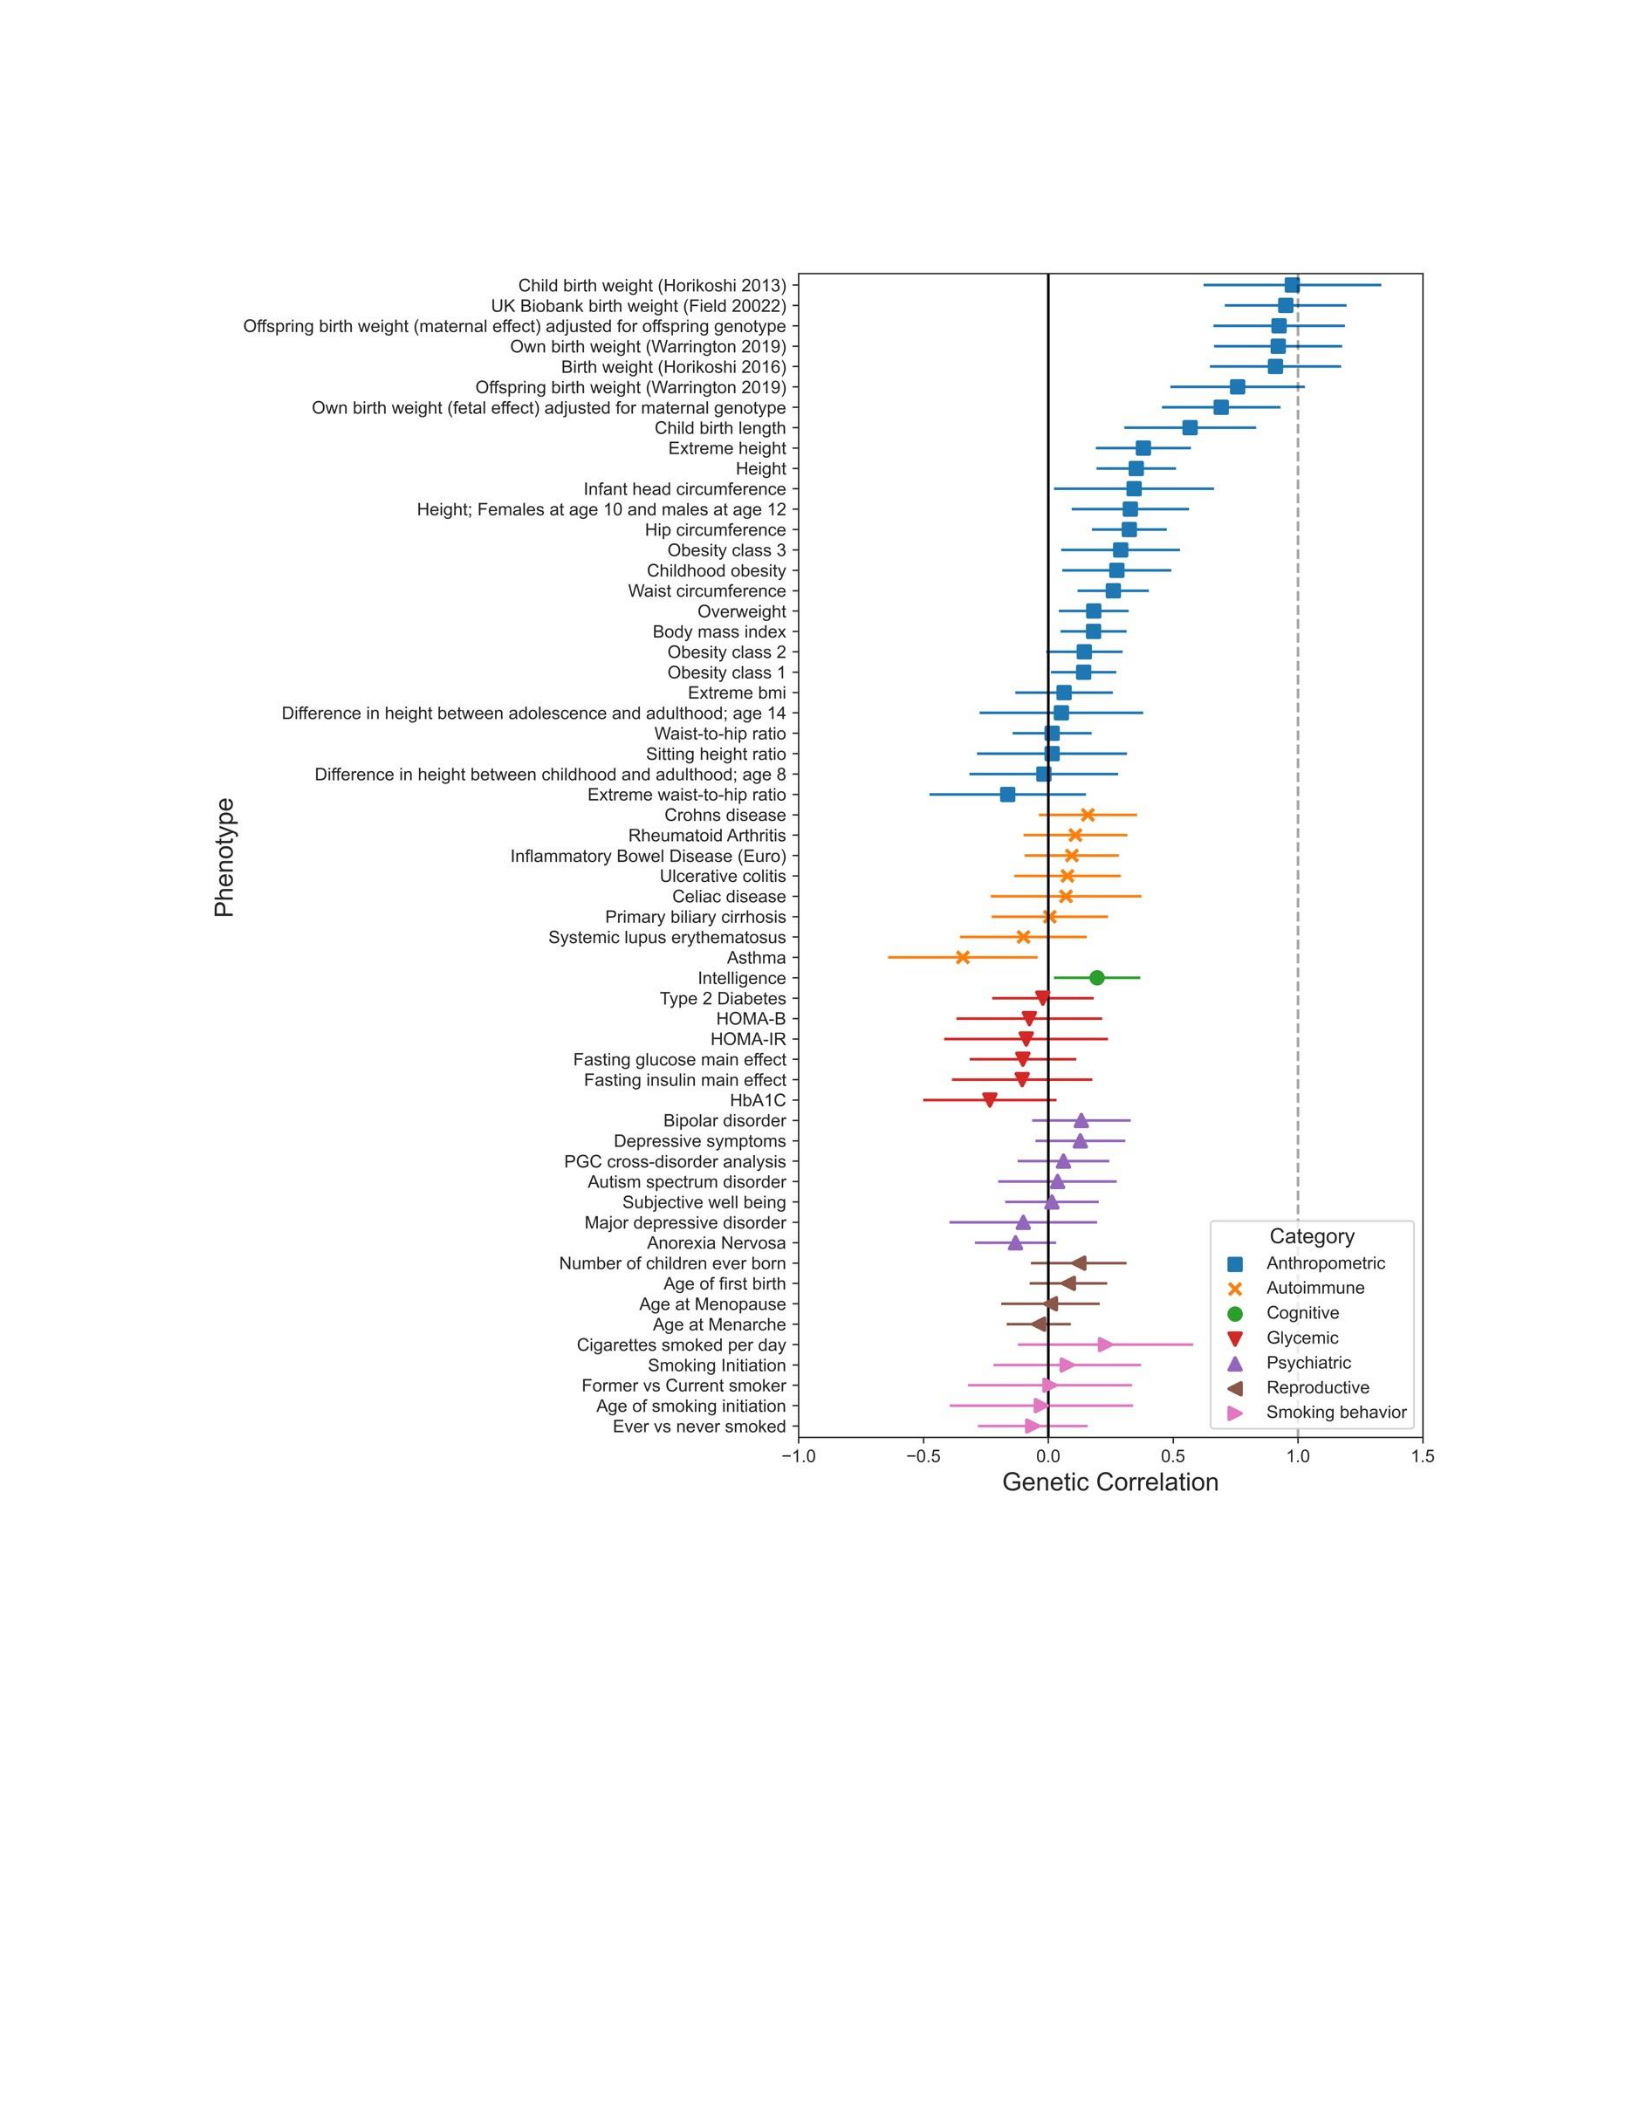
146
Figure 5.3 Genetic relationships between BW in twins and 57 other phenotypes
SNP-based genetic correlations (rg) between BW in twins and a range of other traits and diseases
using LD Score regression. The bars represent 95% confidence intervals. The genetic correlation
estimates are color-coded according to their respective category. HbA1C=hemoglobinA1C,
HOMA-IR=homeostatic model assessment of insulin resistance, HOMA-B=homeostatic model
assessment of beta cell function, PGC=Psychiatric Genetics Consortium, BMI=body mass index.
PubMed reference numbers (PMID) for each trait are listed in Supplementary Material, Table
5.2.

–
147
A positive correlation was also observed with 'offspring birth weight' (i.e., the maternal
genetic effect on offspring BW), as measured in 216611 mothers [25] (rg=0.76, 95% CI: 0.491.03).
Of the genetic correlations with other phenotypes, six additional anthropometric traits exhibited
strong positive genetic correlations, including offspring birth weight (maternal genetic effect on
offspring BW after adjusting for the correlated offspring’s genotype) (rg=0.92, 95% CI: 0.66-1.19),
own birth weight (individuals own genetic effect on their own BW after adjusting for the correlated
maternal genotype) (rg=0.69, 95% CI: 0.45-0.93), child birth length (rg=0.57, 95% CI: 0.30-0.83),
extreme height (rg=0.38, 95% CI: 0.19-0.57), height (rg=0.35, 95% CI: 0.19-0.51), and hip
circumference (rg=0.32, 95% CI: 0.17-0.47).
Glycemic traits were all negatively associated with BW, whereas cognitive characteristics,
measured by intelligence, correlated positively (rg=0.20, 95% CI: 0.02-0.37). Genetic correlations
of BW in twins with autoimmune disorders, psychiatric disorders, reproductive traits, and smoking
behavior yielded mixed results.
The SNP heritability (h2) was calculated using LD Score regression. The h2 was estimated
to be 0.0407 for BW in twins. For BW in singletons, the heritability estimates from three studies
were h2=0.1139, h2=0.0985, and h2=0.1016 for ‘child birth weight’ [22], ‘own birth weight’ [25],
and ‘birth weight’ [23], respectively. The heritability estimate of UK Biobank birth weight was
h2=0.1006.
5.3.4 PolyGenic Score Prediction
The PGS, based on summary statistics from GWA analyses of BW in UK Biobank,
robustly predicted BW in NTR twins and singletons. The PGS, including the fraction of SNPs
with a P-value selection threshold of 0.01, was the best predictor for BW in twins (b=68.19,
148
p=2.10x10-51, PGS R2=0.02) and singletons (b=108.18, p=6.94x10-57, PGS R2=0.03), as shown
in Table 5.1.
As shown in Figure 5.4A, a comb-like distribution of raw BW was observed in
singletons, corresponding to even ~500g increments, reflecting the assessment of BW in this
group.
BW category was also evaluated as the response variable (histograms in Figure 5.4B).
The evaluation was done in all target samples (twins and singletons) by including twin status and
interaction of PGS and twin status as predictors in the model (Table 5.2). As before, the PGS,
including the proportion of SNPs with a P-value selection threshold of 0.01, represented the best
predictor of BW category (b=0.18, p=1.68x10-49, PGS R2=0.02). Together, the results of PGS
prediction analyses suggest that BW PGS constructed from a large representative discovery
population predict BW similarly in a target population of twins and singletons.
Table 5.1 – Results of the PGS prediction in NTR twins and singletons
Twins (N=10487) Singletons (N=6892)
Prop
βPGS
SEPGS
PPGS
PGS R2
βPGS
SEPGS
PPGS
PGS R2
0.001
18.89
4.66
5.04E-05
0.00
34.28
6.87
6.09E-07
0.00
0.003
19.94
4.57
1.26E-05
0.00
38.67
6.72
8.77E-09
0.00
0.005
54.19
4.72
1.86E-30
0.01
75.01
6.75
1.13E-28
0.02
0.01
68.19
4.52
2.10E-51
0.02
108.18
6.81
6.94E-57
0.03
0.05
60.35
4.50
5.39E-41
0.01
101.71
6.88
1.73E-49
0.03
0.1
58.48
4.50
1.26E-38
0.01
99.71
6.88
1.52E-47
0.03
0.2
57.25
4.50
4.46E-37
0.01
98.45
6.89
2.24E-46
0.03
0.3
56.83
4.50
1.43E-36
0.01
98.10
6.89
4.96E-46
0.03
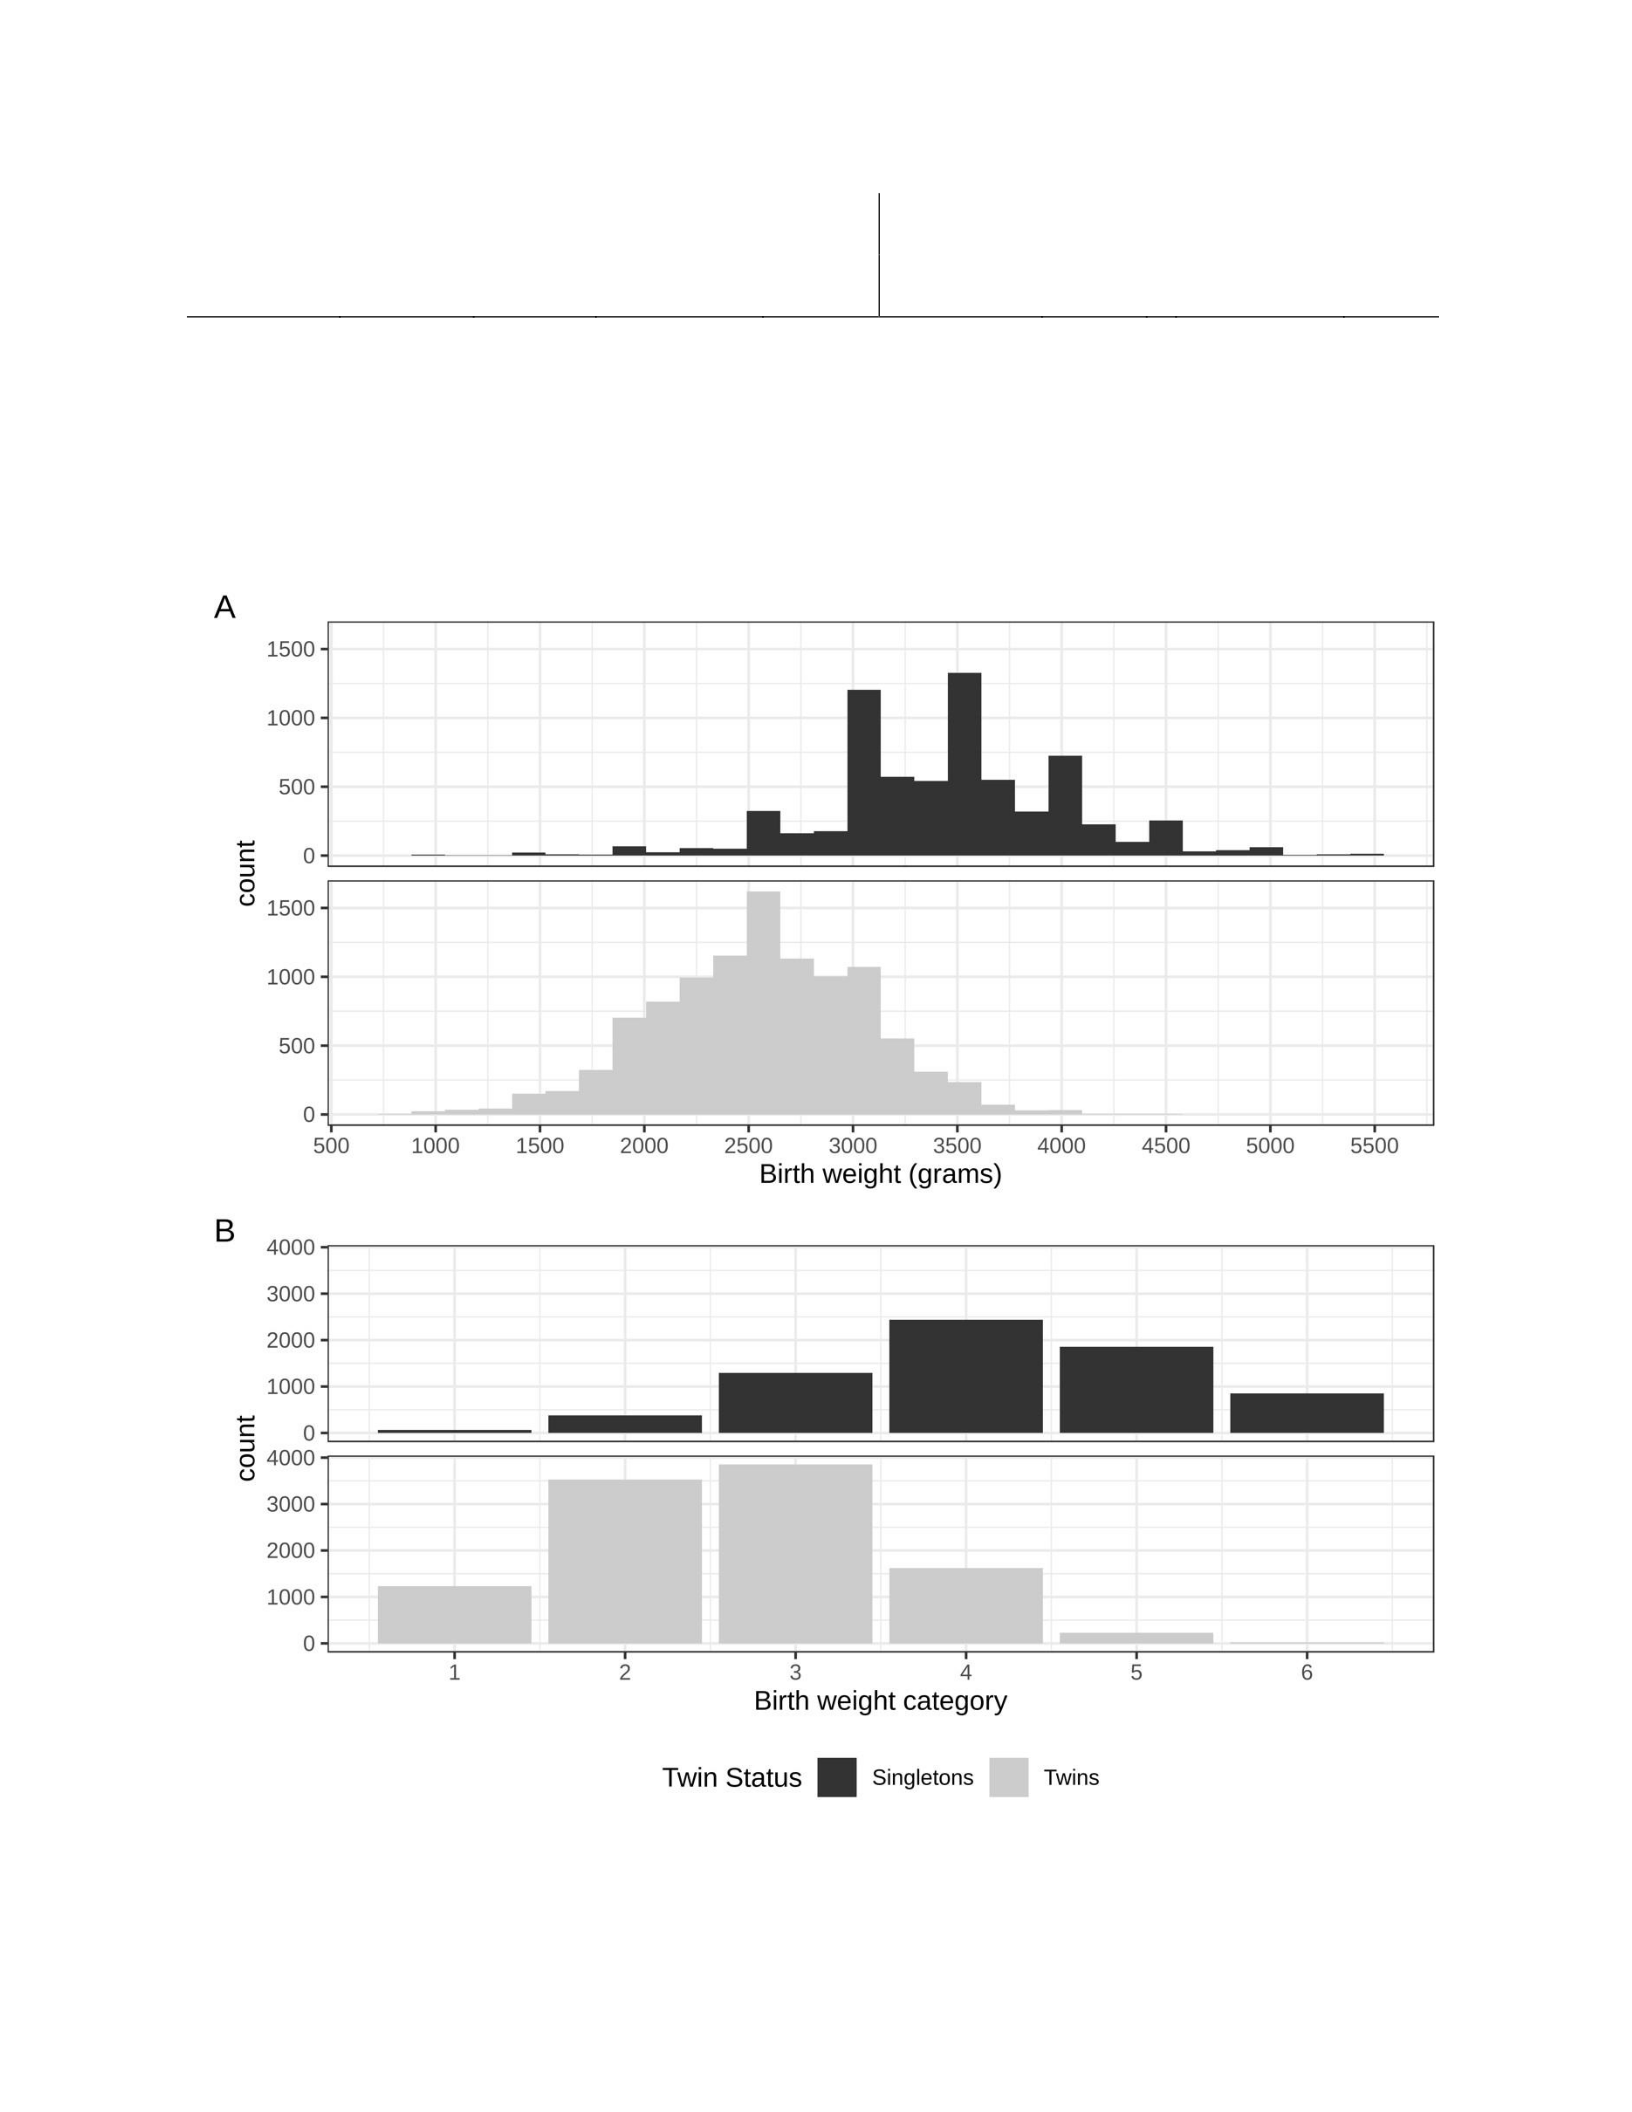
149
0.5
56.53
4.50
3.23E-36
0.01
97.77
6.89
1.01E-45
0.03
INF
55.39
4.53
2.09E-34
0.01
90.48
6.98
1.92E-38
0.02
Note: Prop (proportion) is the P-value threshold for SNP inclusion in the polygenic score (PGS),
β is the regression coefficient for each term with standard error (SE) and P-value (P). PGS R2 is
the phenotypic variance explained by the PGS.
Figure 5.4 – Histograms of raw and categorical BW for NTR twins and singletons

150
Panel A shows histograms for raw BW in grams. Panel B portrays the distributions for BW
categories 1-6 as described in the text. N=10487 twins; 6892 singletons. It is of note to point out
the peaks corresponding to ~500g increments in the singletons in panel A, which simply may
reflect the assessment of BW measures in this group.
151

152
5.4 Discussion
We performed a genome-wide meta-analysis of BW in twins and compared the genetic
architecture of BW between twins and singletons. Our results, particularly the genetic correlation
and PGS analyses, provide compelling evidence for considerable genetic overlap between BW in
twins and singletons.
The genetic correlation between BW in twins and the most recent reported results in
singletons was very strong (rg=0.92, 95% CI: 0.66-1.18), indicating a large overlap in the genetic
variants influencing BW in the two groups. The genetic associations with health-related traits,
when comparing the size and direction from our genetic correlation analyses with the results
from Horikoshi and colleagues [23], showed remarkably similar results. This similarity suggests
that the differential pattern of fetal growth between twins and singletons does not affect the
relation between BW and later-life disease.
We evaluated the predictive performance of PGS derived from a GWAS on BW from a
large representative population from the UK Biobank in a large target sample of NTR twins and
non-twins. The PGS calculated from the proportion of SNPs with a P-value selection threshold of
0.01 demonstrated robust prediction in both singletons (p=6.94x10-57) and twins (p=2.10x1051).
While the proportion of variation explained by the best predicting PGS was small for twins at 2%
and non-twins at 3%, despite moderate heritability estimates, such PGS represents common
genetic architecture underlying BW in twins and singletons even though there are clear
differences in BW between the two groups. Smaller heritability estimates were also observed for
BW in twins, potentially indicating a form of sibling competition. That is if one twin grows and
occupies the growing space of the co-twin, the genes that increase the BW of the larger twin may

153
also limit the growth of the co-twin. Consistent with our results, sibling competition would result
in a dampened effect of the PGS and would be reflected in lower heritability estimates in twins.
The results of the GWAMA did not yield SNPs significantly associated with BW in twins.
Two lead SNPs, rs10800682 and rs3845913, had association signals of P<5x10⁻⁷. rs10800682
was not near (>2Mb away) and was independent (r2<0.05) of all genome-wide significant loci
found by Horikoshi and colleagues [23], making it a potential candidate for future twin studies.
rs3845913 is an intronic variant of ADCY5, which, along with CCNL1, were two of the first
genes to be robustly associated with fetal growth and BW [21]. Additionally, rs3845913 is ~31kb
downstream and is in LD (r2=0.154) with rs11719201 (an intronic variant of ADCY5), one of 60
loci previously associated with BW [23]. To pinpoint exactly how and through which gene(s)
rs10800682 and rs3845913 may exert an effect on BW, additional and functional follow-up
studies are necessary. Previously associated alleles at ADCY5 were found to be BW lowering and
risk increasing for type 2 diabetes, consistent with the fetal insulin hypothesis [35].
The results from this study strongly suggest that BW data from twins and singletons may
be meta-analyzed together in GWAMA, despite the limited sample size of the discovery
GWAMA in twins (N=42212). Another limitation is that we corrected for birth order, gestational
age, and maternal age at birth in a majority of cohorts but could not do so for all cohorts due to
data availability. This information should ideally always be included when BW data are
collected.
Additionally, we report genome-wide estimates of shared genetic effects based on
common genetic variation (SNPs with MAF>0.01 per default settings in LDHub). Suppose the
effects of rare variants are not shared similarly to the effects of common variants for each
phenotype comparison. In that case, the genetic correlation estimates could be misleading.

154
However, in terms of their shared influences on pairs of phenotypes, there is not a theoretical
reason to expect systematic differences in the effects of rare and common variants. Rare variants
with larger effects would not preclude carrying far more numerous common variants with smaller
effects. Thus, the genetic correlations presented in this study may provide reasonable estimates
based on common genetic variation; however, to validate these findings, rare variant studies are
needed. Future studies may also expand upon our genetic correlation estimates by utilizing non-
European populations, greater sample sizes (for discovery and trait-specific phenotypes as they
become available), and increased density across the genome.
Concerning the results of the PGS prediction, we note that the P-value selection threshold
of the most predictive PGS is a function of the effect size distribution, the statistical power of the
discovery GWAMA and the NTR target data, the genetic architecture of BW, as well as the
fraction of associated markers.
Follow-up research may aim to get a better understanding of BW as it is influenced by
direct fetal and indirect maternal genetic influences through the intrauterine environment. The
amount of variance in BW explained by the maternal genotype has been estimated as
substantially smaller than the fetal genetic contribution [47]. Recent work suggests that fetal size
measurements at birth are predominantly determined by the fetal genome, whereas the
gestational duration is primarily dictated by the maternal genome [48]. A better understanding of
the genetic architecture of BW and fetal growth, more generally, will aid in the elucidation of
immediate health outcomes (e.g., preterm birth, fetal growth restriction) and reveal relationships
with later-life health outcomes (e.g., cardiovascular disease, type-2 diabetes).
To conclude, we show that based on genetic correlation and PGS analyses, the genetic
architecture of BW in twins and singletons is similar. Of course, it is known that mean

155
differences in BW between twins and singletons exist; however, the findings of this work
strongly suggest that the genetic causes of variation are the same. Bearing this in mind, the
results of this work indicate that it is appropriate to meta-analyze twins and singletons for genetic
studies of BW. However, careful consideration of analytical strategies will be needed since
details specific to twins may not apply to full-term singletons. Small groups of twins might still
need to be excluded, for example, the highly discordant BW pairs due to the possibility for
twinto-twin transfusion syndrome (TTTS). Also, in full-term singletons, a typical gestational age
cutoff for exclusion (e.g., born before 37 weeks) is often applied, which will not be applicable
with the inclusion of twins due to shorter gestational duration [16] and delayed fetal growth after
32 weeks [38-41]. One approach to address these issues would be to perform separate GWAS on
standardized BW in each group with appropriate exclusion criteria and covariates specific to
twins and non-twins with subsequent meta-analysis of P-values since beta estimates and
intercepts will be affected by raw differences in BW.
5.5 Materials and Methods
5.5.1 Samples
Eight population-based twin registers supplied data: the Netherlands Twin Register
(NTR) [49, 50], Queensland Institute of Medical Research (QIMR – comprised of the
Queensland Twin Registry [51] and the Australian Twin Registry [52, 53]), Danish Twin
Registry (DTR) [54], Finnish Twin Cohort Study (FinnTwin) [55, 56], Twins Early
Development Study (TEDS) [57], Child and Adolescent Twin Study in Sweden (CATSS) [5860],
Avera Twin Register (ATR) [61, 62], and the UK Biobank (UKB) [63]. In UKB, twins were
identified as previously described [64]. A detailed description of cohort sample characteristics

156
can be found in Table 5.3. Information on genotyping and quality control procedures for each
cohort can be found in Supplementary Material, Table 5.3.
5.5.2 Study-Level Analyses
Birth weight (BW) measures were z-score transformed ([BWvalue-BWmean]/BWstandard
deviation) before analysis. Each participating study group performed the association analyses
between each SNP genotype and BW z-scores with the following covariates where available: sex,
gestational age, year of birth, maternal age at birth, birth order, and relevant study-specific
metrics (e.g., principal components (PCs) correcting for genomic ancestry). For all cohorts,
except ATR, birth order was available. The analysis was performed without adjustment for
maternal age at birth and gestational age in the DTR. Association analyses were performed in
PLINK v1.07 [65] with the Generalized Estimation Equation (GEE) package using the Rpackage
plugin to correct for family relatedness or according to local best practices (details provided in
Supplementary Material, Table 5.3). Sample exclusion criteria were phenotypic outliers (BW z-
score greater than or less than five standard deviations from the mean), premature births
(gestational age less than 33 weeks), monozygotic (MZ) twins with TTTS, including twin pairs
with BW more than 35% discordant (a group likely including TTTS twins), triplets and higher-
order multiple births and participants with non-European ancestry.
157

158
5.5.3 Meta-Analysis
Summary statistics from each cohort GWA analysis underwent another round of standard
quality control before meta-analysis. The R-package EasyQC [66] was used to perform quality
control analyses. Insertions and deletions, SNPs with missing or invalid values, markers with
Minor Allele Frequency (MAF)<0.01, and those with poor imputation quality (<0.30) were
excluded. Resulting quality controlled summary statistics from each cohort were meta-analyzed
using the inverse variance-based approach in METAL [67]. Genomic control was applied to
adjust the statistics generated by each cohort [68]. In the meta-analysis, SNPs present in greater
than 70% of all participants were retained.
5.5.4 Association Tests
FUMA (FUnctional Annotation and Mapping v1.3.6) [69] was used to annotate
GWAMA results and identify genomic risk loci. These loci were defined as independent lead
SNPs exhibiting maximum distance between their linkage-disequilibrium (LD) block. For
genome-wide significance in the meta-analysis, a P-value threshold of 5x10⁻⁸ was adopted. The
minimum threshold for defining independent significant SNPs was r2³0.6, which was used to
determine the borders of the genomic risk loci. The minimum threshold for defining lead SNPs,
used for clumping the independent significant SNPs, was r2³0.1. Independent significant SNPs
closer than 250kb were merged into one genomic risk locus. SNPs in LD with the independent
significant SNPs were considered candidate SNPs and defined the borders of the genomic risk
loci. We tested whether the signals from our analyses overlap with previously identified loci for
BW in singletons. In agreement with Horikoshi et al. [23], if a lead SNP mapped >2Mb away
from, and was statistically independent (LD r2<0.05 based on European population reference set)

159
of any of the 60 previously identified loci, it was considered novel. We calculated the r2 between
the signals with the web-based application LDmatrix contained within the LDlink (v3.8) [70]
suite of tools.
5.5.5 Genetic Correlations
To quantify the degree of shared genetic contribution between BW in twins and BW in
singletons and to correlate BW in twins to other individual-level health-related traits and
diseases, we employed LD Hub (v1.9.3) (http://ldsc.broadinstitute.org/ldhub/) [71]. LD Hub is a
centralized database of summary-level GWA study results facilitating the calculation of genetic
correlations [72] between user-supplied summary statistics and a variety of user-selected traits
using LD score regression [73]. HapMap3 SNPs from summary statistics of the GWAS for each
trait and pre-computed LD scores were used in the analyses (available on:
https://github.com/bulik/ldsc). LD score regression requires large sample sizes and utilizes LD
information from an ancestry-matched reference panel; therefore, genetic correlation analyses
were constrained to European GWA study samples. SNPs with a MAF £ 0.01 were excluded.
For the comparisons with previous genome-wide genetic correlation analyses in
singletons (7), we selected the following categories of traits: anthropometric traits, reproductive
traits, glycemic traits, autoimmune disorders, cognitive abilities, psychiatric diseases, and
smoking behavior. In total, we tested for association with 57 traits.
SNP heritability (h2) was calculated in LD Hub with LD score regression to evaluate how
much of the variation in BW could be ascribed to common additive genetic variation.

160
5.5.6 PolyGenic Score Prediction
GWAS results on BW from the UK Biobank (data field 20022)
(http://www.nealelab.is/uk-biobank/) served as the discovery set for calculating polygenic scores
(PGS) in the NTR target dataset. For the PGS prediction of BW in the NTR, participants with
complete BW data and maximum information on covariates (genomic PCs, sex, year of birth,
gestational age, twin status, and genotyping platform) were included. When not available,
gestational age was imputed with the mean gestational age separately for twins (mean=37.38
weeks) and singletons (mean=39.89 weeks). Genotyping platform and ten genomic PCs were
included in the model to account for batch effects (i.e., non-random selection of samples
genotyped on specific arrays) and residual population stratification. The target sample consisted
of 17,379 individuals, comprising 10,487 twins and 6,892 singletons. Summary statistics from
the UK Biobank GWAS on BW were adjusted for the effects of LD with LDpred [74] using the
LD structure of European populations in the 1000 Genomes references set [75]. Recalculated
effect size estimates representing ten thresholds of P-value significance (0.001, 0.003, 0.005,
0.01, 0.05, 0.1, 0.2, 0.3, 0.5, INF (infinitesimal)) were used for allelic scoring in PLINK [65]. We
used the PGS to predict BW in NTR twins and singletons using GEE methods in R [76], taking
into account familial relationships. We also evaluated the predictive performance of the PGS on
categorical BW in the entire target sample of twins and singletons by including twin status and
an interaction term of PGS and twin status in the regression model. Six categories were
constructed, representing the following BW ranges: <2000 grams, 2000-2500 grams, 25013000
grams, 3001-3500 grams, 3501-4000 grams, >4000 grams. Complete regression equations can be
found in the Supplementary Material - Methods. The phenotypic variance explained, captured by
R2, was used to evaluate the predictive performance of each PGS. Our main interest was to
161
determine how well PGS derived from a large discovery population, reflecting general
population numbers of twins, could predict BW in a separate target population of twins and
singletons.
5.6 Data Access
Summary statistics for the GWAMA of BW in twins can be downloaded from the GWAS catalog
website: https://www.ebi.ac.uk/gwas/.
5.7 Acknowledgements
We are extremely grateful to the participants, families, and teams of investigators who
contributed to this work. The research has been conducted using data from UK Biobank, a major
biomedical database, under Application Number 25472. For additional study-specific
acknowledgments, please refer to Supplementary Material, Table 5.4.
5.8 Conflict of Interest Statement
None declared.
5.9 Funding
Wesley W. Parke Research Award Endowment. The Avera Twin Register is supported by Avera
Health, Avera McKennan Hospital, and Avera Institute for Human Genetics. The collaboration
between the Netherlands and the Avera Twin Register arose through NIHM Grant:
1RC2MH089995-01: Genomics of Developmental Trajectories in Twins. CATSS is part of the
Swedish Twin Registry, which is managed by Karolinska Institutet and receives funding through
the Swedish Research Council under the grant no 2017-00641. The DTR data collection is
supported by grants from The National Program for Research Infrastructure 2007 from the
Danish Agency for Science, Technology and Innovation and the US National Institutes of Health

162
(P01 AG08761). Genotyping was supported by NIH R01 AG037985 (Pedersen). Phenotyping
and genotyping of the Finnish twin cohorts was supported by the Academy of Finland Center of
Excellence in Complex Disease Genetics (grants 213506, 129680), the Academy of Finland
(grants 10049, 205585, 118555, 141054, 265240, 263278 and 264146 to J. Kaprio), National
Institute of Alcohol Abuse and Alcoholism (grants AA-12502, AA-00145, and AA-09203 to R. J.
Rose and AA15416 and K02AA018755 to D. M. Dick), and the Wellcome Trust Sanger
Institute, UK. For the NTR, funding was provided by ZonMw (Grant Nos. 904-61-090, 985-
10002, 912-10-020, 904-61-193, 480-04-004, 463-06-001, 451-04-034, 400-05-717, 016-115-
035,
481-08-011 and 056-32-010), Nederlandse Organisatie voor Wetenschappelijk Onderzoek (Grant
Nos. Addiction-31160008, NWO-Middelgroot-911-09-032, OCW_NWO Gravity program
024.001.003, NWO-Groot 480-15-001/674, NWO-56-464-14192), Centre for Medical Systems
Biology (CSMB, NWO Genomics), Biobanking and Biomolecular Resources Research
Infrastructure (Grant Nos. 184.021.007, 184.033.111), Koninklijke Nederlandse Akademie van
Wetenschappen (NL) (Grant No. PAH/6635), European Science Foundation (Grant No.
EU/QLRT-2001-01254), FP7 Health (Grant Nos. 01413: ENGAGE, 602768: ACTION), H2020
European Research Council (Grant Nos. ERC AG 230374, ERC SG 284167, ERC CG 771057),
National Institutes of Health (Grant No. NIH R01 DK092127-04) and Avera Institute for Human
Genetics. Bart Baselmans: NWO/ZonMw: Rubicon 45219101. For QIMR, funding for data
collection and/or genotyping was provided by the Australian National Health and Medical
Research Council (NHMRC); the Australian Research Council (ARC); the FP-5 GenomEUtwin
Project; the US National Institutes of Health (NIH); and the Center for Inherited Disease
Research (CIDR; Baltimore, MD, USA). TEDS is supported by a program grant to RP from the
UK Medical Research Council (MR/M021475/1 and previously G0901245), with additional
support from the US National Institutes of Health (AG046938). The research leading to these
results has also received funding from the European Research Council under the European
Union's Seventh Framework Programme (FP7/2007–2013)/ grant agreement n° 602768 and ERC
grant agreement n° 295366. RP is supported by a Medical Research Council Professorship award
(G19/2). High performance computing facilities were funded with capital equipment grants from
the GSTT Charity (TR130505) and Maudsley Charity (980).
5.10 References
1. Wilcox, A.J., On the importance--and the unimportance--of birthweight. Int J Epidemiol,
2001. 30(6): p. 1233-41.
2. Wilcox, A.J., Birth weight and perinatal mortality: the effect of maternal smoking. Am J
Epidemiol, 1993. 137(10): p. 1098-104.
3. Wilcox, A.J. and I.T. Russell, Birthweight and perinatal mortality: II. On weight-specific
mortality. Int J Epidemiol, 1983. 12(3): p. 319-25.
4. Barker, D.J. and P.M. Clark, Fetal undernutrition and disease in later life. Rev Reprod,
1997. 2(2): p. 105-12.
5. Johansson, M. and F. Rasmussen, Birthweight and body mass index in young adulthood:
the Swedish young male twins study. Twin Res, 2001. 4(5): p. 400-5.

163
6. Sorensen, H.T., et al., Relation between weight and length at birth and body mass index
in young adulthood: cohort study. BMJ, 1997. 315(7116): p. 1137.
7. Eriksson, M., et al., Birth weight and cardiovascular risk factors in a cohort followed
until 80 years of age: the study of men born in 1913. J Intern Med, 2004. 255(2): p.
23646.
8. Wang, S.F., et al., Birth weight and risk of coronary heart disease in adults: a
metaanalysis of prospective cohort studies. J Dev Orig Health Dis, 2014. 5(6): p. 408-19.
9. Whincup, P.H., et al., Birth weight and risk of type 2 diabetes: a systematic review.
JAMA, 2008. 300(24): p. 2886-97.
10. Gamborg, M., et al., Birth weight and systolic blood pressure in adolescence and
adulthood: meta-regression analysis of sex- and age-specific results from 20 Nordic
studies. Am J Epidemiol, 2007. 166(6): p. 634-45.
11. RG, I.J., C.D. Stehouwer, and D.I. Boomsma, Evidence for genetic factors explaining the
birth weight-blood pressure relation. Analysis in twins. Hypertension, 2000. 36(6): p.
1008-12.
12. Law, C.M. and A.W. Shiell, Is blood pressure inversely related to birth weight? The
strength of evidence from a systematic review of the literature. J Hypertens, 1996. 14(8):
p. 935-41.
13. Cheung, Y.B., et al., Birthweight and psychological distress in adult twins: a longitudinal
study. Acta Paediatr, 2004. 93(7): p. 965-8.
14. Kramer, M.S., Determinants of low birth weight: methodological assessment and
metaanalysis. Bull World Health Organ, 1987. 65(5): p. 663-737.
15. Jarvelin, M.R., et al., Ecological and individual predictors of birthweight in a northern
Finland birth cohort 1986. Paediatr Perinat Epidemiol, 1997. 11(3): p. 298-312.
16. Gielen, M., et al., Secular trends in gestational age and birthweight in twins. Hum
Reprod, 2010. 25(9): p. 2346-53.
17. Hur, Y.M., et al., A comparison of twin birthweight data from Australia, the Netherlands,
the United States, Japan, and South Korea: are genetic and environmental variations in
birthweight similar in Caucasians and East Asians? Twin Res Hum Genet, 2005. 8(6): p.
638-48.
18. Clausson, B., P. Lichtenstein, and S. Cnattingius, Genetic influence on birthweight and
gestational length determined by studies in offspring of twins. BJOG, 2000. 107(3): p.
375-81.
19. Mook-Kanamori, D.O., et al., Heritability estimates of body size in fetal life and early
childhood. PLoS One, 2012. 7(7): p. e39901.
20. van Dommelen, P., et al., Genetic study of the height and weight process during infancy.
Twin Res, 2004. 7(6): p. 607-16.
21. Freathy, R.M., et al., Variants in ADCY5 and near CCNL1 are associated with fetal
growth and birth weight. Nat Genet, 2010. 42(5): p. 430-5.
22. Horikoshi, M., et al., New loci associated with birth weight identify genetic links between
intrauterine growth and adult height and metabolism. Nat Genet, 2013. 45(1): p. 76-82.
23. Horikoshi, M., et al., Genome-wide associations for birth weight and correlations with
adult disease. Nature, 2016. 538(7624): p. 248-252.

164
24. Beaumont, R.N., et al., Genome-wide association study of offspring birth weight in 86
577 women identifies five novel loci and highlights maternal genetic effects that are
independent of fetal genetics. Hum Mol Genet, 2018. 27(4): p. 742-756.
25. Warrington, N.M., et al., Maternal and fetal genetic effects on birth weight and their
relevance to cardio-metabolic risk factors. Nat Genet, 2019. 51(5): p. 804-814.
26. Metrustry, S.J., et al., Variants close to NTRK2 gene are associated with birth weight in
female twins. Twin Res Hum Genet, 2014. 17(4): p. 254-61.
27. Barker, D.J. and C. Osmond, Infant mortality, childhood nutrition, and ischaemic heart
disease in England and Wales. Lancet, 1986. 1(8489): p. 1077-81.
28. Barker, D.J., et al., Weight in infancy and death from ischaemic heart disease. Lancet,
1989. 2(8663): p. 577-80.
29. Barker, D.J., et al., Fetal nutrition and cardiovascular disease in adult life. Lancet, 1993.
341(8850): p. 938-41.
30. de Boo, H.A. and J.E. Harding, The developmental origins of adult disease (Barker)
hypothesis. Aust N Z J Obstet Gynaecol, 2006. 46(1): p. 4-14.
31. Geelhoed, J.J. and V.W. Jaddoe, Early influences on cardiovascular and renal
development. Eur J Epidemiol, 2010. 25(10): p. 677-92.
32. Xu, X.F., et al., Effect of low birth weight on childhood asthma: a meta-analysis. BMC
Pediatr, 2014. 14: p. 275.
33. O'Donnell, K.J. and M.J. Meaney, Fetal Origins of Mental Health: The Developmental
Origins of Health and Disease Hypothesis. Am J Psychiatry, 2017. 174(4): p. 319-328.
34. Orri, M., et al., Contribution of birth weight to mental health, cognitive and
socioeconomic outcomes: two-sample Mendelian randomisation. Br J Psychiatry, 2021:
p. 1-8.
35. Hattersley, A.T. and J.E. Tooke, The fetal insulin hypothesis: an alternative explanation
of the association of low birthweight with diabetes and vascular disease. Lancet, 1999.
353(9166): p. 1789-92.
36. Evans, D.M., et al., Elucidating the role of maternal environmental exposures on
offspring health and disease using two-sample Mendelian randomization. Int J
Epidemiol, 2019. 48(3): p. 861-875.
37. Moen, G.H., et al., Mendelian randomization study of maternal influences on birthweight
and future cardiometabolic risk in the HUNT cohort. Nat Commun, 2020. 11(1): p. 5404.
38. Loos, R.J., et al., Determinants of birthweight and intrauterine growth in liveborn twins.
Paediatr Perinat Epidemiol, 2005. 19 Suppl 1: p. 15-22.
39. Bleker, O.P., W. Breur, and B.L. Huidekoper, A study of birth weight, placental weight
and mortality of twins as compared to singletons. Br J Obstet Gynaecol, 1979. 86(2): p.
111-8.
40. Kingdom, J.C., O. Nevo, and K.E. Murphy, Discordant growth in twins. Prenat Diagn,
2005. 25(9): p. 759-65.
41. Senoo, M., et al., Growth pattern of twins of different chorionicity evaluated by
sonographic biometry. Obstet Gynecol, 2000. 95(5): p. 656-61.
42. de Geus, E.J., et al., Comparing blood pressure of twins and their singleton siblings:
being a twin does not affect adult blood pressure. Twin Res, 2001. 4(5): p. 385-91.

165
43. McNeill, G., et al., Blood pressure in relation to birth weight in twins and singleton
controls matched for gestational age. Am J Epidemiol, 2003. 158(2): p. 150-5.
44. Andrew, T., et al., Are twins and singletons comparable? A study of disease-related and
lifestyle characteristics in adult women. Twin Res, 2001. 4(6): p. 464-77.
45. Petersen, I., et al., No evidence of a higher 10 year period prevalence of diabetes among
77,885 twins compared with 215,264 singletons from the Danish birth cohorts 19101989.
Diabetologia, 2011. 54(8): p. 2016-24.
46. Ijzerman, R.G., D.I. Boomsma, and C.D. Stehouwer, Intrauterine environmental and
genetic influences on the association between birthweight and cardiovascular risk
factors: studies in twins as a means of testing the fetal origins hypothesis. Paediatr
Perinat Epidemiol, 2005. 19 Suppl 1: p. 10-4.
47. Magnus, P., Causes of variation in birth weight: a study of offspring of twins. Clin Genet,
1984. 25(1): p. 15-24.
48. Srivastava, A.K., et al., Haplotype-based heritability estimations reveal gestational
duration as a maternal trait and fetal size measurements at birth as fetal traits in human
pregnancy. bioRxiv, 2020: p. 2020.05.12.079863.
49. van Beijsterveldt, C.E., et al., The Young Netherlands Twin Register (YNTR):
longitudinal twin and family studies in over 70,000 children. Twin Res Hum Genet, 2013.
16(1): p. 252-67.
50. Willemsen, G., et al., The Adult Netherlands Twin Register: twenty-five years of survey
and biological data collection. Twin Res Hum Genet, 2013. 16(1): p. 271-81.
51. Wright, M.J., Martin, N., The Brisbane Adolescent Twin Study: Outline of study methods
and research projects. The Australian Journal of Psychology, 2004. 56: p. 56-78.
52. Slutske, W.S., et al., The Australian Twin Study of Gambling (OZ-GAM): rationale,
sample description, predictors of participation, and a first look at sources of individual
differences in gambling involvement. Twin Res Hum Genet, 2009. 12(1): p. 63-78.
53. Medland, S.E., et al., Common variants in the trichohyalin gene are associated with
straight hair in Europeans. Am J Hum Genet, 2009. 85(5): p. 750-5.
54. Pedersen, D.A., et al., The Danish Twin Registry: An Updated Overview. Twin Res Hum
Genet, 2019. 22(6): p. 499-507.
55. Kaprio, J., The Finnish Twin Cohort Study: an update. Twin Res Hum Genet, 2013.
16(1): p. 157-62.
56. Kaprio, J., L. Pulkkinen, and R.J. Rose, Genetic and environmental factors in
healthrelated behaviors: studies on Finnish twins and twin families. Twin Res, 2002.
5(5): p. 366-71.
57. Haworth, C.M., O.S. Davis, and R. Plomin, Twins Early Development Study (TEDS): a
genetically sensitive investigation of cognitive and behavioral development from
childhood to young adulthood. Twin Res Hum Genet, 2013. 16(1): p. 117-25.
58. Anckarsater, H., et al., The Child and Adolescent Twin Study in Sweden (CATSS). Twin
Res Hum Genet, 2011. 14(6): p. 495-508.
59. Magnusson, P.K., et al., The Swedish Twin Registry: establishment of a biobank and other
recent developments. Twin Res Hum Genet, 2013. 16(1): p. 317-29.
60. Ortqvist, A.K., et al., Familial factors do not confound the association between birth
weight and childhood asthma. Pediatrics, 2009. 124(4): p. e737-43.

166
61. Kittelsrud, J., et al., Establishment of the Avera Twin Register in the Midwest USA. Twin
Res Hum Genet, 2017. 20(5): p. 414-418.
62. Kittelsrud, J.M., et al., Avera Twin Register Growing Through Online Consenting and
Survey Collection. Twin Res Hum Genet, 2019. 22(6): p. 686-690.
63. Bycroft, C., et al., The UK Biobank resource with deep phenotyping and genomic data.
Nature, 2018. 562(7726): p. 203-209.
64. Mbarek, H., et al., Biological insights into multiple birth: genetic findings from UK
Biobank. Eur J Hum Genet, 2019. 27(6): p. 970-979.
65. Purcell, S., et al., PLINK: a tool set for whole-genome association and population-based
linkage analyses. Am J Hum Genet, 2007. 81(3): p. 559-75.
66. Winkler, T.W., et al., Quality control and conduct of genome-wide association
metaanalyses. Nat Protoc, 2014. 9(5): p. 1192-212.
67. Willer, C.J., Y. Li, and G.R. Abecasis, METAL: fast and efficient meta-analysis of
genomewide association scans. Bioinformatics, 2010. 26(17): p. 2190-1.
68. Devlin, B. and K. Roeder, Genomic control for association studies. Biometrics, 1999.
55(4): p. 997-1004.
69. Watanabe, K., et al., Functional mapping and annotation of genetic associations with
FUMA. Nat Commun, 2017. 8(1): p. 1826.
70. Machiela, M.J. and S.J. Chanock, LDlink: a web-based application for exploring
population-specific haplotype structure and linking correlated alleles of possible
functional variants. Bioinformatics, 2015. 31(21): p. 3555-7.
71. Zheng, J., et al., LD Hub: a centralized database and web interface to perform LD score
regression that maximizes the potential of summary level GWAS data for SNP heritability
and genetic correlation analysis. Bioinformatics, 2017. 33(2): p. 272-279.
72. Bulik-Sullivan, B., et al., An atlas of genetic correlations across human diseases and
traits. Nat Genet, 2015. 47(11): p. 1236-41.
73. Bulik-Sullivan, B.K., et al., LD Score regression distinguishes confounding from
polygenicity in genome-wide association studies. Nat Genet, 2015. 47(3): p. 291-5.
74. Vilhjalmsson, B.J., et al., Modeling Linkage Disequilibrium Increases Accuracy of
Polygenic Risk Scores. Am J Hum Genet, 2015. 97(4): p. 576-92.
75. Genomes Project, C., et al., A global reference for human genetic variation. Nature, 2015.
526(7571): p. 68-74.
76. Minica, C.C., et al., Sandwich corrected standard errors in family-based genome-wide
association studies. Eur J Hum Genet, 2015. 23(3): p. 388-94.
5.11 Supplementary Materials
5.11.1 Supplementary Figure

167
Supplementary Figure 5.1 – QQ plot of the p-values from the GWAMA on twin BW
5.11.2 Supplementary Methods
Formulas for PGS prediction
PGS were calculated from summary statistics of a UK Biobank GWAS on BW
(http://www.nealelab.is/uk-biobank/) and were used to predict BW in NTR twins and singletons.
The formula below was used to evaluate the prediction in twins and singletons separately:

168
BWraw ~ bGenomic PCs + bSex + bGestational age + bYear of birth + bPGS + bGenotyping platform
The formula below was used to evaluate the prediction in the entire target sample (twins and
singletons) using BW category as the response. In this model, we included a main effect of twin
status and an interaction term between twin status and the PGS.
For prediction in the full target sample using BW category:
BWcategory ~ bGenomic PCs + bSex + bGestational age + bYear of birth + bPGS + bGenotyping platform + bTwin status
+ bPGS * bTwin status
5.11.3 Supplementary Tables
169
170
171
172
173
174
175
Supplementary Table 5.2 – Genetic correlations with BW in twins. Traits are sorted by
category and descending rg
Child birth weight (Horikoshi 2013)
23202124
Anthropometric
0.98
0.18
5.38
7.34E-08
UK Biobank birth weight (Field 20022)
Offspring birth weight (maternal effect)
Anthropometric
0.95
0.12
7.64
2.19E-14
adjusted for offspring genotype
31043758
Anthropometric
0.92
0.13
6.88
6.15E-12
Own birth weight (Warrington 2019)
31043758
Anthropometric
0.92
0.13
7.03
2.07E-12
Birth weight (Horikoshi 2016)
27680694
Anthropometric
0.91
0.13
6.79
1.12E-11
Offspring birth weight (Warrington 2019)
Own birth weight (fetal effect) adjusted
31043758
Anthropometric
0.76
0.14
5.51
3.62E-08
for maternal genotype
31043758
Anthropometric
0.69
0.12
5.71
1.11E-08
Child birth length
25281659
Anthropometric
0.57
0.13
4.21
2.52E-05
Extreme height
23563607
Anthropometric
0.38
0.1
3.92
8.92E-05
Height
20881960
Anthropometric
0.35
0.08
4.34
1.43E-05
Infant head circumference
Height; Females at age 10 and males at
22504419
Anthropometric
0.34
0.16
2.1
0.0358
age 12
23449627
Anthropometric
0.33
0.12
2.73
0.0062
Hip circumference
25673412
Anthropometric
0.32
0.08
4.23
2.34E-05
Obesity class 3
23563607
Anthropometric
0.29
0.12
2.38
0.0173
Childhood obesity
22484627
Anthropometric
0.27
0.11
2.46
0.0141
Waist circumference
25673412
Anthropometric
0.26
0.07
3.56
0.0004
Overweight
23563607
Anthropometric
0.18
0.07
2.54
0.0112
Body mass index
20935630
Anthropometric
0.18
0.07
2.68
0.0074
Obesity class 2
23563607
Anthropometric
0.14
0.08
1.84
0.0652
Obesity class 1
23563607
Anthropometric
0.14
0.07
2.11
0.0352
Extreme bmi
Difference in height between
23563607
Anthropometric
0.06
0.1
0.63
0.529
adolescence and adulthood; age 14
23449627
Anthropometric
0.05
0.17
0.31
0.756
Waist-to-hip ratio
25673412
Anthropometric
0.01
0.08
0.18
0.854
Sitting height ratio
Difference in height between childhood
25865494
Anthropometric
0.01
0.15
0.09
0.925
and adulthood; age 8
23449627
Anthropometric
-0.02
0.15
-0.12
0.905
Extreme waist-to-hip ratio
23563607
Anthropometric
-0.16
0.16
-1.02
0.309
Crohns disease
26192919
Autoimmune
0.16
0.1
1.58
0.114
Rheumatoid Arthritis
24390342
Autoimmune
0.11
0.11
1.02
0.307
Inflammatory Bowel Disease (Euro)
26192919
Autoimmune
0.09
0.1
0.97
0.332
Ulcerative colitis
26192919
Autoimmune
0.08
0.11
0.7
0.483
Celiac disease
20190752
Autoimmune
0.07
0.15
0.46
0.646
Primary biliary cirrhosis
26394269
Autoimmune
0.01
0.12
0.05
0.961
Trait
PMID
a
Category
r
g
b
SE
c
z
d
p
e
176
Systemic lupus erythematosus
26502338
Autoimmune
-0.1
0.13
-0.77
0.44
Asthma
17611496
Autoimmune
-0.34
0.15
-2.25
0.0247
Intelligence
28530673
Cognitive
0.2
0.09
2.21
0.0268
Type 2 Diabetes
22885922
Glycemic
-0.02
0.1
-0.21
0.833
HOMA-Bf
20081858
Glycemic
-0.08
0.15
-0.51
0.609
HOMA-IRg
20081858
Glycemic
-0.09
0.17
-0.53
0.594
Fasting glucose main effect
22581228
Glycemic
-0.1
0.11
-0.94
0.349
Fasting insulin main effect
22581228
Glycemic
-0.11
0.14
-0.73
0.463
HbA1Ch
20858683
Glycemic
-0.23
0.14
-1.72
0.0846
Bipolar disorder
21926972
Psychiatric
0.13
0.1
1.31
0.189
Depressive symptoms
27089181
Psychiatric
0.13
0.09
1.39
0.163
PGCi cross-disorder analysis
23453885
Psychiatric
0.06
0.09
0.64
0.521
Autism spectrum disorder
0
Psychiatric
0.04
0.12
0.3
0.764
Subjective well being
27089181
Psychiatric
0.01
0.1
0.15
0.882
Major depressive disorder
22472876
Psychiatric
-0.1
0.15
-0.67
0.505
Anorexia Nervosa
24514567
Psychiatric
-0.13
0.08
-1.59
0.113
Number of children ever born
27798627
Reproductive
0.12
0.1
1.24
0.214
Age of first birth
27798627
Reproductive
0.08
0.08
1.01
0.313
Age at Menopause
26414677
Reproductive
0.01
0.1
0.08
0.936
Age at Menarche
25231870
Reproductive
-0.04
0.07
-0.59
0.552
Cigarettes smoked per day
20418890
Smoking behavior
0.23
0.18
1.28
0.202
Smoking Initiation
30617275
Smoking behavior
0.08
0.15
0.5
0.616
Former vs Current smoker
20418890
Smoking behavior
0.01
0.17
0.04
0.969
Age of smoking initiation
20418890
Smoking behavior
-0.03
0.19
-0.15
0.88
Ever vs never smoked
20418890
Smoking behavior
-0.06
0.11
-0.56
0.576
a PubMed reference number
b Genetic correlation c
Standard error of rg d Z-
score e P-value
f Homeostatic model assessment of beta cell function g
Homeostatic model assessment of insulin resistance
h HemoglobinA1C
i Pyschiatric Genetics Consortium
000)
TE?
49
VN
SO'O>
4-0T>d
x
ssaupeyeal
%
AewuyuoAsq
winiuyul
eulwn]||
yd
UOISJ3A
¢
‘yo}ewWs!IW
Japuay
cALNdWI
vz
000.
:
36
OQOOT
36
zz
EOVWINIW
49
8-OTXG>d
TO'O>
40T>d
9%,
9%
diygpeag
~APWuPAsd
SSLVO
¢
yo}eq
SuidAjouas
ul
suauggtlios
wuunjuyu]
eulwnj||
UUM
payelosse
jediouiid
om}
3suy
sJaysew
‘Bul|jed
94}
JO
URAW
WO}
yueleA
JOOd
YUM
psg<)
ueadoing
SJBYIEW
[CLI
PUOYIO}IW
-UOU
‘SUOQRIOIA
pue
awosowolyd
xas
‘ssaupayejal
A
‘SUIM}
Z|\ $0
Suled
BAISSOWD
yg
suowe
sdAjouas
.7
JUEPIJOISIP
AUO
ULUY
<j
sascBI9Sior0/y
SJOW
YUM
SiayxJeW
‘sajdwes
azeoijdnp
s¢
HEI
soup
Suowe
ssauepsodsip
ann
SUIMOUS
SJayJe/A|
EDVININIA
49
WN
OT'0>
,0T>d
479
=>oT
Pro
4?
VS
eUuluN|||
VuaAV
E
~
HUlld
Ayso8Az01819H
‘ssoupayejay
‘Sayo}ewsiw
Japuay
pcemes
ued
sous euonppy
av
amd
“|
siomsjeuonippy
“EY
——(s)Aeusy
Busthrous
oye
uoyezndu
pue
Zuiseud
eJ0
dNS
eJ0
ajdwes
JAOYOS
19d
UOLeULAOJUI
SUIdAjOUDs
—
¢°s
B[qQuUL,
AreyusWe;ddns
177
ENVWINIW
T4
YH
eOT>d
}ajeid
To'O>
<OT>d
x
Aujsaoue
x
Z'TAS
Sd
Jo
‘ya}eq
‘wooed
°
ueadoing-uou
°
-aWoxyssasdxqiuwQuewny
yuIM
uoQeIDossy
‘AUSOBAzZ09}9Y
‘0°9
diyjauanxiyawAyy
‘ssaupaye|al
‘SQYD}eWSILU
aan
Japuay
099
SOVININIW
adAjouas
JouNsSIPauOo
§=—TO'O>
4OT>d
x”
(p2a39981109
x”
G*
ZIUWO
‘AeyyosAd
YINIO
g°
‘10
>
24095
3D URAL
°
aqojajqejou
J!)
sdnxiw
ajdwies
ots
‘noe
W7
EP
EB
RuA
‘SOYD]eWSILW
Japuay
000
EDVWINIW
49
Os-Ov'
IVA
TO'0>
0T>d
78
=orgpro
4»
wope|d
eauenbas
1NO
YIN
¢
YIM
SdNS
D1LWOpUul|ed
-
4Ulld
“YS
eUIWIN]||
“WT
eulwny||
‘OZ
<=
JOM
japUud|/|
AysosAzo1a12H
‘O99
Buln]
‘Woy
‘ssoupaye|ay
XUJaWALY
‘O'9
XUJEWAYY
‘Sayo}ewsilw
‘xUeWAYY
Usda]|J9q
Japuay
000
EDVWINIW
49
Suo|snjoxe
T0'0>
gy
0T>d
7?
>e070
900
VO'TA
ulmLuuly
€
491/3NO
Vd
SAIN
-
INMd
p7-awox
dio
UeWNH
‘WT'TA
Aysp3Azo13}3H
‘gO°TA
-aWoxqaojuewWNH
‘Sayo}ewsiw
‘40'TA
peno-oTguewny
Japuag
‘Y
O'TA
Woysngpeno
-oZguewny
eulwn]||
178
Aouonbosy
spo]
[e
JOULPY
umMigitmbe
S1aquiajy-ApseH
Jomo.
AyyTend
+
ZALNdWII
sy
T1000
NOTIN
UL
GOO'O>
50T>d
79)
seyaqewsjw
Japues
70
Aewy
Wwoxy
ain
4VW
0}
pasedwos
sy
°
‘Auysanue
yn
yuegolg
yn
swaisAsoig
€dD
T’
=<
JO
sduaJayIG
-uou
‘ssaupalejay
paddy
au}
‘xujawAyYy
‘c1-OT>d
4!
areld
Jo
‘yo}eq
‘wio0se\d
yum
uoyelDossy
Aq
Aewy
3A3119
IN
179
*(/SOd1AJ9S
-
dus/duldAjouas/as
nn
lsspaw'
besdus//:dyy
uapams
‘ejesddy
‘Aioyesoqge]
DJI]
JO}
BDUTINS
‘WUOe}q
AZojouysaL
"‘(uassapad)
S86ZE09V
TOY
HIN
Aq
payoddns
sem
suidAjouay
‘(T9Z809V
TOd)
YNeaH
Jo
sainyysu|
jeuopeN
S/N
au}
pue
UoyeAouU|
pue
AZojouYsaL
‘a9UaI9S
Joy
Anuasy
ysiueg
ay}
Wo.
/00Z
a4n}INJysesJuU|
yoiueasay
JO}
Weiso1g [PUONEN
ay)
Wo
‘Aduasy
U0Qda}01g
e}eq
Ysiueg ayy
Aq
paaojdde
sem
Apnjs
ay}
pue
‘yJewWuUaqg
UJaY
NOS
JOJ
SA9WIWIWOD
|e91479
IYyWUaIIS
|eUOIZaYy
ay}
Aq
pavosdde
JIM
UOQeWJOJU!
AdAINS
pue
jelazew
JEd1Z0|O1g
JO
aSN
pue
UOQIA]|0D
‘sjuedionied
|je
wos
pauleyqo
OIS'BdNS
243
Aq
pa}anpuod
sem
SBuldAjouay
sjuei3
Aq
payioddns
s|
uogsaijo9
eyep
yg
aUL
3AM
SJUBSUOD
PAWJOJU!
UJALM
Yyld
€/6S0-8T0Z
‘OU
JUaWaas8e
JUeIs
ysnojy}
|INUNOD
Ydeasay
USIPaMs
auy
Aq
papun
Ajjeqied
xewddy
ye
(DINS)
3ugndwo;
JO}
aiNJONAJsesju]
|eEUOWeN
YSIPaMS
ay}
Aq
papiAoid
sadinosad
Aq
pajqeua
alam
‘Ly900-ZT0Z
Ou
jUeIs
ay}
JapUN
*"JUBSUOD
PAWJOJU!
Suljpuey
ejyep
pue
suoyeyndwod
jedo]
ay
jINUNOD
Ydeasay
YSIPaMS
ay}
Ysnoiu]
Bulpuny
anes
Sjuedio
ed
|je
pue
uapams
"9DIAJBS
YUEGOIG
|BUOISSAJOId
JOJ
JOINIYSU,]
SBAJ9D94
Puke
}a}N{YsSu]
eyxSU]Ouey
AG
paseuew
sI
‘WJOYI0}5
UI
Pueog
MaIAaY
|e914I9
exsuljouey
3e
YUeqO!g
24}
YUEYI
0}
YsIM
aM
—_YDIYM
AAsIBEY
UML
YSIPaMs
243
Jo'L@d
si
ssiva
—_-jeoiBay
ay
Aq
pancudde
si
Apnys
a4.
SSD
SUIML
Ul
SAl0JA/[ed
j|e}JUaWdOjaANGg
:1Uet5
[HIN
Usnosy;
SE
REO
Hoy
UIML
BJdAY
3U}
PUe
SpUe|JaYJaN
BY}
UVaMjaq
"uo0Qda}01d
Jaysizay
UOHeJOge|/O9
ay]
*sd4aUaH
UBLUNH
JO}
aINIYSU]
$,JOafqnsg
UeWNH
Jo
JUaWed|ag
eaAY
UIML
ELaAY
33
JO
SJUedIOQed
paljouua
dU}
Jo
BJBAY
puke
jeydsoH
UeUUaYI)\|
BUaAY
‘YYeaH
34}
pue
pueog
MalAay
jeUOAN
WSU
jJe
0}
8
pNyeus
UNO
puay}Xxa
0}
dyI|
PjNOM
ay
elaay
Aq
payoddns
si
Jajysisay
UIML
BJaAY
aUL
eJaAV
34}
Aq
paAoidde
sem
Apnjs
aut
YWYdIAV
s]UaW3pa|mMou
sy
suipun4
JUSLUDZERS
SI147Z
HOYOD
SJUSWIIS
poyMOUyov
puv
‘SUIPUN]
‘s}UIUID}¥}s
SII]
—
p's
9IQuy,
ArvjusWe;ddng
180
“youeasal
aiyiqualos
Jo
Ywoddns
panuljuos
JJ9Y}
JOJ
Ja}sIZay
UIM|
SpUeLJaUuIEN
3U}
YUM
pasaysisaJ
saljiwey
UM
JO
SdJaquatU
[Je
}UEU}
0}
ayI|
PINOM
aM,
“LOT6ET
CSV
uosIqny
:MAIU0Z/OMN
‘suewlaseg
Weg
‘sdijauay
ueWN}
JOJ
94nj!}su]
e4aAY
pue
(7O-LZTZ601G
TOY
HIN
‘ON
3Ue19)
Yea}
JO
saynyysu|
|euoljeN
“(LSOTLL
99
OYA
‘L9TP8Z
OS
OYA
‘VLEOEZ
DV
DF
‘SON
JUeID)
[IDUNOD
YoJeasay
UeadoJNy
0Z0ZH
‘(NOILOV
?892209
‘JDVONI
‘ET
VTO
“SON
JUeJD)
YI]9H
Zd4
‘(~SZTO-T00Z-LYT0/N3
“ON JULIO)
UOIJePUNOY
adUaIIS
UeadoINA
“(SE99/HWd
‘ON
ues)
(1N)
Uaddeyrsuayay
UeA
alWapexy
aspue|Japan
ay{l|UlUOY
“(TT
T€€O'
VST
‘LOO'TZO'V8T
“SON
JUeID)
asnjonsysesju]
yoJeasay
sadinosay
Jejndajowolg
pue
Suyueqoig
“(sa1WOUad
OMN
‘AINSD)
Adojolg
swiayshs
|es!pa
404
243U39
“(76TVT-79t-9S-OMN
‘v£9/T00-ST
-O8
10019-OMN
‘€00°T00'7Z0-
WesBosd
Anes
OMN
M90
‘Z€0-60-TT6-10043|2pP!N-OMN
‘B0009TTE-UONIIPpY
“SON
JUeID)
YOZIBaPUD
yfljaddeydsuayaM
JOOA
aljyesiuesiOC
aspueyapan
‘(OTO-ZE-9S0
PU
TTO-80-T8r
‘SEO-STT-9TO
‘LTL-S0-000
‘VE0-70-TSr
‘T00-90-€9P
‘v00-v0-08r7
‘E6T-19-706
‘O0Z0-OT-ZT6
‘Z00-OT-S86
‘060-19
-706
‘SON
UID)
MWUOZ
Aq
papiAoid
sem
Bulpun4
*(08T0-€0
U.LN
‘Sapoo
a4nq!3sul/gyl
‘86SZTOOOWM4
-
BDUBINSSY
apIM-|eJapaj
Japun
T66Z00008UI!
Jequunu
gy!)
SUo!9a}01g
youeasay
UBWNH
JO
ad1JO
SN
au}
Aq
payiqiao
pseog
MalAay
|2uo!}NyYsSU|
ue
‘weplaysuuy
‘a1]UaZ
|ed1pal\|
AJSJAAIUN
NA
BU}
JO
S}IaIqns
UeWINH
SUIAJOAU|
YDJeaSaYy
UO
39}}/WWOD
$314}
Jesjuaa
ayy
Aq
panoudde
sem
Apnjs
ay
MLN
“uolja}}oo
eyep
pue
quawyins9ad
Ul
UOIIN!4jUOD
ajqen|en
Jay
JO}
paspajmouyose
s!
ejoddey
efuly
‘UOIING!4}UO
Jay}
410}
suled
UIM}
Bulyedioed
ay.
yUeUy
AjWUeM
ay
IN
‘aINUYSU|
JaBUeS
JsN4]
BWOD|a/y
ay}
pue
‘OIG
“Wd
03
SSZ8TOVVZON
PUe
OTPSTYV
pue
aSO¥
“f
"Y
0}
€0Z60-VV
Pue
‘GPTOO-VV ‘Z0SZT-VV
s]UeJ3)
Ws||OYOo|y
pue
asngy
|OYoo|y
Jo
aynqysuU]
jeuoneNn
‘(oludey
“f
01
9pTH9Z
pue
8/ZE97
‘OvZS9Z ‘vSOTVT ‘SSS8TT
‘S8SS02
‘6P00T
s}ueJ3)
puejuly
Jo
Awapesy
ay}
(O896ZT
‘90SETZ
squed3)
$21}8UaD
aseasiq
Xa|dwWoD
U!
adUa||a9xq
JO
Ja}UaD
puejuly
Jo
Awapesy
ay}
Aq
payoddns
sem
syoyoo
UIM}
YS|UUL4
BU}
Jo
SuldAjouas
pue
SuidAjouaud
*UO1}99||09
ajdwes
ay}
asojaq
sjyuedioiqed
24}
Aq
papiAoid
sem
UasUOd
pawWojul
ua}
“(TT0Z/00/€0/ET/PST
pue
8002/T0/€0/€T/0ZZ)
ley!dsoH
Je4UaD
AyssaAluN
PUIS|aH
Pue
(GO0/04/9vE
Pue
TO/€4/ETT)
MUIS|H
JO
AyissanluA
ayy
JO
Saa}IWWOD
$d|U}a
ayy
Aq
panoidde
uaaq
sey
Uo!IaI]O9
EJePD14ayL
UIMLUUIY
181
‘TLySZ
JOQUINN
uoHed|ddy
Japun
adinosay
yUeQqoIg
9
24}
SUISN
paynNpuod
uvaq
sey
Yydeasa
SIUL
ain
“Soljlwe}
4194}
pue
(Sada)
Apnys
quawdoyjanag
Ajseq
SUIML
94}
Ul
s}UedIaqQed
9yj
Jo
UOANG!4UOD
SUIOZUO
9}
aSpa|mMouyDIe
AjjnNja}ess
a
(086)
Aeyd
Aajspnew
pue
(SOSOETUL)
AeYyd
11SD
ay}
Wo,
sjueIs
juawdinba
jeyides
uM
papunj
aiaM
sayiloey
SuNnNdwod
sdueWJOLJad
YZIH
(Z7/6TD)
pueme
diyssossajoid
|INUNOD
Ydieasay
jesipayy
e
Aq
payoddns
si
dy
"99€46Z
,U
JUaWaaIZe
JUeIS
DYA
pue
89/709
,U
JuawaaiZe
quels
(ETO?
JWWeIZO1d
YIOMaWeL4
yfuana€
SOGioin
ueadoing
ay}
Japun
|Inunos
ydieasay
ueadoing
3}
WO
SUIPUN}
paAladai
Osje
sey
s}jnsaJ
9594}
O}
Sulpes|
yeasad
ay!
“(BE69POOV)
YESH
Jo
sajznzQsu]
|eUOWeN
SN
ay}
Wo
Woddns
|euonIppe
YUM
“(S~ZTOG0D
AjsnolAaid
pue
T/SLVTZOW/YIN)
[!DUNOD
Ydeasay
|edIpaW]
YN
e4i
WOdJ dy
0}
JUeIZ
Weidold
e
Aq
payioddns
si
sqa
dd
vOT
‘(Apnys
quawdojaaag
-
/60/WNd
san
wilh
SHUN
uOpuo]
a8aj/O>
s,Suly
Aq
panosdde
sem
ApAks
aut
Sql
‘uonesadood
JIDY}
JO}
SUIM}
BU}
YULUY
3A
‘(VSN
‘GIN
‘asownyeg
“YdiD)
yaseasay
aseasiq
payJayU|
JO}
19}U9D
BY}
pue
“(HIN)
yYyeaH
Jo
Sa}njQsu]
|EUOHEN
SN
ay}
‘efo1g
UMP
AWOUay
S
dj
yi
“(DyYV)
[DuNOD
Yessay
Ueljeujsny
34}
‘(QYWHN)
[DUNO
Yydieasay
|ed1pal/J
pue
yyeaH
jeuoveN
ueljeaysny
ay}
Aq
papiAoid
sem
SuldAjouas
Jo/pue
UoQda|/09
eyep
JO}
Sulpun4
"9IWIWWOD
sdly}y
yYeasay
uewNy
YINIOD
ay3
Aq
paaoidde
sem
Apnjs
aul
YTD
182

183
CHAPTER 6 - INFERENCE OF GENETIC ANCESTRY: EVALUATION WITHIN
FAMILIES AND ACROSS GENOTYPING ARRAYS
Based on:
Beck, J.J., Ahmed, T., Finnicum, C.T., Zwinderman, K., Ehli, E.A., Boomsma, D.I., Hottenga,
J.J. (2021)Inference of genetic ancestry: evaluation within families and across genotyping arrays.
Manuscript submitted for publication.

184
6.1 Abstract
Inference of genetic ancestry is an essential aspect of population-based association studies
to account for population heterogeneity and structure. A key question is how ancestry estimates
compare when family members participate in a study and when genetic data are sourced from
multiple genotyping arrays. In this paper, we analyze genome-wide SNP data to compare genetic
ancestry estimates between pairs of family members across the spectrum of relatedness, from
independently genotyped identical twins through to unrelated parent pairs, and between
individuals genotyped on multiple arrays. Genetic ancestry estimates were obtained utilizing two
conventionally performed tests, principal component analysis (PCA) and a modelbased approach
exemplified by the software ADMIXTURE. We discover that Euclidean distances of genetic
ancestry estimates between pairs of family members are inversely related to the degree of genetic
relatedness between them irrespective of estimation method and genotyping array, confirming
that ancestry estimates are more similar in closely related individuals. Ancestry estimates of the
same individuals genotyped across arrays were nearly indistinguishable, and we attribute the
slight differences to the array-dependent variation in SNPs used for calculation. We also explore
if non-identical twin offspring of ancestrally diverse parents exhibit more appreciable differences
in ancestry than those with ancestrally similar parents. We uncover that ancestry estimates in
offspring of more diverse parents are not considerably different than those with ancestry-similar
parents. This study demonstrates the utility and robustness of current tools used to infer genetic
ancestry, PCA and ADMIXTURE, even when considering the confounders of relatedness and
genotyping array.
Keywords: within-family analysis, genetic ancestry estimation, population structure, principal
components analysis (PCA), ADMIXTURE

185
6.2 Introduction
Genetic association studies have become an effective research tool for identifying genetic
loci related to complex phenotypes and diseases (1). A fundamental step of performing genetic
association studies is the detection of and correction for population structure. In this paper, we
focus on population structure created by ancestry divergence and its detection based on genotype
data. In general, strategies for estimating global ancestry can be categorized into two broad
groups: algorithmic and model-based approaches. Commonly employed, each method has been
shown to provide reliable inferences of genetic ancestry in unrelated individuals and to elucidate
population structure from genome-wide data (2).
Algorithmic methods are exemplified by cluster analysis and principal component
analysis (PCA). Generally, PCA is a method for obtaining low-dimensional summaries of
highdimensional data, increasing interpretability while minimizing information loss. In genetic
datasets, PCA is performed to identify systematic variation amongst individuals’ genotypes. In
this context, a large set of variables (individuals’ genotypes) are transformed into a smaller group
of uncorrelated variables, called principal components (PCs), usually with the constraint that
each PC successively captures less variation in the original data. PCA of genotypic data yields a
series of scores per individual corresponding to the values of these PCs. Top PCs calculated from
genetic data typically reflect population structure, allowing inferences of genetic ancestry. Over
the years, PCA has demonstrated its utility for elucidating genetic ancestry from seemingly
unrelated samples (2), correcting for confounding due population structure (2, 3), and
understanding population ancestry composition and migration (4-6).

186
Best practices for implementing PCA have been suggested (7), but applying PCA in
genetic analysis to capture population structure is not without challenges. Care must be taken to
ensure that PCs are unbiased and reflect variation in ancestry and not some other form of
systematic variation present within the data. Rather than capturing population structure, some
PCs may reflect linkage disequilibrium (LD) structure. If PCs capturing LD are included as
covariates in analyses, the power for detection in association studies is reduced (6, 8-10). The
degree of population structure captured by PCA may also be diminished by the presence of
outlier samples reflecting batch effects or family structure. Therefore, commonly employed steps
in PCA include determining unrelated individuals, pruning genetic markers in LD, and excluding
outlier samples that may be indicative of poor genotyping quality.
Model-based approaches, such as those embodied by the programs STRUCTURE (11),
fastSTRUCTURE (12), FRAPPE (13), and ADMIXTURE (14), present alternative methods for
elucidation of population structure. These approaches provide relative proportions of ancestry,
given that the genetic composition of an individual is a mosaic of the ancestral populations they
represent. In general, model-based methods estimate global individual ancestry proportions based
on parameterized statistical models. Commonly, these techniques take Bayesian or maximum
likelihood estimation approaches to optimize the probability of observed genotypes by
alternatively updating ancestry coefficient and population allele frequency matrices. The
resulting individual ancestry proportions are more directly interpretable than PCs and can
account for population composition in a study.
The two types of methods appear to have little in common at the surface due to
underlying analytical differences. One involves the explicit definition of a model, while the other
does not. A link between the approaches has been investigated, and strategies for identifying

187
admixture proportions from PCs of PCA have been suggested (15-18). In this context, ancestry
proportions interpreted from PCA and the results of model-based approaches, like
ADMIXTURE, are consistent (19, 20). Given the congruent results, the main interest of the
current paper was to compare ancestry estimates in realistic situations, where individuals in large
studies have genome-wide data from different genotyping arrays. This situation arises in large
cohort studies, where successive generations of genotyping arrays were applied across time. Our
second interest involves study designs incorporating family members. Within families, siblings
with the same biological parents necessarily should be assigned the same ancestry, even when
genotyped across different arrays. Here, families with parents from two different ancestry
backgrounds are of special interest. We compare algorithmic and model-based approaches to
obtain ancestry estimates as a function of genomic relatedness within families, across pairs of
individuals from monozygotic twins to nominally unrelated parent pairs, and within and across
genotyping arrays.
One strategy for mitigating concerns of population structure in genetic association studies
is to employ a family-based design (21, 22). These designs have gained popularity with the
increasing availability of large-scale family datasets (21-24). With the inclusion of closely related
family members, a new set of questions may arise. A key consideration involves the extent to
which close relatives may have different ancestry distributions. For example, when two
individuals from diverse populations mate, their offspring will be admixed and have ancestry
distributions that differ from both parents. When a child’s ancestry ‘differs’ from its biological
parents, the child and at least one parent represent potential population outliers and will be
excluded from the study. In this example, genetic ancestry estimates between sibling offspring of
diverse parents may show variation in calculated ancestry due to the ‘random’ assortment of

188
inherited alleles. We assess the conditions under which such situations can occur by examining
ancestry estimates between family members and focusing on sibling offspring of more diverse
parents to determine if they are more dissimilar to each other than those with ancestry-similar
parents.
This study examines genetic ancestry estimates between pairs of family members across
the spectrum of genetic relatedness, from MZ twins to nominally unrelated parent pairs, and
across genotyping arrays. We leverage data from the 1000 Genomes Project (1000G) (25) and the
Genome of the Netherlands (GoNL) (26, 27) reference panels as well as multiple large single
nucleotide polymorphism (SNP) datasets from twin-family participants of the Netherlands Twin
Register (NTR) (28, 29). The NTR includes nuclear families, mainly two-generation, forming
parent, parent-offspring, dizygotic twin and sibling, and monozygotic twin pairs, all
independently genotyped. The NTR also includes SNP datasets of individuals who were
genotyped on at least two separate genotyping arrays, allowing for assessment of potential
platform effects on genetic ancestry estimates.
6.3 Methods
An overview of the analytical strategies employed in this study is shown in Figure 6.1.
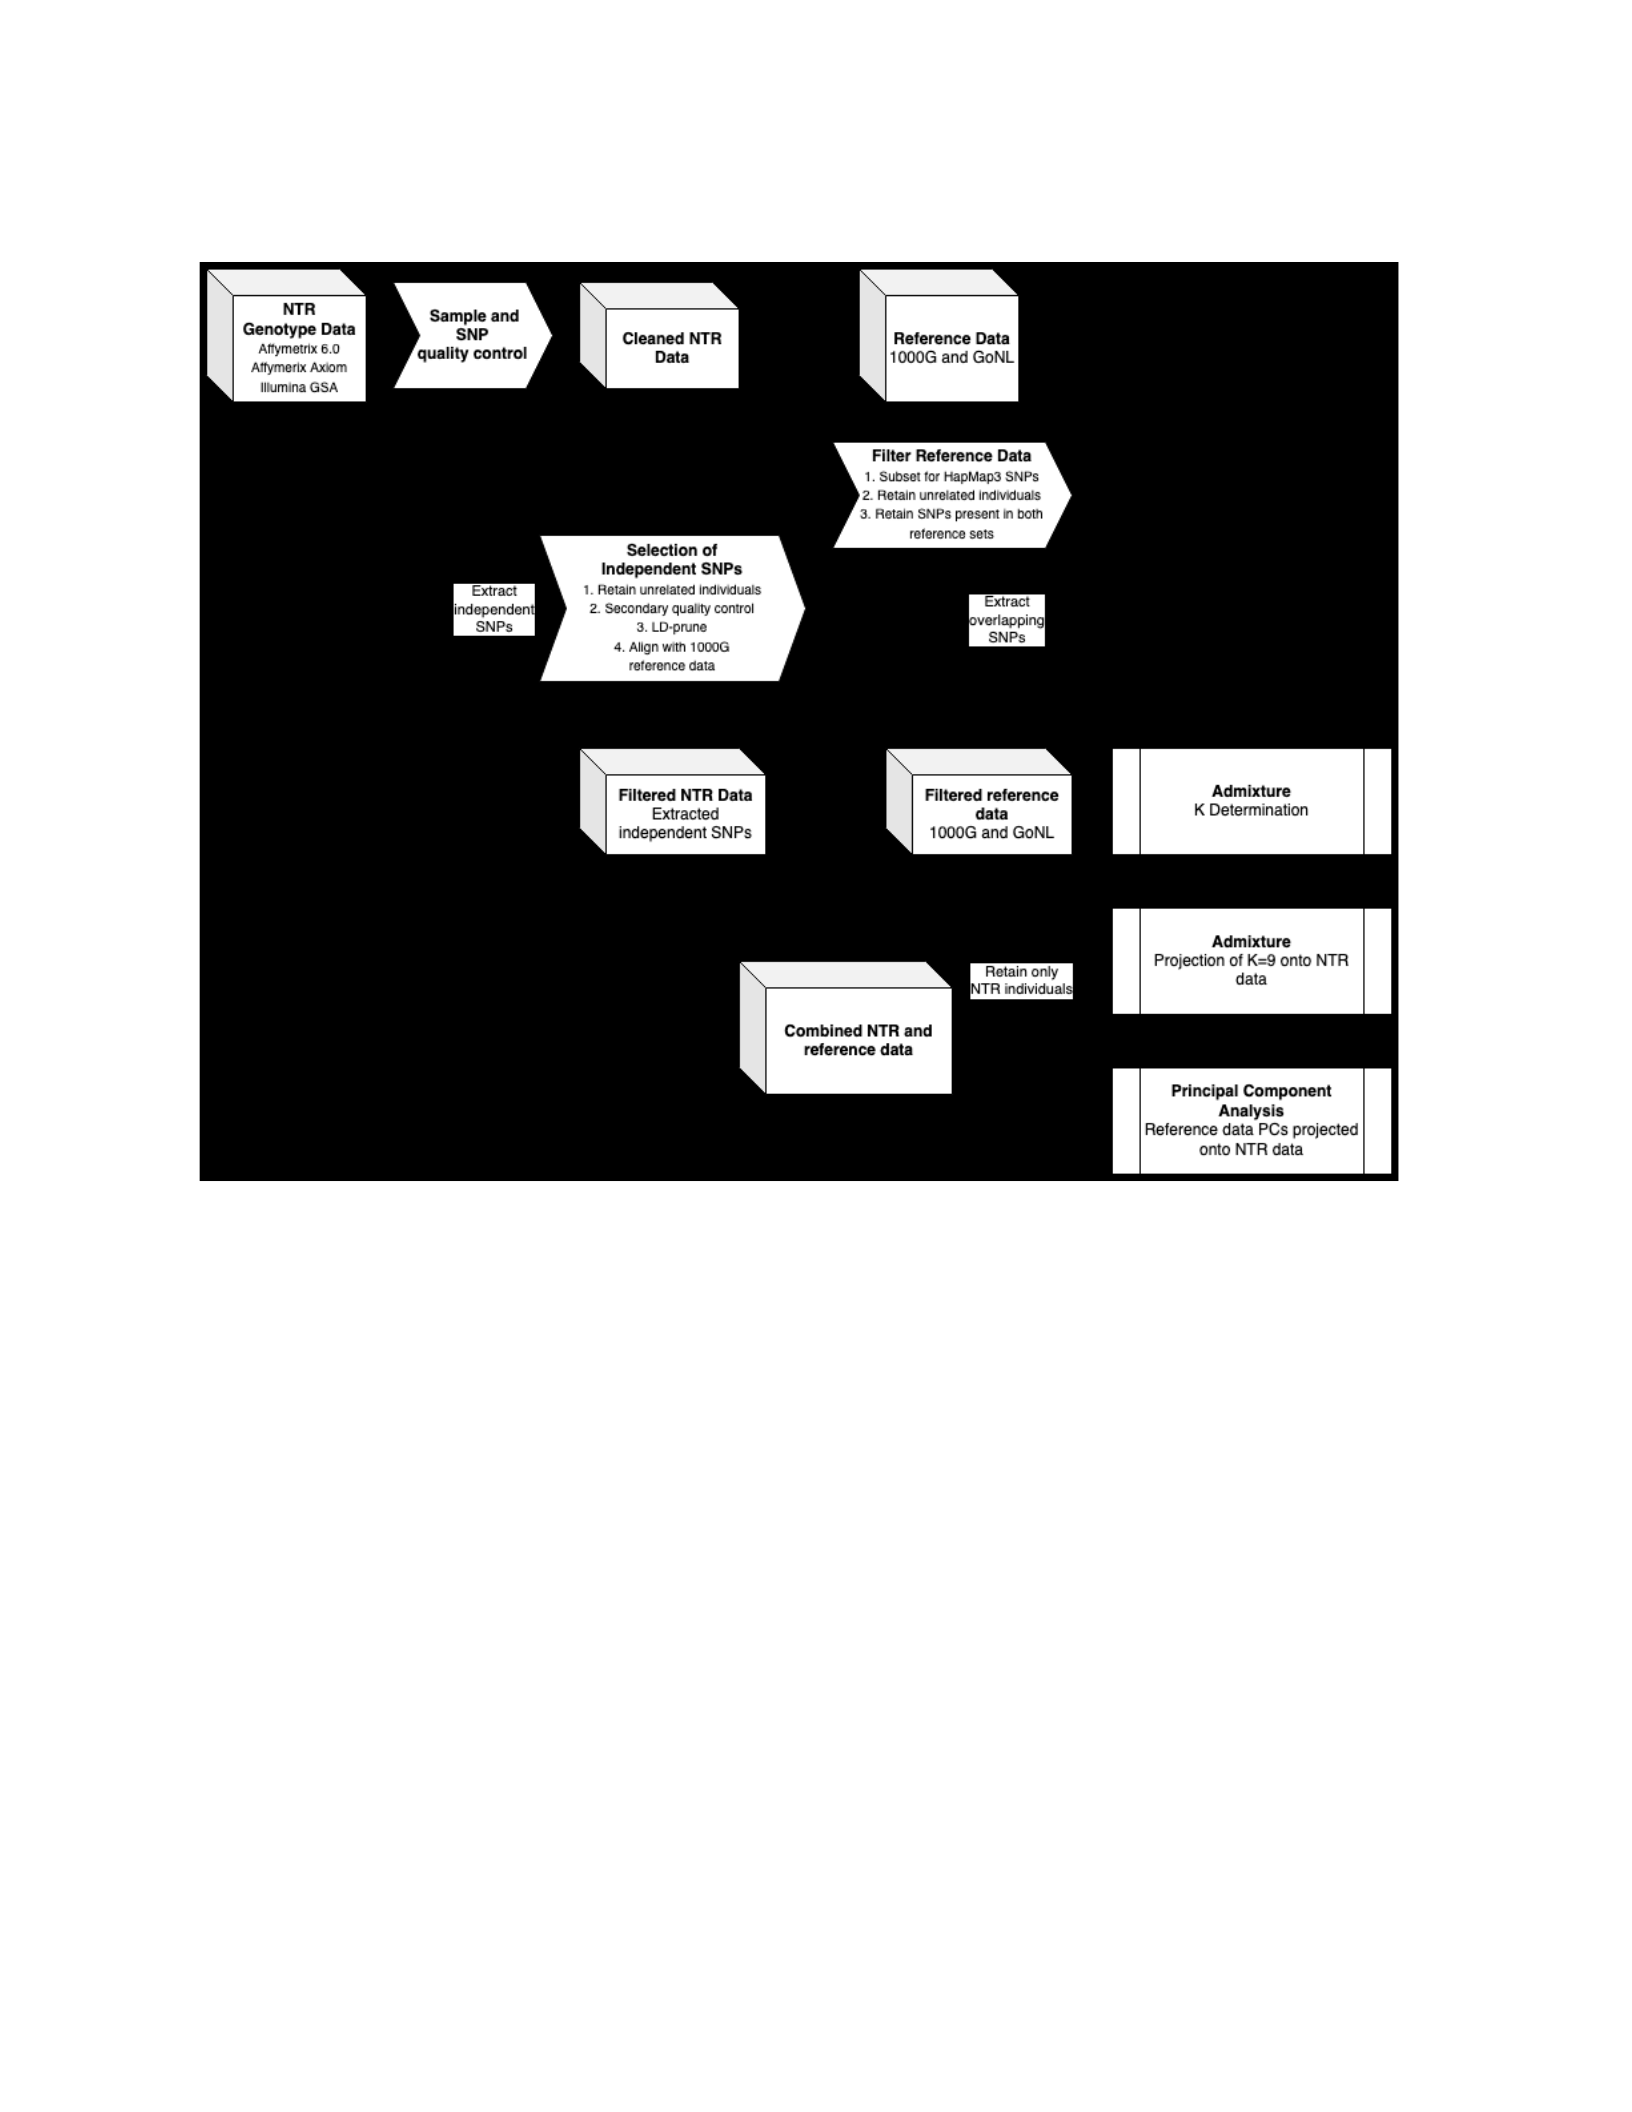
189
Figure 6.1 – Process flowchart of the analytical strategies employed in this study

190
6.3.1 Sample Selection and Genotyping
All individuals in the study are participants of the Netherlands Twin Register (NTR) (28,
29). The NTR recruits twins, higher-order multiples, and their family members, including
parents, siblings, and spouses. DNA from NTR participants was isolated using standard protocols
for obtaining high-quality DNA suitable for genome-wide SNP genotyping with highdensity
DNA microarrays (30). Individuals with genotype data obtained from the Affymetrix 6.0
(AFFY6 Nraw individuals=12779, Nraw variants=905422), Affymetrix Axiom-NTR (AXIOM Nraw
individuals=3606, Nraw variants=642716) (31), or Illumina GSA-NTR (ILLGSA Nraw individuals=14553,
Nraw variants=669322) (32) platforms were selected. All genotyping was performed at the Avera
Institute for Human Genetics (Sioux Falls, South Dakota) according to the manufacturer’s
protocol.
6.3.2 Dataset Curation
Three platform datasets were created with the backbone and custom content of each array
(AFFY6, AXIOM, ILLGSA). Sample and SNP quality control was done on each dataset
separately. In addition, a harmonized dataset (61,433 overlapping markers from all three
platforms) was created from the cleaned platform datasets since family members could be
genotyped on different arrays. The four datasets underwent the same analytical procedures.
6.3.3 Sample and SNP Quality Control
Samples were excluded if phenotypic sex did not match the genotypic sex (indicating
potential sample swap) (N=271; 0.88%), if the Plink heterozygosity F value was <-0.10 or >0.10

191
(N=292; 0.94%), or if the sample call rate was less than 90% (N=16; 0.05%). Within families,

