


Markov Chain Monte Carlo
and Gibbs Sampling
The fact of determining the distributions frequently necessitates the inclusion of strong variables
is a significant obstacle to the increasingly wider usage of Bayesian techniques. It could be quite
mathematically challenging, however numerous alternatives to tight application were presented
(reviewed bySmith 1991, Evans and Schwartz 1995, Tanner 1996). Here, we concentrate on
MarkovChain Monte Carlo (MCMC) techniques that aim to replicate straight pulls from an
intricate distribution. When one creates a Stochastic process by using the past data points to
produce the subsequent data points at arbitrary, MCMC techniques are given their name (as the
transition probabilities between sample values are only a function of the most recent sample
value).
Statistical significance has seen a substantial growth in proposal since it was discovered in the
early 1990s (Gelfand and Smith 1990) that one specific MCMC technique, the Gibbs sampler, is
quite broadly appropriate to a broad class of Bayesian difficulties. This involvement is projected
to keep growing for some further time. The Metropolis methodology (Metropolis and Ulam
1949, Metropolis et al. 1953), developed by researchers in an effort to calculate complicated
formulas by displaying them as aspirations for certain dispersion, then estimating this
presumption whilst also selecting measurements from that dispersion, is where MCMC
techniques got their start. Photogrammetry is where the Gibbs sampler (Geman and Geman
1984) got its start. So, it seems almost paradoxical that till very early, the strong equipment of
MCMC approaches had little to no influence on the discipline of numbers. Tanner (1996) and
Chapter 2 of Draker provide outstanding (and in-depth) discussions of MCMC approaches
(2000). Citations to further sources are provided in the individual portions as follows.
MONTE CARLO INTEGRATION
The inaugural Monte Carlo procedure had been a technique created by mathematicians to
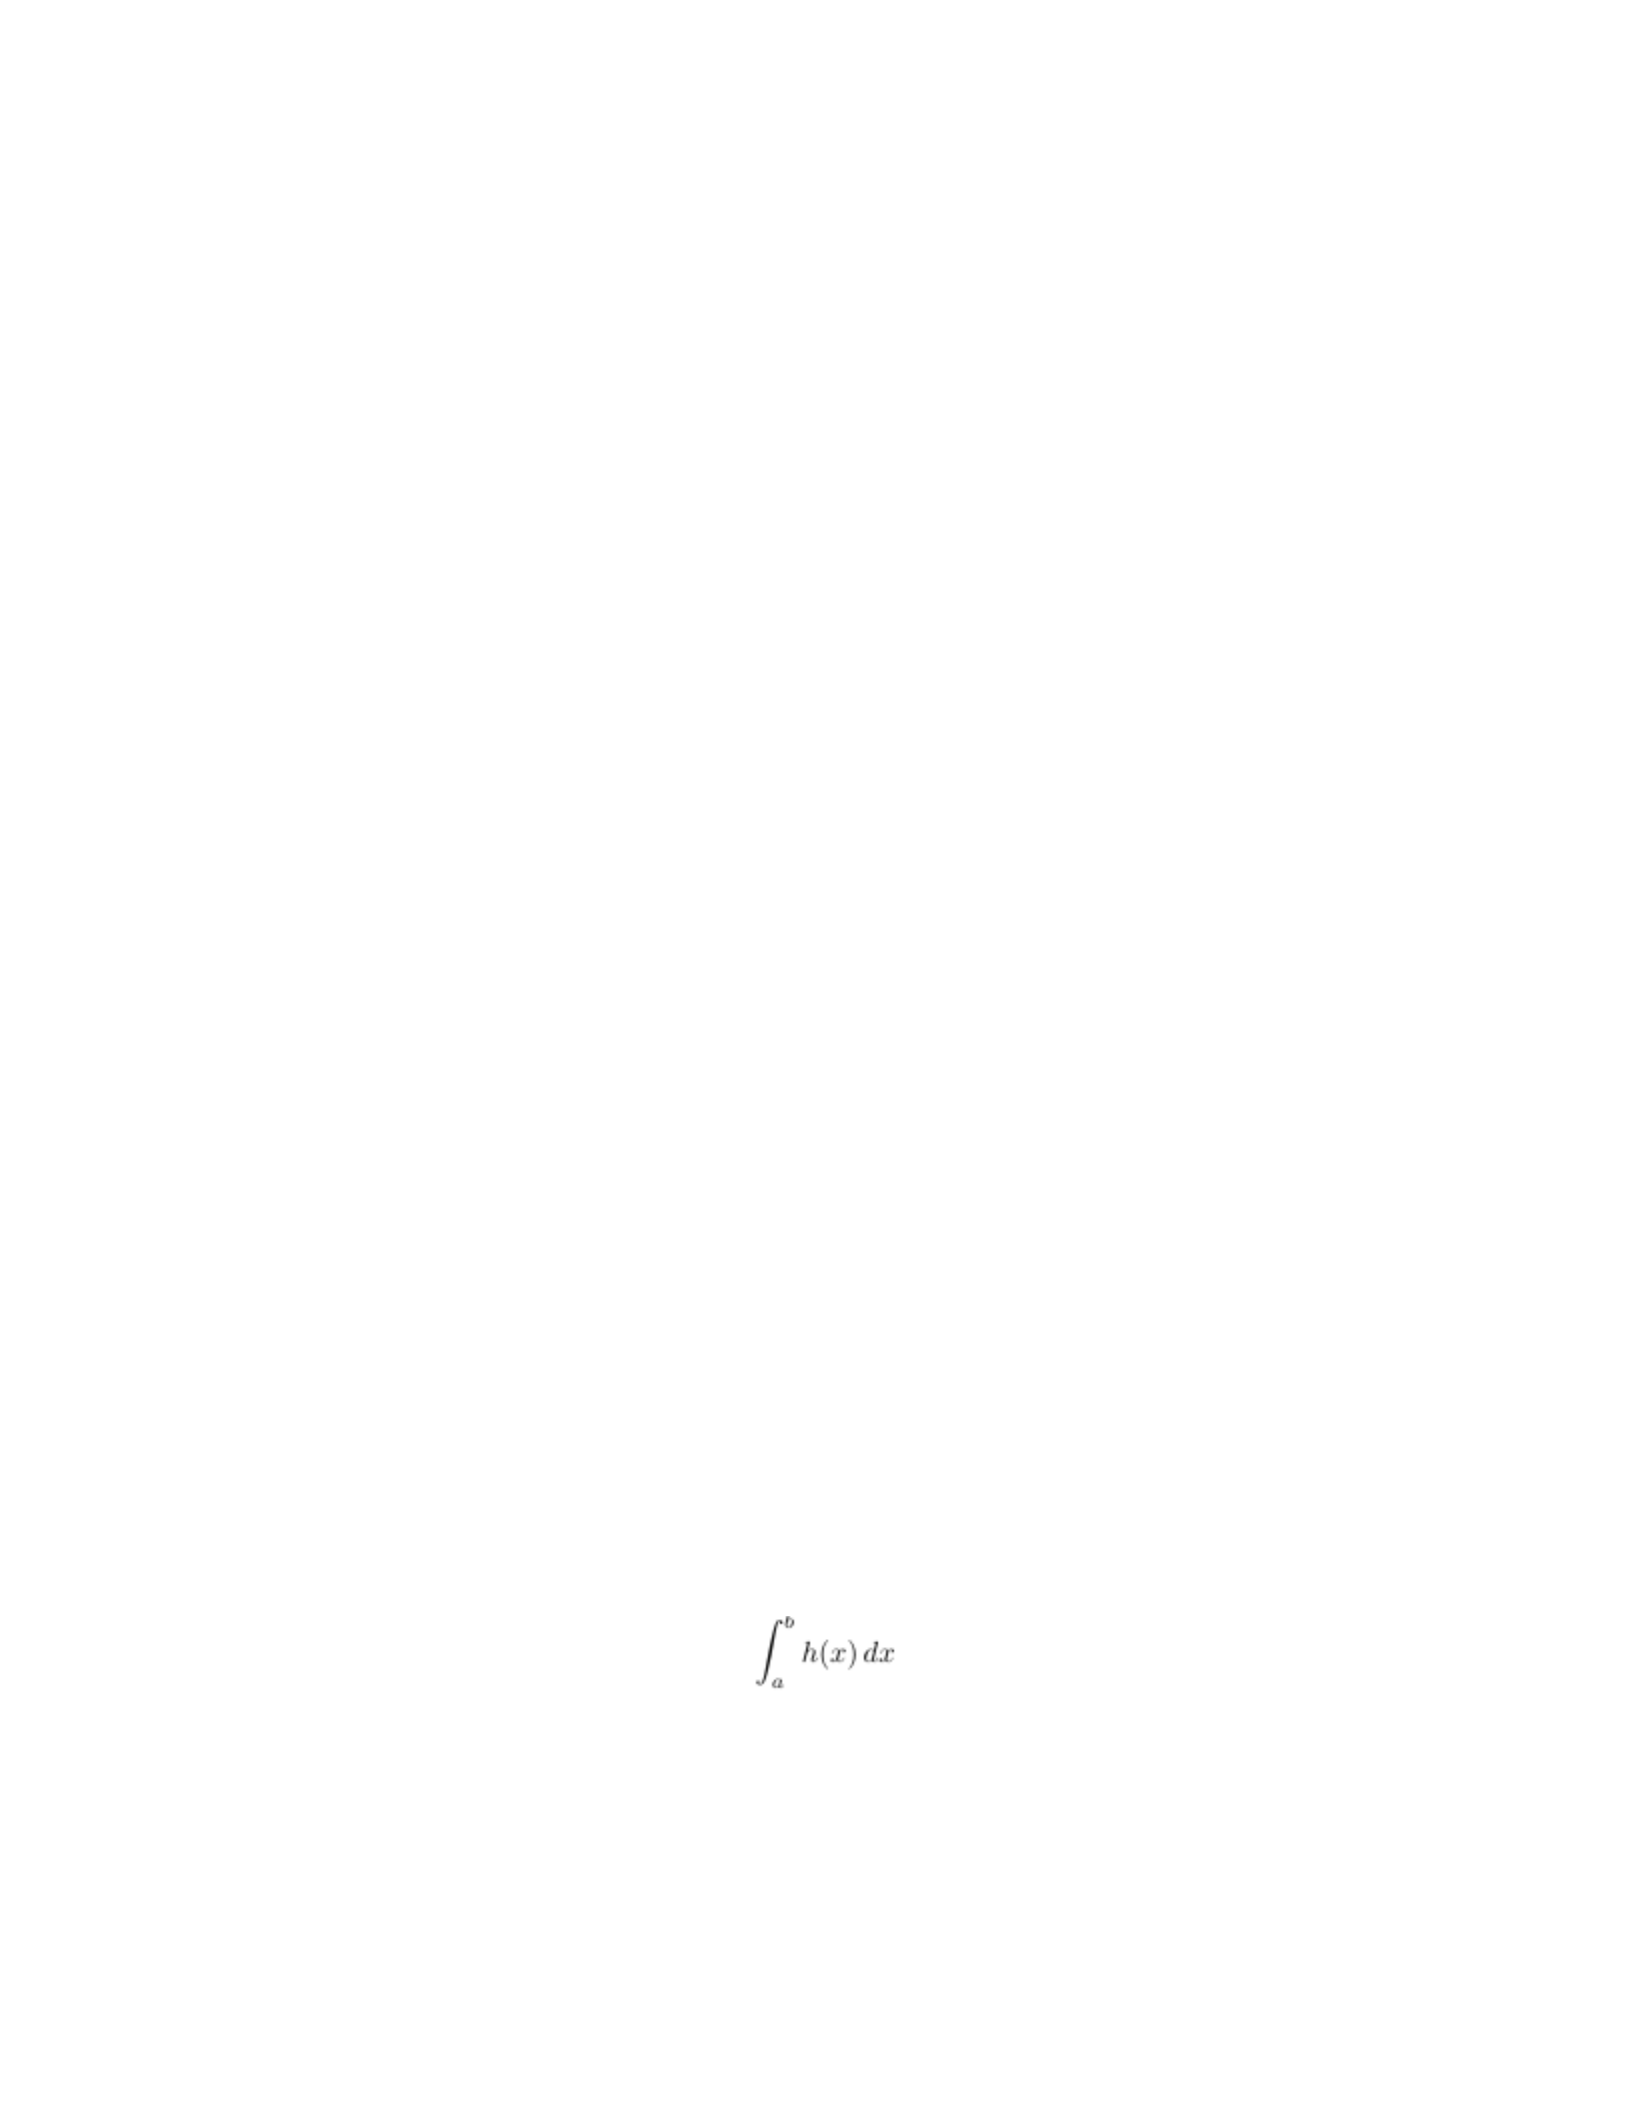
calculate formulas using pseudorandom creation. Let's say we want to calculate a complicated
summation.
A couple preliminary remarks on Time series were required while discussing the Megalopolis
method and the Gibbs tester. Let the state space be the range of feasible X values, and let Xt
signify the value of a stochastic process at time t. If the changeover chances among varying
parameters in the subspace rely only on the arbitrary variable's present state, then the binomial
distribution is a Kernel function.

Pr(Xt+1 =sj|X0=sk,···,X
t=s
i) = Pr(Xt+1 =sj|Xt=si
As the numerical value is unaffected by understanding of the frequencies of earlier states, just
one data regarding the previous necessary to forecast future outcomes for a Markov gaussian
distribution is its present state. A succession of stochastic processes (X0, X1, Xn) produced by a
Markov technique is referred to as a Markov chain. A given chain's transitioning chances (or the
transition kernel), P(i, j)=P(ij), indicating the likelihood that a function in phase space would
shift to state sj in a sequential manner, serve as the definition's most important definitions.
P(i, j)=P(i→j) = Pr(Xt+1 =sj|Xt=si)
As several publications specify P(i, j)=P(ji), we would frequently use the term P(ij)to suggest a
motion from it to j, thus we will use the arrow shorthand to prevent misunderstanding. Let πj(t) =
Pr(Xt=sj)
, then let (t) be the graph form of the mathematical model chances at step t. signify the likelihood
that the loop is in state J at time t. A beginning component is used to start the chain (0). With the
exception of one factor of 1, which corresponds to the aim of preparing in that specific state, all
the components of (0) are frequently zero. The outcomes are dispersed throughout the potential
state space as the tradition continues.
The Chapman-Kolmogorov equation, essentially adds the probabilities of reaching a certain
phase at the previous point and the probabilities of transitioning from that phase into state si,
provides the chance that the network will have measured value si at time (or step) t+1.
πi(t+ 1) = Pr(Xt+1 =si)
=X
k
Pr(Xt+1 =si|Xt=sk)·Pr(Xt=sk)
=X
k
P(k→i)πk(t)=X
k
P(k, i)πk(t
The Chapman-Kolmogorov equation iterates repeatedly to describe the chain's evolution. The
Chapman-Kolmogorov equations can be expressed in matrix form as follows more succinctly.
The probability transition matrix definition P(i, j), the probability of changing from state it to
state j, is the matrix's I jth member. (Notice that PjP(i, j)=PjP(ij)=1 suggests that the rows add to
one.) resulting in the Chapman-Kolmogorov equation.


