


c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c 1
DAT 205
Final Report
August 8, 2022
Executive Summary

c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c 2
According to the U.S. Natural Hazard Statistics, weather-related hazards are causing serious damages, fatalities, and injuries. The
present study revolves around the storm causalities that have frequently occurred in the United States of America (USA). In this
project, the researcher has tried to evaluate a wide range of collected data from the National Oceanic and Atmospheric
Administration (NOAA) and the National Weather Service (NWS) that are associated with storm causalities in the USA. It has been
found that there are some key characteristics that cause fatalities and make a storm deadly, which is considered the main aim of the
researcher to focus on. This research will give emphasis on predicting the likelihood that gives rise to any kind of storm causalities.
The present studied project will also give emphasis on the major primary features that are responsible for causing storm causalities in
the USA so that better outcomes could be generated. For the identification of the major primary features, this project will further
focus on the five predictive models. These models will help the research project to get an insight into the deadly storm characteristics
in the USA in a detailed manner. Here, the most important role is played by the creation of an accurate and reliable model, which is
helpful in limiting the deadly storm causalities as well as increasing the warning signs effectiveness in the USA region. In the present
research project, a detailed analysis has been conducted to provide better visualization of the scenario in the USA. Further, the
project scope, geospatial map, background of the research and other important points have been elaborated to identify the research
area and understand the rising risk of the storm in the USA. Apart from that, this project has also highlighted a time series gap in the
deadly storms to analyze the exact time of the year that is taking place in the USA.

c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c 3
Table of Contents
Project Scope ............................................................................................................................................................................................. 5
Problem Description ............................................................................................................................................................................. 5
c c c Business Understanding....................................................................................................................................................................... 5
Organization .......................................................................................................................................................................................... 6
Stakeholders ........................................................................................................................................................................................... 6
c c c Define Business Area ........................................................................................................................................................................... 6
Business Objectives ............................................................................................................................................................................... 7
Business Success Criteria .................................................................................................................................................................. 7 c
c c c Background ........................................................................................................................................................................................... 8
Research ................................................................................................................................................................................................. 8
Gaps in this Problem Resolution ......................................................................................................................................................... 8
c c c Proposed Project .................................................................................................................................................................................. 9
Key Performance Indicators (KPI) ..................................................................................................................................................... 9
Project Insights of the Data Analysis ................................................................................................................................................ 9 c
c c c Project Milestones .............................................................................................................................................................................. 10
Data Set Description ............................................................................................................................................................................... 13
c c c High-Level Data Diagram ................................................................................................................................................................. 15
c c c Data Definition/Data Profile ............................................................................................................................................................. 17
Data Preparation/Cleansing/Transformation ...................................................................................................................................... 20
Data Preparation ............................................................................................................................................................................. 20
Data Cleansing ................................................................................................................................................................................. 21
Data Transformation ...................................................................................................................................................................... 22

c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c 4
Data Analysis ................................................................................................................................................................................... 25
Data Visualization ................................................................................................................................................................................... 26
Data Visualization 1 – Geospatial Analysis .................................................................................................................................. 27
Data Visualization 2 – Time Series Graph ................................................................................................................................... 29
Word Cloud ...................................................................................................................................................................................... 32
Proposed Visualizations .................................................................................................................................................................. 33
Predictive Models .................................................................................................................................................................................... 35
Predictive Model 1 - Logistical Regression Model ..................................................................................................................... 35
Predictive Model 2 - Neural Networks Model ............................................................................................................................ 37
Predictive Model 3 - Support Vector Machine (SVM) Model .................................................................................................. 40
Predictive Model Review ................................................................................................................................................................ 45
Final Results ............................................................................................................................................................................................ 47
Analysis Justification ...................................................................................................................................................................... 47
Findings ............................................................................................................................................................................................ 48
Review of Success ............................................................................................................................................................................ 49
Recommendations for Future Analysis ......................................................................................................................................... 51
References ................................................................................................................................................................................................ 52

c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c 5
Project Scope
Problem Description
This project has aimed to critically examine various data sets that had detailed information about the deadly storms in the
United States of America (USA). Some reliable sources like the National Oceanic and Atmospheric Administration (NOAA) and the
National Weather Service (NWS) have been involved in gathering all the important information related to the storm in the USA. This
project has given a major focus on the deadly storm that is frequently occurring in the nation. It has given the focus on 2017's
recorded data sets related to storms that have taken place in the USA. This data set is helpful in providing detailed information
related to the total number of injuries, storm date, storm type, location, the total number of fatalities, and many other things.
Business Understanding
In the present scenario, the deadly storms are becoming the main concern for the human beings who are residing in the nation.
These deadly storms can cause serious havoc and damage by affecting the lives of the people along with causing loss of property as
well as lives. It has been found that the USA is the common place where storms usually occur on a yearly basis and create severe
damages to the property and human life in the nation. Here, it has been identified that the high level of unpredictability about the
changing weather event is considered to increase complexities related to storms.

c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c 6
Organization
In the present project study, the two agencies have been selected to collect information related to deadly storm conditions in
the USA. Here, NWS is a well-known government agency in the USA that is responsible for providing and managing different kinds
of hazardous weather conditions data, including weather forecasts, storms, and many others. On the other hand, the NOAA is
popularly known as a scientific agency in the USA that gives emphasis on the atmospheric conditions and the ocean conditions in a
particular geographical location. This agency aims to predict weather events by preserving the marine ecosystem and the coastal
regions (Storm events database. National Centers for Environmental Information, 2021).
Stakeholders
There are various stakeholders who have been associated with the deadly storm issues, including meteorologists and
researchers who work in the NOAA and the NWS, along with the common public who are living in the deadly storm areas of the
USA. If this research project gets a positive outcome, then it would be a great success for the scientific research team and helpful for
the researcher to predict the storms that are causing fatalities. There are other stakeholders like the Coast Guards, the U.S. National
Guard, regional agencies, and others that can be also beneficial from this project.
Define Business Area
Meteorology is considered the specific study of Earth's atmosphere. This study also focuses on the changes that take place in the

c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c 7
temperatures and moisture patterns that cause changes in the weather conditions (Exline et al., 2006). In the present scenario, a
cardinal role is played by severe weather events like deadly storms. Here, the study of meteorology plays an integral role in
understanding the weather elements like wind, surface, temperature, and others at a comprehensive level (Burt, 2012).
Business Objectives
The main objective of the present research project is to identify the possibilities associated with the deadly storms that are
raising causalities in the nation. When the five important features that are responsible for causing a deadly storm are identified as one
of the major objectives of the project, this objective could be achieved easily in an effective manner. This project is ultimately
supporting reliable and accurate predictions about the weather condition along with reducing the storm causalities in the USA. In
other words, it can be said that the present studied research would contribute sincerely to curtailing or reducing storm causalities in
the USA.
Business Success Criteria
The evaluation of the project's success will be based on the reliable and accurate predictive model's performance. If the five
major features associated with the storm's causalities have been identified in the project, then it can be considered to be a great
success for the project. This project will not only identify these variables but also ensures how these variables are making deadly
natural storms in the region.

c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c 8
Background
For the research purpose, the data will be collected from the NOAA and the NWS, which has documented the storm events
monthly. This collected data is used extensively for making predictions and forecasts of weather events. However, it has been
identified that the accurate prediction of the weather condition does not provide any guarantee over the limitation of storm
causalities. Along with the storm prediction, it is also important to control the storm fatalities with better preparedness.
Research
The database of the NOAA and the NWS has been used in many similar research studies and works. Here, it has been
identified that one of the common issues is false tornado warnings that are creating unnecessary tension and panic situation among
the public. As per the NWS report, the responses usually get affected due to the inaccurate or false alarms associated with tornadoes.
It has been found that the vulnerability and risks increase with the rising negative false alarms. This is also affecting the public
responsiveness to the actual storm strikes (NOAA's National Weather Service, 2015).
Gaps in this Problem Resolution
In this problem resolution project, the main gap is related to the prediction of whether a storm results in causalities or not or
whether it is deadly or not. Previous research studies have mentioned that prediction or forecast report about the storm is not helpful
in limiting the fatalities. However, the prediction about the intensity of the storms could be helpful in encouraging responsible
behavior among the public as well as could raise public awareness regarding the intensity of the storms.

c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c 9
Proposed Project
The proposed project related to storm causalities in the USA is aligned with my personal interest and passion in the field of
natural sciences. As I believe that taking certain steps to curtain damages related to storm events is helpful, I have shifted my
attention to going into detail to understand the abnormal weather conditions. This project has grabbed more attention as the USA
region has very frequent storm events every year. The success of this project is very important as thousands of U.S. citizens could be
highly benefited and reduce their vulnerability to the storm events.
Key Performance Indicators (KPI)
According to Velimirovic, Aktuelno, and Rade, the key performance indicators (KPI) play an important role in the project
work as the variables (Velimirović et al., 2011). In the present project, the five primary features are included in the key performance
indicators elements to understand the deadly storm. The key performance indicators that are included in the present recent project are
the path of the storm, the specific type of storm, the specific time for the storm in the year, the residents’ location during the erratic
weather behavior, and the intensity of the extreme weather elements or wind that cause fatalities.
Project Insights of the Data Analysis
In this project, it is projected that it would be insightful as well as useful information to address the issues associated with
storm casualties in the USA. During the analysis process, more value could be given to the use of different predictive models as it
c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c 10
would be helpful to determine the factors that are causing deaths at the time of storm events. In the nation, it becomes a serious
concern now which factor is causing the rise to a high number of storm events as well as causing few numbers of storm deaths. To
address the deadly storm issue, I would like to bring some changes in the research to a cutoff threshold.
Project Milestones
First, I have already submitted the first project assignment. There are several milestones that have been accomplished in the
project work. One of the important milestones that have been identified in the research project is defining the initial scope of the
research study. In this research project, I have also chosen specific database related to storm casualties in the USA from the trusted
agencies that would be very helpful during the analysis process. After that, I have presented the proposal of the research project to
the team members and received some of the valuable feedback so that the project work could be improved in the future. The whole
process of the research work was smooth for me as I had already identified the improvement areas. The received feedbacks were very
helpful in making some changes in the project work.
Completion History
Week 1
Completed weekly reading
Week 2
Completed Assignment 1 and selected the database
Week 3
Completed weekly readings for Weeks 3 and 4
Week 4
Assignment 2 was completed.
c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c 11
Week 5
Weekly reading for Week 5 was completed
Week 6
Presentation 1 completed
Week 7
Completed Assignment 3 and data preparation
Week 8
Finished Presentation 2
Week 9
Worked effectively on the predictive models
Week 10
Assignment 5 completed
Week 11
Began to work on the report of Assignment 6
Week 12
Finished Assignment 6 report
Lessons Learned
Week 1
I learned how to address complex issues by
using an analytical approach.
Week 2
I have understood CRISP-DM proves to get
familiarity with it at a comprehensive level.
Week 3
Received more comments and feedback, so I
started working on my next assignment.
c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c 12
Week 4
I read all the materials critically that has
related to the project work.
Week 5
I started working on my presentation skills
after finishing the week’s reading.
Week 6
Received feedback and comments on
presentation and Assignment 2 and further
worked on it to improve the project work.
Week 7
Analyzed the detailed issues related to the
data quality.
Week 8
Visualization creation has helped a lot to get
the better outcome.
Week 9
Revised predictive models’ concepts.
Week 10
Created highly accurate models with the help
of correlated variables.
Week 11
Identified that fatality database variables is
not helpful in the model.
c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c 13
Week 12
Learned how to manage correlated variables
in data.
Data Set Description
In this project, the selected databases are from the National Oceanic and Atmospheric Administration (NOAA) and National
Weather Service (NWS). These databases are very helpful to get deeper insight of the deadly storms in the United States of America
(USA). Here, the collected data from NWS will be helpful to provide and manage different kinds of hazardous weather conditions
data including weather forecasts, storms, and many others. On the other hand, the collected data from NOAA will be helpful to
understand the atmospheric conditions and the ocean conditions in the geographical location as well as aims to predict the weather
events by preserving the marine ecosystem and the coastal regions (Storm events database. National Centers for Environmental
Information, 2021).
The collected data from NWS helps to understand the severity and intensity of the storm, which contains 56,921 cases and 51
variables in the region (NOAA's National Weather Service, 2022). On the other hand, the collected primary dataset from NOAA has
the presence of the variables and cases to understand the weather condition. In the project analysis, the first target variable is
causalities that are resulting to direct or indirect death to the public. These variables have aims to identify whether the storm causing
fatalities or not. Here, the value of yes would be considered to occur death and the value of no would explain no fatalities are

c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c 14
produced by the storm. With the use of R, the data set related to storm was analyzed. In this research work, it has been identified that
many variables represent missing values. For instance, the magnitude has missing values of 23,000 and category has missing value of
56,000. These missing values are represented in many variables because they are used for describing a single type of storm like a
flood or hurricane.
In the dataset, there were some of the identified issues where one is related to the highly skewed number of deaths as well as
injuries due to storms. It has been identified that the dataset contains nearly 56,000 storm events where 346 direct injuries and 278
direct deaths have been found. Apart from this, I have also identified that the hailstorm and thunderstorms are very common in the
nation because the database states that each of the hazardous weather events consist of nearly 10,000 cases.
In the second database, the collected information about the storm fatalities was from 2017. This database has given emphasis
on the lost lives of the vulnerable people who are in the nation. This research study is helpful to evaluate the important factors that
are causing storm causalities in the region. The database includes some of the specific variables like the age of the victim, the time
and day of death, the death location like vehicle, house etc., and the gender. This dataset is consisting of 775 cases and 11 variables,
which shows that it is smaller data set as compared to the first data set. However, this data set is smaller as it shows very fewer death
cases as compared to a total number of storms in the USA.
After that, the third dataset gives focus on the individual episodes of the storms as well as on the location. It has generated ore
values as it has given focus on the direction of the storm severity as well as the overall impact of the storm range. It has been found

c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c 15
that this dataset is consisting of 43,579 cases and 11 variables. The included variables in this data base are the town where it
occurred, the range of the storm, the direction of the storm, and others. In this database, there were no missing variables.
High-Level Data Diagram
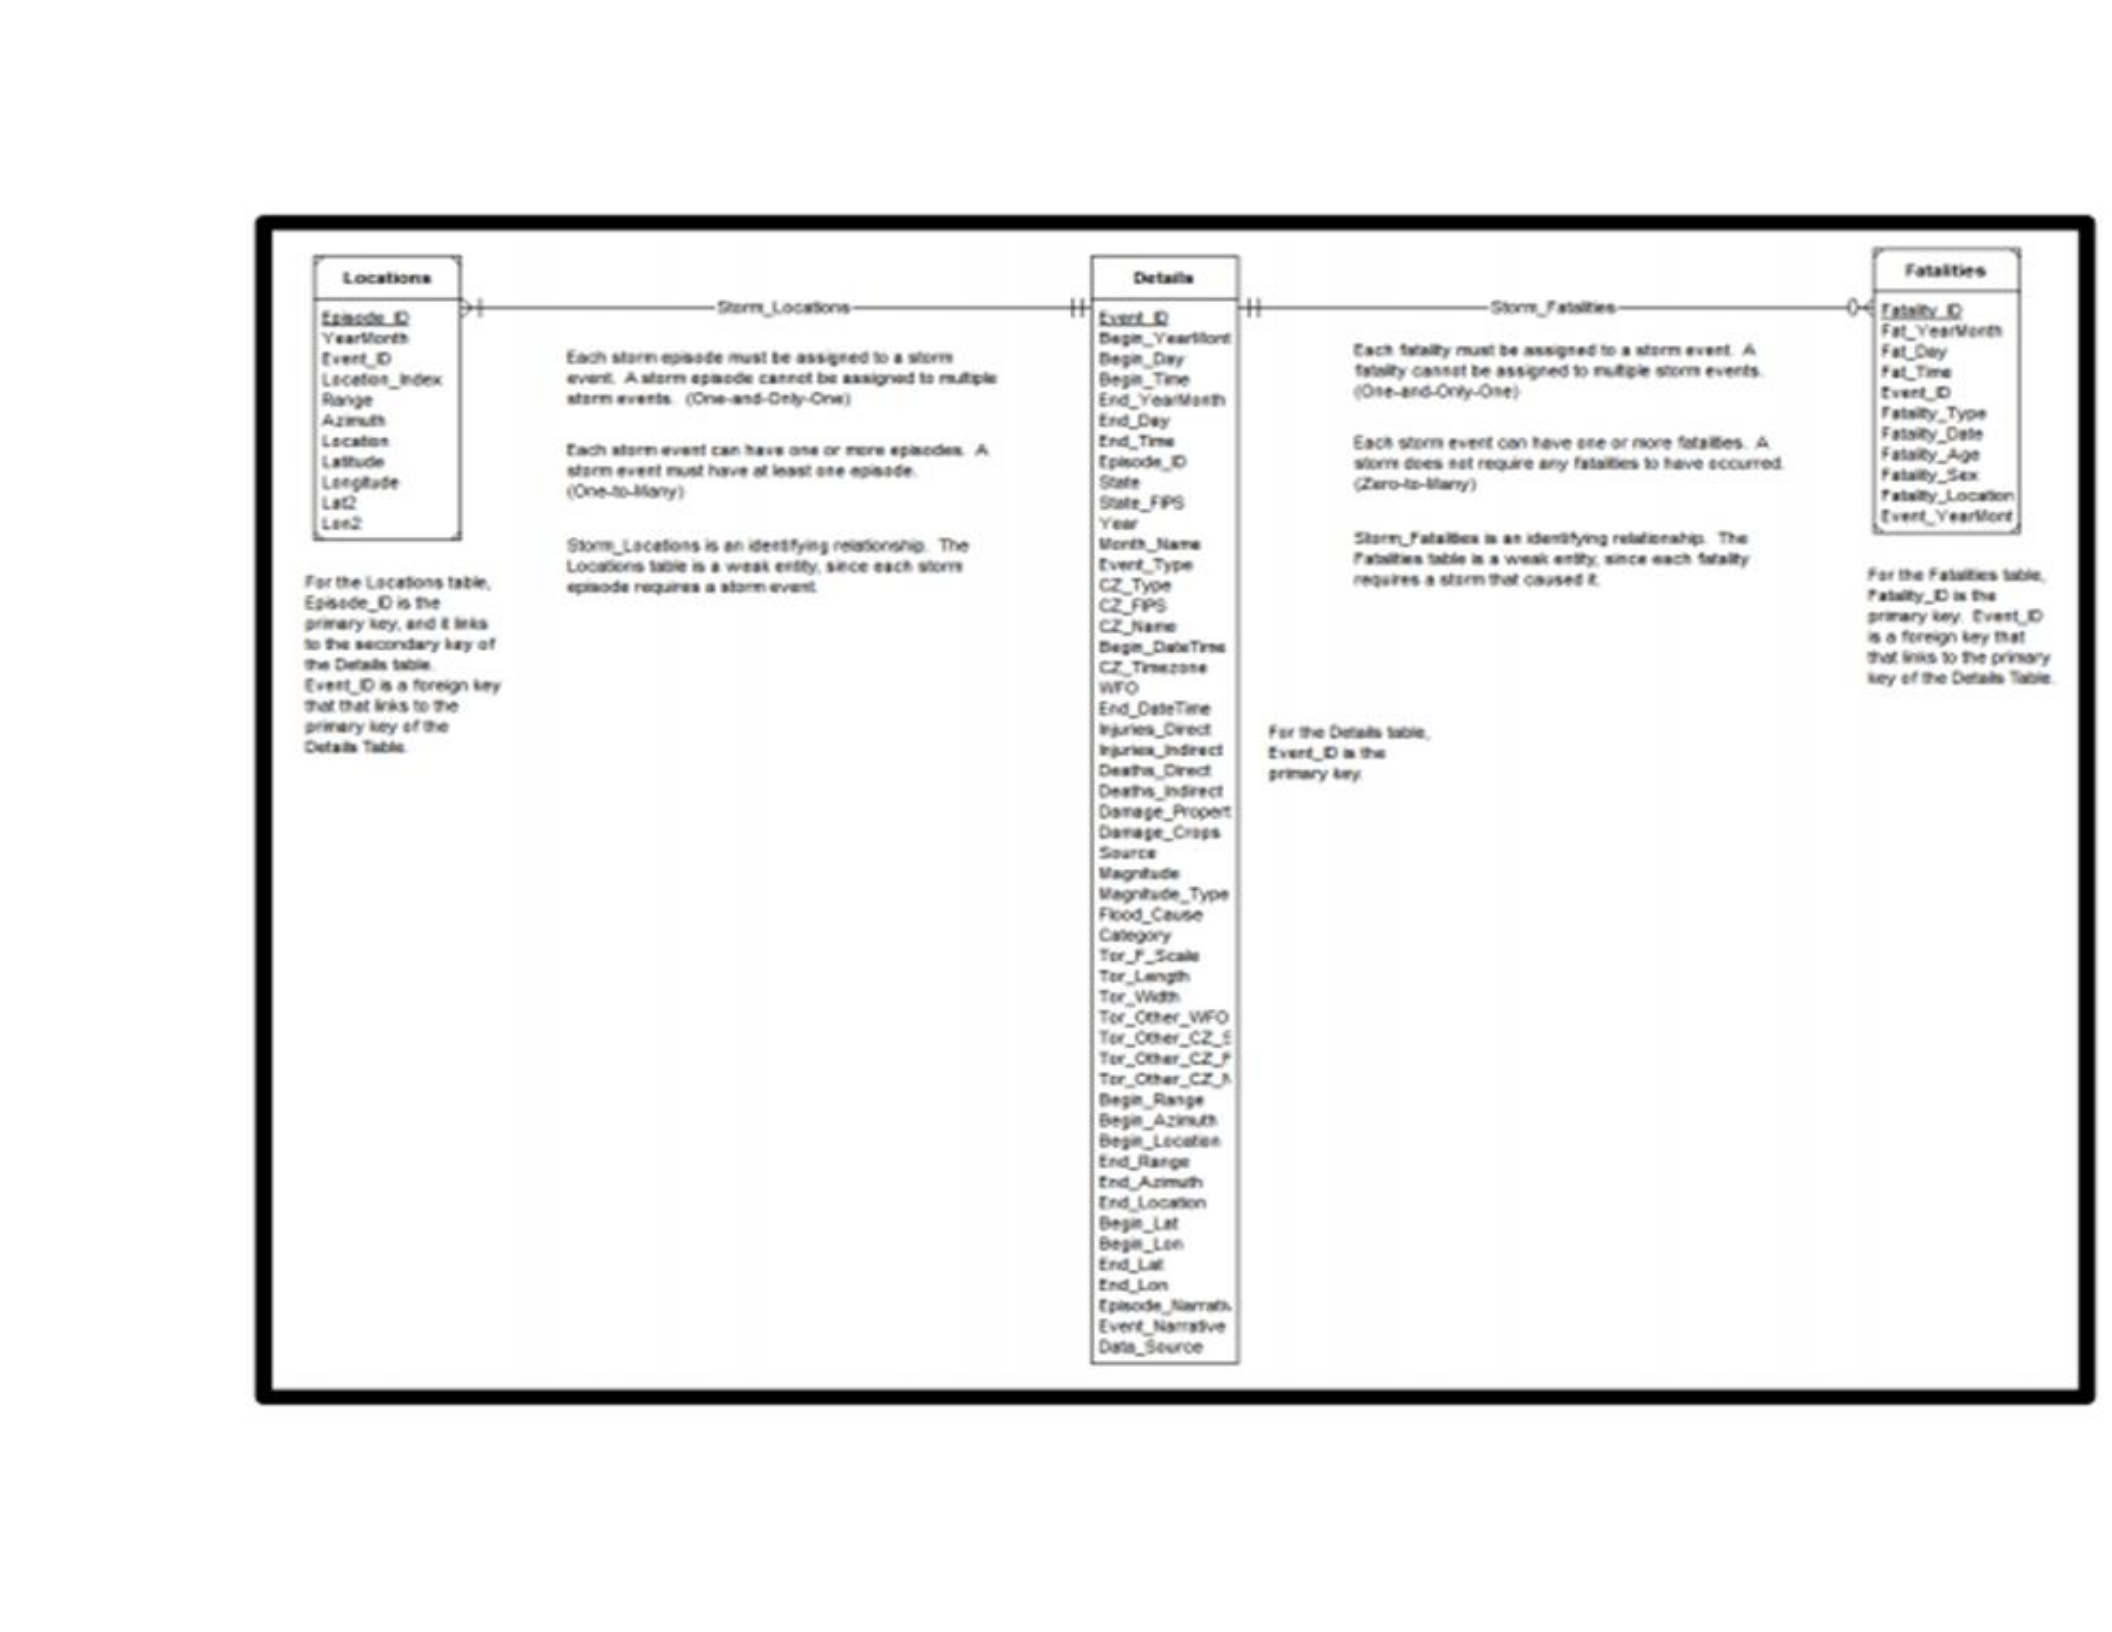
The association between the data sets and data can be seen in the visual representation. Moreover, the variables namely
fatalities, location, details, and others have been highlighted through the Entity-Relationship diagram. Here, the ‘Event ID’ acts are
considered to connect the entire database together so that it could provide better understanding over the project work. In this project,
the Event ID is extensively used here to link with the “details” as foreign keys.
Further, the details associated with the deaths caused by storms can be witnessed in the fatalities table. Here, it can be said
that every death or fatality could be result to a single storm event in the USA. Moreover, it has been found that multiple fatalities can
be raised from a single storm as well as it can also cause a single death. Even, there are also possibilities that the storm could not give
rise to fatalities at all. Apart from that, the location table shows 11 variables where the important key is episode I.D.
Darage
Proper
c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c 16
c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c 17
Data Definition/Data Profile
In this research project, the NWS data description has been provided to examine the variable. A table has been created here
by using the available data that has highlighted the description of the variables, data type, and much other information. Here, the
researcher has improved the work quality by removing the redundant variables. This table highlights a deeper insight of the research
project related to storm data.
However, I have found that many important data have been missed in this data. Approximately 30,000 magnitude type
variables and 56,000 lengths of the tornado values of variable are missing. In addition, nearly 17,000 values of the ending location
and beginning range of the storm are missing. In the data cleansing section, the researcher will give emphasis on the details relating
to missing data that could be taken care of in the further assignment work. Moreover, it has been identified that the fatalities and
location data set have very less issues associated with the data quality.
Variable
Definition
Data Type
Quality Issues
Event Type
The storm type
Character
Na
c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c 18
Direct Injuries
The storm caused
total number of
direct injuries
Integer
Highly skewed data
Indirect Injuries
The storm caused
total number of
indirect injuries
Integer
Highly skewed data
Direct Deaths
The storm caused
deaths directly
Integer
Highly skewed data
Indirect Deaths
The storm caused
deaths indirectly
Integer
Highly skewed data
Event Type
The hazardous
weather event or
type of storm event
Character
None
c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c 19
Begin Date/ Time
The time of the
storm and starting
date
Date
Redundant
variables
Damaged property
The storm caused
property damage in
U.S. dollars
Character
Numeric data not
presented
Damaged crop
The storm caused
crop damage in
U.S. dollars
Character
Numeric data not
presented

c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c 20
Data Preparation/Cleansing/Transformation
After collecting the data relating to U.S. storms, the data will undergo several processes so that it can help to achieve the project
objectives. The main processes that have been carried out on the data sets are data preparation, data cleansing, data
transformation and data analysis. The specific data set used in the project are storm events database from NWS, storm casualties
in 2017 and details on location and independent storm episodes.
Data Preparation
Data preparation refers to the manipulation of raw data so that it can be transformed prior to processing and analysis. In the
research context R tool has been used for the data preparation activity. R is a useful framework that helps to conduct operations
relating to the creation of features and handling of missing values. However, along with R, SAS Enterprise Miner will also be
utilized for performing specific data preparation steps. It has been chosen as another important tool because of the user-friendly
interface that supports efficient calculations on diverse models. With the help of the tools, it will be possible to tackle outliers,
transforming the variables and categorizing the data. However, it might adversely affect the model’s accuracy.
During the data preparation, firstly, data will be imported from the three datasets. Then several packages will be used such as
‘SnowballC,’ ‘wordcloud,’ and ‘tm’ in the text mining area for analysis purpose. Once the initialization of data is done, data

c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c 21
cleansing activity will be initiated. After data cleansing the datasets will be fused using the R tool. Event ID will be used for
interlinking the databases with one another. After the merging is complete, SAS Enterprise Miner will be used for importing the
merged data and preparing data for implementation of the model. The tool will also be used for handling variable skewness prior
to building of the predictive models. Even though there are 57,000 rows in the storm events database, only 387 rows represent
direct or indirect fatalities. Thus, the ideal cutoff threshold for optimizing sensitivity is 0.0068.
The text mining analysis called the ‘bag-of-tokens’ analysis will be performed for evaluating texts that have been used to
describe deadly storms. Re will be used for text mining and preprocessing purposes as it is useful when it comes to cleaning
texts and evaluating word frequencies. A corpus will be developed encompassing event narratives relating to storms with
fatalities.
Data Cleansing
For the data cleansing activity, R will be used as the chief tool. The first step in data cleansing involves handling missing values.
Even though there are 57,000 rows in the storm details dataset, most variables are missing. For instance, the starting and ending
ranges as well as location have around 17,000 missing data cases. The main reason for the missing variables is that they refer to
specific kinds of storms only. For example, cause of flood is applicable only for floods, whereas length of tornado is relevant
only for tornadoes.

c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c 22
For handling missing variables, I will omit a variable from analysis if it has over 20,000 missing cases. If fewer cases are
missing, then appropriate action will be taken based on whether the variable is numeric in nature or categorical. Based on the
investigation of the database, in 17,566 rows there are missing categorical variables. They have been removed from the data. In
case they would have been numerical variables then the missing values would be replaced using the mean. Some of the key
exceptions to the applied approach include latitude, longitude, and beginning as well as ending ranges. They are exceptional
since they are numeric. In the casualties’ dataset, two variables are missing. The victim’s age has 104 missing cases and the
victim’s gender has 68 missing values. As gender is categorical, I will remove the entire rows. Out of a total of 775 casualties’
case, the missing value is small so I will replace them with the mean.
There are several variables containing outliers. Some of the most common ones are direct and indirect deaths, damage to
property, etc. For example, a specific storm caused around 500 indirect injuries whereas most storms contributed to 0 injuries. In
fatalities database there are no outliers, whereas in the location dataset there are outliers. For handling outliers, a replacement
value will be computed using SAS Enterprise Miner which will be 3 standard deviations from the mean. Redundant variables
such as state number will not be considered for data analysis.
Data Transformation
For the data analysis purpose two features will be created. The first is the target variable i.e., casualties. It basically highlights
whether a storm leads to direct or indirect fatalities or not. As the ultimate goal is not to make predictions pertaining to the

c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c 23
number of deaths from a specific storm but to ascertain whether a storm will lead to deaths or not, the specific feature is highly
critical. It can help in the identification of life-threatening storms, irrespective of direct or indirect deaths. It is a binary
categorical variable that has values in ‘yes’ or ‘no.’ This feature will be created using the R tool. ‘Yes’, will be allocated in case
the value of direct or indirect deaths is greater than 0. If the condition is not fulfilled, ‘no’ will be assigned. As the variable is
likely to be skewed, it will be handled by modifying the cutoff threshold for enhancing the model’s sensitivity.
The second feature that will be created is ‘injuries.’ The R tool will be used for developing it. Even though the second variable
is quite similar to the target variable, it will showcase whether a storm to any injuries or not. This variable has been chosen since
it can help to make comprehensive comparisons with the target variable. It is expected that there exists a strong association
between casualties and injuries. However, it will not come as a surprise if a storm leads to several injuries but no casualties
(Centers for Disease Control and Prevention, 2022). It is also a binary categorical variable where ‘yes’ or ‘no’ values will be
assigned. If a storm leads to direct or indirect injuries, ‘yes’ will be assigned, otherwise ‘no’ will be assigned. Initially, the
variable is likely to be highly skewed. It will be resolved by modifying the cutoff threshold with the help of SAS Enterprise
Miner.
After making the two new variables, the issue pertaining to the skewness of other variables will be addressed. The visual
representation highlights the descriptive statistics relating to numeric variables. It is observed that the most skewed variables are
direct and indirect deaths as well as injuries. It can be resolved after changing the cutoff threshold relating to the predictive
models. For addressing the skewness of beginning and ending ranges transformations will be applied prior to building the
c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c 24
predictive models. It can be done using SAS Enterprise Miner. Some of the relevant transformations are ‘maximum normal’ and
‘best’ methods.
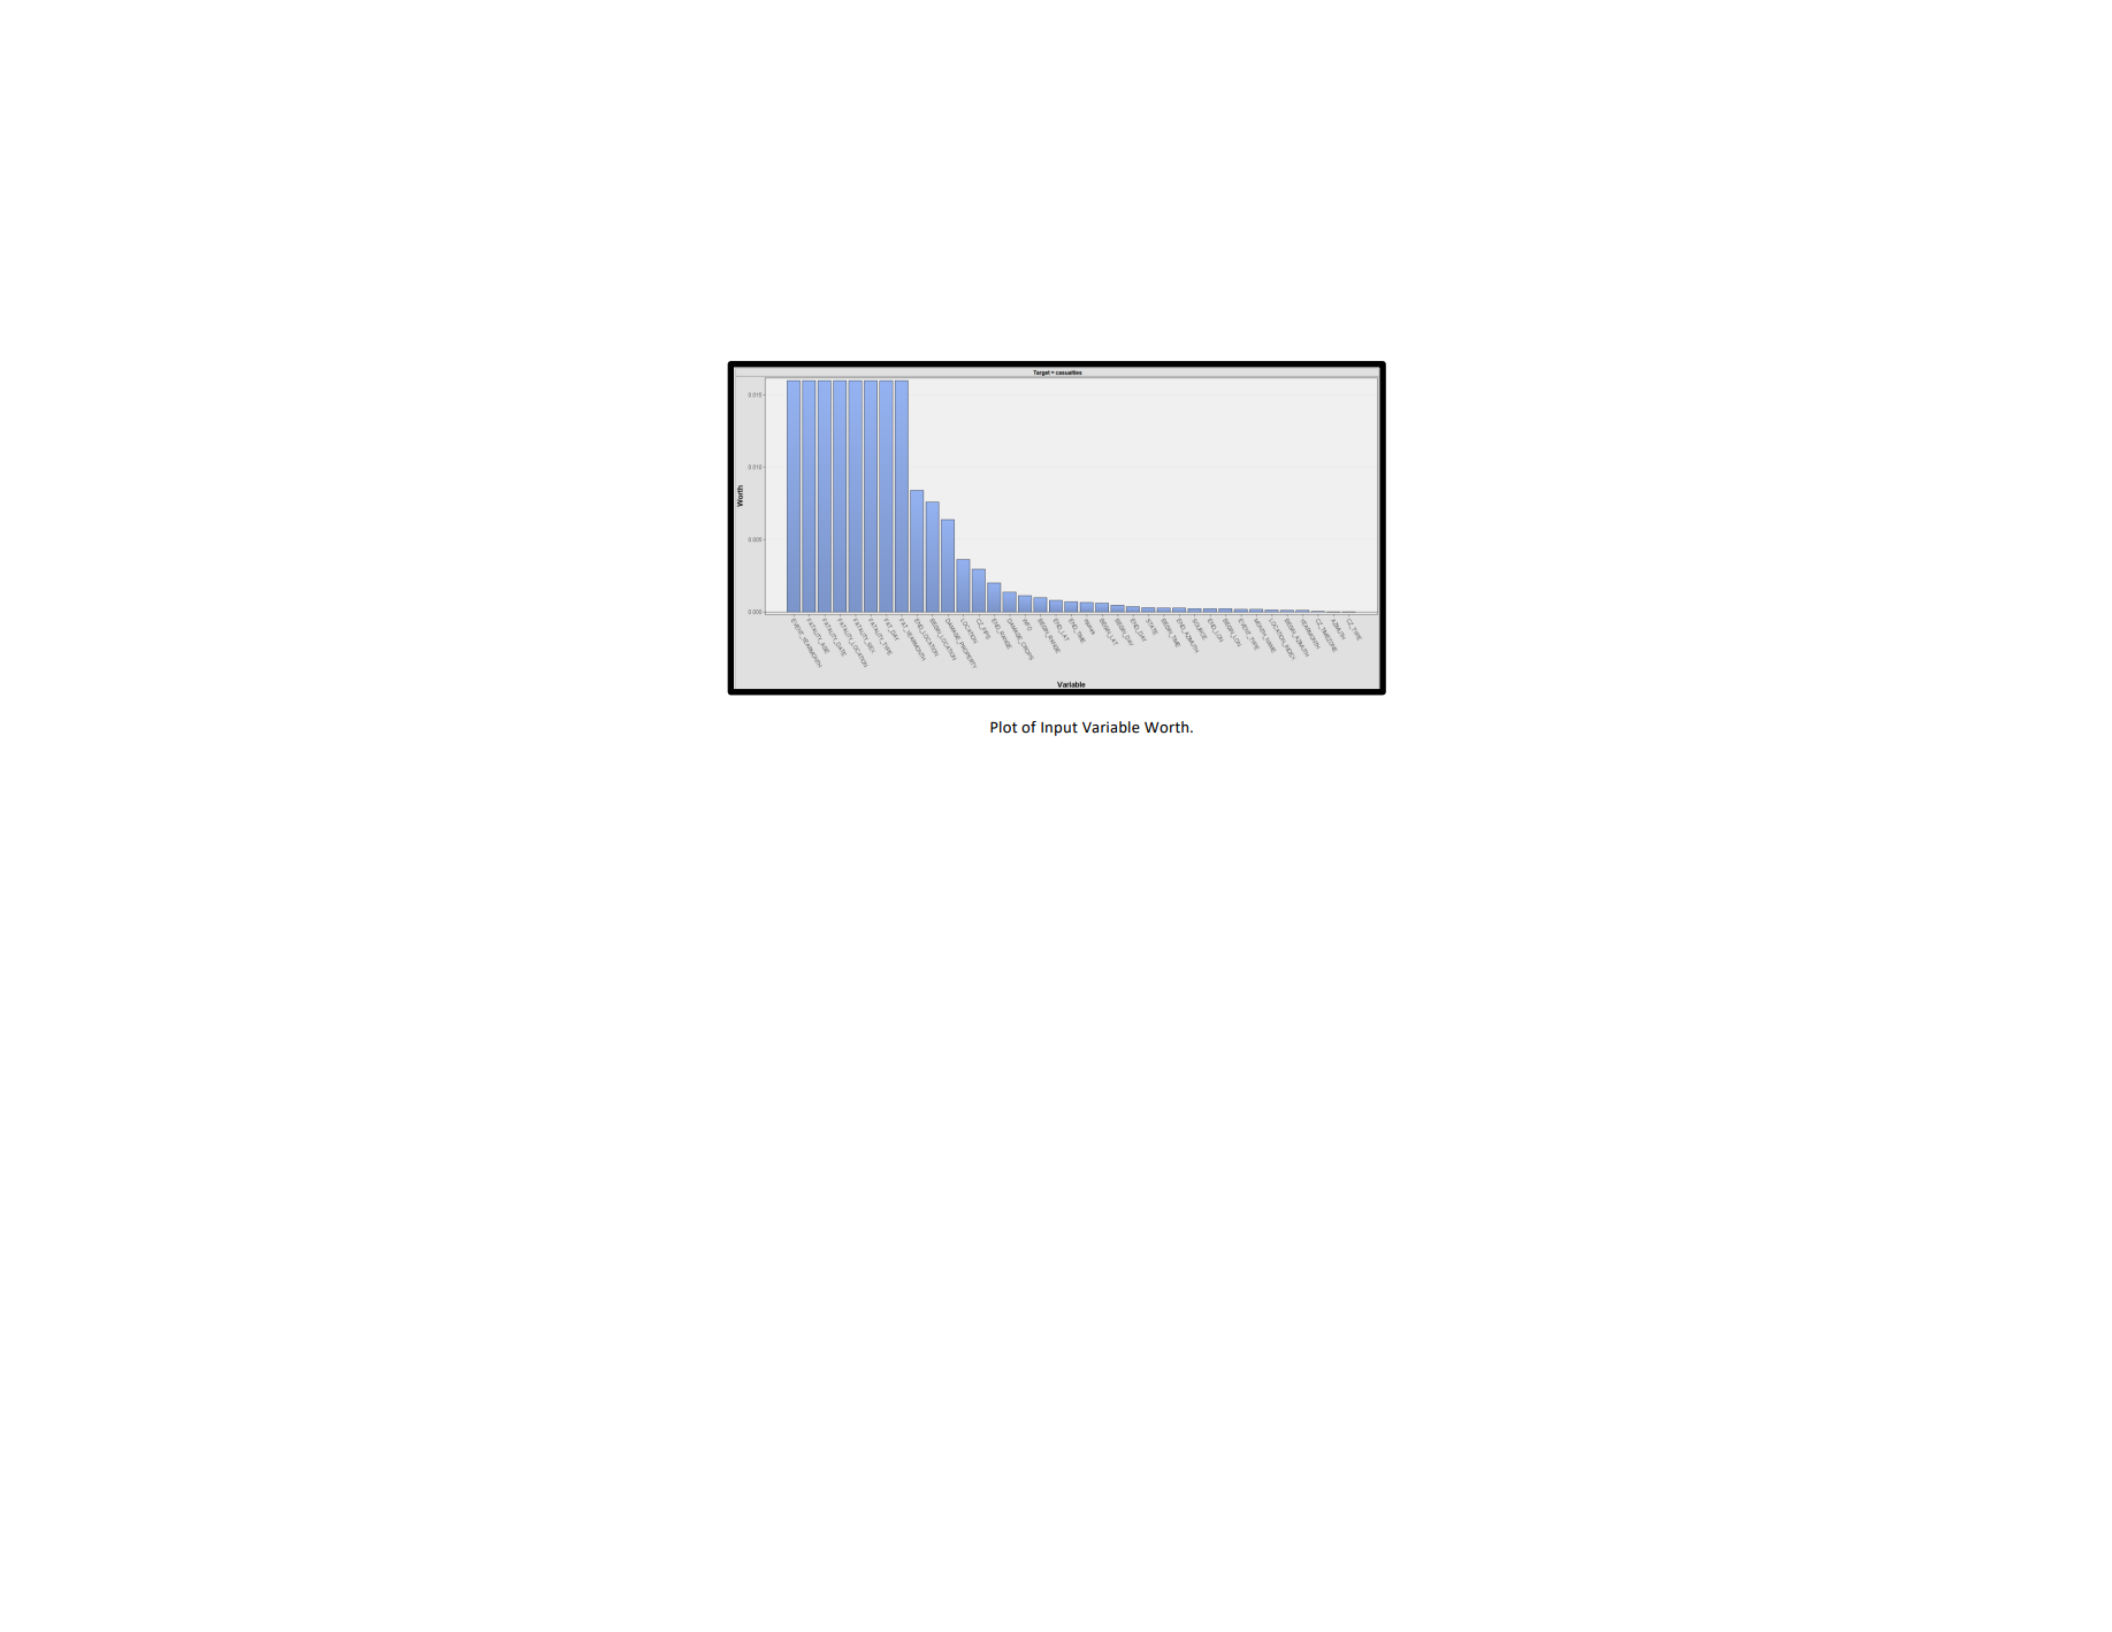
Prior to the implementation of the predictive models, the ‘StatExpore’ node will be used for variable exploration. It will help in
evaluating important features. The figure presented below shows that the variables which have the highest worth are the month
and year of the storm event, death location, death date, victim’s gender and age. A key observation that has been made is that
most of the critical features are extracted from the fatalities’ dataset (Centers for Disease Control and Prevention, 2022). As all
variables are linked to death, it could lead to unusually high accuracy as well as sensitivity rates. SAS Enterprise Miner has been
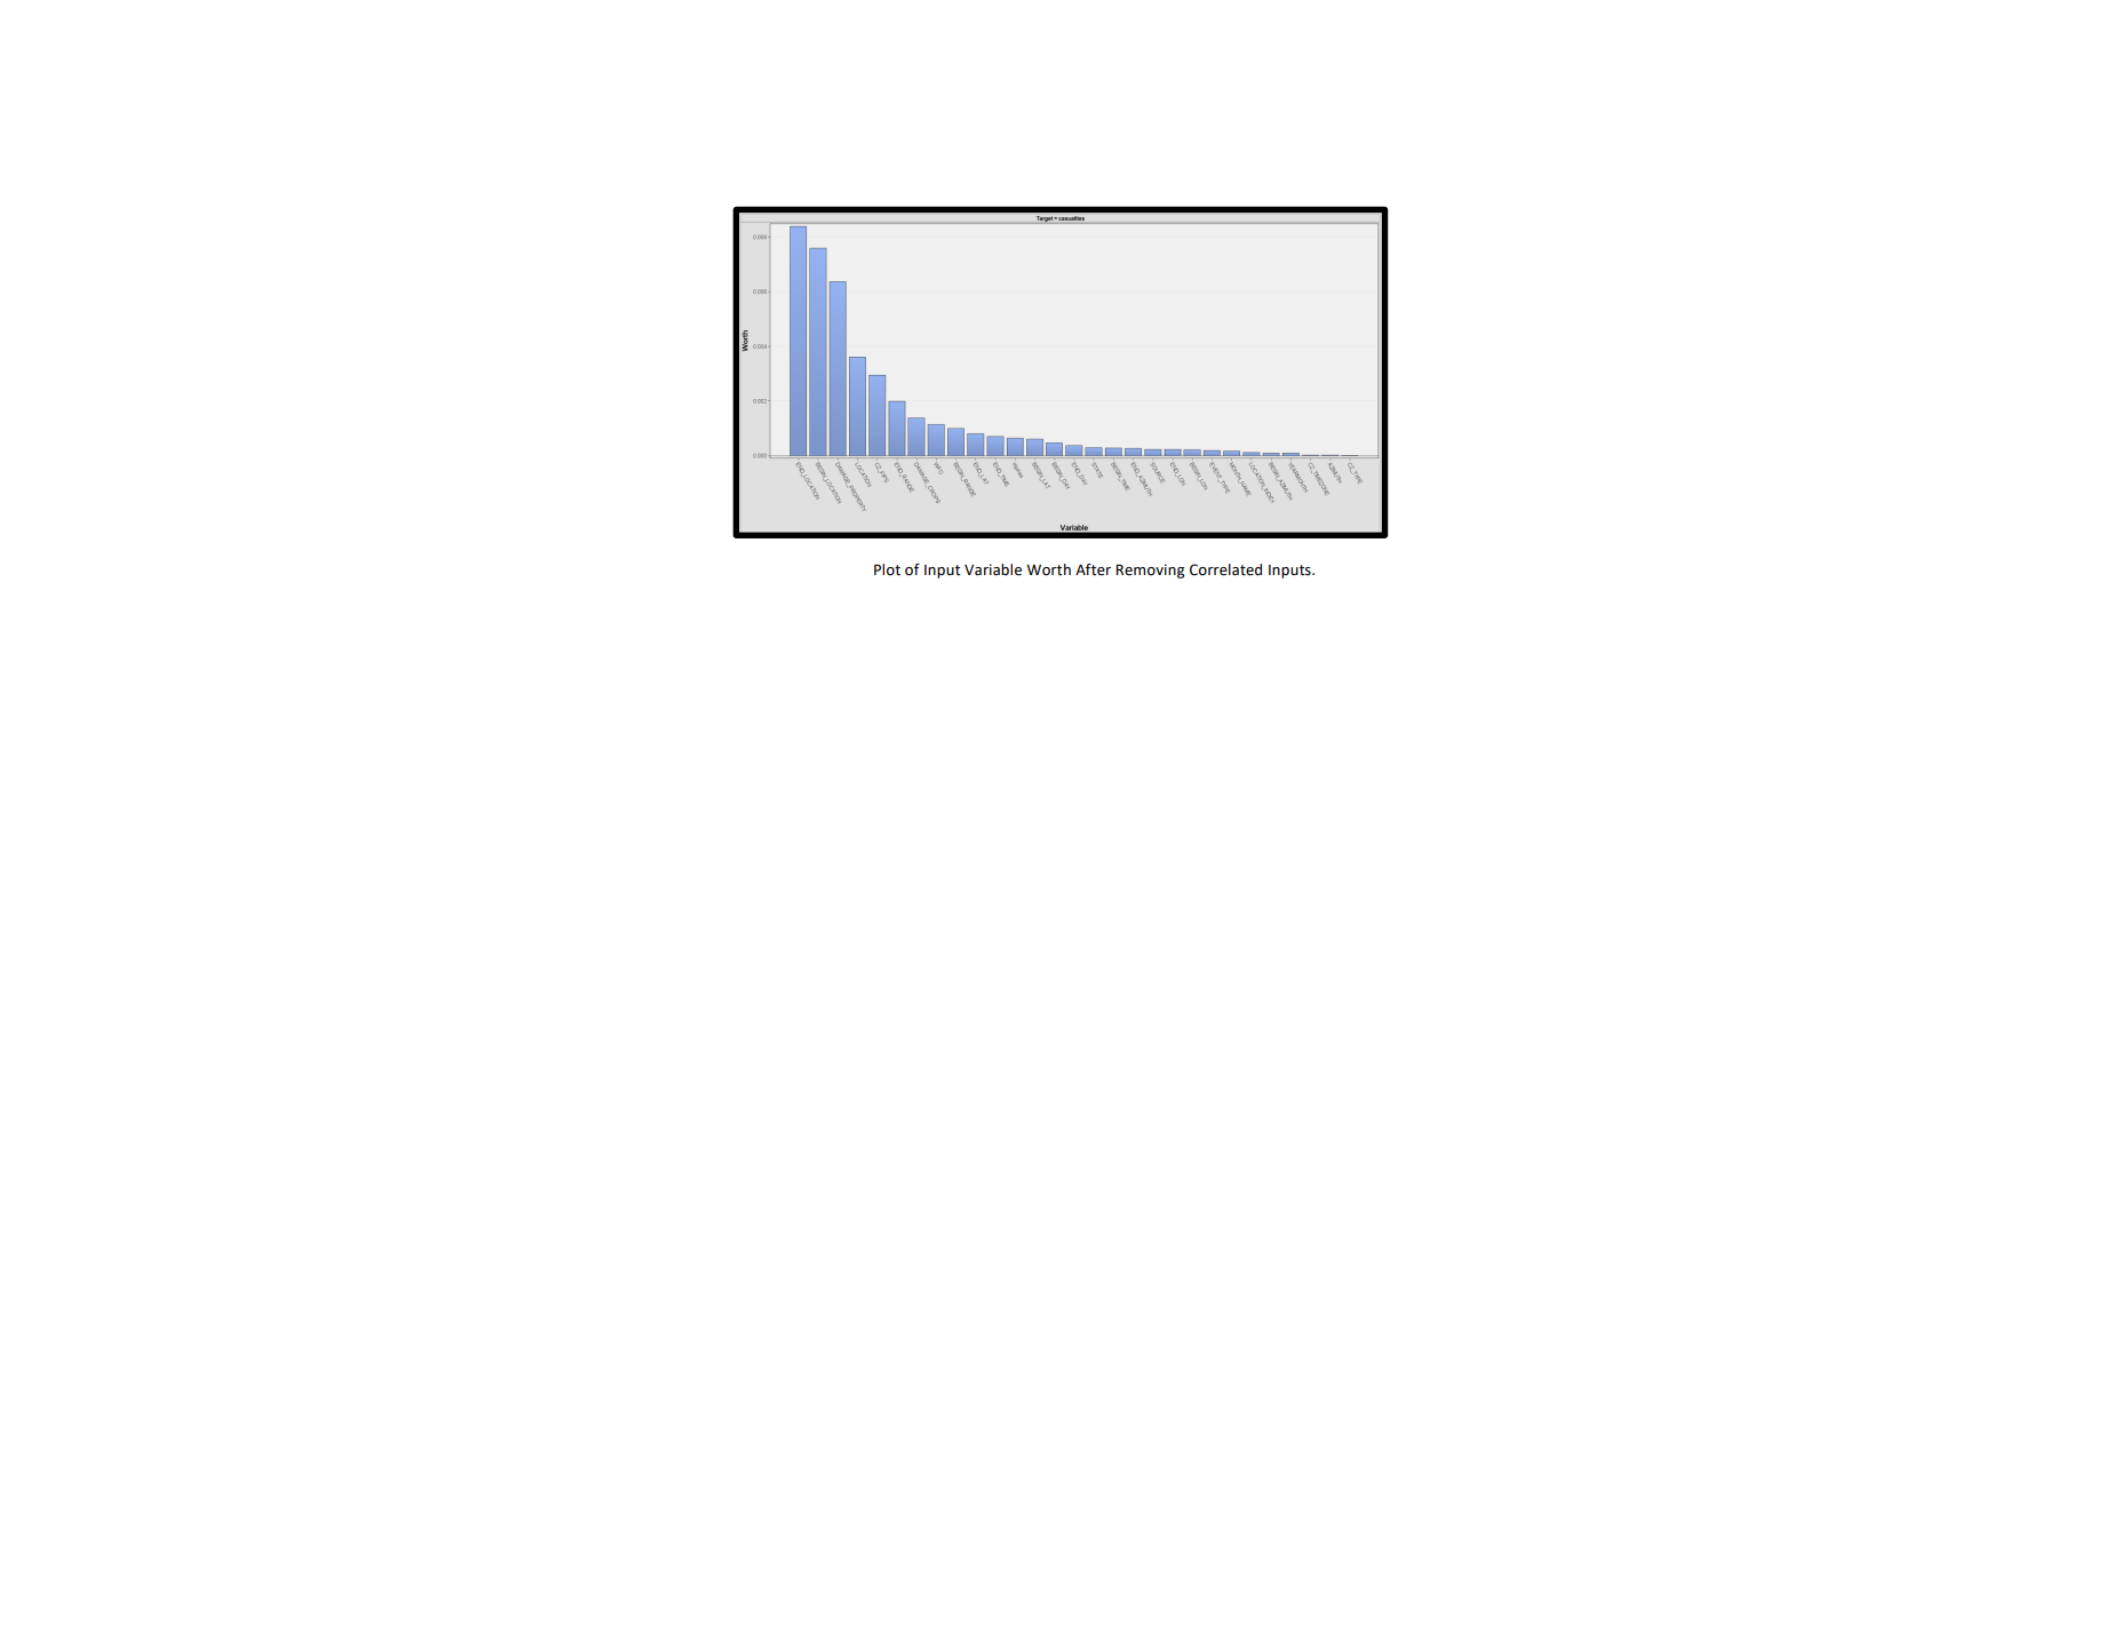
used to test the theory. It was found that almost every model had sensitivity and accuracy of almost 100 %. I have removed the
variables since they showcase correlation to the target variable. The figures shows that several key variables relate to location. It
implies that geographical location plays an important role in the development of lethal storms.
c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c 25
Data Analysis
The data analysis is a critical activity that will be conducted after data preparation. The use of visualizations is an important
element of the data analysis process. Tableau will be used for creating geospatial as well as time series graphs. The geospatial
map will display the number of storm-related deaths in the U.S.A in 2017. It will help to identify the locations that have high
vulnerability because of deadly storms. The Tableau tool has been chosen since it can help in the identification of location-
oriented information from the available data. The time series graph will showcase the deadly storms that have occurred during
2017 (Centers for Disease Control and Prevention, 2022).
Apart from Tableau, R will be used for making visualizations. It will be used for creating comprehensible visual representations
relating to the test mining analysis component. The main emphasis will be laid on keywords. It will help to identify the terms
that are most frequently used for describing storms. Wordcloud is one of the main text mining packages that will be utilized in

c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c 26
the project context. It will help to locate important words relating to storms that can help in recognizing early storm warning
signs in the future.
After making the visualizations, attention will be shifted towards creating the predictive models. A total of five predictive
models will be created and their parameters will be tuned so that at least one of them will have the minimum accuracy level of
80 % and sensitivity of at least 70 %. The predictive models will be implemented using SAS Enterprise Miner. It will help to
modify the parameters and enable model comparison. Several classification models will be used to identify the predictive model
that best suits the storm-related data. The models that have been chosen for the project are neural network, logistic regression
model, and decision tree model, support vector machine (SVM) and ensemble model.
Data Visualization
Data visualization can be defined as the representation of data in the form of visual elements such as graphical representations,
like charts, figures, etc. In the project relating to storm casualties, data visualization has been used to present the statistical
information in a simple and understandable manner. A total of three kinds of data visualizations have been used in the study.
Geospatial analysis is the first visualization that has been used to capture the total number of casualties in every state of the U.S.
in 2017. The time series graph is the second data visualization that has been used to highlight the storm fatalities that occurred
in a monthly as well as daily basis. The third data visualization is a word cloud (Midway, 2020). With the help of the
c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c 27
visualization technique, the 60 most frequently used words have been identified in the context of storm narration. The role and
contribution of each of the three data visualizations is of high value in the research context.
Data Visualization 1 – Geospatial Analysis
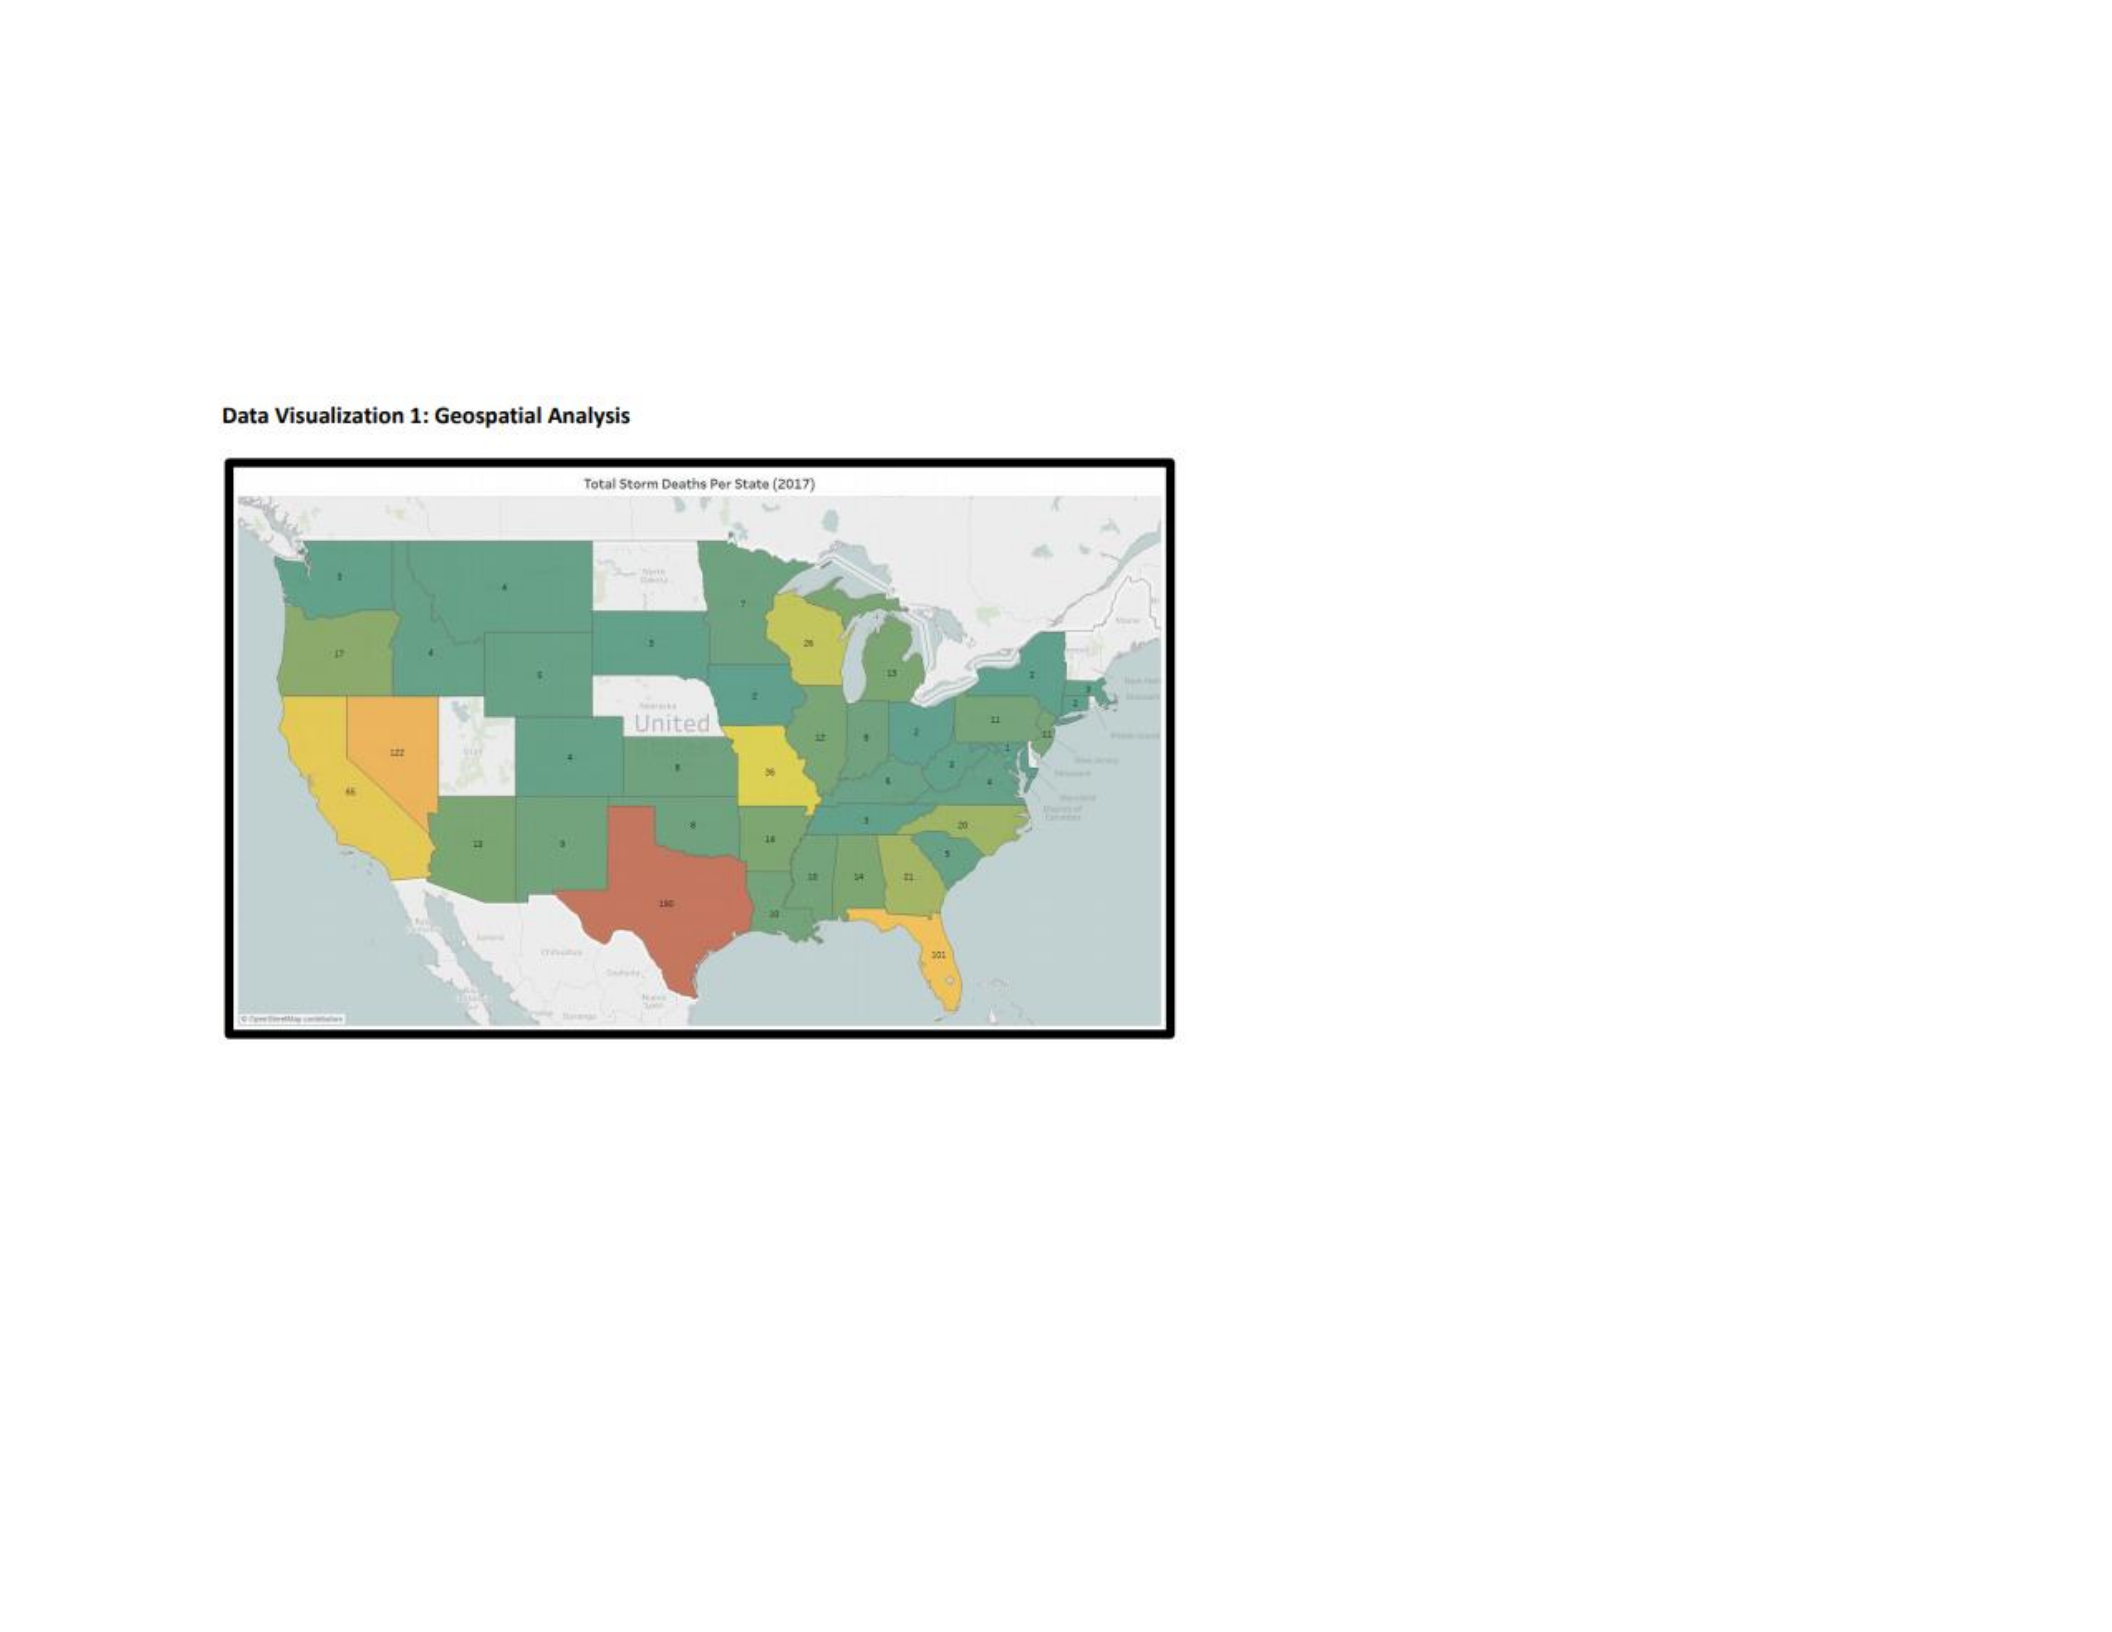
The geospatial map captures the total number of fatalities including direct and indirect that occurred in the U.S. in 2017. A key
highlight of the visualization is that it has helped to identify the ‘location’ factor which is paramount importance in case of a
storm event. Location can influence the type of storm that occurs. For example, coastal regions are more prone to storms as
compared to interior regions.
c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c 28
The map of the country of United States and its states have been captured in the visualization. States with lower fatalities are
colored green, whereas states with higher mortalities have been colored red. For making the visualization Tableau was used. The
storm data was imported in addition to the location database, and they were integrated together.
‘Total deaths’ has been newly created by combining both direct as well as indirect deaths. By creating this field, it was possible
to get a comprehensive insight into storm-related deaths (Midway, 2020). A key observation that is made is that Texas has
maximum casualties with 190 deaths. The reason for the same is Hurricane Harvey. It has also been observed that in Nevada
there are numerous storm-related mortalities. 122 people died due to storms in the region during the year 2017.
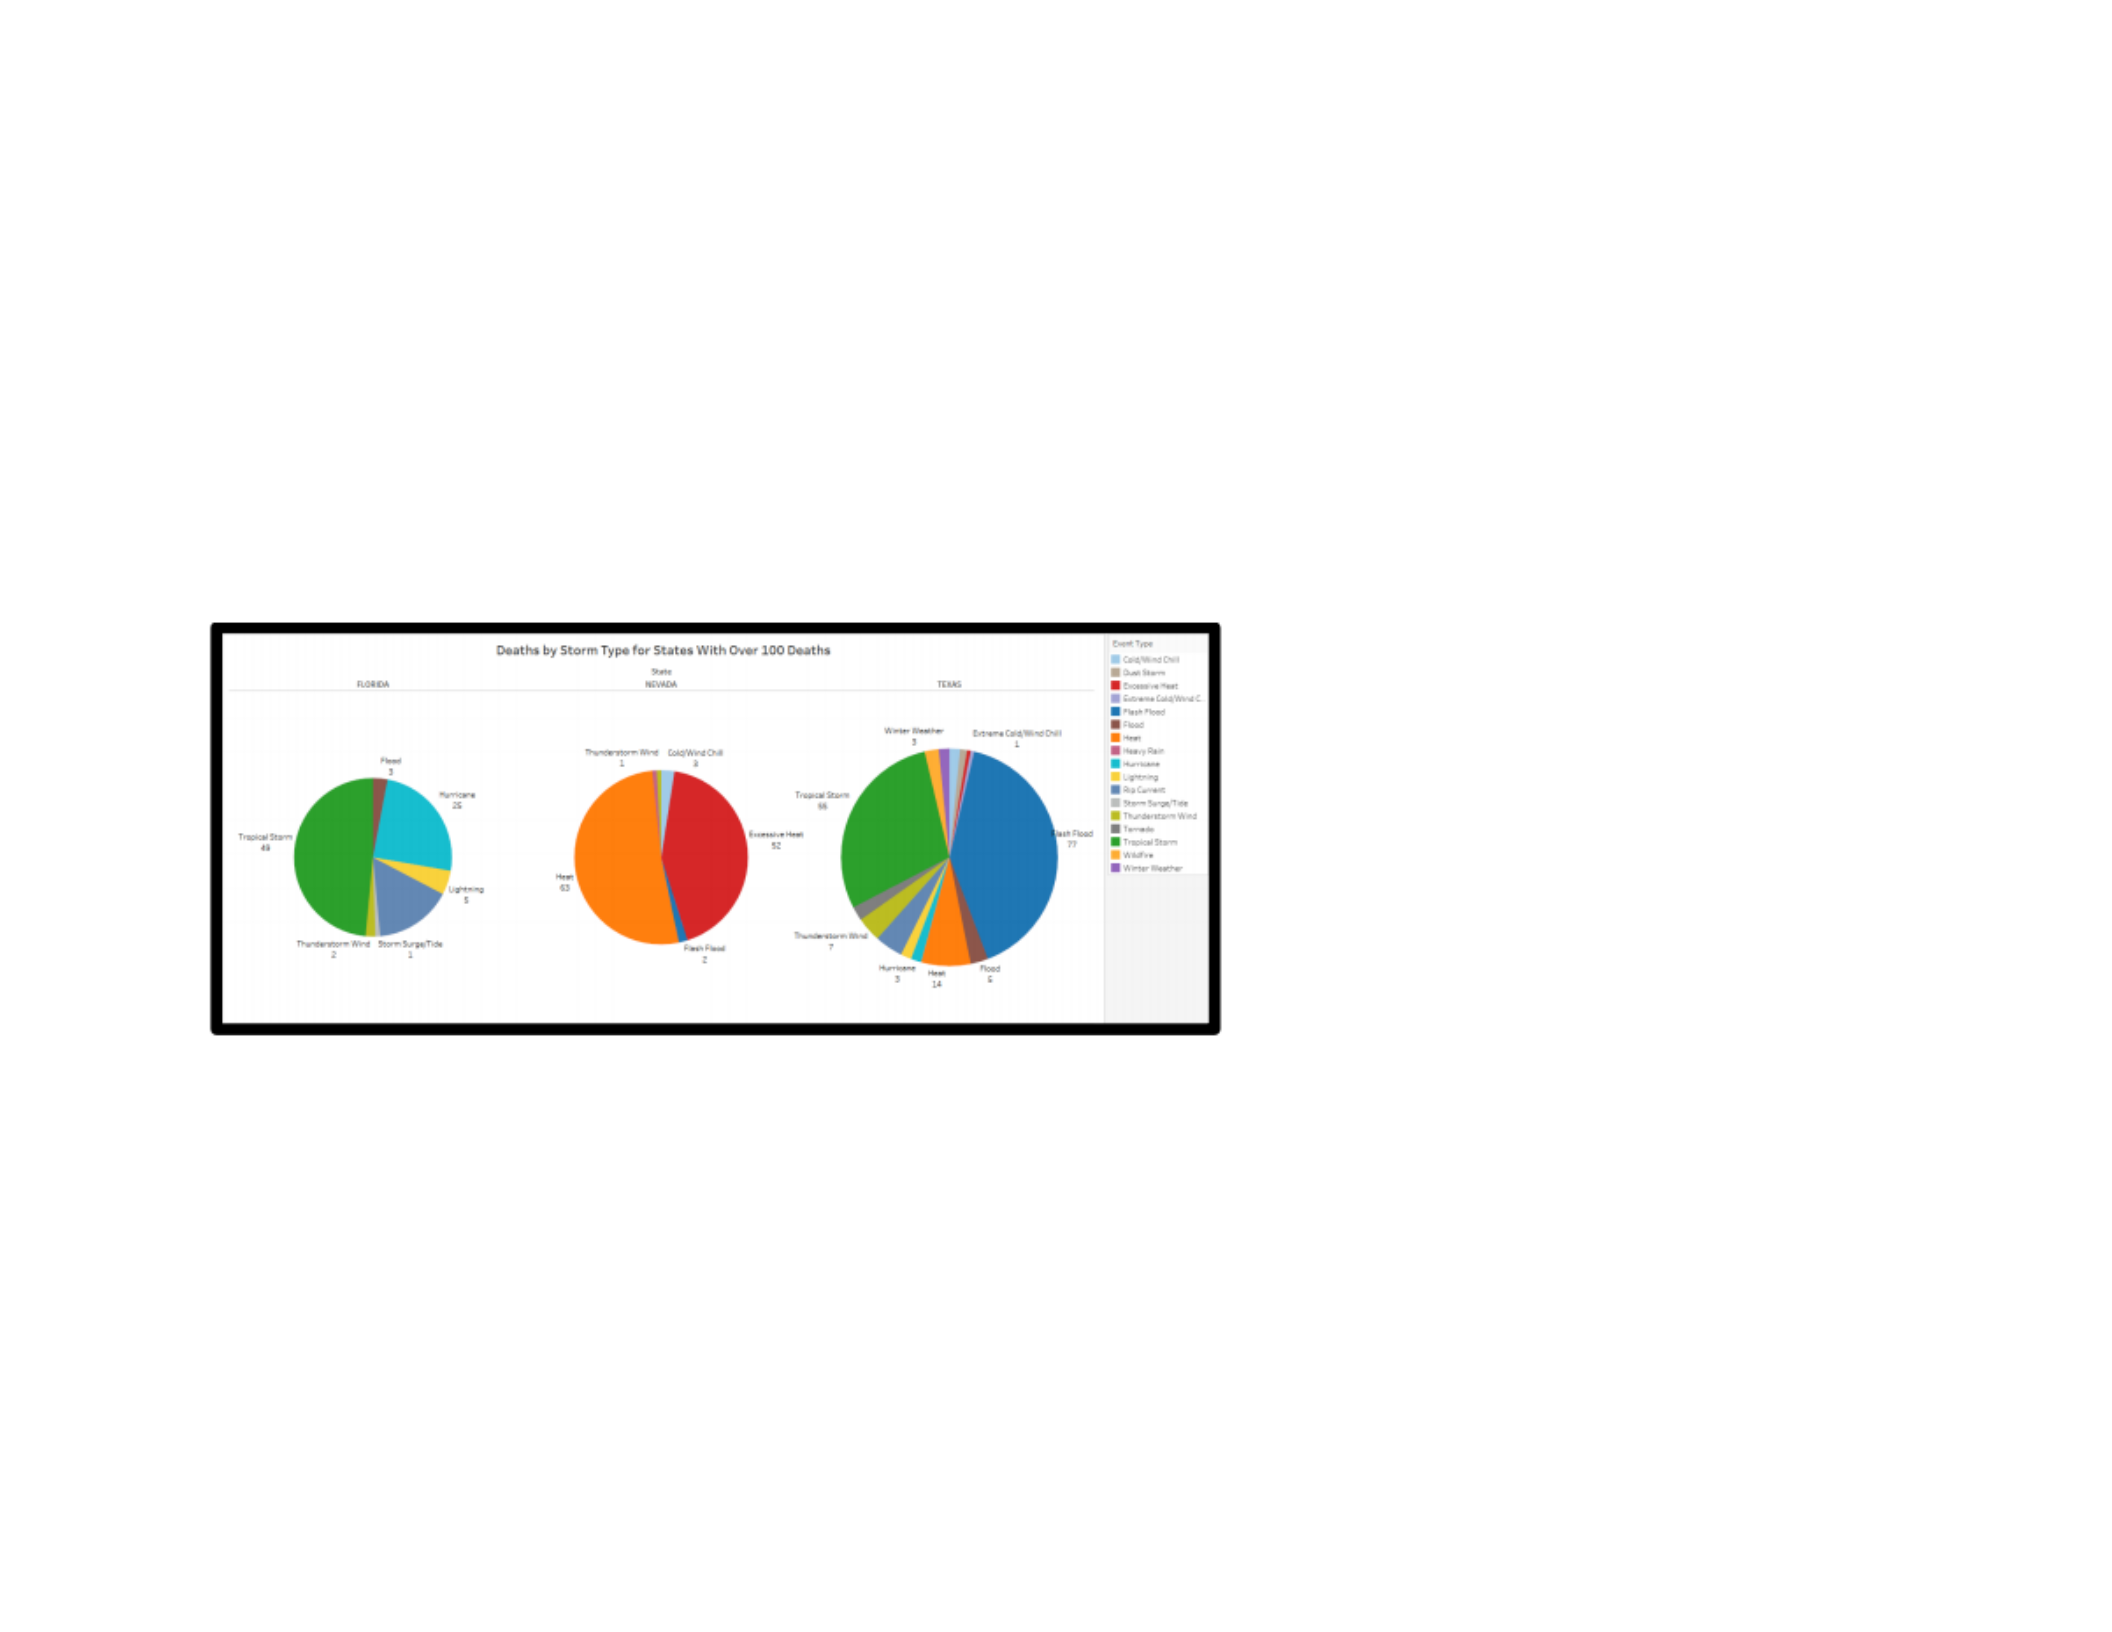
The pie chart shows the storm types that lead to casualties in the states of Texas and Florida. Tropical storms caused the death
of 49 individuals and hurricanes caused the death of 25 people in Florida. Most deaths in Texas can be contributed to tropical
storms or flash floods.
A key visualization element that changes the scope of the analysis is the location factor. For example, Texas has a high risk of
storms, but the possibility of death is low. Similarly, in Great Plains, the storm-related fatalities are low. The storm-related
c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c 29
deaths could fluctuate significantly in a year. So, a more detailed study must be conducted by considering the facts and data for
at least a decade (Midway, 2020).
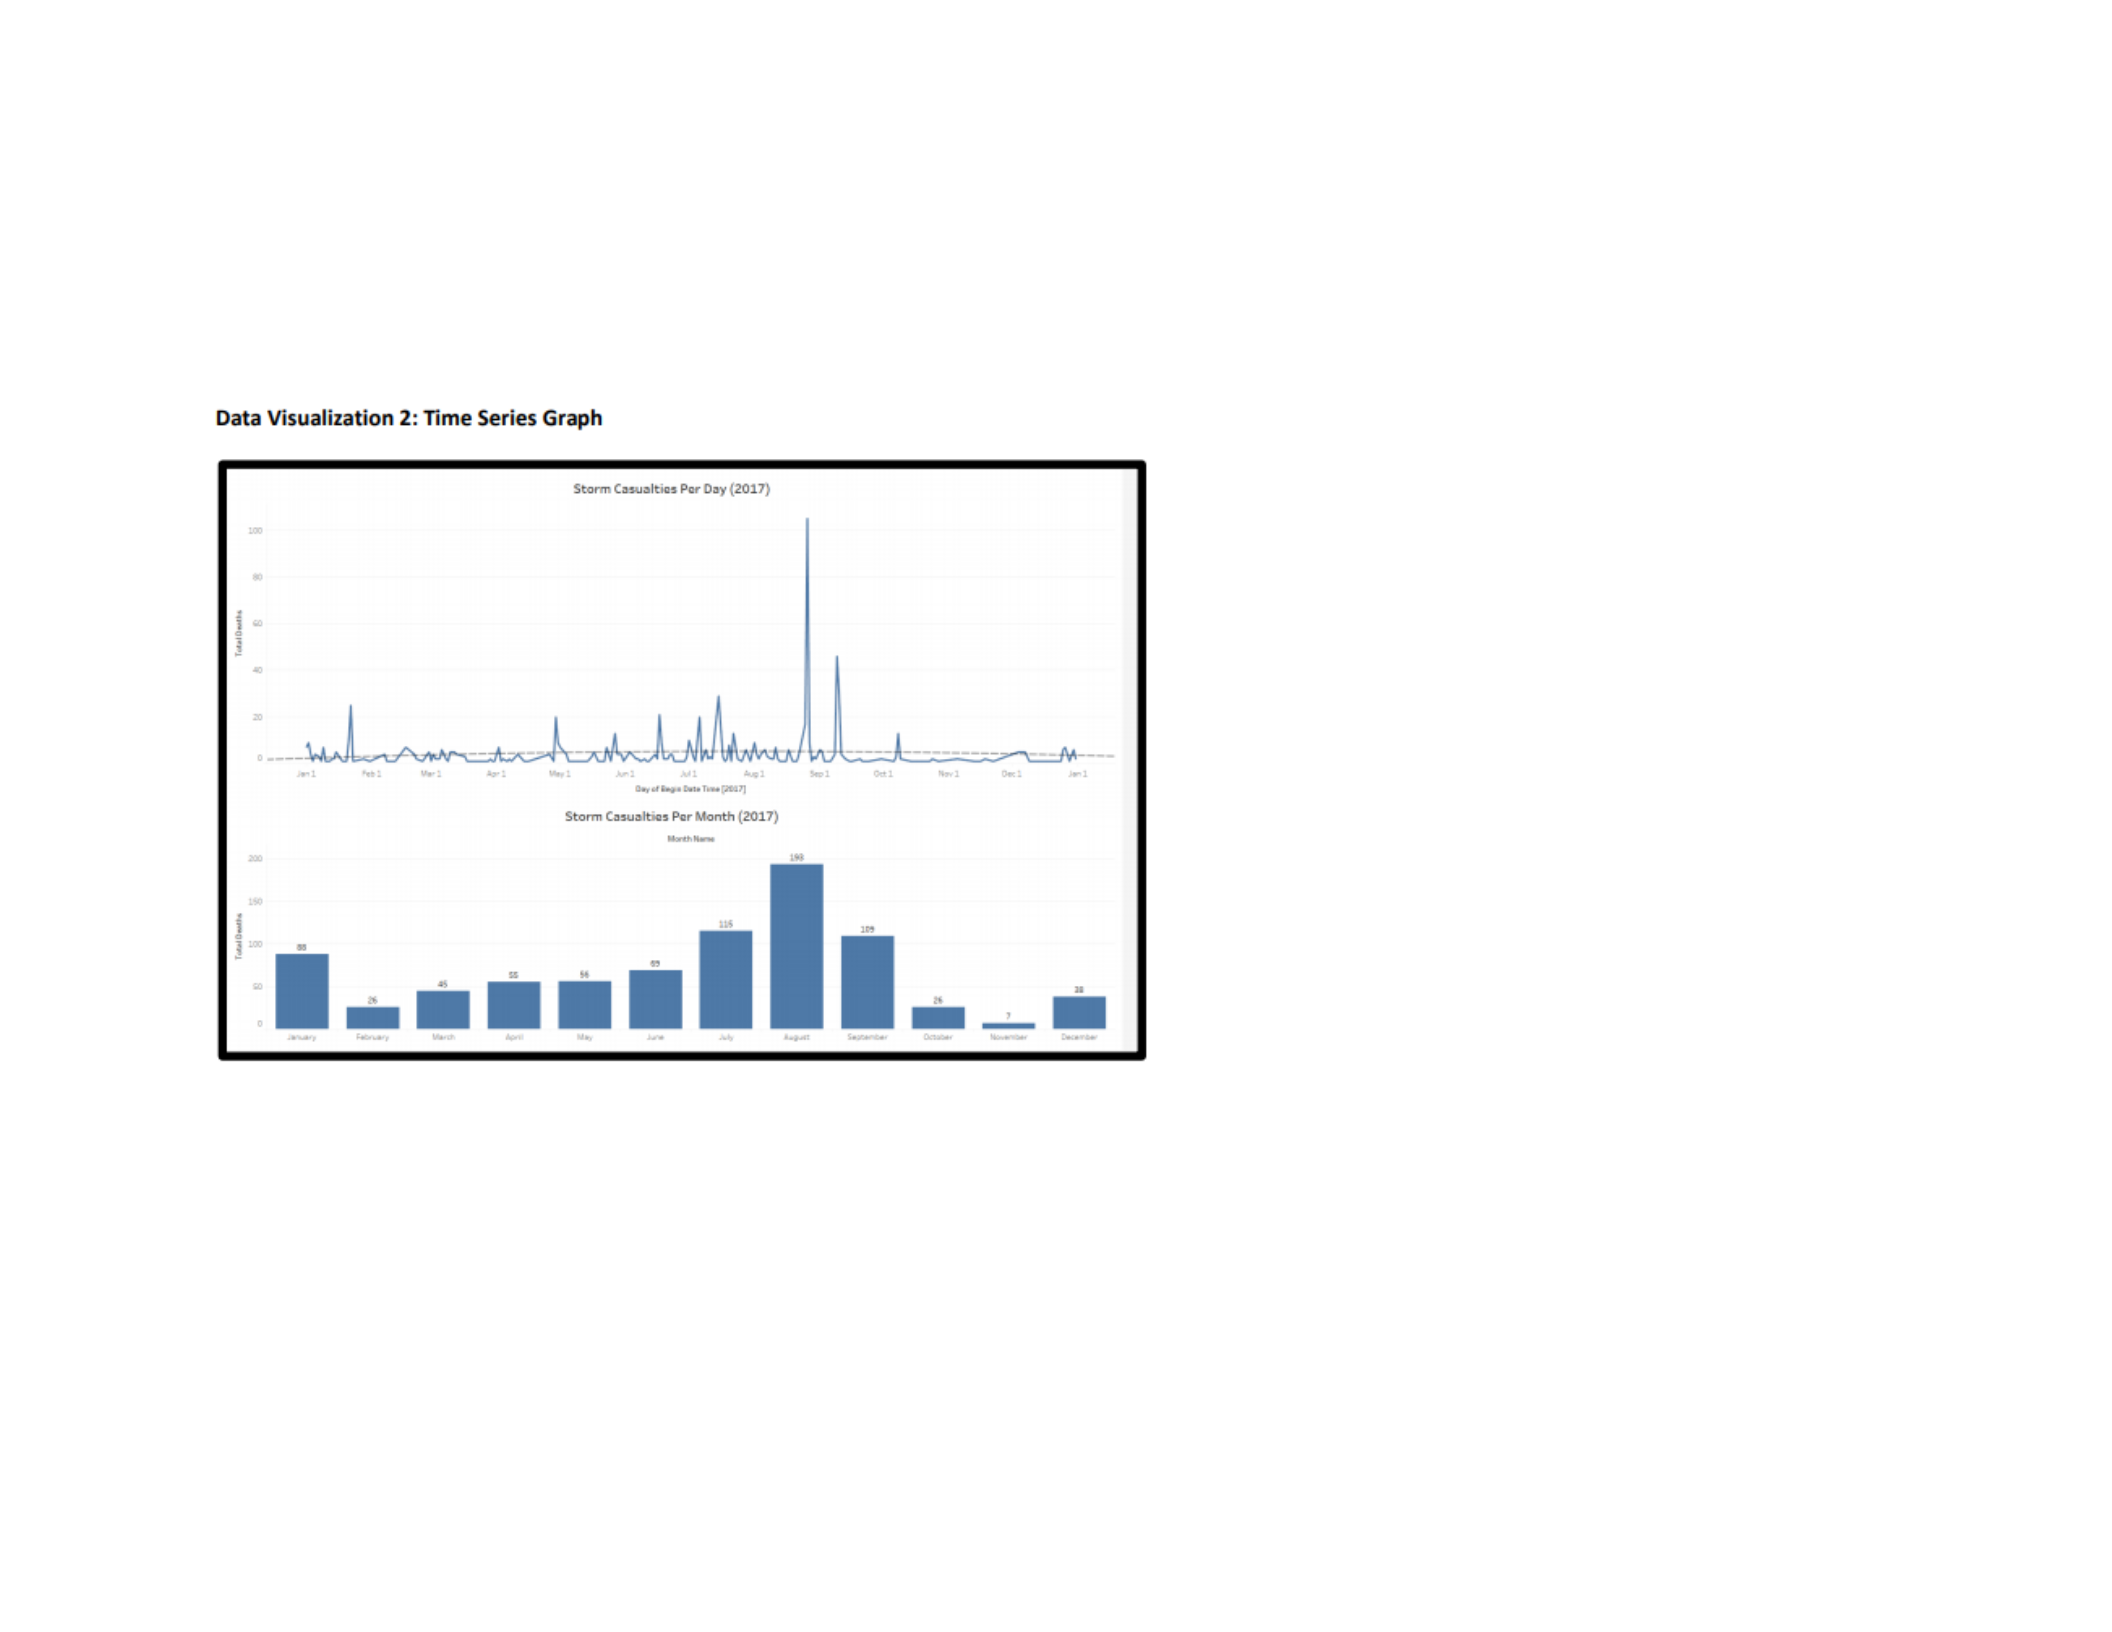
Data Visualization 2 – Time Series Graph
The second visualization in the study is the time series graph. The details that have been presented help to identify storm-related
death at a micro level since the day-wise and month-wide information has been captured. The top graph highlights the deaths
that occurred every day in 2017, whereas the bottom graph shows deaths that occurred each month of the year.
Both direct and indirect deaths have been integrated to get a complete image of the storm-related causalities. The visualization is
valuable since it sheds light on the exact time of the year when a storm becomes life-threatening. It is necessary to examine

c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c 30
every kind of storm that takes place in a year so that it will be possible to identify the riskiest time of the year when a storm
could strike and risk the lives of people (Midway, 2020).
The specific visualization has been categorized into two sections. In the first part, the information is presented in the form of a
trend line. It can be observed that each day when storm occurred there was at least one fatality. A bar graph has been used to
present the information on a monthly basis. The exact number of deaths that took place each month have been presented in the
graph. It can be considered to be simplified version of the storm-related details that have been captured in the top graph.
For making the trend series graph, Tableau was used. Both storm details as well as location datasets were used for the data
preparation purpose. As original dataset versions have been used, there exist outliers. For example, the high death toll related to
Hurricane Harvey is an outlier in the dataset. Outliers were not manipulated or eliminated since it could distort the correct
depiction of the storm events in the specific year.
Several vital observations have been made by using the visual representation. The first observation is that in August there are
maximum storm-related deaths. Most of the fatalities took place on August 26, as a result of torrential rainfall that accompanied
Hurricane Harvey (Midway, 2020). The dates that have been considered in the visualization are the beginning and end dates.
Thus, for the severe weather events that have spanned for over a day, the exact date of the death might not be entirely accurate.
Another observation is the low count of storm-related fatalities between March and June months. The death range that took place
within the period is between 45 to 70. Hence this phase can be considered to be safer as compared to the period between July
and September.
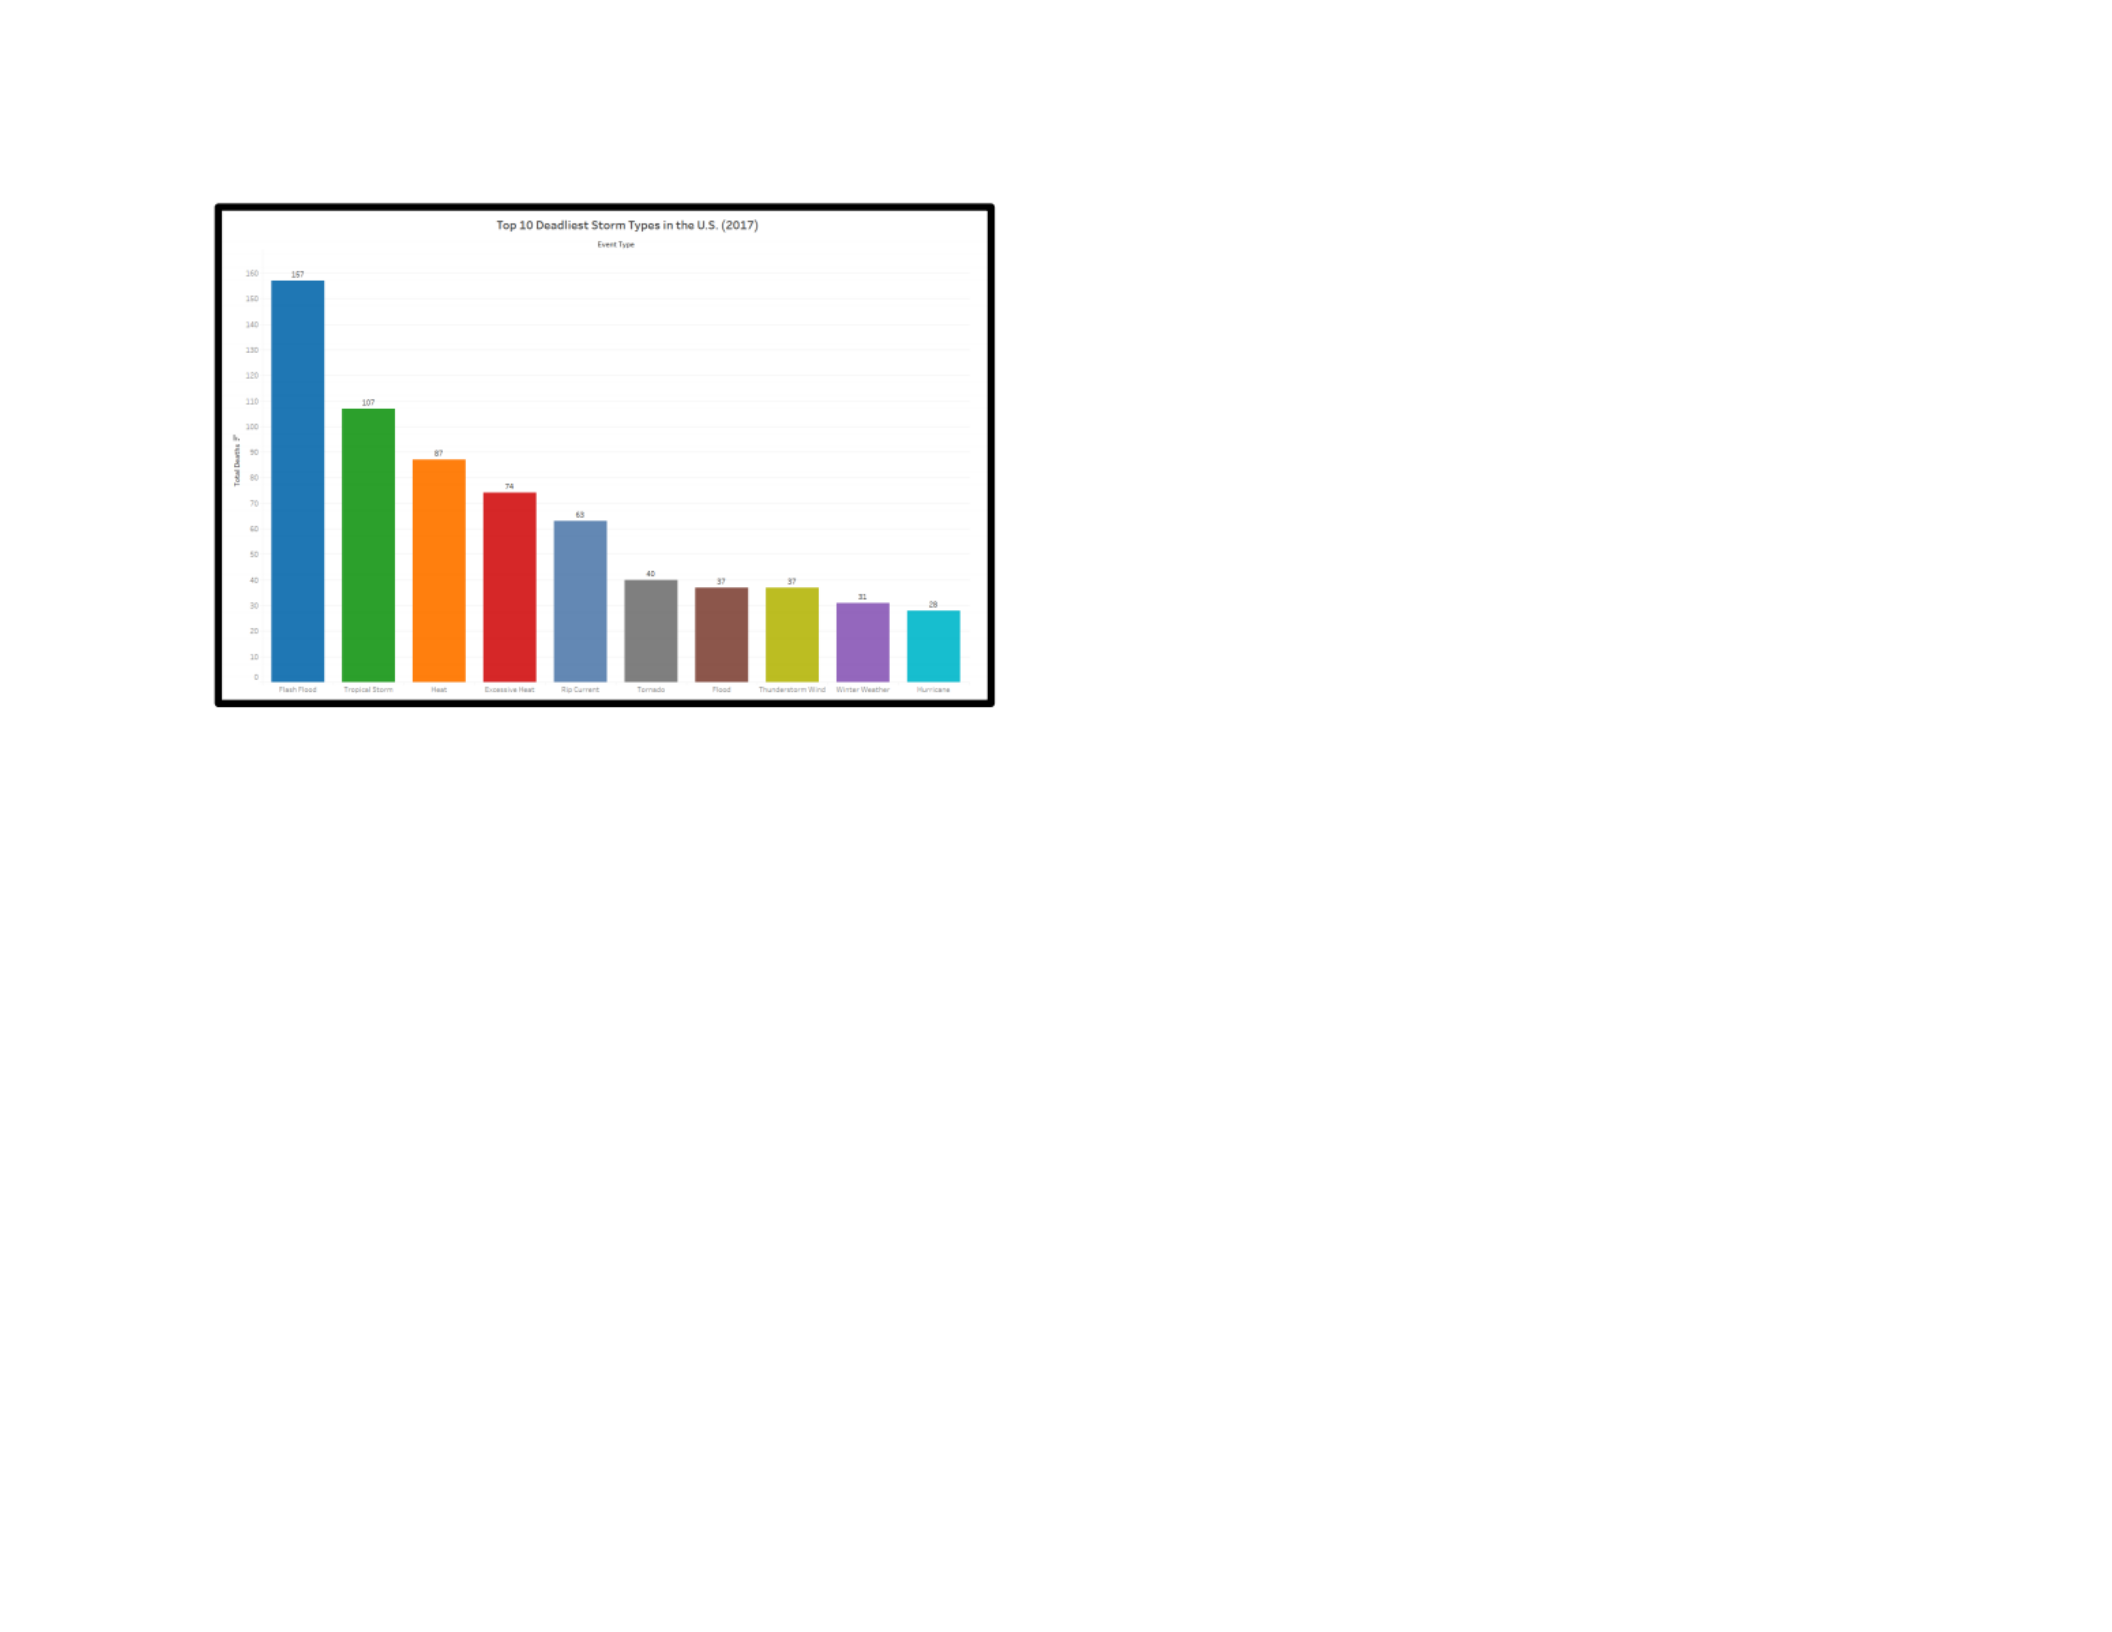
A bar graph has also been created for determining whether storm-related casualties are low or high.
c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c 31
The ten most deadly storms that occurred in the year have been identified. The storms with the maximum deaths have been
presented to the left whereas the weather event with the minimum number of deaths has been placed in the right side. 40 people
lost their lives as a result of tornadoes.
A key finding that has an implication on the research results is that most storm-related deaths occurred in the summer season.
The months when most deaths occurred are July, August, and September. This finding was aligned with my assumption. I had
also assumed that there will lower deaths during the fall and winter. The data showed that during these seasons there were lower
deaths. Only in the month of January there were storm-related casualties. The results affect the scope of the project analysis
since it challenges the belief that a smaller number of fatal storms occur in winter.
c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c 32
Word Cloud
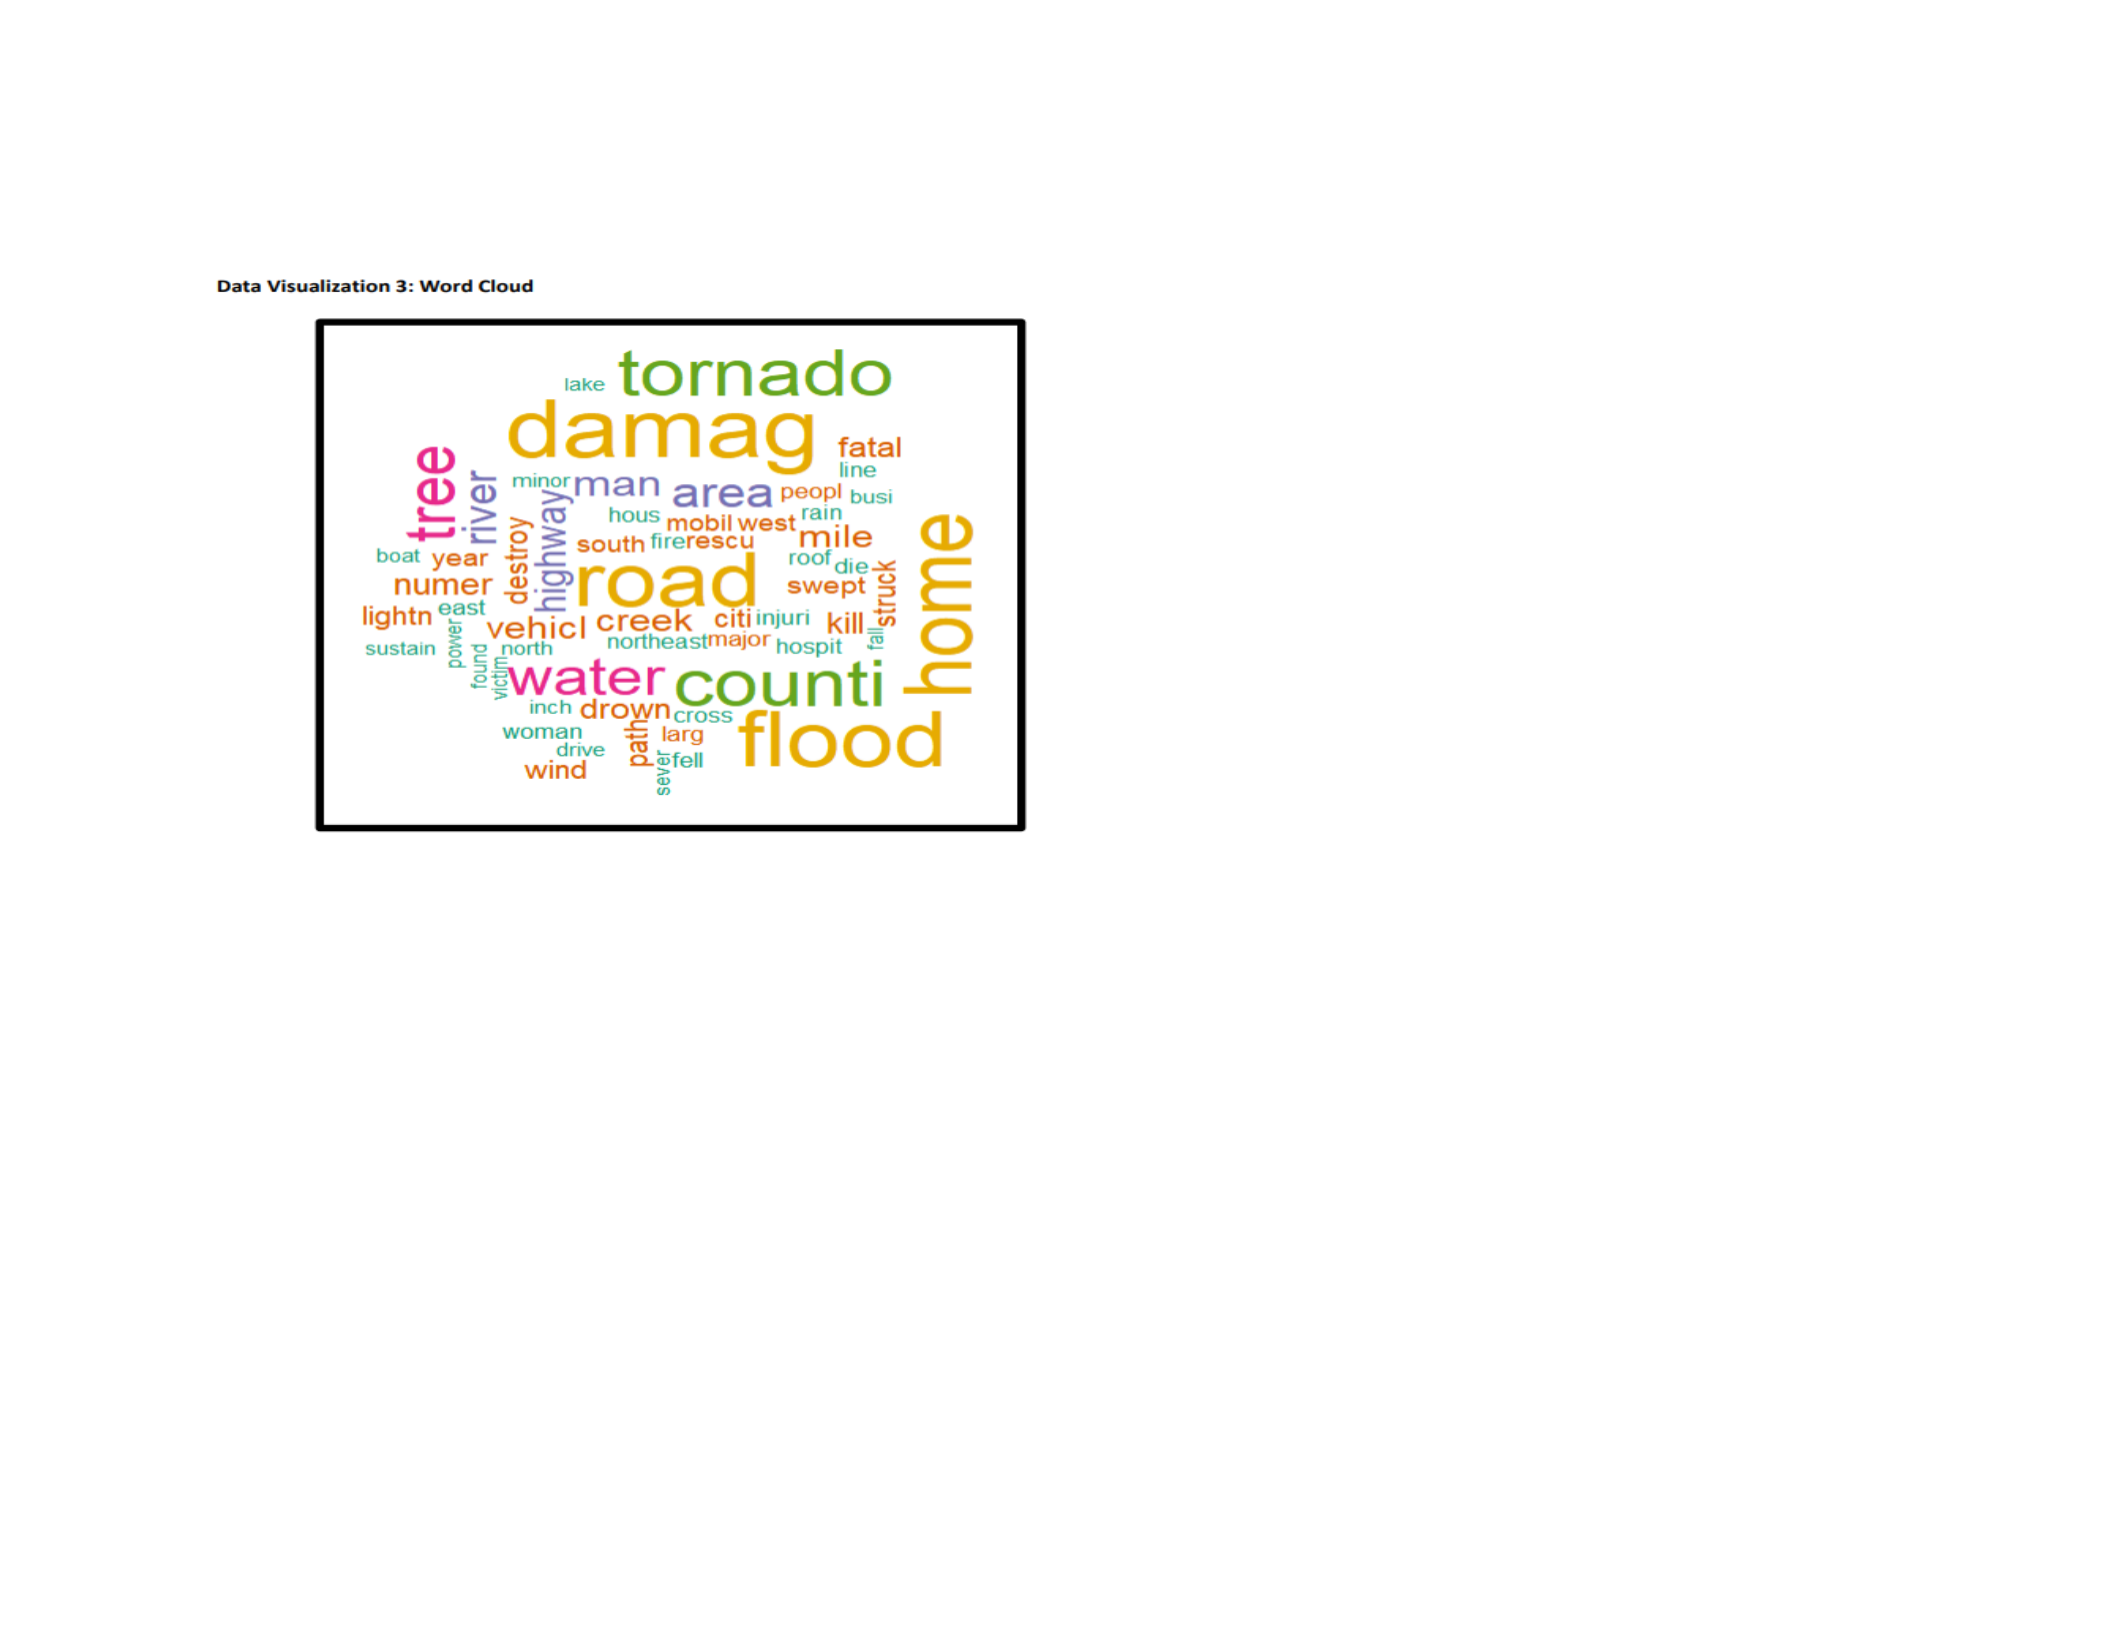
Word Cloud is the final visualization that has been used in the project. This text mining analysis tool has helped to identify the
texts that are commonly used while narrating deadly storms. The bag of words or tokens method was used while using the
visualization. It involved the dividing of a document into a set of words and investigating the frequency of terms. This approach
helps in recognizing the most frequently used words and understand the importance of certain words in a text. It is useful since
it gives a detailed insight into a text document (Midway, 2020).
In the project relating to storm-related casualties, the word cloud visualization is of paramount importance since it can help in
locating the factors that are related to storm-related deaths. It has served as an ideal visualization tool. However, a key limitation
of Word Cloud is offers restricted context because it mainly emphasizes only keywords that have been separated from the entire
sentences. Moreover, on certain occasions it is difficult to accurately quantify the specific frequency of certain terms. While

c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c 33
other visualization techniques such as pie charts and bar graphs can capture the exact frequency of a variable, Word Cloud does
not do so. In the specific Word Cloud that was created, a total of six colors have been used. The colors are lime green, orange,
yellow, magenta, bluish-green and blue. Each color denotes a different meaning. Yellow implies words with the maximum
frequency whereas bluish green has been used for the words with the lowest frequency, in the context of the storm-related
casualties project. A total of 60 words were identified using the visualization technique (Midway, 2020).
R has been used for creating the Word Cloud. A number of preprocessing steps were carried out while working on the specific
visualization. For example, punctuation marks, numbers and special characters had to be removed and the narratives relating to
storm events were arranged in a corpus. The words that were irrelevant or unnecessary in the project context were also
eliminated. The four most frequently used words that have been identified include road, home, damage, and flood. The high
frequency of the term ‘flood’ indicates that the occurrence of floods was high in comparison to tornadoes. Similarly, the use of
terms such as ‘swept’ and ‘drown’ indicate that many people drowned or were swept away as a result of severe weather events.
Certain results of the Word Cloud have an impact on the scope of the analysis. For example, the high frequency of the word
‘damage’ signals that the storms that are destructive in nature are likely to cause higher deaths. Prior to the analysis, I thought
that hurricanes and tornadoes are most dangerous weather events. But according to the visualization, floods are a major source
of threat (Midway, 2020). Another key finding relates to the location of death. The location is a key factor that can come into
play and impact fatalities. For instance, if a person is in a safe location, he might be able to get shelter from a storm and his life
might get saved.
Proposed Visualizations
An additional visualization technique that could be used in the storm casualties project is geospatial map that focuses on property
damage as a result of storms. It could complement the existing geospatial map since it could help to identify whether any
correlation exists between fatalities and property damage or not. An obstacle that may arise while creating the specific

c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c 34
visualization relates to the variable format. As the details are not in numerical format, their conversion would be extremely time-
consuming and challenging.
Another variable that could have been examined in detail while working on the project revolves around storm range. By
examining the variable, it would be possible to uncover whether deadly storms spanning a longer duration leads to higher
casualties or not. For uncovering this specific area, a visualization that I would suggest is the comparison between storm range
and deaths relating to specific storm types. A series of scatterplots could be used for capturing the range of each storm. It could
be potted over the total number of storm-related deaths. For each kind of extreme weather events such as hurricanes, tornadoes
and floods, a separate scatterplot could be prepared. This visualization would help in making a comparison between storms of
the same types. It would also help in identifying weather the storm range acts as a key factor that can influence the severity and
deadly nature of a storm. Tableau could be used as the tool for making the visualization.
The additional visualizations that have been proposed could add value to the project since they can help to identify the
significance of specific kinds of data that are available in the datasets. I would also recommend a visualization for strengthening
the existing text mining analysis in the study. A correlation plot could be created for identifying whether any association exists
between key terms in storm-related narratives or not. In order to prepare the plot, lines would be drawn for connecting pairs of
correlated terms. Such a visualization would be useful in the context of the storm casualties project since it would help to
understand the context in which the terms have been used.
The R tool would be used to prepare the visualization. The ‘Rgraphviz’ package can be used because it helps in the
implementation of correlation plots in an effective and simple manner. By using the new visualization, it would be possible to
not only identify the correlation between words but also the strength of the association between the words.
c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c 35
Predictive Models
In the storm casualties project, three predictive models have been developed by using SAS Enterprise Miner. Predictive models
are useful statistical techniques that help in making predictions about future behavior. With the help of these models, it has been
possible to determine whether a particular storm would be deadly or not. Logistical regression is the first predictive model that
has been created. The second predictive model that has been developed is Neural Networks and the final model is the Support
Vector Machine (SVM) model (Narkunienė & Ulbinaitė, 2018). After the development of these models, their performance has
been analyzed to identify the most effective model that can help in the classification of deadly storms in the U.S. The Support
Vector Machine (SVM) model have been identified as the champion models based on the detailed evaluation.
Predictive Model 1 - Logistical Regression Model
The SAS Enterprise Miner was used for developing the Logistical Regression model. It has been chosen as an ideal model since
it has diverse techniques like forward selection, backward elimination, etc. Data partition node has been used on the storm
casualties project for segmenting the data into test set, validation set and training set. For the selection criteria, ‘validation
misclassification’ and ‘logistic regression’ were used (Narkunienė & Ulbinaitė, 2018). False positives, true positives, false
negatives and negatives have been emphasized while using the model. In case identical outcome was produced in the validation
data it was chosen as training set. The cutoff threshold has been changed for enhancing the classification performance.
Model
Data
True
Positives
False
Positives
True
Negatives
False
Negatives
Misclassification
Rate
Forward
Training
112
6
27932
119
0.004438
c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c 36
Validation
62
4
16759
76
0.004733
Backward
Training
162
14
27924
69
0.002947
Validation
77
30
16733
61
0.005384
Stepwise
Training
100
2
27936
131
0.004722
Validation
81
0.004911
The table presents the outcome of the model, indicating that each one of them is accurate. Validation sensitivity along with
backward regression have been chosen while using the predictive model.
The cutoff threshold of 0.01 has been considered and the backward regression outcome has been presented in the following table.
It can be inferred that the efficiency of the model has increased and for classifying storm-related deaths. In the test set there are
only 21 false negatives and in the validation data there are 28 false negatives indicating the high efficiency of the model.
Data
False
Positives
True
Positives
False
Negatives
True
Negatives
Accuracy
(%)
Sensitivity (%)
Training
1017
221
10
26921
96.35
95.67
Validation
691
110
28
16072
95.74
79.71
Test
424
72
21
10750
96.05
77.42
c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c 37
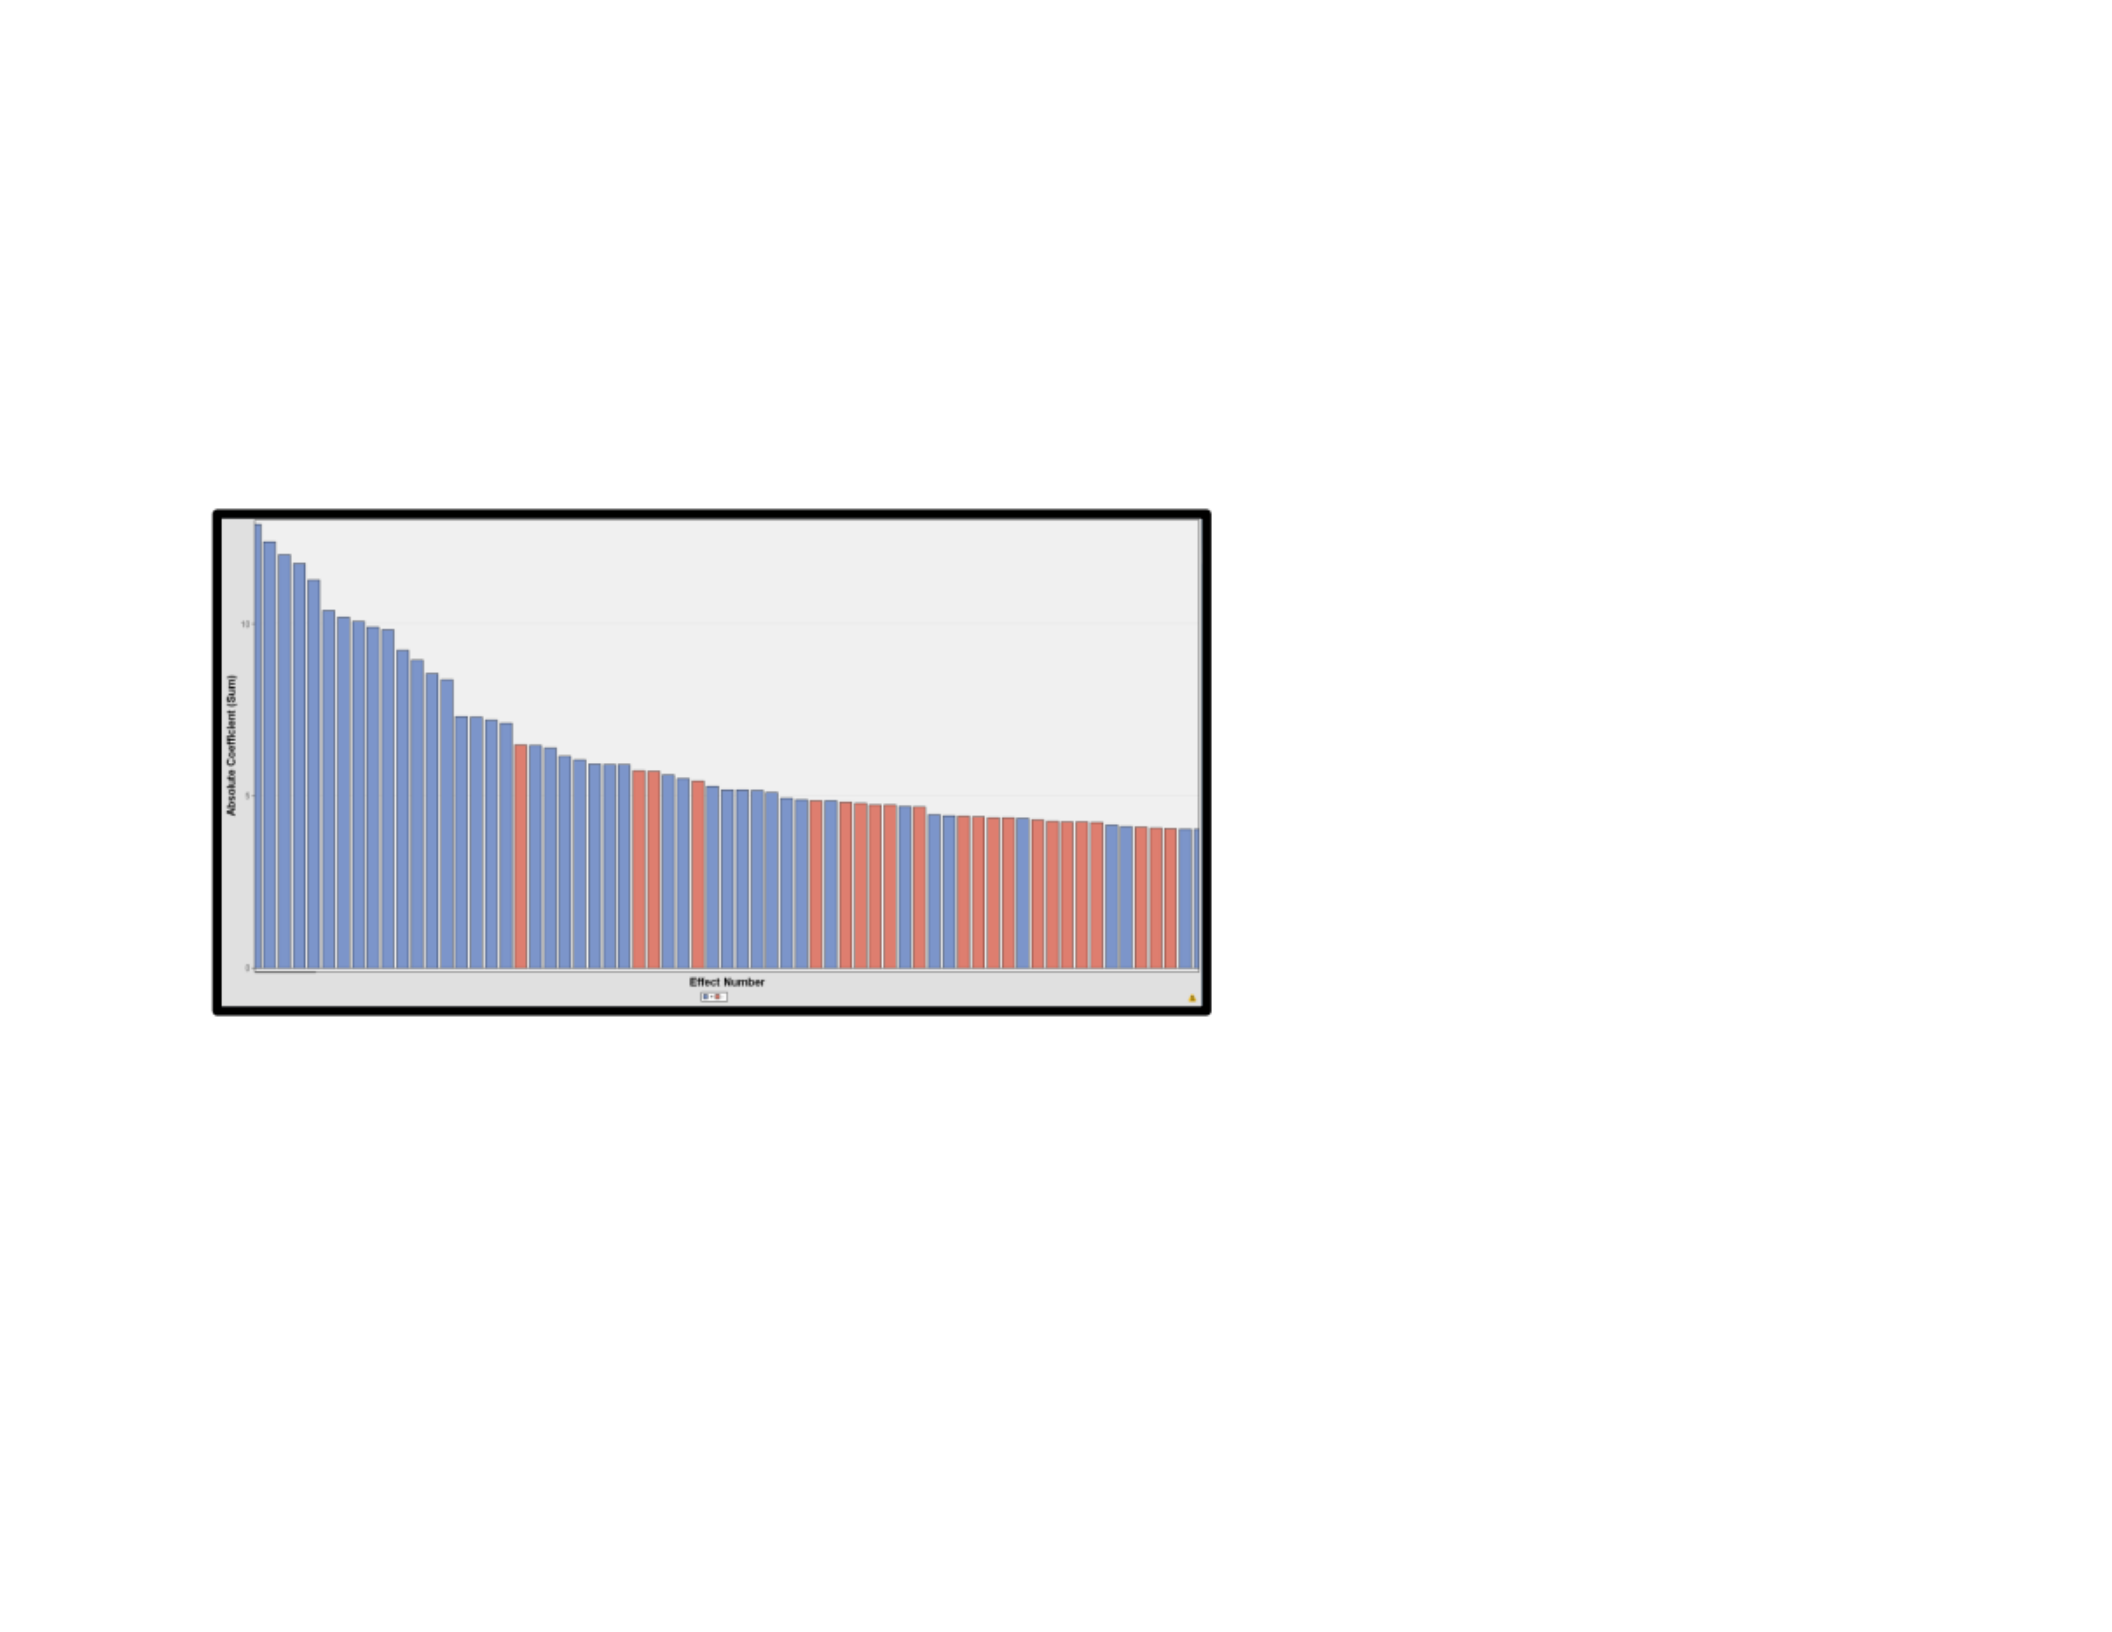
Regression coefficients are captured in the graphical representation showcasing the variables that helped to build the regression
model. They have captured the link between the target and the variables. Furthermore, they have helped to understand whether
the relationship is negative or positive. A chief coefficient that has been identified is damage to property (Narkunienė &
Ulbinaitė, 2018). A chief highlight of the model is the high level of accuracy and low sensitivity rate in the initial stage. The
backward logistic regression can be recommended for the storm casualties project.
Predictive Model 2 - Neural Networks Model
The second predictive model that has been used in the storm casualties project is the Neural Networks model. It has been chosen
since it is capable of using the backpropagation process for making predictions. An advantage of the model is that it is capable
of handling noise data. Additionally, this model is able to identify patterns without the requirement of training.
c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c 38
The data partition node of the model has been utilized for segregating 50 % of data to the training set category, 30 % of data to
the validation set category and remaining 20 % of data to the test set category (Narkunienė & Ulbinaitė, 2018). Several tools
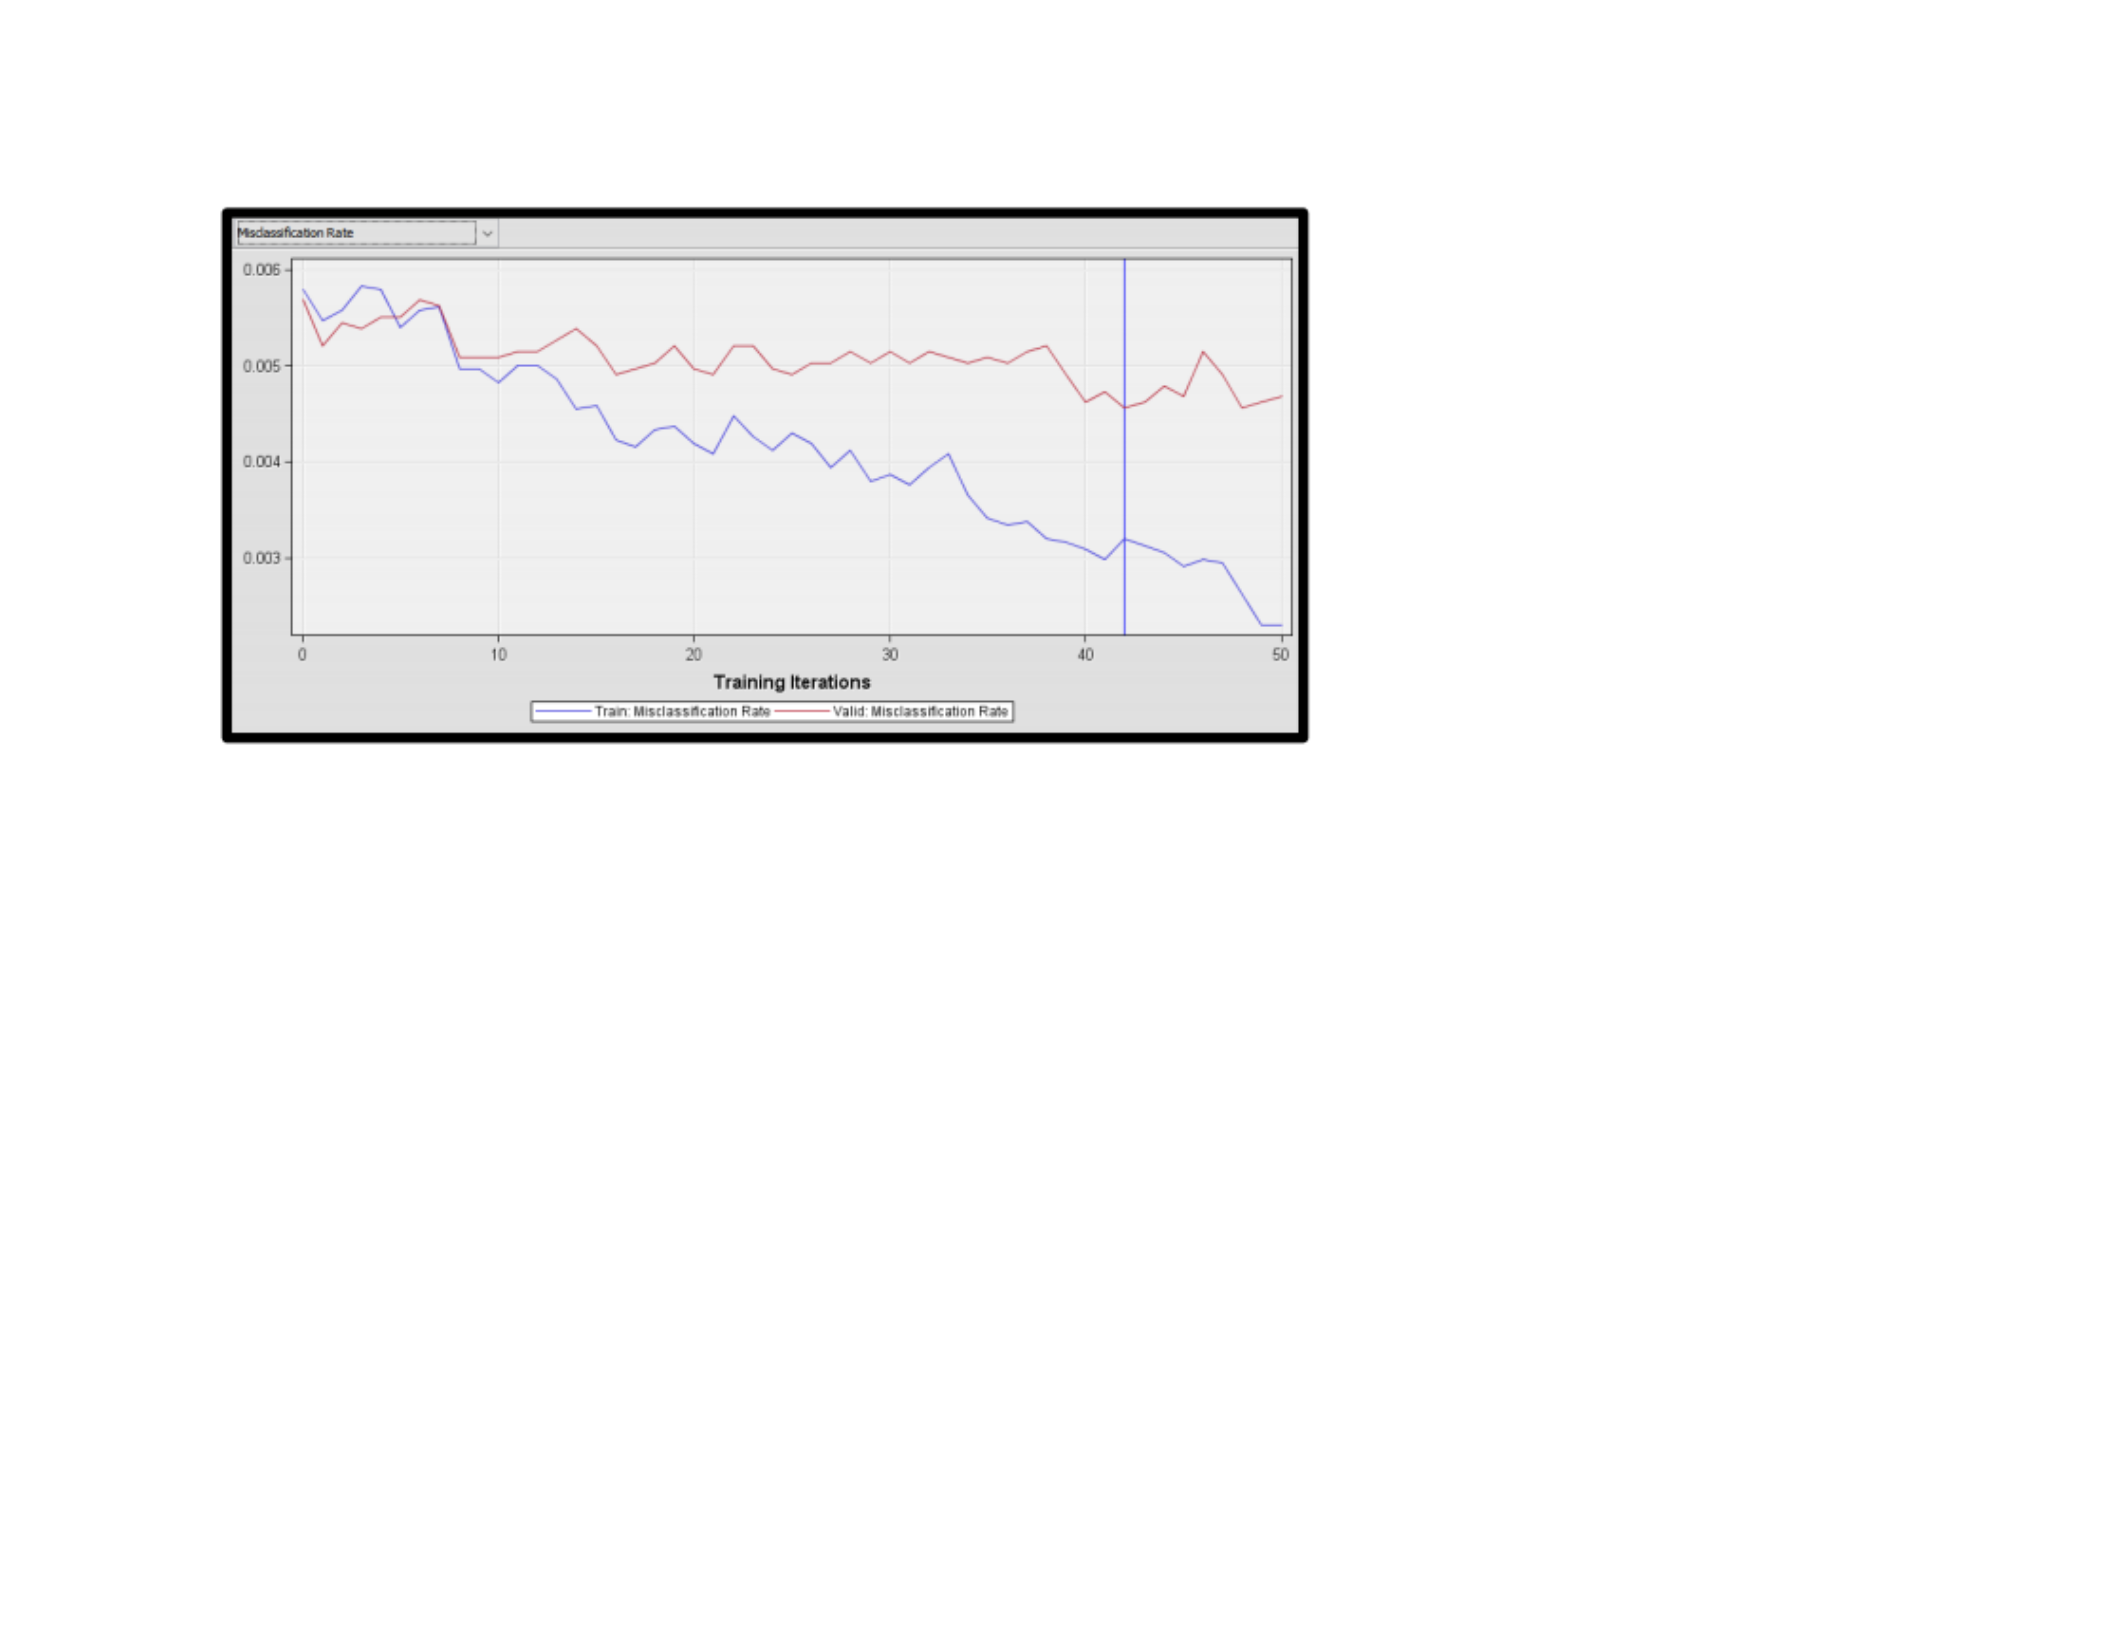
were used for analyzing the model’s outcome. The iteration plot that highlights the needed steps for training the data has been
investigated. The accurate and inaccurate prediction figures and the misclassification rate have been highlighted in the table
below:
Data
False
Positives
True
Positives
False
Negatives
True
Negatives
Misclassification
rate
Training
15
155
75
27923
0.003195115
Validation
11
73
66
16752
0.004555674
According to the graphical representation, the misclassification rate is higher in the validation dataset as compared to the training
dataset. It can further be inferred from the figure that the model requires a total of 42 training iterations Based on the table and
graph, it can be observed that the misclassification rate is low since it has recognized almost all ‘true negatives.’ In the training
set 75 false negatives have been misclassified and, in the validation set 66 false negatives have been misclassified.
c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c 39
The sensitivity of the validation set is 52.5 % and training set is 67.4 %. These figures are lower than the minimum sensitivity
rate of 70 %. The cutoff threshold has been changed with the help of the cutoff node. The cutoff threshold of 0.01 has been
considered. It can be observed that the predictive model’s efficiency increased when it comes to classifying the ‘true positives.’
In the below table it can be observed that there are 17 false negatives which means that 17 storms have been misclassified. The
model’s accuracy is higher in comparison to the logical regression model. But its sensitivity rate is lower. c As sensitivity is a key
criterion, the model fails to meet the requirements relating to the sensitivity dimension.
c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c 40
Data
True
Positives
False
Positives
False
Negatives
True
Negatives
Accuracy
(%)
Sensitivity (%)
Training
213
914
17
27024
96.69
92.61
Validation
103
522
36
16241
96.70
74.10
Test
70
345
23
10829
96.73
75.27
Predictive Model 3 - Support Vector Machine (SVM) Model
The final predictive model that has been used in the storm casualties project is the Support Vector Machine (SVM). This model
basically involves the segregation of classes with the help of a hyperplane. A hyperplane increases the distance that exists
between the closest data point in every category, and it is known as ‘margin.’ If the linear method cannot be applied for the
purpose of separating the dataset, the kernel function can be adopted. It can aid in simplifying the separation process by
transforming the data. Some of the key kernel functions of the SVM model include linear, polynomial, etc. A chief advantage of
the predictive model is that its efficiency does not decline while working on datasets with a large volume of inputs. Another key
advantage of the model is that it is capable of functioning in a compatible manner even if there exists some degree of
disassociation between different classes.
The SAS Enterprise Miner’s HP SVM node was utilized for creating SVMs. While using the predictive model, the data partition
node was used. With the help of the node, the dataset was categorized into training set (50 %), validation set (30 %) and test set
(20 %). In the initial stage, a total of four HP SVM nodes were used. The interior point optimization method was used in the
c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c 41
linear model and the kernel type was set to linear. In the other models, active set was chosen as the optimization method and the
kernel that were adopted were sigmoid, polynomial, and radical basis function.
In the case of the polynomial model, ‘2’ was set as the degree and in the case of the radical basis function, ‘1’was set as the
parameter. For the sigmoid model, 1 and -1 had been set as the parameters. While the SVM Model was being executed, it was
observed that only the linear model functioned in an accurate and effective manner. Based on this observation, emphasis was
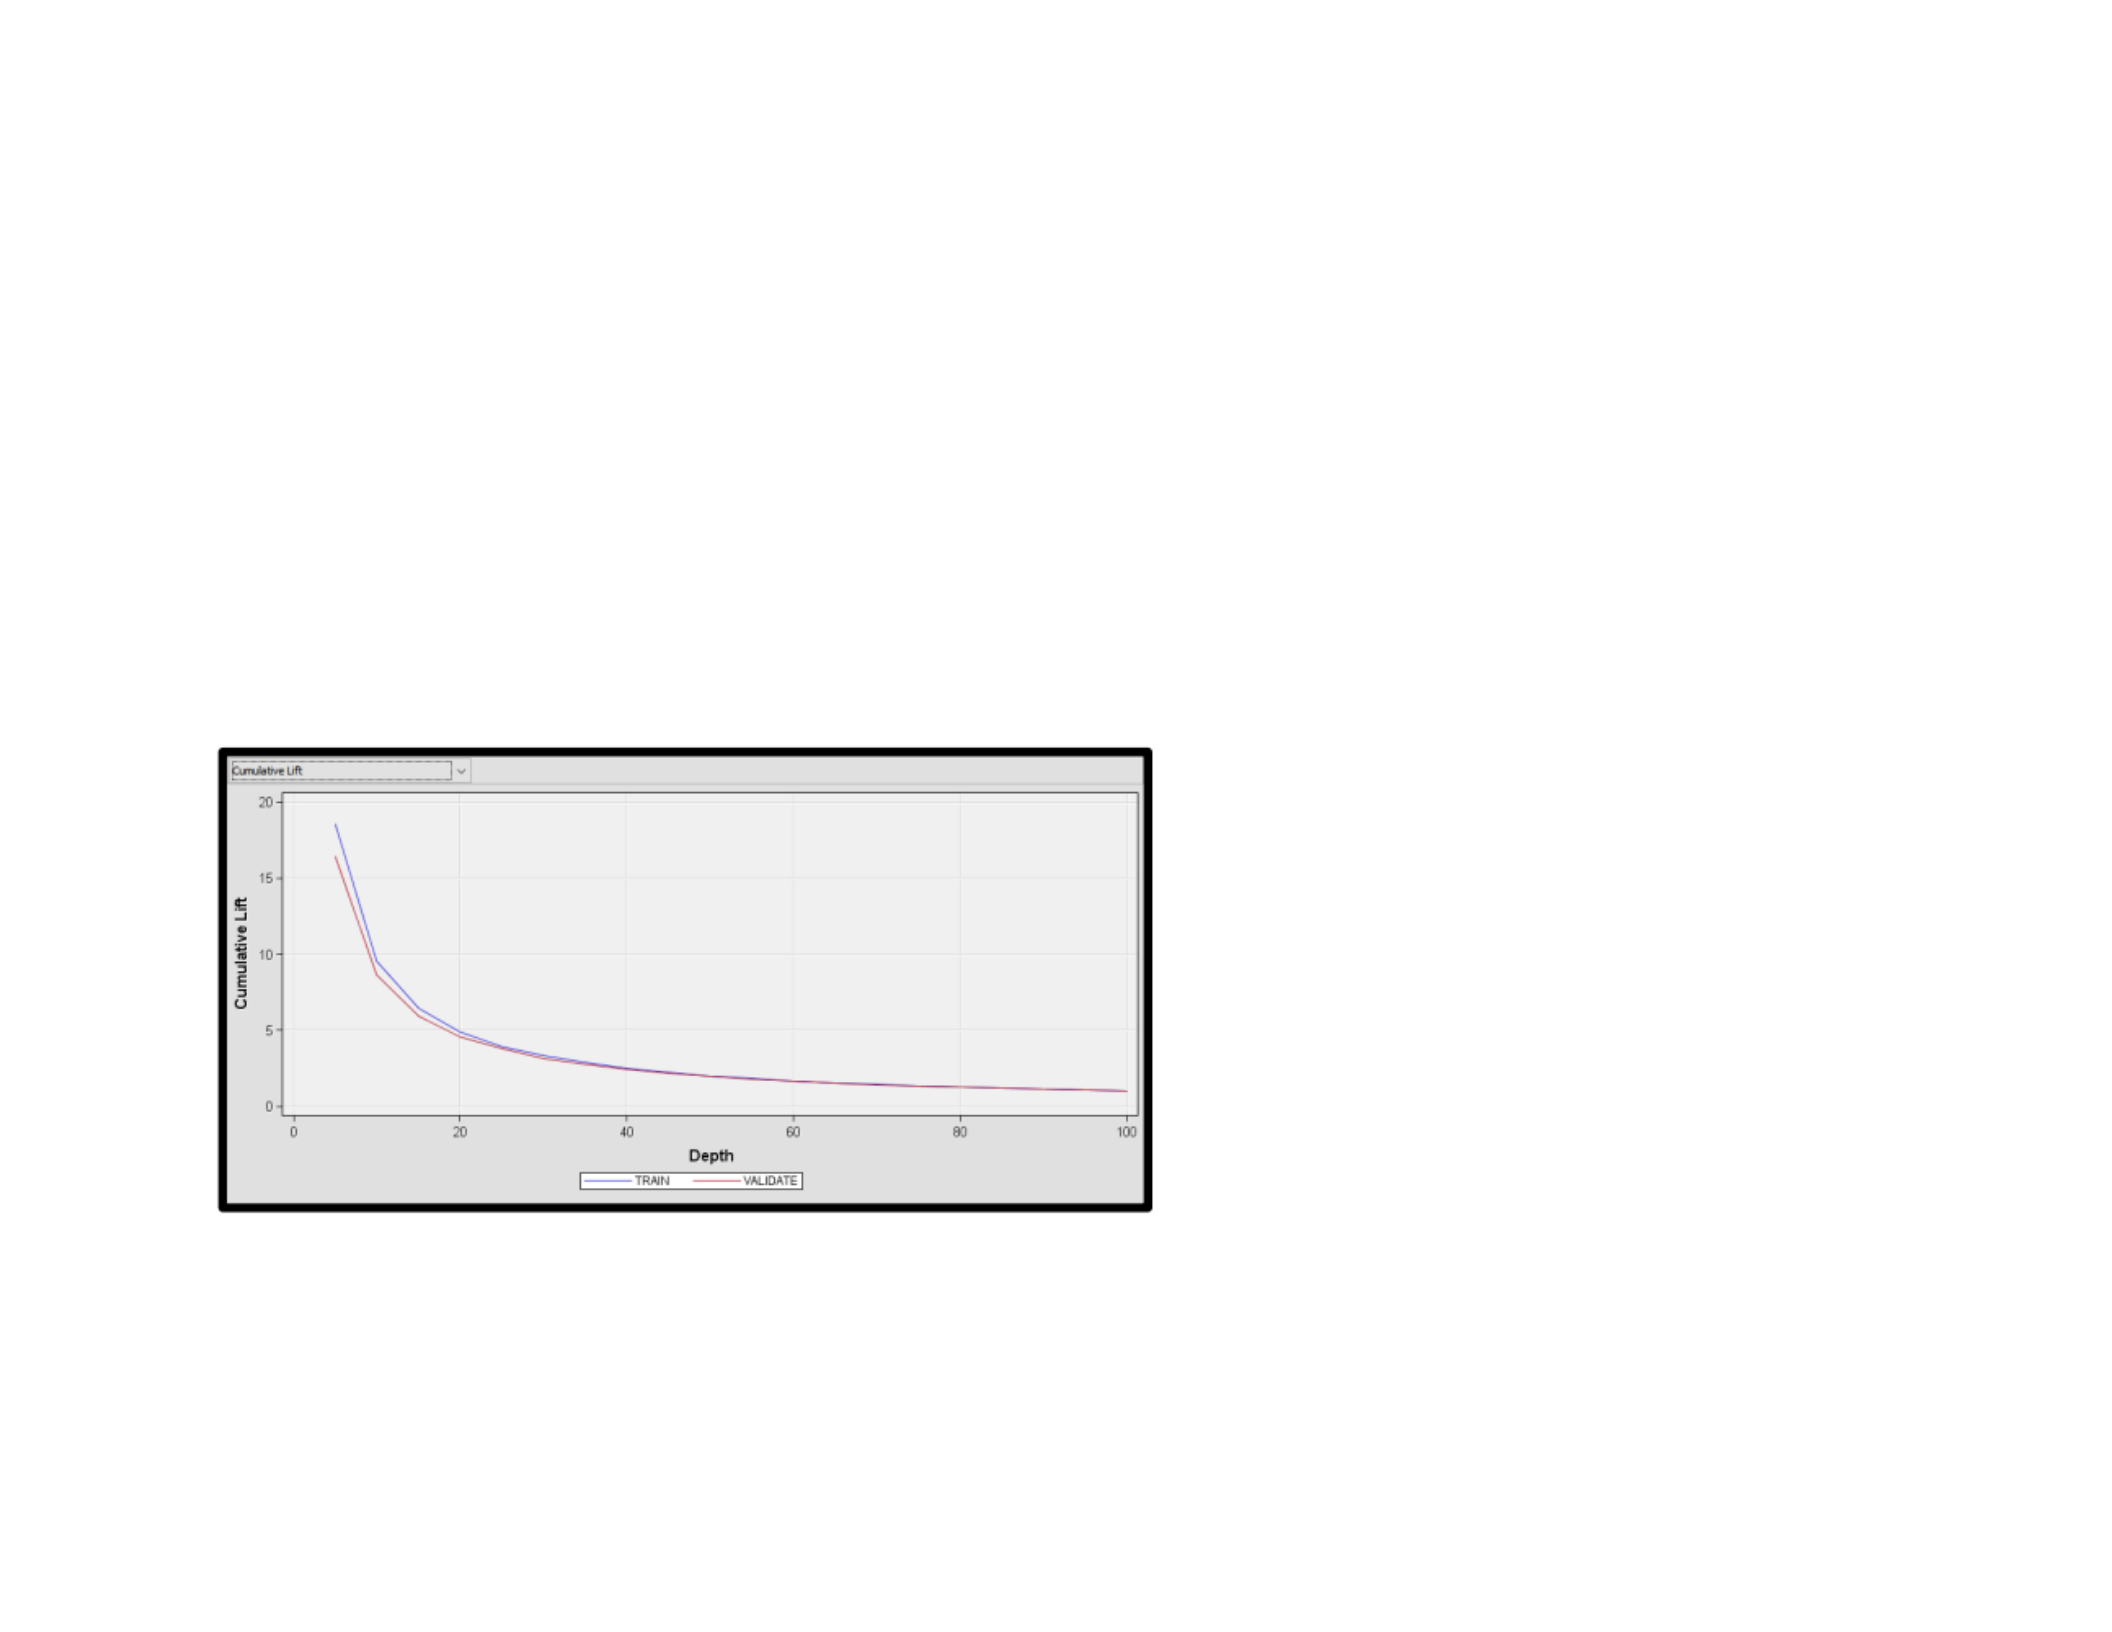
mainly laid on the linear kernel. The graphical representation that has been presented below gives an insight into the cumulative
lift curve. This curve has been derived by using the validation dataset and the training dataset. A model that is effective is likely
to have close validation and training curves. In the case of the project, there is close proximity between these curves which goes
on to indicate that there is no issue relating to overfitting.
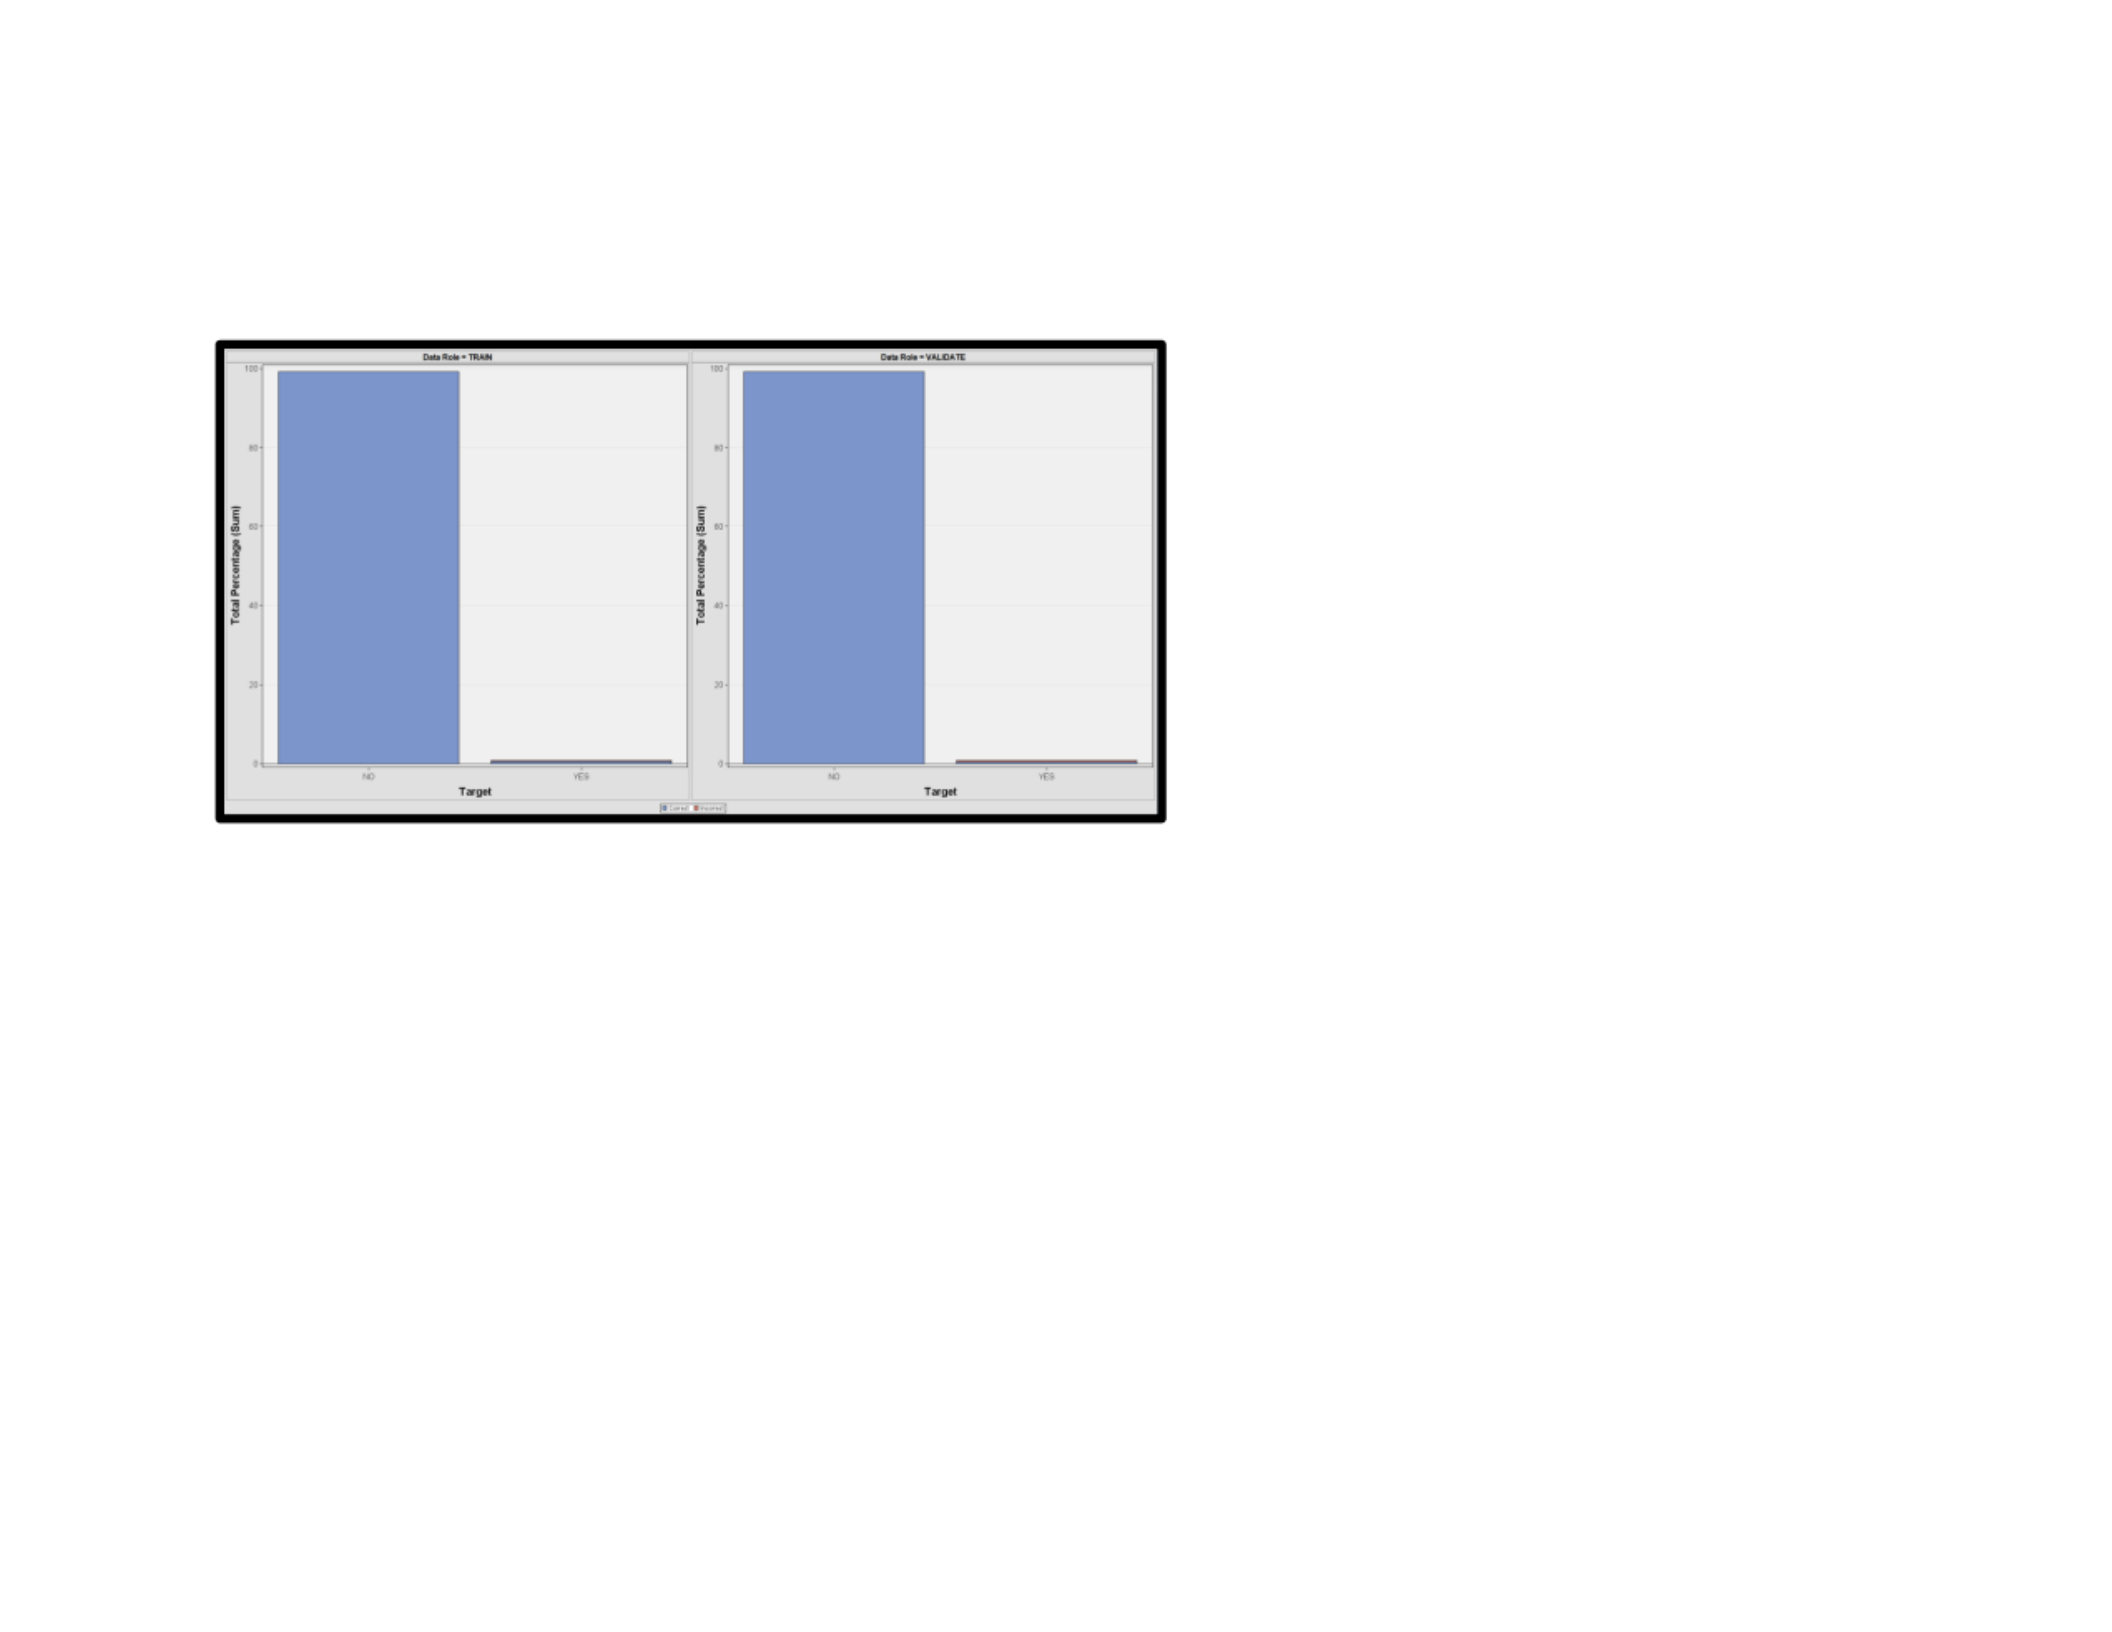
For evaluating the model, another vital instrument that has been used is the classification chart. It includes a bar chart that
represents both accurate along with inaccurate predictions in the context of the validation and training datasets. The classification
c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c 42
chart has been presented below and it has helped in offering a precise visualization of the ability of the SVM predictive model
to classify deadly and life-threatening storms.
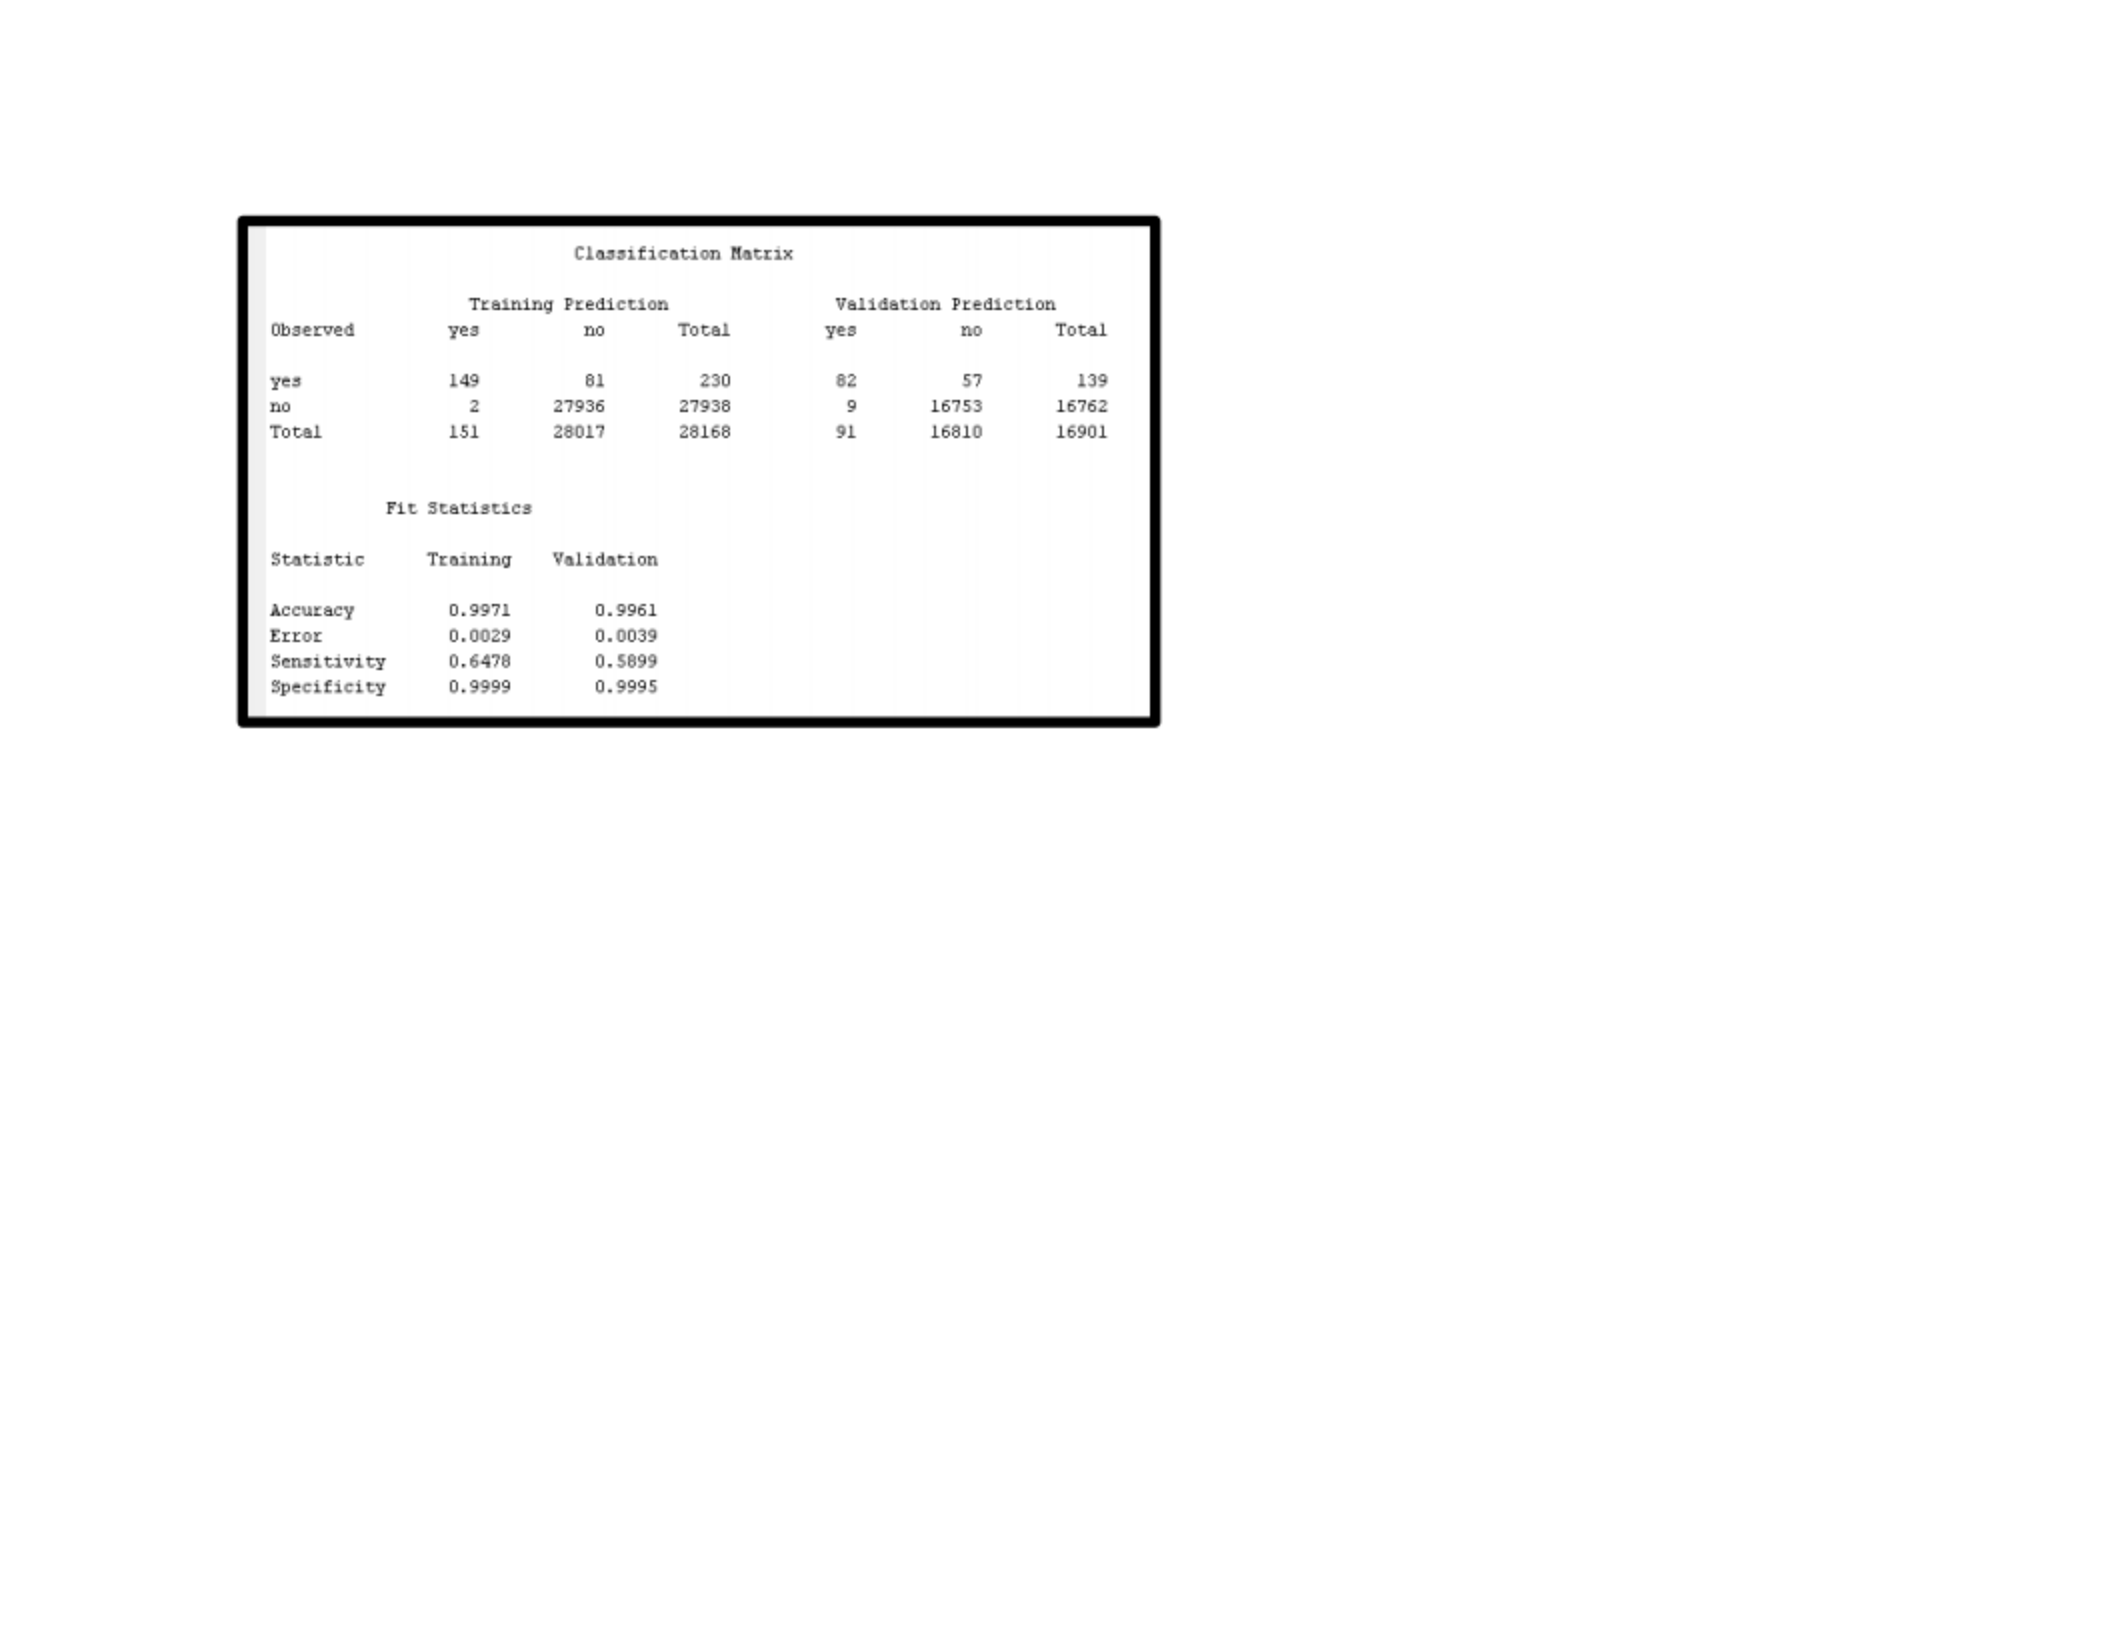
The classification matrix has been further evaluated in order to get a micro-level insight into the predictions as compared to the
actual figures. A perfect model is one in which there is a close match between the predicted classes as well as the actual record
figures in every class. This figure has been integrated into the storm casualties project since it not only sheds light on the
model’s accuracy, but it also helps to get a better insight into its degree of sensitivity.
c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c 43
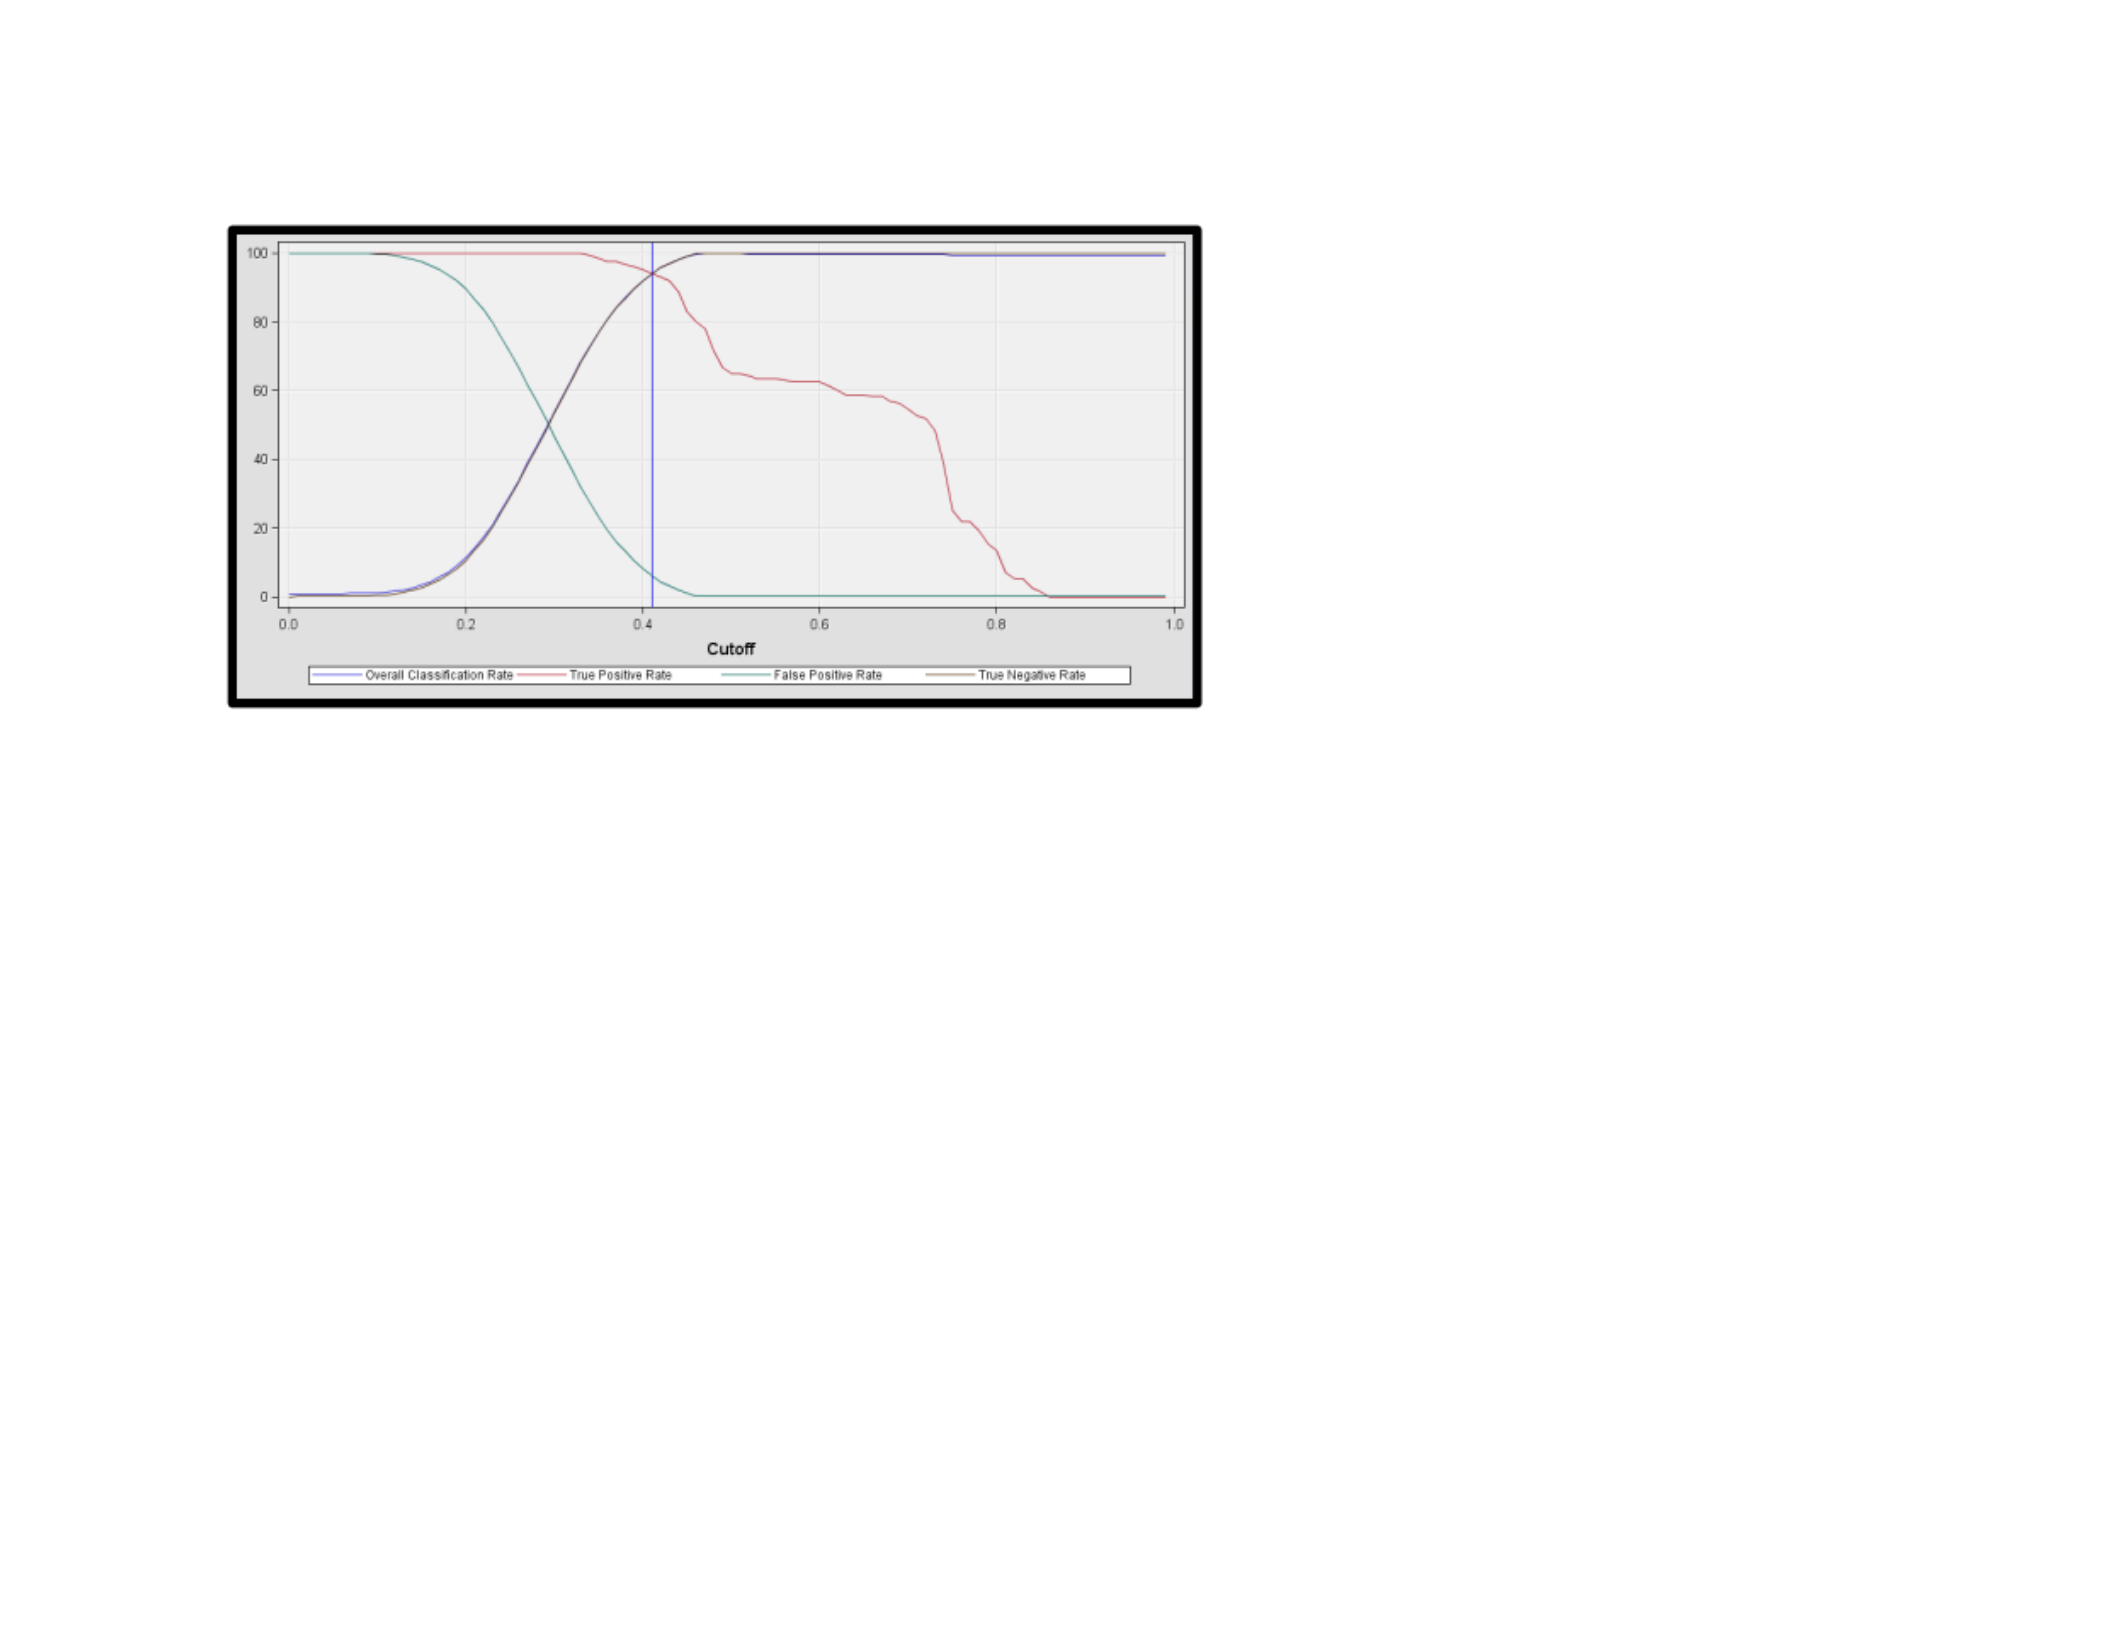
The figure that has been presented gives a glimpse into the classification rate relating to the linear SVM predictive model. The
cutoff threshold of 0.41 has been used. In the initial stage of working on the model, the cutoff threshold of 0.1 was adopted.
However, it was changed because it generated inaccurate results. In the graphical diagram that has been captured, 0.41 seems to
be the ideal cutoff in the predictive model. This is because at this specific cutoff threshold, the true positives rate that is achieved
is 93.91 % and the classification rate relating to the training dataset is 93.90 %.
c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c 44
After altering the predictive model’s cutoff threshold, the evaluation of the classification performance was done. It has been
observed that the overall strength of the model has increased substantially after taking 0.41 as the new cutoff threshold. The
model is able to make better and more accurate classifications relating to storm casualties. For example, while taking into
account the training dataset, there are only 14 ‘false negatives’ values. While focusing on the validation dataset and the test
datasets, the total number of ‘false negatives’ are 22 and 18 respectively, indicating the improved performance of the model.
After the cutoff threshold alteration, the validation sensitivity is 84.17 % which is much higher as compared to the previous
validation sensitivity of 59 %.
c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c 45
Data
False
Positives
True
Positives
False
Negatives
True
Negatives
Accuracy
(%)
Sensitivity (%)
Training
1705
216
14
26233
93.90
93.91
Validation
1048
117
22
15714
93.67
84.17
Test
678
75
18
10497
93.83
80.65
There arise several implications on the scope of the storm casualty’s project. One of the most important implications is that the
linear kernel was able to execute accurate results without showcasing any errors. A major weakness that has been identified
while using the SVM predictive model revolves around the complexity while handling humongous datasets. For example,
initially its sensitivity rate was low at 59 %. However, after changing the cutoff threshold, the sensitivity rate of the validation
dataset increased to 84.2 %. Out of the three predictive models that have been created in the storm casualties project, the
sensitivity rate of the SVM model is highest as compared to the logical regression model and the neural network model
(Narkunienė & Ulbinaitė, 2018). Thus, it seems to be the ideal model that can be used for making predictions about the severity
and deadly nature of storms.
Predictive Model Review
After creating all the three predictive models in the context of the storm casualties project, the most effective model has been
selected. It is necessary to have a robust model that can help to accurately make predictions about the deadly nature of storms.
c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c 46
A comprehensive comparison of the created models has been presented in the table below which has helped to make a
comparison between them.
Model
Cutoff
Threshold
Data
Accuracy
(%)
Sensitivity
(%)
Logistic
Regression
0.01
Training
96.35
95.67
Validation
95.75
79.71
Test
96.05
77.42
Neural
Network
0.01
Training
96.69
92.61
Validation
96.70
74.1
Test
96.73
75.27
SVM
(Linear
Kernel)
0.01
Training
93.9
c c c c c
93.91
Validation
93.67
84.17
Test
93.82
80.65
From the table above it can be seen that the logical regression model is the weakest predictive model that has been used in the
project. On the other hand, the SVM model (Linear Kernel) model is the most effective model that can help in making

c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c 47
predictions from the storm datasets. One of the key elements that has been identified while working on the SVM model is that
after changing the cutoff threshold to 0.41, its efficiency and effectiveness has increased to a significant extent. By using the
model, it will be possible to critically examine datasets relating to storm casualties and infer relevant information from them.
Final Results
Analysis Justification
In the storm casualties project, three predictive models were designed for investigating the storms that occurred in the U.S. in 2017.
The comparison of the models was done to arrive at the most effective model for recognizing life-threatening storms. The objective
was to find a model with more than 80 % accuracy level and over 70 % sensitivity level. Time series graphs, geospatial maps and
word cloud were used for visually representing the storm-related data.
The chief objective of the project was to help minimize storm-related fatalities in the U.S. by accurately identifying deadly storms.
The ‘storm details’ data set was used for creating the target variable i.e., ‘casualties.’ It encompassed direct and indirect fatalities. All
the predictive models showed satisfactory performance and contributed to the target classification.
Word cloud analysis was conducted by using the fatalities data set. However, it was skipped while working on the predictive models
because its variable was related with the ‘casualties’ variable. The data visualizations that were used added value to the project. The
geospatial analysis offered detailed insight into states where there is a high risk of life-threatening storms. The time series graph shed
light on the specific time when the most storm-related deaths occur. The word cloud helped in describing deadly storms.

c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c 48
The predictive models that have been created have offered insight details in the storm casualties project context (Aletdinova &
Bakaev, 2019). The three models that were used are the logistical regression model, the neural networks model, and the Support
Vector Machine (SVM) model. After comparing each of the predictive models, the SVM model (Linear Kernel) model has been
identified as the most effective model to identify life-threatening storms.
Findings
The visualizations that have been used in the project have helped to get an integrated insight into deadly storms that have taken place
in the U.S and the casualties that have been generated as a result of these extreme weather events. The states where the maximum
storm-related fatalities have occurred in the year 2017 include Texas, Florida, and Nevada. Tropical storms and hurricanes have led
to a majority of the deaths.
With the time series graph, it has been possible to get a view into the storm-related fatalities, on the basis of each day and each
month. In the month of August there were maximum storm-related fatalities. During this period, Hurricane Harvey was responsible
for causing havoc in Texas. In the summer season there has been most storm-related deaths. Several hurricanes occurred leading to
significant damage in terms of life and property. c
With the help of the word cloud visualization, 60 words have been identified that are frequently used in storm-related narratives.
Some of the terms are flood, tornado, home, etc. This visualization has only helped in capturing words. However, there is no insight

c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c 49
into the context of these words in the narratives (Merkt, 2019). One of the chief drawbacks of the specific visualization technique is
that it fails to capture how the words have been used and the underlying message that is conveyed. c
While choosing the champion predictive model, a key factor that has been considered is the ease of adoption. Out of the three
models, SVM model seems to be the most feasible. While the logistical regression model has been identified as a weak model, the
problem with the neural networks model is that it is difficult to comprehend. However, each model has added value in the project
context. For example, the logistical regression model has shed light on important variables such as damage to property, storm’s
range, location, injuries, etc.
Review of Success
The project on storm-related casualties in the U.S. can be considered to be a major success because of various reasons. While
conducting the project, it has been possible to achieve several of the key performance indicators (KPIs). One of the major goals of
the project was to arrive at a predictive model with over 80 % accuracy rate with the minimum 70 % sensitivity rate. A key indicator
of the success of the project is that all the three predictive models have succeeded to surpass the minimum accuracy rate prior to the
use of the cutoff threshold. The predictive models also have a sensitivity rate of more than 70 % indicating their effectiveness (Merkt,
2019).
The project has also helped in identifying five features that can help in distinguishing a deadly storm from a non-deadly one. The
logistical regression model offered valuable input on various variables relating to storm features. For instance, it has been identified

c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c 50
that the storms that have the potential to cause immense property damage are likely to be life-threatening in nature. Other key factors
that have been identified include the location of the storms, the quantity of damaged crops and the injuries that have been caused as
a result of storms.
The geospatial analysis helped to ascertain that geographical location is one of the major factors that can contribute to storm-related
deaths. Similarly, the analysis that was conducted with the help of word cloud highlighted the fact that the location of a person during
a storm event could have a significant impact on his possibility of survival. Based on the times series analysis, it has been determined
that the specific time of the year when a storm occurs can impact the possibility of deadly storms.
Since the research is a success, it can be of high value for researchers who intend to work on the storm-related research domain and
help in minimize casualties that arise because of such extreme weather events. Since the accuracy rate and sensitivity rate of the
champion predictive model is high, it can be used as a useful tool to make predictions on deadly storms. The geospatial analysis can
also add value in the practical setting since it can help in promoting the safety of communities which are highly prone to deadly
storms. With the help of the visualization approaches, it is possible to understand the diverse kinds of risks that accompany deadly
storms.
As the project is successful, it can help to increase the average warning time that is available when storm-related risks arise. During
the additional time, it may be possible to take more effective measures to be prepared to face such extreme weather events. A key
criterion that had been identified to consider the project a success is the increase in average warning time by 5 % and lowering the

c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c 51
possibility of false storm alarms by 5 %. However, these aspects are beyond the scope of the project and there is a need to carry out
extra research studies to progress towards these goals. c c c c c c
Recommendations for Future Analysis
Even though the storm casualties project can be considered to be successful, there are a number of areas that require additional
investigation and inquiry. A key aspect that must be considered in future research is that while examining storm-related fatalities,
data spanning several years must be taken into consideration for studying and analysis purposes. This project only focuses on storm
details for 2017. However, by integrating additional data, it is possible to get a comprehensive insight into the subject matter.
While working on the project, it was observed that several natural calamities and disasters took place that influenced the number of
fatalities in the United States of America. However, events such as natural disasters are highly unpredictable in nature and the extent
of damage that may be caused might also vary to a significant extent. As storm-related events can be highly unpredictable in nature
it is vital to expand the timeline of the data that is examined. By taking a small data set, the information that is ultimately derived
might be distorted and it might fail to give a complete picture of the storm-related situation.
A key recommendation that would be made is that data must be taken for at least 10 years. By using a large data set, it will be
possible to get a more holistic and accurate vision relating to storm-related deaths in the United States of America. Such data can also
increase the overall effectiveness of the data visualizations techniques that have been used in the project context. For example, the

c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c 52
new geospatial analysis can help to identify the total number of deaths that have taken place in the nation for a broader length of
time. Thus, a more realistic insight on the topic can be captured by taking into account data that spans a long time. c c c
A key limitation of the text mining approach that was used in the project was that it did not give any insight on the context of the
words that were used in storm narratives. In order to overcome the problem, a feasible option is to include additional elements in the
text mining analysis. It can give a more detailed and comprehensive insight by showing how words have been used to describe
storms and in what context they have been used. These are a few recommendations that have been for researchers who intend to
conduct further research on the storm-related topic. c
References
c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c 53
Adams III, T. E., & Dymond, R. (2019). The effect of QPF on real-time deterministic hydrologic forecast uncertainty. Journal of
Hydrometeorology, 20(8), 1687-1705.
Aletdinova, A., & Bakaev, M. (2019, June). Intelligent data analysis and predictive models for regional labor markets. In
International Conference on Digital Transformation and Global Society (pp. 351-363). Springer, Cham.
Burt, S. (2012). The weather observer's handbook. Cambridge University Press.
Centers for Disease Control and Prevention. (2022, May 4). Fast facts: Firearm violence prevention |violence prevention | injury
Center| CDC. Centers for Disease Control and Prevention. Retrieved June 15, 2022, from
https://www.cdc.gov/violenceprevention/firearms/fastfact.html
Exline, J. D., Levine, A. S., & Levine, J. S. (2006). Meteorology: An educator S resource - NASA. Retrieved June 13, 2022, from
https://www.nasa.gov/pdf/288978main_Meteorology_Guide.pdf
Lim, J. R., Liu, B. F., & Egnoto, M. (2019). Cry wolf effect? Evaluating the impact of false alarms on public responses to tornado
alerts in the southeastern United States. Weather, climate, and society, 11(3), 549-563.
Merkt, O. (2019, September). On the use of predictive models for improving the quality of industrial maintenance: An analytical
literature review of maintenance strategies. In 2019 Federated Conference on Computer Science and Information Systems
(FedCSIS) (pp. 693-704). IEEE.
Midway, S. R. (2020). Principles of effective data visualization. Patterns, 1(9), 100141.

c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c 54
Narkunienė, J., & Ulbinaitė, A. (2018). Comparative analysis of company performance evaluation methods. Entrepreneurship and
sustainability issues, 6(1), 125-138.
NOAA's National Weather Service. (2015, October 1). False alarm reduction research. National Weather Service. Retrieved June
13, 2022, from https://www.weather.gov/bmx/research_falsealarms
NOAA's National Weather Service. (2022, May 20). Storm reports. National Weather Service. Retrieved June 13, 2022, from
https://www.weather.gov/bgm/helpStormReports
Simmons, K. M., & Sutter, D. (2009). False alarms, tornado warnings, and tornado casualties. Weather, Climate, and Society, 1(1),
38-53.
Storm events database. National Centers for Environmental Information. (2021). Retrieved June 13, 2022, from
https://www.ncdc.noaa.gov/stormevents/
Velimirović, D., Velimirović, M., & Stanković, R. (2011). Role and importance of key performance indicators measurement. Serbian
Journal of Management, 6(1), 63-72.
Weather-related deaths and injuries. Injury Facts. (2021, July 20). Retrieved May 28, 2022, from https://injuryfacts.nsc.org/home-
and-community/safety-topics/weather-related-deaths-and-injuries/

c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c c 55

