


Introduction Mergers have become a major strategy
Mergers have become a major strategy for firms’ growth in research-intensive industries. Nonetheless, the
success of mergers depends on whether there is any value creation from the merger of two firms. While
Apple’s $278 million purchase of microchip designer P.A. Semi in 2008 is an example of a successful value-
creating merger, Daimler’s $36 billion-valued acquisition of Chrysler in 1998 is an example of merger failure
due to a misunderstanding of expected merger values (Christensen et al., 2011). Technology and product
market similarities have received much attention as key factors creating merger values (Bena and Li, 2014;
Chondrakis, 2016; Hoberg and Phillips, 2010; Linde and Siebert, 2016; Ornaghi, 2009; Ozcan, 2015; Rao et al.,
2016). Mergers motivated by technology and product market similarities potentially benefit from a larger
knowledge base and
a less competitive market, respectively.
The existing merger literature has focused on the technology proximity within patent classes and
product market similarity between substitute products, which does not explain some mergers motivated
by the technology similarity across patent classes and product market closeness between complementary
products. For example, the merger between Wellfleet and Synoptics in 1994 was based on technology
similarity across patent classes. While Synoptics specialized in information transfer within a single network,
Wellfleet had a comparative advantage in controlling information flow between networks. The merged
firm could process a variety of information including voice and video, indicating significant post-merger
value creation through combining their broadly similar technologies. Further, the merger between Amazon
and Whole Foods in 2017 is an example of the merger based on related type of product markets. The
former excels in its online shopping and delivery system, whereas the latter is well-known for selling high-
quality groceries. Through the merger, Amazon can gain extra profits from food retailing and Whole Foods
can benefit from Amazon’s distribution channels.
Our paper thus examines the roles of technology similarity within and across patent classes and product
market closeness between substitute and complementary products as potential sources of value creation
in mergers. A firm merging with another firm that has similar technologies within and across patent classes
can increase its technological capacity across different R&D areas, which can serve as the basis for absorbing

additional stimuli and information from the external environment. The absorptive capacity hypothesis
suggests that the acquired similar knowledge can provide a cross-fertilization effect wherein old problems
can be addressed through new approaches, while maintaining the elements of commonality that facilitate
interaction between the acquired and acquiring knowledge bases (Cohen and Levinthal, 1990). Further,
mergers between firms with similar and complementary product markets allow the merged firms to
increase their dominance in their common markets and to sell products with complementary demand and
cost structures. First, in the case of horizontal mergers, the merged firms can increase profits by increasing
price through a stronger market power and by reducing costs through scale economies. Second, in the
context of two firms that each sell a product complementary to that sold by the other, neither internalizes
the effect that its own price has on the demand for the others product. If the two firms merge, the merged
firm will increase its profits by accounting for this pricing externality when it sets prices (Cournot, 1838).
The merged firms can also increase profits when the sales of one product generate information spillover on
the demand of the other product (Gal-Or, 1988). Third, the merged firms can increase profits by sharing
costs across products, that is, exploit scope economies.
However, consideration must be made to the challenges that occur in merger analysis, especially the
roles of technology and product market similarities in merger value creation. First, true merger values
driving the decision to merge are unobserved. Thus, quantifying merger value creation due to technology
and product market proximities between acquirers and targets is an empirical challenge. Second, mergers
not only affect the merging firms but also influence the rest of firms in the same merger market. Once a
firm is acquired, then it is excluded from the choice set of other acquirers. Accordingly, every merger within
a same merger market is interdependent with each other. Therefore, an empirical method estimating
merger values needs to account for such strategic interaction among firms competing within a merger
market.
To overcome those challenges, we consider mergers as a two-sided matching problem (Roth and
Sotomayor, 1992) where firms are heterogeneous in their technological and production capacities, and
where the merger value depends on match-specific characteristics between acquirers and targets. Since
our paper focuses on technological proximity and product market similarity as sources of merger value

creation, we postulate that the merger values are a function of the similarity between merging firms’
technologies and product markets. Here, we measure the similarity in technologies by using the
Mahalanobis distance between firms’ vectors of patent share over patent classes. It is shown that mergers
between two firms with more similar technologies increase merger values (e.g. Bena and Li, 2014;
Chondrakis, 2016). The rationale for this finding is that acquiring firms are more likely to understand
expected values of merger with technologically similar target firms. We also measure the similarity in
product markets by using the Mahalanobis distance between firms’ vectors of sales share over business
segments. Merging firms with more similar product markets are expected to gain from reducing
competition in their product markets, internalizing externality between complementary product markets
and exploiting scale and scope economies. Additionally, the merger value function contains a set of control
variables, including geographical proximity, an interaction term of two merger partners’ Tobin’s Q, and an
interaction of their R&D intensity.
We estimate a structural model of two-sided matching to analyze the determinants of the merger value
function. In this model, the same acquirer matched with different targets generates different merger
values, and the merger market is in a pairwise stable equilibrium. That is, two observed acquirer-target
pairs cannot gain by forming counterfactual mergers. Further, we set up a model where an observed
acquirer cannot gain by acting as a target firm in any counterfactual merger, and vice versa. We then
estimate the merger value function using a maximum score estimator approach with the necessary
conditions derived from the stable matching equilibrium (Fox, 2010a). The strength of technology and
product market similarities in creating merger value is identified from comparisons of actual versus
counterfactual mergers. They are the estimated parameters in the merger value function that make the
observed matches best fit the equilibrium matches in terms of merger value. Specifically, the total value
of any two observed mergers exceeds the total value of their counterfactual mergers formed by changing
merger partners.
Our empirical results show that similar technologies and product markets between acquirer and target
are important determinants in creating value in mergers. Taking advantage of the structural estimation,
we conduct counterfactual experiments to examine the importance of the similarity between merging

partners’ technologies and product markets in creating merger value. If the similarity in either the
technology or product market in the merger value function was ignored, the model prediction rate, a
measure of goodness-of-fit, would fall by about 15 and 7 percentage points relative to that of benchmark
model, respectively. The merger value would fall by about 67% and 25% compared to the benchmark case
if it is assumed to be no impact of the similarity in technologies and product markets on the merger value
function, respectively.
We then modify our benchmark model in various aspects by changing the original model assumptions.
First, we use the acquirers’ market instead of the target firms’ as an alternative market definition. This
model extension examines whether our benchmark estimation results are driven by a specific merger
market definition. Second, we restrict the model to allow firms only to choose whom to merge with, so
that the role of being either an acquirer or a target is predetermined as the observed outcome. This model
examines whether fixing the role of each firm to either the acquirer or target makes a difference in the
parameter estimates. Encouragingly, our results are robust to those modifications. Finally, we estimate the
model with alternative measures of technology and product market similarities based on the correlation
measure proposed by Jaffe (1986). As Bloom et al. (2013) point out that the Mahalanobis measure of
similarity has an advantage in the sense that it can reflect technology relatedness across different patent
classes or product market closeness across complementary products, which cannot be captured by the
correlation measure. We find that the impacts of technology and product market similarities are lower
when the correlation measures of similarity are used instead of the Mahalanobis measure of similarity. It
suggests that technology proximity within and across patent classes and product market similarity across
substitute and complementary products are all contributing to value creation in mergers.
Firms merge with each other under the expectation of mutual gains, but the sources of gain can create
values through different channels. Mergers that do not care about the technology similarity cannot
capture positive innovation impacts during the post-merger periods. However, mergers without the
influence of the product market similarity still enjoy positive and significant postmerger innovation
impacts. Thus, we suggest that mergers with similar technologies may seek synergy through the channel
of improving post-merger innnovation performances. These results confirm that our model captures the

initial merger-specific value reasonably well, and the mergers between firms with similar technologies do
have economic impacts.
Our paper contributes to the empirical literature using a two-sided matching model to examine merger
partner choices. Akkus et al. (2015), Ozcan (2015), and Linde and Siebert (2016) are three closest papers
to ours in that they use the two-sided matching model with transferable utility. Akkus et al. (2015) find
positive effects of scale economies on the partner choices in bank mergers. In particular, they show that
banks are more likely to merge with each other if they have similar asset size and number of branches. In
a close relationship with our work, Ozcan (2015) and Linde and Siebert (2016) find that the similarities in
technology and product between acquirer and target increase merger value.
There is another empirical literature on two-sided matching with non-transferable utility, which jointly
examines the determinants of merger partner choice and post-merger outcomes. Park (2013) analyzes
mergers in the U.S. mutual fund sector. She finds that firms using similar fund distribution channels are
more likely to merge, and they achieve a higher asset growth rate after the merger. After analyzing 1,979
mergers in various industries, Rao et al. (2016) conclude that knowledge similarity has positive impacts on
both merger partner choice and post-merger patent application. Ishihara and Rietveld (2017) examine 85
acquisitions and 5,916 products in the U.K. video game industry. They find that the number of past
collaborations and geographical closeness between video game publishers and developers positively affect
the merger value function by developing high-quality products and improving sales performance after the
merger.
Our paper differs from those previous studies in three aspects. First, we examine a larger set of post-
merger outcomes than previous studies do. In addition to the post-merger market valuation effect, we
examine various sets of innovation activities to identify the channels through which mergers create value.
Particularly, we show that mergers motivated by technology similarity create value through improving
their innovativeness. Second, we extend the two-sided matching model with transferable utility to allow
firms not only to choose whom to merge with, but also to choose to be either an acquirer or a target in a
merger. These features of our model extend the model used in Akkus et al. (2015), Ozcan (2015) and Linde
and Siebert (2016), which only allows the decision of whom to merge with. Third, we employ the

Mahalanobis distance to measure technology and product market similarities between merging firms,
which allows our model to incorporate the impact of technology similarity across patent classes and
product market closeness across complementary product markets.
Section 2 discusses the model and estimation methodology. Section 3 describes data. Section 4 presents
empirical results. The last section concludes.
1.2 Model and Estimation
We consider merger as a two-sided matching problem (Roth and Sotomayor, 1992). First, firms are
heterogeneous in their technological and production capacities. Second, the merger value depends on the
synergy between acquirer and target.
Merger market is defined by merger transaction year and target firm’s industry type based on Standard
Industrial Classification (SIC) code following Ozcan (2015). In other words, a merger transaction performed
in one merger market is independent of a merger deal made in another market. For instance, there are
two merger deals performed by Cisco systems in our sample. One is a transaction with Summa Four in
1998, a firm that operates in SIC code 3661 (Telephone & Telegraph apparatus). The other one is a deal
with Scientific-Atlanta in 2006, a firm that operates in SIC code 3663 (Radio & TV broadcasting &
Communications equipment). According to our market definition, the former deal does not affect the latter
because they are made in two different merger markets, even though the acquirer in those two
transactions is the same. This assumption implies that a single acquirer is treated as two different firms
when it matches with two distinct targets in two different merger markets. Further, we assume the
matching is one-to-one because a target disappears after the merger, so that it cannot merge with more
than one acquirer.
1.2.1 Model
There are two sets of merger participants in each merger market m = 1, 2, ..., n: one is a set of acquirers,
Am, and the other one is a set of targets, Tm. Thus, a set of potential mergers in a merger market m is Mm
= Am × Tm. A collection of realized mergers in the merger market m is called a matching µm ⊂ Mm. Hence,

an acquirer a’s merger partner is written as µm(a), and a target t’s merger partner is denoted by µm(t). For
notational simplicity, we drop the subscript m for a merger market in later sections.
Every potential merger has a merger value, which is an expected net present value (NPV) measured at
the time of merger. We denote V(a, t) as the expected value of a merger between acquirer a and target t.
Let the acquirer a’s valuation for merging with target t be Va(a, t). Then,
Va(a, t) = V(a, t) − pat, where pat is the transfer payment from a to t. Accordingly, the target t’s value from this
merger becomes Vt(a, t) = pat. Therefore, the merger value between a and t becomes Va(a, t) + Vt(a, t) = V(a,
t).
The concept of equilibrium used is pairwise stability. We define a merger match to be pairwise stable
if there is no blocking pair whose firms want to deviate from their current merger and form a new merger
by themselves. Formally, a matching µ is pairwise stable if the following inequalities hold:
V(a, t) − pat ≥ V(a, t˜) − pat˜,
(1.1)
V(a˜, t˜) − pa˜t˜ ≥ V(a˜, t) − pat˜ .
(1.2)
V(a, t) and V(a˜, t˜) are match values of realized mergers in µ, where a˜ ∈ A \ a and t˜ ∈ T \ t. The above
inequalities require that acquiring firms a and a˜ cannot gain from counterfactual mergers formed by
swapping targets t and t˜. We assume that every acquirer or target has non-overlapping preference
rankings over all the potential partners in the same merger market. This assumption implies that a
matching equilibrium is unique.
Merger transaction price is a transfer payment from acquirer to target. For our model with transferable
utility, it allows a weaker acquiring firm to induce a stronger target firm to participate in the merger by
offering higher proportion of their merger value to the target. The transfer pat˜ and pat˜ are not available
from data on observed mergers. For the acquirer a to be able to purchase the target t against its rival firm
a˜, the transfer payment pat should be weakly higher than pat˜ . Moreover, pat should not be strictly greater
than pat˜ because a’s payoff from the realized match Va(a, t) (= V(a, t) − pat) falls as pat increases. Thus, pat
= pat˜ at the stable matching equilibrium. We apply this logic to another observed match between acquirer
a˜ and t˜, so that pa˜t˜ = pat˜ at the stable equilibrium. Accordingly, the inequalities (1.1) and (1.2) can be
written as
V(a, t) − pat˜ ≥ V(a, t˜) − pat˜,
(1.3)
V(a˜, t˜) − pat˜ ≥ V(a˜, t) − pat˜ .
(1.4)

Then, we add the inequality (1.3) to (1.4) to derive the following inequality for the stable merger matching
equilibrium:
V(a, t) + V(a˜, t˜) ≥ V(a, t˜) + V(a˜, t). (1.5)
In other words, the total value of realized mergers is weakly greater than the total value of counterfactual
mergers formed by exchanging merger partners.
The existing literature assumes that the sets of acquirers and targets are separate, i.e. there is no
overlapping firm in both sets. However, whether a firm is an acquirer or a target is not predetermined.
Rather, it is a part of merger decision. Hence, we use broader sets of acquirers and targets in our matching
model by incorporating actual acquiring firms into the set of potential target firms, and vice versa.
This extended model needs to incorporate additional inequalities. The first set of inequalities are the
same in the inequality condition (1.5) from the pairwise stable equilibrium for two observed matches (a,
t) and (a˜, t˜). Since the actual acquirer a˜ might be purchased by another actual acquiring firm a before
the realized merger between a and t, we can additionally consider the following inequlities in the stable
matching equilibrium:
V(a, t) − pat ≥ V(a, a˜) − [V(a˜, t˜) − pa˜t˜],
(1.6)
pat ≥ V(t, t˜) − pa˜t˜,
(1.7)
V(a˜, t˜) − pa˜t˜ ≥ V(a˜, a) − [V(a, t) − pat],
(1.8)
pa˜t˜ ≥ V(t˜, t) − pat.
(1.9)
Then, by adding the inequality (1.6) to (1.7) or summing the inequalities (1.8) and (1.9), we obtain the following
additional inquality condition for the stable matching equilibrium.
V(a, t) + V(a˜, t˜) ≥ V(a, a˜) + V(t, t˜). (1.10)
This inequality condition implies that actual merging firms cannot gain from mergers with their rival firms.

1.2.2 Estimation
In this subsection, we first discuss the specification of merger value function. Then, we discuss the
estimation of our structural model, which is based on the maximum score estimation proposed by Fox
(2010a). Several authors apply this methodology to their merger analyses (Ozcan, 2015; Akkus et al., 2015;
Linde and Siebert, 2016; Park, 2016).
Specification of Merger Value Function
This chapter explores the impacts of technology and product market similarities on value creation of
merger. Thus, we assume that the merger value function depends on ex-ante technology and product
market similarities between potential merging partners.
Merging with firms with similar technologies can realize efficiency gains by eliminating duplicated R&D
resources and assimilating the target’s technology into existing resources (Cohen and Levinthal, 1990).
Some prior studies suggest that technology similarity is a determinant of merger value creation or post-
merger outcomes. Ozcan (2015) and Linde and Siebert (2016) present that technology similarity increases
merger value. Rao et al. (2016) find that knowledge similarity between acquirer and target increases
merger value as well as the combined number of patents after the merger. Makri et al. (2010) conclude
that technology similarity has a positive impact on post-merger R&D productivity.
Moreover, merging with firms with technologies in different patent classes can increase a firm’s
knowledge base and allow knowledge transfer across different R&D areas, which can serve as the basis for
absorbing additional stimuli and information from the external environment. The absorptive capacity
hypothesis suggests that acquired knowledge can provide a cross-fertilization effect as old problems can
be addressed through new approaches or by a combination of old and new approaches, while maintaining
the elements of commonality that facilitate interaction between the acquired and acquiring knowledge
bases (Cohen and Levinthal, 1990). Although similar technologies in different R&D areas do not draw much
attention as drivers of merger value function, the existing papers focus on its impacts on post-merger
outcomes (Cassiman et al., 2005; Makri et al., 2010). They present that complementary technologies
between merger partners improve post-merger innovation performances, such as the number of patents

after the merger. These results suggest that firms have incentives to merge with the other firm with similar
technologies in different patent classes. Thus, we present our first hypothesis as follows:
Hypothesis 1. Technology similarity between acquirer and target creates merger value.
Merging with firms producing homogeneous products can increase market power unilaterally and
collusively through relaxing defect incentive by merging with competitors that produce similar products.
This enables the merged firm to set a price higher than the pre-merger price due to increase in market
power (Farrell and Shapiro, 1990). Moreover, the merged entity can gain from exploiting scale economies.
Some prior studies suggest that product similarity is a determinant of merger value creation or post-
merger outcomes. Ozcan (2015) and Linde and Siebert (2016) present that product similarity increases
merger value. Hoberg and Phillips (2010) find that merger is more likely to occur between firms using
similar product market language, and this type of merger transaction increases post-merger outcomes
such as stock returns and cash flows.
Moreover, merging with firms producing complementarity products allow the merged firms to sell
products with complementary demand and cost structure. First, in the context of two firms that each sell
a product complementary to that sold by the other, neither internalizes the effect that its own price has
on the demand for the other’s product. This leads to double marginalization. If the two firms merge, the
merged firm will increase its profits by accounting for this pricing externality when it sets prices (Cournot,
1838). The merged firms can also increase profits when the sales of one product spillover information on
the demand of the other product (Gal-Or, 1988). Second, the merged firms can increase profits by sharing
costs across products, i.e. scope economies. Yu et al. (2015) find that a potential acquirer chooses a target
firm with products complementary to its own products in their sample of pharmaceutical firms.
Accordingly, we suggest our second hypothesis as follows:
Hypothesis 2. Product market similarity between acquirer and target create merger value.
Based on the aforementioned hypotheses, we specify the following merger value function

F(a, t|α) = α1TSat + α2PSat + α3SameStateat + α4(Tobin0s Qa × Tobin0s Qt)
+ α5(R&D intensitya × R&D intensityt) + ηat, (1.11)
where ηat represents an unobserved error term for the merger between a and t. TSat and PSat represent
measures of the similarity in technology and product market between acquirer a and target t, respectively.
The parameters of interest are α1 and α2. A positive and significant α1 supports Hypothesis 1, whereas a
positive and significant α2 supports Hypothesis 2.
In Equation (1.11), we include two sets of control variables. The first set contains a variable related to
geographical proximity. SameStateat is a dummy variable equal to 1 if an acquirer and a target firm are
located in the same state and zero otherwise. It is a proxy variable for geographical distance between
merging firms. Some previous studies suggest that when two firms are located close to each other, they
are more likely to merge (Ozcan, 2015; Erel et al., 2012). Thus, we include this variable into the merger
value function to control for geographical closeness between merging firms.
The second set of control variables includes the interaction term of Tobin’s Q and that of R&D intensity
between acquirers and targets. Rhodes-Kropf and Robinson (2008) suggest that two firms with similar
Tobin’s Q are more likely to merge. The synergy from this type of merger is supported by the property
rights theory introduced by Grossman and Hart (1986). According to the theory, if two firms’ assets have
similar valuations, they should be controlled by a single ownership to realize benefits of complementary
assets. Further, existing studies suggest R&D intensity is the main determinant of merger (Bertrand, 2009;
Blonigen and Taylor, 2000; Desyllas and Hughes, 2010). Particularly, a firm with lower R&D intensity is more
likely to acquire firms with higher R&D intensity for improving its innovation. For example, in 1998,
Hewlett-Packard acquired Heartstream, a maker of automated external defibrillators, which has a R&D
intensity about 30 times higher than itself.
Maximum Score Estimation
We employ the maximum score estimation to estimate the merger value function. Let the merger value
function between acquirer a and target t be F(a, t) = V(a, t) + ηat, where V(a, t) refers to observable
merger values and ηat represents an unobserved merger-specific error term. Suppose that there are two
realized mergers, (a, t), (a˜, t˜) ∈ µ. Also, define
q(α) = V(a, t|α) + V(a˜, t˜|α) − V(a, t˜|α) − V(a˜, t|α),
where α represents a vector of parameters to be estimated in the observable part of the merger value
function. Thus, q(α) indicates a difference between total match values of observed mergers and total
match values of counterfactual mergers formed by exchanging merger partners. According to Fox (2010b),
the only necessary condition to identify parameters in the merger value function using maximum score
estimation is the following rank order property:
q(α) ≥ 0 if and only if Prob{(a, t), (a˜, t˜) ∈ µ} ≥ Prob{(a, t˜), (a˜, t) ∈ µ}.
In other words, if the total value of two observed mergers exceeds the total value from counterfactual
mergers, then the probability of observing realized mergers is higher than the probability of observing
counterfactual mergers. And the reverse is also true. Under this rank order condition, the maximum score
estimator α can maximize
n
Q(α) = ∑, (1.12)
m=1 (a,t),(a˜,t˜)∈µm
over the parameter space in a stable matching equilibrium, where Q(α) is the number of holding inequality
(1.5) in all merger markets. Even though the derivation of the stable matching equilibrium condition
requires the transfer payments, the inequality (1.5) for implementing the equilibrium does not contain
them. We thus adopt the estimation method proposed by Fox (2010a), which does not require the
information on the merger transaction price (i.e. transfer data). Nonetheless, we need to normalize the
coefficient of an interaction term between Tobin’s Q of acquirer and target to +1 and the interpretation of
the other variables is relative to Tobin0s Qa × Tobin0s Qt. The rationale for using this normalization is as
follows. First, we pick up the Tobin’s Q interaction term as the explanatory variable for normalization
because two firms with similar Tobin’s Q are more likely to merge with each other according to Rhodes-
Kropf and Robinson (2008), implying positive impacts on merger value creation. Second, any positive
monotone transformation of coefficients does not affect inequalities that allow us to compare the relative
importance of covariates.
Further, we assume that the role of firms in the merger as either acquirer or target is not
predetermined. We model the observed acquirer cannot gain by acting as target in any counterfactual
merger, and vice versa. Thus, we maximize the following objective function to estimate the parameters
n
Q(α) = ∑, (1.13)
m=1 (a,t),(a˜,t˜)∈µm
where q1(α) = V(a, t|α) + V(a˜, t˜|α) − V(a, t˜|α) − V(a˜, t|α), q2(α) = V(a, t|α) + V(a˜,
t˜|α) − V(a, a˜|α) − V(t, t˜|α).
In addition, since acquirer- and target-specific attributes cancel out in the inequalities, the only
relevant terms in merger value function are match-specific features and interactions between each merger
partner’s characteristics. For example, a merger occurs when acquiring firm’s free cash flow increases
because managers tend to use the increased free cash in performing merger instead of paying it to
shareholders (Jensen, 1988). Such non-interactive term could contribute to merger value, but are
differenced out in equilibrium because both the actual and counterfactual partners value them in the same
way. Our matching model is thus robust to, for example, acquirer-specific attributes, target-specific
attributes, and firm fixed effects.
The objective function in (1.13) yields only integer values. The more inequalities satisfied, the better the
matching model statistically fits the data. This estimation technique is semiparametric
specific characteristics (see Akkus et al., 2015)
in the sense that it does not impose any restriction on unobservables in the objective function. This
estimator is easy to implement because it only requires a set of inequalities necessary to derive a stable
matching equilibrium. Thus, it is not computationally burdensome due to a multidimensional integration
of idiosyncratic error terms, which avoids the curse of dimensionality (Fox, 2010b). Following Akkus et al.
(2015) and Ozcan (2015), we apply the differential evolution algorithm for obtaining point estimates of
parameters that maximize the objective function. Since the maximum score inequality conditions in (1.13)
does not uniquely determine estimated values of parameters, we run the estimation repeatedly by using
20 different starting values of point estimates and select the coefficient vector that maximizes the number
of equilibrium inequalities
satisfied.
Confidence Intervals
To generate confidence intervals for point estimates from the maximum score estimation, we employ
subsampling procedures suggested in the literature (Politis and Romano, 1992; Delgado et al., 2001). First,
we set the subsample size to be 75 observations, which is about 1/3 of the entire sample size, i.e. 224
observations. For each subsample, we compute the parameter vector by maximizing the objective function
and use 100 replications to construct the confidence intervals. Let the parameter vector based on the
subsamples be αˆsub, and the parameter vector based on the full sample be αˆ. The approximate sampling
distribution for our parameter vector can be
computed by using for each subsample. Our maximum score
√
estimates converge to the sampling distribution of α˜sub at the rate of 3 224. We compute 95% confidence
intervals from the 2.5th percentile and 97.5th percentile of this empirical sampling
distribution.
1.3 Data
1.3.1 Data Sources and Sample Construction
Throughout the chapters, a two-sided matching model is a theoretical framework. We study the
matching market of acquirers and targets with the merger records from DYNASS file.5 The data is collected
from the National Bureau of Economic Research (NBER) Patent Data Project website. For the periods
between 1996 and 2006, we observe 224 merger deals in the U.S. manufacturing industries (SIC code
2000-3999). Table 1.3 shows these merger transactions classified by target firm’s industry type and
transaction year. Our sample mergers cover five industry types, namely pharmaceutical, semiconductor,
electronics, computer & communications, and others.6 These industries are appropriate to examine the
role of similar technologies and product markets in determining merger value function for the following
reasons. First, they have experienced many merger transactions in recent decades according to Shleifer
and Vishny (2003). Second, firms in these sectors are more technology- and product-dependent than firms
in other industries such as finance or service sector. It is also related to our selection of merger samples.
That is, since our 224 merger samples are composed of merging firms that are granted at least one patent
during the sample periods, those firms are considered as high-tech firms. Thus, the relationship between
merging partners’ technologies and product markets would play a critical role in merger decision.
In chapters 1 and 3, our merger sample only covers firms actually participating in merger deals
following most of previous literature (e.g. Akkus et al., 2015; Ozcan, 2015; Linde and Siebert, 2016). In
other words, standalone firms are not included in the samples. Our sample provides sufficient data
variations to identify the match-specific determinants driving the decision of whom to merge with. On the
other hand, we use standalone firms in the sample throughout Chapter 2. The rationale for considering
these nonmerging firm samples is that we can address the endogeneity problem caused by the correlation
between unobserved factors affecting merger partner choice
5It contains information of each firms’ ownership change over time.
675 SIC codes for each industry are as follows: pharmaceutical (2834, 2835 and 2836), semiconductor (3674), electronics
(3600, 3620, 3634, 3640, 3670, 3677, 3678, 3679, 3690, 3825 and 3845), computer & communications (3570, 3571, 3572, 3575,
3576, 3577, 3578, 3661, 3663 and 3669), and other sectors (2090, 2631, 2650, 2670, 2821, 2851, 2860, 2890, 2911, 3050, 3060,
3080, 3081, 3089, 3231, 3260, 3312, 3420, 3443, 3460, 3480, 3490, 3510, 3531, 3533, 3537, 3559, 3560, 3561, 3564, 3569, 3579,

3580, 3585, 3590, 3630, 3651, 3714, 3728, 3821, 3823, 3826, 3827, 3829, 3841, 3842, 3851, 3861, 3944 and 3949). More detailed
descriptions for each industry are shown in tables 1.1 and 1.2.
and measures of technology and product market similarities.
According to model assumptions in previous literature, merger transaction occurs between firms
within a single merger market. Each merger market is constructed by the combination of merger deal year,
from 1996 to 2006, and target firms’ 5 industry types, pharmaceutical, semiconductor, electronics,
computer & communications, and other sectors. An equilibrium concept in the two-sided matching model
is pairwise stability, meaning that there is no blocking pair of agents who want to deviate from a current
match and form a new match by themselves. Based on this, a pairwise stable matching equilibrium
requires at least two observed matches. Accordingly, we merge some of the acquirer-target pairs with
others in a different merger market but with same industry type when the former is the only match in its
original market. After adjusting the number of merger matches in every market, we identify 46 merger
markets for empirical analysis.
We obtain information on financial variables of our sample firms from the Compustat. The Compustat
provides each firm’s records on stock market capitalization, book value, total assets, sales and R&D
expenditure. We use those financial features to construct control variables used in our matching model
and to measure post-merger outcomes. Further, we obtain the data on patents and patent citations from
Lai et al. (2014) in the Institute for Quantitative Social Science at Harvard University (IQSS) website. Among
the data, we use information on all the U.S. patents applied during 1994 and 2008. While the sample
periods of the merger dataset is from 1996 to 2006, we extend the periods of the patent dataset to 1994-
2008 to construct the pre-merger patent portfolio for mergers in 1996 and post-merger outcomes for
mergers in 2006. Note that the number of patents and patent citations significantly decreases as time
approaches 2008 (the last year of the patent dataset) due to sample period truncation. That is, since the
entire sample does not contain patents granted and citations received after 2008, the number of those
innovation outcomes in the data is less than actual counts reflecting post-2008 information. Therefore, we
control for year effects in the estimation of post-merger innovation outcomes to tackle this problem of
sample period truncation.
1.3.2 Variable Definitions
The United States Patent and Trademark Office (USPTO) categorizes all the granted patents into 642
technology-based classes. A firm i’s vector of patent shares over those patent classes is represented by Fi
= (Fi,1, Fi,2, ..., Fi,642), where Fi,c is the firm i’s ratio of patent counts in class c to the total number of patents.
We measure technological similarity by Mahalanobis distance (MAHA) between firms’ vectors of patent
shares following Bloom et al. (2013). The way to construct this measure is as follows. First, form a matrix
of every firm’s vector of patent shares over technology classes. That is, the 642 × N matrix, F , ...,
FN0 ], is the matrix of all the firms’ patent distributional vectors over 642 classes, where Fi is the firm i’s 1 ×
642 vector of patent shares across classes and N is the total number of firms. Then, normalize each column
of the matrix F, so that obtain another matrix F˜ 02 1/2 , ..., . Third, form a N × 642
matrix C , ..., F, where F(,c) is the class c’s 1 × N vector of patent shares over N
0
firms. Then, C˜ (F(,1)F0 ) (F(,2)F ) , ...,is the normalized N × 642 matrix of C. Thus, a 642 × 642 matrix CCORR =
C˜0C˜ indicates a uncentered correlation between vectors of all the classes’ patent shares across firms.
Finally, to capture technology similarity between different patent classes, use a N × N matrix TECHSPILL =
F˜0 × CCORR × F˜. Hence, each element of the TECHSPILL matrix is a Mahalanobis distance between two
corresponding firms. That is, Mahalanobis distance is the weighted correlation between firms’ patent class
distributional vectors where the weight is defined by the correlation among all the patent classes (CCORR).
That is,
MAHA = F˜0WmF˜, (1.14)
where F˜ is a matrix of all firms’ normalized vectors of patent shares in patent classes and Wm is a weighting
matrix of correlation between patent classes.
We illustrate the computation of MAHA with the following example. Suppose that there are 3 patent
classes, and that acquirer A’s and target T’s vectors of patent shares over 3 classes are FA =
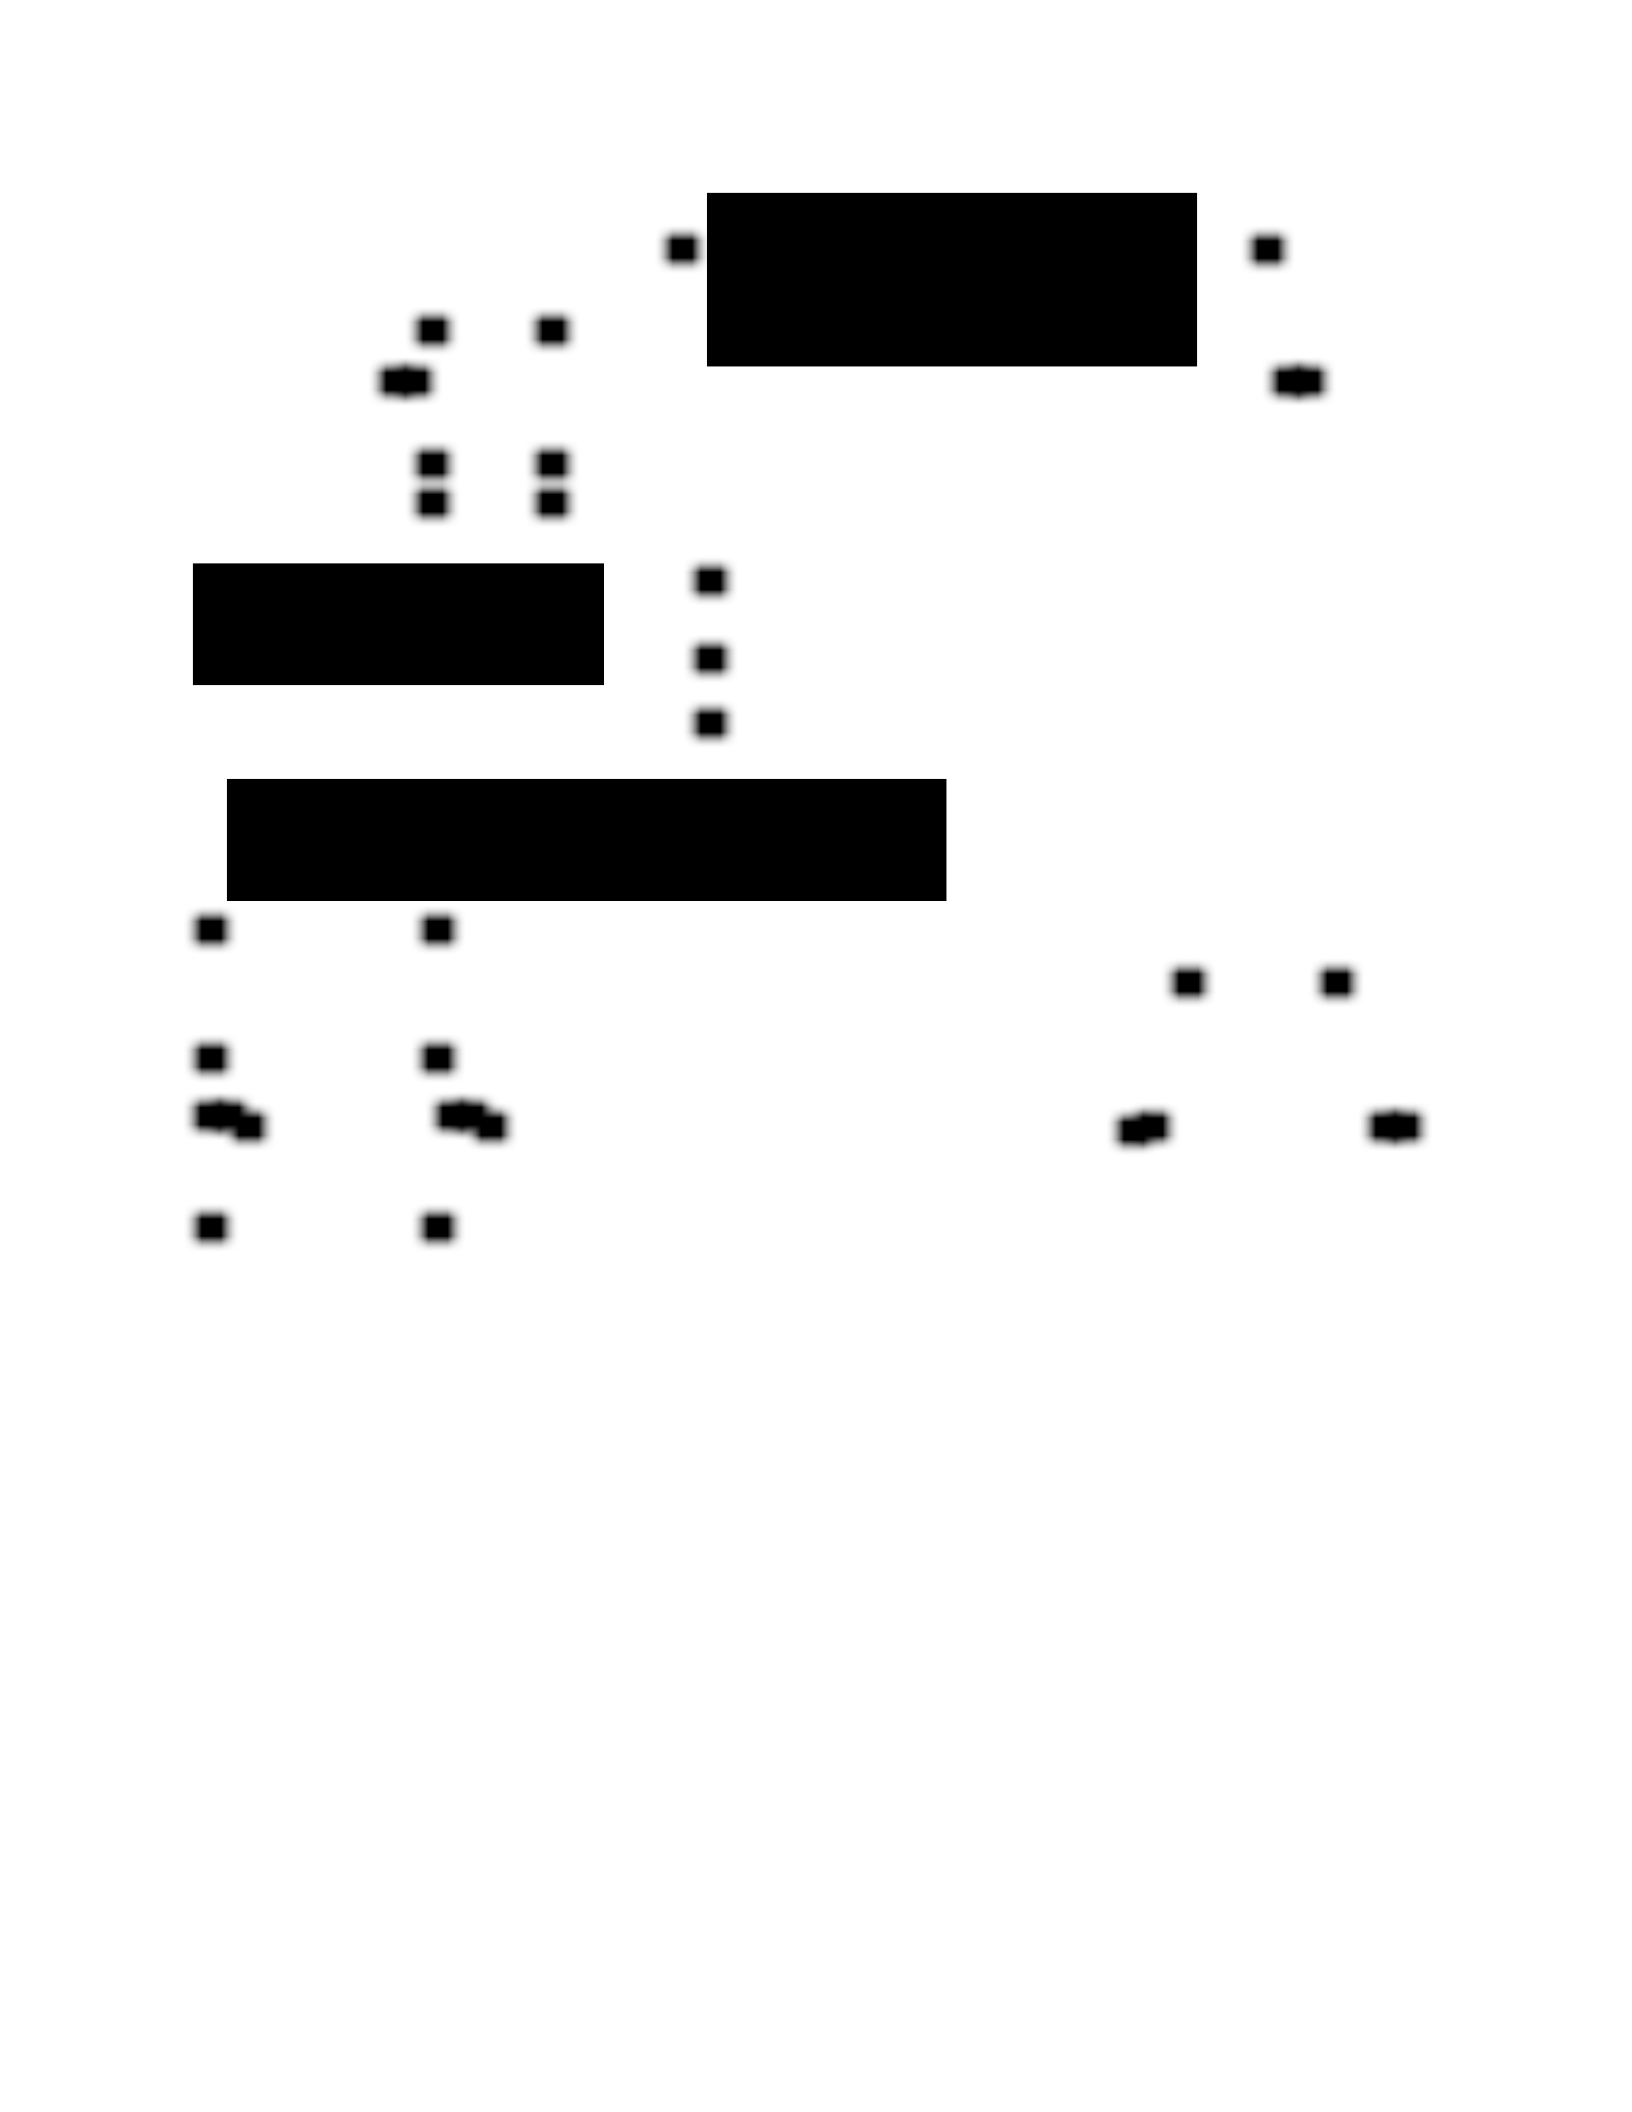
(0.1, 0.4, 0.5) and FT = (0, 0.8, 0.2). To compute MAHA, we
take the following steps. Consider
0.1 0
F = [FA0 , FT0 ] = 0.4 0.8 , so that F˜.
Moreover, C =
0.5 0.2
0.4
0.8
0.5
,
and
0.2
C˜ . Thus, the matrix CCORR = C˜0C˜ =
1 0.45 0.93
= F˜
0.45 1 0.75 . Finally, the matrix TECHSPILL 0 × CCORR × F˜ = 2.021.56 1.561.35 , so
that
0.93 0.75 1
Mahalanobis distance between two merger partners A and T (MAHAAT) corresponds to diagonal elements in
the TECHSPILL matrix, 1.56.
The Compustat provides information of each firm’s business segments classified by 4 digit SIC. We
construct each firm’s vector of pre-merger sales distribution over 216 business segments based on this
product market segment data. That is, the firm i’s vector of sales across business segments is denoted by
Si = (Si,1, Si,2, ..., Si,216), where Si,b is the firm i’s ratio of sales in a business segment b to the total sales before
the merger. We measure product similarity by Mahalanobis distance (PMAHA), which is the correlation
among firms’ vectors of market share in various business segments weighted by the correlation across
those business segments. That is,

PMAHA = S˜0WpS˜, (1.15)
where S˜ is a matrix of all firms’ normalized vectors of sales shares in product markets and Wp is a weighting
matrix of correlation between product markets.
Turning to the post-merger outcomes, we use different dependent variables in each chapter. First,
there have been several attempts to explore the relationship between R&D or patents and stock market
value (Pakes, 1985; Hall, 2000; Hall, B. H., Jaffe, A., & Trajtenberg, 2005). According to those studies, other
measures such as profit or total factor productivity (TFP) do not precisely reflect values of R&D inputs (e.g.,
technologies) or R&D outputs (e.g., patents, citations, or products). On the other hand, Tobin’s Q is a better
indicator of expected net present value generated by those factors related to R&D. Following this, a
measure of growth in stock market valuation is employed in chapters 1 and 2. That is, the difference in 3-
year average Tobin’s Q between preand post-merger periods (DIFFQ) is used, where the pre-merger
average Tobin’s Q is the mean of acquiring firm’s and target firm’s Tobin’s Q during 3 years before the
merger.
Furthermore, we employ total patent counts (PAT) and a total number of citation-weighted patents
(CWP) during 3 years after the merger as measures of post-merger innovation outcomes. Many
researchers use patent counts as a proxy of innovation output (Hausman et al., 1984; Ahuja and Katila,
2001; Fleming, 2001; Benner and Waldfogel, 2008; Ornaghi, 2009). However, each patent has different
technological influence or economic value. In this case, the number of citationweighted patents can be an
alternative measure to simple patent counts in the sense that the number of citations to a patent
represents the patent’s value (Trajtenberg, 1990; Hall, B. H., Jaffe, A., & Trajtenberg, 2005). For instance, a
patent cited by other 100 patents is more valuable than another patent without any citation because the
former is technologically more influential to other patents than the latter. In order to construct citation-
weighted patent counts, we apply the linear weighting scheme to the analysis following Trajtenberg
(1990). That is, let a firm i’s number of citations received for each patent k be CITik, then the firm i’s citation-
weighted patent counts
(CWPi) become
n

CWPi = ∑(1 + CITik), (1.16)
k=1
where n is the number of patents granted to the firm i. For our analysis, we use the number of patents to
measure the quantity of innovation outputs and the citation-weighted patent counts to measure the
quality of innovation outputs. Additionally, we compute the ratio of the number of patent citations to
patent counts (CITINT) to measure the average quality of every patent.
In addition to the number of patents, citation-weighted patents and the ratio of citation counts to the
number of patents, we consider the following post-merger innovation outcomes: (1) the median of
originality of patents (ORIG), (2) the median of generality of patents (GENERAL), and (3) the standard
deviation of CWP during 3 years after merger (STDV). Specifically, we employ originality and generality
index provided in National Bureau of Economic Research (NBER) Patent Data Project website. Following
Hall et al. (2001), the measure of originality (generality) is constructed by Measurei = 1 − ∑Cc s2ic, where sic
indicates the ratio of citations made (received) by patent i in patent class c to C patent classes. While ORIG
and GENERAL measure technological diversity after merger (Hall et al., 2001), STDV measures the risk of
post-merger patenting activity (Amore et al., 2013).
Finally, we also consider the following 4 measures of profitability as post-merger outcomes: (1) gross
margin (GM) is sales revenue minius cost of goods sold divided by sales revenue, (2) costsales ratio (CSR)
is the ratio of cost of goods sold to sales revenue, (3) returns on assets (ROA) is net income divided by total
assets and (4) returns on sales (ROS) is the ratio of net income to sales revenue. These dependent variables
are used to identify the channel of merger value creation due to product market similarity between two
merging firms.
In Chapter 3, we use a different measure of post-merger innovation compared to previous chapters. It
is called the ratio of the novel combination of existing technologies. Even though this measure is
introduced in Strumsky et al. (2011), we follow the definition of it in Akcigit et al. (2013). When
constructing this measure, we do not use the sample of firms that have no patent during our sample
periods. Based on this, 138 nonmerging firms are excluded from the sample among total 369 standalone
firms. The way to construct this measure is as follows. First, list all acquiring and target firms’ subclasses

of patents that are granted to them during 20 years before the merger transaction. Then, we can identify
every patent subclass whether it is previously assigned to other patents before the merger. Next, combine
the list of patent subclasses of two merger partners and compare it with the list of post-merger firm’s
subclasses. Following cases are considered as a novel combinatorial patent : (1) there is a patent after the
merger deal which has more than one combination of patent subclasses not previously assigned, (2) two
merging firms have a unique patent subclass and there is a patent after the merger that has both
subclasses for the first time. In this case, the ratio of novel combination is calculated by dividing the
number of patents with the novel combination of existing patent classes by the total number of patents
granted during 3 years after the merger transaction.
1.3.3 Descriptive Statistics
Table 1.4 reports the descriptive statistics. All financial variables are adjusted to dollar values in 2000
using consumer price index (CPI). Target firms show higher R&D intensity than acquirers, which is
consistent with the results in Blonigen and Taylor (2000). Moreover, acquirers have greater stock market
values than targets, so that they are more capable to finance a merger. Before taking a logarithm, the
average of acquirers’ stock market value before the merger is about $16 billion, whereas the average of
targets’ stock market value is approximately $2.3 billion. The average Tobin’s Q of acquirers is slightly
higher than that of targets. The composition of targets’ industry is similar to that of acquirers’ industry
because most of the deals are horizontal mergers. Pharmaceutical firms involve in more merger
transactions than firms in the other manufacturing sectors. In particular, more than 20% of mergers belong
to pharmaceutical industry.
Turning to the match-specific characteristics which play the key role in merger value function, the
averages of MAHA and PMAHA are 0.941 and 0.352, respectively. The averages of CR and PCR are 0.382
and 0.436, respectively. 40.2% of our mergers have the acquirer and target locating in the same state.
When it comes to post-merger outcome variables, summary statistics are in Table 1.5. Except for NCR,
every dependent variable is used in both chapters 1 and 2 to examine the channel of creating merger
values in terms of technology and product market similarities. For example, merged firms have on average
41 patents after the merger transaction. In Chapter 3, we employ the ratio of novel combination patents

to total number of patents as the dependent variable. According to the mean of NCR for merged firms,
they are more likely to have patents combined by existing technologies in a novel way.
1.4 Empirical Results
1.4.1 Benchmark Model Estimates
This subsection discusses the estimated results of merger value function reported in Table 1.6.
The coefficients for MAHA and PMAHA are positive and significant in Column (1). These results indicate that
the more similar the merger partners’ technologies and product markets, the higher their merger value. These
results suggest that technology and product market similarities between merging firms create merger value.
Our results support Hypotheses 1 and 2.
Turning to the control variables, we find that a firm with high Tobin’s Q derives more value from
another high Q firm, indicating a positive assortative matching in Tobin’s Q. This is supported by the fact
that we obtain more maximum score inequalities satisfied by setting the coefficient for an interaction term
between merging partners’ Tobin’s Q to +1 instead of -1. It implies that merging partners with a similar
level of Tobin’s Q can create larger synergies through the merger (Rhodes-Kropf and Robinson, 2008).
Furthermore, since the coefficient for the interaction term of Tobin’s Q is normalized to +1, we measure
the relative importance of each covariate in creating merger value. In Table 1.7, we multiply one standard
deviation of each covariate to its corresponding point estimate reported in Column (1) of Table 1.6 for
comparison. According to the results, MAHA has the largest impact in creating merger value, and then
followed by PMAHA. That is, when we increase MAHA by one standard deviation (0.51), the merger value
rises by 48.59. The increase in one standard deviation of PMAHA (0.26) raises the merger value by 20.71.
The impact of MAHA on merger value is more than twice of that of PMAHA. Furthermore, when there is
an increase in one standard deviation (0.266) of an interaction term between merging firms’ Tobin’s Q, the
merger value increases by 0.266, only about 0.5% of the rise in the merger value due to the changes in
MAHA.

Finally, we examine the goodness-of-fit of our matching model. To this end, we compare the acquirer-
target pairs in a stable matching equilibrium with those in observed matching. When the stable matching
assignments are similar to the realized merger pairs, the empirical matching model has a predictive power.
The procedure of generating predicted matches from our model is as follows. First, we use the estimated
coefficients reported in Column (1) of Table 1.6 to compute all the possible merger values. Then, deferred
acceptance algorithm based on these match values is applied to matching games in all the merger markets
to find pairwise stable matching assignments.
Table 1.8 shows the goodness-of-fit of our model by year. Finally, we compare the merger matches in the
stable matching equilibrium and those observed in the data. Our model predicts 101 mergers among
224 transactions, indicating 45% of prediction rate. For the realized mergers, their merger values are in
the 74 percentile among all counterfactual mergers, on average. This implies that the estimated merger
values are informative to explain observed mergers. Moreover, the averages of technology (MAHA) and
product market similarities (PMAHA) of merger matches in the stable matching equilibrium are 1.042
and 0.416, respectively.
1.4.2 Counterfactual Analysis
In this subsection, we perform counterfactual experiments exploring changes in merger value function
when technology and product market similarities are assumed to have no effect on merger value function.
In other words, our counterfactual experiments examine characteristics of the matches in a stable
equilibrium if firms do not consider technology and product market similarities as determinants of merger
value function.
Table 1.9 shows the results of these counterfactual experiments. First, we turn the coefficient of MAHA
to zero and compute the stable equilibrium matches. The average of technology similarity in equilibrium
matches decreases from 1.042 in the benchmark model to 0.809 in this counterfactual experiment, and
the average of product similarity in equilibrium matches increases slightly from 0.416 in the benchmark
model to 0.454 in this counterfactual experiment. The reduction of MAHA in equilibrium matches from
the benchmark and this counterfactual experiment is 0.23, which are equivalent to about 45% of one

standard deviation of that measure. Firms select merger partners with less similar technologies if
technology similarity does not appear in the merger value function. More importantly, when it comes to
a decrease in match values in this counterfactual experiment, it shows about 66.8% reduction in value sum
of equilibrium matches relative to value sum from baseline equilibrium matches. The prediction rate of
our model for observed merger decreases from 45.1% to 30.4%. These results suggest that the inclusion
of technology similarity is significantly important to explain merger partner choices.
Second, we turn the coefficient of PMAHA to zero and compute the stable equilibrium matches.
The reductions of MAHA and PMAHA in equilibrium matches from the benchmark and this counterfactual
experiment are 0.05 and 0.19, which are equivalent to 8.4% and 54% of one standard deviation of those
measures, respectively. Firms select merger partners with less similar product markets if they do not concern
about product market similarity in the merger value function. Moreover, the counterfactual model creates
24.5% lower merger value and predicts 7% points fewer realized matches among entire observed matches.
These results imply that product market similarity also plays a crucial role in merger partner choices, but its
impact is weaker than that of technology similarity.
1.4.3 Robustness Check
Alternative Market Definition
The first robustness check is on the specific merger market definition used in our benchmark model.
In this robustness check, we define the merger market as the combination of acquirer’s industry types and
merger transaction year. We report the results from this alternative market definition in Column (2) of
Table 1.6. Encouragingly, the coefficients of MAHA and PMAHA are positive and significant, which are
consistent with the results in Column (1) of Table 1.6.
Predetermination of Acquirer and Target Sets
The second robustness check is on the choice of being acquirer or target. In this robustness check, we
fix the role of each firm as acquirer or target in all counterfactual mergers according to the observed
mergers. We report the results from this alternative model in Column (3) of Table 1.6. Encouragingly, the
coefficients of MAHA and PMAHA are positive and significant, which are consistent with the results in
Column (1) of Table 1.6. Since we incorporate more ex-post information into our empirical model, the
percentage of stable equilibrium inequalities satisfied increases to 90.31% in this robustness check from
71.68% in the benchmark model.
Alternative Measures of Technology and Product Market Similarities
The third robustness check is to employ an alternative measure of technology and product market
similarities. In this robustness check, we use the correlation to construct measures of technology and product
market similarities following Jaffe (1986). These measures represent technology similarity only within the
same patent class and product market similarity only within the same product market. As a result, in the case
that two firms have no patent filed in overlapping classes (no products sold in overlapping markets), the
technology (product market) similarity between the two would be assigned as zero.
We measure technology similarity by the correlation between firms’ vectors of patent share over patent
classes as follows:
CR(FA, FT) = pVarCov(FA(F)A·,VarFT)(FT), (1.17)
where FA (FT) represents acquirer A’s (target T’s) vector of patent shares over patent classes. Some previous
studies construct a measure of technology similarity by using this patent distribution vector of firms. Ozcan
(2015) measures technology similarity for his sample of industrial firms with the Euclidean distance
between merging firms’ vectors of patent share over patent classes, whereas Linde and Siebert (2016)
measure technology similarity for their firms in the U.S. semiconductor industry by using the correlation
between merging firms’ vectors of patent share over patent classes. We employ the correlation (CR)
between pre-merger patent distribution vectors of two firms to measure technology similarity between
firms like Linde and Siebert (2016). Two firms have more similar technologies before their merger when
CR is higher. Analogously, we measure product market similarity by the correlation between firms’ vectors
of sales share over business segments, i.e. PCR. The PCR is the correlation between the pre-merger sales

distribution vectors of two firms, which measures product market similarity between them. Two firms are
more likely to compete in similar product markets before their merger when PCR is higher. Therefore,
MAHA and PMAHA are our preferred measures of technology and product market similarities.
We report the results from this alternative model in Column (4) of Table 1.6. The model specification
of Column (1) corresponds to Column (4). Encouragingly, the coefficients of CR and PCR are positive and
significant in Column (4), which is consistent with the results in columns (1)-(3) of Table 1.6. Comparing
the model predictions between columns (1) and (4), Table 1.8 reports that the model based on Column (4)
predicts 43% of observed mergers, which is lower than predicted by the model based on Column (1). It is
likely because these similarity measures incorporate less information than our preferred measures based
on the Mahalanobis distance. Overall, these results suggest that technology similarity across patent classes
and product market closeness across complementary products are as important as technology similarity
within patent classes and product market proximity within the common markets in creating merger values.
1.4.4 Post-Merger Outcomes
The choice of merger partner is made under the expectation of mutual gain. The probability of merger
between firms with similar technologies and product markets is higher because they expect higher merger
values from combining those resources. An important aspect of merger value creation is post-merger
innovation. That is, the merger value is expected to be positively related to innovation outcomes after
merger in case that the anticipated merger values realized. Such relationship also provides a support for
the specification of our model.
In this section, we regress the post-merger outcomes on the estimated merger values from maximum
score estimation. These regressions also control for year and industry fixed effects as well as acquirer- and
target-specific attributes. Thus, the post-merger outcome equation is
Yi = β1Vi + Xai β2 + Xti β3 + νyear + ξindustry + ei, (1.18)

where Yi represents a merged firm i’s post-merger outcome variables. Vi is the firm i’s estimated merger
value. Xai and Xti are acquirer- and target-specific characteristics, respectively. νyear represents year fixed
effects, ξindustry represents industry fixed effects, and ei is an unobserved error term.
Growth in Stock Market Valuation
Table 1.10 reports the relationship between a measure of post-merger market valuation and estimated
merger value, where the merger value is computed by multiplying the estimated parameters in Column
(1) of Table 1.6 to corresponding covariates. We use a measure of growth in Tobin’s Q between pre- and
post-merger periods. The coefficient is positive and significant, suggesting that the estimated merger
values has positive influences on the growth of firm’s valuation through the merger. This is the evidence
for realization of expected merger values. Thus, we can conclude that the estimated merger value captures
the creation of post-merger market values well.
Innnovation and Profitability
Next, we turn to the relationship between estimated merger value and post-merger innovation
outcomes. The coefficients on the merger value are positive and significant according to columns (1)-(6)
of Table 1.11 in the baseline model. When it comes to post-merger innovation quantity, the larger the
merger value, the more patents after the merger following Column (1). Moreover, the innovation impact
is greater for the number of citations than that of patents according to the larger estimate of CWP than
PAT. Finally, the coefficient in Column (3) is positive and marginally significant, suggesting that the merger
value is more related to innovation quality than innovation quantity.
The estimates of match value are also positive and significant in columns (4) and (5) of Table 1.11 in
the baseline specification. It suggests that the merger value is positively correlated with originality and
generality of patents. This is consistent with firms’ incentives to select merger partners with similar
technologies. That is, technology similarity not only increases the merged firm’s number of patents
granted and citations received but also diversify its technologies. This finding is supported by the
absorptive capacity hypothesis in terms of the following two ways. First, when two merger partners are

technologically similar, the acquirer can better understand the target’s technological resources, leading to
developing novel technologies compared to old ones. Second, technology similarity between two merging
firms expands the acquirer’s post-merger knowledge base, so that it affects various types of technologies
both within and across industries.
A positive and significant estimate in Column (6) of Table 1.11 in the baseline model indicates that
mergers with greater value creation relate to a higher risk of patenting activities, implying that the number
of citations after merger becomes more volatile. A possible explanation is that a merged firm may pursue
riskier R&D projects by combining complementary technologies, which is not a simple task. Overall, Table
1.11 suggests that a merger with larger value creation benefits from positive effects on post-merger
innovation outcomes, such as innovation quantity, quality, technological diversity, and patenting volatility.
In order to investigate the channel of merger value creation, we do counterfactual regressions by
setting the coefficients of technology and product market similarities to 0 in merger value function. Once
those positive and significant innovation impacts are gone, we can conclude that technology similarity
creates merger values via the channel of innovation outcomes. Those counterfactual results are shown in
the second and third panel (i.e. Model: When αMAHA=0 and Model: When αPMAHA=0, respectively) of Table
1.11. When eliminating the influences of technology similarity on merger value creation, we do not find
positive impacts on innovation outcomes during the post-merger periods. However, positive innovation
effects become more significant without considering the role of product market similarity in merger value
creation than those in the baseline model. Thus, we can conclude that technology similarity creates
merger values through the channel of improving innovation outcoess.
However, we do not find any significant relationship between merger values and post-merger
profitability outcomes (e.g. gross margin, cost-sales ratio, returns on assets and returns on sales) following
columns (7)-(10) in Table 1.11. These results imply that product market similarity between merging
partners increases merger values through another channel instead of the channel in product market
performances. We expect that merging firms in our sample focus on synergies in post-merger innovation
when choosing merger partners. This conjecture is supported by the fact that all the sample firms are
manufacturing firms that are more technology-intensive than firms in other industries.

Since Tobin’s Q reflects expected net present value of the firm after a merger, our positive postmerger
innovation impacts (more patents and citations, greater technological diversity, and higher innovation risk)
can be the source of the positive relationship between the estimated merger value and Tobin’s Q. However,
the profitability figures such as gross margin, cost-sales ratio, returns on assets and returns on sales are
short-term measures of post-merger market performances. Therefore, those measures may not be able to
capture the true expected value from the merger.
1.5 Conclusion
This paper examines the effects of technology and product market similarities on merger value
creation. We find that firms prefer to match with the other firm that has similar technologies and product
markets. All these results suggest that merging firms perceive similar technologies and product markets
as sources of creating merger values. Technology and product market similarities contribute a substantial
portion of value creation from merger and improve the predictive power of our model. Post-merger
innovation quantity, innovation quality, and firm valuation are higher for mergers with a larger estimated
merger value, suggesting mutual benefits for both the merging firms from assortative matching in similar
technologies and product markets.
However, there are many merger transactions made by private or low-tech firms instead of publicly-
traded firms. Since the analysis in this chapter focuses on U.S. manufacturing public firms, our results do
not have much implication for those mergers between low-tech or smaller private firms. It is because most
of low-tech mergers and mergers between non-Compustat (smaller) firms are more likely to be made for
financial or organizational reasons instead of post-merger innovation. In the future, we will analyze these
different types of mergers using other measures of post-merger outcomes.
The managerial implication of our analysis highlights the importance of merging with the right partner
in addition to merging with a good partner. While our analysis does not imply that mergers are, in general,
patent and value creating, it does suggest that firms within a merger market tend to sort into merger pairs
in order to maximize post-merger performance. Mergers between firms with similar technologies and
product markets are expected to raise merger values because there is a considerable boost in post-merger
performance. Since divestiture and consolidation after the merger are costly processes, managers would

be wise to consider technology and product market similarities as two additional factors for deciding a
potential merger.
1.6 Tables
Table 1.1: U.S. Manufacturing Industries in the Sample
Industry
SIC code
Description
Pharmaceutical
2834
PHARMACEUTICAL PREPARATIONS
2835
IN VITRO & IN VIVO DIAGNOSTIC SUBSTANCES
2836
BIOLOGICAL PRODUCTS, (NO DISGNOSTIC SUBSTANCES)
Semiconductor
3674
SEMICONDUCTORS & RELATED DEVICES
Electronics
3600
ELECTRONIC & OTHER ELECTRICAL EQUIPMENT (NO COMPUTER EQUIP)
3620
ELECTRICAL INDUSTRIAL APPARATUS
3634
ELECTRIC HOUSEWARES & FANS
3640
ELECTRIC LIGHTING & WIRING EQUIPMENT
3670
ELECTRONIC COMPONENTS & ACCESSORIES
3677
ELECTRONIC COILS, TRANSFORMERS & OTHER INDUCTORS
3678
ELECTRONIC CONNECTORS
3679
ELECTRONIC COMPONENTS, NEC
3690
MISCELLANEOUS ELECTRICAL MACHINERY, EQUIPMENT & SUPPLIES
3825
INSTRUMENTS FOR MEAS & TESTING OF ELECTRICITY & ELEC SIGNALS
3845
ELECTROMEDICAL & ELECTROTHERAPEUTIC APPARATUS
Computer &
Communications
3570
COMPUTER & OFFICE EQUIPMENT
3571
ELECTRONIC COMPUTERS
3572
COMPUTER STORAGE DEVICES
3575
COMPUTER TERMINALS
3576
COMPUTER COMMUNICATIONS EQUIPMENT
3577
COMPUTER PERIPHERAL EQUIPMENT, NEC
3578
CALCULATING & ACCOUNTING MACHINES (NO ELECTRONIC COMPUTERS)
3661
TELEPHONE & TELEGRAPH APPARATUS
3663
RADIO & TV BROADCASTING & COMMUNICATIONS EQUIPMENT
3669
COMMUNICATIONS EQUIPMENT, NEC
Other
2090
MISCELLANEOUS FOOD PREPARATIONS & KINDRED PRODUCTS
2631
PAPERBOARD MILLS
2650
PAPERBOARD CONTAINERS & BOXES
2670
CONVERTED PAPER & PAPERBOARD PRODS (NO CONTANERS/BOXES)
2821
PLASTIC MATERIALS, SYNTH RESINS & NONVULCAN ELASTOMERS
2851
PAINTS, VARNISHES, LACQUERS, ENAMELS & ALLIED PRODS
2860
INDUSTRIAL ORGANIC CHEMICALS
2890
MISCELLANEOUS CHEMICAL PRODUCTS
2911
PETROLEUM REFINING
3050
GASKETS, PACKG & SEALG DEVICES & RUBBER & PLASTICS HOSE
Table 1.2: U.S. Manufacturing Industries in the Sample (Cont.)

Industry
SIC code
Description
Other
3060
FABRICATED RUBBER PRODUCTS, NEC
3080
MISCELLANEOUS PLASTICS PRODUCTS
3081
UNSUPPORTED PLASTICS FILM & SHEET
3089
PLASTICS PRODUCTS, NEC
3231
GLASS PRODUCTS, MADE OF PURCHASED GLASS
3260
POTTERY & RELATED PRODUCTS
3312
STEEL WORKS, BLAST FURNACES & ROLLING MILLS (COKE OVENS)
3420
CUTLERY, HANDTOOLS & GENERAL HARDWARE
3443
FABRICATED PLATE WORK (BOILER SHOPS)
3460
METAL FORGINGS & STAMPINGS
3480
ORDNANCE & ACCESSORIES, (NO VEHICLES/GUIDED MISSILES)
3490
MISCELLANEOUS FABRICATED METAL PRODUCTS
3510
ENGINES & TURBINES
3531
CONSTRUCTION MACHINERY & EQUIP
3533
OIL & GAS FIELD MACHINERY & EQUIPMENT
3537
INDUSTRIAL TRUCKS, TRACTORS, TRAILORS & STACKERS
3559
SPECIAL INDUSTRY MACHINERY, NEC
3560
GENERAL INDUSTRIAL MACHINERY & EQUIPMENT
3561
PUMPS & PUMPING EQUIPMENT
3564
INDUSTRIAL & COMMERCIAL FANS & BLOWERS & AIR PURIFING EQUIP
3569
GENERAL INDUSTRIAL MACHINERY & EQUIPMENT, NEC
3579
OFFICE MACHINES, NEC
3580
REFRIGERATION & SERVICE INDUSTRY MACHINERY
3585
AIR-COND & WARM AIR HEATG EQUIP & COMM & INDL REFRIG EQUIP
3590
MISC INDUSTRIAL & COMMERCIAL MACHINERY & EQUIPMENT
3630
HOUSEHOLD APPLIANCES
3651
HOUSEHOLD AUDIO & VIDEO EQUIPMENT
3714
MOTOR VEHICLE PARTS & ACCESSORIES
3728
AIRCRAFT PARTS & AUXILIARY EQUIPMENT, NEC
3821
LABORATORY APPARATUS & FURNITURE
3823
INDUSTRIAL INSTRUMENTS FOR MEASUREMENT, DISPLAY, AND CONTROL
3826
LABORATORY ANALYTICAL INSTRUMENTS
3827
OPTICAL INSTRUMENTS & LENSES
3829
MEASURING & CONTROLLING DEVICES, NEC
3841
SURGICAL & MEDICAL INSTRUMENTS & APPARATUS
3842
ORTHOPEDIC, PROSTHETIC & SURGICAL APPLIANCES & SUPPLIES
3851
OPHTHALMIC GOODS
3861
PHOTOGRAPHIC EQUIPMENT & SUPPLIES
3944
GAMES, TOYS & CHILDREN’S VEHICLES (NO DOLLS & BICYCLES)
3949
SPORTING & ATHLETIC GOODS, NEC
Table 1.3: Merger Transactions in U.S. Manufacturing Industries
Year
Pharmaceutical
Semiconductor
Electronics
Computer &
Communications
Other
Total
1996
2
3
0
0
0
5
1997
3
0
5
2
10
20
1998
5
0
2
3
9
19
1999
9
2
2
6
18
37
2000
7
0
3
7
12
29
2001
4
6
3
6
11
30
2002
5
0
5
5
7
22
2003
6
2
0
3
4
15
2004
2
4
3
4
3
16
2005
3
0
2
3
8
16
2006
3
2
4
2
4
15
Total
49
19
29
41
86
224
33
Table 1.4: Descriptive Statistics for Merging Firms
Variable
Description
Mean
Std. Dev. N
Acquirer
R&D intensity R&D expenditure 0.166 0.266 224
Tobin’s Q log 1.104 0.126 224
IND1
Pharmaceutical Industry
0.232
0.423
224
IND2
Semiconductor Industry
0.103
0.304
224
IND3
Electronics Industry
0.107
0.31
224
IND4
Computer & Communications Industry
0.161
0.368
224
IND1
Pharmaceutical Industry
0.219
0.414
224
IND2
Semiconductor Industry
0.085
0.279
224
IND3
Electronics Industry
0.129
0.336
224
IND4
Computer & Communications Industry
0.183
0.388
224
IND5
Other Industry
0.384
0.487
224
Match-Specific
Characteristic
MAHA
Mahalanobis distance (technologies)
0.941
0.598
224
PMAHA
Mahalanobis distance (product market)
0.352
0.356
224
CR
Correlation (technologies)
0.382
0.313
224
PCR
Correlation (product market)
0.436
0.467
224
SameState
Dummy variable for same state
0.402
0.491
224
34
Table 1.5: Descriptive Statistics for Post-Merger Outcomes
Variable
Description
Mean
Std. Dev.
N
DIFFQ
Difference in 3-year average Tobin’s Q between
pre- and post-merger periods
-0.132
0.383
224
PAT
log(Patent counts)
3.727
1.941
224
CWP
log(Citation-weighted patent counts)
4.778
2.445
224
CITINT
log
0.939
0.811
224
ORIG
Median of Originality of patents
0.588
0.342
224
GENERAL
Median of Generality of patents
0.460
0.390
224
STDV
3-year standard deviation of CWP after merger
2.257
0.66
224
GM
Sales−Cost of Goods Sold
Sales
0.227
3.011
224
CSR
Cost of Goods Sold
Sales
0.755
3.013
224
ROA
Net Income
Total Assets
-0.03
0.206
224
ROS
Net Income
Sales
-0.384
3.138
224
NCR
The ratio of novel combination patents to total patent counts
0.429
0.3
224
Table 1.6: Merger Value Estimation
(1)
(2)
(3)
(4)
MAHA
95.273
94.703∗∗
[35.333, 95.302]
[35.323, 95.857]
[23.973, 86.925]
PMAHA
79.635
74.076∗∗
[25.541, 93.370]
[31.247, 91.619]
[25.889, 91.178]
CR
69.291∗∗
[27.282,
88.426]
PCR
22.259∗∗
[14.775,
74.487]
SameState
16.676
7.583
10.984
3.288
[-25.619, 39.262]
[-25.283, 59.299]
[-18.976, 60.679]
[-27.897,
15.920]
Tobin’s Qa × Tobin’s Qt
1∗∗
1∗∗
1∗∗
1∗∗
Normalized
Normalized
Normalized
Normalized
R&D intensitya × R&D
intensityt
2.167
42.731
42.534
7.342
[-31.243, 66.119]
[-15.638, 79.497]
[-15.030, 79.719]
[-30.527,
68.776]
Number of
Inequalities
2.684
3,064
671
2.684
% of Inequalities
Satisfied
71.68%
72.69%
90.31%
71.76%
Number of Merger
Markets
46
41
46
46

Note: We use maximum score estimation in all columns and run the estimation first setting the coefficient for an interaction term between merging firms’ Tobin’s Q to
+1. We then select the vectors of parameter estimates that maximize the maximum score objective function. 95% confidence interval is shown in brackets. The
coefficients are significant at the 5% level when the confidence interval does not contain 0. Merger market is defined by the combination of target firms’ industry type
and merger transaction year in columns (1), (3) and (4). For column (2), merger market is constructed by using acquiring firms’ industry type and merger year. ** p <
0.05
Table 1.7: Relative Importance of Covariates in Match Value
Model
Column (1) in Table 1.6
Estimate
Estimate ×
Standard Deviation
Standard Deviation
MAHA
95.27
0.51 48.59
PMAHA
79.64
0.26 20.71
Tobin’s Qa × Tobin’s Qt
1
0.266 0.266
Note: Estimate indicates a point estimate of each covariate in Table 1.6. Observed and
counterfactual mergers are included to compute standard deviation, thus those figures are
different from those reported in descriptive statistics.
Table 1.8: Year-by-Year Goodness-of-Fit
Model
Column (1) in Table 1.6
Column (4) in Table 1.6
Year
Number of
Mergers
Predicted
Match
Prediction
Rate
Average
Rank
Predicted
Match
Prediction
Rate
Average
Rank
1996
5
1
20%
75%
1
20%
72%
1997
20
8
40%
74%
5
25%
58%
1998
19
12
63%
66%
10
53%
70%
1999
37
8
22%
74%
7
19%
69%
2000
29
16
55%
75%
18
62%
62%
2001
30
12
40%
67%
9
30%
65%
2002
22
7
32%
75%
8
36%
71%
2003
15
11
73%
81%
11
73%
76%
2004
16
9
56%
76%
6
38%
70%
2005
16
10
63%
77%
13
81%
71%
2006
15
7
47%
75%
8
53%
68%
Total
224
101
45%
74%
96
43%
68%
Note: Predicted Match represents the number of observed matches consistent with equilibrium matches
driven by the match values computed using estimates in columns (1) and (4) of Table 1.6. Average Rank indicates
the percentile of merger values from realized merger matches relative to values of all the counterfactual
matches.
37
Table 1.9: Counterfactual Analysis
(1)
(2)
(3)
(4)
(5)
(6)
CR
MAHA
PCR
PMAHA
% drop in match value
Prediction rate
Model: Column (1) in Table 1.6
1.042
0.416
0%
45.1%
αMAHA = 0
0.809
0.454
66.8%
30.4%
αPMAHA = 0
0.995
0.229
24.5%
38.1%
αMAHA = 0 & αPMAHA = 0
0.690
0.188
75.2%
21.6%
Model: Column (4) in Table 1.6
0.471
0.5
0%
42.9%
αCR = 0
0.259
0.487
46.1%
39.1%
αPCR = 0
0.387
0.292
14.8%
40.2%
αCR = 0 & αPCR = 0
0.244
0.243
51.7%
34.9%
Note: αCR, αMAHA, αPCR and αPMAHA indicate an estimated coefficient for CR, MAHA, PCR and PMAHA respectively. We do each counterfactual experiment by setting
corresponding parameter estimate in the baseline model to 0 and finding stable equilibrium matches based on deferred acceptance algorithm. CR, MAHA, PCR and
PMAHA are the averages of those measures of all the equilibrium matches in each counterfactual experiment. % drop in match value represents % decrease in sum of
match values from equilibrium matches in each counterfactual experiment compared to value sum of equilibrium matches in our baseline model.
Table 1.10: Growth in Tobin’s Q
Model
Column (1) in Table 1.6
Dependent Variable
DIIFFQ
Merger Value
0.0425†
(0.0219)
Acquirer
R&D intensity
0.0407
(0.121)
Target
R&D intensity
0.036
(0.0541)
Year Effects
YES
Industry Effects
YES
Number of Observations
224
Note: We use OLS estimation in all columns. Robust standard errors are in
parentheses. The dependent variable is the difference in averaged Tobin’s Q
during 3 years before and after merger (DIFFQ). Merger Values are computed
using the estimated parameters in Column (1) of Table 1.6. † p < 0.10, * p < 0.05,
** p < 0.01, *** p < 0.001
Table 1.11: Post-Merger Outcome Estimation
(1)
(2)
(3)
(4)
(5)
(6)
(7)
(8)
(9)
(10)
PAT
CWP
CITINT
ORIG
GENERAL
STDV
GM
CSR
ROA
ROS
Model: Baseline
Merger Value
0.503∗∗∗
0.573∗∗∗
0.0552†
0.0418∗
0.0364∗
0.0568∗
-0.0388
0.0439
0.0072
-0.0134
(0.107)
(0.12)
(0.0299)
(0.0163)
(0.0179)
(0.0274)
(0.199)
(0.199)
(0.0121)
(0.202)
Model: When αMAHA=0
Merger Value
0.0379
0.0208
-0.0331
0.0033
-0.0175
0.271
-0.083
0.085
0.0046
-0.0412
(0.0908)
(0.103)
(0.0244)
(0.0133)
(0.0141)
(0.296)
(0.143)
(0.143)
(0.009)
(0.146)
Model: When αPMAHA=0
Merger Value
0.589∗∗∗
0.704∗∗∗
0.105∗∗∗
0.0615∗∗∗
0.0517∗∗
2.998∗∗∗
0.0167
-0.0148
0.0033
0.0023
(0.104)
(0.117)
(0.0294)
(0.0158)
(0.0171)
(0.301)
(0.177)
(0.177)
(0.0108)
(0.18)
Acquirer & Target Controls
YES
YES
YES
YES
YES
YES
YES
YES
YES
YES
Year & Industry Effects
YES
YES
YES
YES
YES
YES
YES
YES
YES
YES
Number of Observations
224
224
224
224
224
224
224
224
224
224
Note: We use OLS estimation in all the columns. Robust standard errors are in parentheses. The dependent variables are as follows. The logged number of patents (PAT)
in Column (1). The logged number of citation-weighted patents (CWP) in Column (2). The ratio of citation counts to patent counts (CITINT) in Column (3). The median
of originality of patents (ORIG) in Column (4). The median of generality of patents (GENERAL) in Column (5). The standard deviation of CWP during 3 years after merger
(STDV) in Column (6). Gross margin (GM) in Column (7). Cost of goods sold divided by sales revenue (CSR) in Column (8). Returns on Asset (ROA) in Column (9). Returns
on Sales (ROS) in Column (10). Merger Value is computed using the estimated parameters in Column (1) of Table 1.6. † p < 0.10, * p < 0.05, ** p < 0.01, *** p < 0.001

45
Chapter 2
Technology and Product Market
Similarities and Value Creation in
Mergers: Extended Model with
Standalone Firms
2.1 Introduction
Most of previous literature on the determinants of merger transaction have employed standard
discrete choice models such as logit or probit (Ornaghi, 2009; Bena and Li, 2014; Chondrakis, 2016). Using
a logit estimation for the propensity of merger, Ornaghi (2009) suggests that pharmaceutical firms
expecting worse performances are more likely to perform mergers. With the same empirical method of
conditional logit regression, Bena and Li (2014) and Chondrakis (2016) commonly present that
technological proximity between firms increases the probability of merger. These studies, however, have
fundamental limitations to analyze firms’ merger partner choice because they focus on the impacts of
individual firm-specific characteristics on merger decision rather than those of match-specific attributes.
In principle, a merger is performed by a two-sided matching between an acquirer and a target.
That is, two firms involved in a merger try to maximize their own values from the merger with their deal
partners. Thus, a standard discrete choice model such as logit or probit has drawbacks in analyzing the
determinants of merger partner selection because it assumes an independence among error terms in all
merger observations. However, every merger in the same merger market is interdependent with each

46
other in that some potential acquiring firms may consider the same target firm as their merger partner. In
other words, a merger transaction between an acquirer and a target influences other firms’ potential
merger behavior because those other firms should search their merger partner in the rest of firms except
for the two merged firms. Moreover, the discrete choice model assumes that a realized merger reveals
two merging partners’ willingness to match with each other. For example, suppose that there are four
potential merging firms a, b, c and d. And suppose that the firms c and d are strictly preferred merger
partners relative to the firms a and b. When a merger match between a and b is observed, the discrete
choice model implies that V(a, b) > V(a, c), where V(·, ·) represents values from mergers between two
firms. An estimated probability of the merger between a and b under probit or logit model is derived from
this inequality. However, this induced merger probability violates the assumption that V(a, c) > V(a, b),
because c is a preferred partner than b as we assumed. In this case, we can imagine another scenario
where the firms c and d decide to merge with each other. Then, the firm a cannot merge with c, so that it
selects another firm b as its alternative partner and we can observe the merger match between a and b.
The discrete choice model does not allow this possibility. Thus, we rely on a structural model of two-sided
matching to analyze firms’ merger partner choice.
Further, the structural matching model in this chapter differs from the one in previous literature. While
the latter only allows firms to choose whom to merge with, we allow them to jointly select whether to
merge and whom to merge with and include actual acquirers into the set of potential target firms and vice
versa. By using this model setup, we can relax restrictive assumptions of previous two-sided matching
models and tackle the following issues. First, we can address an endogeneity problem caused by a
correlation between unobservable factors affecting firms’ merger decision and similarity measures by
providing firms with unmatching outside option. Second, allowing firms to be both a potential acquirer
and a potential target before a merger is reasonable in that a role of firms in the merger as either the
acquirer or the target is not predetermined since they are founded. Taken together, we call our model a
general model of structural two-sided merger matching.
Using a maximum score estimation approach, we find that technology similarity between two merger
partners plays a positive role in creating merger values, being consistent with the main results in Chapter

47
1. This finding can be supported by the absorptive capacity hypothesis introduced in Cohen and Levinthal
(1990). According to the hypothesis, performance of learning can be maximized when a target of learning
is associated with existing technologies or knowledge. Since firms in our samples are more technology-
dependent than those in other industries such as finance or service sector, they tend to select merger
partners with similar technologies for the purpose of maximizing post-merger performances. Another
finding is that product market similarity also increases merger values, so that firms are more likely to
search merger partners operating similar product markets. This result is equivalent to the finding in Hoberg
and Phillips (2010). That is, acquiring firms can efficiently operate target firms’ assets when they have
similar product resources, leading to better post-merger performance.
This study contributes to the previous literature in the following aspects. First, we add the extended
model of two-sided matching that considers standalone firms to prior two-sided matching literature. In
light of the endogeneity problem caused by the model set-up in the two-sided matching model of the
previous chapter, we justify our selection of the extended model specification for the analysis of merger
partner selection. Second, our extended two-sided matching model provides the rationale for using it
instead of standard discrete choice models such as logit or probit in terms of merger mechanism and
model’s goodness-of-fit. Previous literature on twosided matching model argues that the matching model
is appropriate in merger analysis because discrete choice models do not capture the fundamental
mechanism of the merger partner selection. By comparing the model fit of our extended two-sided
matching model and probit model, we also support the utilization of our general two-sided matching
model. Finally, we contribute to a growing number of studies on the relationship between merger and
innovation. More diverse measures of post-merger innovation outcomes allow us to consistently
emphasize the impacts of the merger on innovation during the post-merger periods.
Section 2 discusses the model and estimation methodology. Section 3 presents empirical results. The
last section concludes.
48
2.2 Model and Estimation
2.2.1 Merger Value and Maximum Score Estimation
We use the same merger value function in Chapter 1
F(a, t|α) = α1TSat + α2PSat + α3SameStateat + α4(Tobin0s Qa × Tobin0s Qt)
+ α5(R&D intensitya × R&D intensityt) + ηat, (2.1)
where ηat represents an unobserved error term for the merger between acquirer a and target t. TSat and
PSat represent measures of the similarity in technology and product markets between a and t,
respectively.
Most of the existing literature employs a two-sided merger matching model that allows firms to choose
only whom to merge with (e.g. Ozcan, 2015; Akkus et al., 2015). Unlike those studies, we set up a general
model of two-sided merger matching. In this model, firms are assumed to make a joint decision of whether
to merge, whom to merge with, and being either an acquirer or a target. Specifically, we alleviate the
endogeneity problem caused by the correlation between unobservable factors driving merger partner
choice and similarity measures by including standalone firms in our sample. Moreover, by allowing firms
to choose to be either an acquirer or a target, we relax a restrictivce assumption that whether a firm is
either an acquirer or a target in a merger is predetermined.
The important property used in the identification of maximum score estimates is the rank order
condition (Manski, 1975, 1985). The basic principle of this condition is as follows. If the sum of values from
two observed mergers are greater than the sum of values from counterfactual mergers, then the realized
mergers are more likely to be observed than the counterfactual mergers. And the reverse is also true.
Under this rank order condition, the maximum score estimator α can maximize
( h
Q(α) =∑ 1 {V(a, t|α) + V(a˜, t˜|α) ≥ V(a, t˜|α) + V(a˜, t|α)} ∩

49
mµm
)
{V(a, t|α) + V(a˜, t˜|α) ≥ V(a, a˜|α) + V(t, t˜|α)}i , (2.2)
over the parameter space at a stable matching equilibrium, where Q(α) is the number of inequalities in
(2.2) satisfied in all merger markets. Fox (2010a) suggests the estimation method which does not require
the information on the merger transaction price. Following the previous literature and Chapter 1, we
normalize the coefficient of an interaction term of acquirer’s and target’s Tobin’s Q to +1. Then, we
interpret the impacts of other covariates on merger value creation relative to those of Tobin0s Qa × Tobin0s
Qt.
The following example shows how to construct maximum score inequalities for the general model of
two-sided matching. Suppose that there are seven firms in a merger market, two acquirers a and a˜, two
targets t and t˜ and three nonmerging firms s, s1 and s2. Their matching outcomes are (a, t), (a˜, t˜) ∈ µ
and s, s1, s2 ∈ SA, where µ and SA represent a set of merging and standalone firms, respectively. For two
realized merger pairs (a, t) and (a˜, t˜), we use the inequalities in (2.2) to determine whether they belong
to a stable matching equilibrium. However, to distinguish match value between observed merger pairs and
standalone firms, we assign 0 to values of technology and product market similarities for standalone firms.
Furthermore, an individual standalone firm’s characteristics (R&D intensity and Tobin’s Q) are used in the
match value function (2.1) instead of the interaction term of those covariates. Then, a stable matching
inequality for a pair of merging firms and a standalone firm can be written as
V(a, t) + V(s, 0) ≥ V(a, 0) + V(s, t), (2.3)
where (s, 0) and (a, 0) represent self-matches of standalone firms s and a, respectively. Even though the
standalone firm s acts as an acquirer in (2.3), it can also be acquired by another firm.
Thus, we construct an additional inequality
V(a, t) + V(0, s) ≥ V(a, s) + V(0, t). (2.4)
50
When it comes to two standalone firms s1 and s2, they prefer to be stay-alone rather than merging with
each other. This implies the following inequality
V(s1, 0) + V(s2, 0) ≥ V(s1, s2).
Taken together, our maximum score objective function becomes
(2.5)
Q(α) = ∑ 1 {q1(α) ≥ 0} ∩
{q2(α) ≥ 0}
m=1 s,s1,s2∈SAm (a,t),(a˜,t˜)∈µm
, (2.6)
where q1(α) = V(a, t|α) + V(a˜, t˜|α) − V(a, t˜|α) − V(a˜,
t|α), q2(α) = V(a, t|α) + V(a˜, t˜|α) − V(a, a˜|α) − V(t,
t˜|α), q3(α) = V(a, t|α) + V(s, 0|α) − V(a, 0|α) − V(s, t|α),
q4(α) = V(a, t|α) + V(0, s|α) − V(a, s|α) − V(0, t|α), q5(α) =
V(a˜, t˜|α) + V(s, 0|α) − V(a˜, 0|α) − V(s, t˜|α), q6(α) =
V(a˜, t˜|α) + V(0, s|α) − V(a˜, s|α) − V(0, t˜|α), q7(α) =
V(s1, 0|α) + V(s2, 0|α) − V(s1, s2|α).
2.2.2 Sample Construction of Standalone Firms
Since we include standalone firms in our sample, we need to discuss how to pick up those samples
from our data sources. First, we obtain the samples of nonmerging firms from the Compustat which is the
same data source of merging firm samples. In particular, we randomly draw 5 standalone firms based on
year and industry of merging firm samples. Then, we keep the firm samples that have available financial

51
records as well as at least one patent during our sample periods. Finally, we end up using 369 standalone
firms in our maximum score estimation.
We also perform a test for the difference in outcome and explanatory variables of two firm groups,
merged and standalone firms. As a result, the merged firms significantly have more patents than the
standalone firms during the post-merger periods. Moreover, measures of technological diversity
(originality and generality) are higher for merged firms than standalone firms, even though the difference
is significant only for the generality. Finally, Tobin’s Q is significantly higher for the merged firms than the
standalone firms, implying that the former can easily finance the cost of the merger transaction.
2.3 Empirical Results
2.3.1 Benchmark Results
Table 2.2 shows maximum score estimation results based on the objective function (2.6), representing
a set-up of the general matching model. Columns (1) and (2) are different specifications in terms of
measures of technology and product market similarities used in the estimation. In both columns,
technology similarity plays a positive role in creating merger values. While firms are more likely to choose
merger partners with higher product market similarity measured by Mahalanobis distance according to
Column (1), product market similarity measured by correlation (PCR) does not have a significant estimate
in Column (2). When it comes to other control variables, there is a positive assortative matching between
merger partners in terms of both Tobin’s Q and R&D intensity. Since the coefficient for the interaction term
of Tobin’s Q is normalized to +1, other estimates represent the importance of corresponding covariates in
raising merger values relative to the impact of Tobin’s Q interaction term. Thus, technology similarity is the
most important factor in merger value creation among all the covariates.
2.3.2 Model Comparison
In this section, we compare the estimation results of the extended model with those in the benchmark
model in Chapter 1 as well as those from probit estimation. The general model of two-sided merger
matching relaxes assumptions of the two-sided matching model in the previous chapter. Even though two

52
models have a different number of maximum score inequalities and observations, it is worthwhile
comparing estimates of each covariate in merger value estimation. Columns (3) and (4) in Table 2.2 shows
maximum score estimation results based on the matching model in Chapter 1. According to those columns,
technology and product market similarities increase merger values in both specifications. Moreover, signs
of estimates for covariates remain unchanged except for that of SameState which is insignificant. Note that
there is a positive assortative matching in terms of R&D intensity in the general model, whereas the term
has insignificant impacts on merger value creation in the previous model of Chapter 1.
According to the results in Table 2.3, the relative impacts of technology and product market similarities
on merger value creation become smaller in the general model than the model in Chapter 1. A possible
explanation is that the estimated coefficients for similarity measures (MAHA and PMAHA) decrease
because we include standalone firms into the sample. That is, the inequality q7(α) ≥ 0 in the maximum
score objective function (2.6) means that the sum of values from two standalone firms with 0 Mahalanobis
similarity should be greater than their merger value containing weakly positive Mahalanobis similarity.
Thus, the role of technology and product market similarities in matching two merger partners may be less
influential in the general model. In Table 2.4, we compare the performance of two matching models. The
general model is appropriate to analyze firms’ merger partner choice than the model in Chapter 1 because
the former avoid biased results caused by the correlation between unobserved factors affecting merger
partner selection and similarity measures, even though the model prediction rate of the former (17.7%) is
lower than that of the latter (45.1%). Moreover, technology similarity plays the most important role in
raising merger values in both models. This is supported by the fact that merger values drop when shutting
down the impact of MAHA in the models following the second row in each panel. On the other hand, note
that when ignoring the impacts of both technology and product market similarities on the merger value
creation (see the 4th row in the 1st panel of Table 2.4), all the predicted matches except for 1 match are
self matches of standalone firms. This implies that for the decision of being standalone, technology and
product market similarities do not matter any more.
Probit model estimation results are shown in Table 2.5. Technology and product market similarities
have positive impacts on the probability of merger. Moreover, the interaction term of two merging firms’

53
Tobin’s Q increases the likelihood of merger incidence. However, the interaction term between two merger
partners’ R&D intensity is negatively correlated with merger probability, which differs from the results in
Table 2.2. Since we take into account the mechanism of equilibrium matching in our general model or the
model in the previous chapter, we attribute this result in probit estimation to the model misspecification.
One way to measure a goodness-of-fit of the model is using prediction rate. Table 2.6 presents the
prediction rate of both general and probit model by year. While the number of realized matches consistent
with stable equilibrium matches is 91 in the probit model, the general matching model predicts 105 actual
matches. These statistics provide the rationale for applying the two-sided matching model to the analysis
of merger instead of using a discrete choice model such as probit or logit. Another way of evaluating the
model fit is to compare estimated merger values from realized matches with those of counterfactual
matches (e.g. Akkus et al., 2015). In columns (5) and (8) of Table 2.6, we provide the average percentile of
observed match values relative to counterfactual match values over time for the general and the probit
model, respectively. The average rank of the actual matches in the general model ranges from 0 to 0.7.
This implies that actual matches create values relatively close to the highest match values. However, the
probit model shows the lower average rank of realized matches than the general model. Thus, the
goodness-offit of our general matching model appears to be better than the probit model.
2.3.3 Post-Merger Outcomes
Growth in Stock Market Valuation
In Chapter 1, we find that merger values created by technology and product market similarities
between merging firms are positively correlated with post-merger stock market valuation. As an extension
of those findings, we examine whether merger values have positive relationship with growth in stock
market valuation after merger when considering standalone firms in the sample. For this purpose, we use
the difference in averaged Tobin’s Q during 3 years before and after merger (DIFFQ) as the dependent
variable and employ Heckman two-step regression as the emprical methodology. When examining the
relationship between merger values and post-merger outcomes, it is important to control for selection
bias in the estimation equation. This is because merging firms are different from standalone firms in terms
54
of both characteristics and the outcome variable in that the former group of firms are not randomly
selected. The first stage equation of probit model is as follows:
Pr(Mergerij , (2.7)
where Mergerij is a dummy variable equal to 1 if a firm pair ij performs a merger and Xij are two firms’ pre-
merger characteristics. If i 6= j, then the firm pair ij represents a merging firm pair. Otherwise, it indicates
a standalone firm. Next, the second stage equation of ols regression is
Yij = Zijγ + δλ(Xβ) + ζ · YEAR + ξ · INDUSTRY + νij, (2.8)
where Zij are two firms’ pre-merger characteristics and λ(·) is an inverse Mills ratio. That is, λ(Xβ) =
. YEAR and INDUSTRY represent entire sets of year and industry dummy vari-
ables, respectively.
Table 2.7 provides the first stage probit estimation results in Heckman two-step procedure. Most
importantly, the estimated merger values from maximum score approach have positive impacts on the
probability of merger. Other results are consistent with the findings in previous merger studies. That is,
target firms’ R&D intensity has positive impacts on merger incidence (Bertrand, 2009), whereas acquirers’
R&D intensity is negatively correlated with the likelihood of merger (Blonigen and Taylor, 2000; Desyllas
and Hughes, 2010). Moreover, while acquiring firms with higher Tobin’s Q are more likely to perform a
merger with other firms (Jovanovic and Rousseau, 2002), target firms tend to have lower Tobin’s Q.
Table 2.8 shows the estimation results for growth in stock market valuation in the model in Chapter 1
and the general model. The key difference between two models is whether the sample contains
standalone firms or not. When considering nonmerging firms in the analysis, the estimate of merger
values is also positive and significant according to Column (1), being consistent with Column (2). This
result suggests that merger values are positively correlated with the growth of firms’ stock market values
through the merger. Figure 2.1 supports the result in Table 2.8. Here, we compare Tobin’s Q during pre-
merger and post-merger periods for merging and standalone firms. Note that two groups of firms show a
similar pattern of decreasing Q during pre-merger years. This implies that they have similar

55
characteristics before merger transaction year. The group of merging firms experience a larger increase
in Tobin’s Q between one year before the merger and the transaction year than the group of standalone
firms. Given that two groups of firms have analogous pre-merger attributes, the merger plays a positive
role in raising market valuation.
Innovation and Profitability
According to the findings in Chapter 1, technology similarity raises merger values through the channel
of increasing post-merger innovation outcomes such as more patents and citations. In this section, we also
examine the channel of merger value creation by including standalone firms into the sample. As we
discussed before, this model specification is more desirable than the model set-up in Chapter 1 in the
sense that we control for selection bias resulted from nonrandom selection of merging firm samples. The
main estimation results in Table 2.9 are consistent with the findings in the previous chapter. Specifically,
merger values are positively correlated with post-merger innovation outcomes such as more patents and
citations, greater originality and higher patenting risk. In order to investigate the channel of merger value
creation, we do counterfactual regressions excluding the contribution of technology and product market
similarities from merger values. Those results are also shown in Table 2.9. While all positive innovation
impacts disappear when shutting down the coefficient for technology similarity (i.e. Model: When
αMAHA=0), they become larger and more significant when ignoring product market similarity (i.e. Model:
When αPMAHA=0) than those in the baseline model. These results imply that technology similarity plays the
most important role in creating merger values through the channel of raising innovation outputs. This
importance of technology similarity is supported by the fact that the impacts of merger values on merger
incidence become insignificant when shutting off technology similarity in merger value function following
Column (2) in Table 2.7.
However, there is no significant relationship between merger values and measures of profitability (e.g.
gross margin, cost-sales ratio, returns on assets and returns on sales) following columns (7)-(10) in Table
2.9. These results imply that merging firms in our sample care about innovation impacts rather than post-
merger product market performance when performing mergers. One possible explanation is that firms in

56
the sample belong to manufacturing industries that are more technology-dependent than other sectors
such as finance or service industry. Another explanation is that we restrict our sample of firms which are
granted at least one patent during the sample periods, also implying that they are high-tech firms.
2.4 Conclusion
A two-sided matching model is a useful theoretical framework to analyze firms’ merger partner choice.
Nevertheless, assumptions in the model in previous literature prevent us from appropriately addressing
econometric issues in merger analysis. For example, prior studies only consider actual merging firms in
their sample, leading to selection bias in model estimates. Another common assumption is that firms’ role
in mergers as either an acquirer or a target is predetermined, even though it is a part of merger decision
at the time of the merger transaction. By both including standalone firms into our sample and allowing
firms to choose whether to be an acquirer or a target, we set up a general model of two-sided matching
in this chapter. Since we consider unobservable factors not related to firms’ merger partner selection, this
model can resolve the endogeneity problem caused by nonrandom sample selection of merging firms.
The main estimation results in the general model of two-sided matching are consistent with the
findings in Chapter 1. Technology similarity between two firms increases their merger values, implying that
firms prefer to merge with other firms with more similar technologies as their merger partner. Moreover,
the channels for creating merger values due to technology similarity are post-merger innovation outcomes
such as more patents and citations, higher technological diversity and patenting risk. Finally, our general
model performs better than the probit model in terms of different measures of model fit.
Nonetheless, our general model has a limitation in that it assumes a static model. Thus, it cannot
analyze firms’ dynamic matching behavior such as multiple mergers within the same year or consecutive
mergers for several years. For example, even though an acquiring firm’s merger in 1996 can affect its
mergers following 1996, our general model cannot reflect that point. In the future, a dynamic model of
two-sided matching will tackle this issue.
57
2.5 Tables and Figures
Table 2.1: Descriptive Statistics for Standalone Firms
Variable
Description
Mean
Std. Dev. N
R&D intensity R&D expenditure 0.499 0.941 369
Tobin’s Q log 1.03 0.492 369
IND1
Pharmaceutical Industry
0.187
0.39
369
IND2
Semiconductor Industry
0.106
0.308
369
IND3
Electronics Industry
0.133
0.34
369
IND4
Computer & Communications Industry
0.173
0.379
369
IND5
Other Industry
0.4
0.49
369
Table 2.2: Merger Value Estimation
Model
General Model
Model in Chapter 1
(1)
(2)
(3)
(4)
MAHA
82.272
95.273∗∗
[49.143, 93.443]
[35.333, 95.302]
PMAHA
47.639
79.635∗∗
[20.011, 82.073]
[25.541, 93.370]
CR
10.547
[0.824, 66.496]
[27.282, 88.426]
PCR
0.204
22.259
[-6.215, 56.253]
[14.775,
74.487]
SameState
-7.27
-0.016
16.676
3.288
[-28.813, 21.848]
[-32.505, 0.514]
[-25.619, 39.262]
[-27.897, 15.920]
Tobin’s Qa × Tobin’s Qt
1∗∗
1∗∗
Normalized
Normalized
Normalized
Normalized
R&D intensitya × R&D intensityt
24.954∗∗
7.585∗∗
2.167
7.342
[7.807, 67.516]
[0.390, 65.590]
[-31.243, 66.119]
[-30.527, 68.776]
Number of Inequalities
14,592
14,592
2,684
2,684
% of Inequalities satisfied
31.25%
34.17%
71.68%
71.76%
Number of Merger markets
46
46
46
46
Note: We use maximum score estimation in all columns and run the estimation first setting the coefficient for an interaction term between merging firms’ Tobin’s Q to
+1. We then select the vectors of parameter estimates that maximize the maximum score objective function. 95% confidence interval is shown in brackets. The
coefficients are significant at the 5% level when the confidence interval does not contain 0. Merger market is defined by the combination of target firms’ industry type
and merger transaction year.
** p < 0.05
Table 2.3: Relative Importance of Covariates in Match Value
Model
Column (1) in Table 2.2
Column (3) in Table 2.2
Estimate
Estimate ×
Standard Deviation
Standard Deviation
Estimate
Estimate ×
Standard Deviation
Standard Deviation
MAHA
82.27
0.45 37.02
95.27
0.51 48.59
PMAHA
47.64
0.29 13.82
79.64
0.26 20.71
Tobin’s Qa × Tobin’s Qt
1
0.554 0.554
1
0.266 0.266
Note: Estimate indicate point estimates of each covariate in Table 2.2. Observed and counterfactual mergers are included to compute standard deviation, thus
those figures are different from those reported in descriptive statistics.
Table 2.4: Counterfactual Analysis
(1)
(2)
(3)
(4)
MAHA
PMAHA
% drop in match value
Prediction rate
Model: Column (1) in Table 2.2
0.682
0.262
0%
17.7%
αMAHA = 0
0.31
0.24
76.7%
17.7%
αPMAHA = 0
0.584
0.161
7.1%
22.6%
αMAHA = 0 & αPMAHA = 0
0.003
0
72.5%
54%
Model: Column (3) in Table 2.2
1.042
0.416
0%
45.1%
αMAHA = 0
0.809
0.454
66.8%
30.4%
αPMAHA = 0
0.995
0.229
24.5%
38.1%
αMAHA = 0 & αPMAHA = 0
0.69
0.188
75.2%
21.6%
Note: αMAHA and αPMAHA indicate an estimated coefficient for MAHA and PMAHA in Table 2.2. We do each counterfactual experiment by setting
corresponding parameter estimate in the baseline model to 0 and finding stable equilibrium matches based on deferred acceptance algorithm. MAHA
and PMAHA are the averages of those measures of all the equilibrium matches in each counterfactual experiment. % drop in match value represents
% decrease in sum of match values from equilibrium matches in each counterfactual experiment compared to value sum of equilibrium matches in
our baseline model.
61
Table 2.5: Merger Probability Estimation
CR 1.292
PCR 0.294
SameState
0.091
-0.017
Tobin’s Qa × Tobin’s Qt
R&D intensitya × R&D intensityt
0.185
Year Dummy Included
YES
YES
Industry Dummy Included
YES
YES
Number of Observations
21,303
21,303
Pseudo R2
0.091
0.12
Note: We use probit estimation in all columns. Robust standard errors are in parentheses. The
dependent variable is an indicator variable which is equal to 1 if two firms are merged with
each other.
† p < 0.10, * p < 0.05, ** p < 0.01, *** p < 0.001
Table 2.6: Year-by-Year Goodness-of-Fit
Model
Column (1) in Table 2.2
Column (1) in Table 2.5
Year
Number of
Matches
Predicted
Matches
Prediction
Rate
Average
Rank
Predicted
Matches
Prediction
Rate
Average
Rank
1996
13
0
0%
0%
0
0%
0%
1997
58
5
8.6%
60%
4
6.9%
59%
1998
51
13
25.5%
55%
11
21.6%
52%
1999
98
9
9.2%
60%
9
9.2%
57%
2000
70
11
15.7%
60%
13
18.6%
51%
2001
85
14
16.5%
62%
10
11.8%
53%
2002
61
12
19.7%
57%
8
13.1%
51%
2003
37
8
21.6%
70%
8
21.6%
62%
2004
40
11
27.5%
60%
8
20%
56%
2005
40
14
35%
63%
13
32.5%
55%
2006
40
8
20%
62%
7
17.5%
50%
Total
593
105
17.7%
55%
91
15.3%
50%
Note: Average Rank in Column (5) indicates the percentile of values from actual matches relative to values of
all the counterfactual matches. These values are calculated based on the merger value function in (1) using
estimated parameters from Column (1) of Table 2.2. Average Rank in Column (8) indicates the percentile of
predicted values of realized matches relative to those values of all the counterfactual matches. These predicted
values are calculated using estimated parameters from Column (1) of Table 2.5.
58
Table 2.7: Determinants of Merger Decision
Model
Baseline
αMAHA=0
αPMAHA=0
Merger Value
1.067∗∗∗
0.105
0.879∗∗∗
(0.0942)
(0.0724)
(0.084)
R&D intensitya
-3.444∗∗∗
-2.922∗∗∗
-3.335∗∗∗
(0.441)
(0.41)
(0.417)
R&D intensityt
0.374
1.065∗∗
0.459
63
(0.337)
(0.359)
(0.327)
Tobin’s Qa
1.496∗
1.475∗∗
1.794∗∗
(0.725)
(0.552)
(0.66)
Tobin’s Qt
-1.468∗
-0.341
-1.517∗
(0.704)
(0.529)
(0.644)
Year Dummy Included
YES
YES
YES
Industry Dummy Included
YES
YES
YES
Number of Observations
455
455
455
Note: We use probit estimation as the first stage of Heckman 2-step procedure. Robust standard
errors are in parentheses. The dependent variable is a dummy variable equal to 1 if a pair of firms
performs a merger. † p < 0.10, * p < 0.05, ** p < 0.01, *** p < 0.001
Table 2.8: Growth in Tobin’s Q
(1)
(2)
Model
Column (1) in Table 2.2
Column (3) in Table 2.2
Merger Value
0.0453†
0.0425†
(0.0244)
(0.0219)
Acquirer
R&D intensity
-0.0195
0.0407
(0.0819)
(0.121)
Target
R&D intensity
0.0468∗
0.036
(0.0233)
(0.0541)
λ
0.0427
(0.0461)
Year Effects
YES
YES
Industry Effects
YES
YES
Number of Observations
224
224
Note: We use OLS estimation in all columns. Robust standard errors are in parentheses. The dependent
variable is the difference in averaged Tobin’s Q during 3 years before and after merger (DIFFQ). Merger
Value in Column (1) is computed using the estimated parameters in Column (1) of Table 2.2. Merger value
in Column (2) is calculated using the estimated parameters in Column (3) of Table 2.2. λ represents an
estimated coefficient for the inverse Mills ratio in Heckman twostep estimation.
† p < 0.10, * p < 0.05, ** p < 0.01, *** p < 0.001
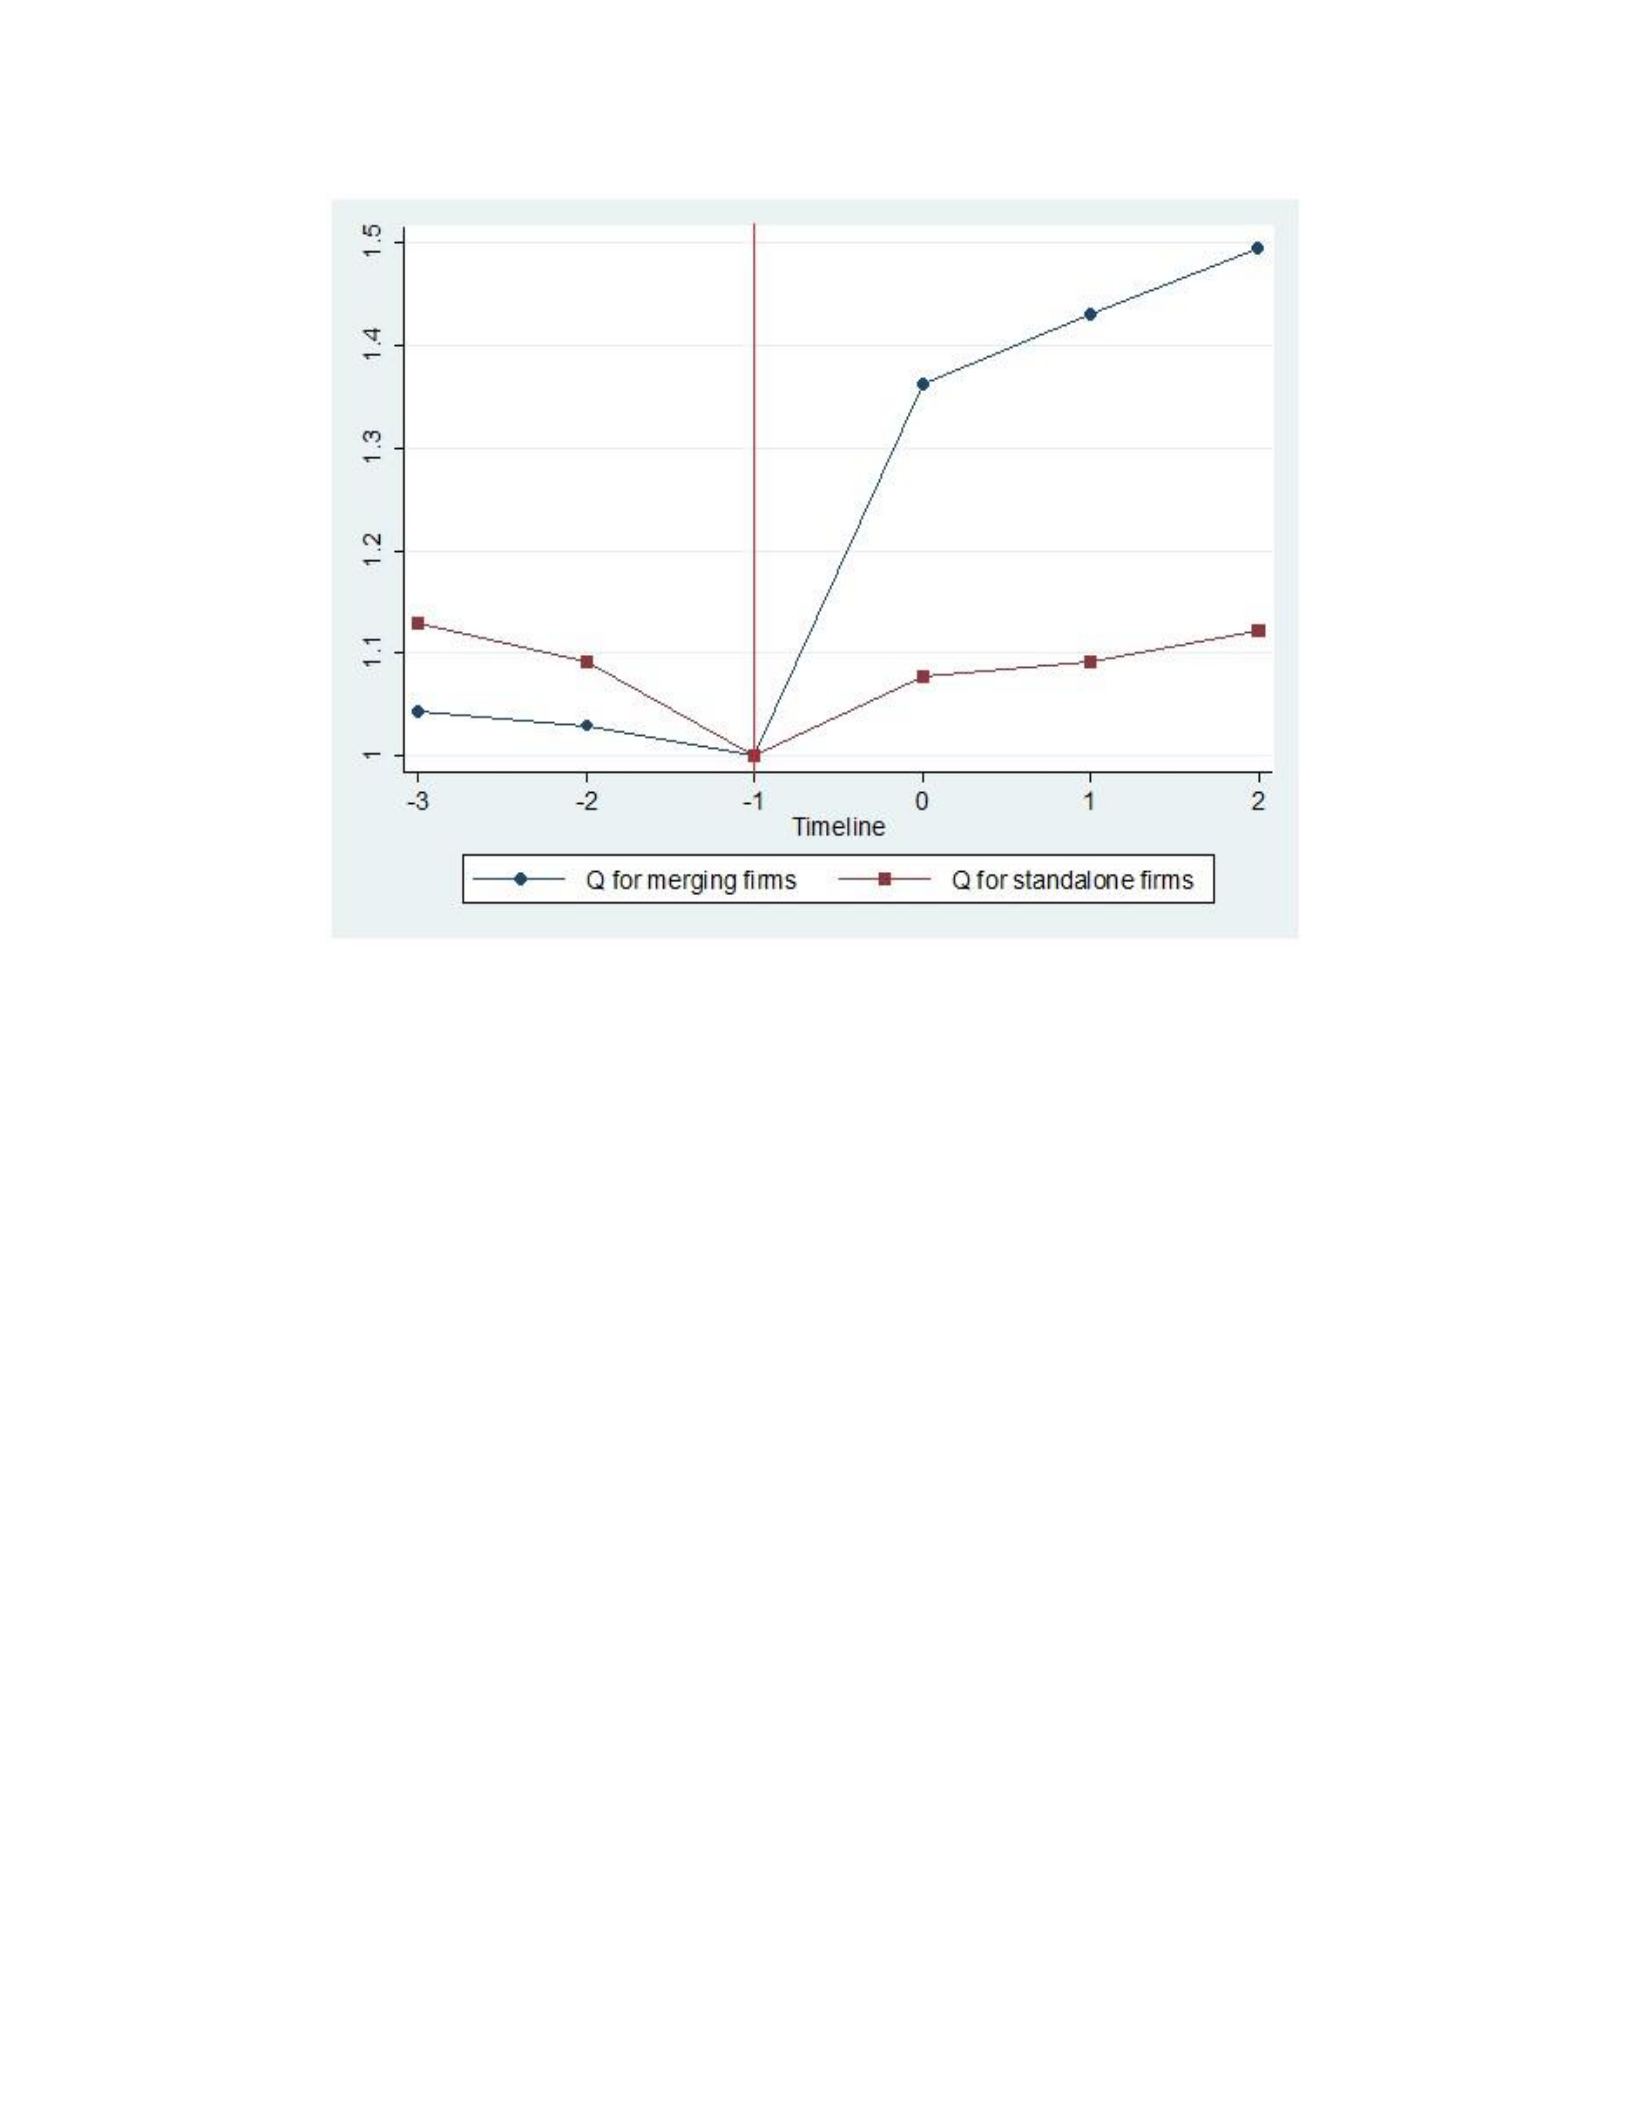
65
Notes: Timeline 0 indicates the year when a merger occurs. For the purpose of comparison, Tobin’s Q in one year before the
merger is normalized to 1 for firms in both groups.
Figure 2.1: The Trend of Tobin’s Q of Merging and Standalone Firms
Table 2.9: Post-Merger Outcome Estimation
(1)
(2)
(3)
(4)
(5)
(6)
(7)
(8)
(9)
(10)
PAT
CWP
CITINT
ORIG
GENERAL
STDV
GM
CSR
ROA
ROS
Model: Baseline
Merger Value
1.075∗∗∗
1.185∗∗∗
0.211∗
0.109∗
0.0799
0.484∗∗∗
0.298
-0.325
0.0397
0.285
(0.309)
(0.348)
(0.0864)
(0.0463)
(0.0494)
(0.105)
(0.512)
(0.511)
(0.0311)
(0.519)
λ
1.079†
1.088†
0.266
0.109
0.0597
0.417∗
0.665
-0.725
0.0627
0.596
(0.582)
(0.656)
(0.163)
(0.0878)
(0.0941)
(0.197)
(0.974)
(0.973)
(0.059)
(0.99)
Model: When αMAHA=0
Merger Value
0.0343
0.0139
-0.0389
0.009
-0.004
-0.0263
0.166
-0.162
0.0122
0.198
(0.122)
(0.138)
(0.0326)
(0.0177)
(0.0188)
(0.0436)
(0.212)
(0.212)
(0.0123)
(0.209)
λ
0.384
0.315
-0.0226
0.009
0.0122
-0.0284
2.112
-2.126
0.093
1.827
(1.008)
(1.137)
(0.269)
(0.146)
(0.156)
(0.36)
(1.71)
(1.71)
(0.1)
(1.701)
Model: When αPMAHA=0
Merger Value
1.176∗∗∗
1.268∗∗∗
0.189∗
0.11∗
0.0823†
0.41∗∗∗
0.462
-0.483
0.0414
0.39
(0.301)
(0.336)
(0.0833)
(0.0453)
(0.0484)
(0.0947)
(0.507)
(0.507)
(0.0309)
(0.514)
λ
1.352∗
1.268†
0.167
0.11
0.0549
0.181
1.074
-1.122
0.0859
0.926
(0.647)
(0.724)
(0.181)
(0.0983)
(0.105)
(0.206)
(1.102)
(1.101)
(0.0669)
(1.12)
Acquirer & Target Controls
YES
YES
YES
YES
YES
YES
YES
YES
YES
YES
Year & Industry Effects
YES
YES
YES
YES
YES
YES
YES
YES
YES
YES
Number of Observations
224
224
224
224
224
224
224
224
224
224

Note: We use OLS estimation in all the columns. Robust standard errors are in parentheses. The dependent variables are as follows. The logged number of patents (PAT)
in Column (1). The logged number of citation-weighted patents (CWP) in Column (2). The ratio of citation counts to patent counts (CITINT) in Column (3). The median
of originality of patents (ORIG) in Column (4). The median of generality of patents (GENERAL) in Column (5). The standard deviation of CWP during 3 years after merger
(STDV) in Column (6). Gross margin (GM) in Column (7). Cost of goods sold divided by sales revenue (CSR) in Column (8). Returns on Asset (ROA) in Column (9). Returns
on Sales (ROS) in Column (10). Merger Value is computed using the estimated parameters in Column (1) of Table 2.2. λ represent estimated coefficients for the inverse
Mills ratio in Heckman two-step estimation.
† p < 0.10, * p < 0.05, ** p < 0.01, *** p < 0.001

68
Chapter 3
Merger-Driven Innovation
3.1 Introduction
Innovation plays an important role in realizing firms’ growth. For example, firms enjoy increased profits
when they develop qualitatively new products via the innovation after investment in research and
development (R&D). Moreover, the innovation in production processes allows firms to reduce production
costs, making them more efficient. While innovation can be induced by exogenous shocks outside
industries such as government regulation, it is also resulted from endogenous innovation activities of firms
within or across industries. The latter perspective means that innovation can be built upon old
technologies employed by firms. Since Schumpeter (1911)’s seminal paper, innovation is considered as a
combination of existing technologies in a different way. In this case, new technology can be regarded as a
function of previous technologies (e.g. Weitzman, 1998).
In this chapter, we suggest that the merger between firms is a crucial driver of innovation. This
conjecture is plausible in the sense that many firms perform mergers in order to realize innovation by
combining their technological resources. For instance, Bena and Li (2014) present that about two-thirds of
merger transactions in their sample occur for the purpose of achieving technical innovations. Then, what
factors do induce these merging firms to realize innovation through the combination of pre-merger
resources? We suggest that technology similarity between merger partners positively affects this
combinatorial type of innovation after the merger. This implies that a firm is more likely to merge with
another firm with similar technologies, expecting the improvement in post-merger innovation.
To investigate the impacts of merger or the effects of technology similarity between merging firms on
post-merger innovation, we use the dataset of U.S. patents in recent decades. Many prior studies use
patents as an indicator of innovation (Griliches, 1990; Fleming, 2001; Hall et al., 2001; Lanjouw and

69
Schankerman, 2004; Strumsky et al., 2011; Akcigit et al., 2013; Bena and Li, 2014). Specifically, it is
appropriate to use the U.S. patent dataset to analyze innovation because it contains the information of
each patent’s technology-based patent classes. Strumsky et al. (2011) and Akcigit et al. (2013) illustrate
how to use these patent classes in defining innovation. I employ one of the innovation types in Akcigit et
al. (2013), a novel combination of existing technologies, as a dependent variable in this study. There are
two reasons for this choice of the dependent variable. First, this type of innovation reflects perspectives
of combinatorial innovation documented in previous literature since Schumpeter (1911). Second, the
recent patent dataset shows an increasing trend of patents with this innovation type. According to Akcigit
et al. (2013), the share of patents with the novel combination of prior technologies rose by 48% point
between the 1870s and the 1970s, whereas the proportion of patents based on novel technologies
significantly fell from 31% point to 0.5% point during the same periods.
Since we care about factors that can affect firms’ merger partner choice, we need to consider drivers
of the merger itself as a preliminary step. There have been many papers examining the determinants of
the merger (Blonigen and Taylor, 2000; Jovanovic and Rousseau, 2002; Bertrand, 2009; Desyllas and
Hughes, 2010; Bena and Li, 2014). Jovanovic and Rousseau (2002) consider Tobin’s Q as the main driving
force of the merger. Estimating effects of Tobin’s Q on a firm’s investment decision, they present that a
firm with high Tobin’s Q is more likely to make a merger deal than a low-Q firm. Some authors suggest that
R&D intensity is the main driver of the merger (Blonigen and Taylor, 2000; Bertrand, 2009; Desyllas and
Hughes, 2010). They document that a firm with lower R&D intensity tends to acquire highly R&D intensive
firms for improving postmerger innovation outcomes.
When it comes to non-financial factors affecting merger incidence as well as firms’ merger partner
choice, a growing number of studies provide similarity in either technology or knowledge between
merging firms as the key factor (Bena and Li, 2014; Ozcan, 2015; Chondrakis, 2016; Rao et al., 2016; Linde
and Siebert, 2016). Bena and Li (2014) suggest that technological proximity between merging partners and
their overlapping knowledge increase the probability of occurring merger between them. Similar to Bena
and Li (2014), Chondrakis (2016) presents that a firm is more likely to make a merger with technologically
closer firms than others without similar technologies. Ozcan (2015), Linde and Siebert (2016) and Rao et

70
al. (2016) apply a two-sided matching model to the analysis of firms’ merger partner selection. Ozcan
(2015) and Linde and Siebert (2016) conclude that the more similar two merging firms’ technologies before
merger deal, the more favorable they are considered as each other’s deal partner. Furthermore, Rao et al.
(2016) suggest that two firms with similar knowledge during pre-merger periods yield high merger value
when merging with each other.
Since we also estimate the impacts of the merger or the effects of determinants of merger partner
selection on post-merger innovation outcomes, we need to review previous literature dealing with those
impacts. Moreover, the findings of those studies are mixed and inconclusive. First, some papers suggest
positive impacts of technological mergers on innovation performance after the merger transaction (Ahuja
and Katila, 2001; Cloodt et al., 2006). Ahuja and Katila (2001) and Cloodt et al. (2006) are similar to each
other in the sense that they examine the role of the technological merger in increasing combined firm’s
patents after the merger. Their common conclusion is that the merged firm has more patents during the
post-merger periods if the absolute size of the acquired knowledge base is large in the context of the
technological merger. Other authors, however, provide negative effects of mergers on post-merger
innovation outcomes (Haucap and Stiebale, 2016; Cunningham et al., 2018; Federico et al., 2018).
Analyzing merger transactions in the European pharmaceutical industry, Haucap and Stiebale (2016)
present that a merger reduces patenting activities and R&D investment of both merged firms and their
standalone rival firms.
Using drug development projects as an innovation measure, Cunningham et al. (2018) suggest that
acquiring firms are more likely to stop continuing those projects due to the acquisition of innovative target
firms. Finally, Federico et al. (2018) provide a theoretical finding that the merger lowers firms’ incentives
to innovate and makes consumers worse off. Nevertheless, all these studies do not examine the impacts
of ex-ante technology similarity between merging partners on post-merger outcomes.
For these effects of pre-merger technology similarity between firms on post-merger outcomes, there
have not been many studies on this topic (Cassiman et al., 2005; Makri et al., 2010; Chondrakis, 2016; Rao
et al., 2016). Nevertheless, those studies commonly suggest positive effects of technology proximity on
the outcomes after the merger. Rao et al. (2016) present that the more similar merging firms’ knowledge

71
before the merger, the greater the combined firm’s number of patents after the deal. Cassiman et al. (2005)
conclude that ex-ante technology relatedness between merger partners improves post-merger R&D
performances. Makri et al. (2010) and Chondrakis (2016) also suggest that pre-merger technology
similarity and complementarity between acquirers and targets have positive impacts on post-merger
outcomes such as R&D productivity and abnormal returns, respectively.
Finally, we follow the approach of previous literature jointly analyzing merger partner choice and post-
merger outcomes (Park, 2013; Rao et al., 2016; Ishihara and Rietveld, 2017). They apply Bayesian Markov
chain Monte Carlo (MCMC) simulation to the estimation of a structural model of two-sided matching.
Ishihara and Rietveld (2017) present that game publishers are more likely to acquire developers with
higher development capabilities, which leads to high-quality products as well as better sales performance
during the post-acquisition periods. After analyzing merger deals in the U.S. mutual fund sector, Park
(2013) emphasizes that managers of inefficient acquiring firms have greater willingness to perform merger
with high-quality target firms. Moreover, she suggests that factors affecting merger partner choice such as
similarity in the fund distribution channel between two mutual fund companies also influence the post-
merger asset growth rate. Rao et al. (2016) conclude that the similarity in combining firms’ knowledge has
positive impacts on both merger partner choice and ex-post innovation outputs (the number of patents).
To the best of my knowledge, there is no literature that examines the effect of either merger itself or
technology similarity between merger partners on combinatorial innovation drived by merging firms’
existing technologies. This research question is important in the sense that we can predict the innovation
outcome of potential mergers in terms of the novel combination of preexisting technologies. First, we
employ propensity score matching to investigate the impacts of the merger on combinatorial innovation.
The rationale for using this approach is that we cannot observe counterfactual outcomes of merging firm
pairs when they are not merged. Second, Bayesian MCMC simulation is applied to the joint analysis of
merger partner choice and postmerger innovation. It is one of the common empirical methods to estimate
structural matching models together with maximum score estimation.
Section 2 discusses estimation methodology. Section 3 presents empirical results. The last section
concludes.
72
3.2 Empirical Strategy
3.2.1 Propensity Score Matching
One challenge in merger analysis like nonexperimental studies is nonobservability of outcome
variables in the absence of the merger. It is clearly shown by the following example. Suppose that ij
represents a pair of firms under consideration. Let Yij,1 be the outcome variable when the firms i and j are
treated, i.e. merged, and let Yij,0 be the outcome of the same pair when it is not treated. Then, we can
compute the treatment effect for the firm pair ij as τij = Yij,1 − Yij,0. Based on this,
the expectation of the treatment effect for the group of merging firm pairs is
τ|Merger=1 = E(τij|Mergerij = 1)
= E(Yij,1|Mergerij = 1) − E(Yij,0|Mergerij = 1), (3.1)
where Mergerij = 1 (= 0) if the firms i and j are merged (not merged). The problem of this approach is that
we can estimate E(Yij,1|Mergerij = 1), but E(Yij,0|Mergerij = 1) is not estimable because we do not know the
outcome when the firm pair ij is not merged.
Another challenge is that the outcome is more likely to be correlated with the merger decision. To
demonstrate this, consider the following estimation equations:
Pr(Mergerij , (3.2)
Yij = αMergerij + ψij,
(3.3)
where Yij indicates a dependent variable and ψij represents an idiosyncratic error term. According to (3.2),
the firm pair ij’s probability of performing a merger depends on their characteristics Xij before the merger.
Since its post-merger outcome Yij is influenced by its merger decision as well as pre-merger attributes Xij,
the estimates in the second equation will be biased unless Xij are included in (3.3). For example, firms’
characteristics such as pre-merger R&D intensity can influence their future innovation outcomes as well
as the likelihood of merging with other firms.
73
To address the aforementioned challenges, we use the propensity score matching method suggested
by Rosenbaum and Rubin (1983). The basic assumption of this approach is as follows. The outcomes of a
control group composed of standalone firms with observable attributes similar to those of merging firms
can be considered as counterfactual outcomes of the treated group. We focus on the average treatment
effect on the treated group (ATT). Then, the ATT is calculated by
τˆ|Merger=1 = Yij
N ij∈N
Yij
, (3.4)
N ij∈N
where N is the set of merging firms, ωij are weights imposed on the control sample, Cij is the set of the
control sample (i.e. standalone firms) matched to the merging firm pair ij based on the propensity score,
and | · | represents the number of elements in the set. The outcome variable of interest, Yij, is the ratio of
the novel combination of existing technologies for the merging firm pair ij. Among various types of
matching methods, we use the kernel matching approach in which all treated units are matched to control
units with weights inversely proportional to the distance in propensity scores between treated and control
units.
To compute the propensity score, we use the following explanatory variables: the 3-year average of
acquirer’s R&D intensity and Tobin’s Q before a merger, the 3-year mean of target firm’s R&D intensity and
Tobin’s Q during the pre-merger periods, a dummy variable for each merger transaction year, and a dummy
variable for acquirer’s industry type. These variable are chosen based on the previous literature about the
determinants of firms’ merger decision (Blonigen and Taylor, 2000; Jovanovic and Rousseau, 2002;
Bertrand, 2009; Desyllas and Hughes, 2010; Bena and Li, 2014).
74
3.2.2 Bayesian Estimation with Gibbs Sampling
In previous two chapters, we use maximum score estimation approach to estimate a two-sided
matching model with transferable utility. Here, we employ a structural two-sided matching model without
transferable utility as a theoretical framework of merger analysis. This model is composed of two parts.
The first one is a selection equation which determines values of every merger match between acquirers
and targets. Let the value of potential merger between an acquirer a and a target t be Vat, then the
selection equation becomes
Vat at, (3.5)
where Wat represents a vector of observable attributes of the merging firm pair a and t, and ηat is a
unobservable error term. This selection equation is based on a discrete choice model in the sense that
each merger match between a potential acquirer and a potential target can be either observed or
unobserved. This observability of an acquirer-target pair depends on the difference in valuations
(preference ranking) among all the feasible matches. We exclude constant terms from Wat to normalize
parameters in the equation (3.5). The rationale for using this normalization is that the preference ranking
of all the potential matches does not vary with a uniform change in the scale or level of every match value.
By setting a variance of the error term ηat to 1, we normalize those parameters in the selection equation.
In the selection equation, the product of observable characteristics and estimated parameters,
W, determines the rank of every potential merger match. Accordingly, whether a match is realized or
not depends on this product term. Moreover, signs of parameters α show a direction of effects on match
valuation of match-specific characteristics. For example, if the estimate of exante technology similarity
between an acquirer and a target is positive, then the match value will be higher for pairs of firms with
more similar technologies than the matching between technologically unrelated firms. If the estimated
coefficient for the interaction term of merger partners’ R&D intensity has a positive sign, then merging
firms with the similar level of R&D intensity can achieve larger match value than those with different
intensities.
75
The second component of the structural model is an outcome equation. Let the observable
characteristics of acquirer a and target t be Xat and let the outcome variable after merger be Yat for each
merger match (a, t). Then, the outcome equation can be written as
Yat eat, (3.6)
where eat is a unobserved error term. Theoretically, all the potential merger matches between acquirer a
and target t have values of Yat. However, we observe Yat only for realized merger matches in the data.
When it comes to the distribution of error terms, we follow the same assumptions in Sørensen (2007).
First, the joint distribution of two error terms (eat, ηat) follows a bivariate normal distribution such that
eat 1 + κ2 κ
∼ N 0, . (3.7)
ηat κ 1
The key difference between the reduced form and structural approaches comes from the covariance of
error terms in the selection and the outcome equation, κ. Even though this covariance structure is found
in Heckman’s two-step procedure, it differs from Heckman’s model because of the assumption on complex
interactions among potential firms in the first stage matching model. The structure of covariance between
error terms can be written as
eat = ηatκ + νat, (3.8)
where κ indicates unobservable factors that affect match values as well as post-merger outcomes, and νat
is a unobserved error term in the outcome equation. Plugging the equation (3.8) into (3.6), then
Yat . (3.9)
Thus, we control for latent match valuations to precisely estimate post-merger outcomes given that κ 6=
0. Moreover, substituing the equation (3.5) to (3.9), then
Yat . (3.10)
Hence, we obtain the following equations for two error terms from (3.5) and (3.10):
76
, (3.11)
. (3.12)
A merger market is defined by merger transaction year and 5 industry types of target firms:
pharmaceutical, semiconductor, electronics, computers & communications, and other sectors. This merger
market is indexed by m = 1, 2, ..., n. Given the merger market m, there are two sets of firms in each merger
market: the set of acquiring firms Am and the set of target firms Tm. Also, we denote the set of all the values
from potential mergers Mm between acquirer a and target t as Vm = {Vat : (a, t) ∈ Mm}. Moreover, the set
of the outcome variables from observed matching is Ym = {Yat : (a, t) ∈ µm}, where µm is the set of pairwise
stable merger matches. We denote the collection of latent match valuations and outcome variables in all
the merger markets as V and Y, respectively. The model does not impose any restriction on the
unobservable outcome variables in terms of implementing a stable matching equilibrium. Thus, it is not
necessary to include outcome variables of unobserved merger matches in the estimation. Similar to
notations above, the explanatory variables in the selection equation for the merger market m is indicated
by Wm = {Wat : (a, t) ∈ Mm}. The independent variables in the outcome equation for the same market is
denoted by Xm = {Xat : (a, t) ∈ Mm}. Then, the pairwise stable matching equilibrium condition can be written
as the following:
Vat > Vat ∀(a, t) ∈ µm,
(3.13)
Vat < Vat ∀(a, t) ∈/ µm,
(3.14)
where Vat ≡ max{maxa0∈S(t) Va0t, maxt0∈S(a) Vat0 } with S(t) ≡ {a ∈ Am|Vat > Vµ(t),t} and S(a) ≡
{t ∈ Tm|Vat > Va,µ(a)}, for every merger market m, Vat ≡ max{Vµ(t),t, Va,µ(a)}. That is, Vat is the opportunity cost
of maintaining current match, so that a pairwise stable equilibrium matching does not allow any blocking
pairs. Moreover, since unobserved matches do not guarantee valuations from each merging firm’s current
match, it is better for firm pairs not belong to stable equilibrium matches to stay with existing merger
partners.

77
Let the set of valuations from the equilibrium matches be VE. In other words, the match values included
in VE satisfy the equilibrium condition inequalities (3.13) and (3.14). Then, a potential merger match
between acquirer a and target t is observed in the data if and only if Vat ∈ VE. Combining this equilibrium
condition and the equation (3.11), a matching µ is pairwise stable if and only if
η ∈ VE − Wα, (3.15)
where η and W are the vector of error terms and the matrix of explanatory variables of all the merger
matches in the every merger market, respectively. Thus, the following likelihood function
Z
l(µ; α) = Prob{η ∈ VE − Wα} = 1[η ∈ VE − Wα]dF(η) (3.16)
must be maximized at a stable matching equilibrium.
One empirical method to estimate this structural matching model is Bayesian estimation with Gibbs
sampling, a type of MCMC simulation methodology, and data augmentation. A standard discrete choice
model like logit or probit analysis depends on maximum likelihood estimation based on the given
assumption of the error term distribution. When the sample size is large and all the error terms are
independent of each other, key parameters are identified by maximizing the product of likelihood function
of every error term. The two-sided merger matching model, however, contains individual error terms
related to each other in the sense that any realized merger match is a consequence of complex interactions
among all the firms within the same merger market. Thus, each likelihood function of error terms satisfying
a stable matching equilibrium condition should be integrated at the same time. In this case, Bayesian
estimation with Gibbs sampling is a solution to avoid a high-dimensional integration problem, so that the
estimation becomes more tractable. Moreover, we treat latent merger match values in the selection
equation as nuisance parameters to be estimated. This is called the method of data augmentation. Using
this methodology makes the simulation procedure less complex (Tanner and Wong, 1987; Albert and Chib,
1993).
78
Prior Distribution of Key Parameters
Suppose that there is a prior normal distribution for parameters of interest, θ ≡ (α, β, κ). The marginal
prior distribution of each parameter is as follows: α ∼ N(0, 10I), β ∼ N(0, 10I), and κ ∼ N(0, 10), where I
is an identity matrix with dimensions corresponding to each parameter. The rationale for using large
variance in all the prior distributions of parameters is to make prior more uninformative so that they will
eventually converge to the posterior distribution. Accordingly, the simulated posterior distribution also
follows a normal or a truncated normal distribution. We denote densities defined by the model as p(·).
Thus, p
C , and p, where C is a generic constant such that the
integral of p(·) is equal to 1. Then, the joint prior density of those parameters is
p , (3.17)
where Σθ is the variance-covariance matrix based on the prior distribution of all the parameters. This matrix
can be constructed by multiplying 10 to identity matrix and decomposed into Σα, Σβ, and Σκ.
Likelihood function
Let V−at be the valuations from all the possible merger matches except for the value of merger match
between a and t, Vat. Then, the likelihood function is defined by the joint probability of obtaining
equilibrium matching and observing post-merger outcome variables given the other matches’ valuations,
explanatory variables in the selection and the outcome equations and parameters. That is,
Z
L(µat,Yat|Wat, Xat, θ) = p(Vat,Yat|V−at,Wat, Xat, θ)dG(η, ν)
ZVat∈VE (3.18)
= p(Vat|V−at,Wat, θ)p(Yat|Vat,Wat, Xat, θ)dG(η, ν).
Vat∈VE
Thus, the likelihood function for the entire merger markets can be written as
79
N Z
L(µ,Y|W, X, θ) = C × ∏
m=1 Vm⊂VE (a,t)∈Mm
Yat.
(3.19)
2
However, it is difficult to simulate parameter draws directly from this posterior distribution because Vm ⊂
VE is not observable. In this case, data augmentation combined with Gibbs sampling method provides a
reasonable solution to this problem. Previous studies suggest that the estimation of latent variables,
known as data augmentation, can remarkably simplify the simulation procedure (Tanner and Wong, 1987;
Albert and Chib, 1993). Following their convention, we also consider latent merger match values Vm as
nuisance parameters to be estimated. Given the prior density of parameters and the likelihood function
augmented by the conditional density of latent match valuations, the augmented posterior distribution of
parameters is
N
π(V, θ|W, X, µ,Y) = C × p(θ) × ∏ L(µm, Vm,Ym|Wm, Xm, θ)
m=1 (3.21)
(a,t)∈Om
Augmented Posterior Distribution
The posterior distribution of parameters is represented by
π(θ|W, X, µ,Y) = C × p(θ) × L(µ,Y|W, X, θ).
(3.20)

80
N
= C × p(θ) × ∏1(Vm ⊂ VE)p(Vm,Ym|Wm, Xm, θ).
m=1
Bayesian Estimation Procedure
Using Gibbs sampling with data augmentation, parameters of interest are drawn from the posterior
distribution. The rationale for using Gibbs sampling is that while it is hard to obtain a simulated draw of a
parameter from the joint density of all the parameters, drawing from conditional density given the values
of other parameters allows simulation to be more tractable. The basic process of Gibbs sampling is the
following: start from initial values for key parameters θ ≡ (α, β, κ) and latent match values V, say (α(0),
β(0), κ(0), V(0)). Then, simulate α(1) using the conditional posterior density φ(α|β(0), κ(0), V(0)). With simulated
draw of α(1) and the conditional density, draw β(1) from φ(β|α(1), κ(0), V(0)). Then, κ(1) is drawn using
φ(κ|α(1), β(1), V(0)). Accordingly, parameters are simulated following this processes based on a large
number of iterations. Since these simulated draws will follow the true joint density of parameters, we can
obtain the mean and variance of every parameter of interest using them.
3.3 Empirical Results
3.3.1 The Impact of Merger on Novel Combination of Existing Technologies
Estimation results on merger probability in Table 3.1 are consistent with those in the previous
literature. Target firms are more likely to have higher R&D intensity, whereas acquiring firms tend to be
less R&D intensive. Moreover, acquirers with higher Tobin’s Q before mergers have higher probability of
performing merger transactions. Propensity score of merger is calculated based on the probit regression
results in Column (3). Then, we match standalone firms (control group) to merging firms (treated group)
using similar propensity scores. In the end, the expected treatment effect of a merger on novel
combination of existing technologies among entire and matched samples are shown in Table 3.3.

81
Specifically, the average treatment effect on treated samples (ATT) suggests that merging firms have higher
ratio of innovation outcomes with novel combination of pre-existing technologies than the ratio when they
are not merged.
Figure 3.1 shows the novel combination ratio for both standalone and merging firms depending on the
propensity score. Note that novel combinatorial innovation is more likely to occur in merging firms with
higher propensity score of performing merger. Furthermore, standalone firms with higher propensity score
tend to have patents composed of novel combination of pre-existing technologies. These results imply that
we can predict more patents developed by innovative combination of old technologies for merging firms.
Another way to identify the impact of the merger on novel combinatorial innovation is using a
weighted regression for matched samples. According to the estimation results in Table 3.4, the group of
merged firms has the ratio of novel combination patents 37% higher than standalone firms. Among other
attributes affecting post-merger novel innovation, the R&D intensity of target firms plays a positive and
marginally significant role in raising the ratio.
3.3.2 The Impact of Technology Similarity on Novel Combination of Existing Technologies
Given that mergers have positive effects on novel combination of old technologies, we estimate the
impacts of the merger match-specific attributes on the same outcome variable. Here, a matchspecific
variable of interest is the measure of technology similarity between merging firms. Table 3.5 presents
estimation results of selection equation which is the first stage of Bayesian MCMC estimation. Being
consistent with results in previous two chapters, technology similarity plays a positive role in firms’ merger
partner choice in all columns. In other words, firms prefer other firms with more similar technologies as
their merger partners. When it comes to other factors correlated with merger partner decision, product
market similarity has positive impacts on merger value creation according to columns (3) and (4).
Moreover, there is a positive assortative matching in terms of both total asset and Tobin’s Q of merger
partners in all columns. These results suggest that similarity in firm size and market valuation before
merger can drive firms’ merger partner selection.

82
Turning to the estimation results of the outcome equation, technology similarity has positive effects
on novel combination of existing technologies in all columns of Table 3.6. These results can be supported
by the absorptive capacity hypothesis suggested in Cohen and Levinthal (1990). Based on the hypothesis,
performance of learning can be maximized when the target of learning is associated with pre-existing
technologies or knowledge. Once two merging firms have similar and related technologies before their
merger, the merged entity can easily assimilate old technologies and develop new invention by combining
them in an innovative way. Figure 3.2 shows the distribution of novel combination ratio (NCR) of the
merged firms over MAHA measure. Except for outliers (NCR=0), NCR has generally a positive correlation
with technology similarity. Furthermore, note that the covariance between the selection and outcome
equation, κ, has positive and significant estimates in all columns of Table 3.6. This implies that there are
some unobserved factors that positively affect firms’ merger partner selection as well as the merged firms’
novel combination of pre-existing technologies.
3.4 Conclusion
Innovation plays an important role in realizing economic growth. Firms use mergers as a way to achieve
innovation. Specifically, two potential merging firms can combine their existing technologies, leading to
novel combinatorial innovation of old technologies. This chapter suggests that merger has positive impacts
on this type of innovation. With the propensity score matching method, we find that merging firms enjoy
higher ratio of novel combination patents than those in the absence of the merger. Further, we find that
technology similarity between two merger partners positively affects novel combinatorial innovation by
estimating the impacts through Bayesian MCMC simulation. Taken together, we can predict more
innovation outcomes (e.g. patent) based on novel combination of pre-existing technologies for merging
firms with similar technologies.
Our measure of post-merger innovation outcome, NCR, is based on the number of patents that have
the new combination of old technologies not previously used before a merger but each individual
technology is used before the merger. Since we focus on patents with the novel combination of existing
technologies which have been increased in recent decades following Akcigit et al. (2013), this measure can

83
better capture the recent trend of innovation than other metrics. Moreover, the novel configuration of
existing technologies can be the main drivers for long-term economic growth as Weitzman (1998) suggests.
Nevertheless, this measure has limitations to measure novel and transformative innovation in the sense
that novel innovation instead of novel combinatorial innovation represents no appearance of technologies
before the merger. For the future work, it is worthwhile to examine the impacts of technology similarity
on the novel innovation outcomes such as novel patents or the ratio of novel patents scaled by citations.
84
3.5 Tables and Figures
Table 3.1: Determinants of Merger Decision
Year Dummy Included
YES
NO
YES
Industry Dummy Included
NO
YES
YES
Number of Observations
455
455
455
Pseudo R2
0.22
0.22
0.23
Note: We use probit estimation in all columns. Robust standard errors are in parentheses. The dependent
variable is a dummy variable equal to 1 if a pair of firms performs a merger.
† p < 0.10, * p < 0.05, ** p < 0.01, *** p < 0.001
Table 3.2: Difference in Characteristics
Acquiring firms
Standalone firms
(Total)
Standalone firms
(High propensity score)
Mean SD
Mean
SD
Mean
SD
log(Asset)
7.159 2.012
4.96
2.088
5.158
1.966
R&D intensity
0.166 0.266
0.499
0.941
0.162
0.198
Tobin’s Q
1.104 0.126
1.03
0.492
1.158
0.427
NCR
0.429 0.3
0.209
0.328
0.17
0.286
Note: The sample of standalone firms with high propensity score is chosen when the propensity
score is greater than 0.3.
Table 3.3: The Treatment Effects of Merger on Novel Combination of Existing Technologies
Sample
Treated
Controls
Difference
T-statistics
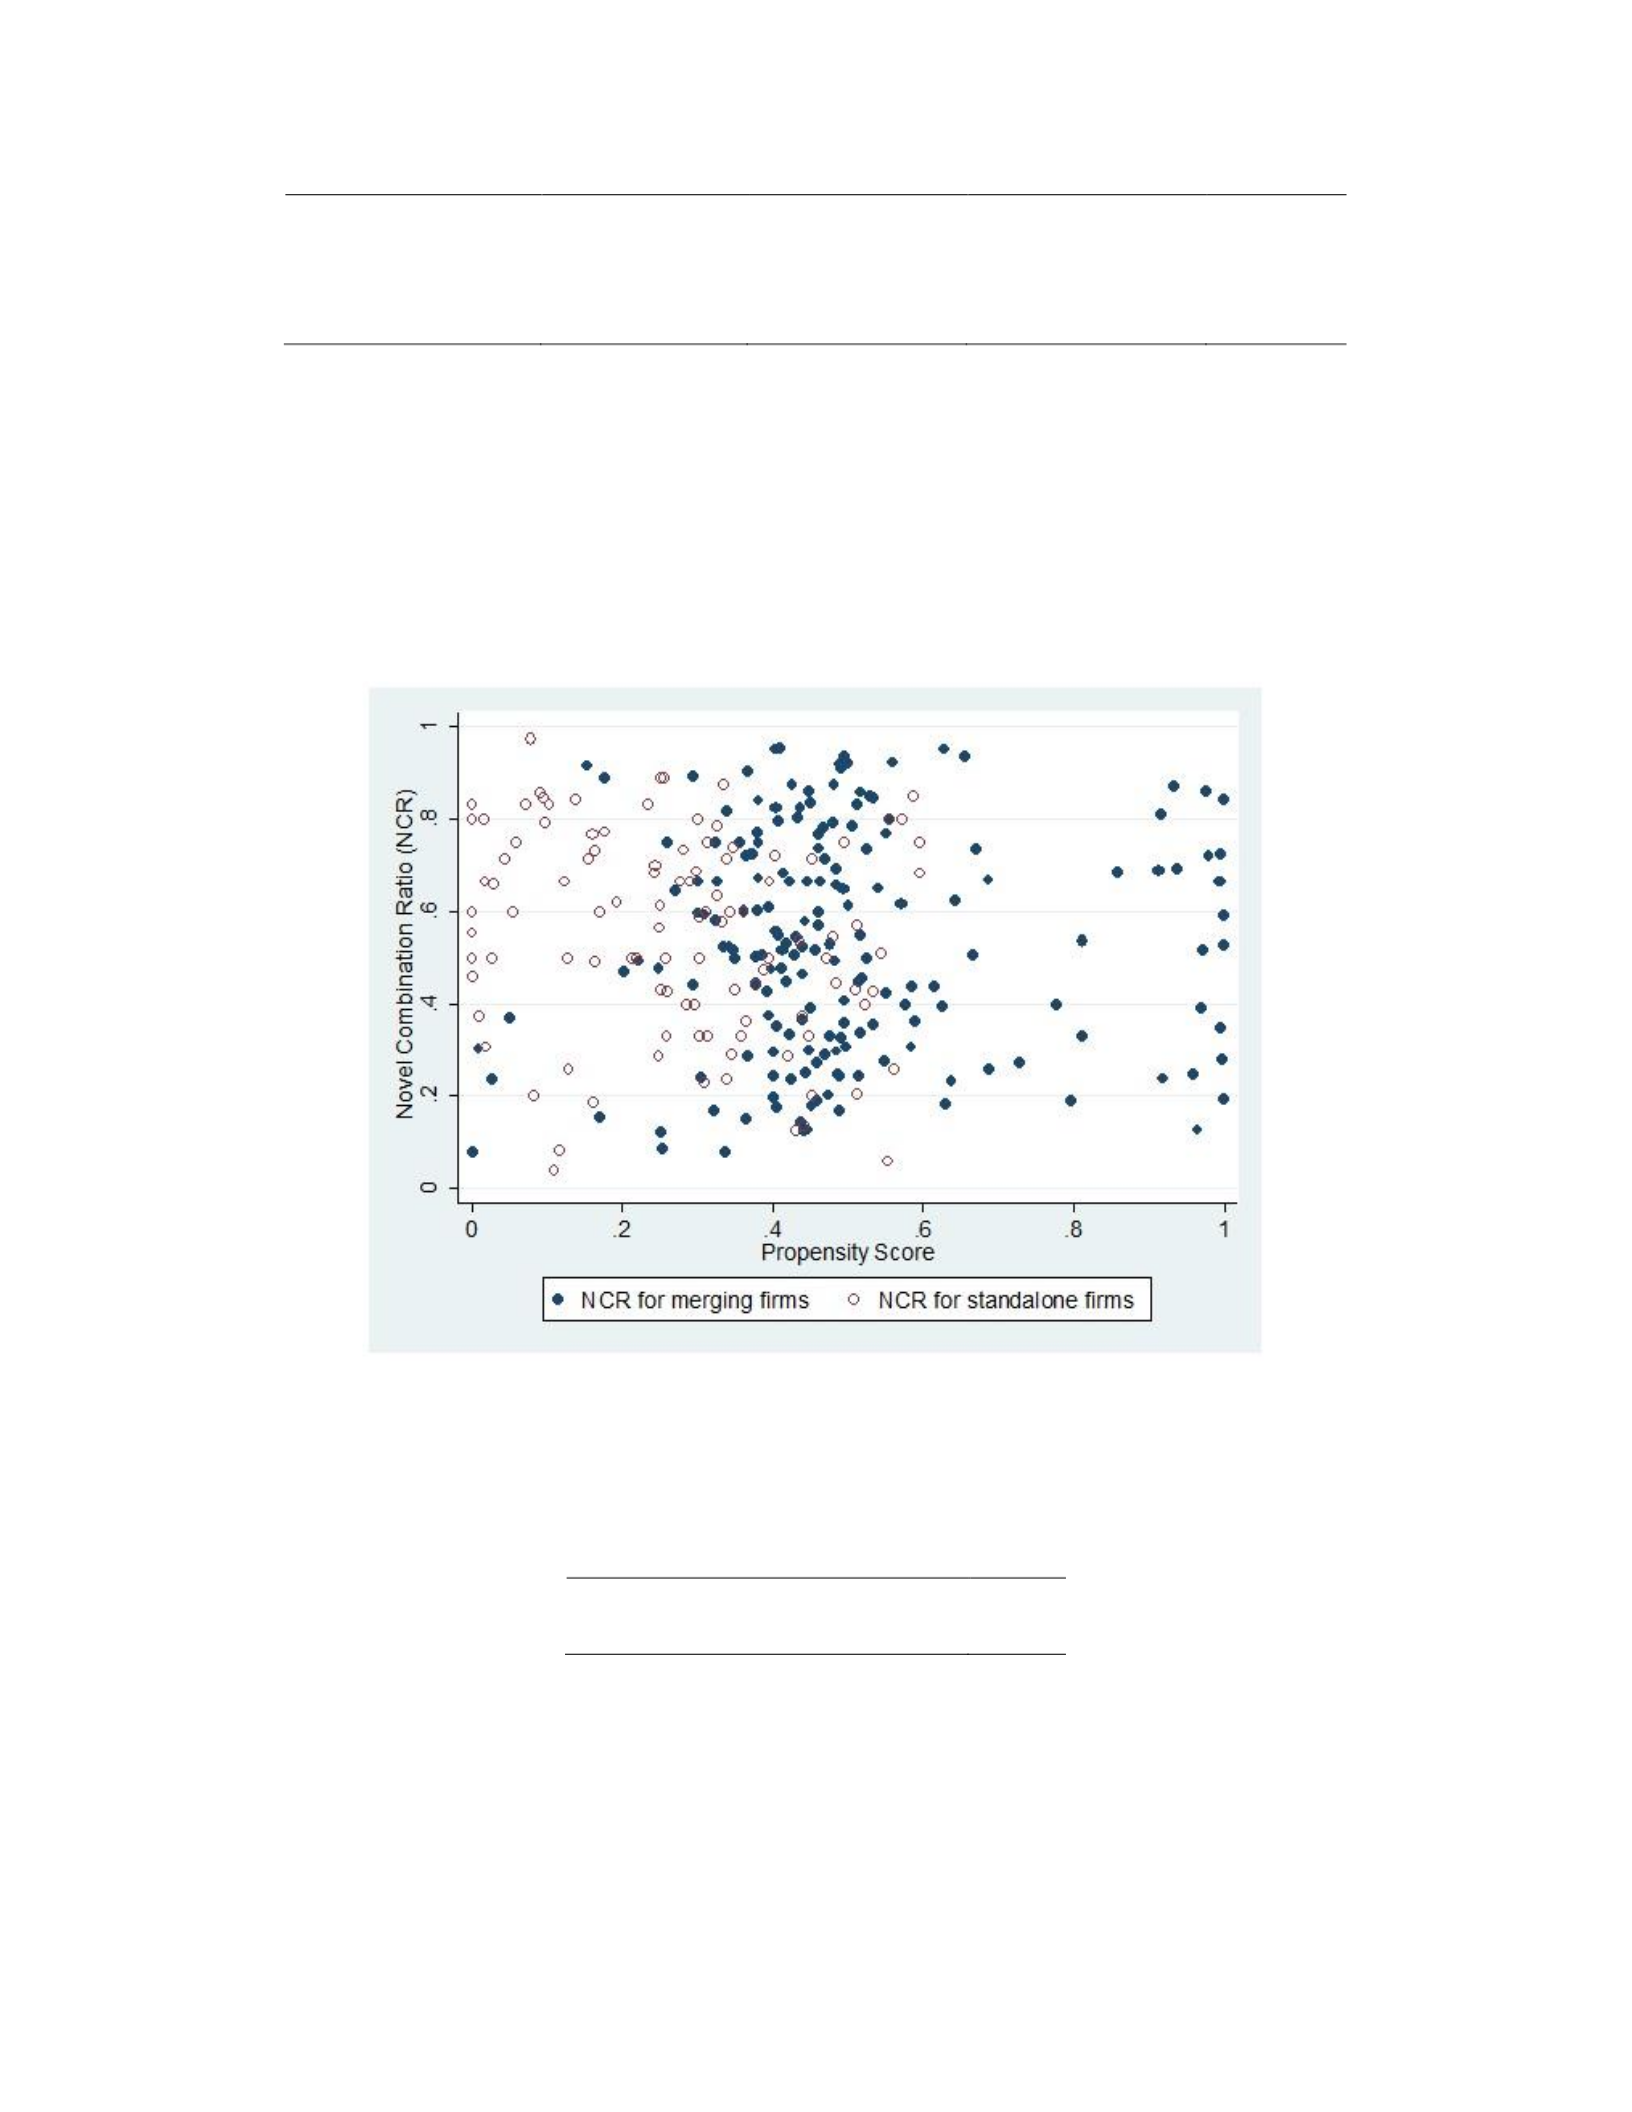
85
Unmatched
0.527
0.209
0.318∗∗∗
11.7
ATT
0.53
0.15
0.38∗∗∗
11.22
Note: We use propensity score matching. The dependent variable is a ratio of novel combination of existing
technologies. ATT represents the average treatment effect of merger on the novel combination ratio for
the treatement group.
† p < 0.10, * p < 0.05, ** p < 0.01, *** p < 0.001
Notes: This figure includes 369 standalone firms and 224 observations for the merging firm pairs. NCR is the ratio of novel
combination of existing technologies.
Figure 3.1: The Novel Combination Ratio based on the Propensity Score
Table 3.4: The Effects of Merger on Novel Combination of Existing Technologies
Deprendent Variable
NCR
86
Merger dummy
R&D intensitya
R&D intensityt
Tobin’s Qa
Tobin’s Qt
0.37
Year Dummy Included
YES
Industry Dummy Included
YES
Number of Observations
408
Adjusted R2
0.3
Note: We use weighted OLS estimation. Robust
standard errors are in parentheses. The
weights are calculated based on the propensity
score from probit estimation results. The
dependent variable is a ratio of patents with
novel combination of existing technologies
(NCR).
† p < 0.10, * p < 0.05, ** p < 0.01, *** p <
0.001
Table 3.5: Estimation of Selection Equation
× 0.068 0.071∗∗∗ 0.054∗∗∗ 0.057∗∗∗
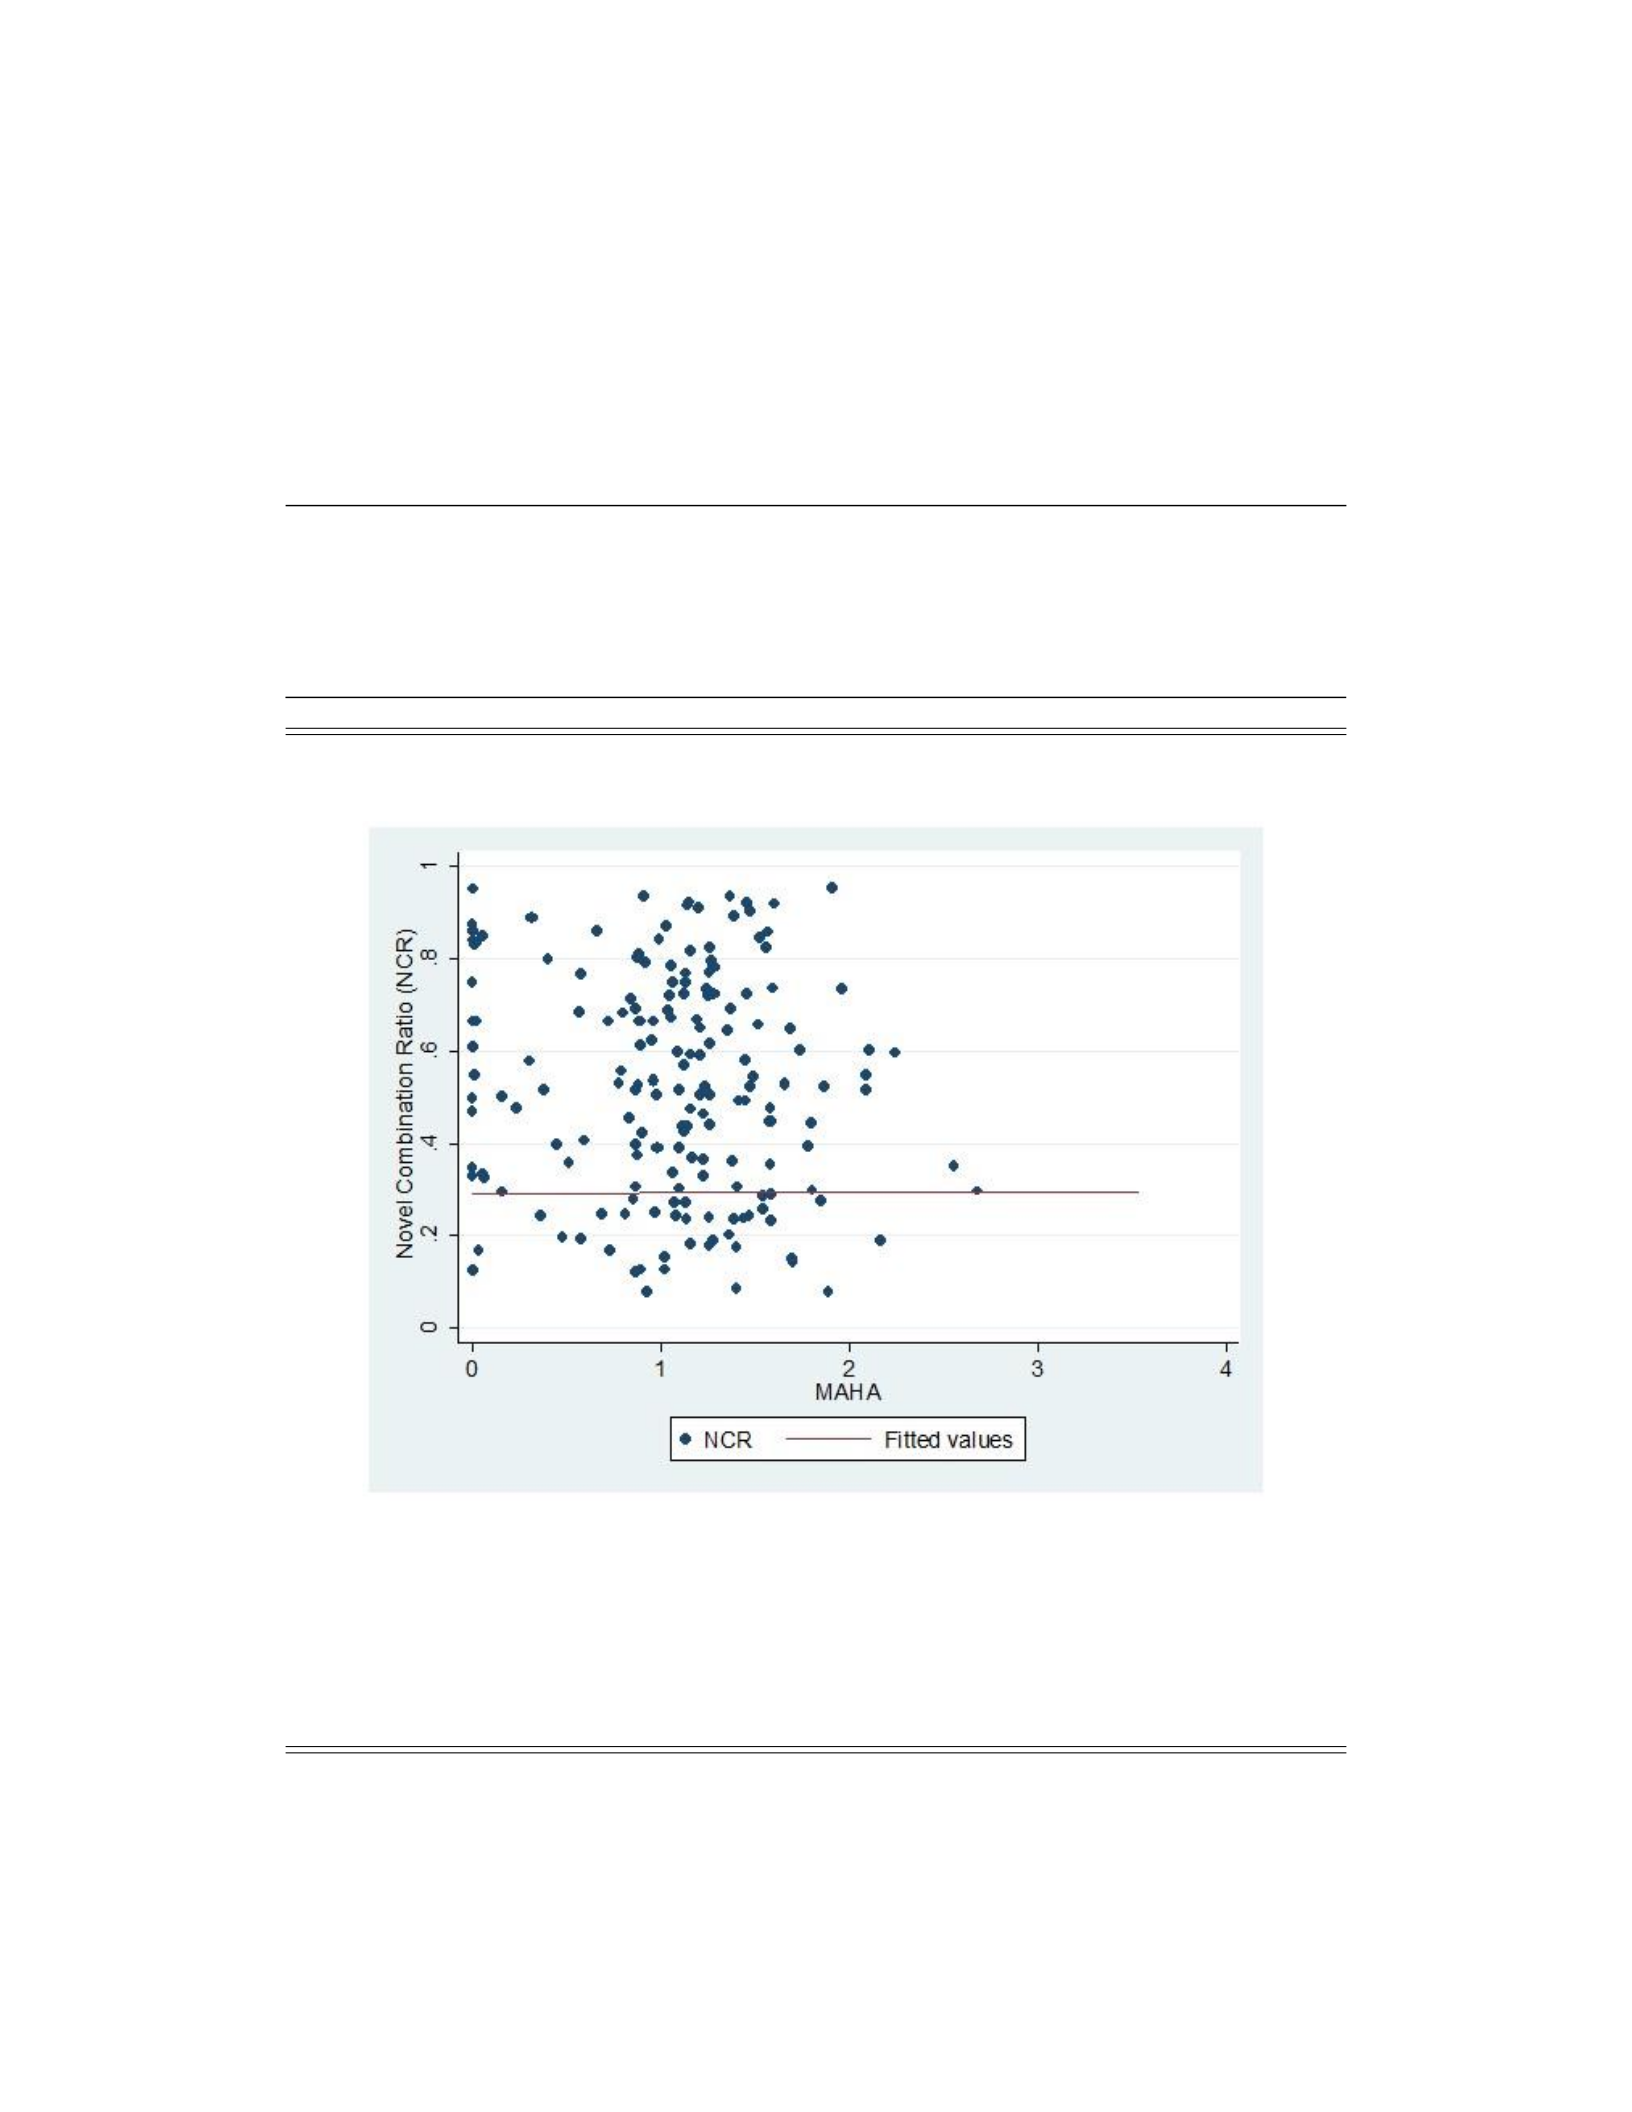
87
(0.013) (0.013) (0.013) (0.014)
×2.545∗∗ 2.792∗∗ 2.65∗∗
(0.849) (0.849) (0.973) (0.952)
× 0.459 0.545 0.462 0.53
(0.565) (0.516) (0.562) (0.539)
Note: We use Bayesian MCMC estimation in all columns. Robust standard errors are in parentheses.
† p < 0.1, * p < 0.05, ** p < 0.01, *** p < 0.001
Notes: This figure includes all 224 observations for the merging firm pairs. NCR is the ratio of novel combination of existing
technologies.
Figure 3.2: The Novel Combination Ratio based on Technology Similarity
Table 3.6: Estimation of Novel Combination Ratio
Year Dummy Included
YES
YES
YES
YES
Industry Dummy Included
YES
YES
YES
YES
Number of Actual Mergers
224
224
224
224
Number of Counterfactual Mergers
1,342
1,342
1,342
1,342
88
× -0.003∗ -0.003∗ -0.003∗ -0.002∗
(0.001) (0.001) (0.001) (0.001)
× -0.143† -0.133 -0.14† -0.132
(0.083) (0.084) (0.084) (0.084)
× 0.046 0.053 0.051 0.058
(0.044) (0.045) (0.045) (0.046)
Note: We use Bayesian MCMC estimation in all columns. Robust standard errors are in parentheses. The
outcome variable is the ratio of novel combination patent counts to the total number of patents after
mergers. κ represents a covariance of error terms in the selection and outcome equation.
† p < 0.1, * p < 0.05, ** p < 0.01, *** p < 0.001
Year Dummy Included
YES
YES
YES
YES
Industry Dummy Included
YES
YES
YES
YES
Number of Observations
224
224
224
224

