


d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d
d d d d d d d d d d d d d d d d 1
Week 10: Assignment 5 Analysis Evaluation
July 25, 2022

d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d
d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d 2
Table of Contents
Predictive Models ....................................................................................................................................................................................... 3
Predictive Model 1 - Logistical Regression model ........................................................................................................................ 3
Predictive Model 2 - Neural Networks model................................................................................................................................ 6
Predictive Model 3 - Support Vector Machine (SVM) model ..................................................................................................... 9
Predictive Model Review ................................................................................................................................................................. 14
References ......................................................................................................................................................................................... 16
d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d
d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d 3
Predictive Models
In the storm casualties project, three predictive models have been developed by using SAS Enterprise Miner. Predictive
models are useful statistical techniques that help in making predictions about future behavior. With the help of these
models, it has been possible to determine whether a particular storm would be deadly or not. Logistical regression is the
first predictive model that has been created. The second predictive model that has been developed is Neural Networks and
the final model is the Support Vector Machine (SVM) model (Narkunienė & Ulbinaitė, 2018). After the development of
these models, their performance has been analyzed to identify the most effective model that can help in the classification
of deadly storms in the U.S. The Support Vector Machine (SVM) model have been identified as the champion models
based on the detailed evaluation.
Predictive Model 1 - Logistical Regression model
The SAS Enterprise Miner was used for developing the Logistical Regression model. It has been chosen as an ideal model
since it has diverse techniques like forward selection, backward elimination, etc. Data partition node has been used on the
storm casualties project for segmenting the data into test set, validation set and training set. For the selection criteria,
‘validation misclassification’ and ‘logistic regression’ were used (Narkunienė & Ulbinaitė, 2018). False positives, true
positives, false negatives and negatives have been emphasized while using the model. In case identical outcome was
produced in the validation data it was chosen as training set. The cutoff threshold has been changed for enhancing the
classification performance.
Model
Data
True
Positives
False
Positives
True
Negatives
False
Negatives
Misclassification
Rate
d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d
d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d 4
Forward
Training
112
6
27932
119
0.004438
Validation
62
4
16759
76
0.004733
Backward
Training
162
14
27924
69
0.002947
Validation
77
30
16733
61
0.005384
Stepwise
Training
100
2
27936
131
0.004722
Validation
81
0.004911
The table presents the outcome of the model, indicating that each one of them is accurate. Validation sensitivity along with
backward regression have been chosen while using the predictive model.
The cutoff threshold of 0.01 has been considered and the backward regression outcome has been presented in the following
table. It can be inferred that the efficiency of the model has increased and for classifying storm-related deaths. In the test
set there are only 21 false negatives and in the validation data there are 28 false negatives indicating the high efficiency
of the model.
d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d
d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d 5
Data
False
Positives
True
Positives
False
Negatives
True
Negatives
Accuracy
(%)
Sensitivity (%)
Training
1017
221
10
26921
96.35
95.67
Validation
691
110
28
16072
95.74
79.71
Test
424
72
21
10750
96.05
77.42
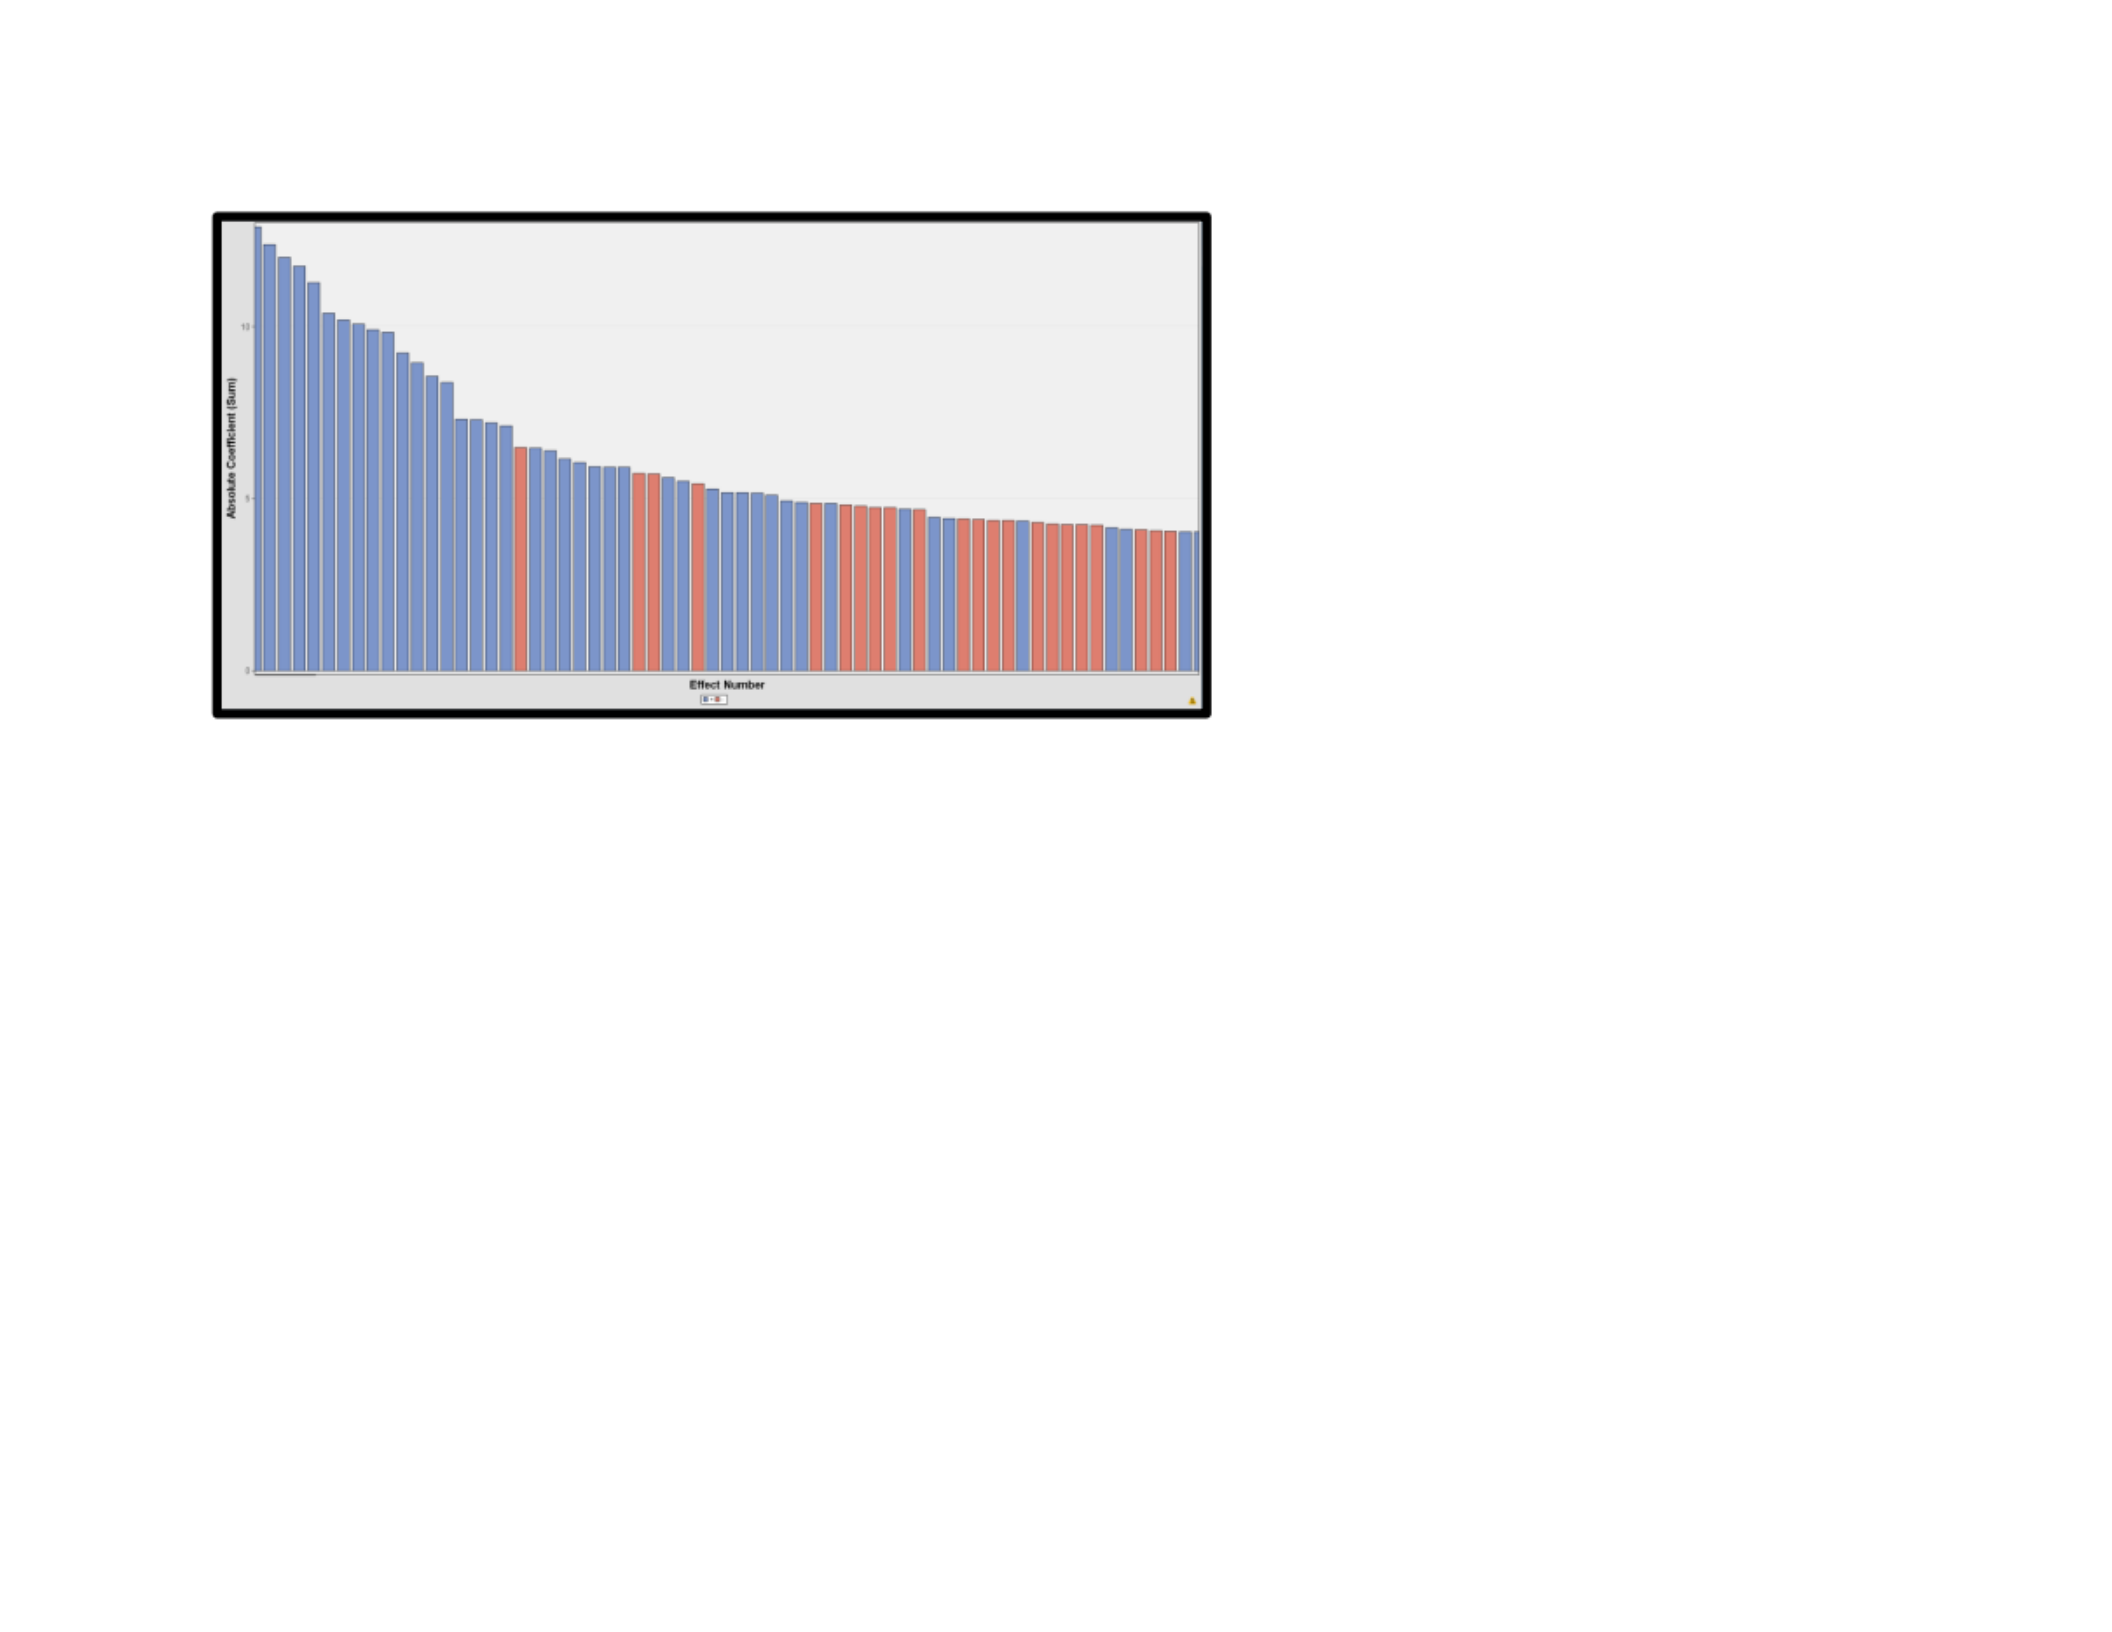
Regression coefficients are captured in the graphical representation showcasing the variables that helped to build the
regression model. They have captured the link between the target and the variables. Furthermore, they have helped to
understand whether the relationship is negative or positive. A chief coefficient that has been identified is damage to
property (Narkunienė & Ulbinaitė, 2018). A chief highlight of the model is the high level of accuracy and low sensitivity
rate in the initial stage. The backward logistic regression can be recommended for the storm casualties project.
d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d
d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d 6
Predictive Model 2 - Neural Networks model
The second predictive model that has been used in the storm casualties project is the Neural Networks model. It has been
chosen since it is capable of using the backpropagation process for making predictions. An advantage of the model is that
it is capable of handling noise data. Additionally, this model is able to identify patterns without the requirement of training.
The data partition node of the model has been utilized for segregating 50 % of data to the training set category, 30 % of
data to the validation set category and remaining 20 % of data to the test set category (Narkunienė & Ulbinaitė, 2018).
Several tools were used for analyzing the model’s outcome. The iteration plot that highlights the needed steps for training
the data has been investigated. The accurate and inaccurate prediction figures and the misclassification rate have been
highlighted in the table below:
d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d
d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d 7
Data
False
Positives
True
Positives
False
Negatives
True
Negatives
Misclassification
rate
Training
15
155
75
27923
0.003195115
Validation
11
73
66
16752
0.004555674
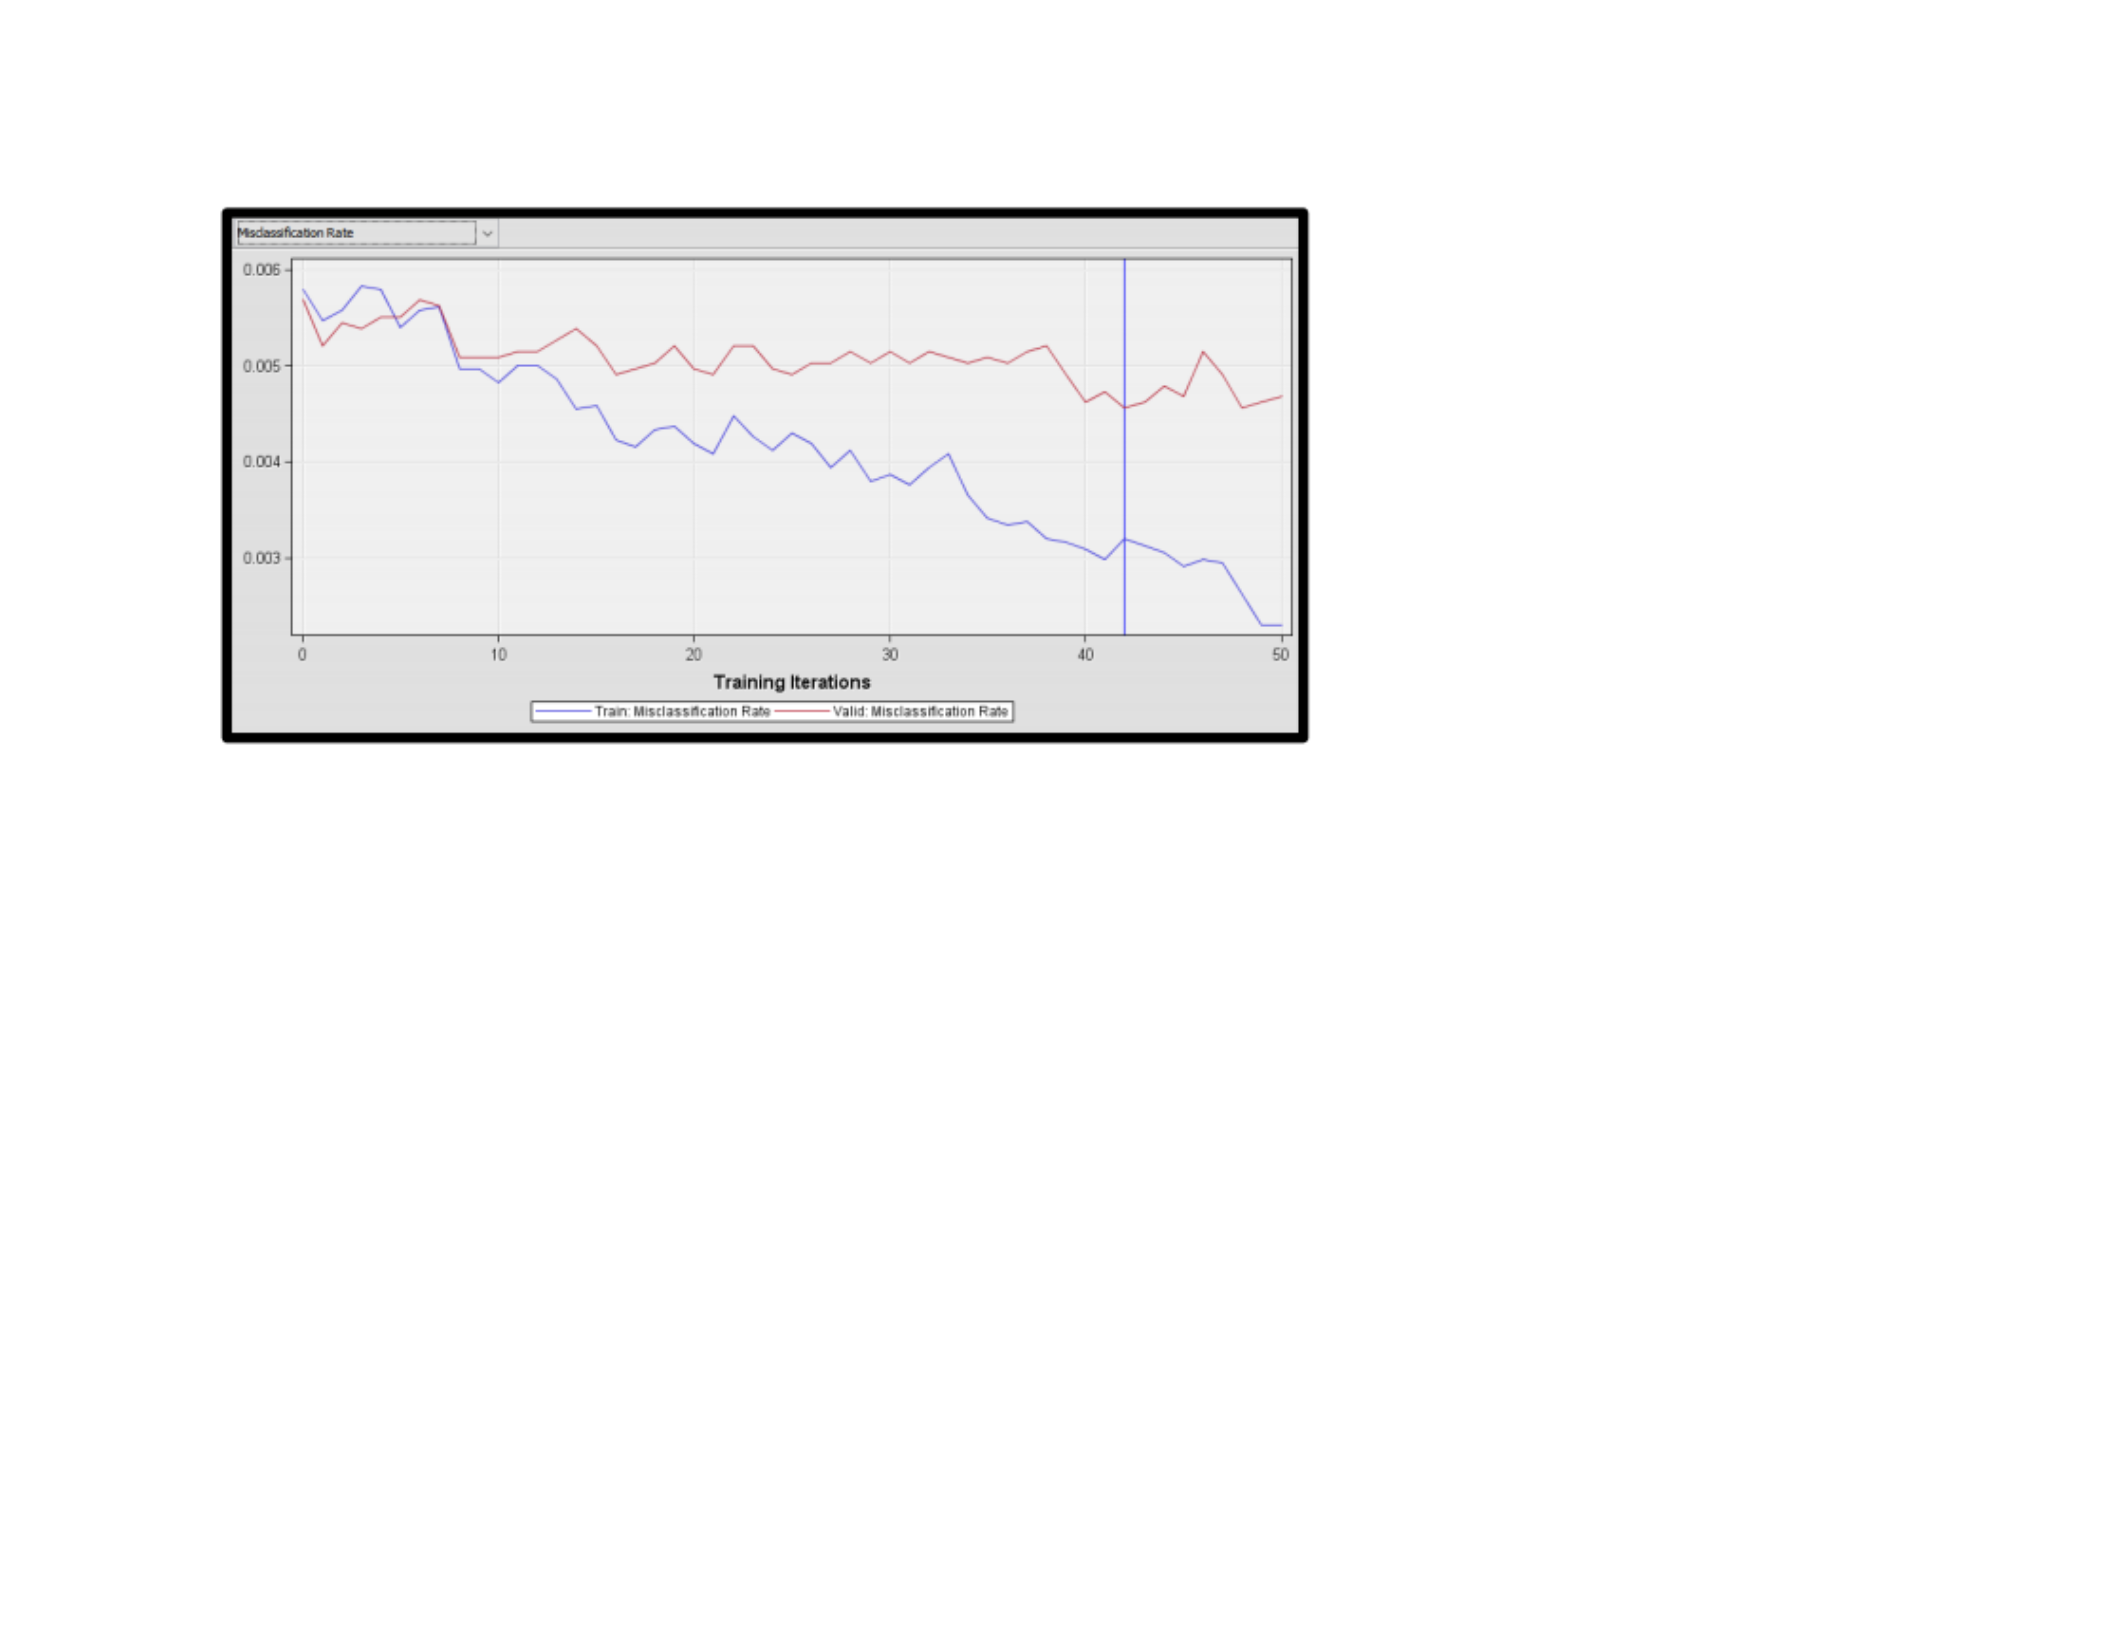
According to the graphical representation, the misclassification rate is higher in the validation dataset as compared to the
training dataset. It can further be inferred from the figure that the model requires a total of 42 training iterations Based on
the table and graph, it can be observed that the misclassification rate is low since it has recognized almost all ‘true
negatives.’ In the training set 75 false negatives have been misclassified and, in the validation set 66 false negatives have
been misclassified.
d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d
d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d 8
The sensitivity of the validation set is 52.5 % and training set is 67.4 %. These figures are lower than the minimum
sensitivity rate of 70 %. The cutoff threshold has been changed with the help of the cutoff node. The cutoff threshold of
0.01 has been considered. It can be observed that the predictive model’s efficiency increased when it comes to classifying
the ‘true positives.’ In the below table it can be observed that there are 17 false negatives which means that 17 storms
have been misclassified. The model’s accuracy is higher in comparison to the logical regression model. But its sensitivity
rate is lower. As sensitivity is a key criterion, the model fails to meet the requirements relating to the sensitivity
dimension.
d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d
d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d 9
Data
True
Positives
False
Positives
False
Negatives
True
Negatives
Accuracy
(%)
Sensitivity (%)
Training
213
914
17
27024
96.69
92.61
Validation
103
522
36
16241
96.70
74.10
Test
70
345
23
10829
96.73
75.27
Predictive Model 3 - Support Vector Machine (SVM) model
The final predictive model that has been used in the storm casualties project is the Support Vector Machine (SVM). This
model basically involves the segregation of classes with the help of a hyperplane. A hyperplane increases the distance that
exists between the closest data point in every category, and it is known as ‘margin.’ If the linear method cannot be applied
for the purpose of separating the dataset, the kernel function can be adopted. It can aid in simplifying the separation process
by transforming the data. Some of the key kernel functions of the SVM model include linear, polynomial, etc. A chief
advantage of the predictive model is that its efficiency does not decline while working on datasets with a large volume of
inputs. Another key advantage of the model is that it is capable of functioning in a compatible manner even if there exists
some degree of disassociation between different classes.
The SAS Enterprise Miner’s HP SVM node was utilized for creating SVMs. While using the predictive model, the data
partition node was used. With the help of the node, the dataset was categorized into training set (50 %), validation set (30
%) and test set (20 %). In the initial stage, a total of four HP SVM nodes were used. The interior point optimization
d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d
d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d 10
method was used in the linear model and the kernel type was set to linear. In the other models, active set was chosen as
the optimization method and the kernel that were adopted were sigmoid, polynomial, and radical basis function.
In the case of the polynomial model, ‘2’ was set as the degree and in the case of the radical basis function, ‘1’was set as
the parameter. For the sigmoid model, 1 and -1 had been set as the parameters. While the SVM Model was being executed,
it was observed that only the linear model functioned in an accurate and effective manner. Based on this observation,
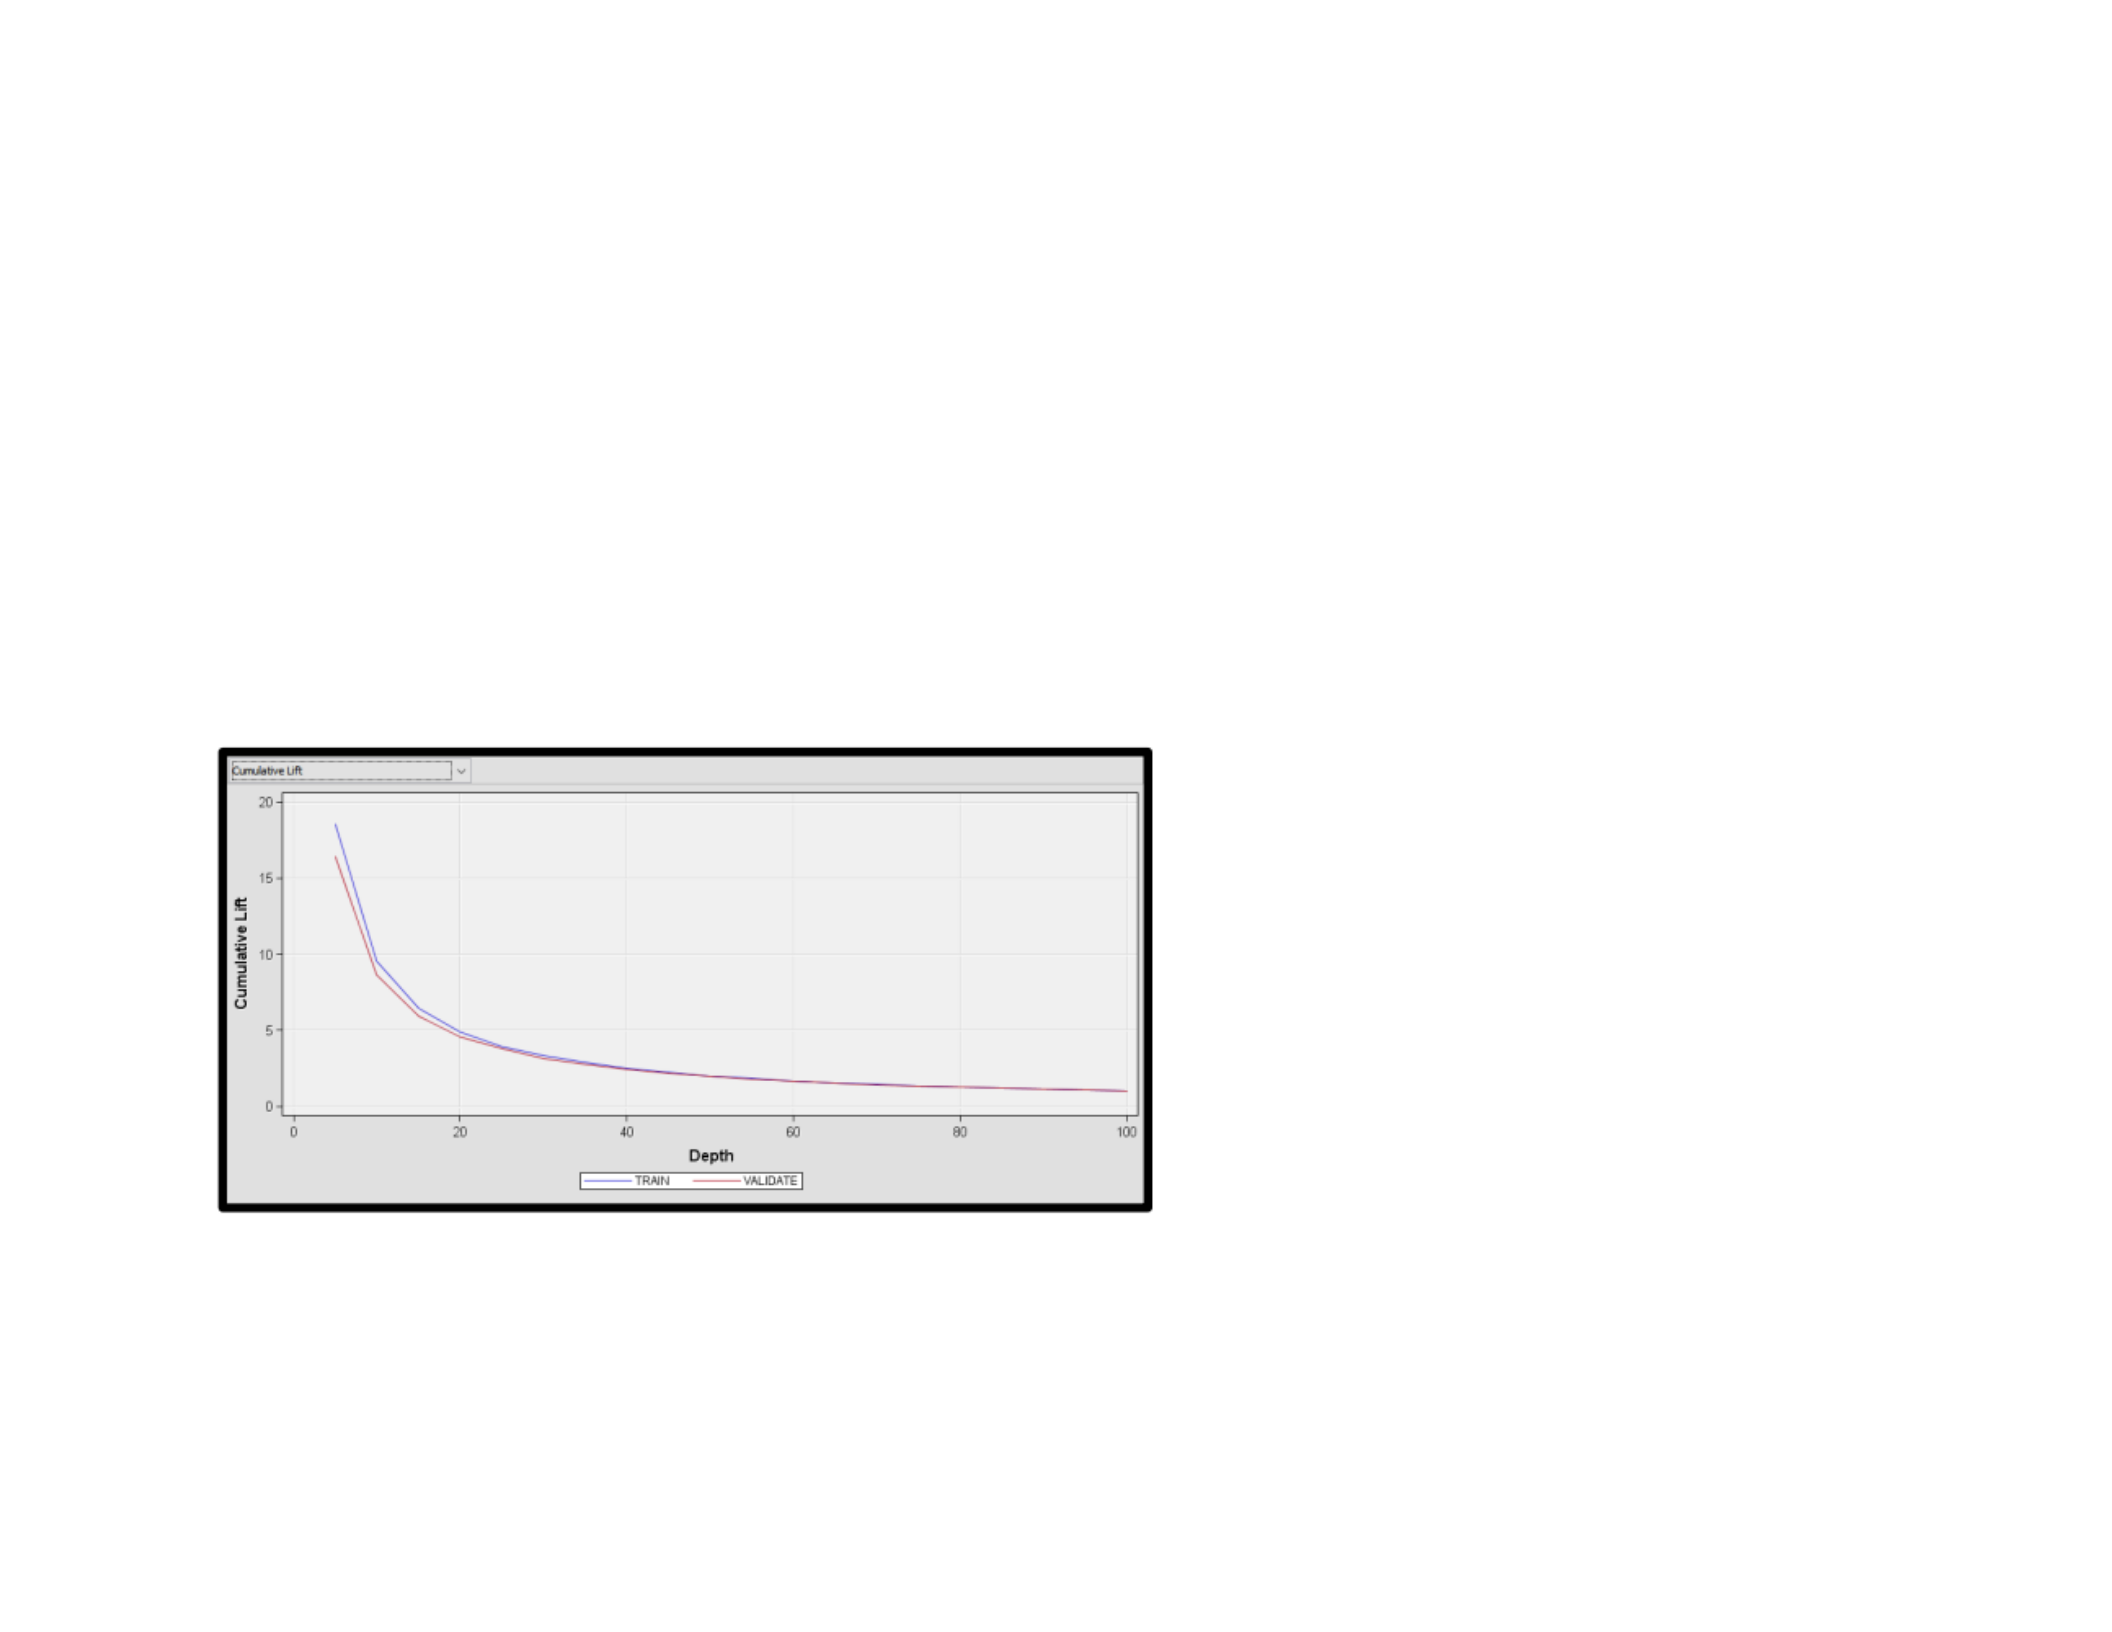
emphasis was mainly laid on the linear kernel. The graphical representation that has been presented below gives an insight
into the cumulative lift curve. This curve has been derived by using the validation dataset and the training dataset. A model
that is effective is likely to have close validation and training curves. In the case of the project, there is close proximity
between these curves which goes on to indicate that there is no issue relating to overfitting.
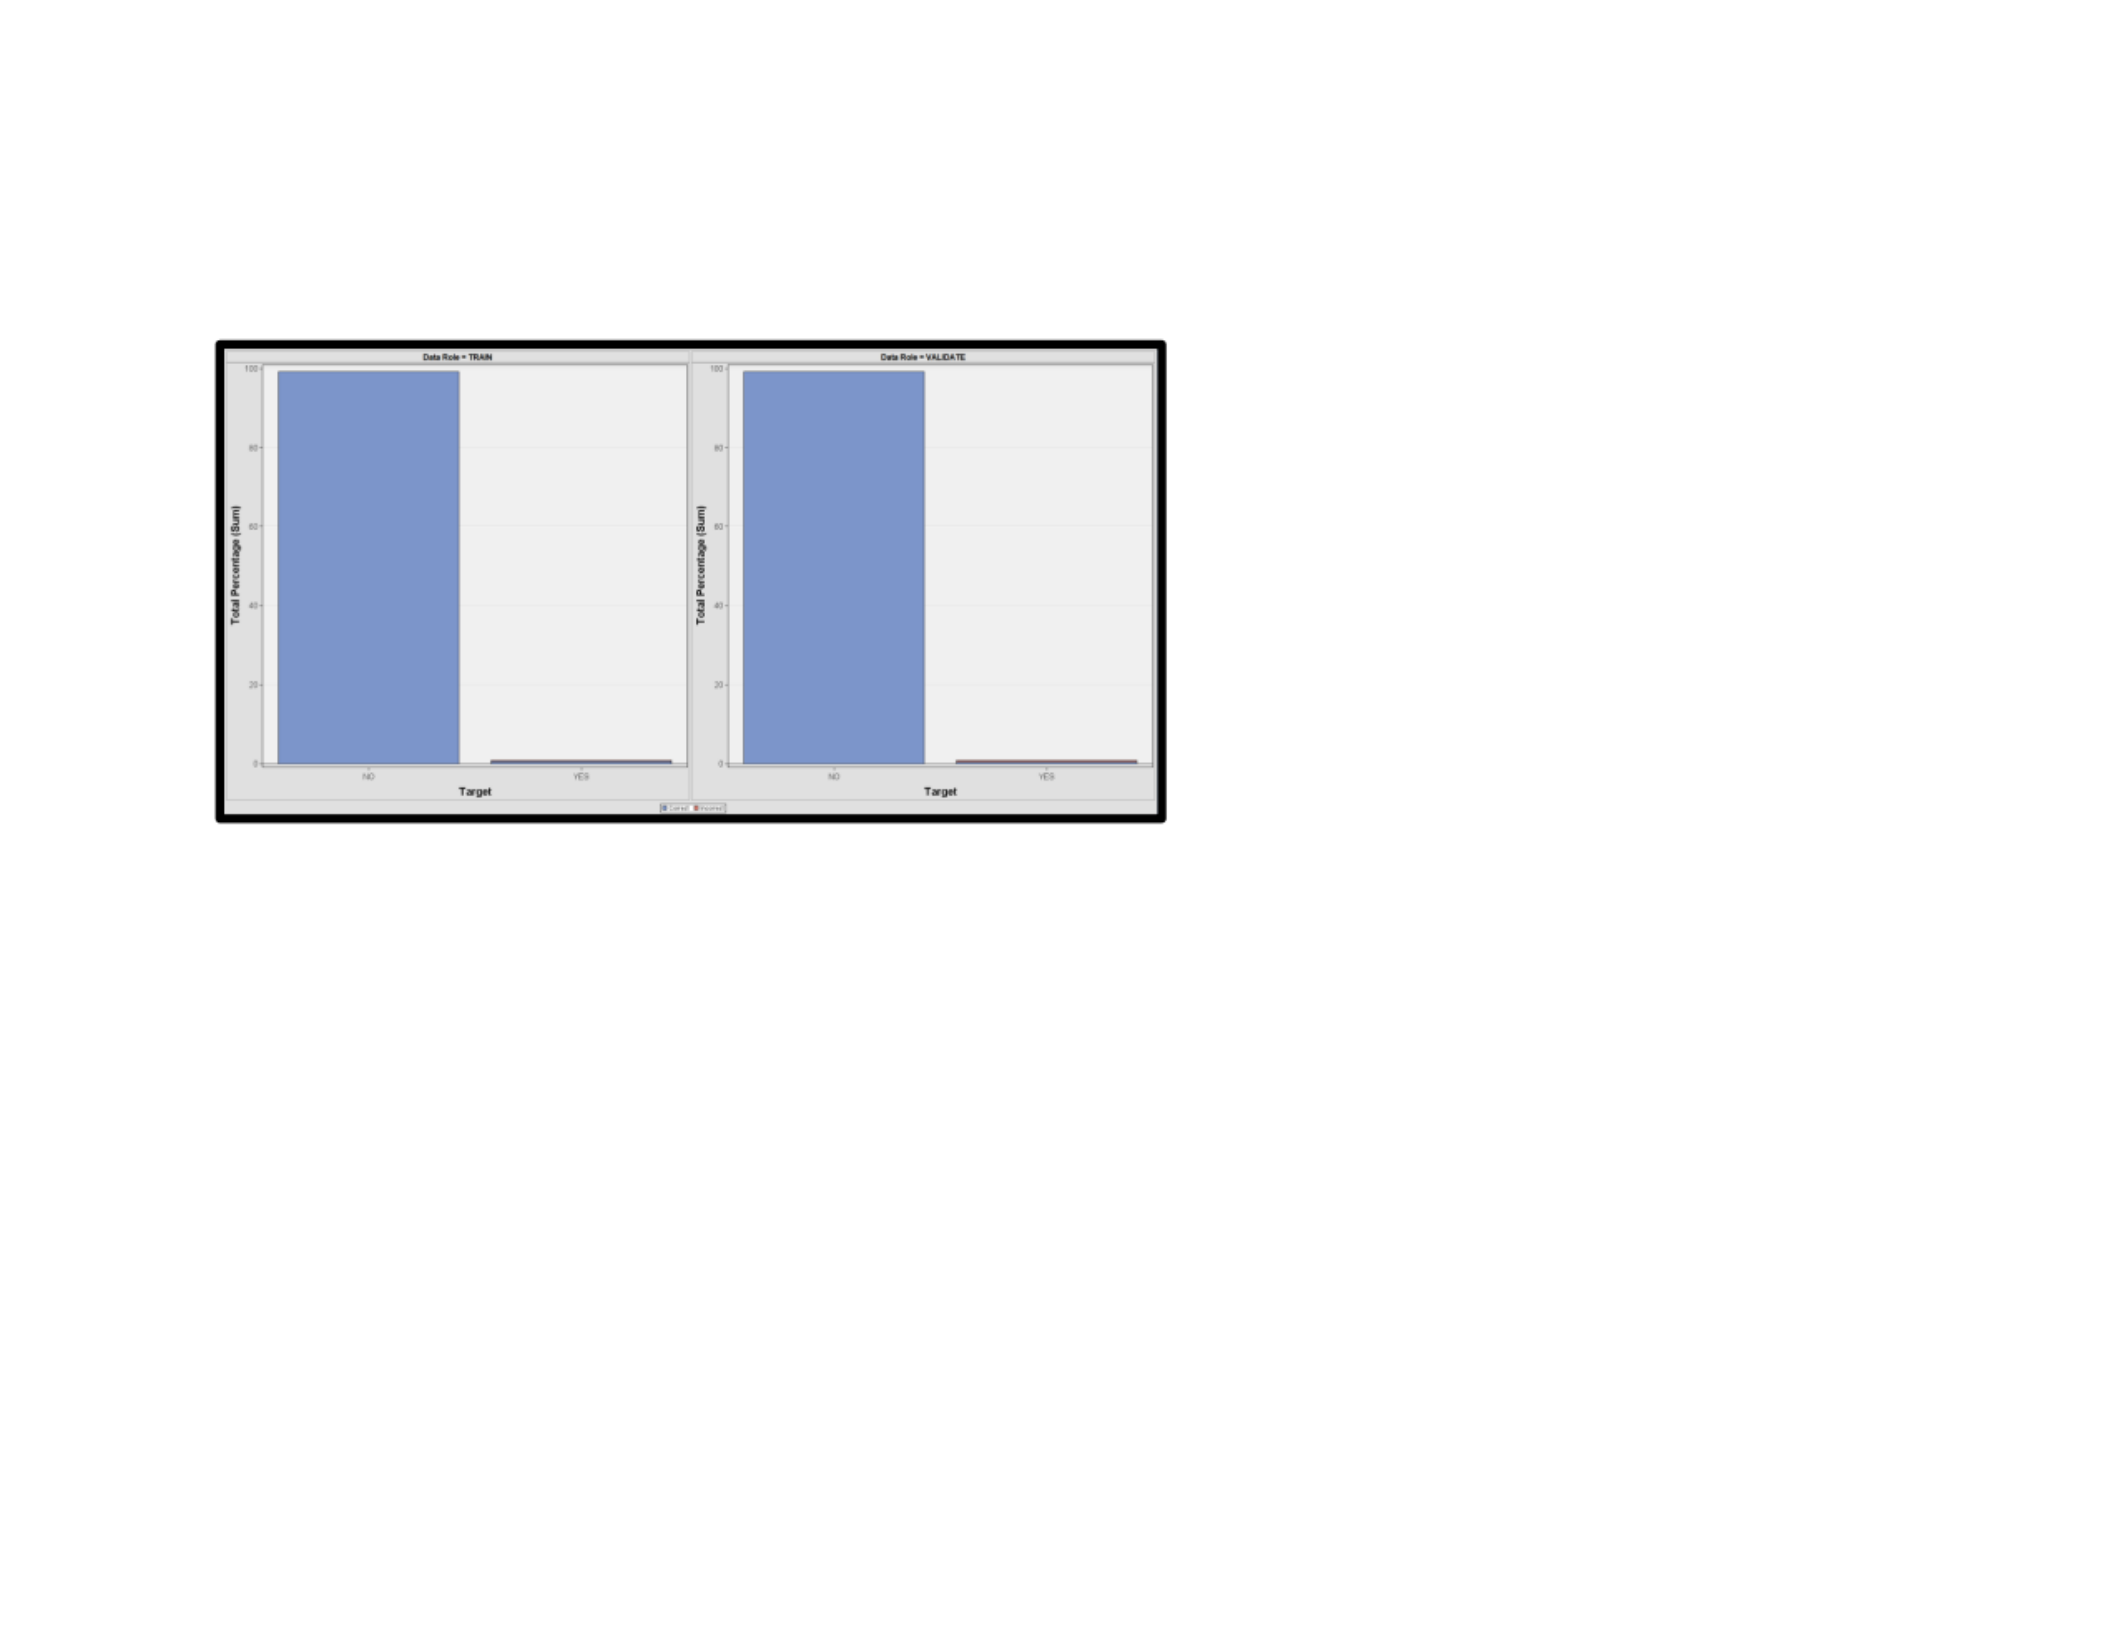
For evaluating the model, another vital instrument that has been used is the classification chart. It includes a bar chart that
represents both accurate along with inaccurate predictions in the context of the validation and training datasets. The
d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d
d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d 11
classification chart has been presented below and it has helped in offering a precise visualization of the ability of the SVM
predictive model to classify deadly and life-threatening storms.
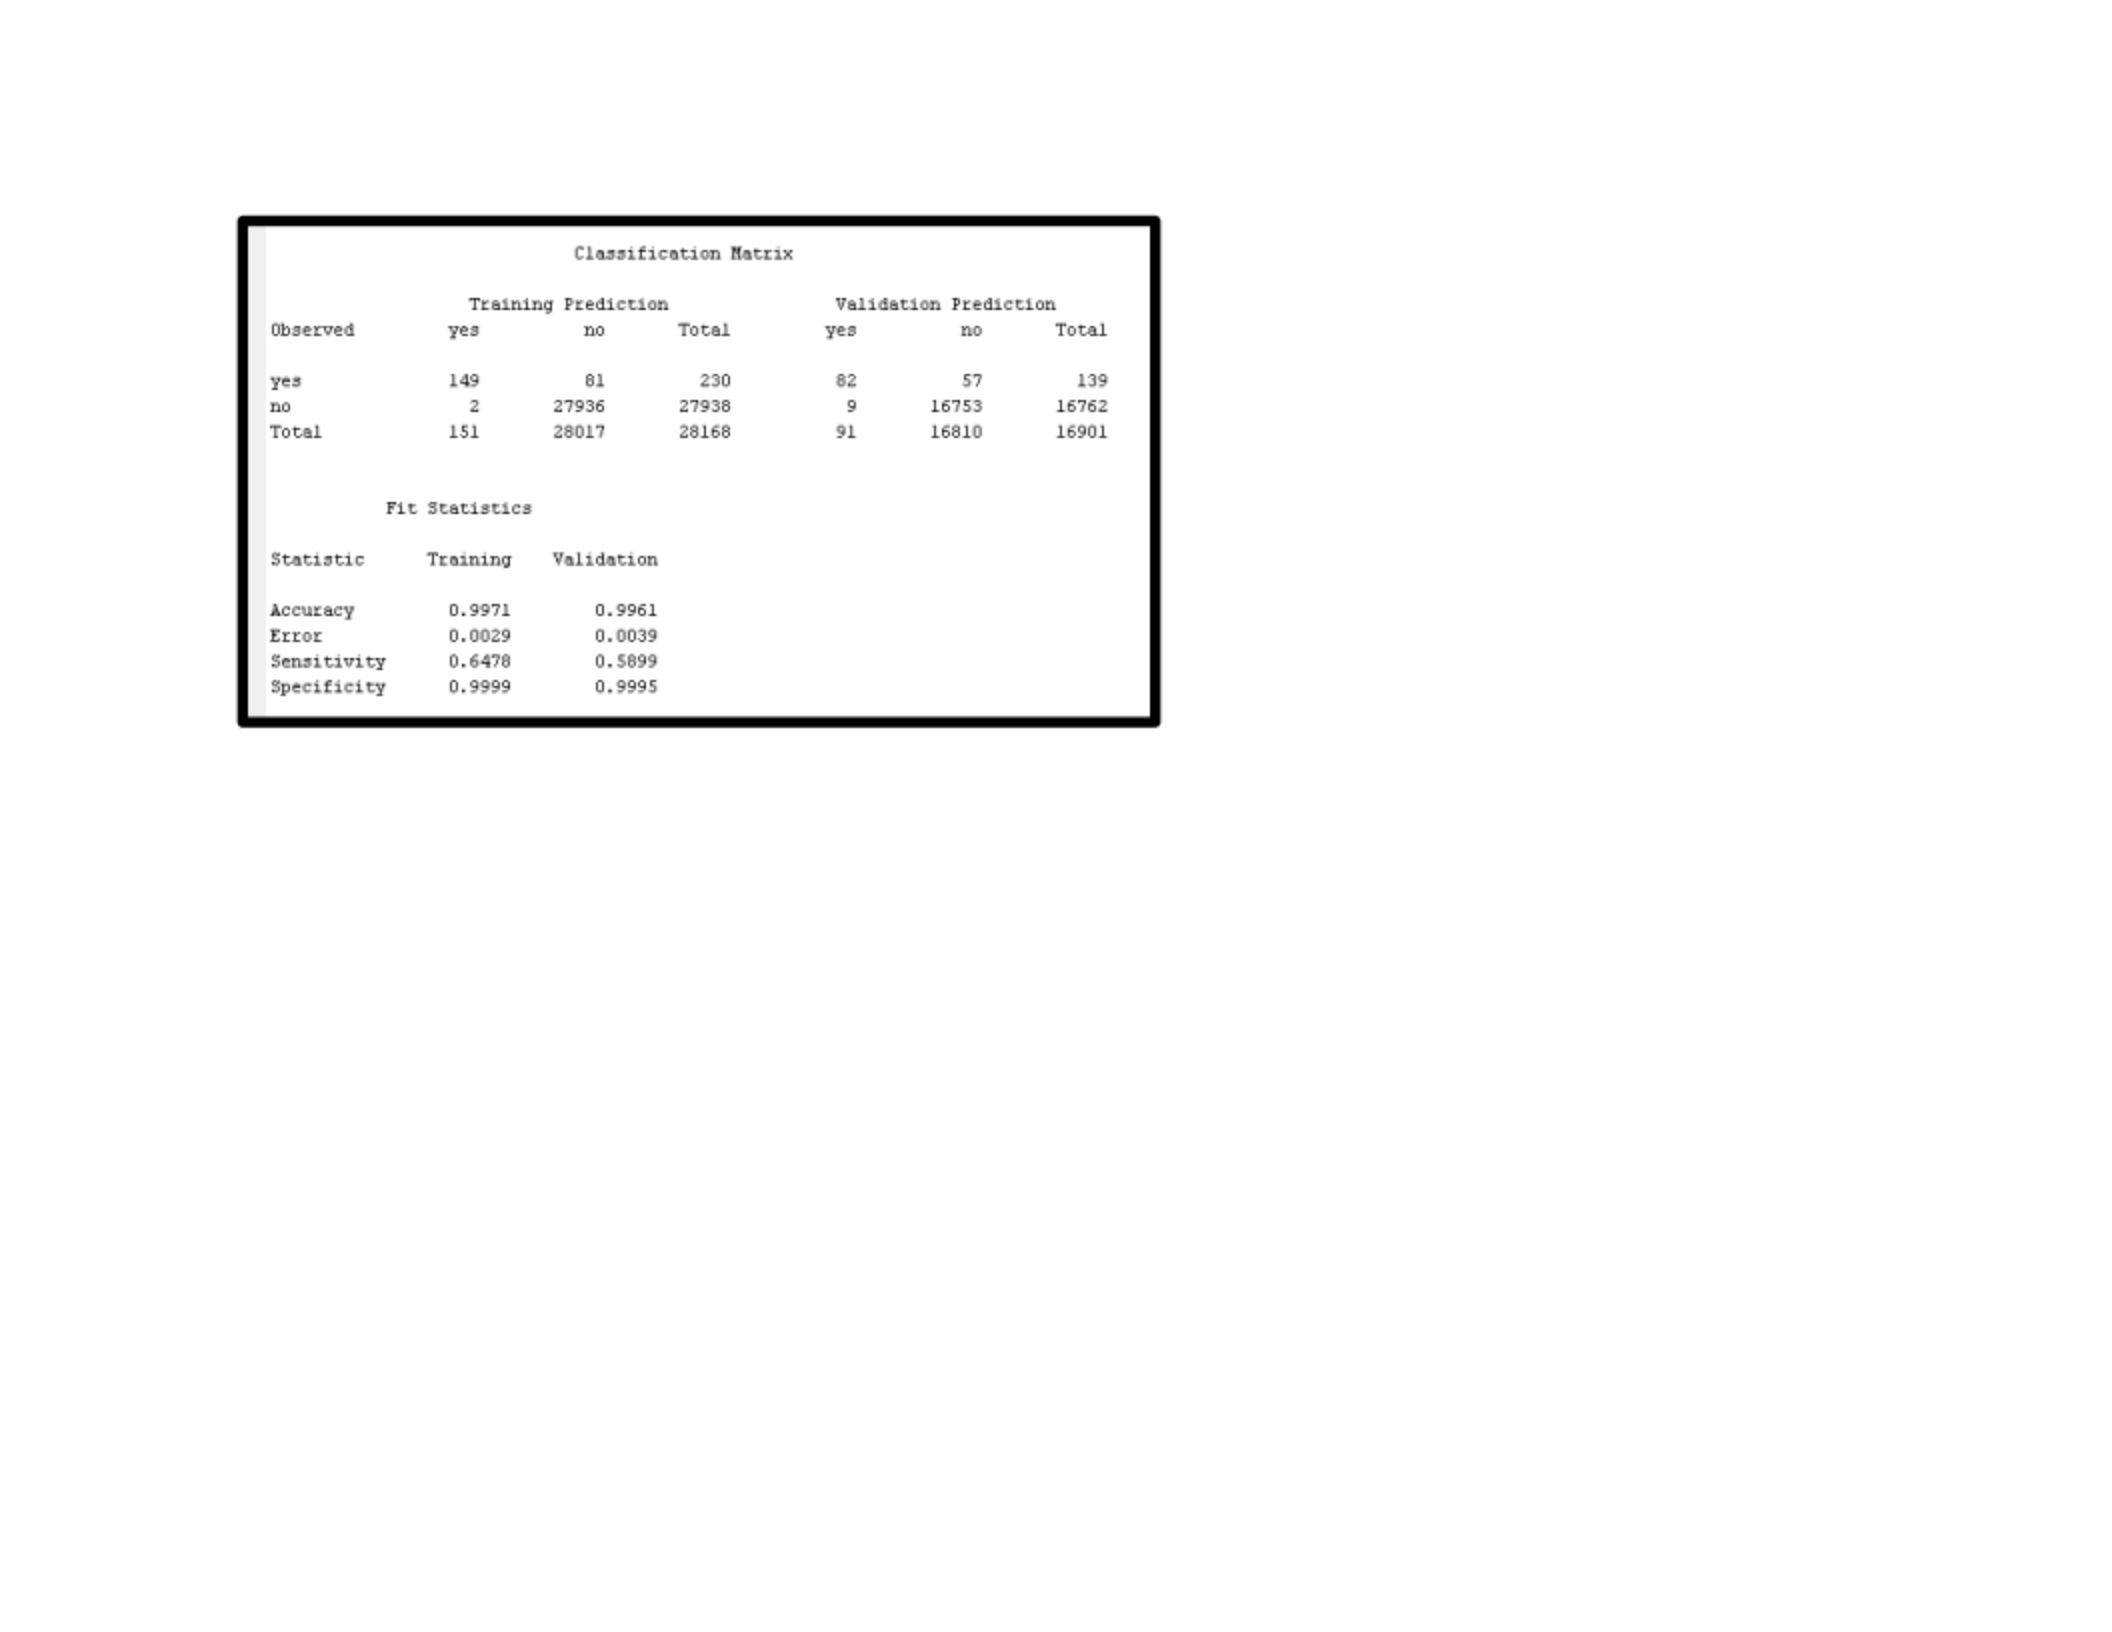
The classification matrix has been further evaluated in order to get a micro-level insight into the predictions as compared
to the actual figures. A perfect model is one in which there is a close match between the predicted classes as well as the
actual record figures in every class. This figure has been integrated into the storm casualties project since it not only sheds
light on the model’s accuracy, but it also helps to get a better insight into its degree of sensitivity.
d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d
d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d 12
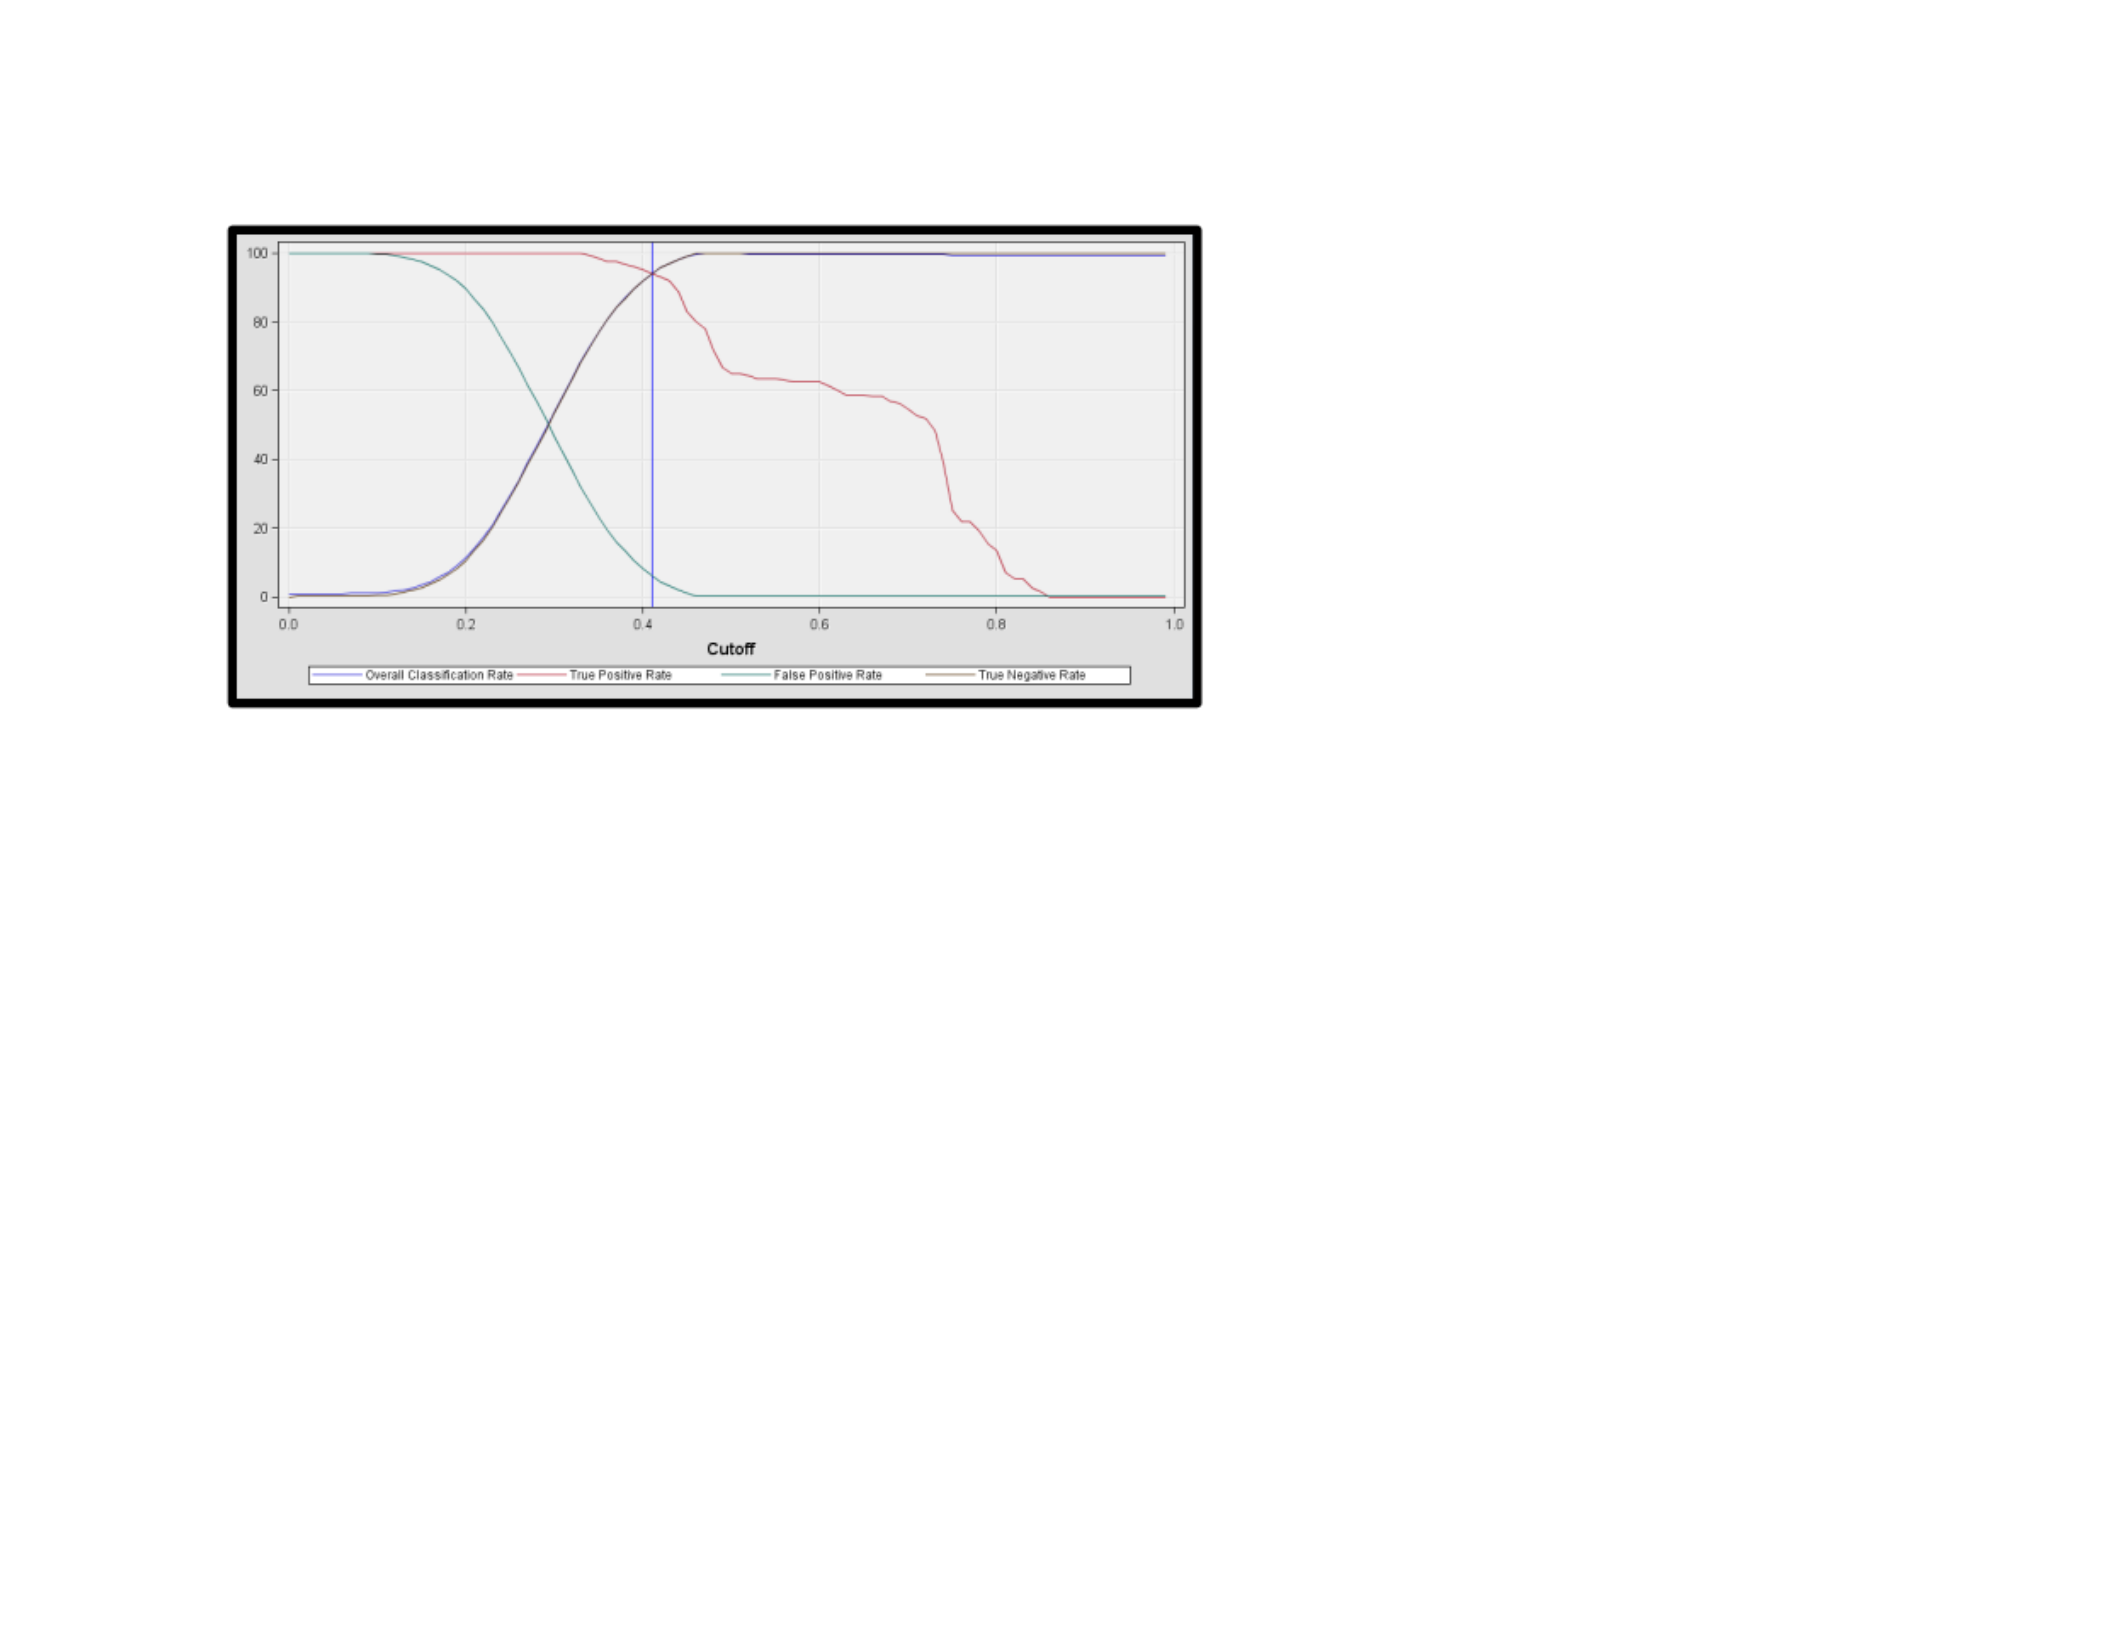
The figure that has been presented gives a glimpse into the classification rate relating to the linear SVM predictive model.
The cutoff threshold of 0.41 has been used. In the initial stage of working on the model, the cutoff threshold of 0.1 was
adopted. However, it was changed because it generated inaccurate results. In the graphical diagram that has been captured,
0.41 seems to be the ideal cutoff in the predictive model. This is because at this specific cutoff threshold, the true positives
rate that is achieved is 93.91 % and the classification rate relating to the training dataset is 93.90 %.
d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d
d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d 13
After altering the predictive model’s cutoff threshold, the evaluation of the classification performance was done. It has been
observed that the overall strength of the model has increased substantially after taking 0.41 as the new cutoff threshold.
The model is able to make better and more accurate classifications relating to storm casualties. For example, while taking
into account the training dataset, there are only 14 ‘false negatives’ values. While focusing on the validation dataset and
the test datasets, the total number of ‘false negatives’ are 22 and 18 respectively, indicating the improved performance of
the model. After the cutoff threshold alteration, the validation sensitivity is 84.17 % which is much higher as compared to
the previous validation sensitivity of 59 %.
d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d
d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d 14
Data
False
Positives
True
Positives
False
Negatives
True
Negatives
Accuracy
(%)
Sensitivity (%)
Training
1705
216
14
26233
93.90
93.91
Validation
1048
117
22
15714
93.67
84.17
Test
678
75
18
10497
93.83
80.65
There arise several implications on the scope of the storm casualty’s project. One of the most important implications is that
the linear kernel was able to execute accurate results without showcasing any errors. A major weakness that has been
identified while using the SVM predictive model revolves around the complexity while handling humongous datasets. For
example, initially its sensitivity rate was low at 59 %. However, after changing the cutoff threshold, the sensitivity rate of
the validation dataset increased to 84.2 %. Out of the three predictive models that have been created in the storm casualties
project, the sensitivity rate of the SVM model is highest as compared to the logical regression model and the neural
network model (Narkunienė & Ulbinaitė, 2018). Thus, it seems to be the ideal model that can be used for making
predictions about the severity and deadly nature of storms.
Predictive Model Review
After creating all the three predictive models in the context of the storm casualties project, the most effective model has
been selected. It is necessary to have a robust model that can help to accurately make predictions about the deadly nature
d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d
d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d 15
of storms. A comprehensive comparison of the created models has been presented in the table below which has helped to
make a comparison between them.
Model
Cutoff
Threshold
Data
Accuracy
(%)
Sensitivity
(%)
Logistic
Regression
0.01
Training
96.35
95.67
Validation
95.75
79.71
Test
96.05
77.42
Neural
Network
0.01
Training
96.69
92.61
Validation
96.70
74.1
Test
96.73
75.27
SVM
(Linear
Kernel)
0.01
Training
93.9
93.91
Validation
93.67
84.17
Test
93.82
80.65
From the table above it can be seen that the logical regression model is the weakest predictive model that has been used
in the project. On the other hand, the SVM model (Linear Kernel) model is the most effective model that can help in

d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d
d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d d 16
making predictions from the storm datasets. One of the key elements that has been identified while working on the SVM
model is that after changing the cutoff threshold to 0.41, its efficiency and effectiveness has increased to a significant
extent. By using the model, it will be possible to critically examine datasets relating to storm casualties and infer relevant
information from them.
References
Narkunienė, J., & Ulbinaitė, A. (2018). Comparative analysis of company performance evaluation methods. Entrepreneurship
and sustainability issues, 6(1), 125-138.

