


The Quadratic Forms of Random Vectors
Introduction
These notes discuss the decay of probability 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡} as 𝑡 approaches infinity, where
𝑋 is a random vector in ℝ𝑑 and 𝐶 is a real 𝑑×𝑑 matrix.
Key points:
• The decay depends on the distribution of 𝑋 and matrix 𝐶
• Two types of distributions are considered: symmetric Weibull-like and Student-like
• Weibull-like tails are handled using Theorem 7.1
• Student-like tails are handled using a change of variable technique and Theorem 5.1
Light Tail Distribution Example
Setup
Consider a random vector 𝑋=(𝑋1,…,𝑋𝑑) in ℝ𝑑 with density 𝑓=𝑒−𝐼, where 𝐼 is a convex,
𝛼-positively homogeneous function on ℝ𝑑.
Important:
• 𝐴𝑡={𝑥∈ℝ𝑑:⟨𝐶𝑥,𝑥⟩>𝑡}=√𝑡𝐴1
• 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}=∫𝑒−𝐼(𝑥)
𝐴𝑡𝑑𝑥
Specific Case
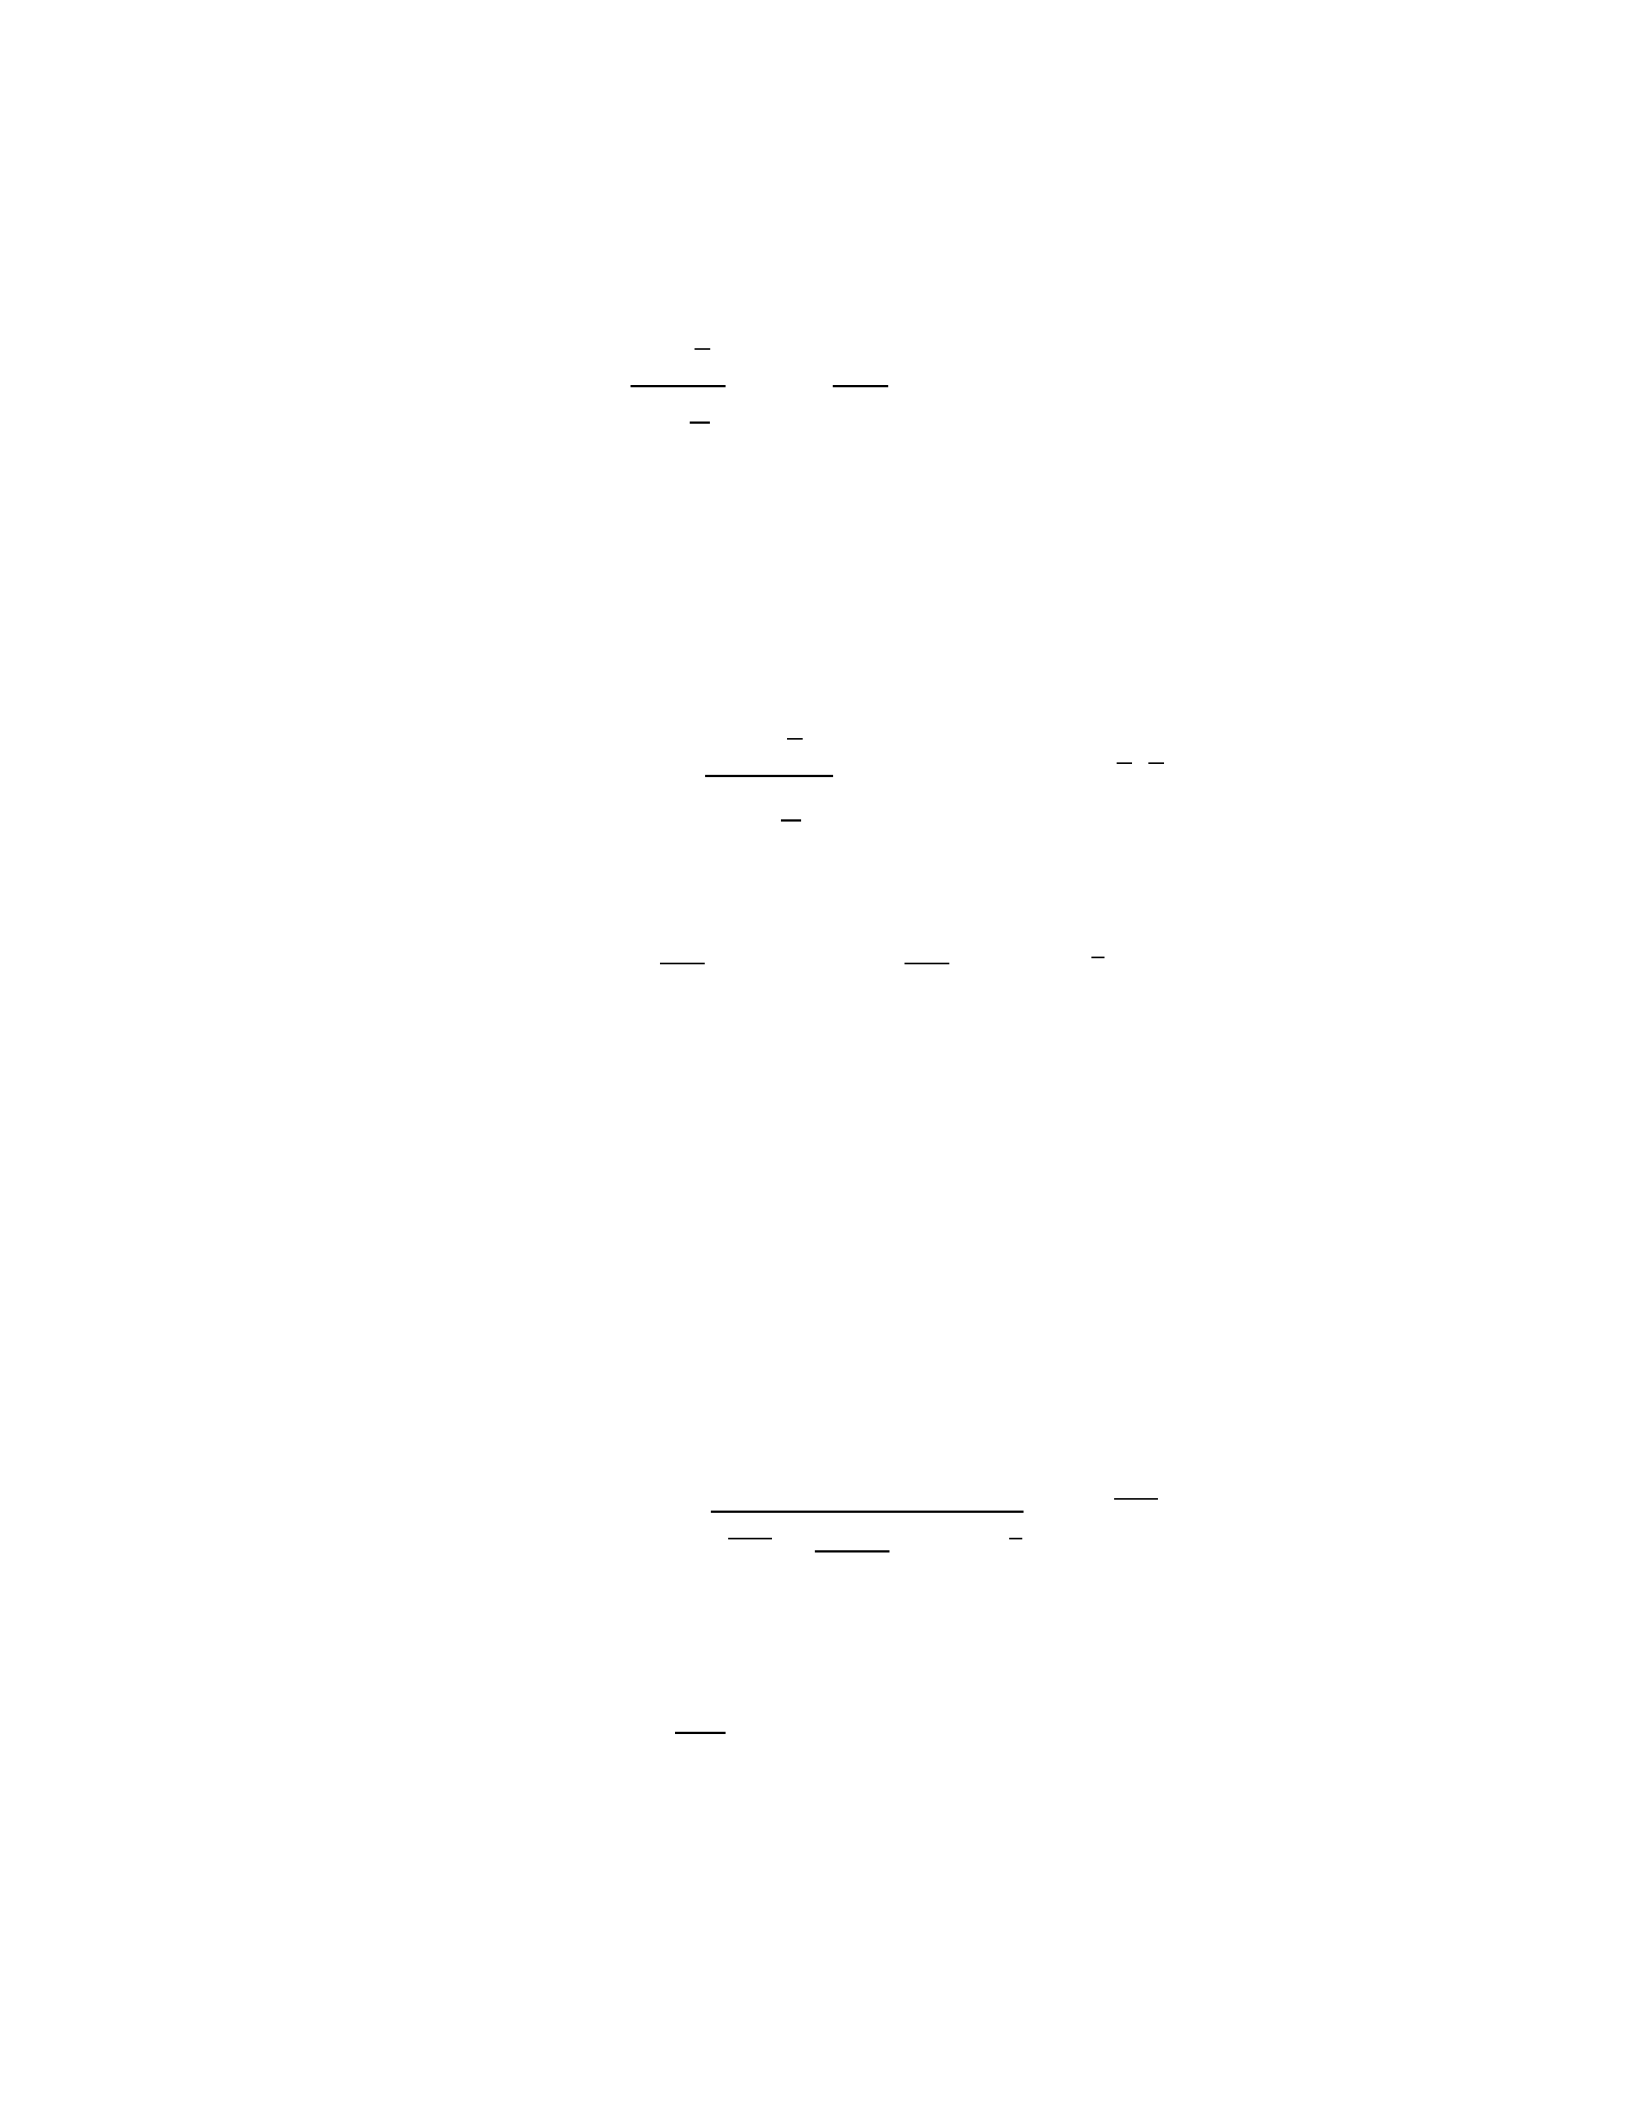
Assume the components 𝑋𝑖 of 𝑋 are i.i.d. with density:
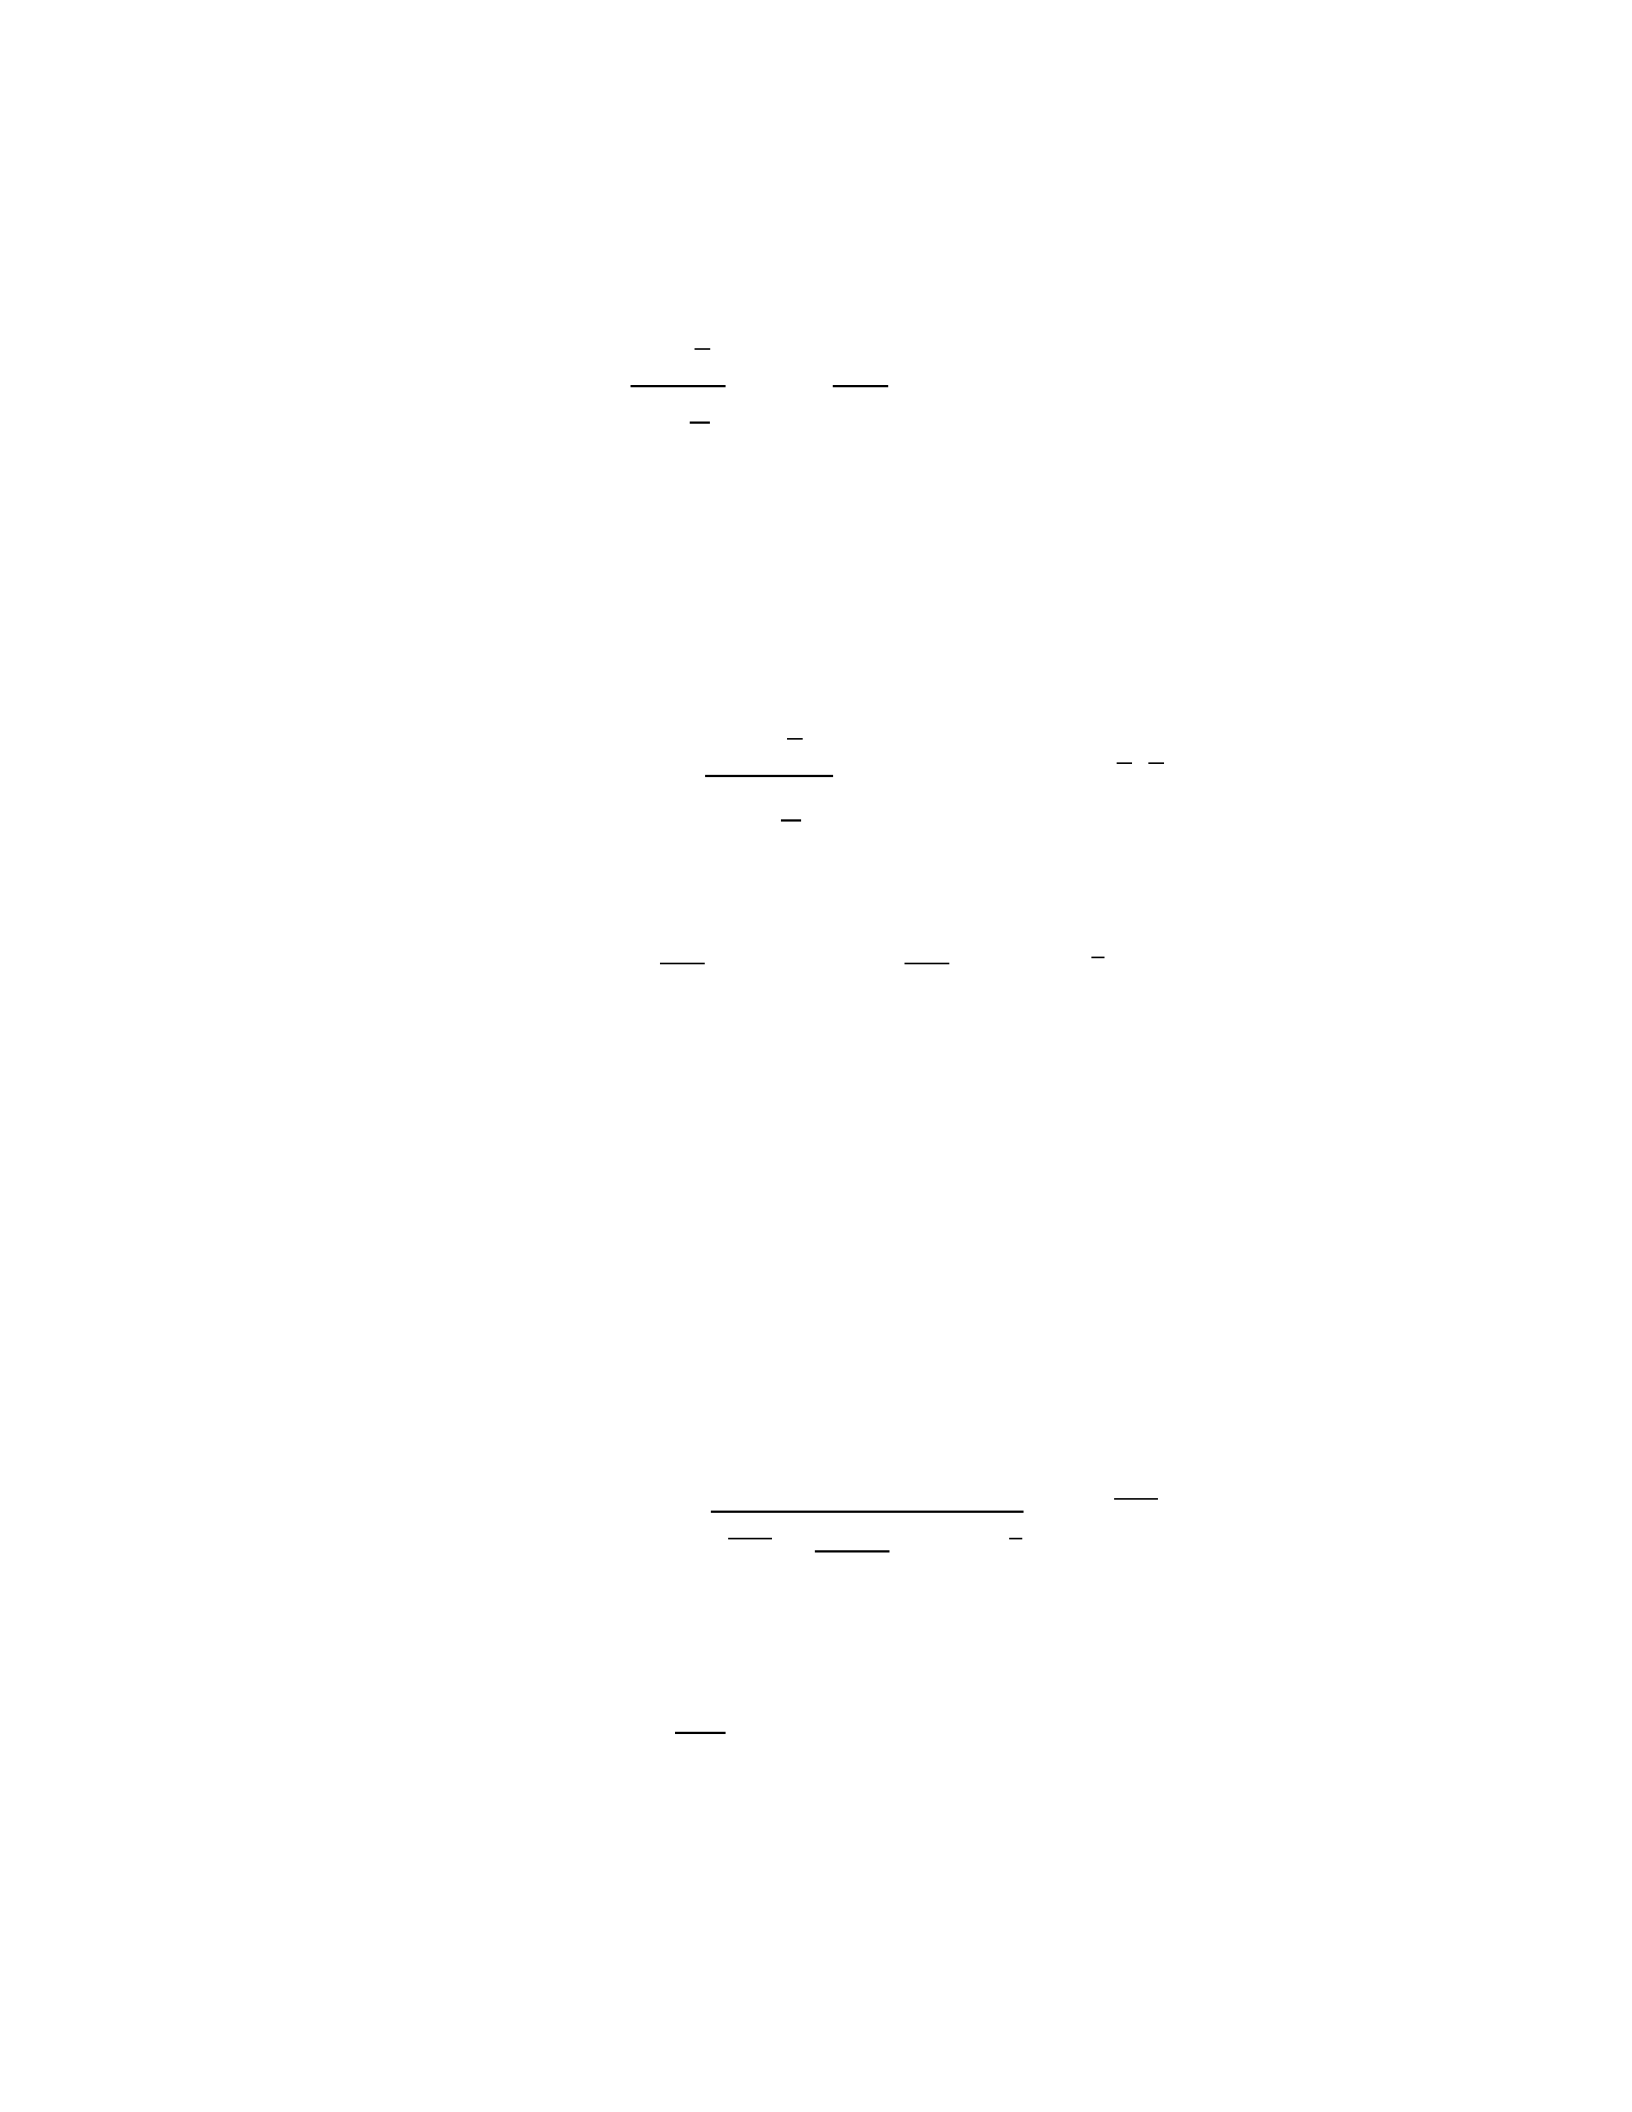
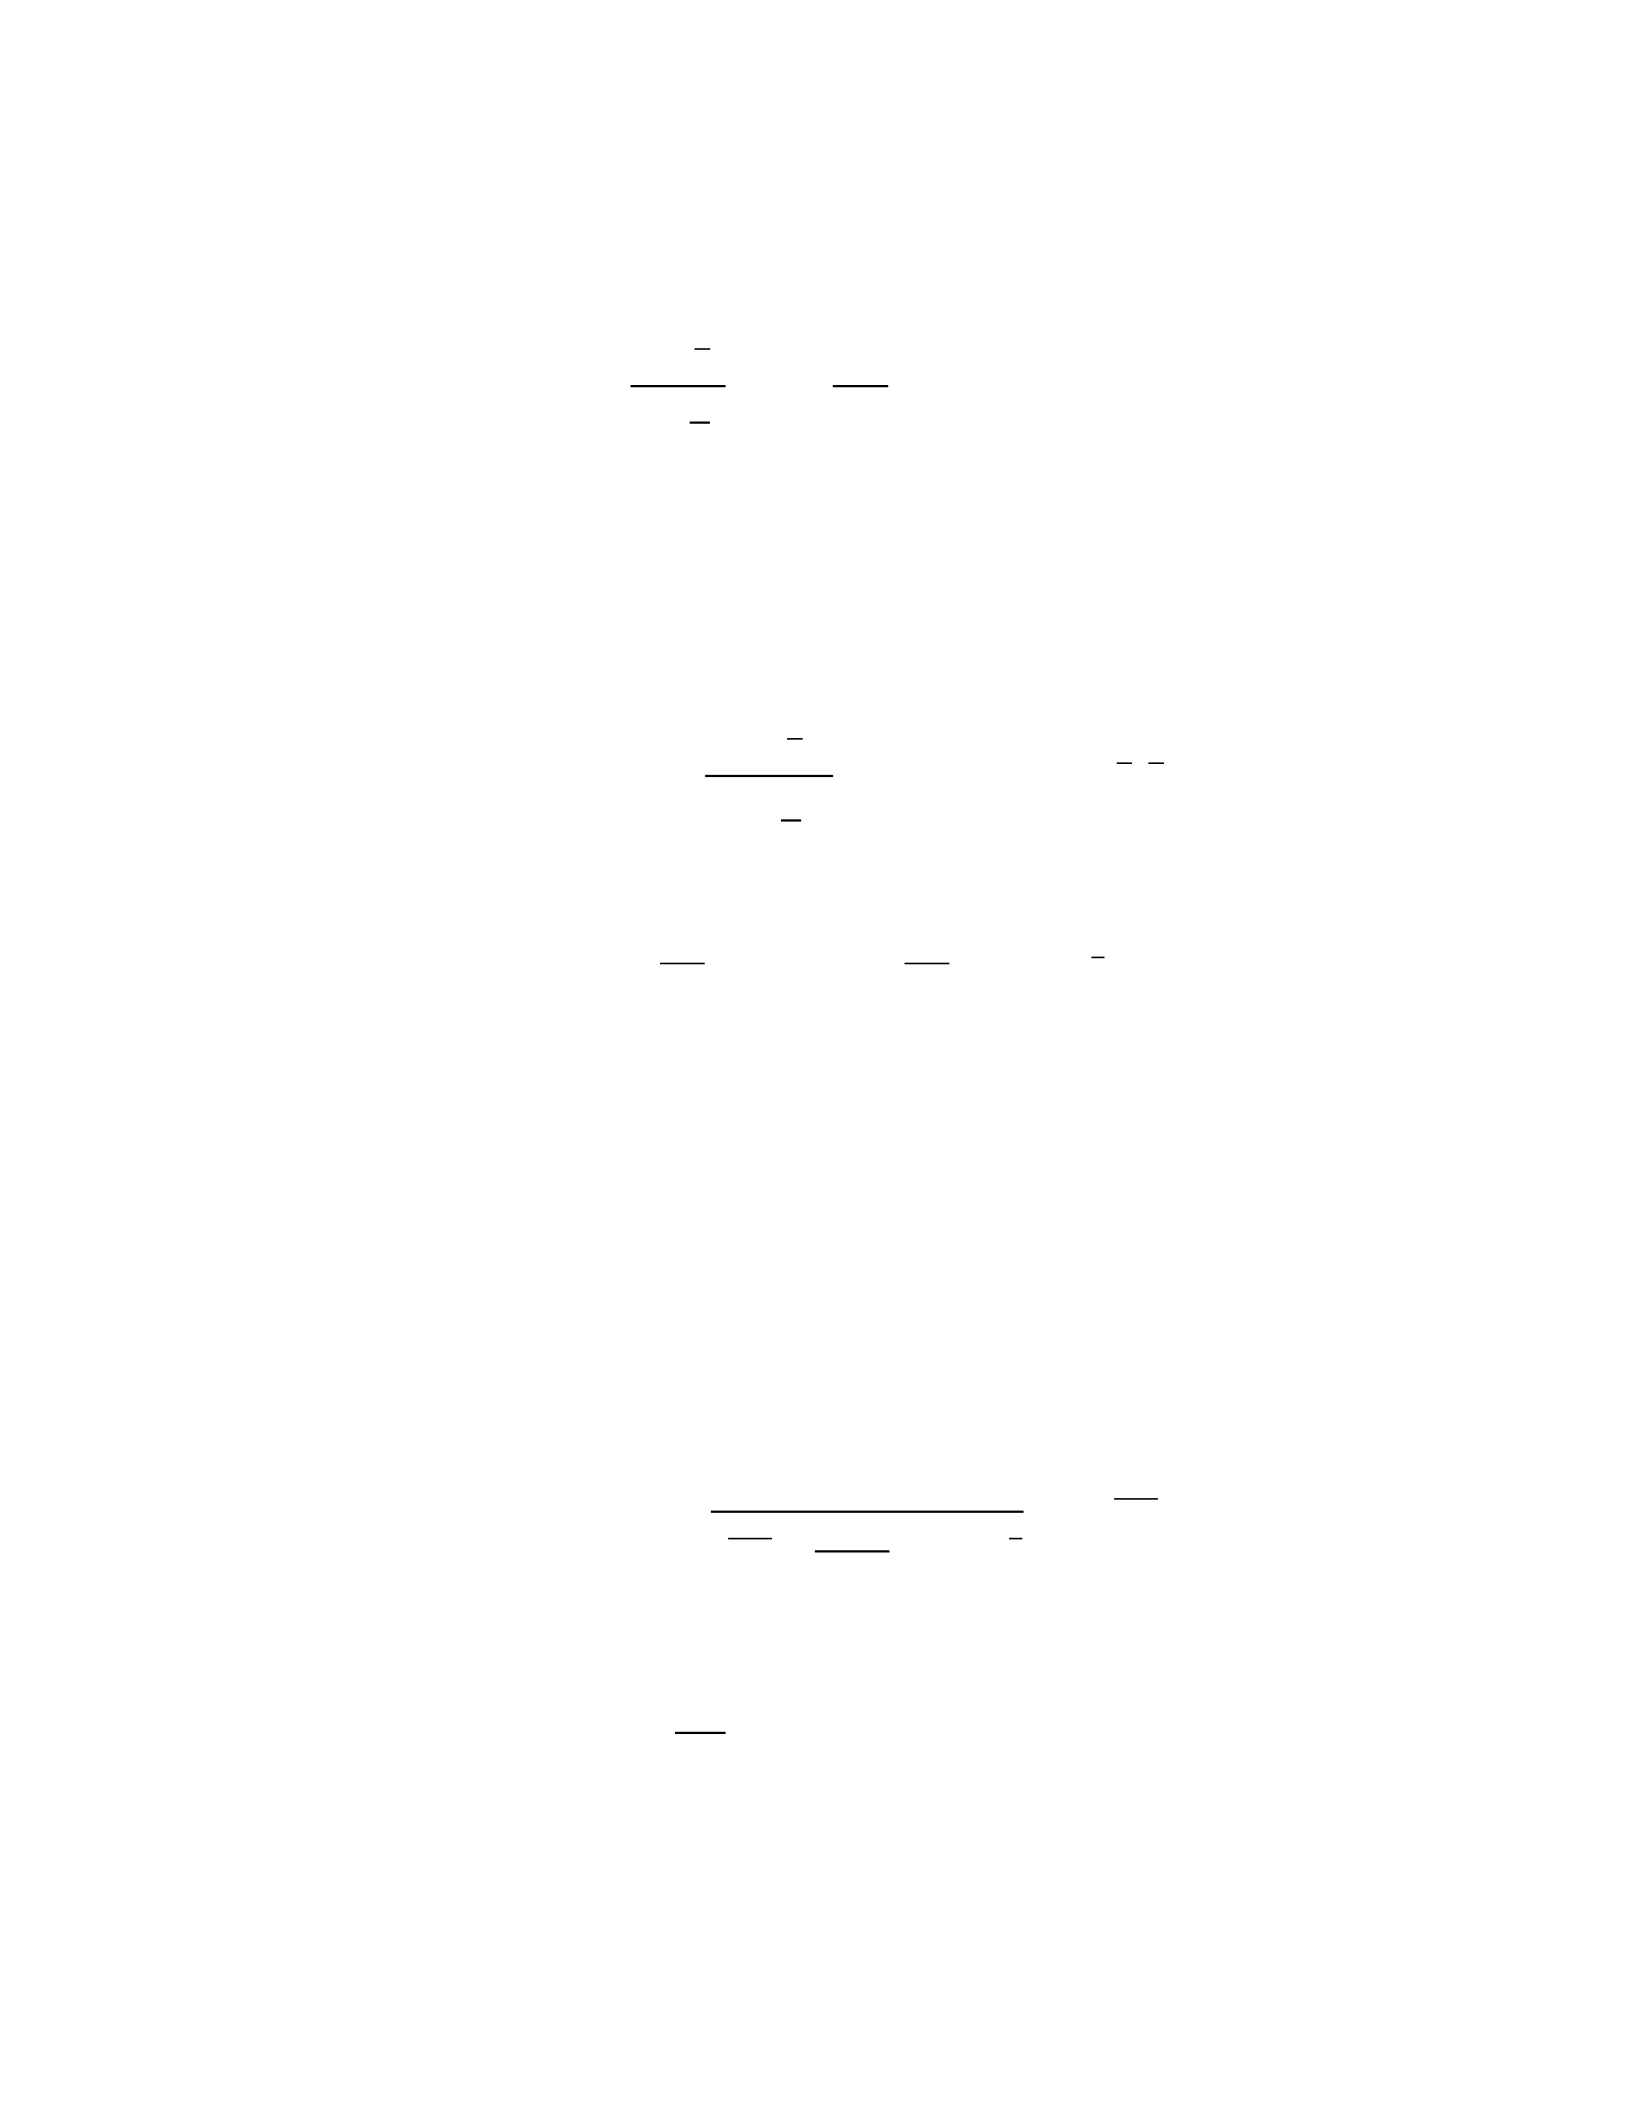
𝑤𝛼(𝑥)=𝛼1−1
𝛼
2𝛤(1
𝛼)exp(−|𝑥|𝛼
𝛼), 𝑥∈ℝ,𝛼>1
Conjecture 8.1.1: If 𝛼≠2 and 𝐶+𝐶𝑇 has no vanishing eigenvalue, then ∑ |𝑥𝑖|𝛼
𝑑
𝑖=1 admits a
finite number of minima in 𝐴1, and det𝐺𝐴1 is non-zero at these minima.
Results
For 𝛼≠2:
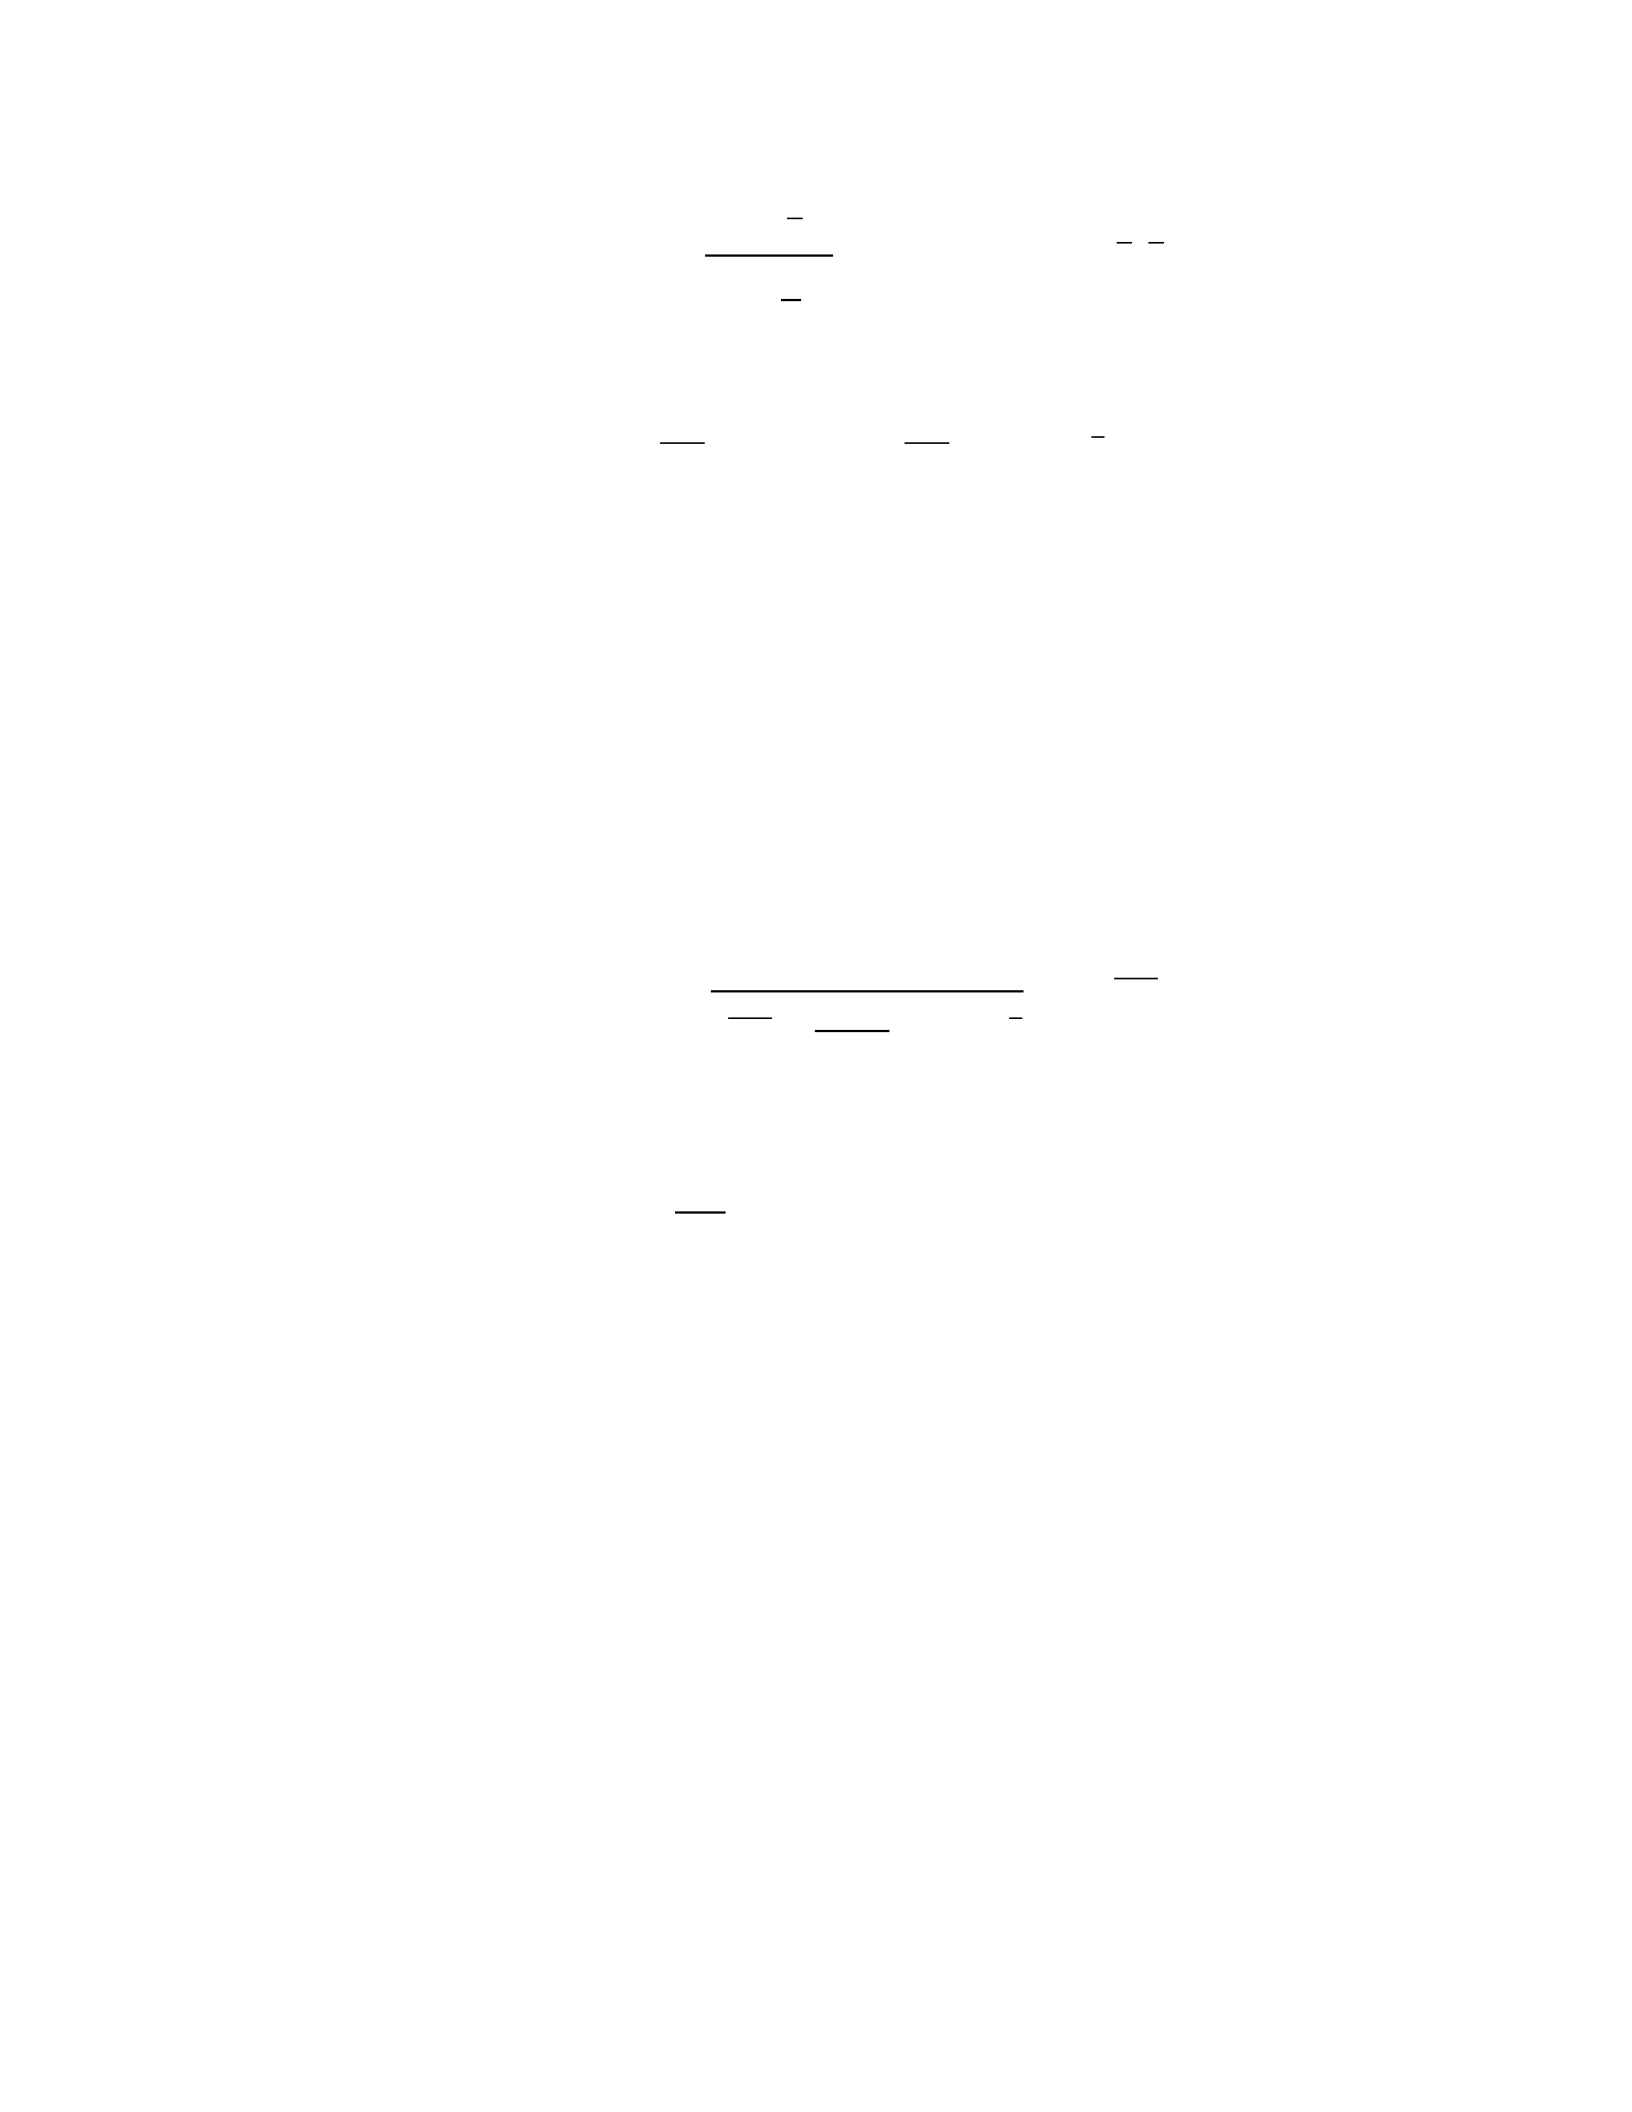
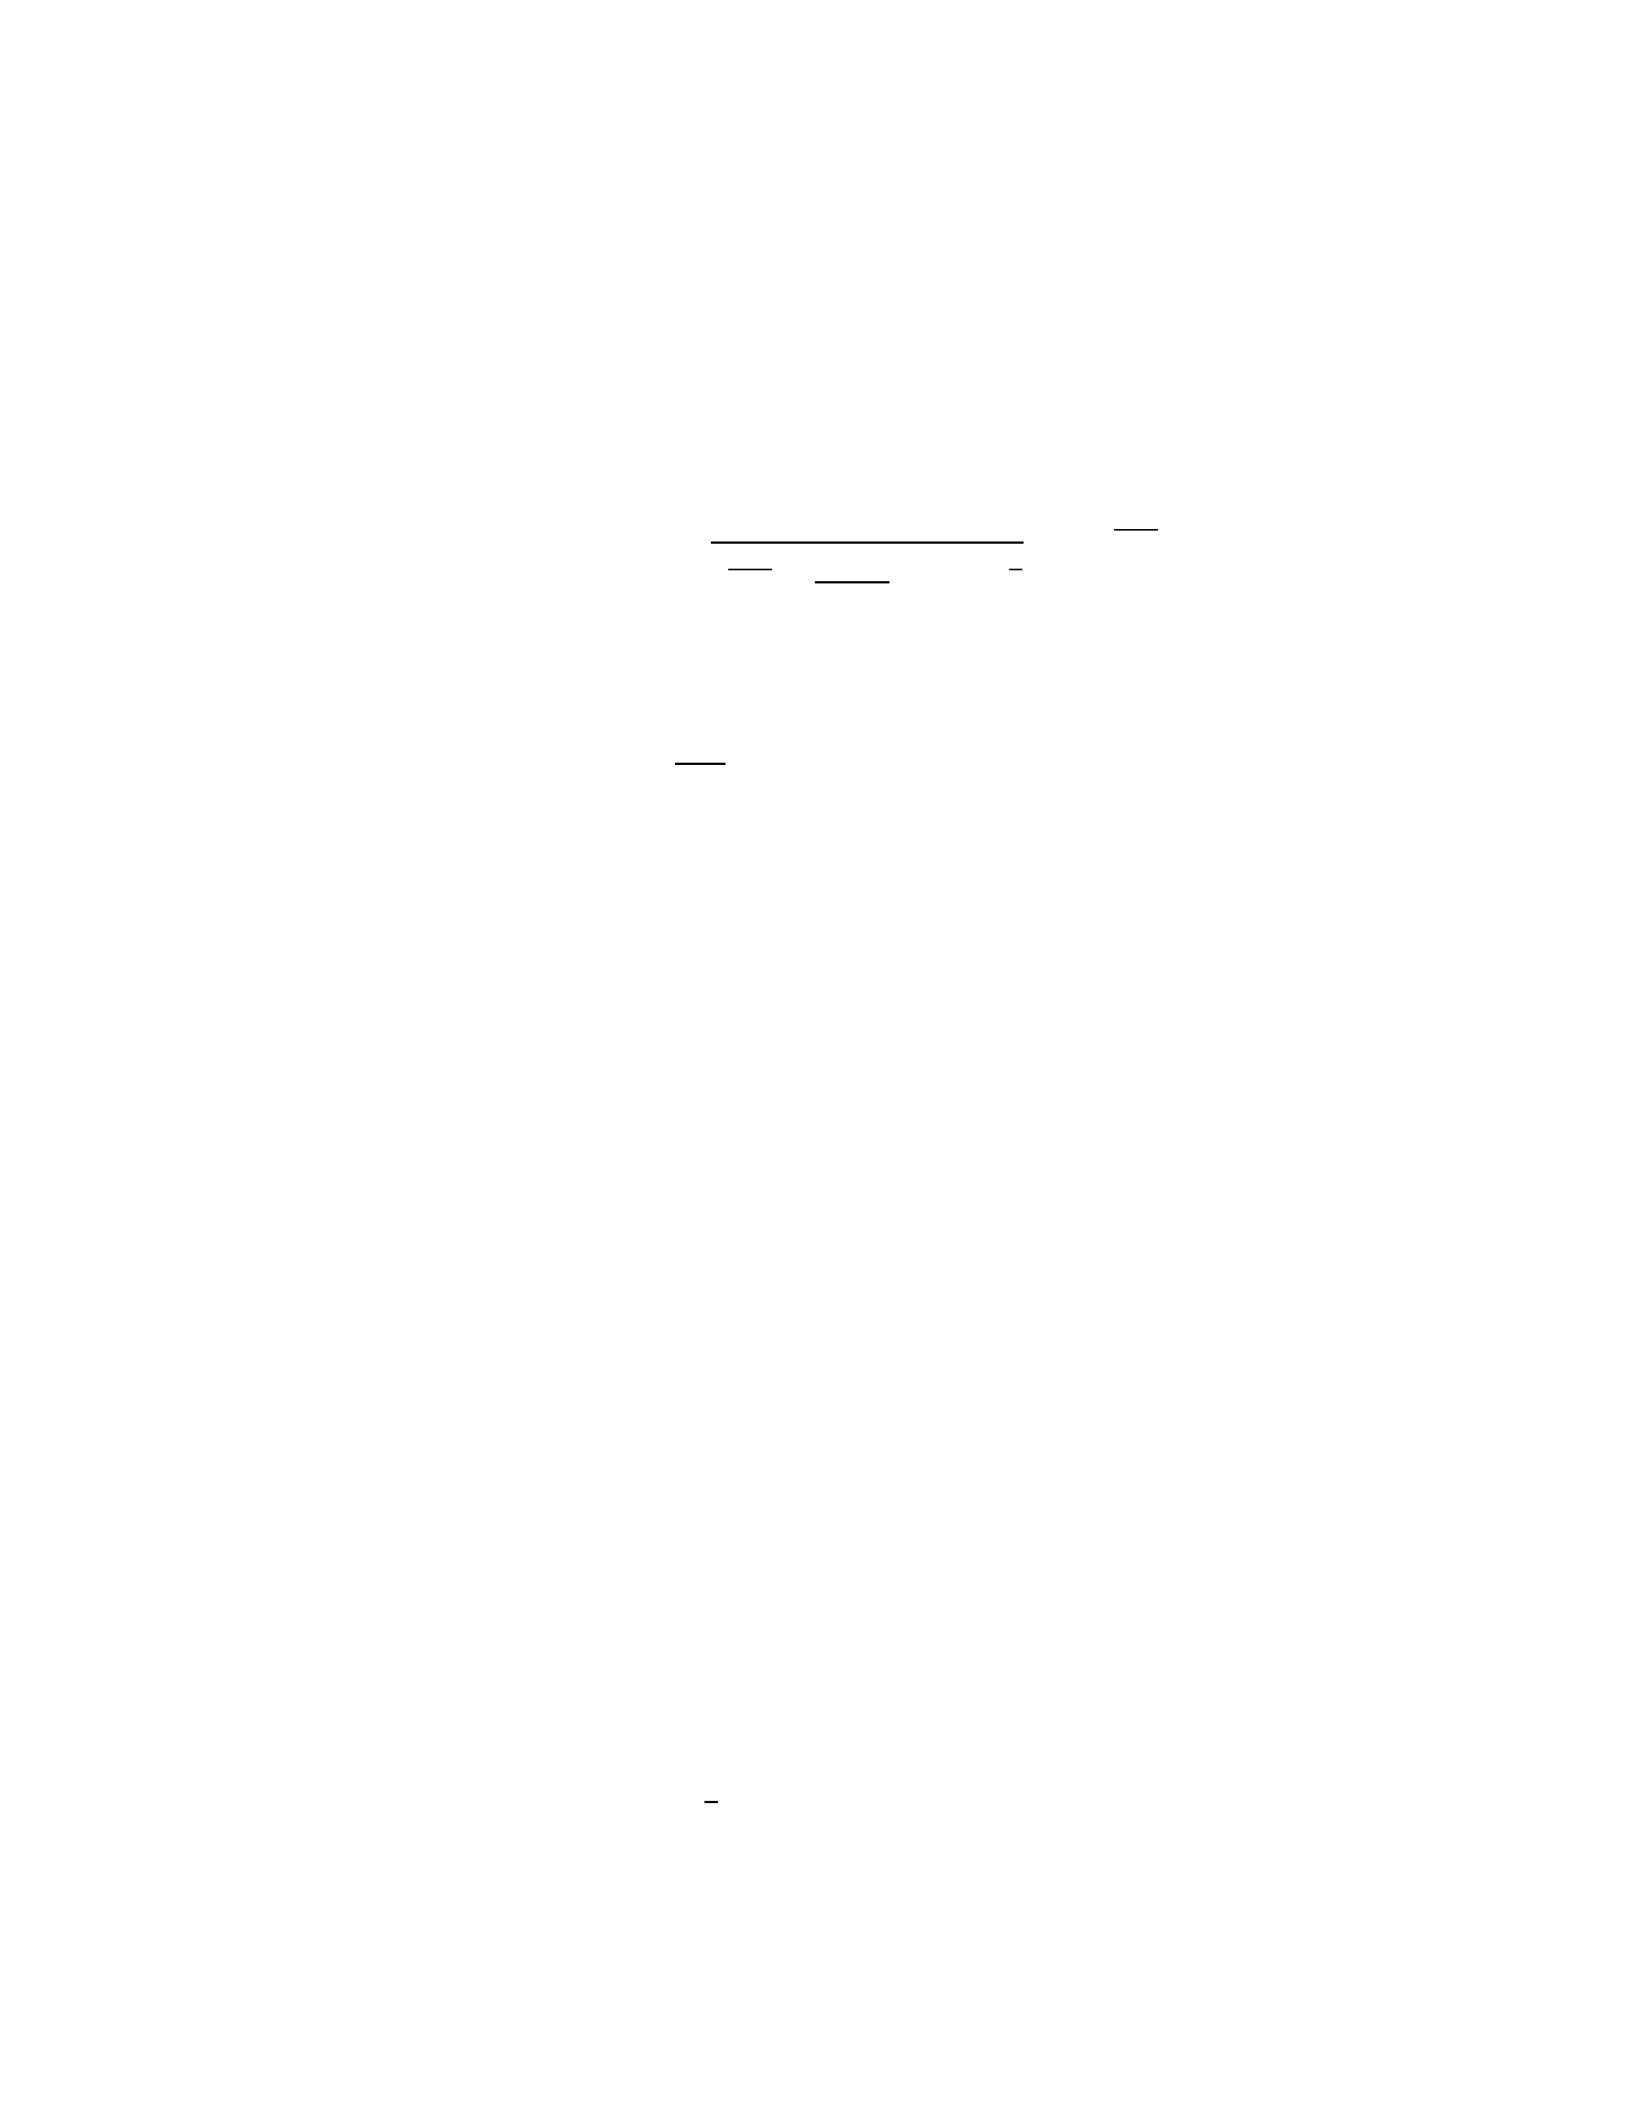
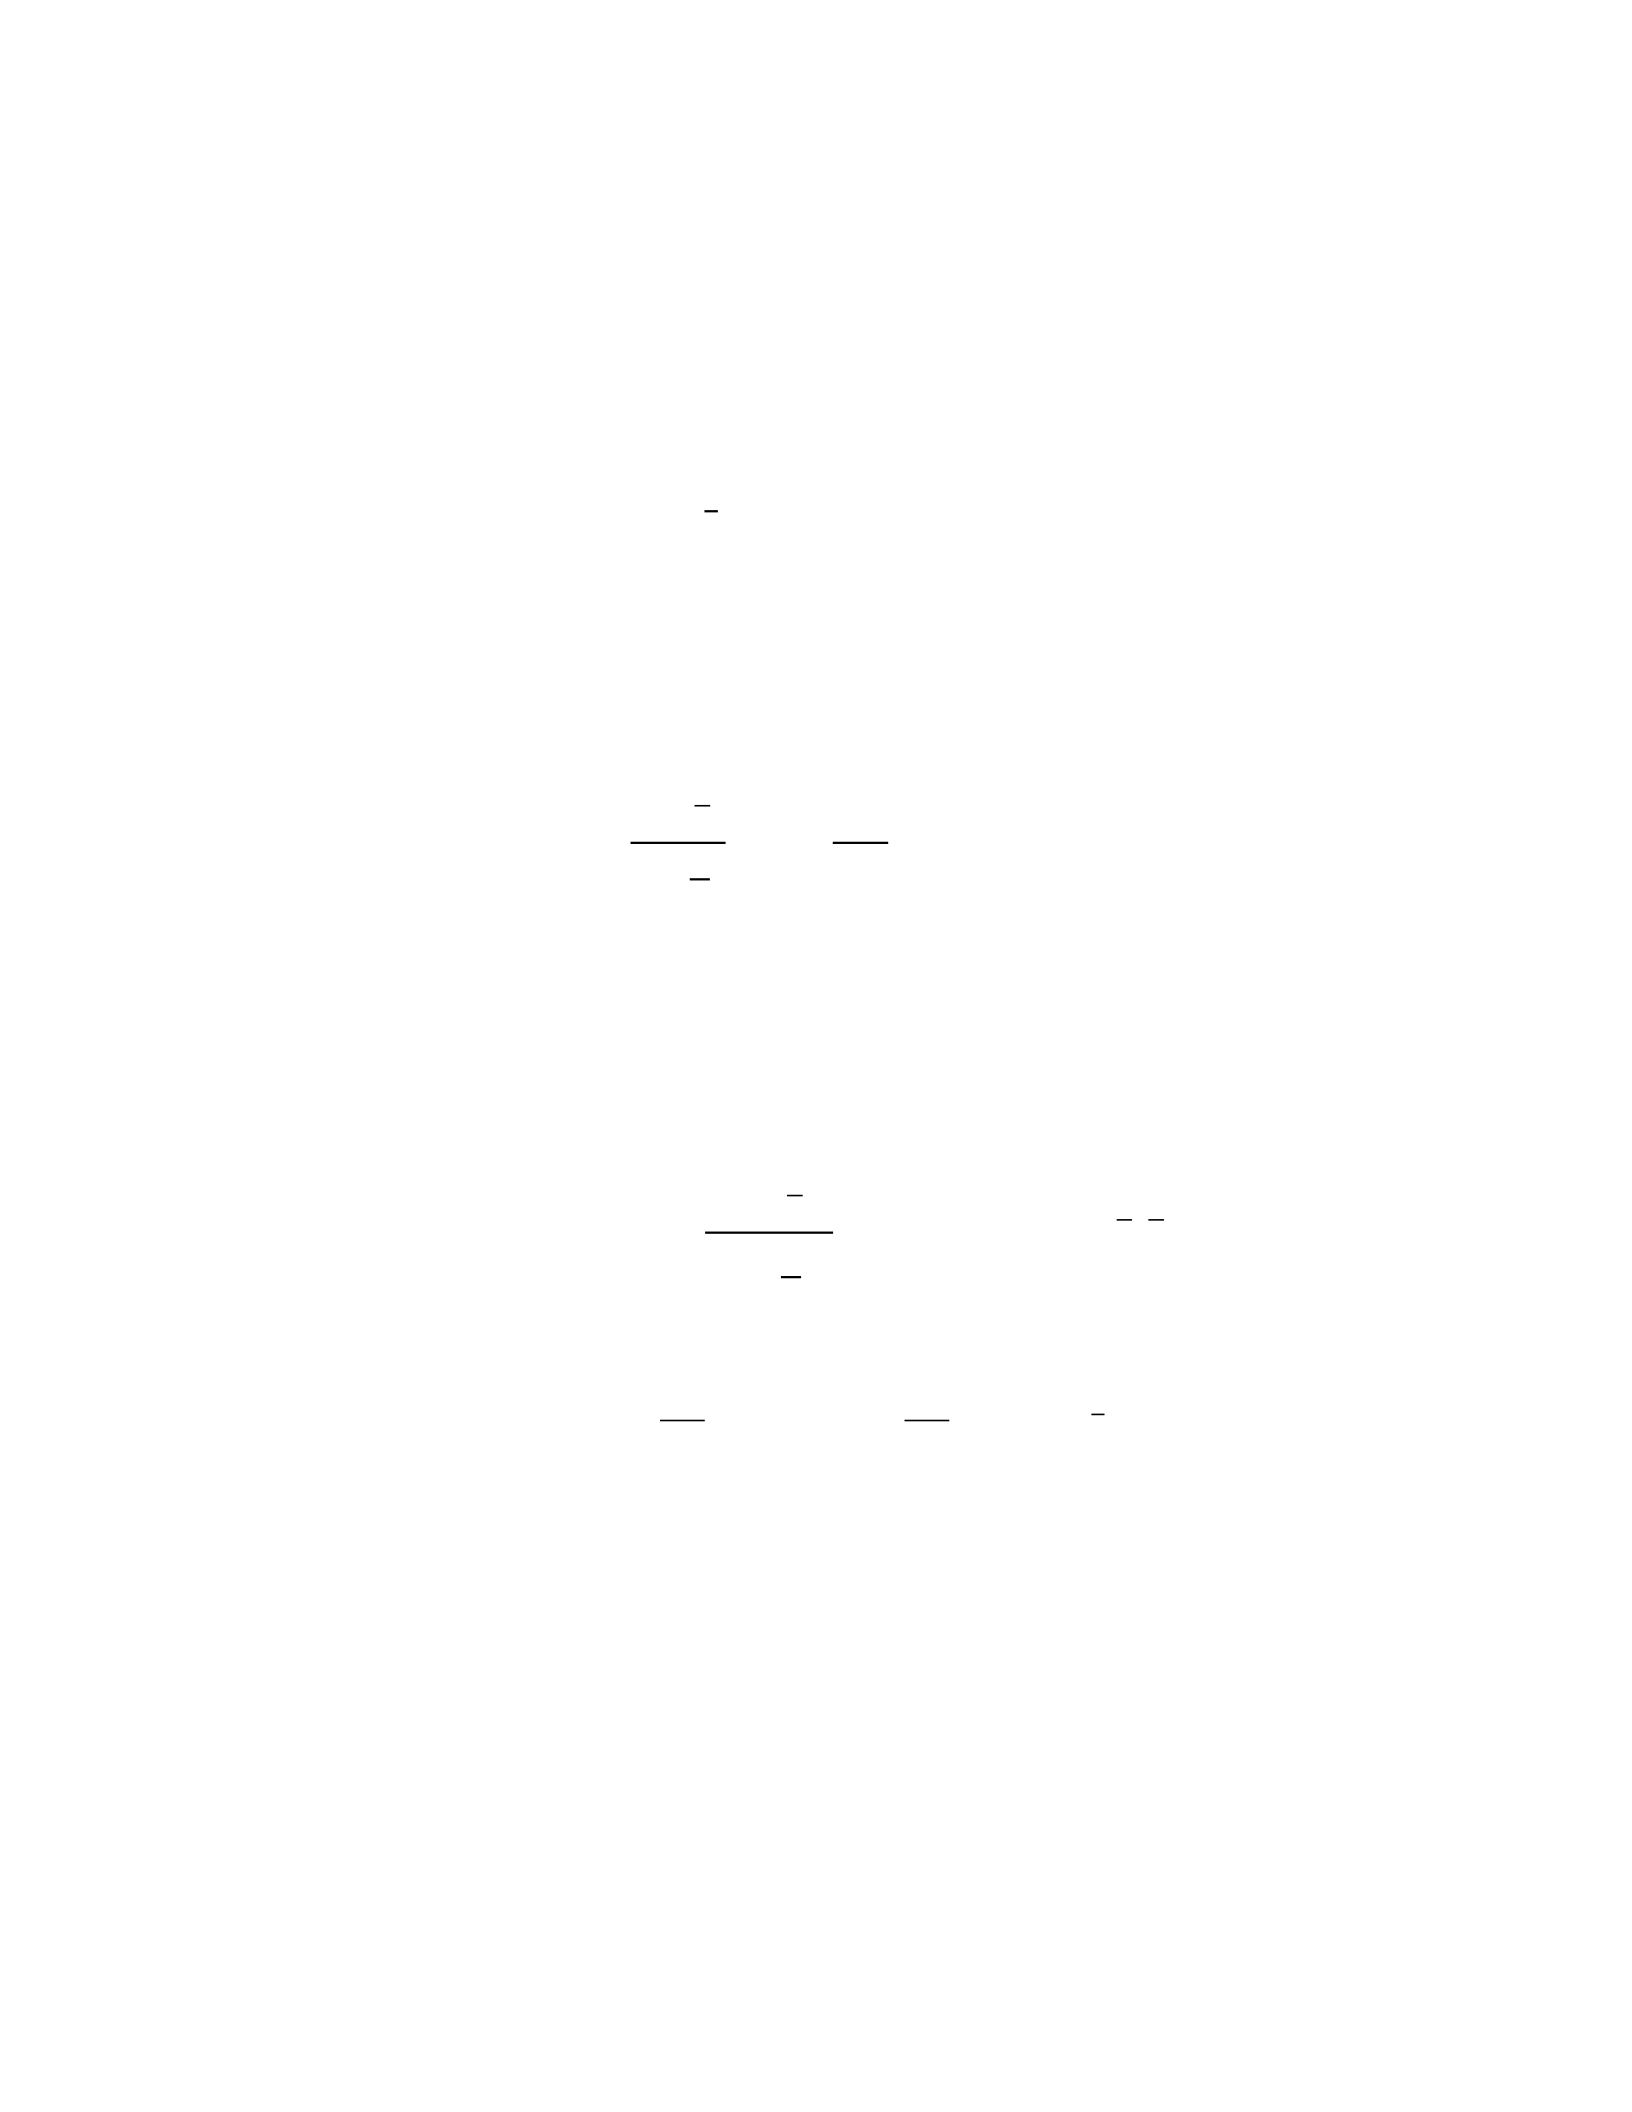
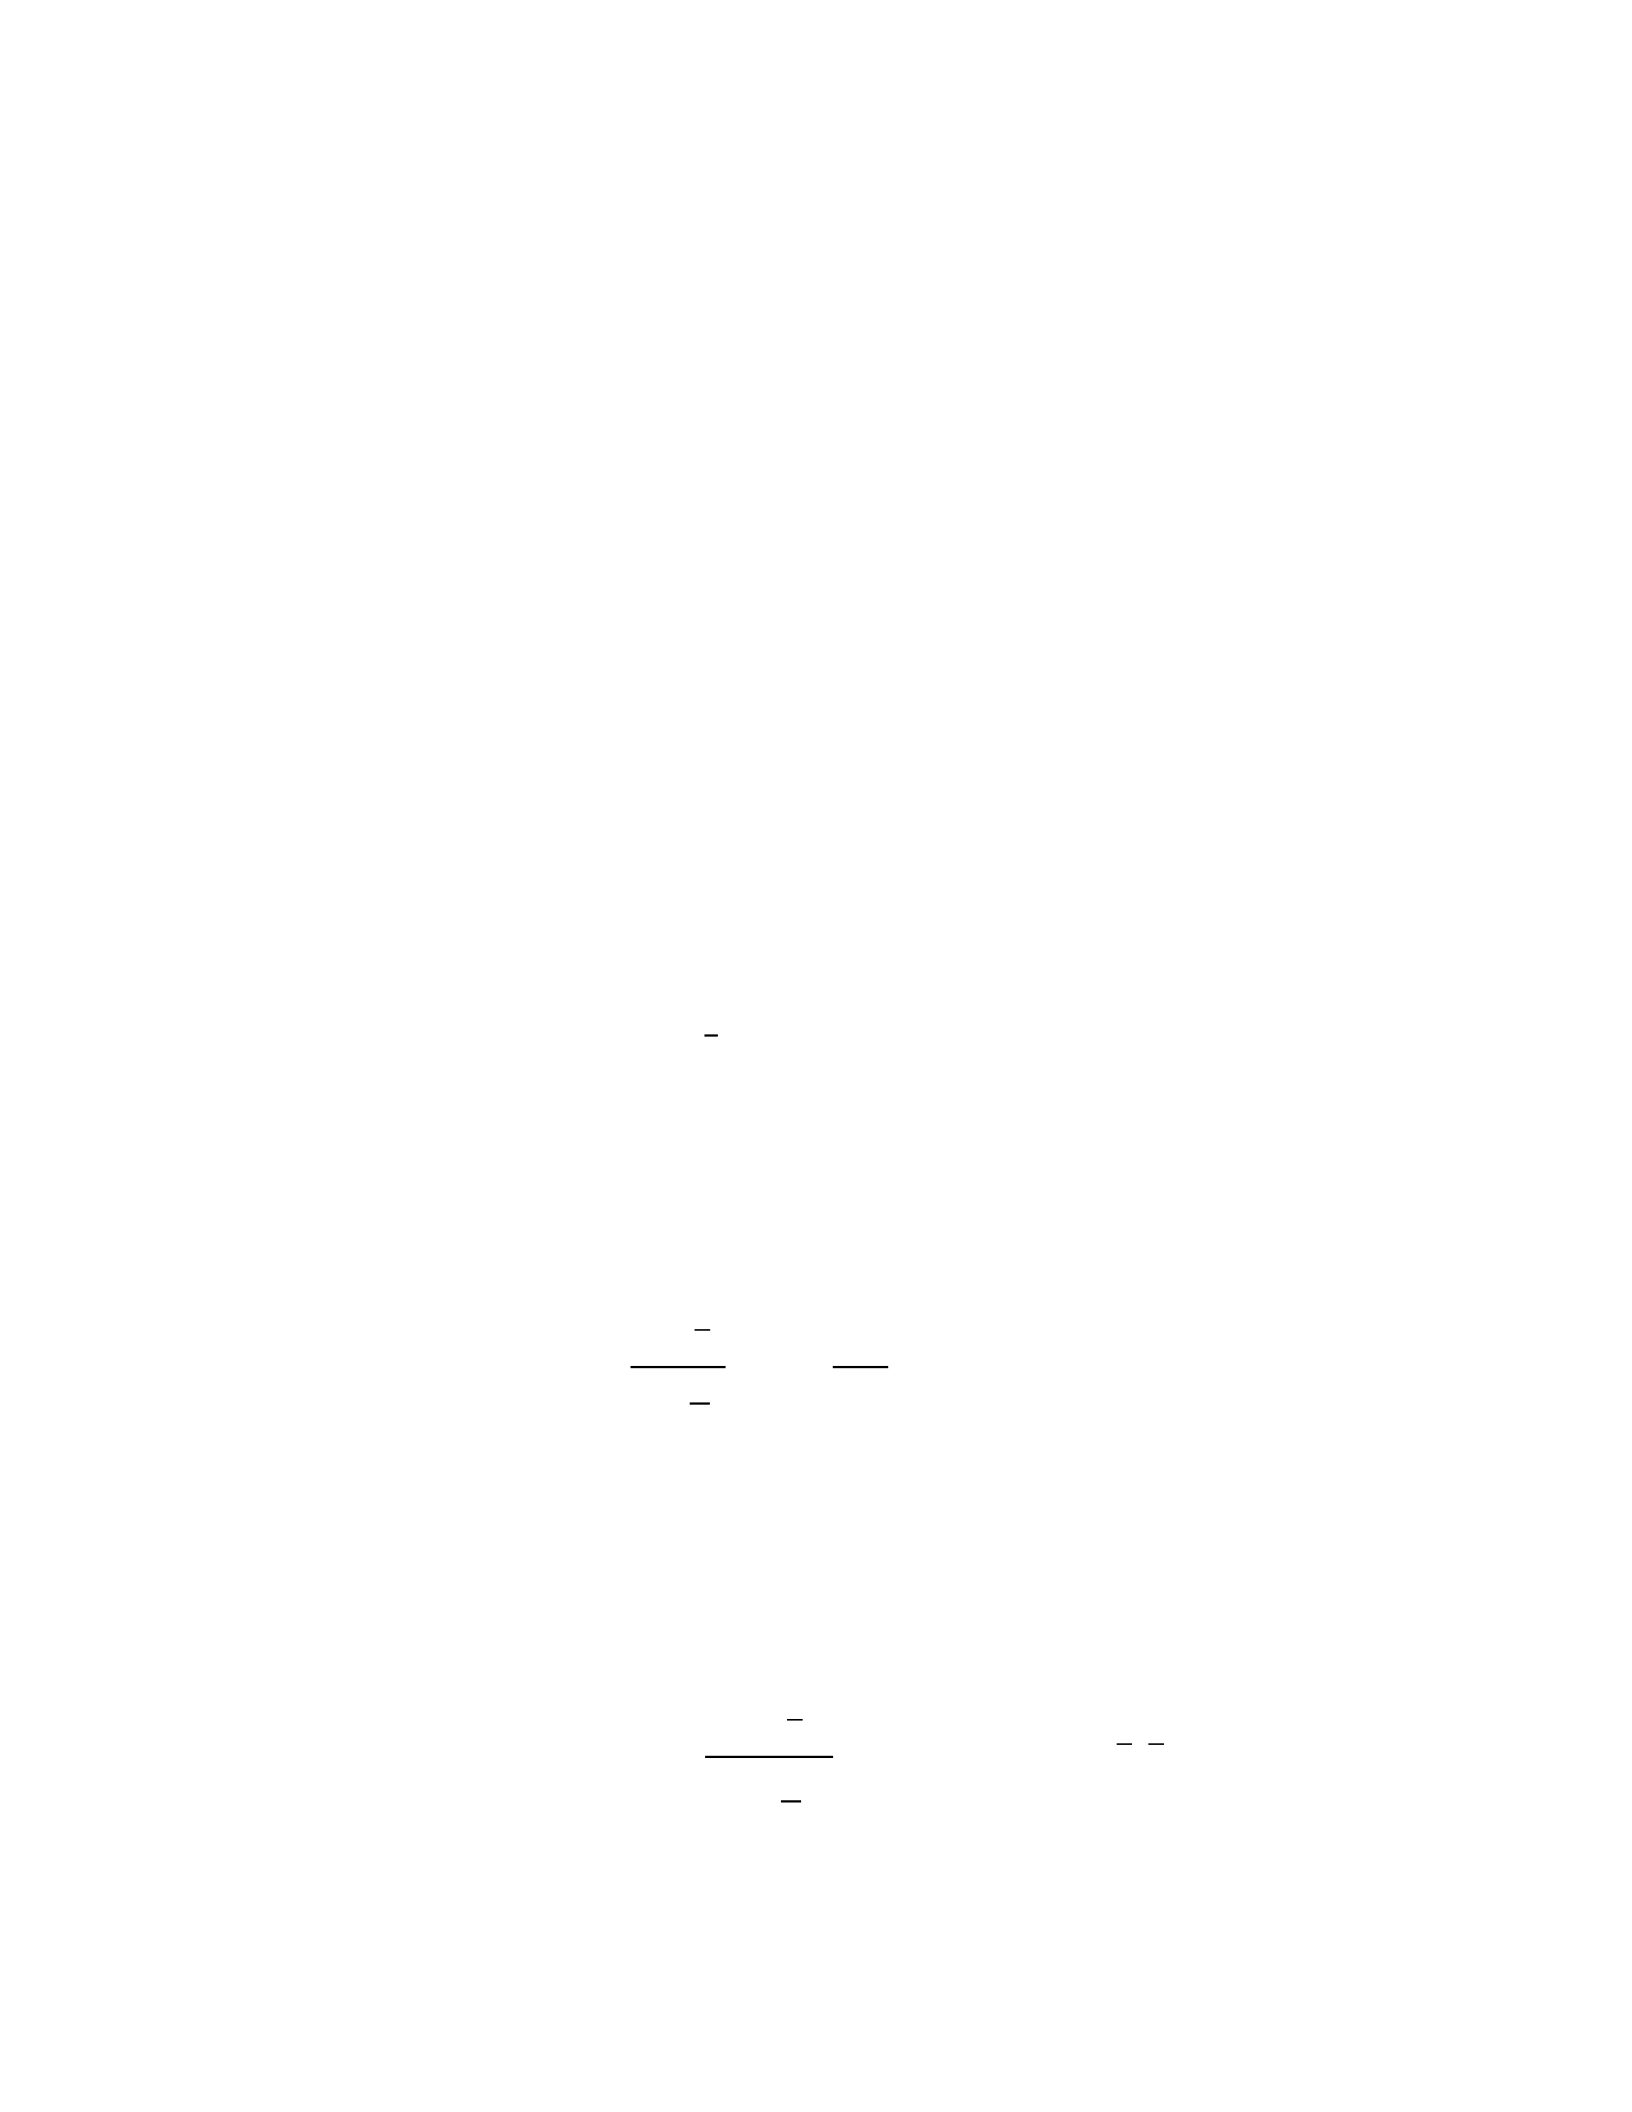
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 𝛼𝑑−𝑑
𝛼
2𝑑𝛤(1
𝛼)𝑑𝑐1𝑒−𝑡𝛼/2𝐼(𝐴1)𝑡−(𝛼−2)𝑑
4−𝛼
4
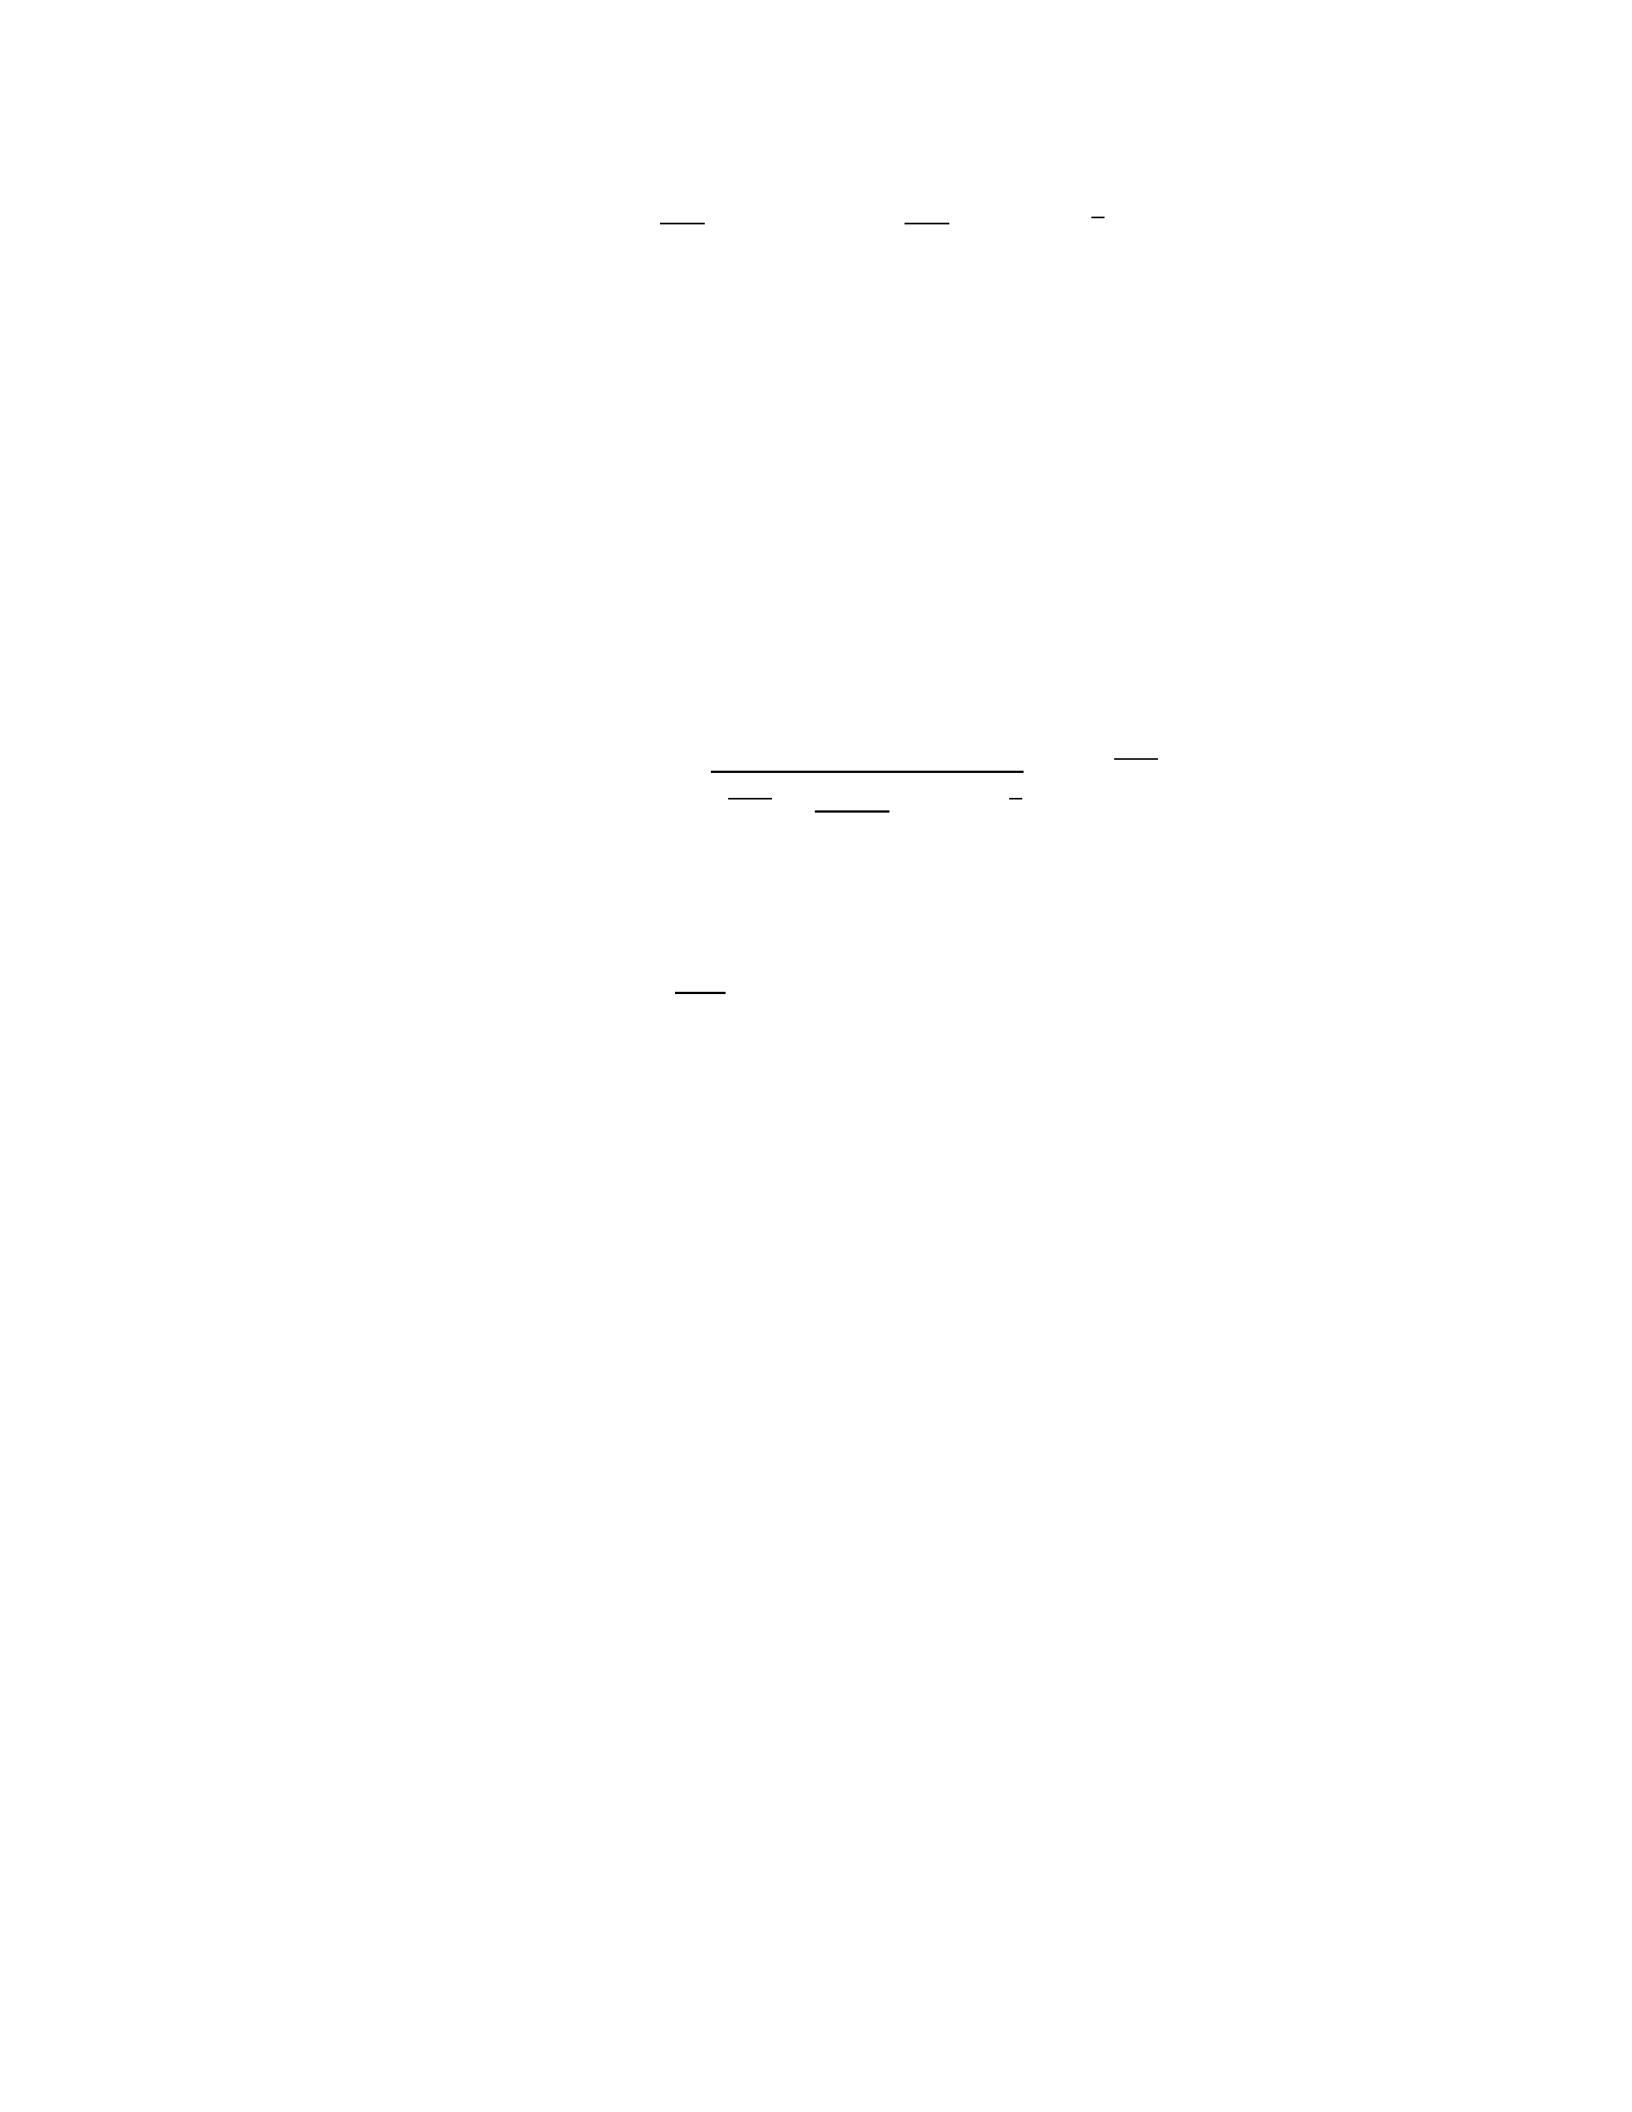
where
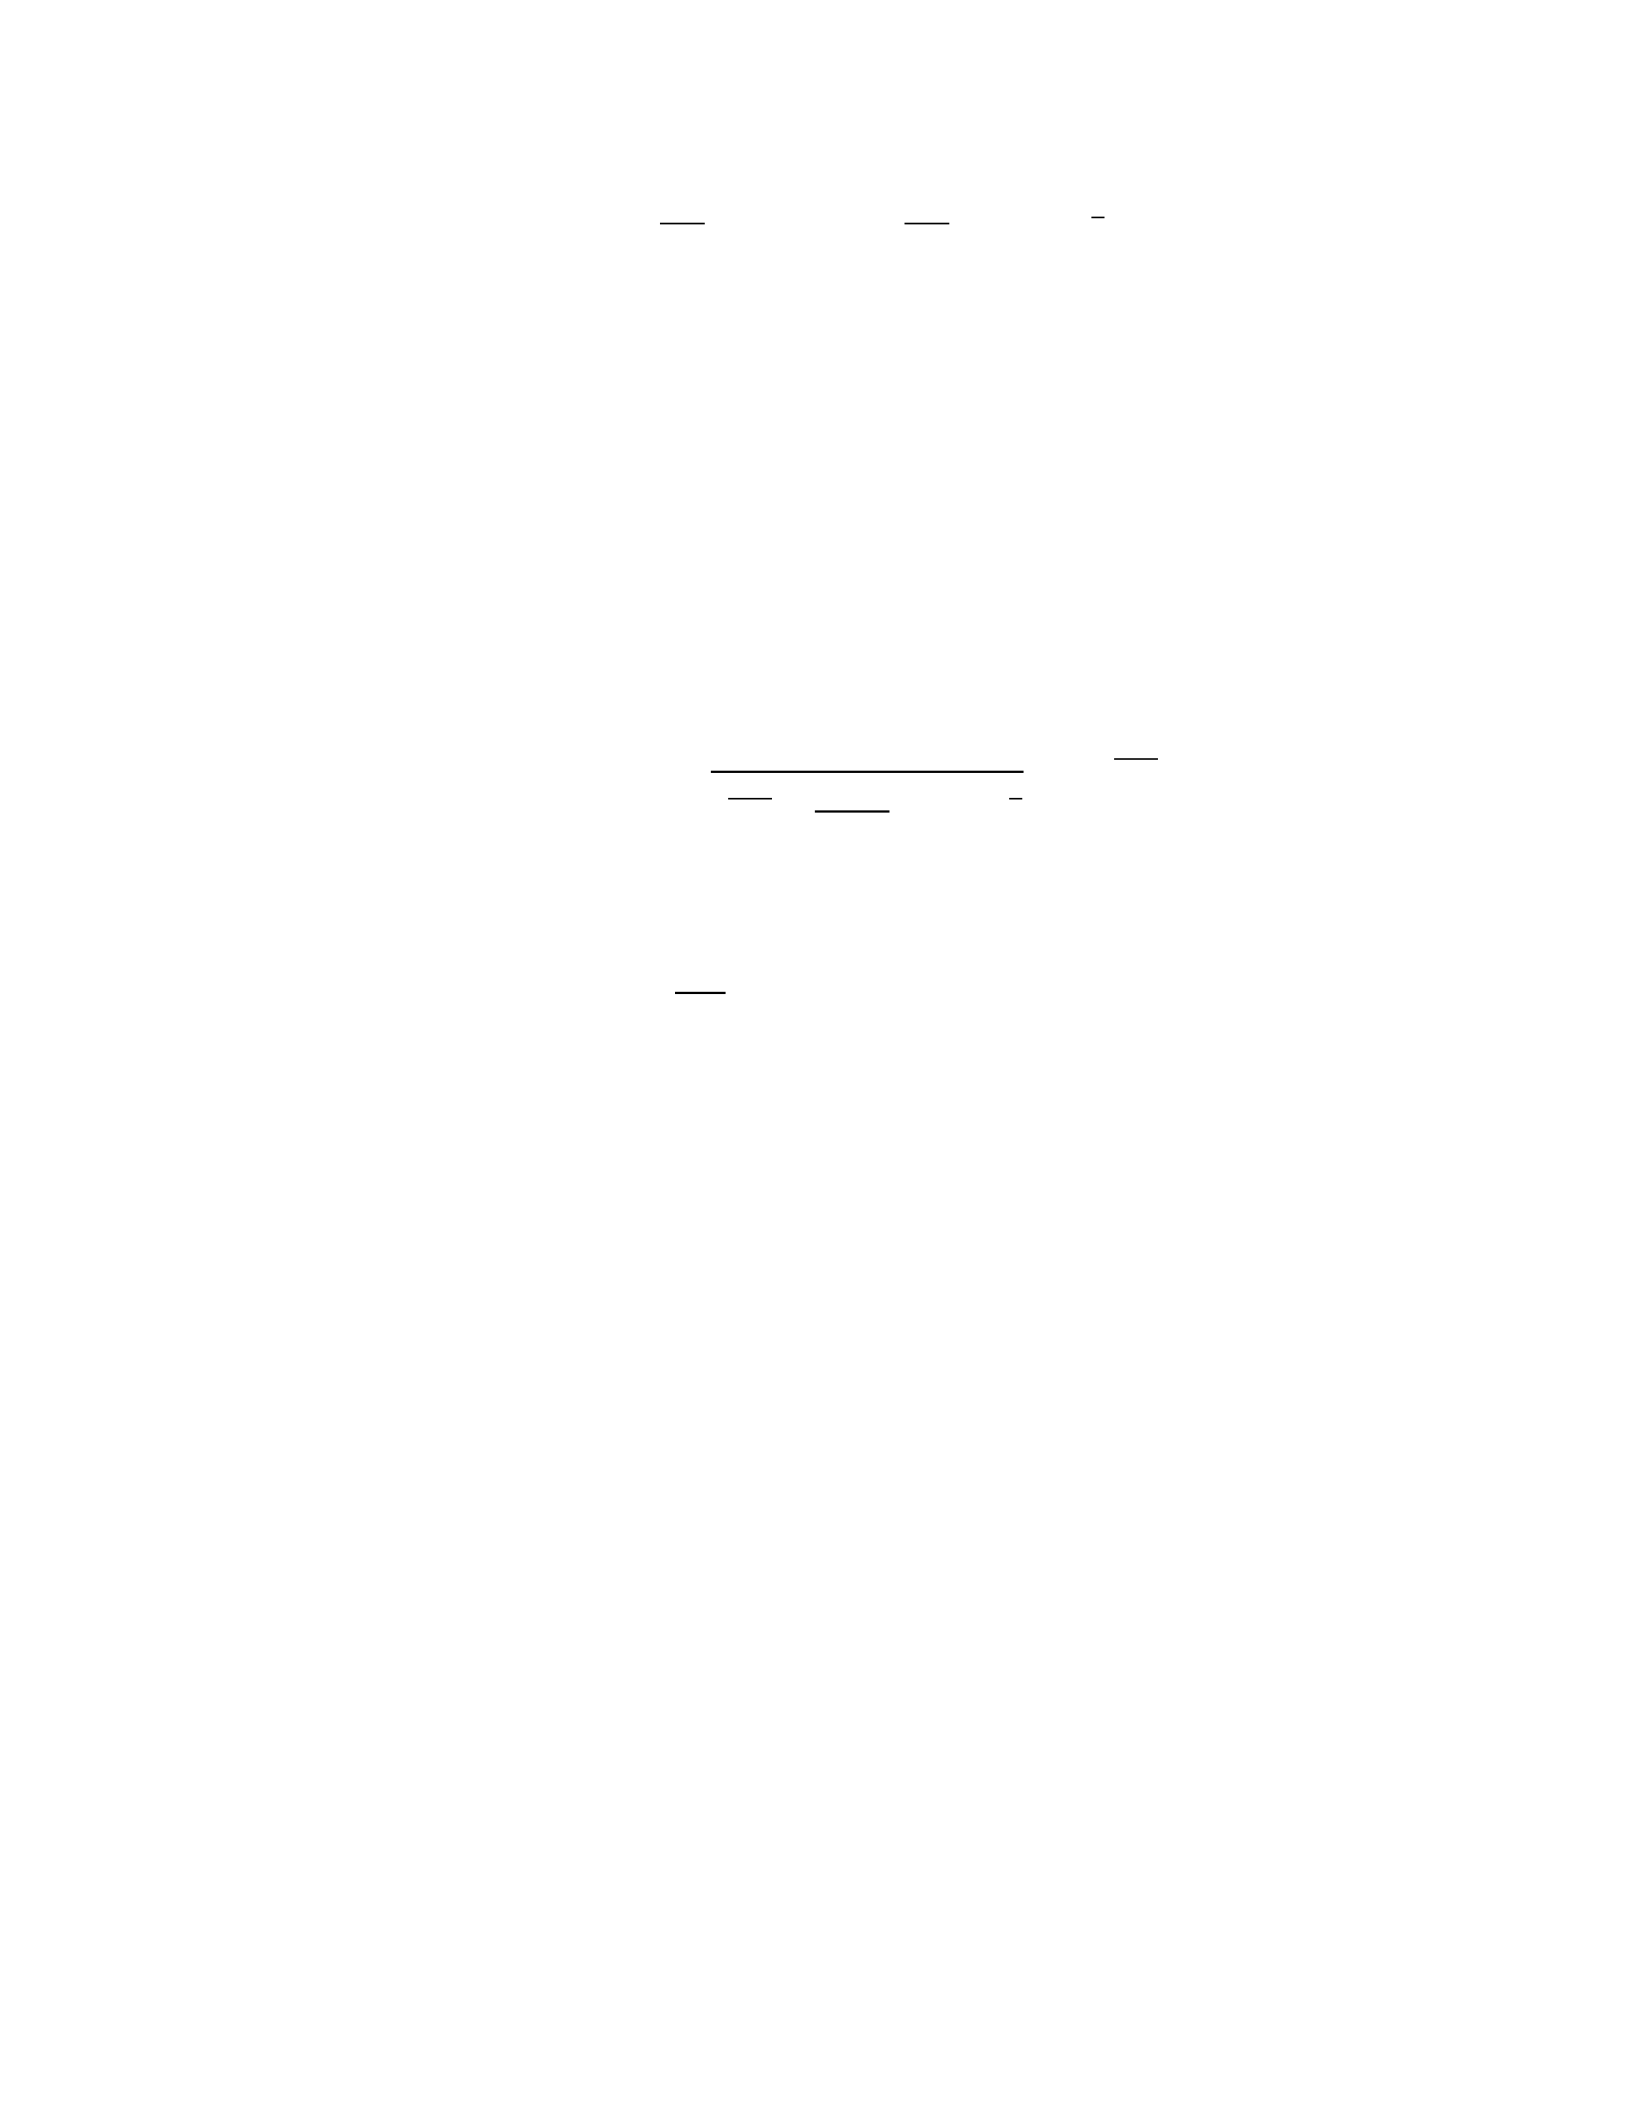
𝑐1=(2𝜋)𝑑−1
2∑|𝐷𝐼(𝑥)|−𝑑+1
2
𝑥∈𝐷𝐴1(det𝐺𝐴1)−1
2
Note: 𝐷𝐼(𝑥)=(sign(𝑥𝑖)|𝑥𝑖|𝛼−1)1≤𝑖≤𝑑 for 𝛼 >1
Special Case: 𝛼=2
Let 𝜆 be the largest eigenvalue of 𝐶+𝐶𝑇 (assumed positive), and 𝐻={𝑥:(𝐶+𝐶𝑇)𝑥=𝜆𝑥}
be the associated eigenspace.
Theorem 8.1.2
For 𝛼=2 and 𝜆>0:
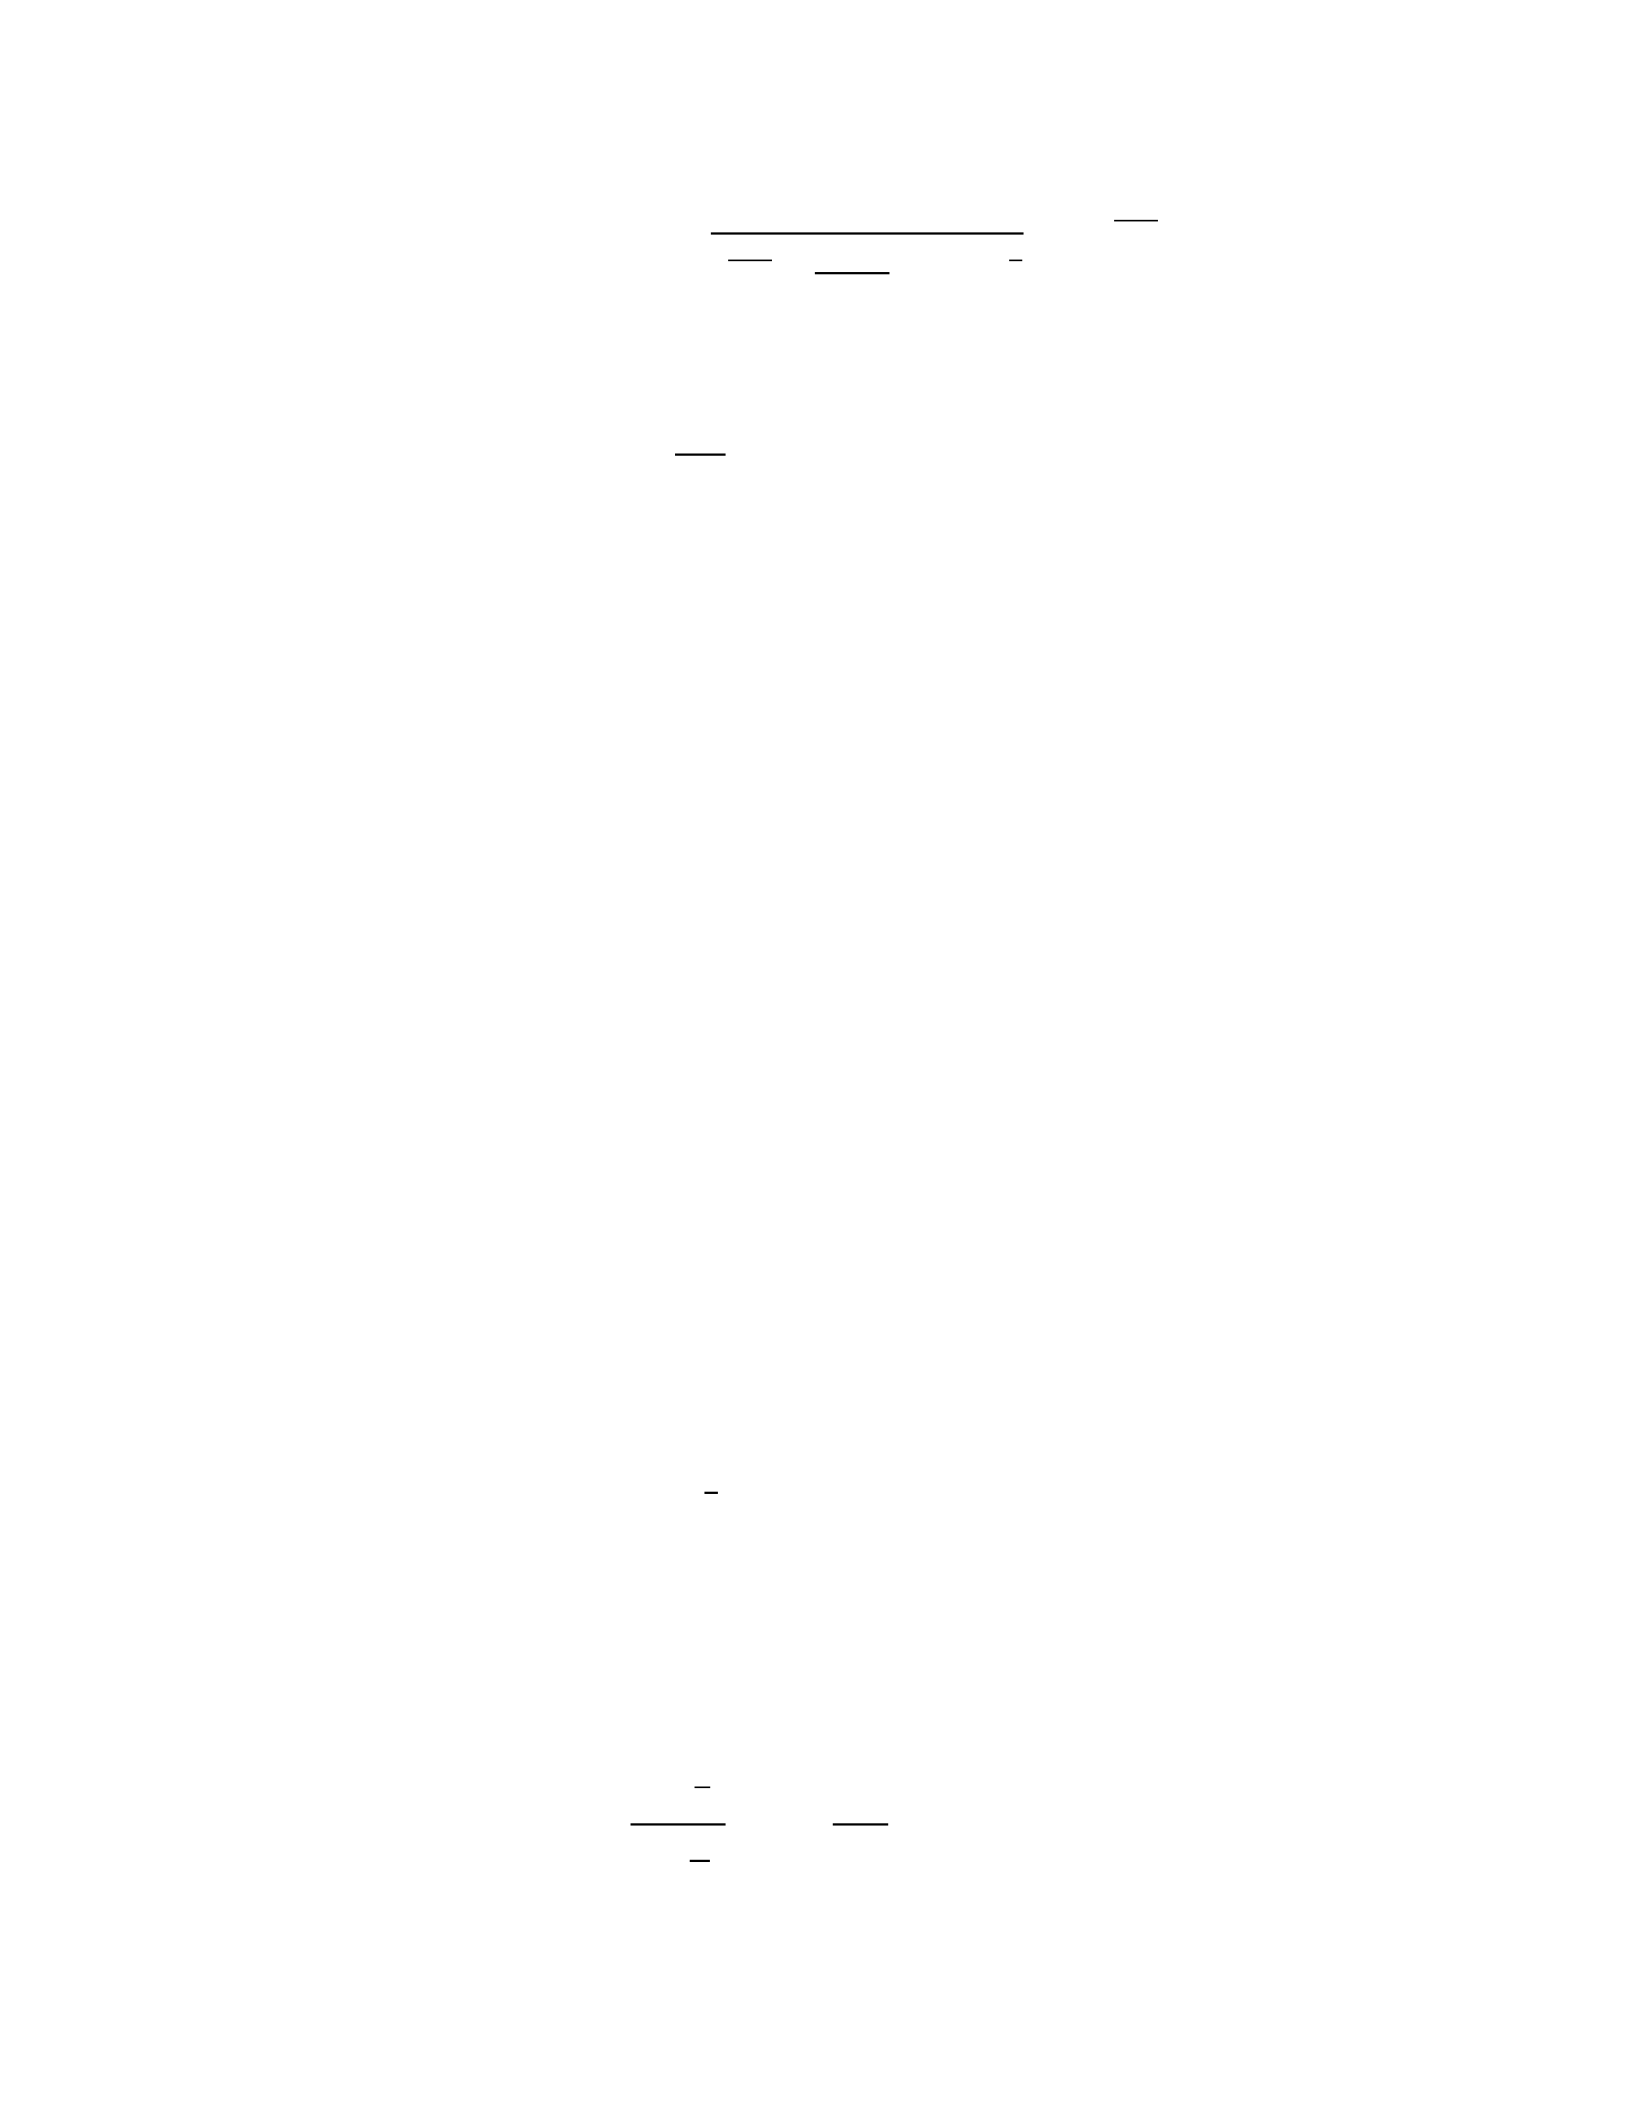
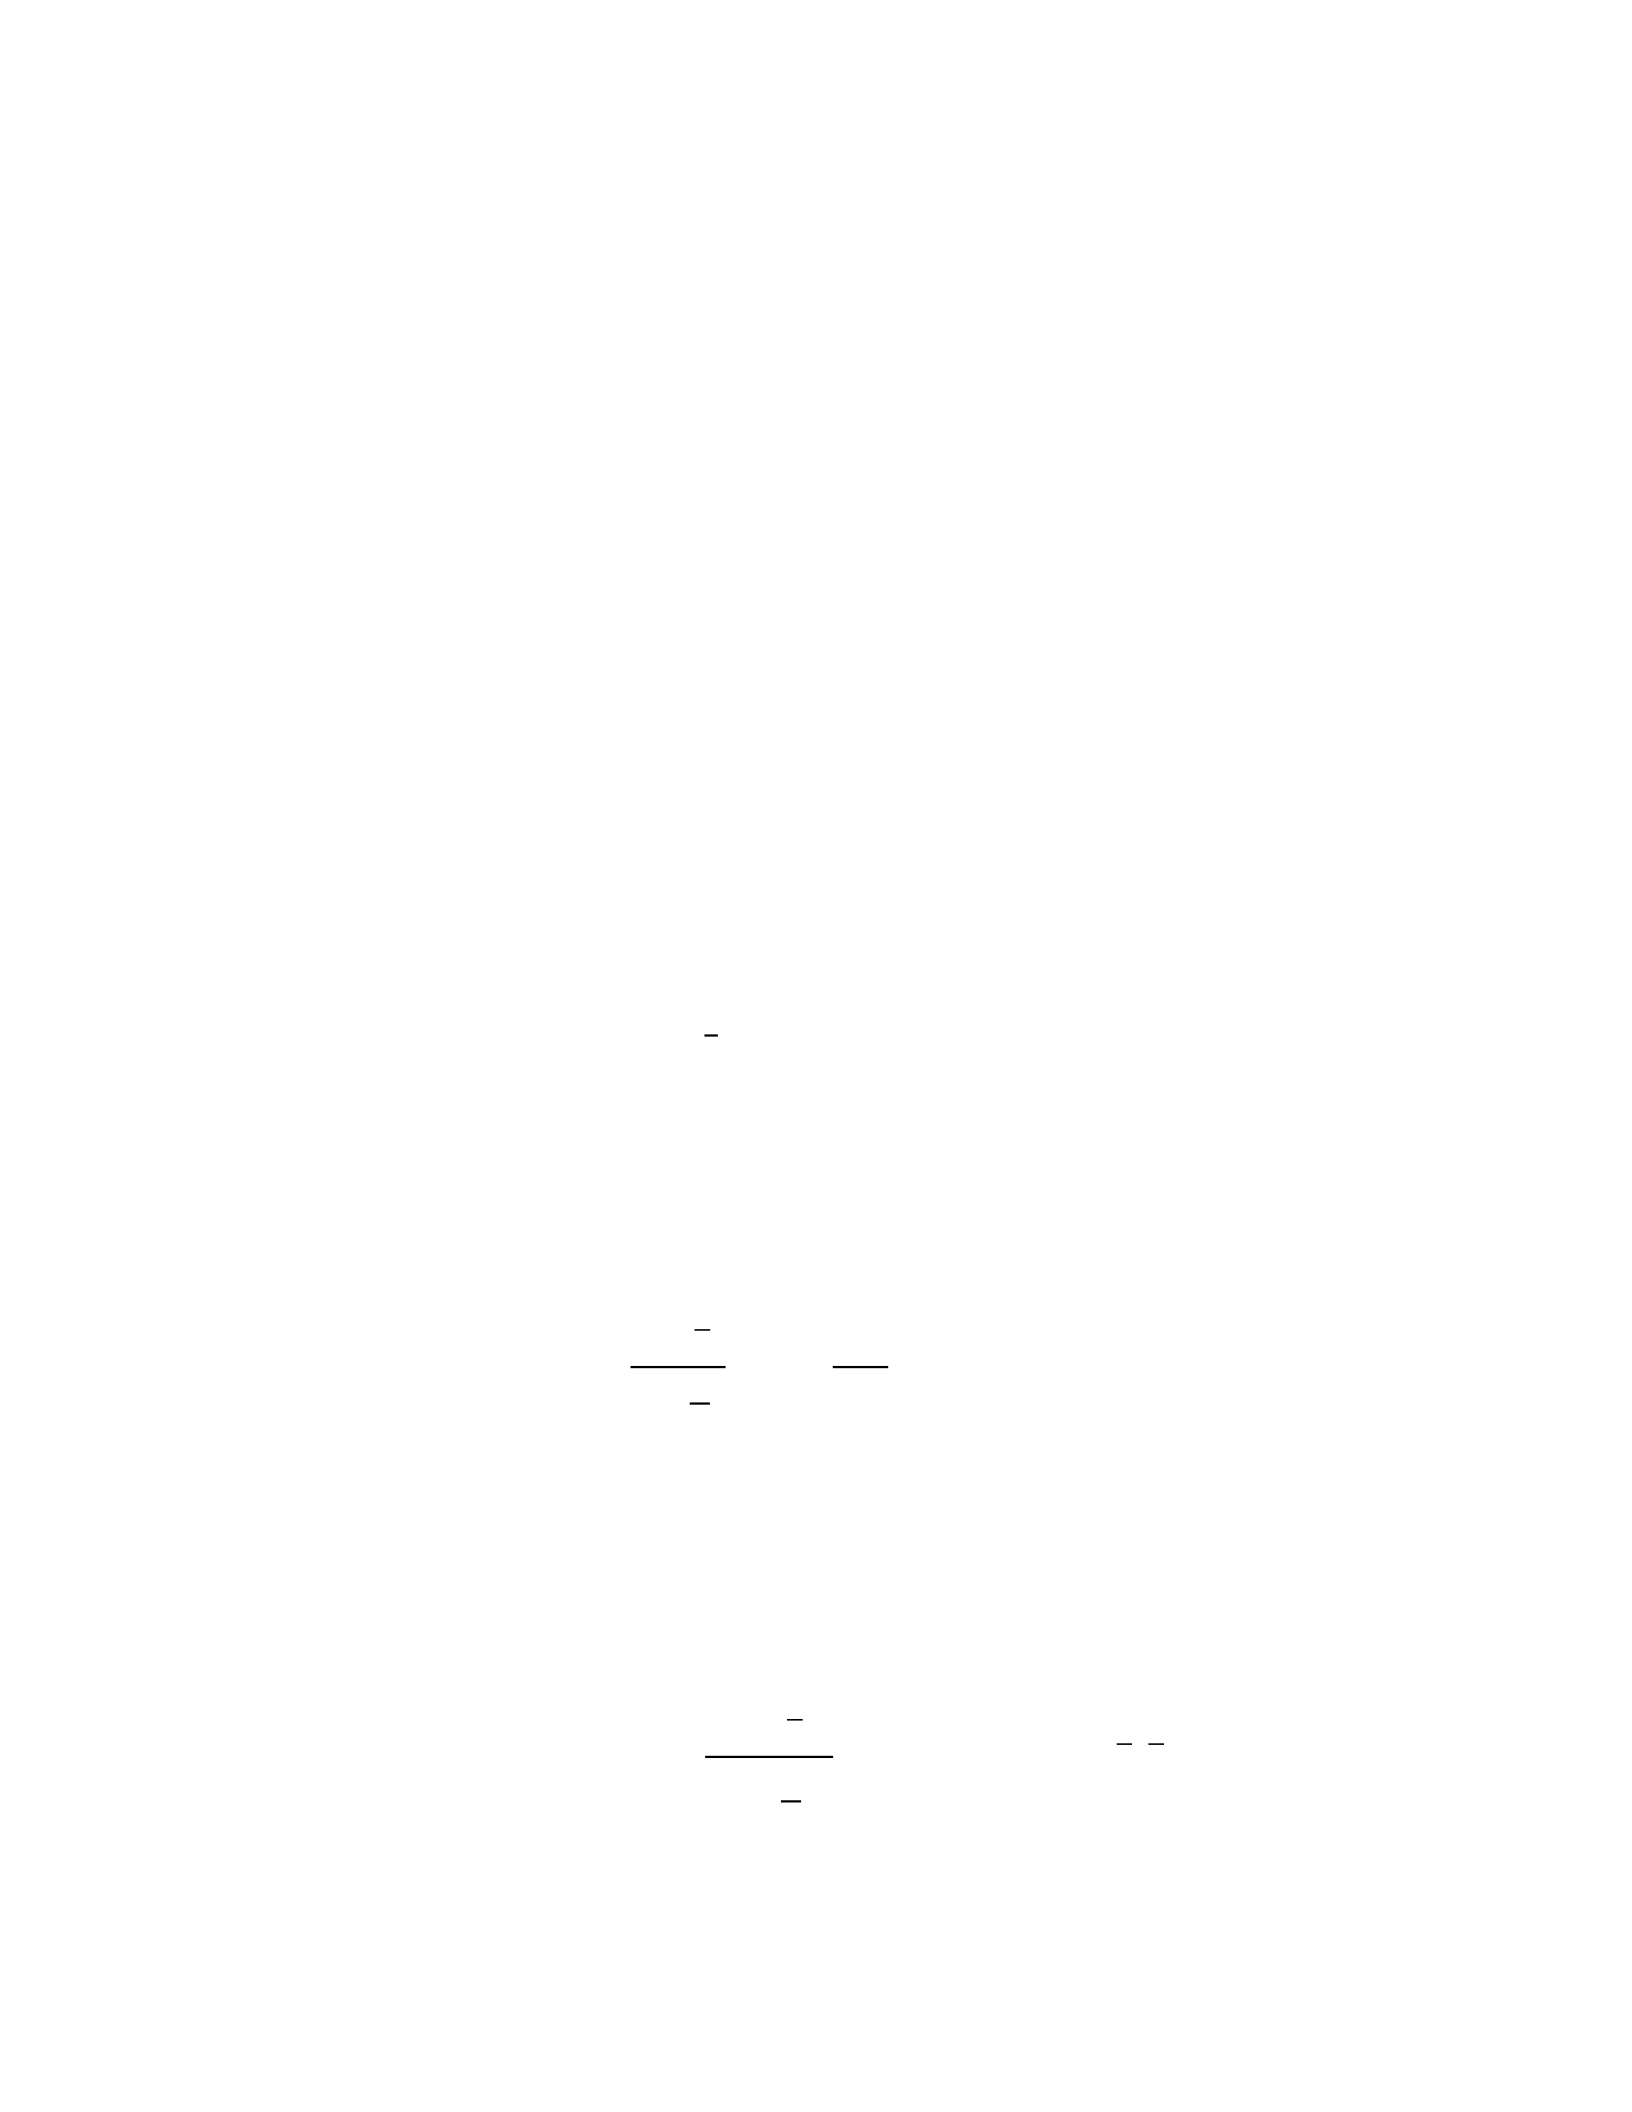
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 1
𝜆𝑘−1
2𝛤(𝑘+1
2)(det𝑀)1
2𝑒−𝑡/𝜆𝑡𝑘−1
2
where 𝑘=dim𝐻−1 and 𝑀 is the compression of 𝐼𝑑−𝜆−1(𝐶+𝐶𝑇) to 𝐻⊥.
Proof outline:
• 𝐷𝐴1 is the sphere of radius √2/𝜆 centered at the origin in 𝐻
• Apply Theorem 7.1
• Calculate 𝐼(𝐴1)=1/𝜆
• Determine 𝐺𝐴1 using second fundamental forms of 𝐼(𝐴1) and ∂𝐴1
These notes discuss the decay of probability 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡} as 𝑡 approaches infinity, where
𝑋 is a random vector in ℝ𝑑 and 𝐶 is a real 𝑑×𝑑 matrix.
Key points:
• The decay depends on the distribution of 𝑋 and matrix 𝐶
• Two types of distributions are considered: symmetric Weibull-like and Student-like
• Weibull-like tails are handled using Theorem 7.1
• Student-like tails are handled using a change of variable technique and Theorem 5.1
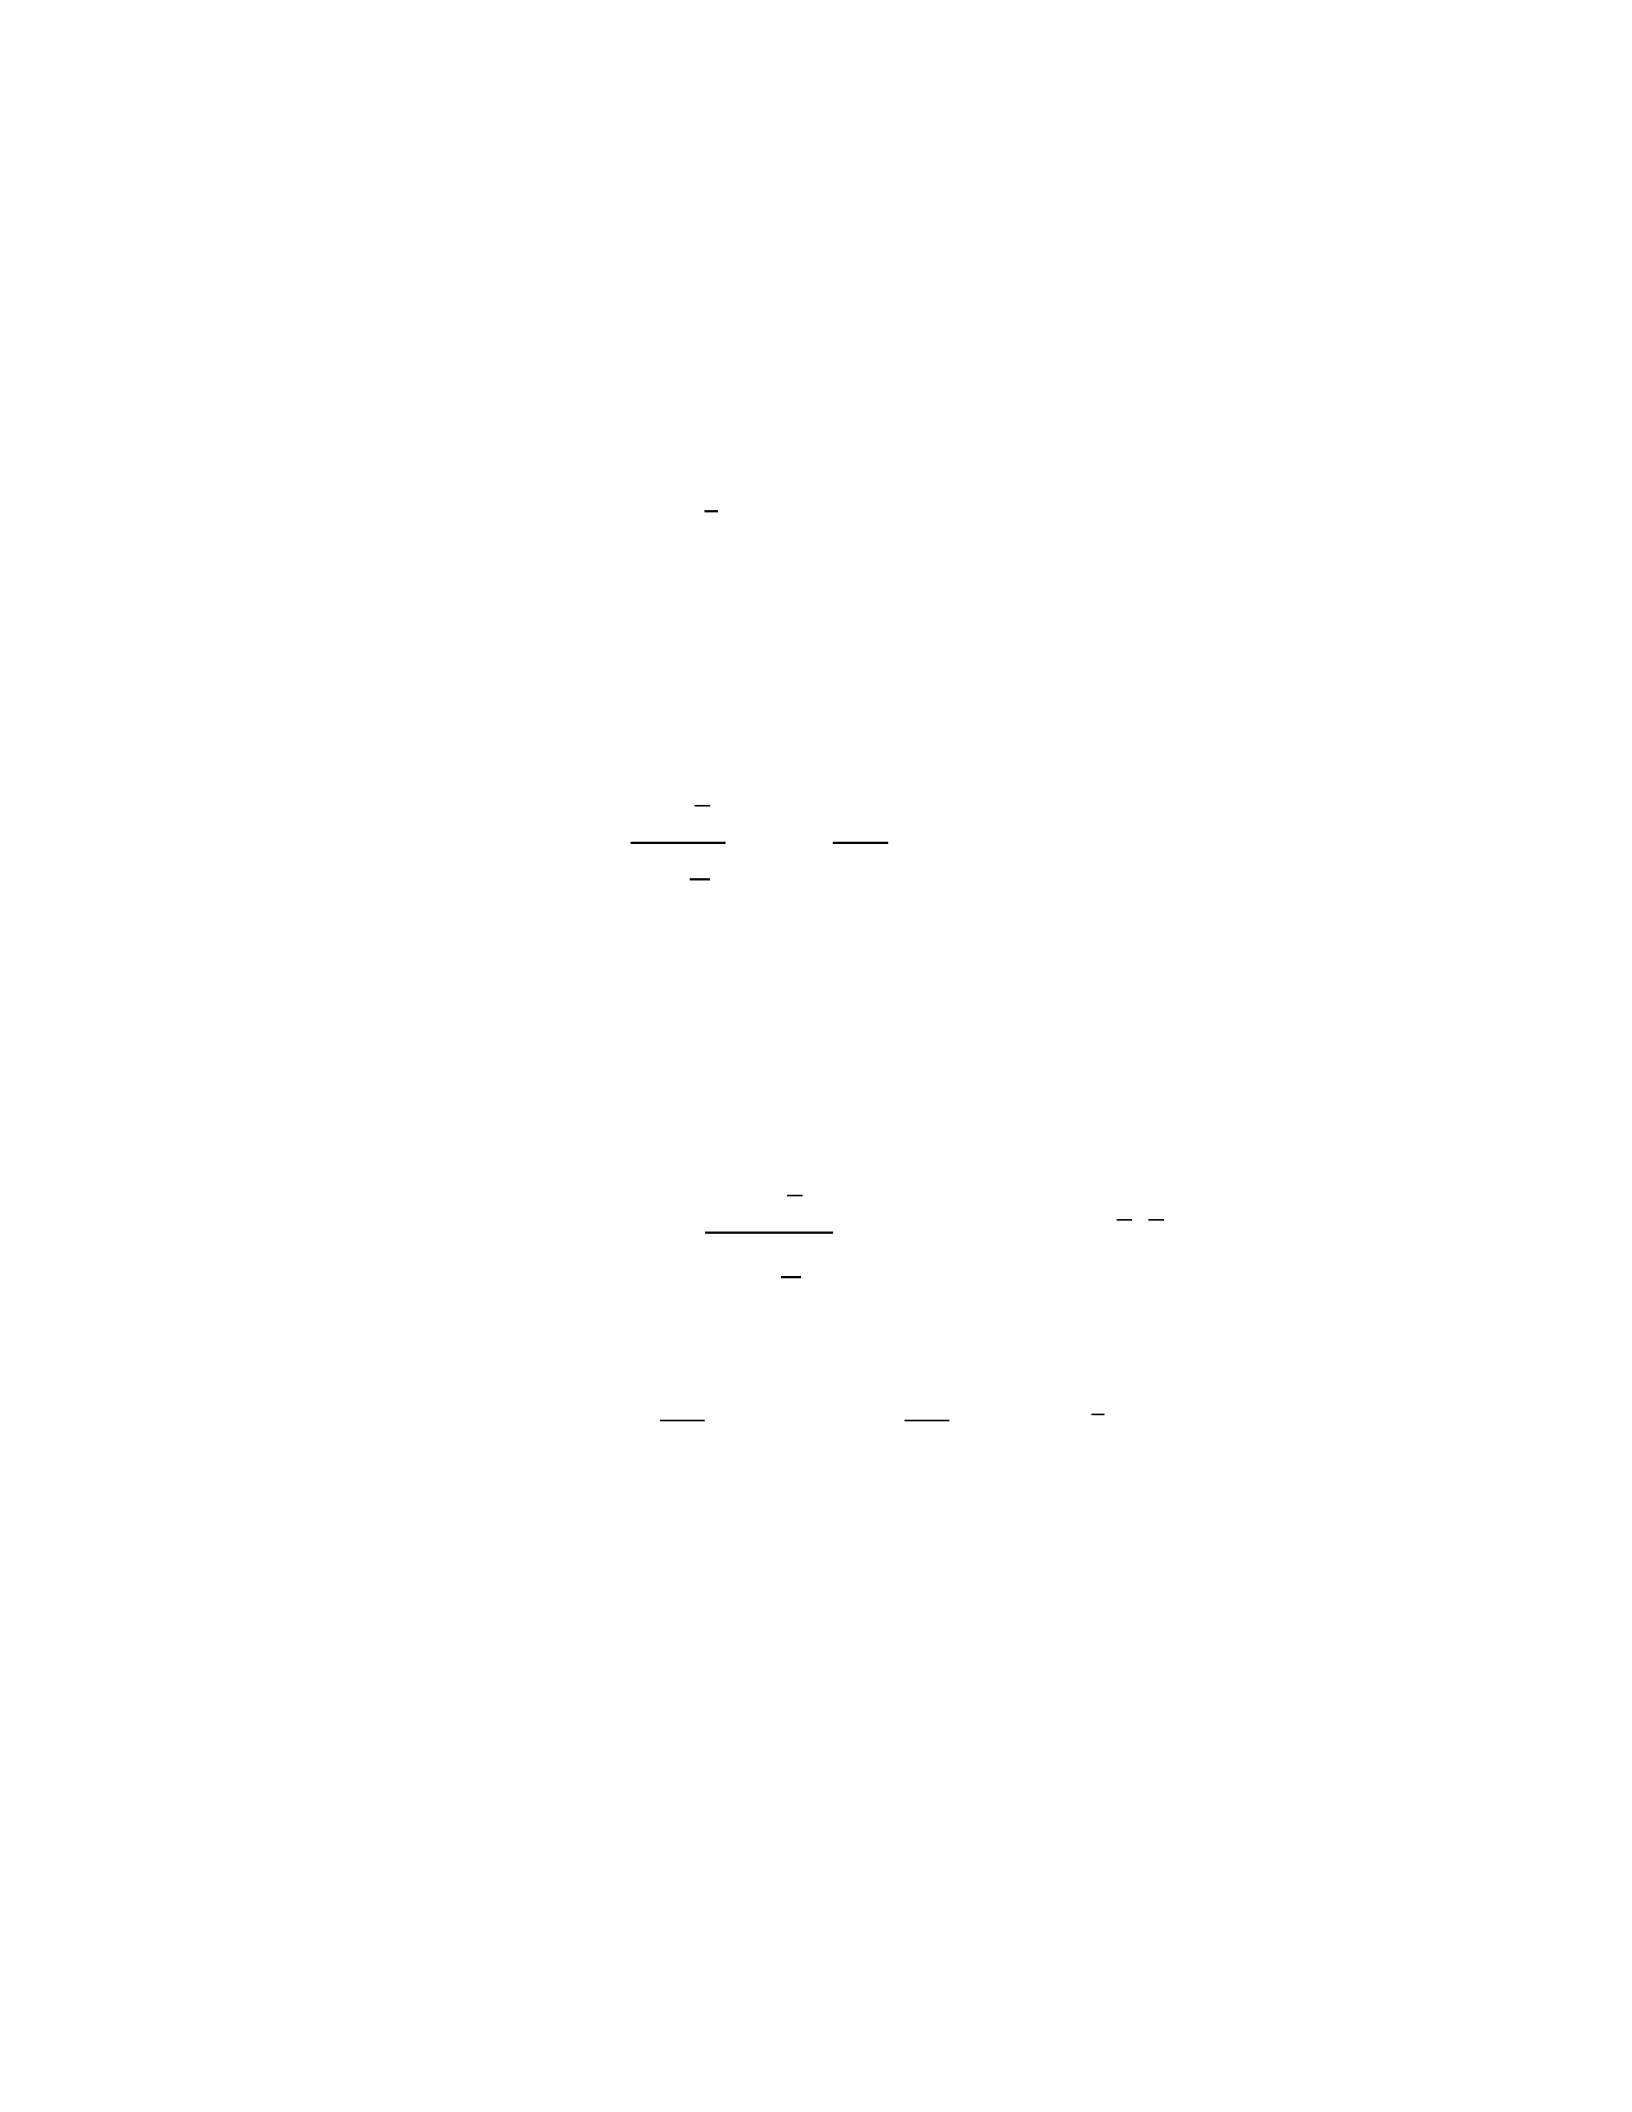
Light Tail Distribution Example
Setup
Consider a random vector 𝑋=(𝑋1,…,𝑋𝑑) in ℝ𝑑 with density 𝑓=𝑒−𝐼, where 𝐼 is a convex,
𝛼-positively homogeneous function on ℝ𝑑.
Important:
• 𝐴𝑡={𝑥∈ℝ𝑑:⟨𝐶𝑥,𝑥⟩>𝑡}=√𝑡𝐴1
• 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}=∫𝑒−𝐼(𝑥)
𝐴𝑡𝑑𝑥
Specific Case
Assume the components 𝑋𝑖 of 𝑋 are i.i.d. with density:
𝑤𝛼(𝑥)=𝛼1−1
𝛼
2𝛤(1
𝛼)exp(−|𝑥|𝛼
𝛼), 𝑥∈ℝ,𝛼>1
Conjecture 8.1.1: If 𝛼≠2 and 𝐶+𝐶𝑇 has no vanishing eigenvalue, then ∑ |𝑥𝑖|𝛼
𝑑
𝑖=1 admits a
finite number of minima in 𝐴1, and det𝐺𝐴1 is non-zero at these minima.
Results
For 𝛼≠2:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 𝛼𝑑−𝑑
𝛼
2𝑑𝛤(1
𝛼)𝑑𝑐1𝑒−𝑡𝛼/2𝐼(𝐴1)𝑡−(𝛼−2)𝑑
4−𝛼
4
where
𝑐1=(2𝜋)𝑑−1
2∑|𝐷𝐼(𝑥)|−𝑑+1
2
𝑥∈𝐷𝐴1(det𝐺𝐴1)−1
2
Note: 𝐷𝐼(𝑥)=(sign(𝑥𝑖)|𝑥𝑖|𝛼−1)1≤𝑖≤𝑑 for 𝛼 >1
Special Case: 𝛼=2
Let 𝜆 be the largest eigenvalue of 𝐶+𝐶𝑇 (assumed positive), and 𝐻={𝑥:(𝐶+𝐶𝑇)𝑥 =𝜆𝑥}
be the associated eigenspace.
Theorem 8.1.2
For 𝛼=2 and 𝜆>0:
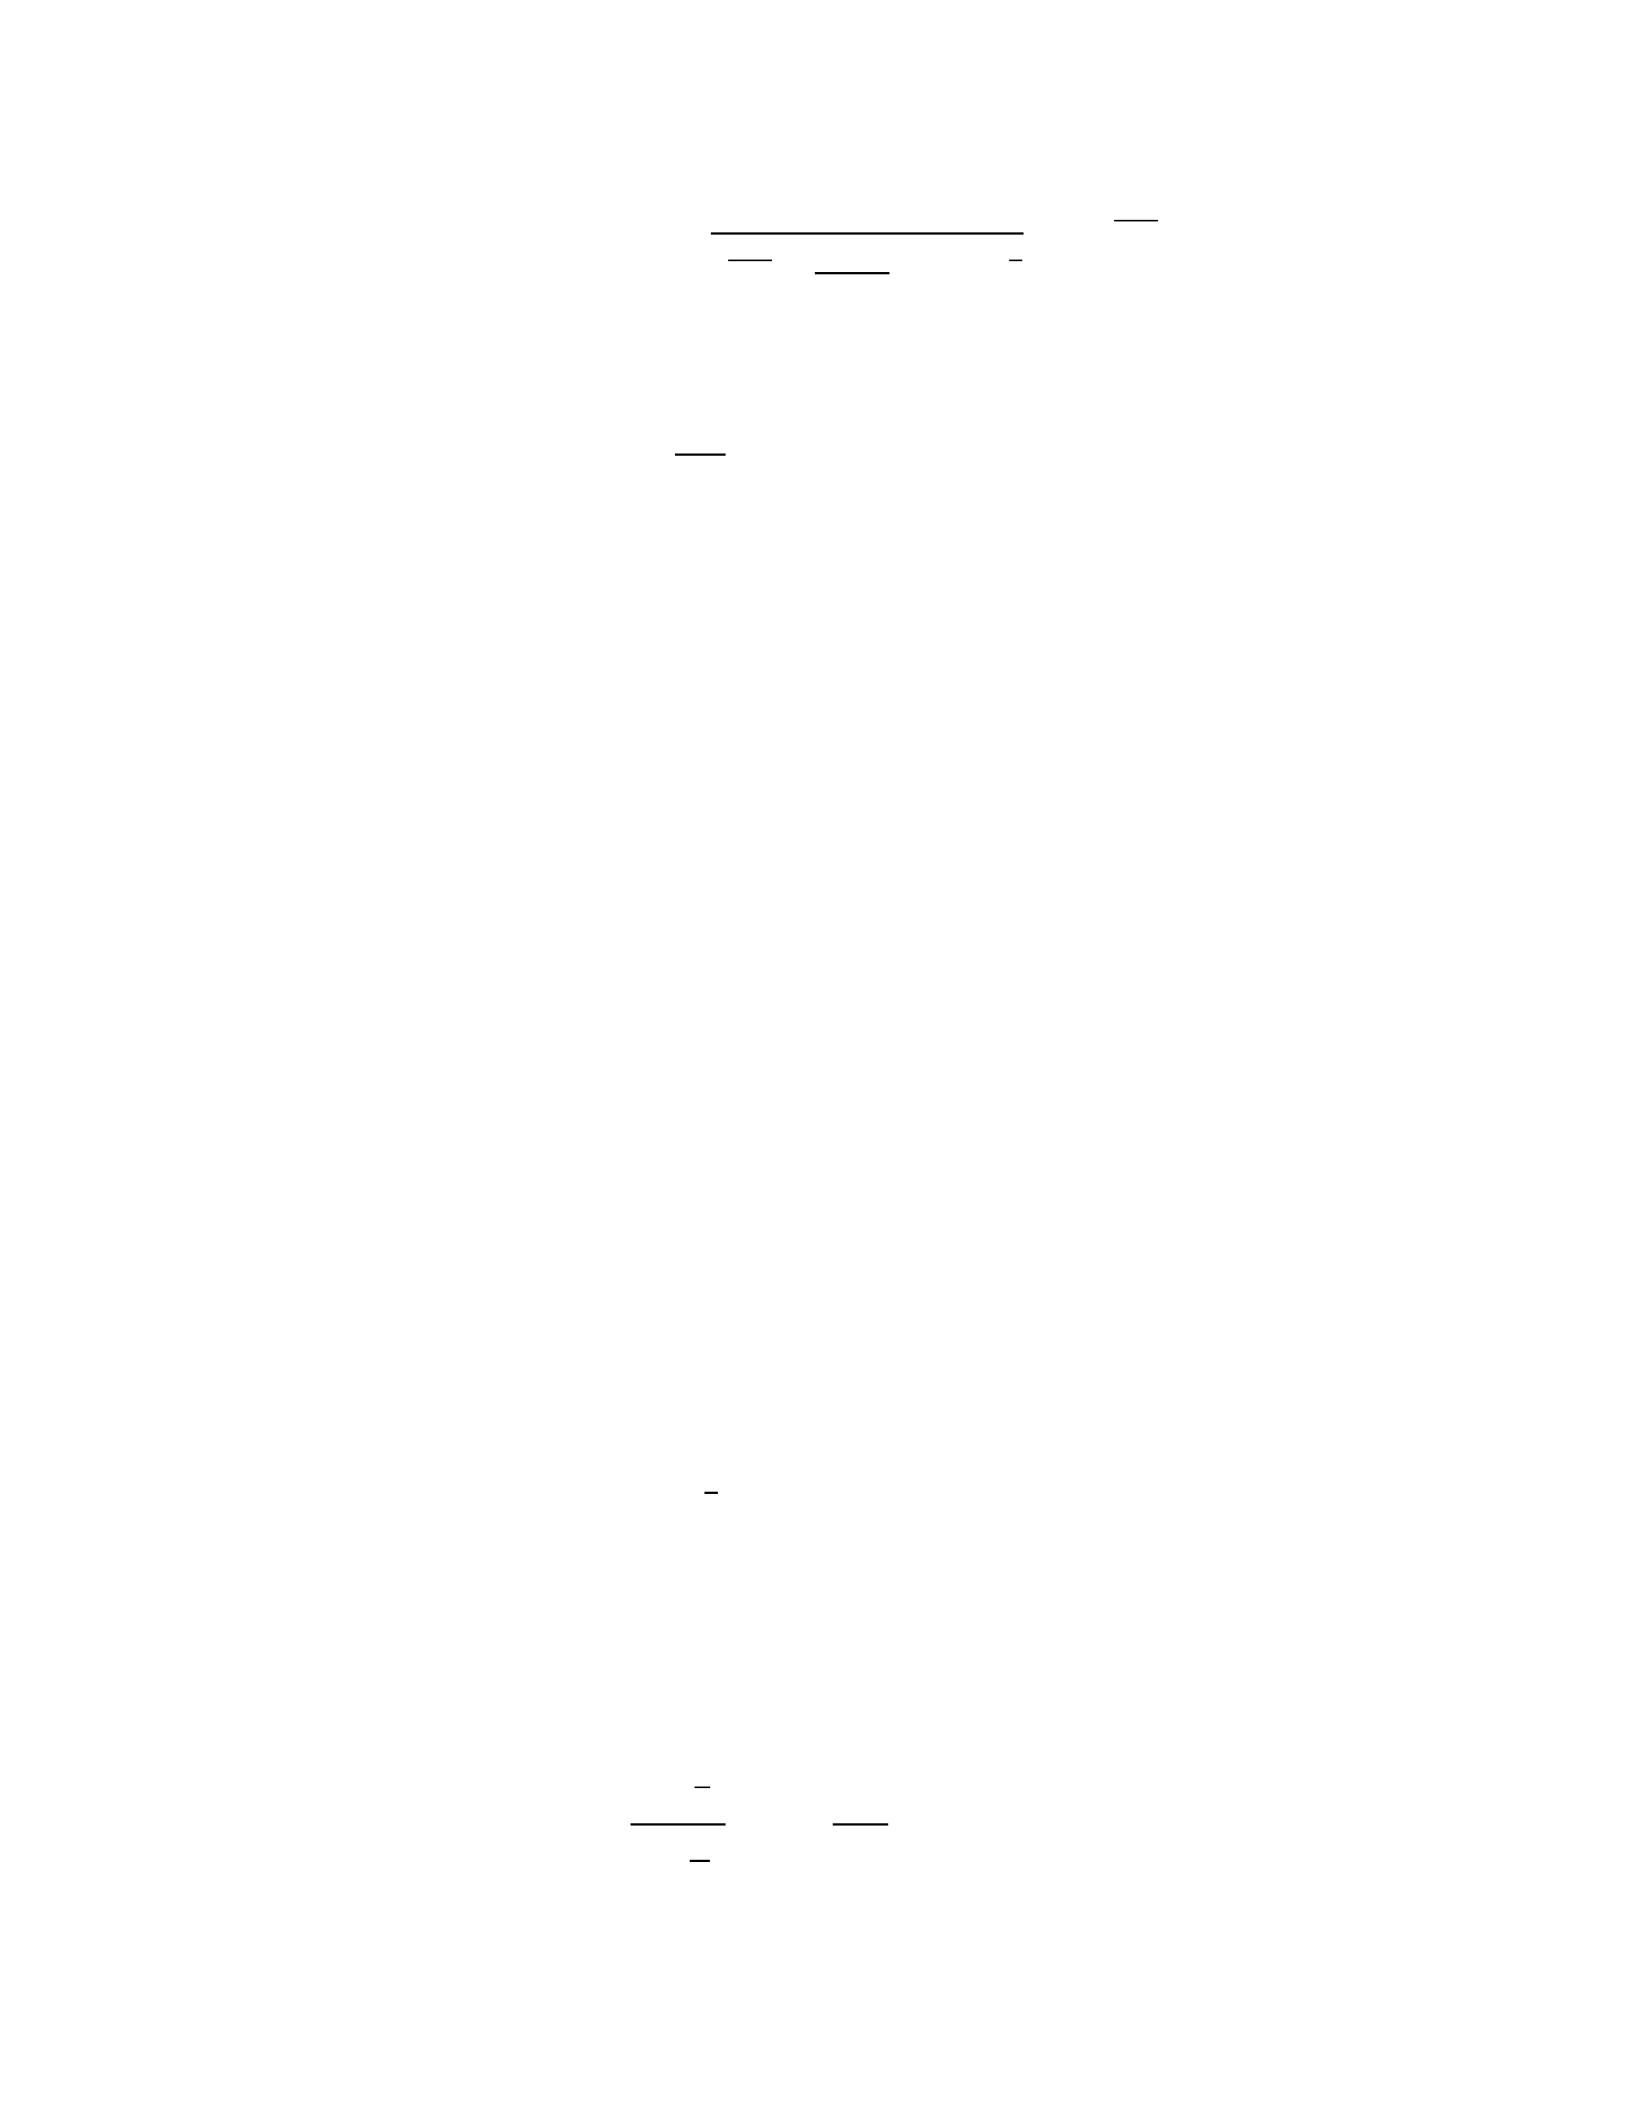
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 1
𝜆𝑘−1
2𝛤(𝑘+1
2)(det𝑀)1
2𝑒−𝑡/𝜆𝑡𝑘−1
2
where 𝑘=dim𝐻−1 and 𝑀 is the compression of 𝐼𝑑−𝜆−1(𝐶+𝐶𝑇) to 𝐻⊥.
Proof outline:
• 𝐷𝐴1 is the sphere of radius √2/𝜆 centered at the origin in 𝐻
• Apply Theorem 7.1
• Calculate 𝐼(𝐴1)=1/𝜆
• Determine 𝐺𝐴1 using second fundamental forms of 𝐼(𝐴1) and ∂𝐴1
These notes discuss the decay of probability 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡} as 𝑡 approaches infinity, where
𝑋 is a random vector in ℝ𝑑 and 𝐶 is a real 𝑑×𝑑 matrix.
Key points:
• The decay depends on the distribution of 𝑋 and matrix 𝐶
• Two types of distributions are considered: symmetric Weibull-like and Student-like
• Weibull-like tails are handled using Theorem 7.1
• Student-like tails are handled using a change of variable technique and Theorem 5.1
Light Tail Distribution Example
Setup
Consider a random vector 𝑋=(𝑋1,…,𝑋𝑑) in ℝ𝑑 with density 𝑓=𝑒−𝐼, where 𝐼 is a convex,
𝛼-positively homogeneous function on ℝ𝑑.
Important:
• 𝐴𝑡={𝑥∈ℝ𝑑:⟨𝐶𝑥,𝑥⟩>𝑡}=√𝑡𝐴1
• 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}=∫𝑒−𝐼(𝑥)
𝐴𝑡𝑑𝑥
Specific Case
Assume the components 𝑋𝑖 of 𝑋 are i.i.d. with density:
𝑤𝛼(𝑥)=𝛼1−1
𝛼
2𝛤(1
𝛼)exp(−|𝑥|𝛼
𝛼), 𝑥∈ℝ,𝛼>1

Conjecture 8.1.1: If 𝛼≠2 and 𝐶+𝐶𝑇 has no vanishing eigenvalue, then ∑ |𝑥𝑖|𝛼
𝑑
𝑖=1 admits a
finite number of minima in 𝐴1, and det𝐺𝐴1 is non-zero at these minima.
Results
For 𝛼≠2:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 𝛼𝑑−𝑑
𝛼
2𝑑𝛤(1
𝛼)𝑑𝑐1𝑒−𝑡𝛼/2𝐼(𝐴1)𝑡−(𝛼−2)𝑑
4−𝛼
4
where
𝑐1=(2𝜋)𝑑−1
2∑|𝐷𝐼(𝑥)|−𝑑+1
2
𝑥∈𝐷𝐴1(det𝐺𝐴1)−1
2
Note: 𝐷𝐼(𝑥)=(sign(𝑥𝑖)|𝑥𝑖|𝛼−1)1≤𝑖≤𝑑 for 𝛼 >1
Special Case: 𝛼=2
Let 𝜆 be the largest eigenvalue of 𝐶+𝐶𝑇 (assumed positive), and 𝐻={𝑥:(𝐶+𝐶𝑇)𝑥 =𝜆𝑥}
be the associated eigenspace.
Theorem 8.1.2
For 𝛼=2 and 𝜆>0:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 1
𝜆𝑘−1
2𝛤(𝑘+1
2)(det𝑀)1
2𝑒−𝑡/𝜆𝑡𝑘−1
2
where 𝑘=dim𝐻−1 and 𝑀 is the compression of 𝐼𝑑−𝜆−1(𝐶+𝐶𝑇) to 𝐻⊥.
Proof outline:
• 𝐷𝐴1 is the sphere of radius √2/𝜆 centered at the origin in 𝐻
• Apply Theorem 7.1
• Calculate 𝐼(𝐴1)=1/𝜆
• Determine 𝐺𝐴1 using second fundamental forms of 𝐼(𝐴1) and ∂𝐴1
These notes discuss the decay of probability 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡} as 𝑡 approaches infinity, where
𝑋 is a random vector in ℝ𝑑 and 𝐶 is a real 𝑑×𝑑 matrix.
Key points:
• The decay depends on the distribution of 𝑋 and matrix 𝐶
• Two types of distributions are considered: symmetric Weibull-like and Student-like
• Weibull-like tails are handled using Theorem 7.1
• Student-like tails are handled using a change of variable technique and Theorem 5.1
Light Tail Distribution Example
Setup
Consider a random vector 𝑋=(𝑋1,…,𝑋𝑑) in ℝ𝑑 with density 𝑓=𝑒−𝐼, where 𝐼 is a convex,
𝛼-positively homogeneous function on ℝ𝑑.
Important:
• 𝐴𝑡={𝑥∈ℝ𝑑:⟨𝐶𝑥,𝑥⟩>𝑡}=√𝑡𝐴1
• 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}=∫𝑒−𝐼(𝑥)
𝐴𝑡𝑑𝑥
Specific Case
Assume the components 𝑋𝑖 of 𝑋 are i.i.d. with density:
𝑤𝛼(𝑥)=𝛼1−1
𝛼
2𝛤(1
𝛼)exp(−|𝑥|𝛼
𝛼), 𝑥∈ℝ,𝛼>1
Conjecture 8.1.1: If 𝛼≠2 and 𝐶+𝐶𝑇 has no vanishing eigenvalue, then ∑ |𝑥𝑖|𝛼
𝑑
𝑖=1 admits a
finite number of minima in 𝐴1, and det𝐺𝐴1 is non-zero at these minima.
Results
For 𝛼≠2:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 𝛼𝑑−𝑑
𝛼
2𝑑𝛤(1
𝛼)𝑑𝑐1𝑒−𝑡𝛼/2𝐼(𝐴1)𝑡−(𝛼−2)𝑑
4−𝛼
4
where
𝑐1=(2𝜋)𝑑−1
2∑|𝐷𝐼(𝑥)|−𝑑+1
2
𝑥∈𝐷𝐴1(det𝐺𝐴1)−1
2
Note: 𝐷𝐼(𝑥)=(sign(𝑥𝑖)|𝑥𝑖|𝛼−1)1≤𝑖≤𝑑 for 𝛼 >1
Special Case: 𝛼=2
Let 𝜆 be the largest eigenvalue of 𝐶+𝐶𝑇 (assumed positive), and 𝐻={𝑥:(𝐶+𝐶𝑇)𝑥 =𝜆𝑥}
be the associated eigenspace.
Theorem 8.1.2
For 𝛼=2 and 𝜆>0:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 1
𝜆𝑘−1
2𝛤(𝑘+1
2)(det𝑀)1
2𝑒−𝑡/𝜆𝑡𝑘−1
2
where 𝑘=dim𝐻−1 and 𝑀 is the compression of 𝐼𝑑−𝜆−1(𝐶+𝐶𝑇) to 𝐻⊥.
Proof outline:
• 𝐷𝐴1 is the sphere of radius √2/𝜆 centered at the origin in 𝐻
• Apply Theorem 7.1
• Calculate 𝐼(𝐴1)=1/𝜆
• Determine 𝐺𝐴1 using second fundamental forms of 𝐼(𝐴1) and ∂𝐴1
These notes discuss the decay of probability 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡} as 𝑡 approaches infinity, where
𝑋 is a random vector in ℝ𝑑 and 𝐶 is a real 𝑑×𝑑 matrix.
Key points:
• The decay depends on the distribution of 𝑋 and matrix 𝐶
• Two types of distributions are considered: symmetric Weibull-like and Student-like
• Weibull-like tails are handled using Theorem 7.1
• Student-like tails are handled using a change of variable technique and Theorem 5.1
Light Tail Distribution Example
Setup
Consider a random vector 𝑋=(𝑋1,…,𝑋𝑑) in ℝ𝑑 with density 𝑓=𝑒−𝐼, where 𝐼 is a convex,
𝛼-positively homogeneous function on ℝ𝑑.
Important:
• 𝐴𝑡={𝑥∈ℝ𝑑:⟨𝐶𝑥,𝑥⟩>𝑡}=√𝑡𝐴1
• 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}=∫𝑒−𝐼(𝑥)
𝐴𝑡𝑑𝑥
Specific Case
Assume the components 𝑋𝑖 of 𝑋 are i.i.d. with density:
𝑤𝛼(𝑥)=𝛼1−1
𝛼
2𝛤(1
𝛼)exp(−|𝑥|𝛼
𝛼), 𝑥∈ℝ,𝛼>1
Conjecture 8.1.1: If 𝛼≠2 and 𝐶+𝐶𝑇 has no vanishing eigenvalue, then ∑ |𝑥𝑖|𝛼
𝑑
𝑖=1 admits a
finite number of minima in 𝐴1, and det𝐺𝐴1 is non-zero at these minima.
Results
For 𝛼≠2:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 𝛼𝑑−𝑑
𝛼
2𝑑𝛤(1
𝛼)𝑑𝑐1𝑒−𝑡𝛼/2𝐼(𝐴1)𝑡−(𝛼−2)𝑑
4−𝛼
4
where
𝑐1=(2𝜋)𝑑−1
2∑|𝐷𝐼(𝑥)|−𝑑+1
2
𝑥∈𝐷𝐴1(det𝐺𝐴1)−1
2
Note: 𝐷𝐼(𝑥)=(sign(𝑥𝑖)|𝑥𝑖|𝛼−1)1≤𝑖≤𝑑 for 𝛼 >1
Special Case: 𝛼=2
Let 𝜆 be the largest eigenvalue of 𝐶+𝐶𝑇 (assumed positive), and 𝐻={𝑥:(𝐶+𝐶𝑇)𝑥 =𝜆𝑥}
be the associated eigenspace.
Theorem 8.1.2
For 𝛼=2 and 𝜆>0:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 1
𝜆𝑘−1
2𝛤(𝑘+1
2)(det𝑀)1
2𝑒−𝑡/𝜆𝑡𝑘−1
2
where 𝑘=dim𝐻−1 and 𝑀 is the compression of 𝐼𝑑−𝜆−1(𝐶+𝐶𝑇) to 𝐻⊥.
Proof outline:
• 𝐷𝐴1 is the sphere of radius √2/𝜆 centered at the origin in 𝐻
• Apply Theorem 7.1
• Calculate 𝐼(𝐴1)=1/𝜆

• Determine 𝐺𝐴1 using second fundamental forms of 𝐼(𝐴1) and ∂𝐴1
These notes discuss the decay of probability 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡} as 𝑡 approaches infinity, where
𝑋 is a random vector in ℝ𝑑 and 𝐶 is a real 𝑑×𝑑 matrix.
Key points:
• The decay depends on the distribution of 𝑋 and matrix 𝐶
• Two types of distributions are considered: symmetric Weibull-like and Student-like
• Weibull-like tails are handled using Theorem 7.1
• Student-like tails are handled using a change of variable technique and Theorem 5.1
Light Tail Distribution Example
Setup
Consider a random vector 𝑋=(𝑋1,…,𝑋𝑑) in ℝ𝑑 with density 𝑓=𝑒−𝐼, where 𝐼 is a convex,
𝛼-positively homogeneous function on ℝ𝑑.
Important:
• 𝐴𝑡={𝑥∈ℝ𝑑:⟨𝐶𝑥,𝑥⟩>𝑡}=√𝑡𝐴1
• 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}=∫𝑒−𝐼(𝑥)
𝐴𝑡𝑑𝑥
Specific Case
Assume the components 𝑋𝑖 of 𝑋 are i.i.d. with density:
𝑤𝛼(𝑥)=𝛼1−1
𝛼
2𝛤(1
𝛼)exp(−|𝑥|𝛼
𝛼), 𝑥∈ℝ,𝛼>1
Conjecture 8.1.1: If 𝛼≠2 and 𝐶+𝐶𝑇 has no vanishing eigenvalue, then ∑ |𝑥𝑖|𝛼
𝑑
𝑖=1 admits a
finite number of minima in 𝐴1, and det𝐺𝐴1 is non-zero at these minima.
Results
For 𝛼≠2:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 𝛼𝑑−𝑑
𝛼
2𝑑𝛤(1
𝛼)𝑑𝑐1𝑒−𝑡𝛼/2𝐼(𝐴1)𝑡−(𝛼−2)𝑑
4−𝛼
4
where
𝑐1=(2𝜋)𝑑−1
2∑|𝐷𝐼(𝑥)|−𝑑+1
2
𝑥∈𝐷𝐴1(det𝐺𝐴1)−1
2
Note: 𝐷𝐼(𝑥)=(sign(𝑥𝑖)|𝑥𝑖|𝛼−1)1≤𝑖≤𝑑 for 𝛼 >1
Special Case: 𝛼=2
Let 𝜆 be the largest eigenvalue of 𝐶+𝐶𝑇 (assumed positive), and 𝐻={𝑥:(𝐶+𝐶𝑇)𝑥 =𝜆𝑥}
be the associated eigenspace.
Theorem 8.1.2
For 𝛼=2 and 𝜆>0:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 1
𝜆𝑘−1
2𝛤(𝑘+1
2)(det𝑀)1
2𝑒−𝑡/𝜆𝑡𝑘−1
2
where 𝑘=dim𝐻−1 and 𝑀 is the compression of 𝐼𝑑−𝜆−1(𝐶+𝐶𝑇) to 𝐻⊥.
Proof outline:
• 𝐷𝐴1 is the sphere of radius √2/𝜆 centered at the origin in 𝐻
• Apply Theorem 7.1
• Calculate 𝐼(𝐴1)=1/𝜆
• Determine 𝐺𝐴1 using second fundamental forms of 𝐼(𝐴1) and ∂𝐴1
These notes discuss the decay of probability 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡} as 𝑡 approaches infinity, where
𝑋 is a random vector in ℝ𝑑 and 𝐶 is a real 𝑑×𝑑 matrix.
Key points:
• The decay depends on the distribution of 𝑋 and matrix 𝐶
• Two types of distributions are considered: symmetric Weibull-like and Student-like
• Weibull-like tails are handled using Theorem 7.1
• Student-like tails are handled using a change of variable technique and Theorem 5.1

Light Tail Distribution Example
Setup
Consider a random vector 𝑋=(𝑋1,…,𝑋𝑑) in ℝ𝑑 with density 𝑓=𝑒−𝐼, where 𝐼 is a convex,
𝛼-positively homogeneous function on ℝ𝑑.
Important:
• 𝐴𝑡={𝑥∈ℝ𝑑:⟨𝐶𝑥,𝑥⟩>𝑡}=√𝑡𝐴1
• 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}=∫𝑒−𝐼(𝑥)
𝐴𝑡𝑑𝑥
Specific Case
Assume the components 𝑋𝑖 of 𝑋 are i.i.d. with density:
𝑤𝛼(𝑥)=𝛼1−1
𝛼
2𝛤(1
𝛼)exp(−|𝑥|𝛼
𝛼), 𝑥∈ℝ,𝛼>1
Conjecture 8.1.1: If 𝛼≠2 and 𝐶+𝐶𝑇 has no vanishing eigenvalue, then ∑ |𝑥𝑖|𝛼
𝑑
𝑖=1 admits a
finite number of minima in 𝐴1, and det𝐺𝐴1 is non-zero at these minima.
Results
For 𝛼≠2:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 𝛼𝑑−𝑑
𝛼
2𝑑𝛤(1
𝛼)𝑑𝑐1𝑒−𝑡𝛼/2𝐼(𝐴1)𝑡−(𝛼−2)𝑑
4−𝛼
4
where
𝑐1=(2𝜋)𝑑−1
2∑|𝐷𝐼(𝑥)|−𝑑+1
2
𝑥∈𝐷𝐴1(det𝐺𝐴1)−1
2
Note: 𝐷𝐼(𝑥)=(sign(𝑥𝑖)|𝑥𝑖|𝛼−1)1≤𝑖≤𝑑 for 𝛼 >1
Special Case: 𝛼=2
Let 𝜆 be the largest eigenvalue of 𝐶+𝐶𝑇 (assumed positive), and 𝐻={𝑥:(𝐶+𝐶𝑇)𝑥 =𝜆𝑥}
be the associated eigenspace.
Theorem 8.1.2
For 𝛼=2 and 𝜆>0:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 1
𝜆𝑘−1
2𝛤(𝑘+1
2)(det𝑀)1
2𝑒−𝑡/𝜆𝑡𝑘−1
2
where 𝑘=dim𝐻−1 and 𝑀 is the compression of 𝐼𝑑−𝜆−1(𝐶+𝐶𝑇) to 𝐻⊥.
Proof outline:
• 𝐷𝐴1 is the sphere of radius √2/𝜆 centered at the origin in 𝐻
• Apply Theorem 7.1
• Calculate 𝐼(𝐴1)=1/𝜆
• Determine 𝐺𝐴1 using second fundamental forms of 𝐼(𝐴1) and ∂𝐴1
These notes discuss the decay of probability 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡} as 𝑡 approaches infinity, where
𝑋 is a random vector in ℝ𝑑 and 𝐶 is a real 𝑑×𝑑 matrix.
Key points:
• The decay depends on the distribution of 𝑋 and matrix 𝐶
• Two types of distributions are considered: symmetric Weibull-like and Student-like
• Weibull-like tails are handled using Theorem 7.1
• Student-like tails are handled using a change of variable technique and Theorem 5.1
Light Tail Distribution Example
Setup
Consider a random vector 𝑋=(𝑋1,…,𝑋𝑑) in ℝ𝑑 with density 𝑓=𝑒−𝐼, where 𝐼 is a convex,
𝛼-positively homogeneous function on ℝ𝑑.
Important:
• 𝐴𝑡={𝑥∈ℝ𝑑:⟨𝐶𝑥,𝑥⟩>𝑡}=√𝑡𝐴1
• 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}=∫𝑒−𝐼(𝑥)
𝐴𝑡𝑑𝑥
Specific Case
Assume the components 𝑋𝑖 of 𝑋 are i.i.d. with density:
𝑤𝛼(𝑥)=𝛼1−1
𝛼
2𝛤(1
𝛼)exp(−|𝑥|𝛼
𝛼), 𝑥∈ℝ,𝛼>1

Conjecture 8.1.1: If 𝛼≠2 and 𝐶+𝐶𝑇 has no vanishing eigenvalue, then ∑ |𝑥𝑖|𝛼
𝑑
𝑖=1 admits a
finite number of minima in 𝐴1, and det𝐺𝐴1 is non-zero at these minima.
Results
For 𝛼≠2:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 𝛼𝑑−𝑑
𝛼
2𝑑𝛤(1
𝛼)𝑑𝑐1𝑒−𝑡𝛼/2𝐼(𝐴1)𝑡−(𝛼−2)𝑑
4−𝛼
4
where
𝑐1=(2𝜋)𝑑−1
2∑|𝐷𝐼(𝑥)|−𝑑+1
2
𝑥∈𝐷𝐴1(det𝐺𝐴1)−1
2
Note: 𝐷𝐼(𝑥)=(sign(𝑥𝑖)|𝑥𝑖|𝛼−1)1≤𝑖≤𝑑 for 𝛼 >1
Special Case: 𝛼=2
Let 𝜆 be the largest eigenvalue of 𝐶+𝐶𝑇 (assumed positive), and 𝐻={𝑥:(𝐶+𝐶𝑇)𝑥 =𝜆𝑥}
be the associated eigenspace.
Theorem 8.1.2
For 𝛼=2 and 𝜆>0:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 1
𝜆𝑘−1
2𝛤(𝑘+1
2)(det𝑀)1
2𝑒−𝑡/𝜆𝑡𝑘−1
2
where 𝑘=dim𝐻−1 and 𝑀 is the compression of 𝐼𝑑−𝜆−1(𝐶+𝐶𝑇) to 𝐻⊥.
Proof outline:
• 𝐷𝐴1 is the sphere of radius √2/𝜆 centered at the origin in 𝐻
• Apply Theorem 7.1
• Calculate 𝐼(𝐴1)=1/𝜆
• Determine 𝐺𝐴1 using second fundamental forms of 𝐼(𝐴1) and ∂𝐴1
These notes discuss the decay of probability 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡} as 𝑡 approaches infinity, where
𝑋 is a random vector in ℝ𝑑 and 𝐶 is a real 𝑑×𝑑 matrix.
Key points:
• The decay depends on the distribution of 𝑋 and matrix 𝐶
• Two types of distributions are considered: symmetric Weibull-like and Student-like
• Weibull-like tails are handled using Theorem 7.1
• Student-like tails are handled using a change of variable technique and Theorem 5.1
Light Tail Distribution Example
Setup
Consider a random vector 𝑋=(𝑋1,…,𝑋𝑑) in ℝ𝑑 with density 𝑓=𝑒−𝐼, where 𝐼 is a convex,
𝛼-positively homogeneous function on ℝ𝑑.
Important:
• 𝐴𝑡={𝑥∈ℝ𝑑:⟨𝐶𝑥,𝑥⟩>𝑡}=√𝑡𝐴1
• 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}=∫𝑒−𝐼(𝑥)
𝐴𝑡𝑑𝑥
Specific Case
Assume the components 𝑋𝑖 of 𝑋 are i.i.d. with density:
𝑤𝛼(𝑥)=𝛼1−1
𝛼
2𝛤(1
𝛼)exp(−|𝑥|𝛼
𝛼), 𝑥∈ℝ,𝛼>1
Conjecture 8.1.1: If 𝛼≠2 and 𝐶+𝐶𝑇 has no vanishing eigenvalue, then ∑ |𝑥𝑖|𝛼
𝑑
𝑖=1 admits a
finite number of minima in 𝐴1, and det𝐺𝐴1 is non-zero at these minima.
Results
For 𝛼≠2:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 𝛼𝑑−𝑑
𝛼
2𝑑𝛤(1
𝛼)𝑑𝑐1𝑒−𝑡𝛼/2𝐼(𝐴1)𝑡−(𝛼−2)𝑑
4−𝛼
4
where
𝑐1=(2𝜋)𝑑−1
2∑|𝐷𝐼(𝑥)|−𝑑+1
2
𝑥∈𝐷𝐴1(det𝐺𝐴1)−1
2
Note: 𝐷𝐼(𝑥)=(sign(𝑥𝑖)|𝑥𝑖|𝛼−1)1≤𝑖≤𝑑 for 𝛼 >1
Special Case: 𝛼=2
Let 𝜆 be the largest eigenvalue of 𝐶+𝐶𝑇 (assumed positive), and 𝐻={𝑥:(𝐶+𝐶𝑇)𝑥 =𝜆𝑥}
be the associated eigenspace.
Theorem 8.1.2
For 𝛼=2 and 𝜆>0:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 1
𝜆𝑘−1
2𝛤(𝑘+1
2)(det𝑀)1
2𝑒−𝑡/𝜆𝑡𝑘−1
2
where 𝑘=dim𝐻−1 and 𝑀 is the compression of 𝐼𝑑−𝜆−1(𝐶+𝐶𝑇) to 𝐻⊥.
Proof outline:
• 𝐷𝐴1 is the sphere of radius √2/𝜆 centered at the origin in 𝐻
• Apply Theorem 7.1
• Calculate 𝐼(𝐴1)=1/𝜆
• Determine 𝐺𝐴1 using second fundamental forms of 𝐼(𝐴1) and ∂𝐴1
These notes discuss the decay of probability 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡} as 𝑡 approaches infinity, where
𝑋 is a random vector in ℝ𝑑 and 𝐶 is a real 𝑑×𝑑 matrix.
Key points:
• The decay depends on the distribution of 𝑋 and matrix 𝐶
• Two types of distributions are considered: symmetric Weibull-like and Student-like
• Weibull-like tails are handled using Theorem 7.1
• Student-like tails are handled using a change of variable technique and Theorem 5.1
Light Tail Distribution Example
Setup
Consider a random vector 𝑋=(𝑋1,…,𝑋𝑑) in ℝ𝑑 with density 𝑓=𝑒−𝐼, where 𝐼 is a convex,
𝛼-positively homogeneous function on ℝ𝑑.
Important:
• 𝐴𝑡={𝑥∈ℝ𝑑:⟨𝐶𝑥,𝑥⟩>𝑡}=√𝑡𝐴1
• 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}=∫𝑒−𝐼(𝑥)
𝐴𝑡𝑑𝑥

Specific Case
Assume the components 𝑋𝑖 of 𝑋 are i.i.d. with density:
𝑤𝛼(𝑥)=𝛼1−1
𝛼
2𝛤(1
𝛼)exp(−|𝑥|𝛼
𝛼), 𝑥∈ℝ,𝛼>1
Conjecture 8.1.1: If 𝛼≠2 and 𝐶+𝐶𝑇 has no vanishing eigenvalue, then ∑ |𝑥𝑖|𝛼
𝑑
𝑖=1 admits a
finite number of minima in 𝐴1, and det𝐺𝐴1 is non-zero at these minima.
Results
For 𝛼≠2:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 𝛼𝑑−𝑑
𝛼
2𝑑𝛤(1
𝛼)𝑑𝑐1𝑒−𝑡𝛼/2𝐼(𝐴1)𝑡−(𝛼−2)𝑑
4−𝛼
4
where
𝑐1=(2𝜋)𝑑−1
2∑|𝐷𝐼(𝑥)|−𝑑+1
2
𝑥∈𝐷𝐴1(det𝐺𝐴1)−1
2
Note: 𝐷𝐼(𝑥)=(sign(𝑥𝑖)|𝑥𝑖|𝛼−1)1≤𝑖≤𝑑 for 𝛼 >1
Special Case: 𝛼=2
Let 𝜆 be the largest eigenvalue of 𝐶+𝐶𝑇 (assumed positive), and 𝐻={𝑥:(𝐶+𝐶𝑇)𝑥 =𝜆𝑥}
be the associated eigenspace.
Theorem 8.1.2
For 𝛼=2 and 𝜆>0:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 1
𝜆𝑘−1
2𝛤(𝑘+1
2)(det𝑀)1
2𝑒−𝑡/𝜆𝑡𝑘−1
2
where 𝑘=dim𝐻−1 and 𝑀 is the compression of 𝐼𝑑−𝜆−1(𝐶+𝐶𝑇) to 𝐻⊥.
Proof outline:
• 𝐷𝐴1 is the sphere of radius √2/𝜆 centered at the origin in 𝐻
• Apply Theorem 7.1
• Calculate 𝐼(𝐴1)=1/𝜆

• Determine 𝐺𝐴1 using second fundamental forms of 𝐼(𝐴1) and ∂𝐴1
These notes discuss the decay of probability 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡} as 𝑡 approaches infinity, where
𝑋 is a random vector in ℝ𝑑 and 𝐶 is a real 𝑑×𝑑 matrix.
Key points:
• The decay depends on the distribution of 𝑋 and matrix 𝐶
• Two types of distributions are considered: symmetric Weibull-like and Student-like
• Weibull-like tails are handled using Theorem 7.1
• Student-like tails are handled using a change of variable technique and Theorem 5.1
Light Tail Distribution Example
Setup
Consider a random vector 𝑋=(𝑋1,…,𝑋𝑑) in ℝ𝑑 with density 𝑓=𝑒−𝐼, where 𝐼 is a convex,
𝛼-positively homogeneous function on ℝ𝑑.
Important:
• 𝐴𝑡={𝑥∈ℝ𝑑:⟨𝐶𝑥,𝑥⟩>𝑡}=√𝑡𝐴1
• 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}=∫𝑒−𝐼(𝑥)
𝐴𝑡𝑑𝑥
Specific Case
Assume the components 𝑋𝑖 of 𝑋 are i.i.d. with density:
𝑤𝛼(𝑥)=𝛼1−1
𝛼
2𝛤(1
𝛼)exp(−|𝑥|𝛼
𝛼), 𝑥∈ℝ,𝛼>1
Conjecture 8.1.1: If 𝛼≠2 and 𝐶+𝐶𝑇 has no vanishing eigenvalue, then ∑ |𝑥𝑖|𝛼
𝑑
𝑖=1 admits a
finite number of minima in 𝐴1, and det𝐺𝐴1 is non-zero at these minima.
Results
For 𝛼≠2:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 𝛼𝑑−𝑑
𝛼
2𝑑𝛤(1
𝛼)𝑑𝑐1𝑒−𝑡𝛼/2𝐼(𝐴1)𝑡−(𝛼−2)𝑑
4−𝛼
4
where

𝑐1=(2𝜋)𝑑−1
2∑|𝐷𝐼(𝑥)|−𝑑+1
2
𝑥∈𝐷𝐴1(det𝐺𝐴1)−1
2
Note: 𝐷𝐼(𝑥)=(sign(𝑥𝑖)|𝑥𝑖|𝛼−1)1≤𝑖≤𝑑 for 𝛼 >1
Special Case: 𝛼=2
Let 𝜆 be the largest eigenvalue of 𝐶+𝐶𝑇 (assumed positive), and 𝐻={𝑥:(𝐶+𝐶𝑇)𝑥 =𝜆𝑥}
be the associated eigenspace.
Theorem 8.1.2
For 𝛼=2 and 𝜆>0:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 1
𝜆𝑘−1
2𝛤(𝑘+1
2)(det𝑀)1
2𝑒−𝑡/𝜆𝑡𝑘−1
2
where 𝑘=dim𝐻−1 and 𝑀 is the compression of 𝐼𝑑−𝜆−1(𝐶+𝐶𝑇) to 𝐻⊥.
Proof outline:
• 𝐷𝐴1 is the sphere of radius √2/𝜆 centered at the origin in 𝐻
• Apply Theorem 7.1
• Calculate 𝐼(𝐴1)=1/𝜆
• Determine 𝐺𝐴1 using second fundamental forms of 𝐼(𝐴1) and ∂𝐴1
These notes discuss the decay of probability 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡} as 𝑡 approaches infinity, where
𝑋 is a random vector in ℝ𝑑 and 𝐶 is a real 𝑑×𝑑 matrix.
Key points:
• The decay depends on the distribution of 𝑋 and matrix 𝐶
• Two types of distributions are considered: symmetric Weibull-like and Student-like
• Weibull-like tails are handled using Theorem 7.1
• Student-like tails are handled using a change of variable technique and Theorem 5.1

Light Tail Distribution Example
Setup
Consider a random vector 𝑋=(𝑋1,…,𝑋𝑑) in ℝ𝑑 with density 𝑓=𝑒−𝐼, where 𝐼 is a convex,
𝛼-positively homogeneous function on ℝ𝑑.
Important:
• 𝐴𝑡={𝑥∈ℝ𝑑:⟨𝐶𝑥,𝑥⟩>𝑡}=√𝑡𝐴1
• 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}=∫𝑒−𝐼(𝑥)
𝐴𝑡𝑑𝑥
Specific Case
Assume the components 𝑋𝑖 of 𝑋 are i.i.d. with density:
𝑤𝛼(𝑥)=𝛼1−1
𝛼
2𝛤(1
𝛼)exp(−|𝑥|𝛼
𝛼), 𝑥∈ℝ,𝛼>1
Conjecture 8.1.1: If 𝛼≠2 and 𝐶+𝐶𝑇 has no vanishing eigenvalue, then ∑ |𝑥𝑖|𝛼
𝑑
𝑖=1 admits a
finite number of minima in 𝐴1, and det𝐺𝐴1 is non-zero at these minima.
Results
For 𝛼≠2:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 𝛼𝑑−𝑑
𝛼
2𝑑𝛤(1
𝛼)𝑑𝑐1𝑒−𝑡𝛼/2𝐼(𝐴1)𝑡−(𝛼−2)𝑑
4−𝛼
4
where
𝑐1=(2𝜋)𝑑−1
2∑|𝐷𝐼(𝑥)|−𝑑+1
2
𝑥∈𝐷𝐴1(det𝐺𝐴1)−1
2
Note: 𝐷𝐼(𝑥)=(sign(𝑥𝑖)|𝑥𝑖|𝛼−1)1≤𝑖≤𝑑 for 𝛼 >1
Special Case: 𝛼=2
Let 𝜆 be the largest eigenvalue of 𝐶+𝐶𝑇 (assumed positive), and 𝐻={𝑥:(𝐶+𝐶𝑇)𝑥 =𝜆𝑥}
be the associated eigenspace.
Theorem 8.1.2
For 𝛼=2 and 𝜆>0:

𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 1
𝜆𝑘−1
2𝛤(𝑘+1
2)(det𝑀)1
2𝑒−𝑡/𝜆𝑡𝑘−1
2
where 𝑘=dim𝐻−1 and 𝑀 is the compression of 𝐼𝑑−𝜆−1(𝐶+𝐶𝑇) to 𝐻⊥.
Proof outline:
• 𝐷𝐴1 is the sphere of radius √2/𝜆 centered at the origin in 𝐻
• Apply Theorem 7.1
• Calculate 𝐼(𝐴1)=1/𝜆
• Determine 𝐺𝐴1 using second fundamental forms of 𝐼(𝐴1) and ∂𝐴1
These notes discuss the decay of probability 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡} as 𝑡 approaches infinity, where
𝑋 is a random vector in ℝ𝑑 and 𝐶 is a real 𝑑×𝑑 matrix.
Key points:
• The decay depends on the distribution of 𝑋 and matrix 𝐶
• Two types of distributions are considered: symmetric Weibull-like and Student-like
• Weibull-like tails are handled using Theorem 7.1
• Student-like tails are handled using a change of variable technique and Theorem 5.1
Light Tail Distribution Example
Setup
Consider a random vector 𝑋=(𝑋1,…,𝑋𝑑) in ℝ𝑑 with density 𝑓=𝑒−𝐼, where 𝐼 is a convex,
𝛼-positively homogeneous function on ℝ𝑑.
Important:
• 𝐴𝑡={𝑥∈ℝ𝑑:⟨𝐶𝑥,𝑥⟩>𝑡}=√𝑡𝐴1
• 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}=∫𝑒−𝐼(𝑥)
𝐴𝑡𝑑𝑥
Specific Case
Assume the components 𝑋𝑖 of 𝑋 are i.i.d. with density:
𝑤𝛼(𝑥)=𝛼1−1
𝛼
2𝛤(1
𝛼)exp(−|𝑥|𝛼
𝛼), 𝑥∈ℝ,𝛼>1

Conjecture 8.1.1: If 𝛼≠2 and 𝐶+𝐶𝑇 has no vanishing eigenvalue, then ∑ |𝑥𝑖|𝛼
𝑑
𝑖=1 admits a
finite number of minima in 𝐴1, and det𝐺𝐴1 is non-zero at these minima.
Results
For 𝛼≠2:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 𝛼𝑑−𝑑
𝛼
2𝑑𝛤(1
𝛼)𝑑𝑐1𝑒−𝑡𝛼/2𝐼(𝐴1)𝑡−(𝛼−2)𝑑
4−𝛼
4
where
𝑐1=(2𝜋)𝑑−1
2∑|𝐷𝐼(𝑥)|−𝑑+1
2
𝑥∈𝐷𝐴1(det𝐺𝐴1)−1
2
Note: 𝐷𝐼(𝑥)=(sign(𝑥𝑖)|𝑥𝑖|𝛼−1)1≤𝑖≤𝑑 for 𝛼 >1
Special Case: 𝛼=2
Let 𝜆 be the largest eigenvalue of 𝐶+𝐶𝑇 (assumed positive), and 𝐻={𝑥:(𝐶+𝐶𝑇)𝑥 =𝜆𝑥}
be the associated eigenspace.
Theorem 8.1.2
For 𝛼=2 and 𝜆>0:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 1
𝜆𝑘−1
2𝛤(𝑘+1
2)(det𝑀)1
2𝑒−𝑡/𝜆𝑡𝑘−1
2
where 𝑘=dim𝐻−1 and 𝑀 is the compression of 𝐼𝑑−𝜆−1(𝐶+𝐶𝑇) to 𝐻⊥.
Proof outline:
• 𝐷𝐴1 is the sphere of radius √2/𝜆 centered at the origin in 𝐻
• Apply Theorem 7.1
• Calculate 𝐼(𝐴1)=1/𝜆
• Determine 𝐺𝐴1 using second fundamental forms of 𝐼(𝐴1) and ∂𝐴1
These notes discuss the decay of probability 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡} as 𝑡 approaches infinity, where
𝑋 is a random vector in ℝ𝑑 and 𝐶 is a real 𝑑×𝑑 matrix.
Key points:
• The decay depends on the distribution of 𝑋 and matrix 𝐶

• Two types of distributions are considered: symmetric Weibull-like and Student-like
• Weibull-like tails are handled using Theorem 7.1
• Student-like tails are handled using a change of variable technique and Theorem 5.1
Light Tail Distribution Example
Setup
Consider a random vector 𝑋=(𝑋1,…,𝑋𝑑) in ℝ𝑑 with density 𝑓=𝑒−𝐼, where 𝐼 is a convex,
𝛼-positively homogeneous function on ℝ𝑑.
Important:
• 𝐴𝑡={𝑥∈ℝ𝑑:⟨𝐶𝑥,𝑥⟩>𝑡}=√𝑡𝐴1
• 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}=∫𝑒−𝐼(𝑥)
𝐴𝑡𝑑𝑥
Specific Case
Assume the components 𝑋𝑖 of 𝑋 are i.i.d. with density:
𝑤𝛼(𝑥)=𝛼1−1
𝛼
2𝛤(1
𝛼)exp(−|𝑥|𝛼
𝛼), 𝑥∈ℝ,𝛼>1
Conjecture 8.1.1: If 𝛼≠2 and 𝐶+𝐶𝑇 has no vanishing eigenvalue, then ∑ |𝑥𝑖|𝛼
𝑑
𝑖=1 admits a
finite number of minima in 𝐴1, and det𝐺𝐴1 is non-zero at these minima.
Results
For 𝛼≠2:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 𝛼𝑑−𝑑
𝛼
2𝑑𝛤(1
𝛼)𝑑𝑐1𝑒−𝑡𝛼/2𝐼(𝐴1)𝑡−(𝛼−2)𝑑
4−𝛼
4
where
𝑐1=(2𝜋)𝑑−1
2∑|𝐷𝐼(𝑥)|−𝑑+1
2
𝑥∈𝐷𝐴1(det𝐺𝐴1)−1
2
Note: 𝐷𝐼(𝑥)=(sign(𝑥𝑖)|𝑥𝑖|𝛼−1)1≤𝑖≤𝑑 for 𝛼 >1

Special Case: 𝛼=2
Let 𝜆 be the largest eigenvalue of 𝐶+𝐶𝑇 (assumed positive), and 𝐻={𝑥:(𝐶+𝐶𝑇)𝑥 =𝜆𝑥}
be the associated eigenspace.
Theorem 8.1.2
For 𝛼=2 and 𝜆>0:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 1
𝜆𝑘−1
2𝛤(𝑘+1
2)(det𝑀)1
2𝑒−𝑡/𝜆𝑡𝑘−1
2
where 𝑘=dim𝐻−1 and 𝑀 is the compression of 𝐼𝑑−𝜆−1(𝐶+𝐶𝑇) to 𝐻⊥.
Proof outline:
• 𝐷𝐴1 is the sphere of radius √2/𝜆 centered at the origin in 𝐻
• Apply Theorem 7.1
• Calculate 𝐼(𝐴1)=1/𝜆
• Determine 𝐺𝐴1 using second fundamental forms of 𝐼(𝐴1) and ∂𝐴1
These notes discuss the decay of probability 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡} as 𝑡 approaches infinity, where
𝑋 is a random vector in ℝ𝑑 and 𝐶 is a real 𝑑×𝑑 matrix.
Key points:
• The decay depends on the distribution of 𝑋 and matrix 𝐶
• Two types of distributions are considered: symmetric Weibull-like and Student-like
• Weibull-like tails are handled using Theorem 7.1
• Student-like tails are handled using a change of variable technique and Theorem 5.1
Light Tail Distribution Example
Setup
Consider a random vector 𝑋=(𝑋1,…,𝑋𝑑) in ℝ𝑑 with density 𝑓=𝑒−𝐼, where 𝐼 is a convex,
𝛼-positively homogeneous function on ℝ𝑑.
Important:
• 𝐴𝑡={𝑥∈ℝ𝑑:⟨𝐶𝑥,𝑥⟩>𝑡}=√𝑡𝐴1
• 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}=∫𝑒−𝐼(𝑥)
𝐴𝑡𝑑𝑥

Specific Case
Assume the components 𝑋𝑖 of 𝑋 are i.i.d. with density:
𝑤𝛼(𝑥)=𝛼1−1
𝛼
2𝛤(1
𝛼)exp(−|𝑥|𝛼
𝛼), 𝑥∈ℝ,𝛼>1
Conjecture 8.1.1: If 𝛼≠2 and 𝐶+𝐶𝑇 has no vanishing eigenvalue, then ∑ |𝑥𝑖|𝛼
𝑑
𝑖=1 admits a
finite number of minima in 𝐴1, and det𝐺𝐴1 is non-zero at these minima.
Results
For 𝛼≠2:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 𝛼𝑑−𝑑
𝛼
2𝑑𝛤(1
𝛼)𝑑𝑐1𝑒−𝑡𝛼/2𝐼(𝐴1)𝑡−(𝛼−2)𝑑
4−𝛼
4
where
𝑐1=(2𝜋)𝑑−1
2∑|𝐷𝐼(𝑥)|−𝑑+1
2
𝑥∈𝐷𝐴1(det𝐺𝐴1)−1
2
Note: 𝐷𝐼(𝑥)=(sign(𝑥𝑖)|𝑥𝑖|𝛼−1)1≤𝑖≤𝑑 for 𝛼 >1
Special Case: 𝛼=2
Let 𝜆 be the largest eigenvalue of 𝐶+𝐶𝑇 (assumed positive), and 𝐻={𝑥:(𝐶+𝐶𝑇)𝑥 =𝜆𝑥}
be the associated eigenspace.
Theorem 8.1.2
For 𝛼=2 and 𝜆>0:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 1
𝜆𝑘−1
2𝛤(𝑘+1
2)(det𝑀)1
2𝑒−𝑡/𝜆𝑡𝑘−1
2
where 𝑘=dim𝐻−1 and 𝑀 is the compression of 𝐼𝑑−𝜆−1(𝐶+𝐶𝑇) to 𝐻⊥.
Proof outline:
• 𝐷𝐴1 is the sphere of radius √2/𝜆 centered at the origin in 𝐻
• Apply Theorem 7.1
• Calculate 𝐼(𝐴1)=1/𝜆

• Determine 𝐺𝐴1 using second fundamental forms of 𝐼(𝐴1) and ∂𝐴1
These notes discuss the decay of probability 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡} as 𝑡 approaches infinity, where
𝑋 is a random vector in ℝ𝑑 and 𝐶 is a real 𝑑×𝑑 matrix.
Key points:
• The decay depends on the distribution of 𝑋 and matrix 𝐶
• Two types of distributions are considered: symmetric Weibull-like and Student-like
• Weibull-like tails are handled using Theorem 7.1
• Student-like tails are handled using a change of variable technique and Theorem 5.1
Light Tail Distribution Example
Setup
Consider a random vector 𝑋=(𝑋1,…,𝑋𝑑) in ℝ𝑑 with density 𝑓=𝑒−𝐼, where 𝐼 is a convex,
𝛼-positively homogeneous function on ℝ𝑑.
Important:
• 𝐴𝑡={𝑥∈ℝ𝑑:⟨𝐶𝑥,𝑥⟩>𝑡}=√𝑡𝐴1
• 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}=∫𝑒−𝐼(𝑥)
𝐴𝑡𝑑𝑥
Specific Case
Assume the components 𝑋𝑖 of 𝑋 are i.i.d. with density:
𝑤𝛼(𝑥)=𝛼1−1
𝛼
2𝛤(1
𝛼)exp(−|𝑥|𝛼
𝛼), 𝑥∈ℝ,𝛼>1
Conjecture 8.1.1: If 𝛼≠2 and 𝐶+𝐶𝑇 has no vanishing eigenvalue, then ∑ |𝑥𝑖|𝛼
𝑑
𝑖=1 admits a
finite number of minima in 𝐴1, and det𝐺𝐴1 is non-zero at these minima.
Results
For 𝛼≠2:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 𝛼𝑑−𝑑
𝛼
2𝑑𝛤(1
𝛼)𝑑𝑐1𝑒−𝑡𝛼/2𝐼(𝐴1)𝑡−(𝛼−2)𝑑
4−𝛼
4
where

𝑐1=(2𝜋)𝑑−1
2∑|𝐷𝐼(𝑥)|−𝑑+1
2
𝑥∈𝐷𝐴1(det𝐺𝐴1)−1
2
Note: 𝐷𝐼(𝑥)=(sign(𝑥𝑖)|𝑥𝑖|𝛼−1)1≤𝑖≤𝑑 for 𝛼 >1
Special Case: 𝛼=2
Let 𝜆 be the largest eigenvalue of 𝐶+𝐶𝑇 (assumed positive), and 𝐻={𝑥:(𝐶+𝐶𝑇)𝑥 =𝜆𝑥}
be the associated eigenspace.
Theorem 8.1.2
For 𝛼=2 and 𝜆>0:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 1
𝜆𝑘−1
2𝛤(𝑘+1
2)(det𝑀)1
2𝑒−𝑡/𝜆𝑡𝑘−1
2
where 𝑘=dim𝐻−1 and 𝑀 is the compression of 𝐼𝑑−𝜆−1(𝐶+𝐶𝑇) to 𝐻⊥.
Proof outline:
• 𝐷𝐴1 is the sphere of radius √2/𝜆 centered at the origin in 𝐻
• Apply Theorem 7.1
• Calculate 𝐼(𝐴1)=1/𝜆
• Determine 𝐺𝐴1 using second fundamental forms of 𝐼(𝐴1) and ∂𝐴1
These notes discuss the decay of probability 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡} as 𝑡 approaches infinity, where
𝑋 is a random vector in ℝ𝑑 and 𝐶 is a real 𝑑×𝑑 matrix.
Key points:
• The decay depends on the distribution of 𝑋 and matrix 𝐶
• Two types of distributions are considered: symmetric Weibull-like and Student-like
• Weibull-like tails are handled using Theorem 7.1
• Student-like tails are handled using a change of variable technique and Theorem 5.1

Light Tail Distribution Example
Setup
Consider a random vector 𝑋=(𝑋1,…,𝑋𝑑) in ℝ𝑑 with density 𝑓=𝑒−𝐼, where 𝐼 is a convex,
𝛼-positively homogeneous function on ℝ𝑑.
Important:
• 𝐴𝑡={𝑥∈ℝ𝑑:⟨𝐶𝑥,𝑥⟩>𝑡}=√𝑡𝐴1
• 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}=∫𝑒−𝐼(𝑥)
𝐴𝑡𝑑𝑥
Specific Case
Assume the components 𝑋𝑖 of 𝑋 are i.i.d. with density:
𝑤𝛼(𝑥)=𝛼1−1
𝛼
2𝛤(1
𝛼)exp(−|𝑥|𝛼
𝛼), 𝑥∈ℝ,𝛼>1
Conjecture 8.1.1: If 𝛼≠2 and 𝐶+𝐶𝑇 has no vanishing eigenvalue, then ∑ |𝑥𝑖|𝛼
𝑑
𝑖=1 admits a
finite number of minima in 𝐴1, and det𝐺𝐴1 is non-zero at these minima.
Results
For 𝛼≠2:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 𝛼𝑑−𝑑
𝛼
2𝑑𝛤(1
𝛼)𝑑𝑐1𝑒−𝑡𝛼/2𝐼(𝐴1)𝑡−(𝛼−2)𝑑
4−𝛼
4
where
𝑐1=(2𝜋)𝑑−1
2∑|𝐷𝐼(𝑥)|−𝑑+1
2
𝑥∈𝐷𝐴1(det𝐺𝐴1)−1
2
Note: 𝐷𝐼(𝑥)=(sign(𝑥𝑖)|𝑥𝑖|𝛼−1)1≤𝑖≤𝑑 for 𝛼 >1
Special Case: 𝛼=2
Let 𝜆 be the largest eigenvalue of 𝐶+𝐶𝑇 (assumed positive), and 𝐻={𝑥:(𝐶+𝐶𝑇)𝑥 =𝜆𝑥}
be the associated eigenspace.
Theorem 8.1.2
For 𝛼=2 and 𝜆>0:

𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 1
𝜆𝑘−1
2𝛤(𝑘+1
2)(det𝑀)1
2𝑒−𝑡/𝜆𝑡𝑘−1
2
where 𝑘=dim𝐻−1 and 𝑀 is the compression of 𝐼𝑑−𝜆−1(𝐶+𝐶𝑇) to 𝐻⊥.
Proof outline:
• 𝐷𝐴1 is the sphere of radius √2/𝜆 centered at the origin in 𝐻
• Apply Theorem 7.1
• Calculate 𝐼(𝐴1)=1/𝜆
• Determine 𝐺𝐴1 using second fundamental forms of 𝐼(𝐴1) and ∂𝐴1
These notes discuss the decay of probability 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡} as 𝑡 approaches infinity, where
𝑋 is a random vector in ℝ𝑑 and 𝐶 is a real 𝑑×𝑑 matrix.
Key points:
• The decay depends on the distribution of 𝑋 and matrix 𝐶
• Two types of distributions are considered: symmetric Weibull-like and Student-like
• Weibull-like tails are handled using Theorem 7.1
• Student-like tails are handled using a change of variable technique and Theorem 5.1
Light Tail Distribution Example
Setup
Consider a random vector 𝑋=(𝑋1,…,𝑋𝑑) in ℝ𝑑 with density 𝑓=𝑒−𝐼, where 𝐼 is a convex,
𝛼-positively homogeneous function on ℝ𝑑.
Important:
• 𝐴𝑡={𝑥∈ℝ𝑑:⟨𝐶𝑥,𝑥⟩>𝑡}=√𝑡𝐴1
• 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}=∫𝑒−𝐼(𝑥)
𝐴𝑡𝑑𝑥
Specific Case
Assume the components 𝑋𝑖 of 𝑋 are i.i.d. with density:
𝑤𝛼(𝑥)=𝛼1−1
𝛼
2𝛤(1
𝛼)exp(−|𝑥|𝛼
𝛼), 𝑥∈ℝ,𝛼>1

Conjecture 8.1.1: If 𝛼≠2 and 𝐶+𝐶𝑇 has no vanishing eigenvalue, then ∑ |𝑥𝑖|𝛼
𝑑
𝑖=1 admits a
finite number of minima in 𝐴1, and det𝐺𝐴1 is non-zero at these minima.
Results
For 𝛼≠2:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 𝛼𝑑−𝑑
𝛼
2𝑑𝛤(1
𝛼)𝑑𝑐1𝑒−𝑡𝛼/2𝐼(𝐴1)𝑡−(𝛼−2)𝑑
4−𝛼
4
where
𝑐1=(2𝜋)𝑑−1
2∑|𝐷𝐼(𝑥)|−𝑑+1
2
𝑥∈𝐷𝐴1(det𝐺𝐴1)−1
2
Note: 𝐷𝐼(𝑥)=(sign(𝑥𝑖)|𝑥𝑖|𝛼−1)1≤𝑖≤𝑑 for 𝛼 >1
Special Case: 𝛼=2
Let 𝜆 be the largest eigenvalue of 𝐶+𝐶𝑇 (assumed positive), and 𝐻={𝑥:(𝐶+𝐶𝑇)𝑥 =𝜆𝑥}
be the associated eigenspace.
Theorem 8.1.2
For 𝛼=2 and 𝜆>0:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 1
𝜆𝑘−1
2𝛤(𝑘+1
2)(det𝑀)1
2𝑒−𝑡/𝜆𝑡𝑘−1
2
where 𝑘=dim𝐻−1 and 𝑀 is the compression of 𝐼𝑑−𝜆−1(𝐶+𝐶𝑇) to 𝐻⊥.
Proof outline:
• 𝐷𝐴1 is the sphere of radius √2/𝜆 centered at the origin in 𝐻
• Apply Theorem 7.1
• Calculate 𝐼(𝐴1)=1/𝜆
• Determine 𝐺𝐴1 using second fundamental forms of 𝐼(𝐴1) and ∂𝐴1
These notes discuss the decay of probability 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡} as 𝑡 approaches infinity, where
𝑋 is a random vector in ℝ𝑑 and 𝐶 is a real 𝑑×𝑑 matrix.
Key points:
• The decay depends on the distribution of 𝑋 and matrix 𝐶
• Two types of distributions are considered: symmetric Weibull-like and Student-like
• Weibull-like tails are handled using Theorem 7.1
• Student-like tails are handled using a change of variable technique and Theorem 5.1
Light Tail Distribution Example
Setup
Consider a random vector 𝑋=(𝑋1,…,𝑋𝑑) in ℝ𝑑 with density 𝑓=𝑒−𝐼, where 𝐼 is a convex,
𝛼-positively homogeneous function on ℝ𝑑.
Important:
• 𝐴𝑡={𝑥∈ℝ𝑑:⟨𝐶𝑥,𝑥⟩>𝑡}=√𝑡𝐴1
• 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}=∫𝑒−𝐼(𝑥)
𝐴𝑡𝑑𝑥
Specific Case
Assume the components 𝑋𝑖 of 𝑋 are i.i.d. with density:
𝑤𝛼(𝑥)=𝛼1−1
𝛼
2𝛤(1
𝛼)exp(−|𝑥|𝛼
𝛼), 𝑥∈ℝ,𝛼>1
Conjecture 8.1.1: If 𝛼≠2 and 𝐶+𝐶𝑇 has no vanishing eigenvalue, then ∑ |𝑥𝑖|𝛼
𝑑
𝑖=1 admits a
finite number of minima in 𝐴1, and det𝐺𝐴1 is non-zero at these minima.
Results
For 𝛼≠2:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 𝛼𝑑−𝑑
𝛼
2𝑑𝛤(1
𝛼)𝑑𝑐1𝑒−𝑡𝛼/2𝐼(𝐴1)𝑡−(𝛼−2)𝑑
4−𝛼
4
where
𝑐1=(2𝜋)𝑑−1
2∑|𝐷𝐼(𝑥)|−𝑑+1
2
𝑥∈𝐷𝐴1(det𝐺𝐴1)−1
2
Note: 𝐷𝐼(𝑥)=(sign(𝑥𝑖)|𝑥𝑖|𝛼−1)1≤𝑖≤𝑑 for 𝛼 >1

Special Case: 𝛼=2
Let 𝜆 be the largest eigenvalue of 𝐶+𝐶𝑇 (assumed positive), and 𝐻={𝑥:(𝐶+𝐶𝑇)𝑥 =𝜆𝑥}
be the associated eigenspace.
Theorem 8.1.2
For 𝛼=2 and 𝜆>0:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 1
𝜆𝑘−1
2𝛤(𝑘+1
2)(det𝑀)1
2𝑒−𝑡/𝜆𝑡𝑘−1
2
where 𝑘=dim𝐻−1 and 𝑀 is the compression of 𝐼𝑑−𝜆−1(𝐶+𝐶𝑇) to 𝐻⊥.
Proof outline:
• 𝐷𝐴1 is the sphere of radius √2/𝜆 centered at the origin in 𝐻
• Apply Theorem 7.1
• Calculate 𝐼(𝐴1)=1/𝜆
• Determine 𝐺𝐴1 using second fundamental forms of 𝐼(𝐴1) and ∂𝐴1
These notes discuss the decay of probability 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡} as 𝑡 approaches infinity, where
𝑋 is a random vector in ℝ𝑑 and 𝐶 is a real 𝑑×𝑑 matrix.
Key points:
• The decay depends on the distribution of 𝑋 and matrix 𝐶
• Two types of distributions are considered: symmetric Weibull-like and Student-like
• Weibull-like tails are handled using Theorem 7.1
• Student-like tails are handled using a change of variable technique and Theorem 5.1
Light Tail Distribution Example
Setup
Consider a random vector 𝑋=(𝑋1,…,𝑋𝑑) in ℝ𝑑 with density 𝑓=𝑒−𝐼, where 𝐼 is a convex,
𝛼-positively homogeneous function on ℝ𝑑.
Important:
• 𝐴𝑡={𝑥∈ℝ𝑑:⟨𝐶𝑥,𝑥⟩>𝑡}=√𝑡𝐴1
• 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}=∫𝑒−𝐼(𝑥)
𝐴𝑡𝑑𝑥

Specific Case
Assume the components 𝑋𝑖 of 𝑋 are i.i.d. with density:
𝑤𝛼(𝑥)=𝛼1−1
𝛼
2𝛤(1
𝛼)exp(−|𝑥|𝛼
𝛼), 𝑥∈ℝ,𝛼>1
Conjecture 8.1.1: If 𝛼≠2 and 𝐶+𝐶𝑇 has no vanishing eigenvalue, then ∑ |𝑥𝑖|𝛼
𝑑
𝑖=1 admits a
finite number of minima in 𝐴1, and det𝐺𝐴1 is non-zero at these minima.
Results
For 𝛼≠2:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 𝛼𝑑−𝑑
𝛼
2𝑑𝛤(1
𝛼)𝑑𝑐1𝑒−𝑡𝛼/2𝐼(𝐴1)𝑡−(𝛼−2)𝑑
4−𝛼
4
where
𝑐1=(2𝜋)𝑑−1
2∑|𝐷𝐼(𝑥)|−𝑑+1
2
𝑥∈𝐷𝐴1(det𝐺𝐴1)−1
2
Note: 𝐷𝐼(𝑥)=(sign(𝑥𝑖)|𝑥𝑖|𝛼−1)1≤𝑖≤𝑑 for 𝛼 >1
Special Case: 𝛼=2
Let 𝜆 be the largest eigenvalue of 𝐶+𝐶𝑇 (assumed positive), and 𝐻={𝑥:(𝐶+𝐶𝑇)𝑥 =𝜆𝑥}
be the associated eigenspace.
Theorem 8.1.2
For 𝛼=2 and 𝜆>0:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 1
𝜆𝑘−1
2𝛤(𝑘+1
2)(det𝑀)1
2𝑒−𝑡/𝜆𝑡𝑘−1
2
where 𝑘=dim𝐻−1 and 𝑀 is the compression of 𝐼𝑑−𝜆−1(𝐶+𝐶𝑇) to 𝐻⊥.
Proof outline:
• 𝐷𝐴1 is the sphere of radius √2/𝜆 centered at the origin in 𝐻
• Apply Theorem 7.1
• Calculate 𝐼(𝐴1)=1/𝜆

• Determine 𝐺𝐴1 using second fundamental forms of 𝐼(𝐴1) and ∂𝐴1
These notes discuss the decay of probability 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡} as 𝑡 approaches infinity, where
𝑋 is a random vector in ℝ𝑑 and 𝐶 is a real 𝑑×𝑑 matrix.
Key points:
• The decay depends on the distribution of 𝑋 and matrix 𝐶
• Two types of distributions are considered: symmetric Weibull-like and Student-like
• Weibull-like tails are handled using Theorem 7.1
• Student-like tails are handled using a change of variable technique and Theorem 5.1
Light Tail Distribution Example
Setup
Consider a random vector 𝑋=(𝑋1,…,𝑋𝑑) in ℝ𝑑 with density 𝑓=𝑒−𝐼, where 𝐼 is a convex,
𝛼-positively homogeneous function on ℝ𝑑.
Important:
• 𝐴𝑡={𝑥∈ℝ𝑑:⟨𝐶𝑥,𝑥⟩>𝑡}=√𝑡𝐴1
• 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}=∫𝑒−𝐼(𝑥)
𝐴𝑡𝑑𝑥
Specific Case
Assume the components 𝑋𝑖 of 𝑋 are i.i.d. with density:
𝑤𝛼(𝑥)=𝛼1−1
𝛼
2𝛤(1
𝛼)exp(−|𝑥|𝛼
𝛼), 𝑥∈ℝ,𝛼>1
Conjecture 8.1.1: If 𝛼≠2 and 𝐶+𝐶𝑇 has no vanishing eigenvalue, then ∑ |𝑥𝑖|𝛼
𝑑
𝑖=1 admits a
finite number of minima in 𝐴1, and det𝐺𝐴1 is non-zero at these minima.
Results
For 𝛼≠2:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 𝛼𝑑−𝑑
𝛼
2𝑑𝛤(1
𝛼)𝑑𝑐1𝑒−𝑡𝛼/2𝐼(𝐴1)𝑡−(𝛼−2)𝑑
4−𝛼
4
where
𝑐1=(2𝜋)𝑑−1
2∑|𝐷𝐼(𝑥)|−𝑑+1
2
𝑥∈𝐷𝐴1(det𝐺𝐴1)−1
2
Note: 𝐷𝐼(𝑥)=(sign(𝑥𝑖)|𝑥𝑖|𝛼−1)1≤𝑖≤𝑑 for 𝛼 >1
Special Case: 𝛼=2
Let 𝜆 be the largest eigenvalue of 𝐶+𝐶𝑇 (assumed positive), and 𝐻={𝑥:(𝐶+𝐶𝑇)𝑥 =𝜆𝑥}
be the associated eigenspace.
Theorem 8.1.2
For 𝛼=2 and 𝜆>0:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 1
𝜆𝑘−1
2𝛤(𝑘+1
2)(det𝑀)1
2𝑒−𝑡/𝜆𝑡𝑘−1
2
where 𝑘=dim𝐻−1 and 𝑀 is the compression of 𝐼𝑑−𝜆−1(𝐶+𝐶𝑇) to 𝐻⊥.
Proof outline:
• 𝐷𝐴1 is the sphere of radius √2/𝜆 centered at the origin in 𝐻
• Apply Theorem 7.1
• Calculate 𝐼(𝐴1)=1/𝜆
• Determine 𝐺𝐴1 using second fundamental forms of 𝐼(𝐴1) and ∂𝐴1
These notes discuss the decay of probability 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡} as 𝑡 approaches infinity, where
𝑋 is a random vector in ℝ𝑑 and 𝐶 is a real 𝑑×𝑑 matrix.
Key points:
• The decay depends on the distribution of 𝑋 and matrix 𝐶
• Two types of distributions are considered: symmetric Weibull-like and Student-like
• Weibull-like tails are handled using Theorem 7.1
• Student-like tails are handled using a change of variable technique and Theorem 5.1

Light Tail Distribution Example
Setup
Consider a random vector 𝑋=(𝑋1,…,𝑋𝑑) in ℝ𝑑 with density 𝑓=𝑒−𝐼, where 𝐼 is a convex,
𝛼-positively homogeneous function on ℝ𝑑.
Important:
• 𝐴𝑡={𝑥∈ℝ𝑑:⟨𝐶𝑥,𝑥⟩>𝑡}=√𝑡𝐴1
• 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}=∫𝑒−𝐼(𝑥)
𝐴𝑡𝑑𝑥
Specific Case
Assume the components 𝑋𝑖 of 𝑋 are i.i.d. with density:
𝑤𝛼(𝑥)=𝛼1−1
𝛼
2𝛤(1
𝛼)exp(−|𝑥|𝛼
𝛼), 𝑥∈ℝ,𝛼>1
Conjecture 8.1.1: If 𝛼≠2 and 𝐶+𝐶𝑇 has no vanishing eigenvalue, then ∑ |𝑥𝑖|𝛼
𝑑
𝑖=1 admits a
finite number of minima in 𝐴1, and det𝐺𝐴1 is non-zero at these minima.
Results
For 𝛼≠2:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 𝛼𝑑−𝑑
𝛼
2𝑑𝛤(1
𝛼)𝑑𝑐1𝑒−𝑡𝛼/2𝐼(𝐴1)𝑡−(𝛼−2)𝑑
4−𝛼
4
where
𝑐1=(2𝜋)𝑑−1
2∑|𝐷𝐼(𝑥)|−𝑑+1
2
𝑥∈𝐷𝐴1(det𝐺𝐴1)−1
2
Note: 𝐷𝐼(𝑥)=(sign(𝑥𝑖)|𝑥𝑖|𝛼−1)1≤𝑖≤𝑑 for 𝛼 >1
Special Case: 𝛼=2
Let 𝜆 be the largest eigenvalue of 𝐶+𝐶𝑇 (assumed positive), and 𝐻={𝑥:(𝐶+𝐶𝑇)𝑥 =𝜆𝑥}
be the associated eigenspace.
Theorem 8.1.2
For 𝛼=2 and 𝜆>0:

𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 1
𝜆𝑘−1
2𝛤(𝑘+1
2)(det𝑀)1
2𝑒−𝑡/𝜆𝑡𝑘−1
2
where 𝑘=dim𝐻−1 and 𝑀 is the compression of 𝐼𝑑−𝜆−1(𝐶+𝐶𝑇) to 𝐻⊥.
Proof outline:
• 𝐷𝐴1 is the sphere of radius √2/𝜆 centered at the origin in 𝐻
• Apply Theorem 7.1
• Calculate 𝐼(𝐴1)=1/𝜆
• Determine 𝐺𝐴1 using second fundamental forms of 𝐼(𝐴1) and ∂𝐴1
These notes discuss the decay of probability 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡} as 𝑡 approaches infinity, where
𝑋 is a random vector in ℝ𝑑 and 𝐶 is a real 𝑑×𝑑 matrix.
Key points:
• The decay depends on the distribution of 𝑋 and matrix 𝐶
• Two types of distributions are considered: symmetric Weibull-like and Student-like
• Weibull-like tails are handled using Theorem 7.1
• Student-like tails are handled using a change of variable technique and Theorem 5.1
Light Tail Distribution Example
Setup
Consider a random vector 𝑋=(𝑋1,…,𝑋𝑑) in ℝ𝑑 with density 𝑓=𝑒−𝐼, where 𝐼 is a convex,
𝛼-positively homogeneous function on ℝ𝑑.
Important:
• 𝐴𝑡={𝑥∈ℝ𝑑:⟨𝐶𝑥,𝑥⟩>𝑡}=√𝑡𝐴1
• 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}=∫𝑒−𝐼(𝑥)
𝐴𝑡𝑑𝑥
Specific Case
Assume the components 𝑋𝑖 of 𝑋 are i.i.d. with density:
𝑤𝛼(𝑥)=𝛼1−1
𝛼
2𝛤(1
𝛼)exp(−|𝑥|𝛼
𝛼), 𝑥∈ℝ,𝛼>1

Conjecture 8.1.1: If 𝛼≠2 and 𝐶+𝐶𝑇 has no vanishing eigenvalue, then ∑ |𝑥𝑖|𝛼
𝑑
𝑖=1 admits a
finite number of minima in 𝐴1, and det𝐺𝐴1 is non-zero at these minima.
Results
For 𝛼≠2:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 𝛼𝑑−𝑑
𝛼
2𝑑𝛤(1
𝛼)𝑑𝑐1𝑒−𝑡𝛼/2𝐼(𝐴1)𝑡−(𝛼−2)𝑑
4−𝛼
4
where
𝑐1=(2𝜋)𝑑−1
2∑|𝐷𝐼(𝑥)|−𝑑+1
2
𝑥∈𝐷𝐴1(det𝐺𝐴1)−1
2
Note: 𝐷𝐼(𝑥)=(sign(𝑥𝑖)|𝑥𝑖|𝛼−1)1≤𝑖≤𝑑 for 𝛼 >1
Special Case: 𝛼=2
Let 𝜆 be the largest eigenvalue of 𝐶+𝐶𝑇 (assumed positive), and 𝐻={𝑥:(𝐶+𝐶𝑇)𝑥 =𝜆𝑥}
be the associated eigenspace.
Theorem 8.1.2
For 𝛼=2 and 𝜆>0:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 1
𝜆𝑘−1
2𝛤(𝑘+1
2)(det𝑀)1
2𝑒−𝑡/𝜆𝑡𝑘−1
2
where 𝑘=dim𝐻−1 and 𝑀 is the compression of 𝐼𝑑−𝜆−1(𝐶+𝐶𝑇) to 𝐻⊥.
Proof outline:
• 𝐷𝐴1 is the sphere of radius √2/𝜆 centered at the origin in 𝐻
• Apply Theorem 7.1
• Calculate 𝐼(𝐴1)=1/𝜆
• Determine 𝐺𝐴1 using second fundamental forms of 𝐼(𝐴1) and ∂𝐴1
These notes discuss the decay of probability 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡} as 𝑡 approaches infinity, where
𝑋 is a random vector in ℝ𝑑 and 𝐶 is a real 𝑑×𝑑 matrix.
Key points:
• The decay depends on the distribution of 𝑋 and matrix 𝐶

• Two types of distributions are considered: symmetric Weibull-like and Student-like
• Weibull-like tails are handled using Theorem 7.1
• Student-like tails are handled using a change of variable technique and Theorem 5.1
Light Tail Distribution Example
Setup
Consider a random vector 𝑋=(𝑋1,…,𝑋𝑑) in ℝ𝑑 with density 𝑓=𝑒−𝐼, where 𝐼 is a convex,
𝛼-positively homogeneous function on ℝ𝑑.
Important:
• 𝐴𝑡={𝑥∈ℝ𝑑:⟨𝐶𝑥,𝑥⟩>𝑡}=√𝑡𝐴1
• 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}=∫𝑒−𝐼(𝑥)
𝐴𝑡𝑑𝑥
Specific Case
Assume the components 𝑋𝑖 of 𝑋 are i.i.d. with density:
𝑤𝛼(𝑥)=𝛼1−1
𝛼
2𝛤(1
𝛼)exp(−|𝑥|𝛼
𝛼), 𝑥∈ℝ,𝛼>1
Conjecture 8.1.1: If 𝛼≠2 and 𝐶+𝐶𝑇 has no vanishing eigenvalue, then ∑ |𝑥𝑖|𝛼
𝑑
𝑖=1 admits a
finite number of minima in 𝐴1, and det𝐺𝐴1 is non-zero at these minima.
Results
For 𝛼≠2:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 𝛼𝑑−𝑑
𝛼
2𝑑𝛤(1
𝛼)𝑑𝑐1𝑒−𝑡𝛼/2𝐼(𝐴1)𝑡−(𝛼−2)𝑑
4−𝛼
4
where
𝑐1=(2𝜋)𝑑−1
2∑|𝐷𝐼(𝑥)|−𝑑+1
2
𝑥∈𝐷𝐴1(det𝐺𝐴1)−1
2
Note: 𝐷𝐼(𝑥)=(sign(𝑥𝑖)|𝑥𝑖|𝛼−1)1≤𝑖≤𝑑 for 𝛼 >1

Special Case: 𝛼=2
Let 𝜆 be the largest eigenvalue of 𝐶+𝐶𝑇 (assumed positive), and 𝐻={𝑥:(𝐶+𝐶𝑇)𝑥 =𝜆𝑥}
be the associated eigenspace.
Theorem 8.1.2
For 𝛼=2 and 𝜆>0:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 1
𝜆𝑘−1
2𝛤(𝑘+1
2)(det𝑀)1
2𝑒−𝑡/𝜆𝑡𝑘−1
2
where 𝑘=dim𝐻−1 and 𝑀 is the compression of 𝐼𝑑−𝜆−1(𝐶+𝐶𝑇) to 𝐻⊥.
Proof outline:
• 𝐷𝐴1 is the sphere of radius √2/𝜆 centered at the origin in 𝐻
• Apply Theorem 7.1
• Calculate 𝐼(𝐴1)=1/𝜆
• Determine 𝐺𝐴1 using second fundamental forms of 𝐼(𝐴1) and ∂𝐴1
These notes discuss the decay of probability 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡} as 𝑡 approaches infinity, where
𝑋 is a random vector in ℝ𝑑 and 𝐶 is a real 𝑑×𝑑 matrix.
Key points:
• The decay depends on the distribution of 𝑋 and matrix 𝐶
• Two types of distributions are considered: symmetric Weibull-like and Student-like
• Weibull-like tails are handled using Theorem 7.1
• Student-like tails are handled using a change of variable technique and Theorem 5.1
Light Tail Distribution Example
Setup
Consider a random vector 𝑋=(𝑋1,…,𝑋𝑑) in ℝ𝑑 with density 𝑓=𝑒−𝐼, where 𝐼 is a convex,
𝛼-positively homogeneous function on ℝ𝑑.
Important:
• 𝐴𝑡={𝑥∈ℝ𝑑:⟨𝐶𝑥,𝑥⟩>𝑡}=√𝑡𝐴1
• 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}=∫𝑒−𝐼(𝑥)
𝐴𝑡𝑑𝑥
Specific Case
Assume the components 𝑋𝑖 of 𝑋 are i.i.d. with density:
𝑤𝛼(𝑥)=𝛼1−1
𝛼
2𝛤(1
𝛼)exp(−|𝑥|𝛼
𝛼), 𝑥∈ℝ,𝛼>1
Conjecture 8.1.1: If 𝛼≠2 and 𝐶+𝐶𝑇 has no vanishing eigenvalue, then ∑ |𝑥𝑖|𝛼
𝑑
𝑖=1 admits a
finite number of minima in 𝐴1, and det𝐺𝐴1 is non-zero at these minima.
Results
For 𝛼≠2:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 𝛼𝑑−𝑑
𝛼
2𝑑𝛤(1
𝛼)𝑑𝑐1𝑒−𝑡𝛼/2𝐼(𝐴1)𝑡−(𝛼−2)𝑑
4−𝛼
4
where
𝑐1=(2𝜋)𝑑−1
2∑|𝐷𝐼(𝑥)|−𝑑+1
2
𝑥∈𝐷𝐴1(det𝐺𝐴1)−1
2
Note: 𝐷𝐼(𝑥)=(sign(𝑥𝑖)|𝑥𝑖|𝛼−1)1≤𝑖≤𝑑 for 𝛼 >1
Special Case: 𝛼=2
Let 𝜆 be the largest eigenvalue of 𝐶+𝐶𝑇 (assumed positive), and 𝐻={𝑥:(𝐶+𝐶𝑇)𝑥 =𝜆𝑥}
be the associated eigenspace.
Theorem 8.1.2
For 𝛼=2 and 𝜆>0:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 1
𝜆𝑘−1
2𝛤(𝑘+1
2)(det𝑀)1
2𝑒−𝑡/𝜆𝑡𝑘−1
2
where 𝑘=dim𝐻−1 and 𝑀 is the compression of 𝐼𝑑−𝜆−1(𝐶+𝐶𝑇) to 𝐻⊥.
Proof outline:
• 𝐷𝐴1 is the sphere of radius √2/𝜆 centered at the origin in 𝐻
• Apply Theorem 7.1
• Calculate 𝐼(𝐴1)=1/𝜆
• Determine 𝐺𝐴1 using second fundamental forms of 𝐼(𝐴1) and ∂𝐴1
These notes discuss the decay of probability 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡} as 𝑡 approaches infinity, where
𝑋 is a random vector in ℝ𝑑 and 𝐶 is a real 𝑑×𝑑 matrix.
Key points:
• The decay depends on the distribution of 𝑋 and matrix 𝐶
• Two types of distributions are considered: symmetric Weibull-like and Student-like
• Weibull-like tails are handled using Theorem 7.1
• Student-like tails are handled using a change of variable technique and Theorem 5.1
Light Tail Distribution Example
Setup
Consider a random vector 𝑋=(𝑋1,…,𝑋𝑑) in ℝ𝑑 with density 𝑓=𝑒−𝐼, where 𝐼 is a convex,
𝛼-positively homogeneous function on ℝ𝑑.
Important:
• 𝐴𝑡={𝑥∈ℝ𝑑:⟨𝐶𝑥,𝑥⟩>𝑡}=√𝑡𝐴1
• 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}=∫𝑒−𝐼(𝑥)
𝐴𝑡𝑑𝑥
Specific Case
Assume the components 𝑋𝑖 of 𝑋 are i.i.d. with density:
𝑤𝛼(𝑥)=𝛼1−1
𝛼
2𝛤(1
𝛼)exp(−|𝑥|𝛼
𝛼), 𝑥∈ℝ,𝛼>1
Conjecture 8.1.1: If 𝛼≠2 and 𝐶+𝐶𝑇 has no vanishing eigenvalue, then ∑ |𝑥𝑖|𝛼
𝑑
𝑖=1 admits a
finite number of minima in 𝐴1, and det𝐺𝐴1 is non-zero at these minima.
Results
For 𝛼≠2:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 𝛼𝑑−𝑑
𝛼
2𝑑𝛤(1
𝛼)𝑑𝑐1𝑒−𝑡𝛼/2𝐼(𝐴1)𝑡−(𝛼−2)𝑑
4−𝛼
4
where
𝑐1=(2𝜋)𝑑−1
2∑|𝐷𝐼(𝑥)|−𝑑+1
2
𝑥∈𝐷𝐴1(det𝐺𝐴1)−1
2
Note: 𝐷𝐼(𝑥)=(sign(𝑥𝑖)|𝑥𝑖|𝛼−1)1≤𝑖≤𝑑 for 𝛼 >1
Special Case: 𝛼=2
Let 𝜆 be the largest eigenvalue of 𝐶+𝐶𝑇 (assumed positive), and 𝐻={𝑥:(𝐶+𝐶𝑇)𝑥 =𝜆𝑥}
be the associated eigenspace.
Theorem 8.1.2
For 𝛼=2 and 𝜆>0:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 1
𝜆𝑘−1
2𝛤(𝑘+1
2)(det𝑀)1
2𝑒−𝑡/𝜆𝑡𝑘−1
2
where 𝑘=dim𝐻−1 and 𝑀 is the compression of 𝐼𝑑−𝜆−1(𝐶+𝐶𝑇) to 𝐻⊥.
Proof outline:
• 𝐷𝐴1 is the sphere of radius √2/𝜆 centered at the origin in 𝐻
• Apply Theorem 7.1
• Calculate 𝐼(𝐴1)=1/𝜆
• Determine 𝐺𝐴1 using second fundamental forms of 𝐼(𝐴1) and ∂𝐴1
These notes discuss the decay of probability 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡} as 𝑡 approaches infinity, where
𝑋 is a random vector in ℝ𝑑 and 𝐶 is a real 𝑑×𝑑 matrix.
Key points:
• The decay depends on the distribution of 𝑋 and matrix 𝐶
• Two types of distributions are considered: symmetric Weibull-like and Student-like
• Weibull-like tails are handled using Theorem 7.1
• Student-like tails are handled using a change of variable technique and Theorem 5.1
Light Tail Distribution Example
Setup
Consider a random vector 𝑋=(𝑋1,…,𝑋𝑑) in ℝ𝑑 with density 𝑓=𝑒−𝐼, where 𝐼 is a convex,
𝛼-positively homogeneous function on ℝ𝑑.
Important:
• 𝐴𝑡={𝑥∈ℝ𝑑:⟨𝐶𝑥,𝑥⟩>𝑡}=√𝑡𝐴1
• 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}=∫𝑒−𝐼(𝑥)
𝐴𝑡𝑑𝑥
Specific Case
Assume the components 𝑋𝑖 of 𝑋 are i.i.d. with density:
𝑤𝛼(𝑥)=𝛼1−1
𝛼
2𝛤(1
𝛼)exp(−|𝑥|𝛼
𝛼), 𝑥∈ℝ,𝛼>1
Conjecture 8.1.1: If 𝛼≠2 and 𝐶+𝐶𝑇 has no vanishing eigenvalue, then ∑ |𝑥𝑖|𝛼
𝑑
𝑖=1 admits a
finite number of minima in 𝐴1, and det𝐺𝐴1 is non-zero at these minima.
Results
For 𝛼≠2:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 𝛼𝑑−𝑑
𝛼
2𝑑𝛤(1
𝛼)𝑑𝑐1𝑒−𝑡𝛼/2𝐼(𝐴1)𝑡−(𝛼−2)𝑑
4−𝛼
4
where
𝑐1=(2𝜋)𝑑−1
2∑|𝐷𝐼(𝑥)|−𝑑+1
2
𝑥∈𝐷𝐴1(det𝐺𝐴1)−1
2
Note: 𝐷𝐼(𝑥)=(sign(𝑥𝑖)|𝑥𝑖|𝛼−1)1≤𝑖≤𝑑 for 𝛼 >1
Special Case: 𝛼=2
Let 𝜆 be the largest eigenvalue of 𝐶+𝐶𝑇 (assumed positive), and 𝐻={𝑥:(𝐶+𝐶𝑇)𝑥 =𝜆𝑥}
be the associated eigenspace.
Theorem 8.1.2
For 𝛼=2 and 𝜆>0:
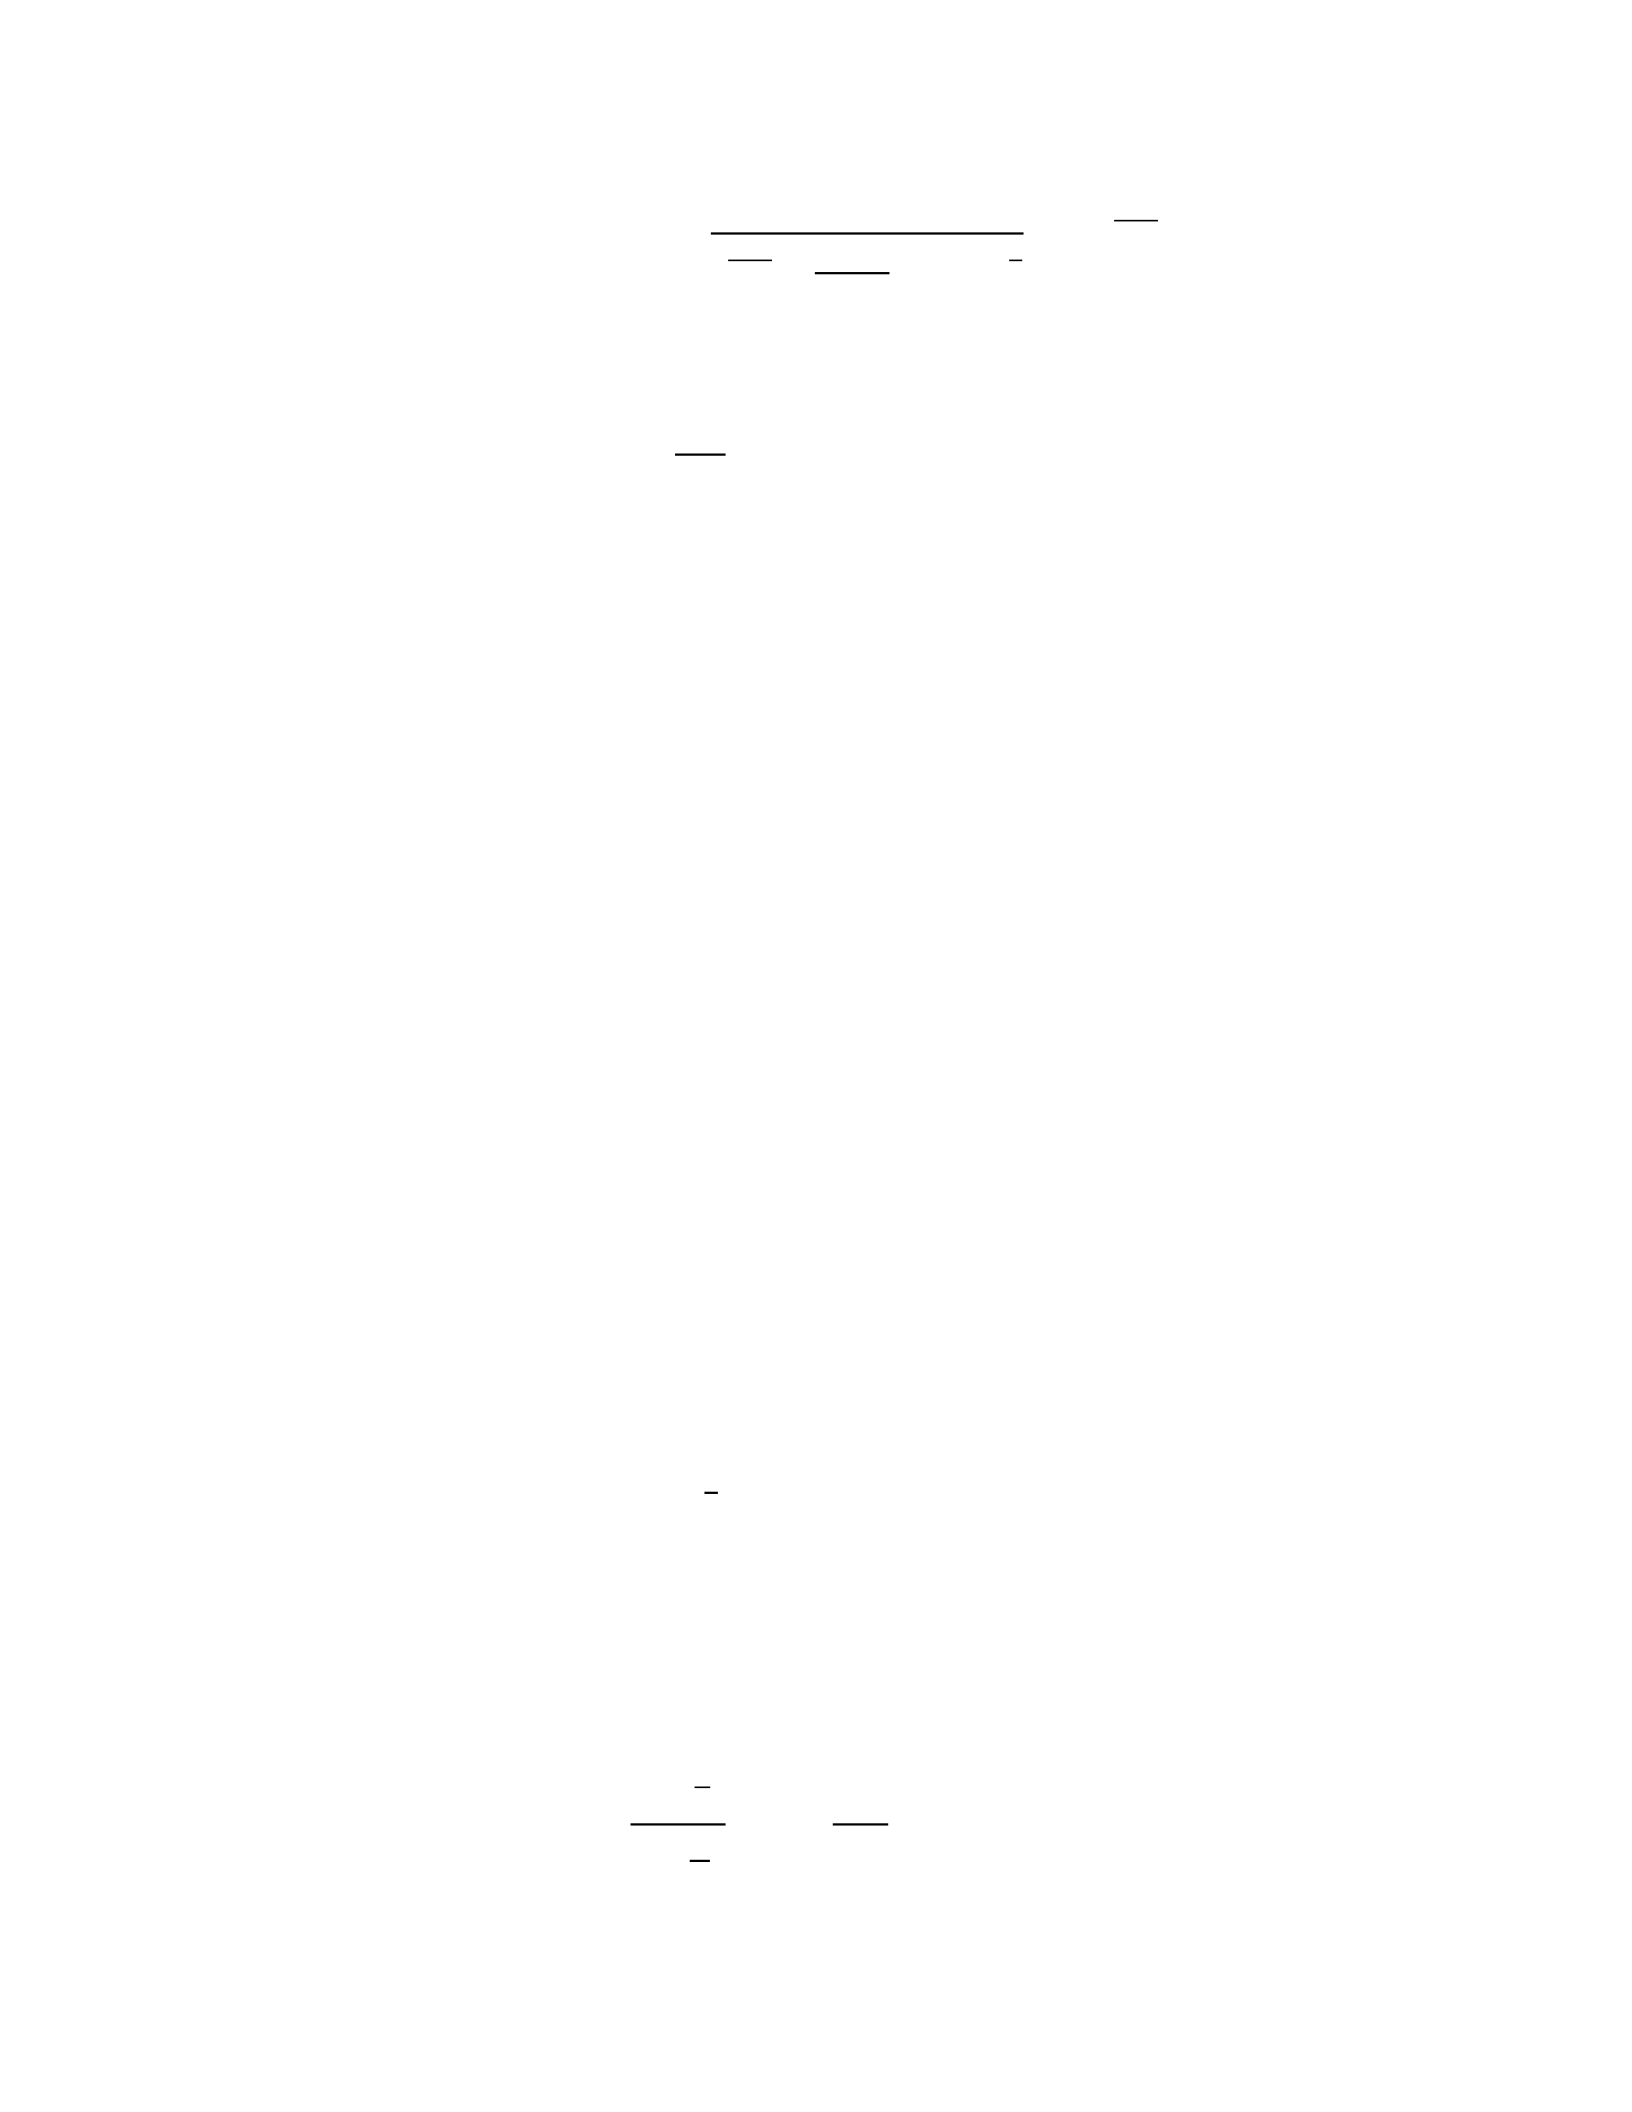
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 1
𝜆𝑘−1
2𝛤(𝑘+1
2)(det𝑀)1
2𝑒−𝑡/𝜆𝑡𝑘−1
2
where 𝑘=dim𝐻−1 and 𝑀 is the compression of 𝐼𝑑−𝜆−1(𝐶+𝐶𝑇) to 𝐻⊥.
Proof outline:
• 𝐷𝐴1 is the sphere of radius √2/𝜆 centered at the origin in 𝐻
• Apply Theorem 7.1
• Calculate 𝐼(𝐴1)=1/𝜆
• Determine 𝐺𝐴1 using second fundamental forms of 𝐼(𝐴1) and ∂𝐴1
These notes discuss the decay of probability 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡} as 𝑡 approaches infinity, where
𝑋 is a random vector in ℝ𝑑 and 𝐶 is a real 𝑑×𝑑 matrix.
Key points:
• The decay depends on the distribution of 𝑋 and matrix 𝐶
• Two types of distributions are considered: symmetric Weibull-like and Student-like
• Weibull-like tails are handled using Theorem 7.1
• Student-like tails are handled using a change of variable technique and Theorem 5.1
Light Tail Distribution Example
Setup
Consider a random vector 𝑋=(𝑋1,…,𝑋𝑑) in ℝ𝑑 with density 𝑓=𝑒−𝐼, where 𝐼 is a convex,
𝛼-positively homogeneous function on ℝ𝑑.
Important:
• 𝐴𝑡={𝑥∈ℝ𝑑:⟨𝐶𝑥,𝑥⟩>𝑡}=√𝑡𝐴1
• 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}=∫𝑒−𝐼(𝑥)
𝐴𝑡𝑑𝑥
Specific Case
Assume the components 𝑋𝑖 of 𝑋 are i.i.d. with density:
𝑤𝛼(𝑥)=𝛼1−1
𝛼
2𝛤(1
𝛼)exp(−|𝑥|𝛼
𝛼), 𝑥∈ℝ,𝛼>1

Conjecture 8.1.1: If 𝛼≠2 and 𝐶+𝐶𝑇 has no vanishing eigenvalue, then ∑ |𝑥𝑖|𝛼
𝑑
𝑖=1 admits a
finite number of minima in 𝐴1, and det𝐺𝐴1 is non-zero at these minima.
Results
For 𝛼≠2:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 𝛼𝑑−𝑑
𝛼
2𝑑𝛤(1
𝛼)𝑑𝑐1𝑒−𝑡𝛼/2𝐼(𝐴1)𝑡−(𝛼−2)𝑑
4−𝛼
4
where
𝑐1=(2𝜋)𝑑−1
2∑|𝐷𝐼(𝑥)|−𝑑+1
2
𝑥∈𝐷𝐴1(det𝐺𝐴1)−1
2
Note: 𝐷𝐼(𝑥)=(sign(𝑥𝑖)|𝑥𝑖|𝛼−1)1≤𝑖≤𝑑 for 𝛼 >1
Special Case: 𝛼=2
Let 𝜆 be the largest eigenvalue of 𝐶+𝐶𝑇 (assumed positive), and 𝐻={𝑥:(𝐶+𝐶𝑇)𝑥 =𝜆𝑥}
be the associated eigenspace.
Theorem 8.1.2
For 𝛼=2 and 𝜆>0:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 1
𝜆𝑘−1
2𝛤(𝑘+1
2)(det𝑀)1
2𝑒−𝑡/𝜆𝑡𝑘−1
2
where 𝑘=dim𝐻−1 and 𝑀 is the compression of 𝐼𝑑−𝜆−1(𝐶+𝐶𝑇) to 𝐻⊥.
Proof outline:
• 𝐷𝐴1 is the sphere of radius √2/𝜆 centered at the origin in 𝐻
• Apply Theorem 7.1
• Calculate 𝐼(𝐴1)=1/𝜆
• Determine 𝐺𝐴1 using second fundamental forms of 𝐼(𝐴1) and ∂𝐴1
These notes discuss the decay of probability 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡} as 𝑡 approaches infinity, where
𝑋 is a random vector in ℝ𝑑 and 𝐶 is a real 𝑑×𝑑 matrix.
Key points:
• The decay depends on the distribution of 𝑋 and matrix 𝐶

• Two types of distributions are considered: symmetric Weibull-like and Student-like
• Weibull-like tails are handled using Theorem 7.1
• Student-like tails are handled using a change of variable technique and Theorem 5.1
Light Tail Distribution Example
Setup
Consider a random vector 𝑋=(𝑋1,…,𝑋𝑑) in ℝ𝑑 with density 𝑓=𝑒−𝐼, where 𝐼 is a convex,
𝛼-positively homogeneous function on ℝ𝑑.
Important:
• 𝐴𝑡={𝑥∈ℝ𝑑:⟨𝐶𝑥,𝑥⟩>𝑡}=√𝑡𝐴1
• 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}=∫𝑒−𝐼(𝑥)
𝐴𝑡𝑑𝑥
Specific Case
Assume the components 𝑋𝑖 of 𝑋 are i.i.d. with density:
𝑤𝛼(𝑥)=𝛼1−1
𝛼
2𝛤(1
𝛼)exp(−|𝑥|𝛼
𝛼), 𝑥∈ℝ,𝛼>1
Conjecture 8.1.1: If 𝛼≠2 and 𝐶+𝐶𝑇 has no vanishing eigenvalue, then ∑ |𝑥𝑖|𝛼
𝑑
𝑖=1 admits a
finite number of minima in 𝐴1, and det𝐺𝐴1 is non-zero at these minima.
Results
For 𝛼≠2:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 𝛼𝑑−𝑑
𝛼
2𝑑𝛤(1
𝛼)𝑑𝑐1𝑒−𝑡𝛼/2𝐼(𝐴1)𝑡−(𝛼−2)𝑑
4−𝛼
4
where
𝑐1=(2𝜋)𝑑−1
2∑|𝐷𝐼(𝑥)|−𝑑+1
2
𝑥∈𝐷𝐴1(det𝐺𝐴1)−1
2
Note: 𝐷𝐼(𝑥)=(sign(𝑥𝑖)|𝑥𝑖|𝛼−1)1≤𝑖≤𝑑 for 𝛼 >1
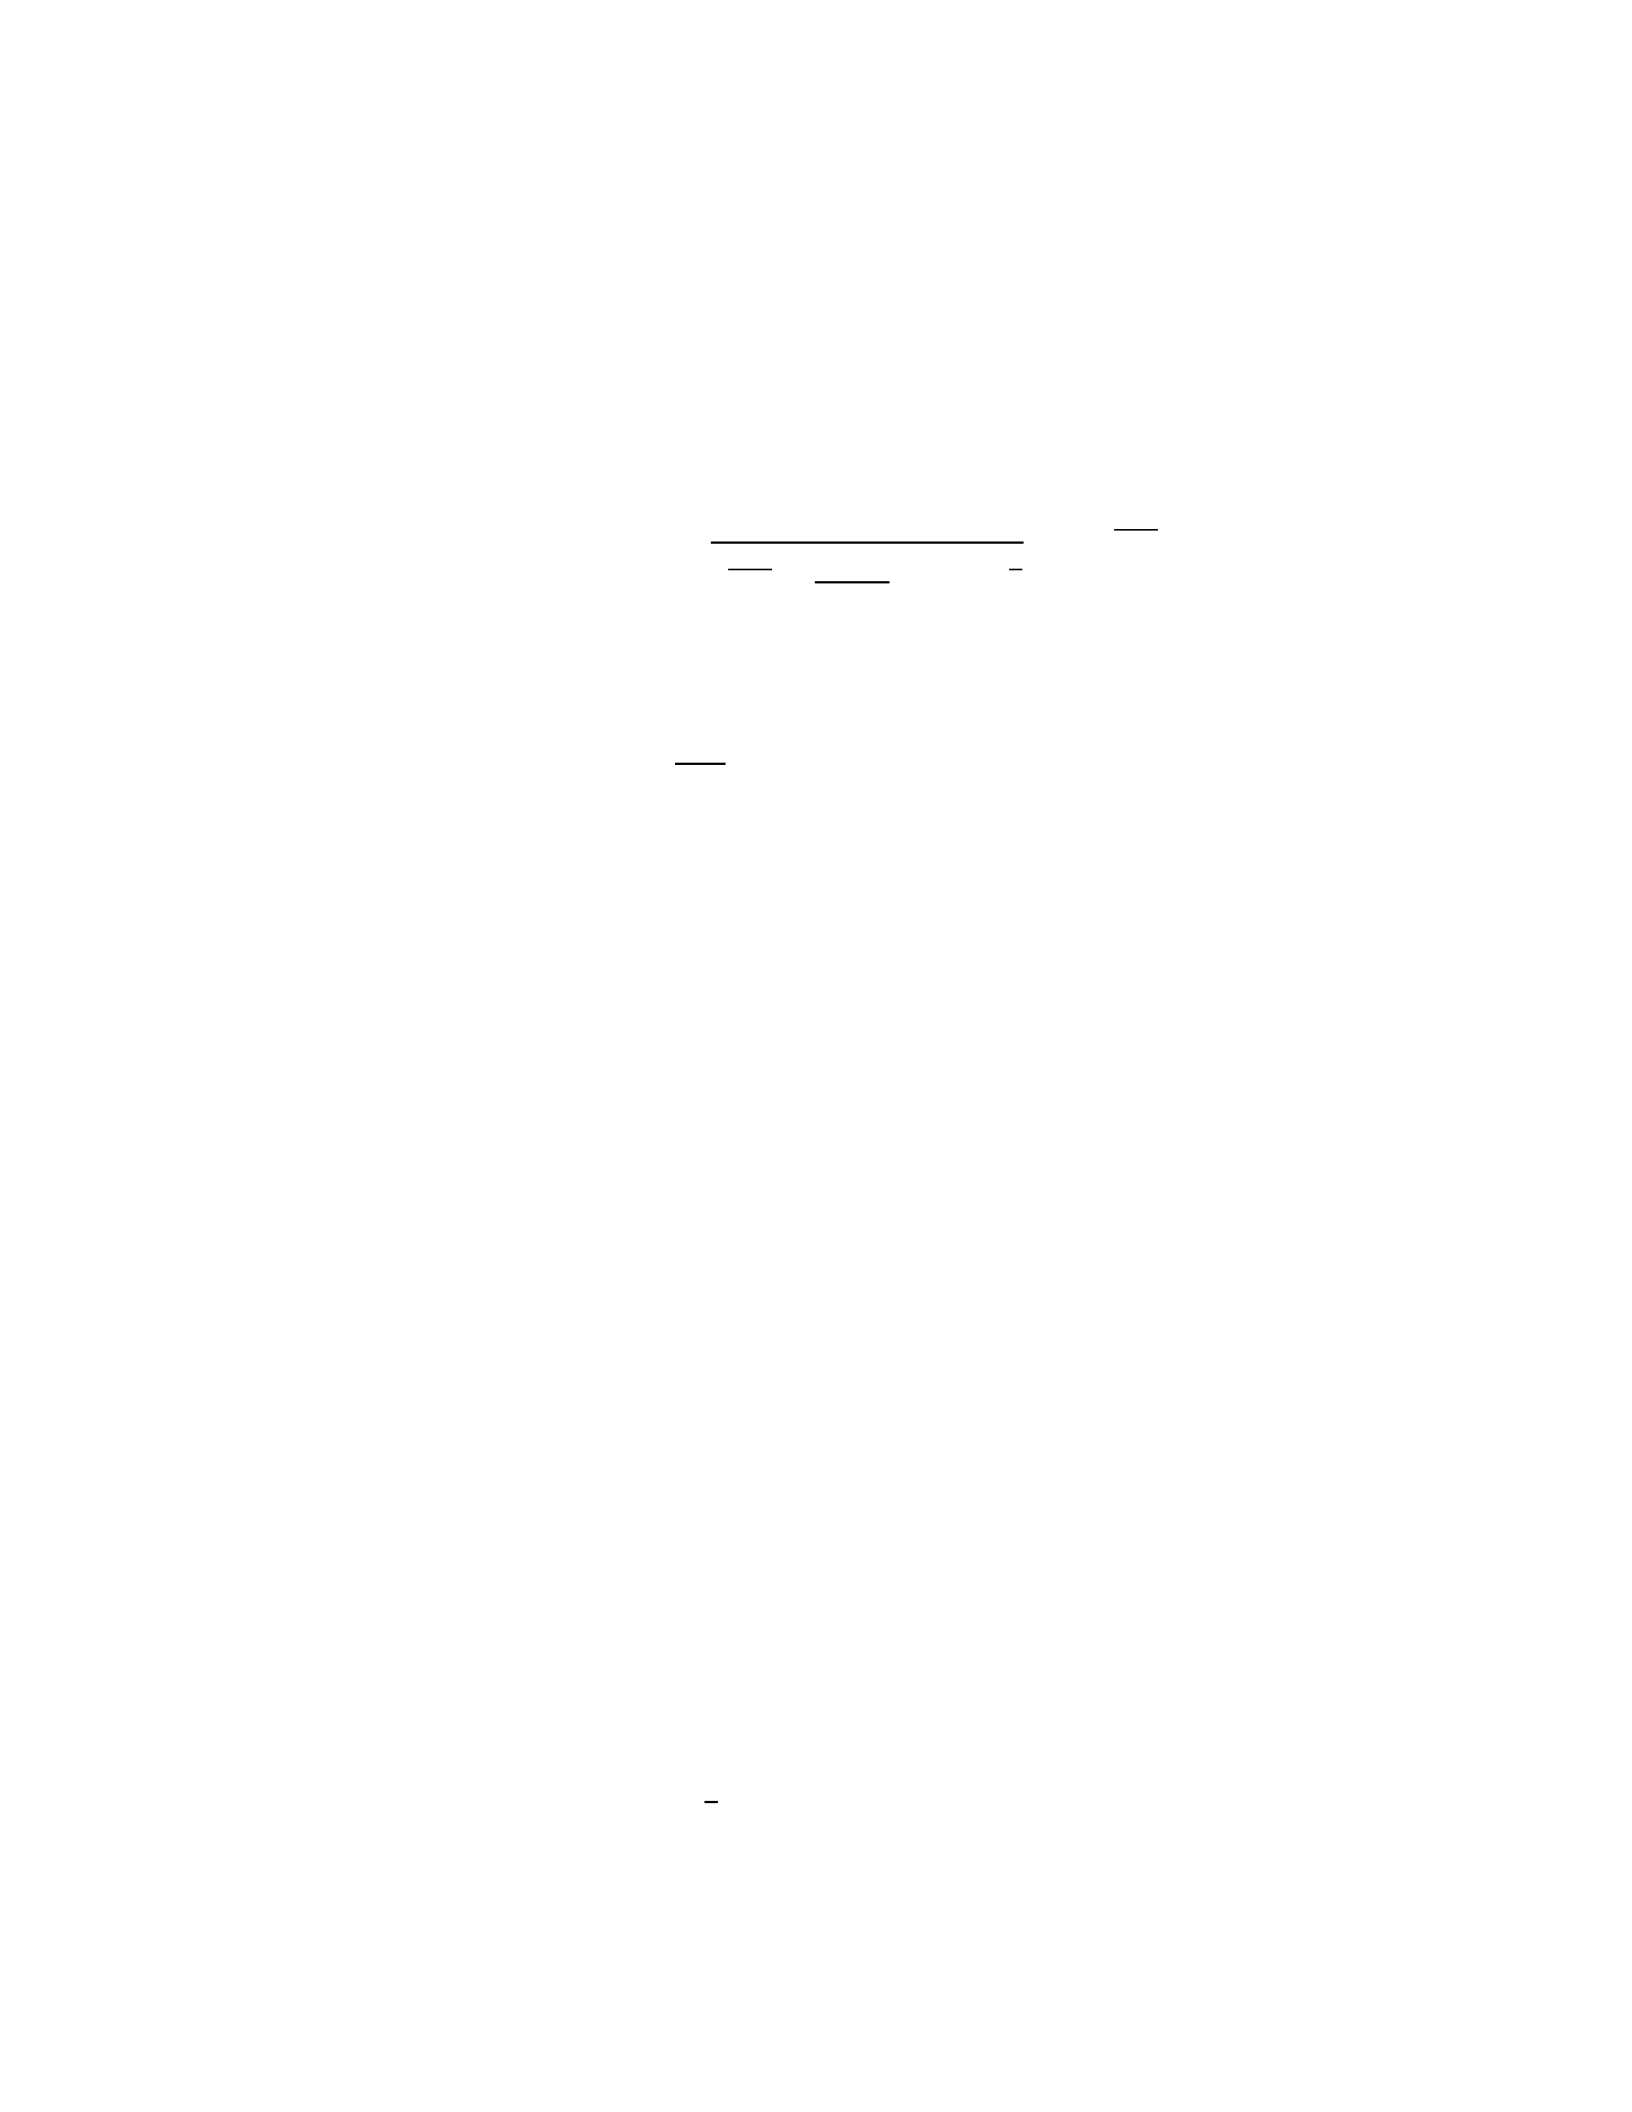
Special Case: 𝛼=2
Let 𝜆 be the largest eigenvalue of 𝐶+𝐶𝑇 (assumed positive), and 𝐻={𝑥:(𝐶+𝐶𝑇)𝑥 =𝜆𝑥}
be the associated eigenspace.
Theorem 8.1.2
For 𝛼=2 and 𝜆>0:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 1
𝜆𝑘−1
2𝛤(𝑘+1
2)(det𝑀)1
2𝑒−𝑡/𝜆𝑡𝑘−1
2
where 𝑘=dim𝐻−1 and 𝑀 is the compression of 𝐼𝑑−𝜆−1(𝐶+𝐶𝑇) to 𝐻⊥.
Proof outline:
• 𝐷𝐴1 is the sphere of radius √2/𝜆 centered at the origin in 𝐻
• Apply Theorem 7.1
• Calculate 𝐼(𝐴1)=1/𝜆
• Determine 𝐺𝐴1 using second fundamental forms of 𝐼(𝐴1) and ∂𝐴1
These notes discuss the decay of probability 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡} as 𝑡 approaches infinity, where
𝑋 is a random vector in ℝ𝑑 and 𝐶 is a real 𝑑×𝑑 matrix.
Key points:
• The decay depends on the distribution of 𝑋 and matrix 𝐶
• Two types of distributions are considered: symmetric Weibull-like and Student-like
• Weibull-like tails are handled using Theorem 7.1
• Student-like tails are handled using a change of variable technique and Theorem 5.1
Light Tail Distribution Example
Setup
Consider a random vector 𝑋=(𝑋1,…,𝑋𝑑) in ℝ𝑑 with density 𝑓=𝑒−𝐼, where 𝐼 is a convex,
𝛼-positively homogeneous function on ℝ𝑑.
Important:
• 𝐴𝑡={𝑥∈ℝ𝑑:⟨𝐶𝑥,𝑥⟩>𝑡}=√𝑡𝐴1
• 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}=∫𝑒−𝐼(𝑥)
𝐴𝑡𝑑𝑥

Specific Case
Assume the components 𝑋𝑖 of 𝑋 are i.i.d. with density:
𝑤𝛼(𝑥)=𝛼1−1
𝛼
2𝛤(1
𝛼)exp(−|𝑥|𝛼
𝛼), 𝑥∈ℝ,𝛼>1
Conjecture 8.1.1: If 𝛼≠2 and 𝐶+𝐶𝑇 has no vanishing eigenvalue, then ∑ |𝑥𝑖|𝛼
𝑑
𝑖=1 admits a
finite number of minima in 𝐴1, and det𝐺𝐴1 is non-zero at these minima.
Results
For 𝛼≠2:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 𝛼𝑑−𝑑
𝛼
2𝑑𝛤(1
𝛼)𝑑𝑐1𝑒−𝑡𝛼/2𝐼(𝐴1)𝑡−(𝛼−2)𝑑
4−𝛼
4
where
𝑐1=(2𝜋)𝑑−1
2∑|𝐷𝐼(𝑥)|−𝑑+1
2
𝑥∈𝐷𝐴1(det𝐺𝐴1)−1
2
Note: 𝐷𝐼(𝑥)=(sign(𝑥𝑖)|𝑥𝑖|𝛼−1)1≤𝑖≤𝑑 for 𝛼 >1
Special Case: 𝛼=2
Let 𝜆 be the largest eigenvalue of 𝐶+𝐶𝑇 (assumed positive), and 𝐻={𝑥:(𝐶+𝐶𝑇)𝑥 =𝜆𝑥}
be the associated eigenspace.
Theorem 8.1.2
For 𝛼=2 and 𝜆>0:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 1
𝜆𝑘−1
2𝛤(𝑘+1
2)(det𝑀)1
2𝑒−𝑡/𝜆𝑡𝑘−1
2
where 𝑘=dim𝐻−1 and 𝑀 is the compression of 𝐼𝑑−𝜆−1(𝐶+𝐶𝑇) to 𝐻⊥.
Proof outline:
• 𝐷𝐴1 is the sphere of radius √2/𝜆 centered at the origin in 𝐻
• Apply Theorem 7.1
• Calculate 𝐼(𝐴1)=1/𝜆

• Determine 𝐺𝐴1 using second fundamental forms of 𝐼(𝐴1) and ∂𝐴1
These notes discuss the decay of probability 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡} as 𝑡 approaches infinity, where
𝑋 is a random vector in ℝ𝑑 and 𝐶 is a real 𝑑×𝑑 matrix.
Key points:
• The decay depends on the distribution of 𝑋 and matrix 𝐶
• Two types of distributions are considered: symmetric Weibull-like and Student-like
• Weibull-like tails are handled using Theorem 7.1
• Student-like tails are handled using a change of variable technique and Theorem 5.1
Light Tail Distribution Example
Setup
Consider a random vector 𝑋=(𝑋1,…,𝑋𝑑) in ℝ𝑑 with density 𝑓=𝑒−𝐼, where 𝐼 is a convex,
𝛼-positively homogeneous function on ℝ𝑑.
Important:
• 𝐴𝑡={𝑥∈ℝ𝑑:⟨𝐶𝑥,𝑥⟩>𝑡}=√𝑡𝐴1
• 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}=∫𝑒−𝐼(𝑥)
𝐴𝑡𝑑𝑥
Specific Case
Assume the components 𝑋𝑖 of 𝑋 are i.i.d. with density:
𝑤𝛼(𝑥)=𝛼1−1
𝛼
2𝛤(1
𝛼)exp(−|𝑥|𝛼
𝛼), 𝑥∈ℝ,𝛼>1
Conjecture 8.1.1: If 𝛼≠2 and 𝐶+𝐶𝑇 has no vanishing eigenvalue, then ∑ |𝑥𝑖|𝛼
𝑑
𝑖=1 admits a
finite number of minima in 𝐴1, and det𝐺𝐴1 is non-zero at these minima.
Results
For 𝛼≠2:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 𝛼𝑑−𝑑
𝛼
2𝑑𝛤(1
𝛼)𝑑𝑐1𝑒−𝑡𝛼/2𝐼(𝐴1)𝑡−(𝛼−2)𝑑
4−𝛼
4
where
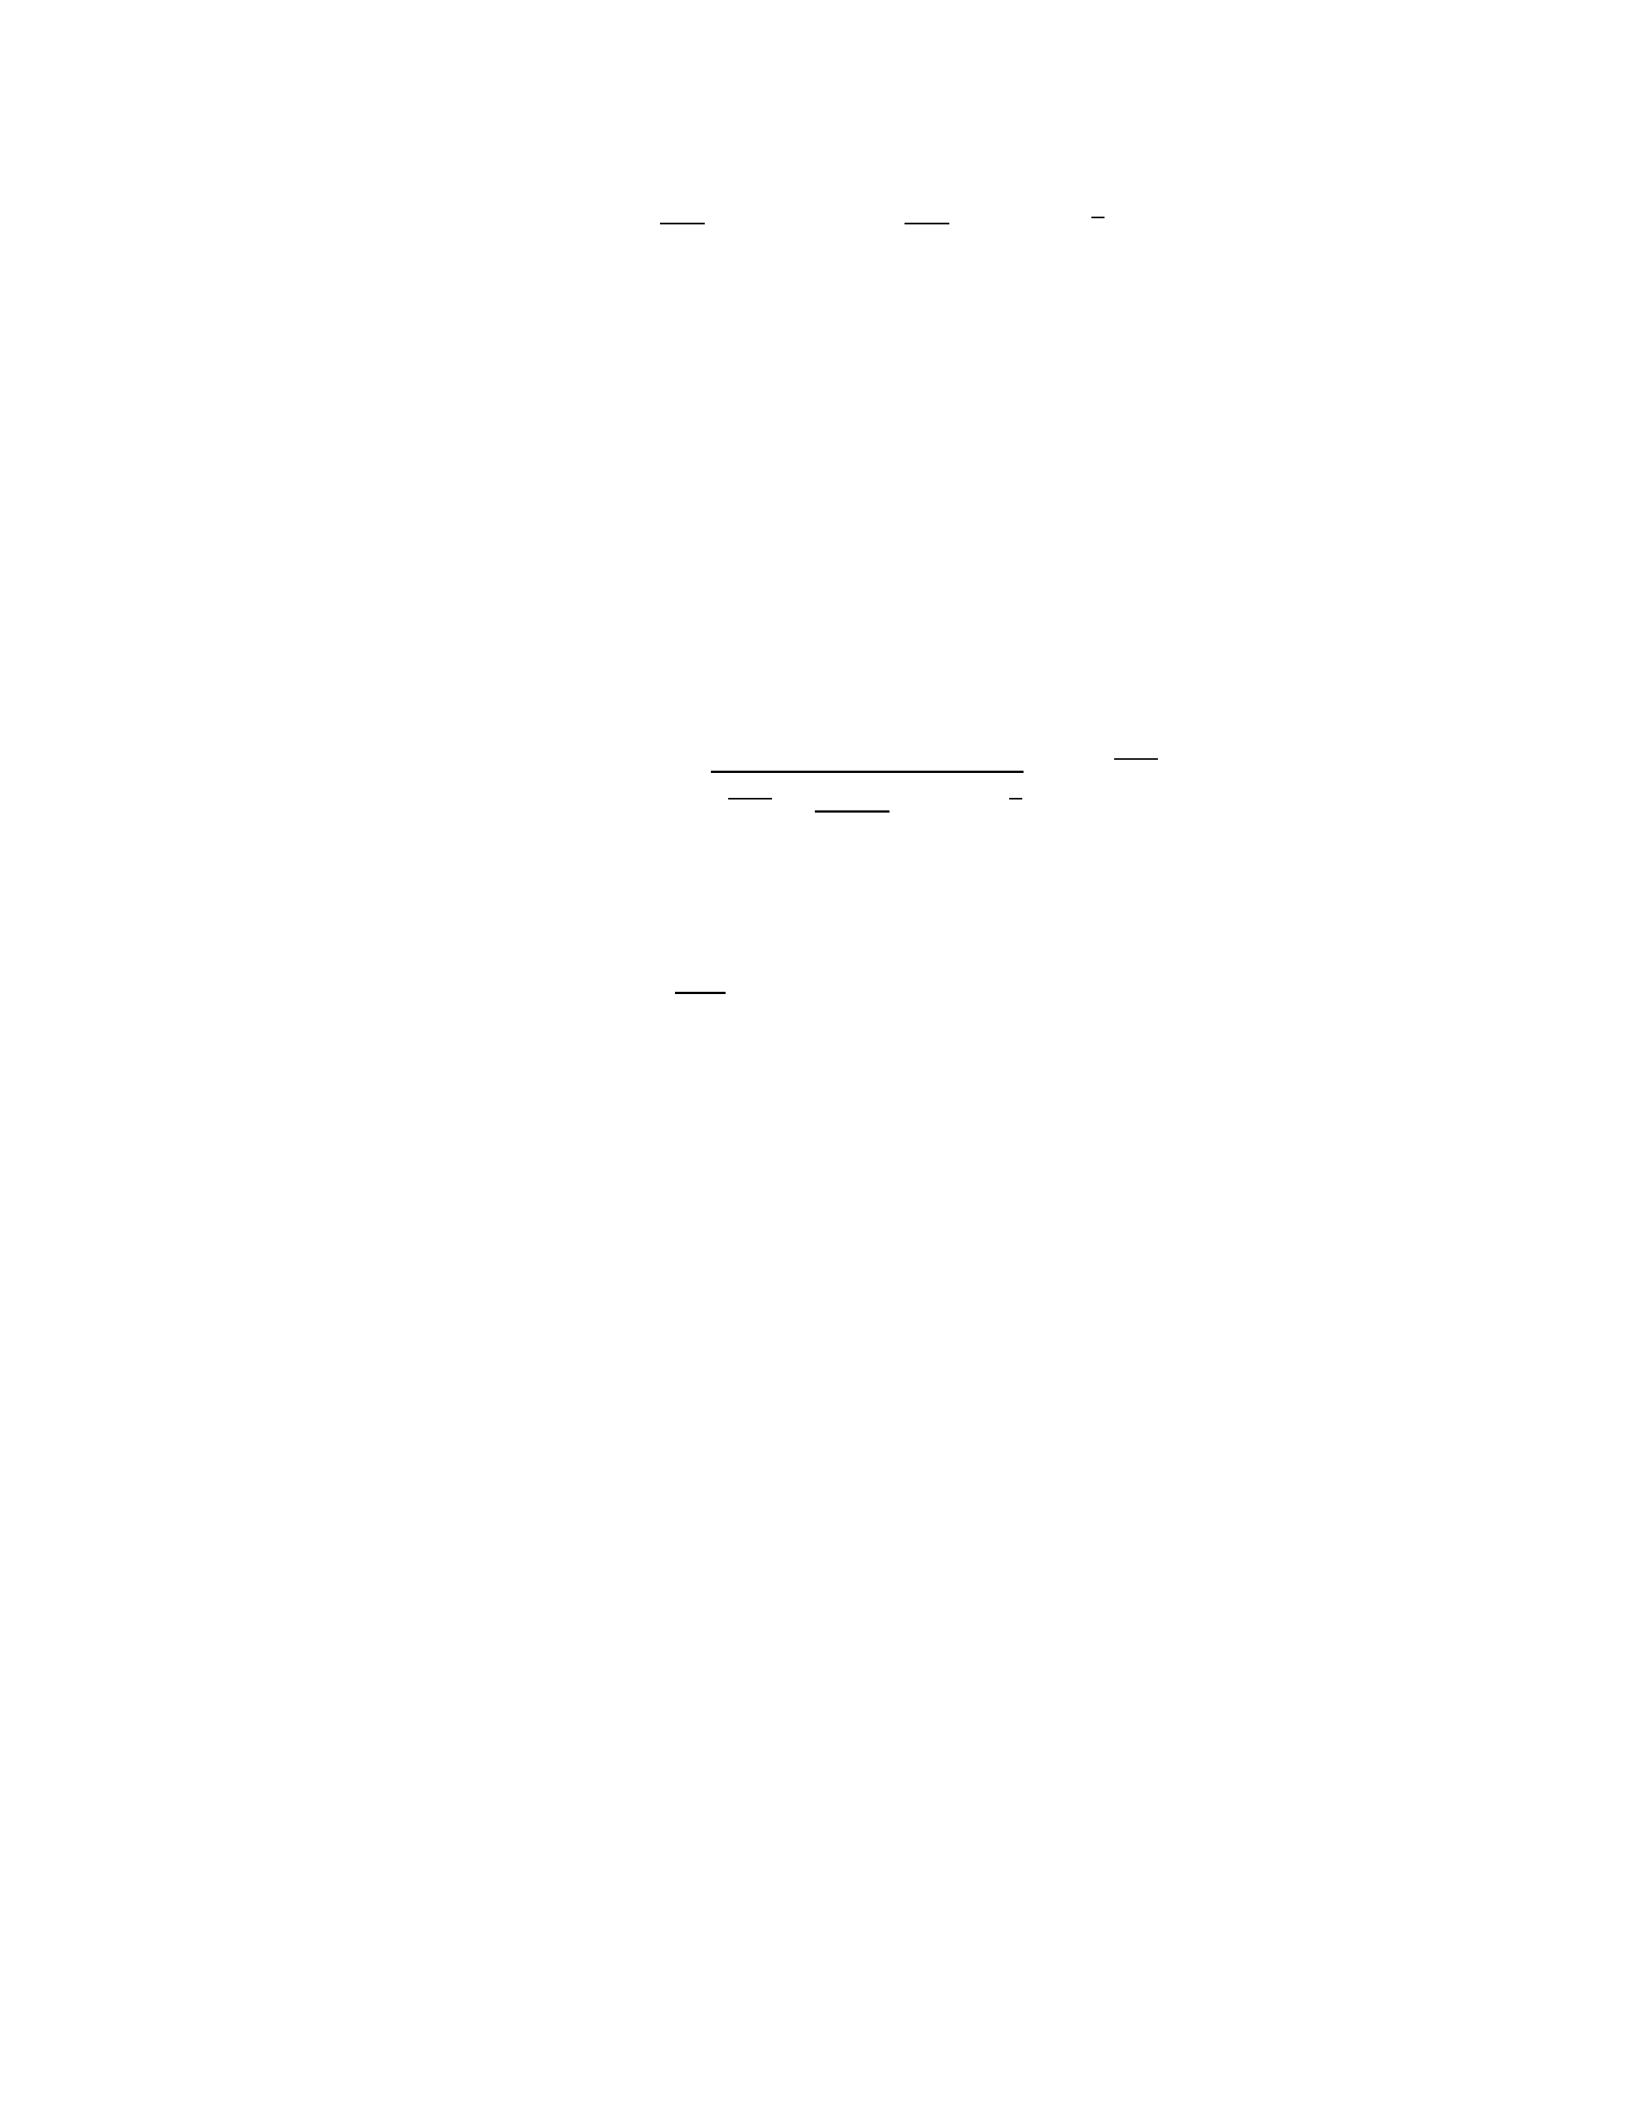
𝑐1=(2𝜋)𝑑−1
2∑|𝐷𝐼(𝑥)|−𝑑+1
2
𝑥∈𝐷𝐴1(det𝐺𝐴1)−1
2
Note: 𝐷𝐼(𝑥)=(sign(𝑥𝑖)|𝑥𝑖|𝛼−1)1≤𝑖≤𝑑 for 𝛼 >1
Special Case: 𝛼=2
Let 𝜆 be the largest eigenvalue of 𝐶+𝐶𝑇 (assumed positive), and 𝐻={𝑥:(𝐶+𝐶𝑇)𝑥 =𝜆𝑥}
be the associated eigenspace.
Theorem 8.1.2
For 𝛼=2 and 𝜆>0:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 1
𝜆𝑘−1
2𝛤(𝑘+1
2)(det𝑀)1
2𝑒−𝑡/𝜆𝑡𝑘−1
2
where 𝑘=dim𝐻−1 and 𝑀 is the compression of 𝐼𝑑−𝜆−1(𝐶+𝐶𝑇) to 𝐻⊥.
Proof outline:
• 𝐷𝐴1 is the sphere of radius √2/𝜆 centered at the origin in 𝐻
• Apply Theorem 7.1
• Calculate 𝐼(𝐴1)=1/𝜆
• Determine 𝐺𝐴1 using second fundamental forms of 𝐼(𝐴1) and ∂𝐴1
These notes discuss the decay of probability 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡} as 𝑡 approaches infinity, where
𝑋 is a random vector in ℝ𝑑 and 𝐶 is a real 𝑑×𝑑 matrix.
Key points:
• The decay depends on the distribution of 𝑋 and matrix 𝐶
• Two types of distributions are considered: symmetric Weibull-like and Student-like
• Weibull-like tails are handled using Theorem 7.1
• Student-like tails are handled using a change of variable technique and Theorem 5.1
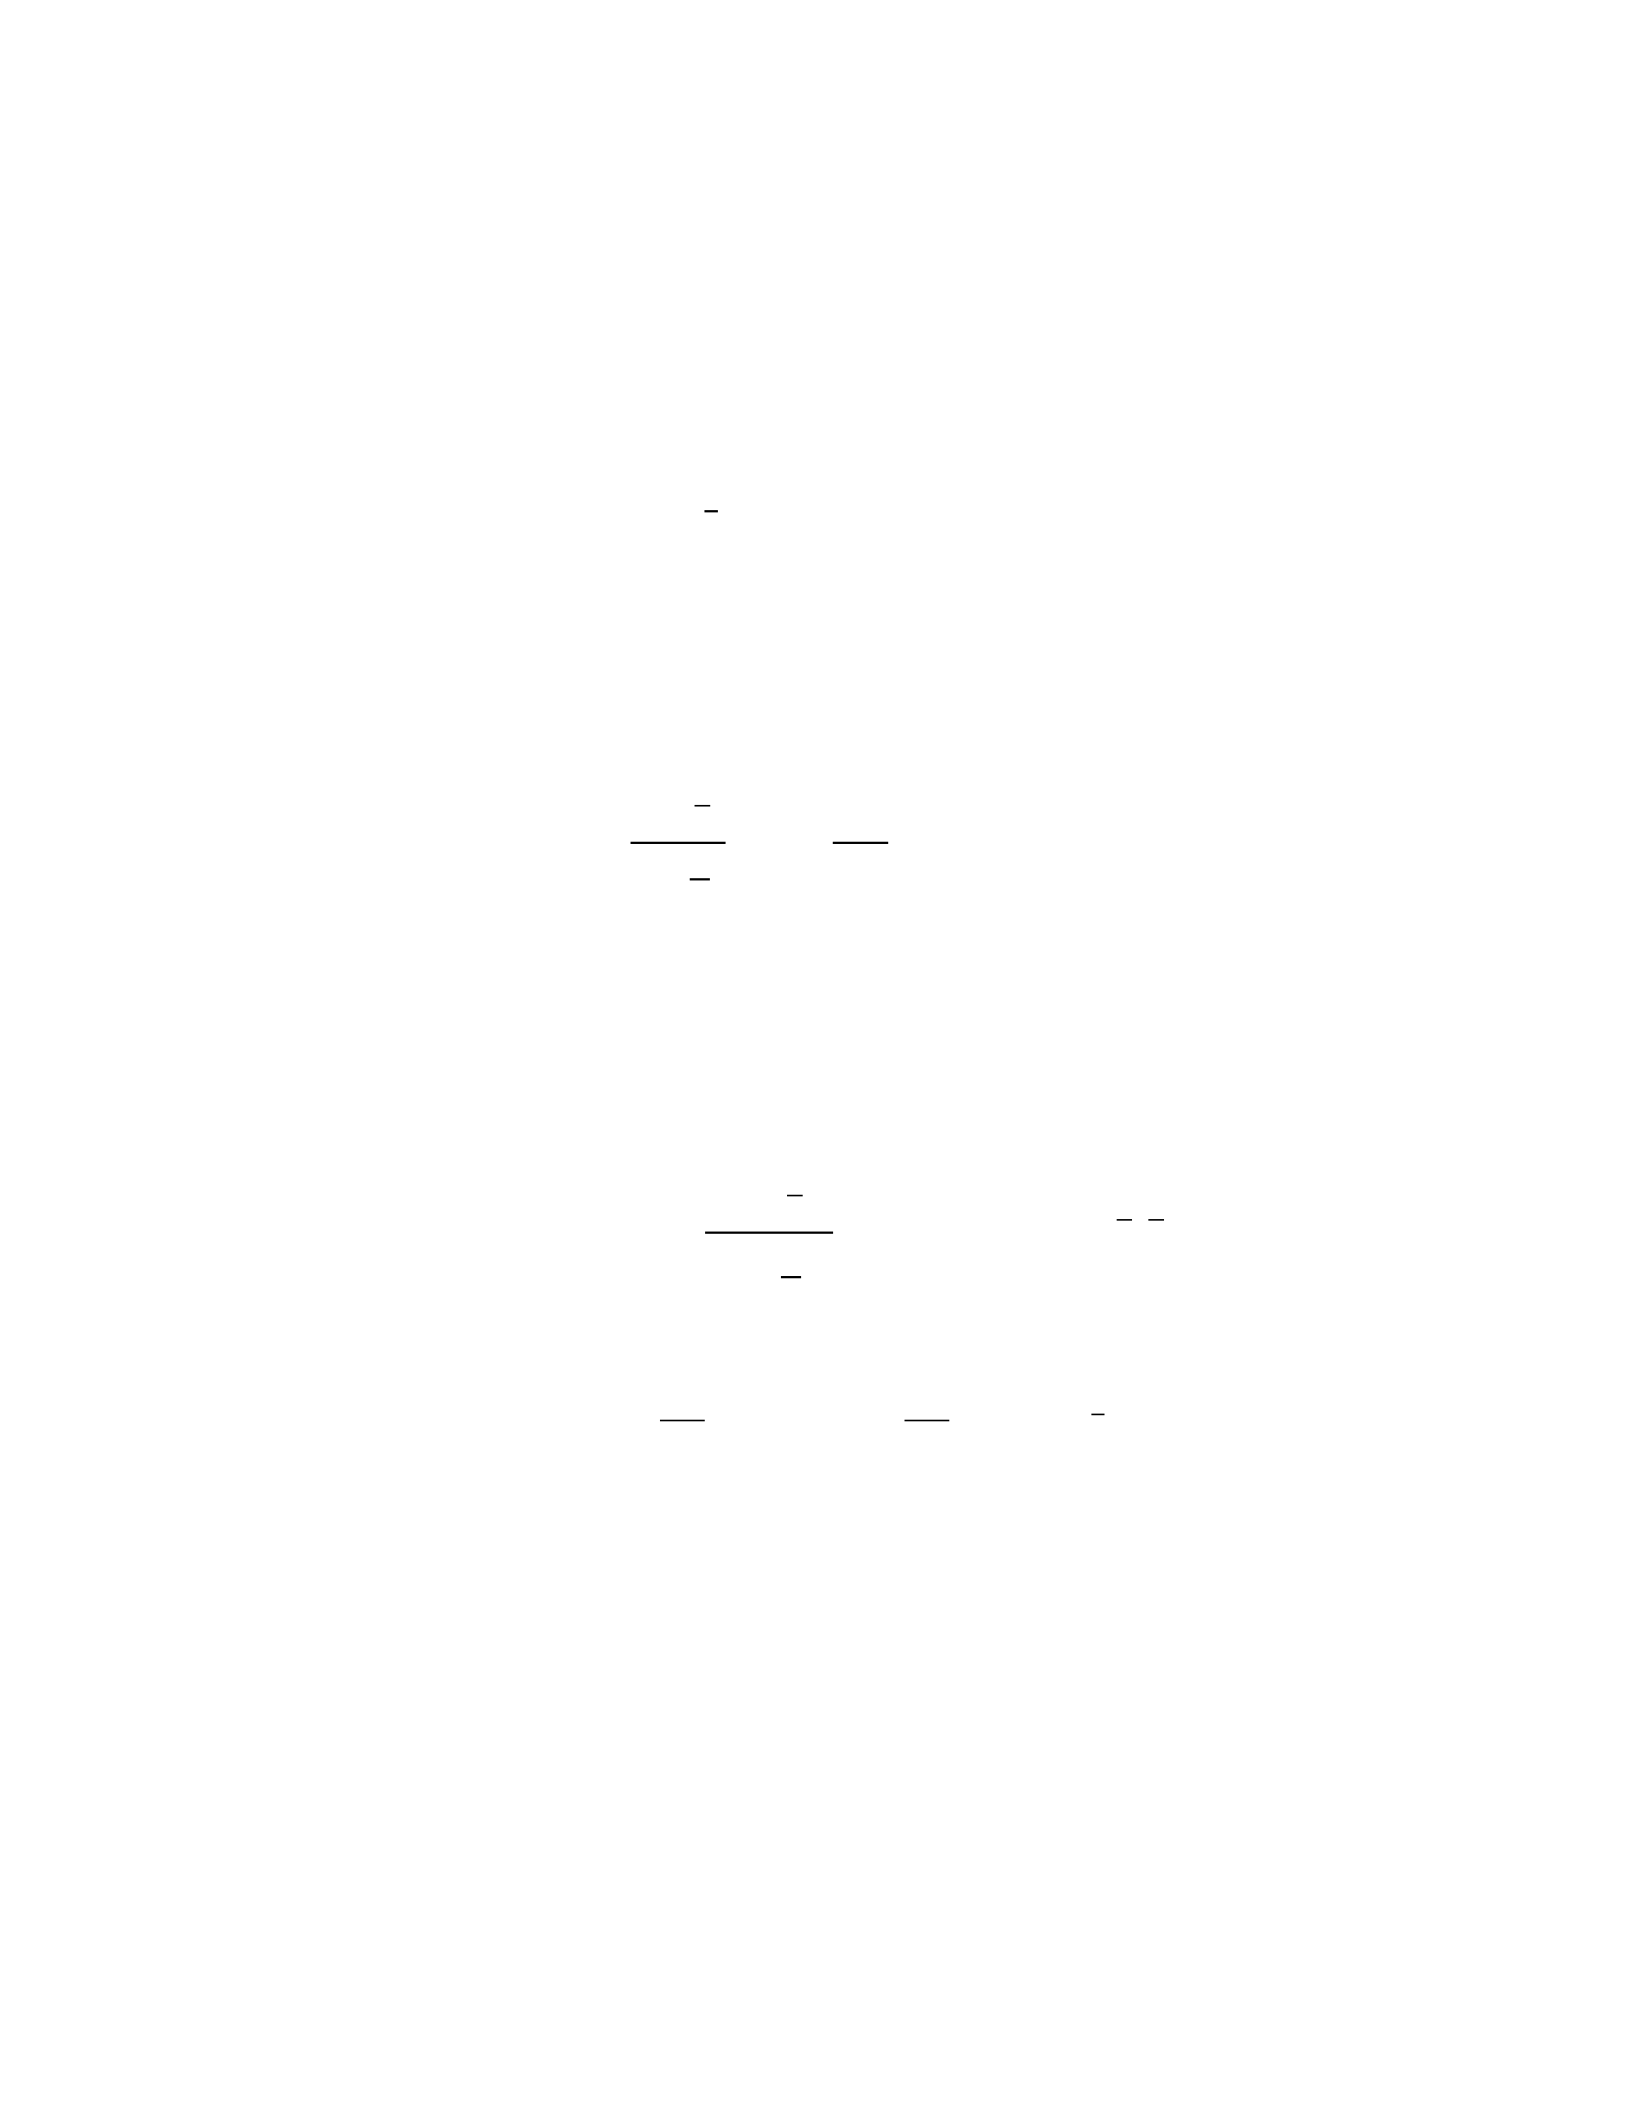
Light Tail Distribution Example
Setup
Consider a random vector 𝑋=(𝑋1,…,𝑋𝑑) in ℝ𝑑 with density 𝑓=𝑒−𝐼, where 𝐼 is a convex,
𝛼-positively homogeneous function on ℝ𝑑.
Important:
• 𝐴𝑡={𝑥∈ℝ𝑑:⟨𝐶𝑥,𝑥⟩>𝑡}=√𝑡𝐴1
• 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}=∫𝑒−𝐼(𝑥)
𝐴𝑡𝑑𝑥
Specific Case
Assume the components 𝑋𝑖 of 𝑋 are i.i.d. with density:
𝑤𝛼(𝑥)=𝛼1−1
𝛼
2𝛤(1
𝛼)exp(−|𝑥|𝛼
𝛼), 𝑥∈ℝ,𝛼>1
Conjecture 8.1.1: If 𝛼≠2 and 𝐶+𝐶𝑇 has no vanishing eigenvalue, then ∑ |𝑥𝑖|𝛼
𝑑
𝑖=1 admits a
finite number of minima in 𝐴1, and det𝐺𝐴1 is non-zero at these minima.
Results
For 𝛼≠2:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 𝛼𝑑−𝑑
𝛼
2𝑑𝛤(1
𝛼)𝑑𝑐1𝑒−𝑡𝛼/2𝐼(𝐴1)𝑡−(𝛼−2)𝑑
4−𝛼
4
where
𝑐1=(2𝜋)𝑑−1
2∑|𝐷𝐼(𝑥)|−𝑑+1
2
𝑥∈𝐷𝐴1(det𝐺𝐴1)−1
2
Note: 𝐷𝐼(𝑥)=(sign(𝑥𝑖)|𝑥𝑖|𝛼−1)1≤𝑖≤𝑑 for 𝛼 >1
Special Case: 𝛼=2
Let 𝜆 be the largest eigenvalue of 𝐶+𝐶𝑇 (assumed positive), and 𝐻={𝑥:(𝐶+𝐶𝑇)𝑥 =𝜆𝑥}
be the associated eigenspace.
Theorem 8.1.2
For 𝛼=2 and 𝜆>0:
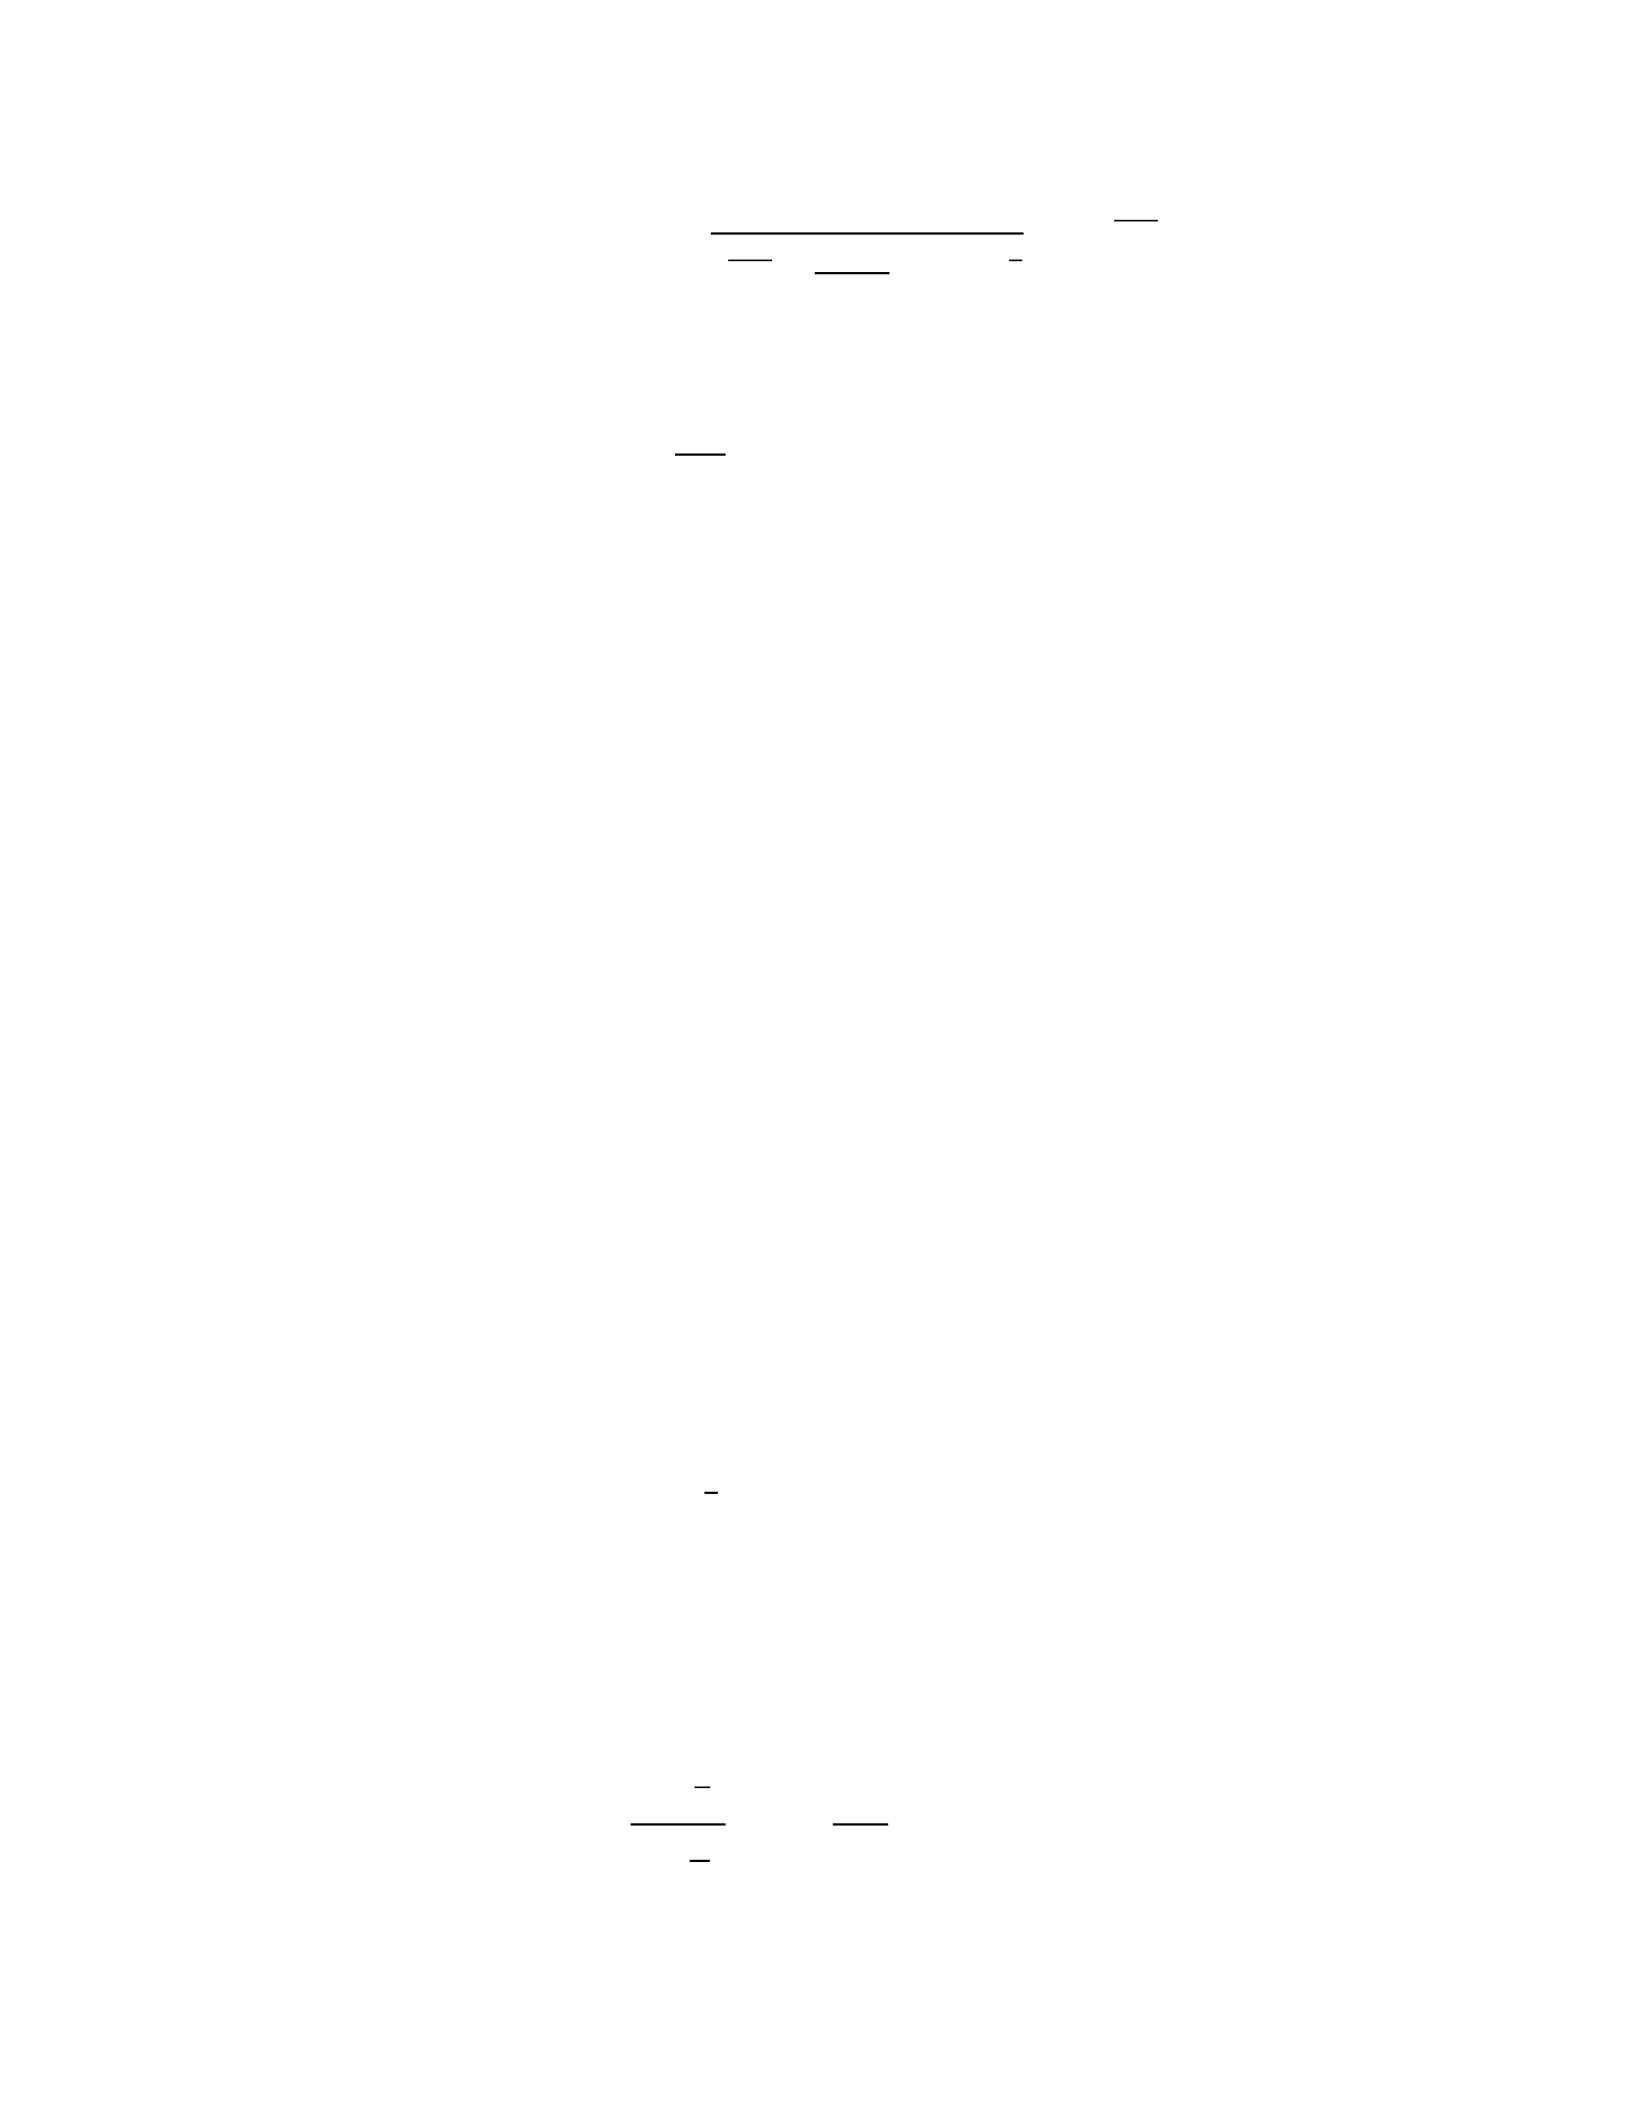
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 1
𝜆𝑘−1
2𝛤(𝑘+1
2)(det𝑀)1
2𝑒−𝑡/𝜆𝑡𝑘−1
2
where 𝑘=dim𝐻−1 and 𝑀 is the compression of 𝐼𝑑−𝜆−1(𝐶+𝐶𝑇) to 𝐻⊥.
Proof outline:
• 𝐷𝐴1 is the sphere of radius √2/𝜆 centered at the origin in 𝐻
• Apply Theorem 7.1
• Calculate 𝐼(𝐴1)=1/𝜆
• Determine 𝐺𝐴1 using second fundamental forms of 𝐼(𝐴1) and ∂𝐴1
These notes discuss the decay of probability 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡} as 𝑡 approaches infinity, where
𝑋 is a random vector in ℝ𝑑 and 𝐶 is a real 𝑑×𝑑 matrix.
Key points:
• The decay depends on the distribution of 𝑋 and matrix 𝐶
• Two types of distributions are considered: symmetric Weibull-like and Student-like
• Weibull-like tails are handled using Theorem 7.1
• Student-like tails are handled using a change of variable technique and Theorem 5.1
Light Tail Distribution Example
Setup
Consider a random vector 𝑋=(𝑋1,…,𝑋𝑑) in ℝ𝑑 with density 𝑓=𝑒−𝐼, where 𝐼 is a convex,
𝛼-positively homogeneous function on ℝ𝑑.
Important:
• 𝐴𝑡={𝑥∈ℝ𝑑:⟨𝐶𝑥,𝑥⟩>𝑡}=√𝑡𝐴1
• 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}=∫𝑒−𝐼(𝑥)
𝐴𝑡𝑑𝑥
Specific Case
Assume the components 𝑋𝑖 of 𝑋 are i.i.d. with density:
𝑤𝛼(𝑥)=𝛼1−1
𝛼
2𝛤(1
𝛼)exp(−|𝑥|𝛼
𝛼), 𝑥∈ℝ,𝛼>1
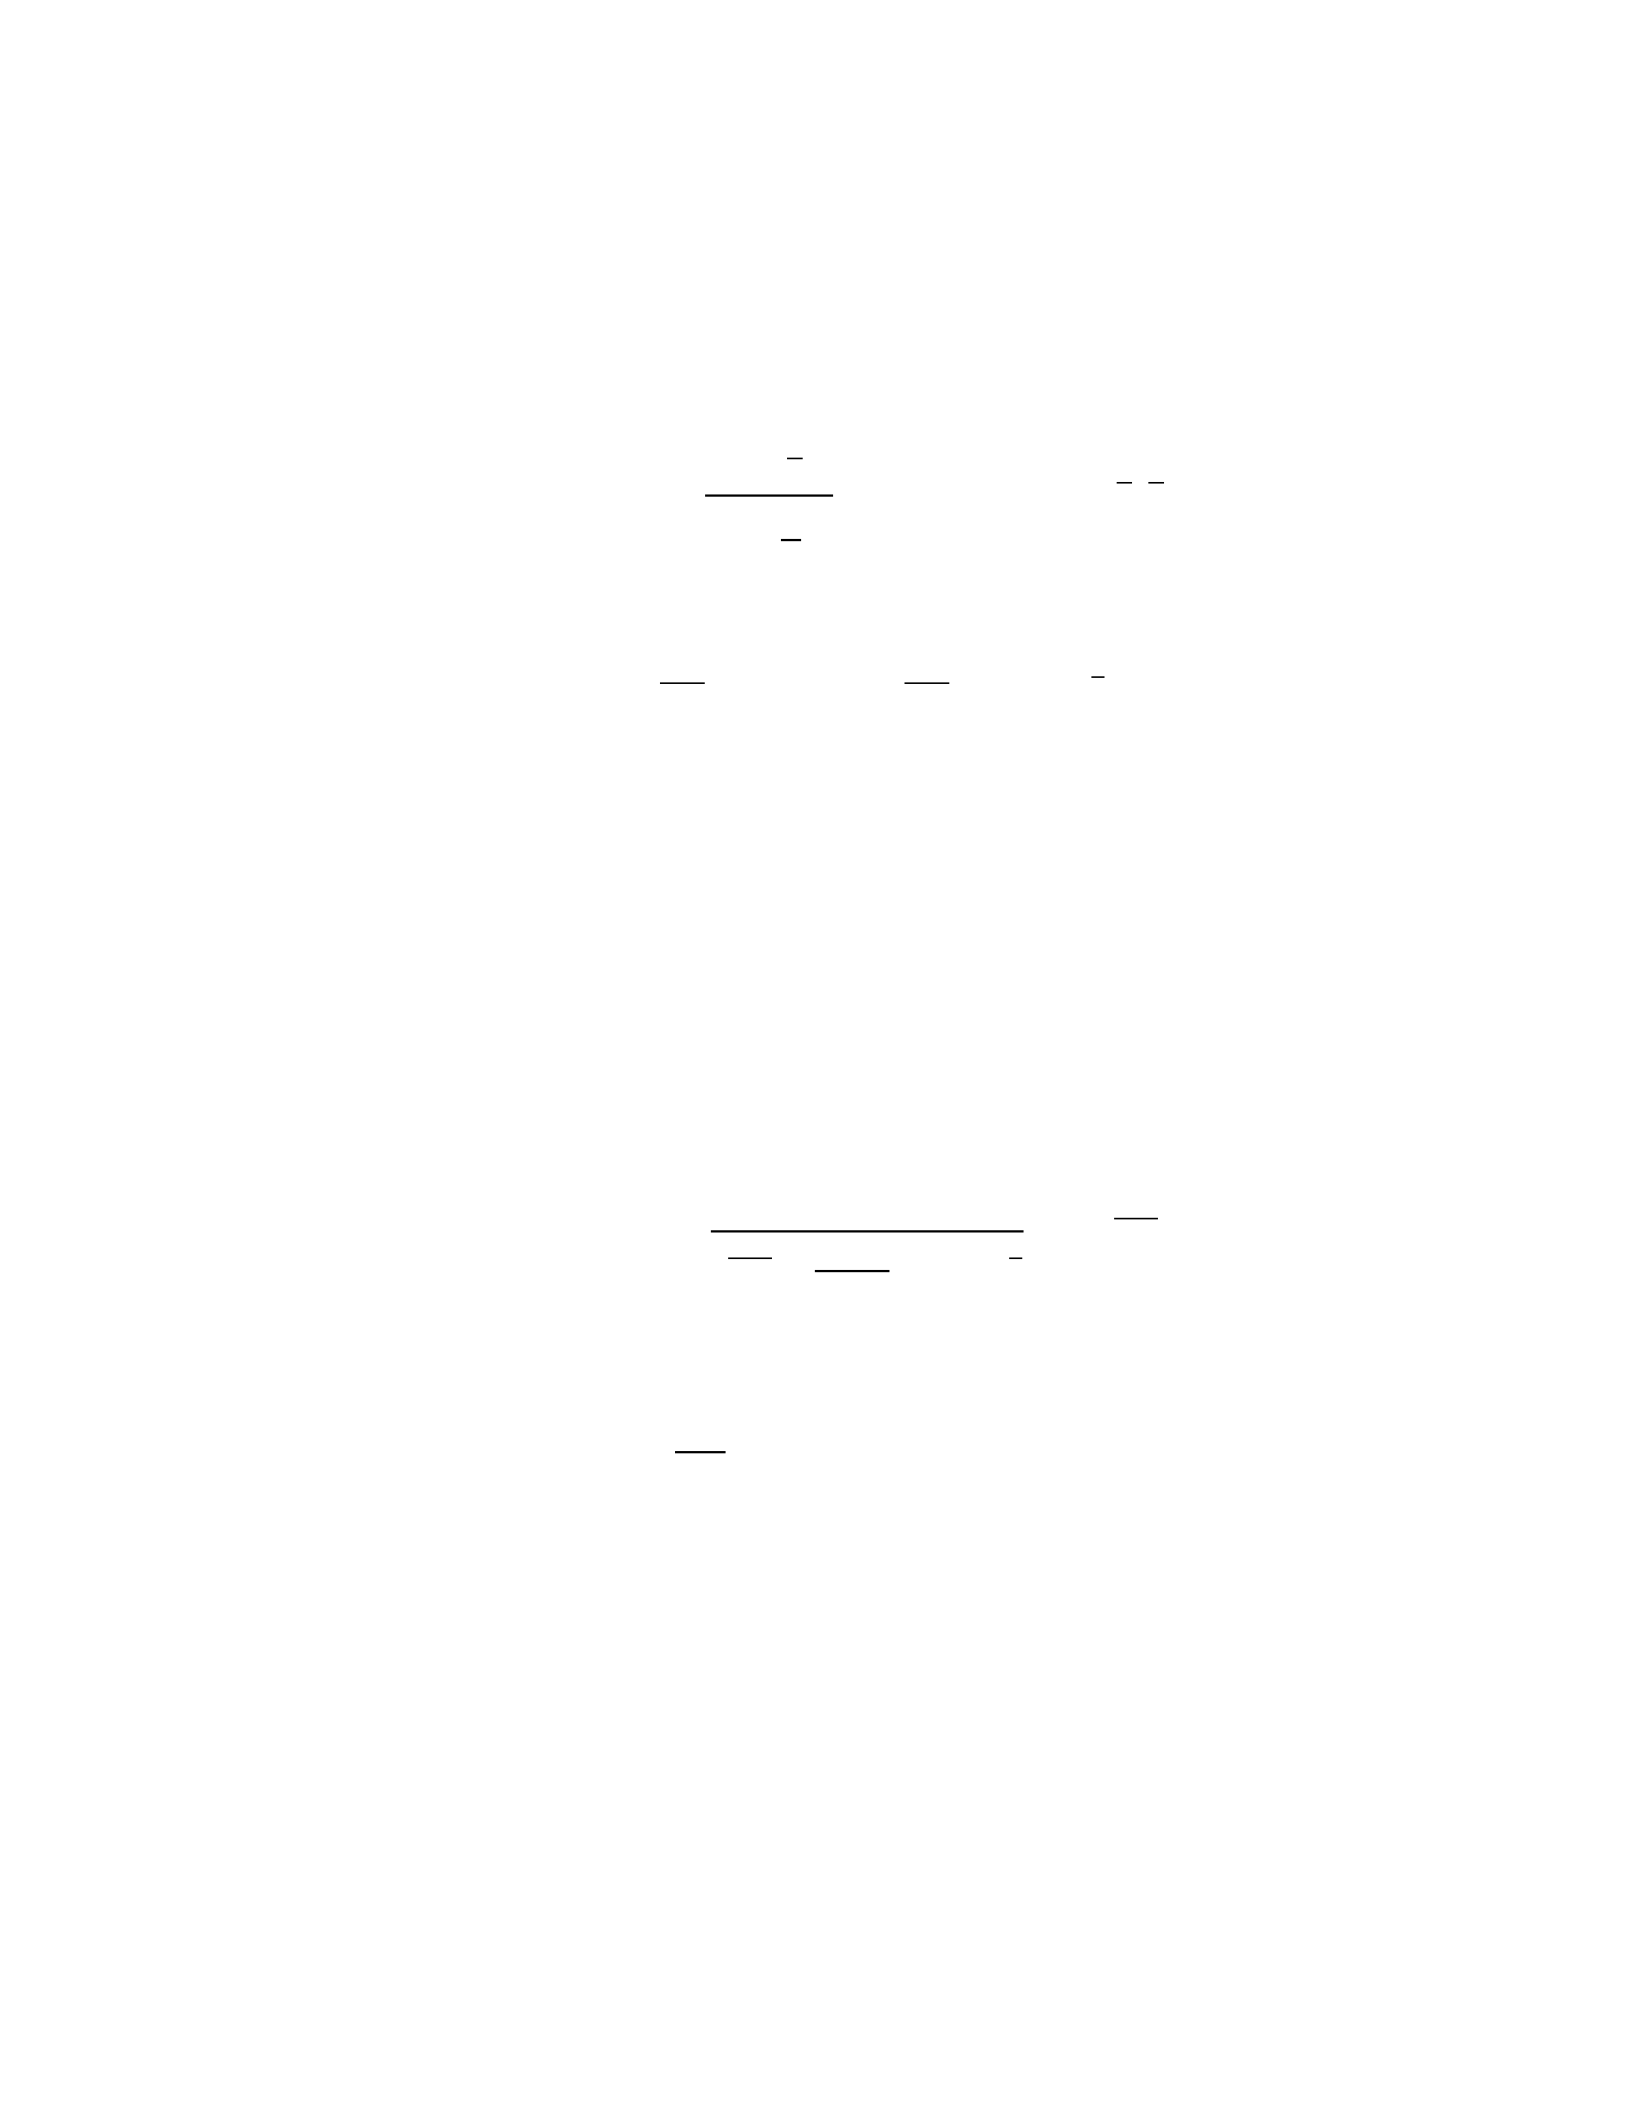
Conjecture 8.1.1: If 𝛼≠2 and 𝐶+𝐶𝑇 has no vanishing eigenvalue, then ∑ |𝑥𝑖|𝛼
𝑑
𝑖=1 admits a
finite number of minima in 𝐴1, and det𝐺𝐴1 is non-zero at these minima.
Results
For 𝛼≠2:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 𝛼𝑑−𝑑
𝛼
2𝑑𝛤(1
𝛼)𝑑𝑐1𝑒−𝑡𝛼/2𝐼(𝐴1)𝑡−(𝛼−2)𝑑
4−𝛼
4
where
𝑐1=(2𝜋)𝑑−1
2∑|𝐷𝐼(𝑥)|−𝑑+1
2
𝑥∈𝐷𝐴1(det𝐺𝐴1)−1
2
Note: 𝐷𝐼(𝑥)=(sign(𝑥𝑖)|𝑥𝑖|𝛼−1)1≤𝑖≤𝑑 for 𝛼 >1
Special Case: 𝛼=2
Let 𝜆 be the largest eigenvalue of 𝐶+𝐶𝑇 (assumed positive), and 𝐻={𝑥:(𝐶+𝐶𝑇)𝑥 =𝜆𝑥}
be the associated eigenspace.
Theorem 8.1.2
For 𝛼=2 and 𝜆>0:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 1
𝜆𝑘−1
2𝛤(𝑘+1
2)(det𝑀)1
2𝑒−𝑡/𝜆𝑡𝑘−1
2
where 𝑘=dim𝐻−1 and 𝑀 is the compression of 𝐼𝑑−𝜆−1(𝐶+𝐶𝑇) to 𝐻⊥.
Proof outline:
• 𝐷𝐴1 is the sphere of radius √2/𝜆 centered at the origin in 𝐻
• Apply Theorem 7.1
• Calculate 𝐼(𝐴1)=1/𝜆
• Determine 𝐺𝐴1 using second fundamental forms of 𝐼(𝐴1) and ∂𝐴1
These notes discuss the decay of probability 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡} as 𝑡 approaches infinity, where
𝑋 is a random vector in ℝ𝑑 and 𝐶 is a real 𝑑×𝑑 matrix.
Key points:
• The decay depends on the distribution of 𝑋 and matrix 𝐶

• Two types of distributions are considered: symmetric Weibull-like and Student-like
• Weibull-like tails are handled using Theorem 7.1
• Student-like tails are handled using a change of variable technique and Theorem 5.1
Light Tail Distribution Example
Setup
Consider a random vector 𝑋=(𝑋1,…,𝑋𝑑) in ℝ𝑑 with density 𝑓=𝑒−𝐼, where 𝐼 is a convex,
𝛼-positively homogeneous function on ℝ𝑑.
Important:
• 𝐴𝑡={𝑥∈ℝ𝑑:⟨𝐶𝑥,𝑥⟩>𝑡}=√𝑡𝐴1
• 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}=∫𝑒−𝐼(𝑥)
𝐴𝑡𝑑𝑥
Specific Case
Assume the components 𝑋𝑖 of 𝑋 are i.i.d. with density:
𝑤𝛼(𝑥)=𝛼1−1
𝛼
2𝛤(1
𝛼)exp(−|𝑥|𝛼
𝛼), 𝑥∈ℝ,𝛼>1
Conjecture 8.1.1: If 𝛼≠2 and 𝐶+𝐶𝑇 has no vanishing eigenvalue, then ∑ |𝑥𝑖|𝛼
𝑑
𝑖=1 admits a
finite number of minima in 𝐴1, and det𝐺𝐴1 is non-zero at these minima.
Results
For 𝛼≠2:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 𝛼𝑑−𝑑
𝛼
2𝑑𝛤(1
𝛼)𝑑𝑐1𝑒−𝑡𝛼/2𝐼(𝐴1)𝑡−(𝛼−2)𝑑
4−𝛼
4
where
𝑐1=(2𝜋)𝑑−1
2∑|𝐷𝐼(𝑥)|−𝑑+1
2
𝑥∈𝐷𝐴1(det𝐺𝐴1)−1
2
Note: 𝐷𝐼(𝑥)=(sign(𝑥𝑖)|𝑥𝑖|𝛼−1)1≤𝑖≤𝑑 for 𝛼 >1

Special Case: 𝛼=2
Let 𝜆 be the largest eigenvalue of 𝐶+𝐶𝑇 (assumed positive), and 𝐻={𝑥:(𝐶+𝐶𝑇)𝑥 =𝜆𝑥}
be the associated eigenspace.
Theorem 8.1.2
For 𝛼=2 and 𝜆>0:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 1
𝜆𝑘−1
2𝛤(𝑘+1
2)(det𝑀)1
2𝑒−𝑡/𝜆𝑡𝑘−1
2
where 𝑘=dim𝐻−1 and 𝑀 is the compression of 𝐼𝑑−𝜆−1(𝐶+𝐶𝑇) to 𝐻⊥.
Proof outline:
• 𝐷𝐴1 is the sphere of radius √2/𝜆 centered at the origin in 𝐻
• Apply Theorem 7.1
• Calculate 𝐼(𝐴1)=1/𝜆
• Determine 𝐺𝐴1 using second fundamental forms of 𝐼(𝐴1) and ∂𝐴1
These notes discuss the decay of probability 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡} as 𝑡 approaches infinity, where
𝑋 is a random vector in ℝ𝑑 and 𝐶 is a real 𝑑×𝑑 matrix.
Key points:
• The decay depends on the distribution of 𝑋 and matrix 𝐶
• Two types of distributions are considered: symmetric Weibull-like and Student-like
• Weibull-like tails are handled using Theorem 7.1
• Student-like tails are handled using a change of variable technique and Theorem 5.1
Light Tail Distribution Example
Setup
Consider a random vector 𝑋=(𝑋1,…,𝑋𝑑) in ℝ𝑑 with density 𝑓=𝑒−𝐼, where 𝐼 is a convex,
𝛼-positively homogeneous function on ℝ𝑑.
Important:
• 𝐴𝑡={𝑥∈ℝ𝑑:⟨𝐶𝑥,𝑥⟩>𝑡}=√𝑡𝐴1
• 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}=∫𝑒−𝐼(𝑥)
𝐴𝑡𝑑𝑥
Specific Case
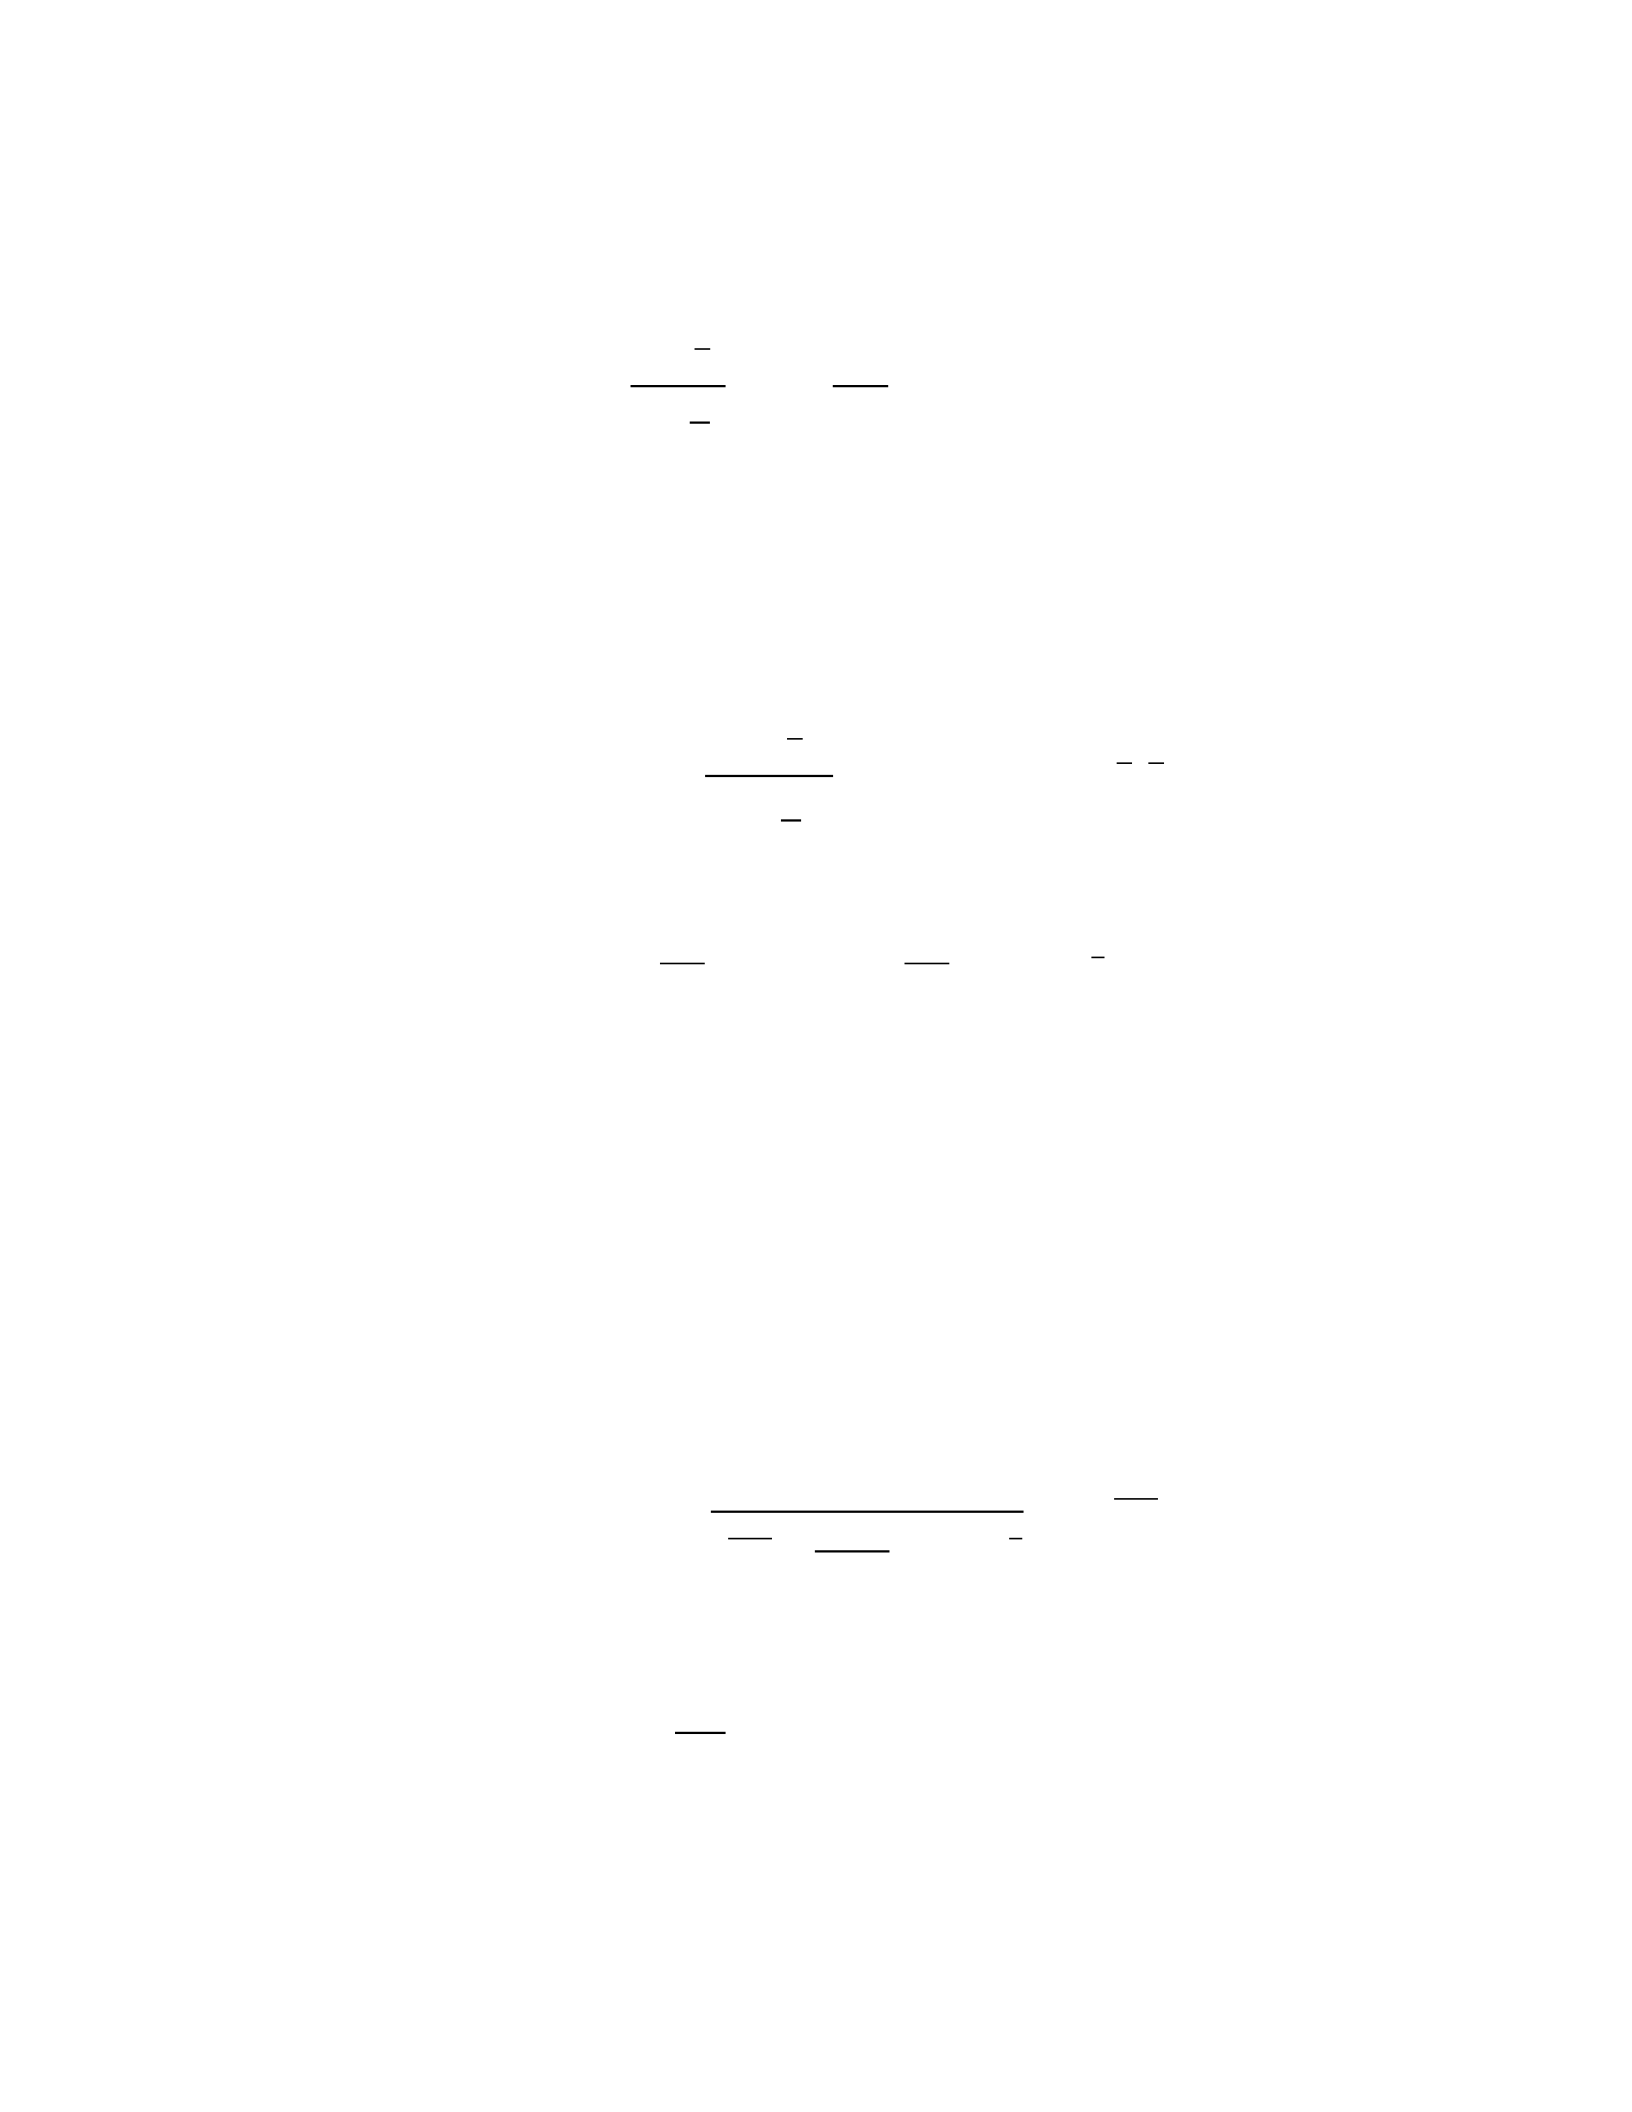
Assume the components 𝑋𝑖 of 𝑋 are i.i.d. with density:
𝑤𝛼(𝑥)=𝛼1−1
𝛼
2𝛤(1
𝛼)exp(−|𝑥|𝛼
𝛼), 𝑥∈ℝ,𝛼>1
Conjecture 8.1.1: If 𝛼≠2 and 𝐶+𝐶𝑇 has no vanishing eigenvalue, then ∑ |𝑥𝑖|𝛼
𝑑
𝑖=1 admits a
finite number of minima in 𝐴1, and det𝐺𝐴1 is non-zero at these minima.
Results
For 𝛼≠2:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 𝛼𝑑−𝑑
𝛼
2𝑑𝛤(1
𝛼)𝑑𝑐1𝑒−𝑡𝛼/2𝐼(𝐴1)𝑡−(𝛼−2)𝑑
4−𝛼
4
where
𝑐1=(2𝜋)𝑑−1
2∑|𝐷𝐼(𝑥)|−𝑑+1
2
𝑥∈𝐷𝐴1(det𝐺𝐴1)−1
2
Note: 𝐷𝐼(𝑥)=(sign(𝑥𝑖)|𝑥𝑖|𝛼−1)1≤𝑖≤𝑑 for 𝛼 >1
Special Case: 𝛼=2
Let 𝜆 be the largest eigenvalue of 𝐶+𝐶𝑇 (assumed positive), and 𝐻={𝑥:(𝐶+𝐶𝑇)𝑥 =𝜆𝑥}
be the associated eigenspace.
Theorem 8.1.2
For 𝛼=2 and 𝜆>0:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 1
𝜆𝑘−1
2𝛤(𝑘+1
2)(det𝑀)1
2𝑒−𝑡/𝜆𝑡𝑘−1
2
where 𝑘=dim𝐻−1 and 𝑀 is the compression of 𝐼𝑑−𝜆−1(𝐶+𝐶𝑇) to 𝐻⊥.
Proof outline:
• 𝐷𝐴1 is the sphere of radius √2/𝜆 centered at the origin in 𝐻
• Apply Theorem 7.1
• Calculate 𝐼(𝐴1)=1/𝜆

• Determine 𝐺𝐴1 using second fundamental forms of 𝐼(𝐴1) and ∂𝐴1
These notes discuss the decay of probability 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡} as 𝑡 approaches infinity, where
𝑋 is a random vector in ℝ𝑑 and 𝐶 is a real 𝑑×𝑑 matrix.
Key points:
• The decay depends on the distribution of 𝑋 and matrix 𝐶
• Two types of distributions are considered: symmetric Weibull-like and Student-like
• Weibull-like tails are handled using Theorem 7.1
• Student-like tails are handled using a change of variable technique and Theorem 5.1
Light Tail Distribution Example
Setup
Consider a random vector 𝑋=(𝑋1,…,𝑋𝑑) in ℝ𝑑 with density 𝑓=𝑒−𝐼, where 𝐼 is a convex,
𝛼-positively homogeneous function on ℝ𝑑.
Important:
• 𝐴𝑡={𝑥∈ℝ𝑑:⟨𝐶𝑥,𝑥⟩>𝑡}=√𝑡𝐴1
• 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}=∫𝑒−𝐼(𝑥)
𝐴𝑡𝑑𝑥
Specific Case
Assume the components 𝑋𝑖 of 𝑋 are i.i.d. with density:
𝑤𝛼(𝑥)=𝛼1−1
𝛼
2𝛤(1
𝛼)exp(−|𝑥|𝛼
𝛼), 𝑥∈ℝ,𝛼>1
Conjecture 8.1.1: If 𝛼≠2 and 𝐶+𝐶𝑇 has no vanishing eigenvalue, then ∑ |𝑥𝑖|𝛼
𝑑
𝑖=1 admits a
finite number of minima in 𝐴1, and det𝐺𝐴1 is non-zero at these minima.
Results
For 𝛼≠2:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 𝛼𝑑−𝑑
𝛼
2𝑑𝛤(1
𝛼)𝑑𝑐1𝑒−𝑡𝛼/2𝐼(𝐴1)𝑡−(𝛼−2)𝑑
4−𝛼
4
where
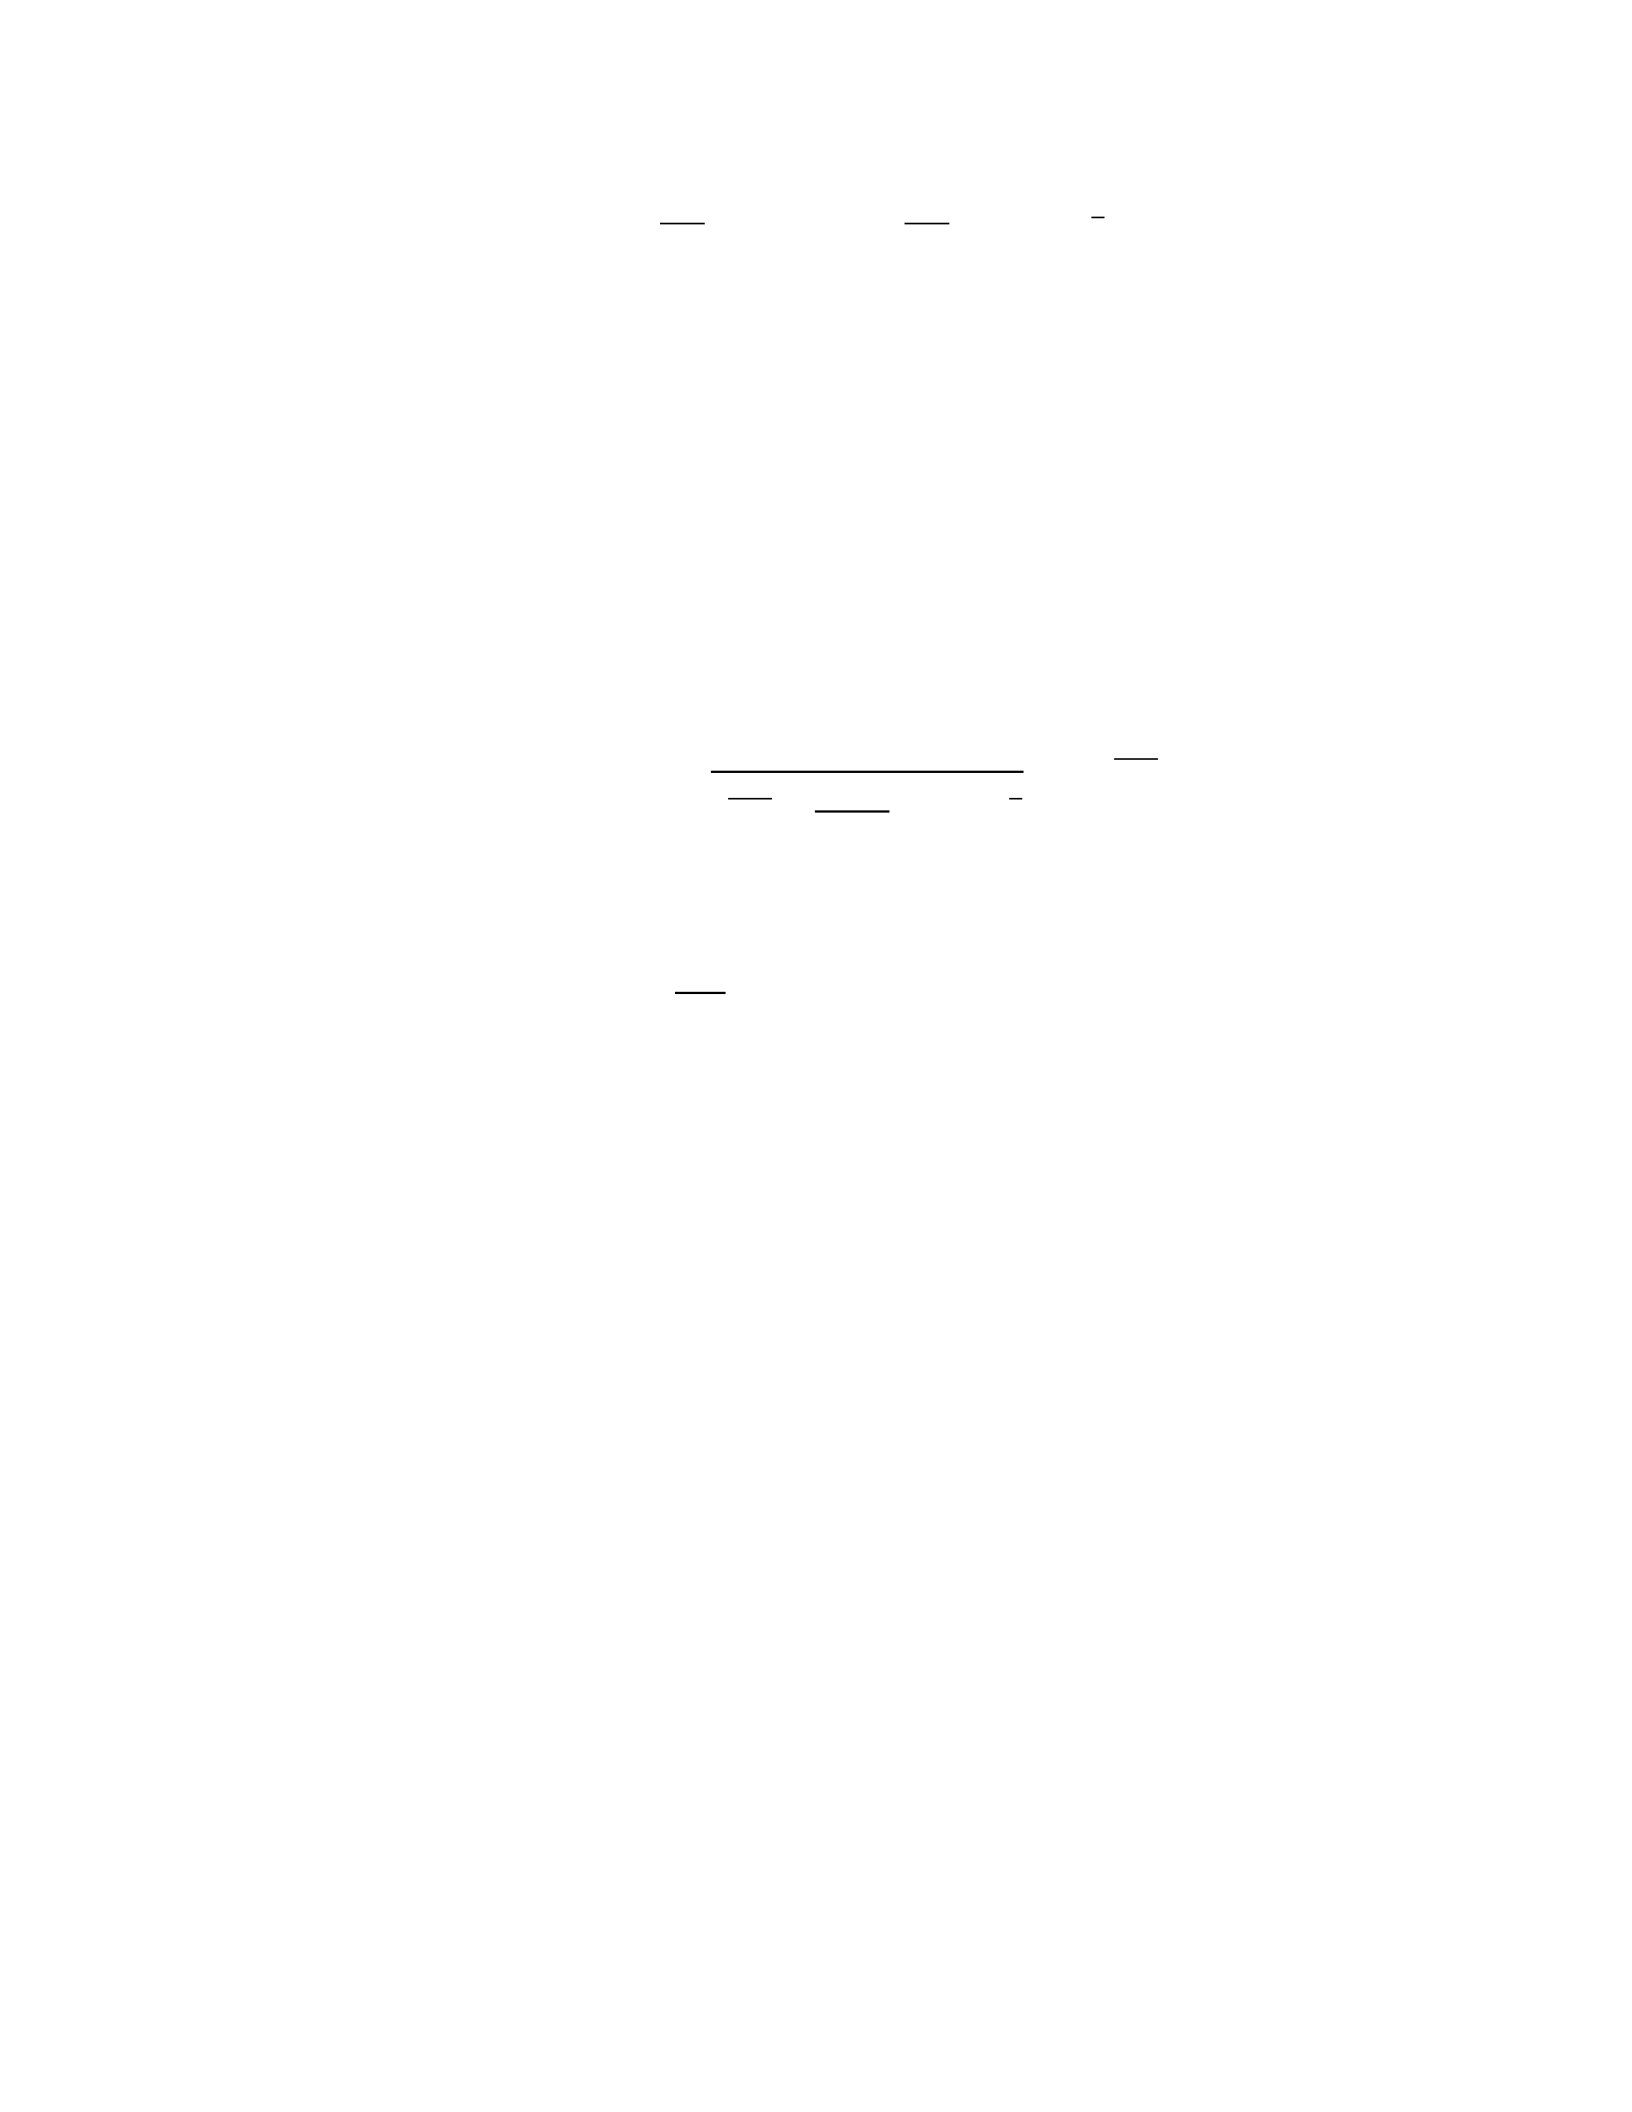
𝑐1=(2𝜋)𝑑−1
2∑|𝐷𝐼(𝑥)|−𝑑+1
2
𝑥∈𝐷𝐴1(det𝐺𝐴1)−1
2
Note: 𝐷𝐼(𝑥)=(sign(𝑥𝑖)|𝑥𝑖|𝛼−1)1≤𝑖≤𝑑 for 𝛼 >1
Special Case: 𝛼=2
Let 𝜆 be the largest eigenvalue of 𝐶+𝐶𝑇 (assumed positive), and 𝐻={𝑥:(𝐶+𝐶𝑇)𝑥 =𝜆𝑥}
be the associated eigenspace.
Theorem 8.1.2
For 𝛼=2 and 𝜆>0:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 1
𝜆𝑘−1
2𝛤(𝑘+1
2)(det𝑀)1
2𝑒−𝑡/𝜆𝑡𝑘−1
2
where 𝑘=dim𝐻−1 and 𝑀 is the compression of 𝐼𝑑−𝜆−1(𝐶+𝐶𝑇) to 𝐻⊥.
Proof outline:
• 𝐷𝐴1 is the sphere of radius √2/𝜆 centered at the origin in 𝐻
• Apply Theorem 7.1
• Calculate 𝐼(𝐴1)=1/𝜆
• Determine 𝐺𝐴1 using second fundamental forms of 𝐼(𝐴1) and ∂𝐴1
These notes discuss the decay of probability 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡} as 𝑡 approaches infinity, where
𝑋 is a random vector in ℝ𝑑 and 𝐶 is a real 𝑑×𝑑 matrix.
Key points:
• The decay depends on the distribution of 𝑋 and matrix 𝐶
• Two types of distributions are considered: symmetric Weibull-like and Student-like
• Weibull-like tails are handled using Theorem 7.1
• Student-like tails are handled using a change of variable technique and Theorem 5.1

Light Tail Distribution Example
Setup
Consider a random vector 𝑋=(𝑋1,…,𝑋𝑑) in ℝ𝑑 with density 𝑓=𝑒−𝐼, where 𝐼 is a convex,
𝛼-positively homogeneous function on ℝ𝑑.
Important:
• 𝐴𝑡={𝑥∈ℝ𝑑:⟨𝐶𝑥,𝑥⟩>𝑡}=√𝑡𝐴1
• 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}=∫𝑒−𝐼(𝑥)
𝐴𝑡𝑑𝑥
Specific Case
Assume the components 𝑋𝑖 of 𝑋 are i.i.d. with density:
𝑤𝛼(𝑥)=𝛼1−1
𝛼
2𝛤(1
𝛼)exp(−|𝑥|𝛼
𝛼), 𝑥∈ℝ,𝛼>1
Conjecture 8.1.1: If 𝛼≠2 and 𝐶+𝐶𝑇 has no vanishing eigenvalue, then ∑ |𝑥𝑖|𝛼
𝑑
𝑖=1 admits a
finite number of minima in 𝐴1, and det𝐺𝐴1 is non-zero at these minima.
Results
For 𝛼≠2:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 𝛼𝑑−𝑑
𝛼
2𝑑𝛤(1
𝛼)𝑑𝑐1𝑒−𝑡𝛼/2𝐼(𝐴1)𝑡−(𝛼−2)𝑑
4−𝛼
4
where
𝑐1=(2𝜋)𝑑−1
2∑|𝐷𝐼(𝑥)|−𝑑+1
2
𝑥∈𝐷𝐴1(det𝐺𝐴1)−1
2
Note: 𝐷𝐼(𝑥)=(sign(𝑥𝑖)|𝑥𝑖|𝛼−1)1≤𝑖≤𝑑 for 𝛼 >1
Special Case: 𝛼=2
Let 𝜆 be the largest eigenvalue of 𝐶+𝐶𝑇 (assumed positive), and 𝐻={𝑥:(𝐶+𝐶𝑇)𝑥 =𝜆𝑥}
be the associated eigenspace.
Theorem 8.1.2
For 𝛼=2 and 𝜆>0:
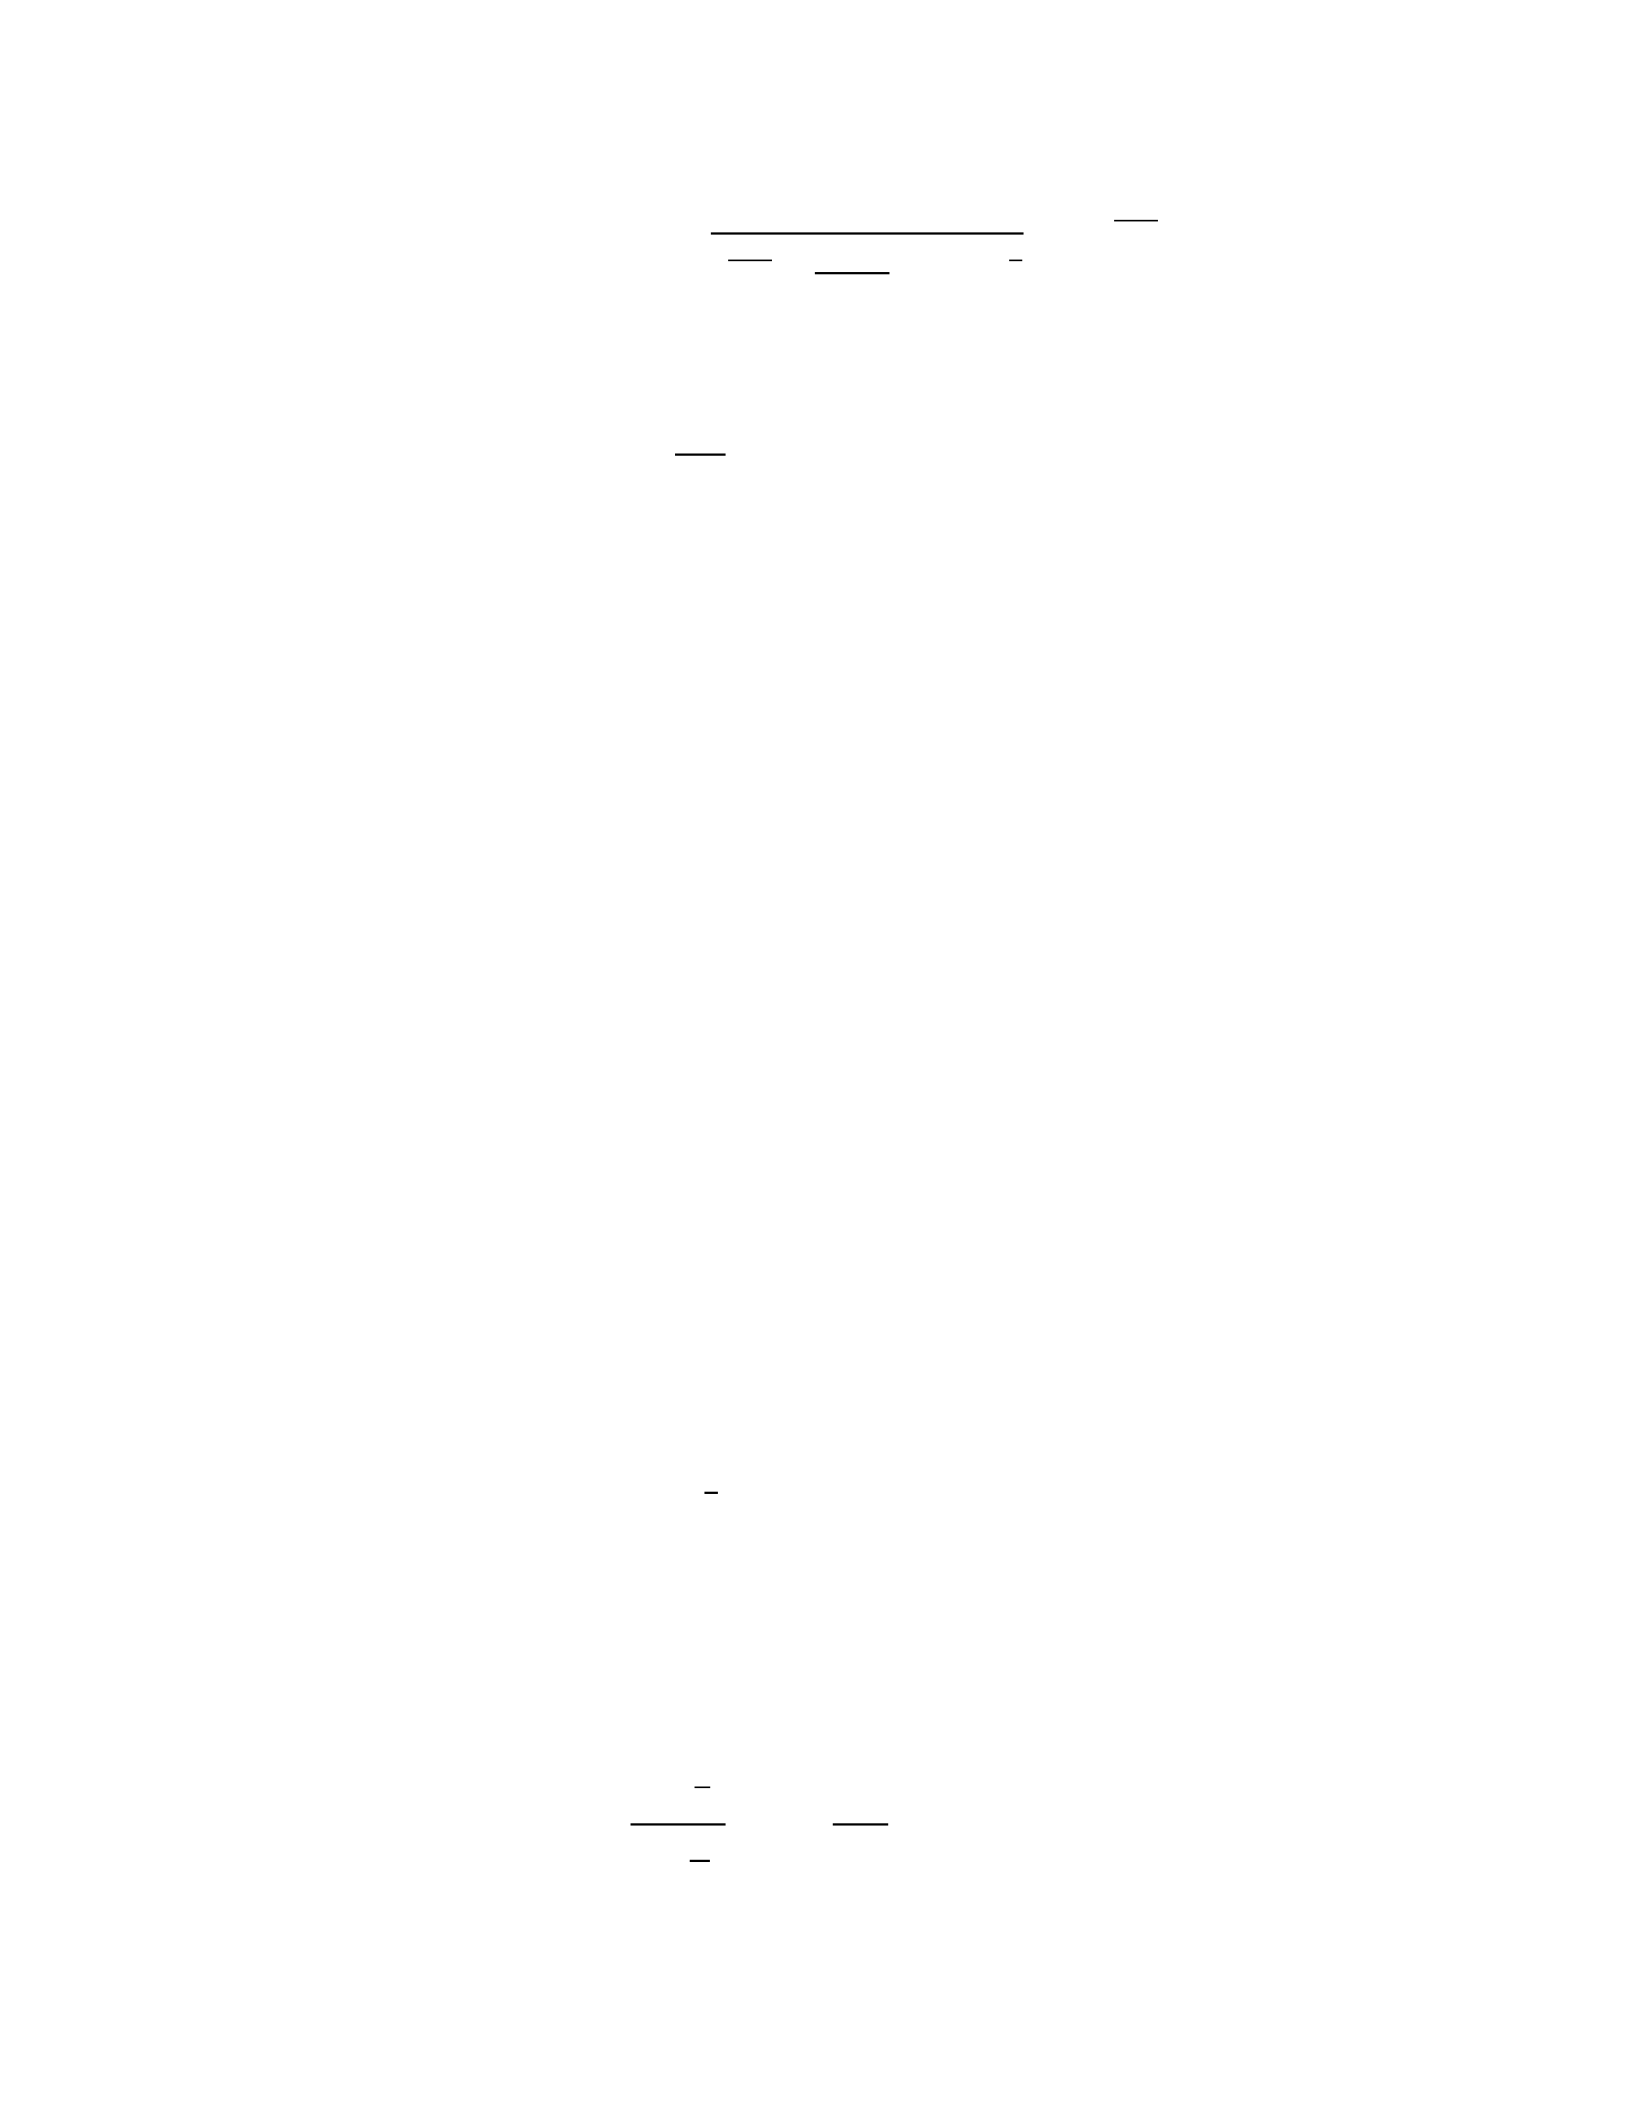
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 1
𝜆𝑘−1
2𝛤(𝑘+1
2)(det𝑀)1
2𝑒−𝑡/𝜆𝑡𝑘−1
2
where 𝑘=dim𝐻−1 and 𝑀 is the compression of 𝐼𝑑−𝜆−1(𝐶+𝐶𝑇) to 𝐻⊥.
Proof outline:
• 𝐷𝐴1 is the sphere of radius √2/𝜆 centered at the origin in 𝐻
• Apply Theorem 7.1
• Calculate 𝐼(𝐴1)=1/𝜆
• Determine 𝐺𝐴1 using second fundamental forms of 𝐼(𝐴1) and ∂𝐴1
These notes discuss the decay of probability 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡} as 𝑡 approaches infinity, where
𝑋 is a random vector in ℝ𝑑 and 𝐶 is a real 𝑑×𝑑 matrix.
Key points:
• The decay depends on the distribution of 𝑋 and matrix 𝐶
• Two types of distributions are considered: symmetric Weibull-like and Student-like
• Weibull-like tails are handled using Theorem 7.1
• Student-like tails are handled using a change of variable technique and Theorem 5.1
Light Tail Distribution Example
Setup
Consider a random vector 𝑋=(𝑋1,…,𝑋𝑑) in ℝ𝑑 with density 𝑓=𝑒−𝐼, where 𝐼 is a convex,
𝛼-positively homogeneous function on ℝ𝑑.
Important:
• 𝐴𝑡={𝑥∈ℝ𝑑:⟨𝐶𝑥,𝑥⟩>𝑡}=√𝑡𝐴1
• 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}=∫𝑒−𝐼(𝑥)
𝐴𝑡𝑑𝑥
Specific Case
Assume the components 𝑋𝑖 of 𝑋 are i.i.d. with density:
𝑤𝛼(𝑥)=𝛼1−1
𝛼
2𝛤(1
𝛼)exp(−|𝑥|𝛼
𝛼), 𝑥∈ℝ,𝛼>1
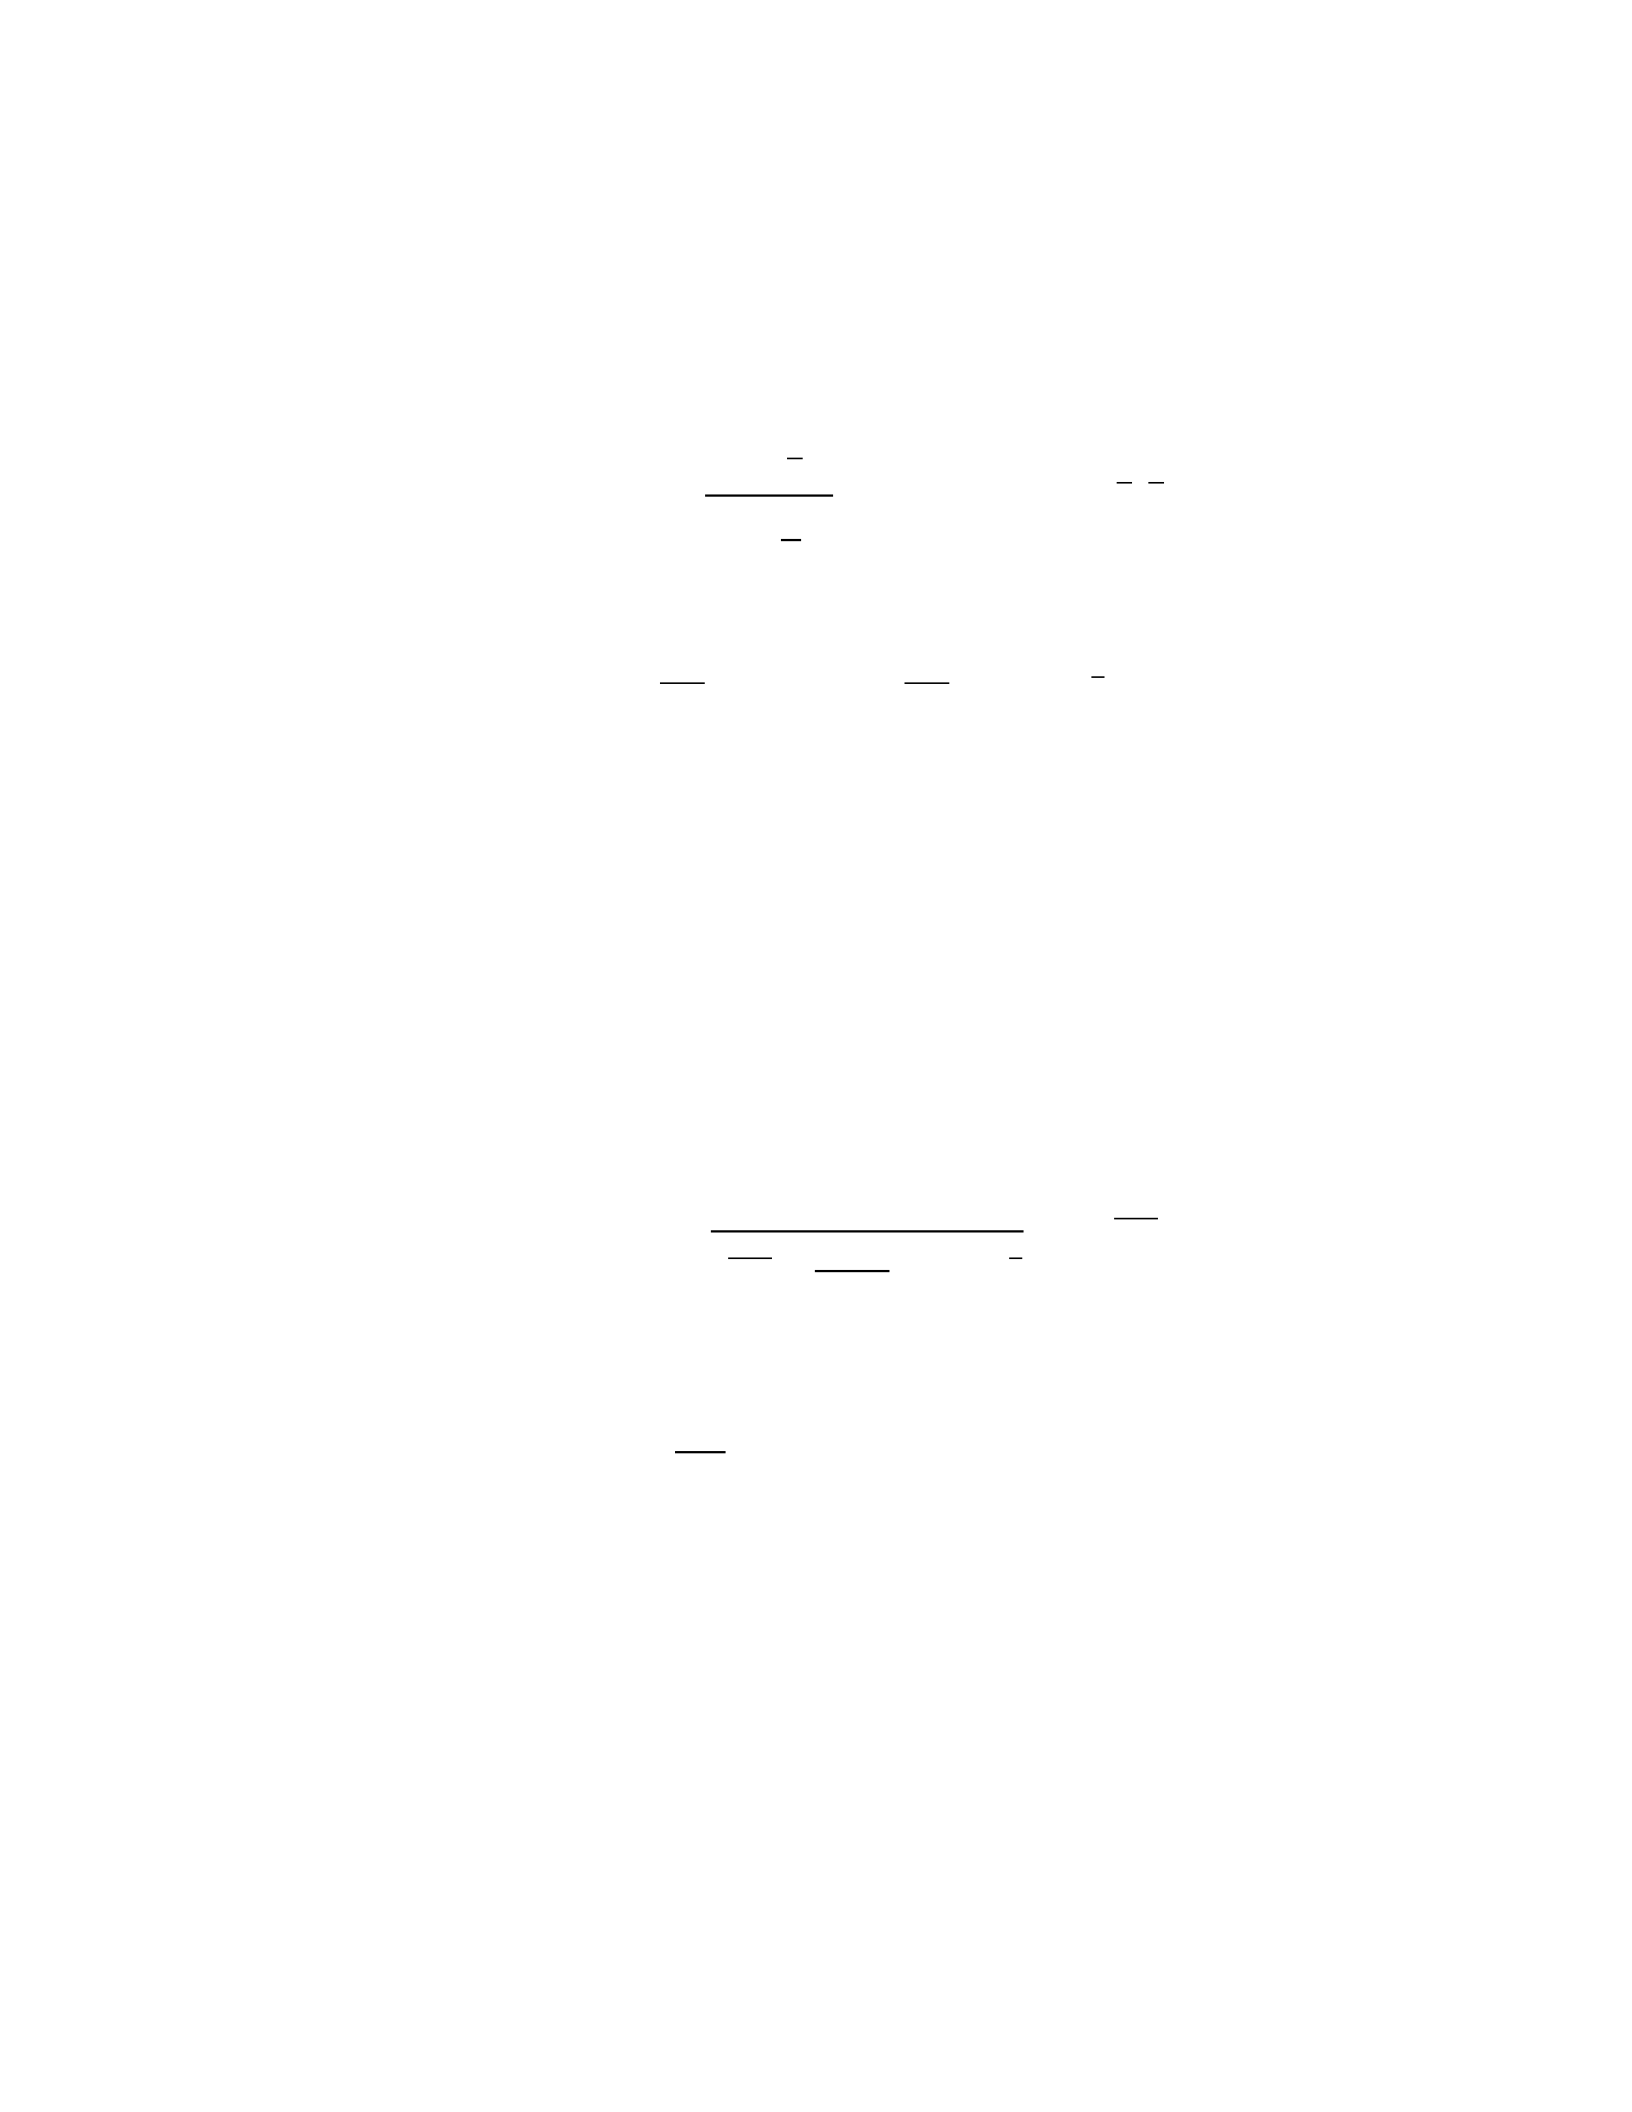
Conjecture 8.1.1: If 𝛼≠2 and 𝐶+𝐶𝑇 has no vanishing eigenvalue, then ∑ |𝑥𝑖|𝛼
𝑑
𝑖=1 admits a
finite number of minima in 𝐴1, and det𝐺𝐴1 is non-zero at these minima.
Results
For 𝛼≠2:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 𝛼𝑑−𝑑
𝛼
2𝑑𝛤(1
𝛼)𝑑𝑐1𝑒−𝑡𝛼/2𝐼(𝐴1)𝑡−(𝛼−2)𝑑
4−𝛼
4
where
𝑐1=(2𝜋)𝑑−1
2∑|𝐷𝐼(𝑥)|−𝑑+1
2
𝑥∈𝐷𝐴1(det𝐺𝐴1)−1
2
Note: 𝐷𝐼(𝑥)=(sign(𝑥𝑖)|𝑥𝑖|𝛼−1)1≤𝑖≤𝑑 for 𝛼 >1
Special Case: 𝛼=2
Let 𝜆 be the largest eigenvalue of 𝐶+𝐶𝑇 (assumed positive), and 𝐻={𝑥:(𝐶+𝐶𝑇)𝑥 =𝜆𝑥}
be the associated eigenspace.
Theorem 8.1.2
For 𝛼=2 and 𝜆>0:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 1
𝜆𝑘−1
2𝛤(𝑘+1
2)(det𝑀)1
2𝑒−𝑡/𝜆𝑡𝑘−1
2
where 𝑘=dim𝐻−1 and 𝑀 is the compression of 𝐼𝑑−𝜆−1(𝐶+𝐶𝑇) to 𝐻⊥.
Proof outline:
• 𝐷𝐴1 is the sphere of radius √2/𝜆 centered at the origin in 𝐻
• Apply Theorem 7.1
• Calculate 𝐼(𝐴1)=1/𝜆
• Determine 𝐺𝐴1 using second fundamental forms of 𝐼(𝐴1) and ∂𝐴1
These notes discuss the decay of probability 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡} as 𝑡 approaches infinity, where
𝑋 is a random vector in ℝ𝑑 and 𝐶 is a real 𝑑×𝑑 matrix.
Key points:
• The decay depends on the distribution of 𝑋 and matrix 𝐶
• Two types of distributions are considered: symmetric Weibull-like and Student-like
• Weibull-like tails are handled using Theorem 7.1
• Student-like tails are handled using a change of variable technique and Theorem 5.1
Light Tail Distribution Example
Setup
Consider a random vector 𝑋=(𝑋1,…,𝑋𝑑) in ℝ𝑑 with density 𝑓=𝑒−𝐼, where 𝐼 is a convex,
𝛼-positively homogeneous function on ℝ𝑑.
Important:
• 𝐴𝑡={𝑥∈ℝ𝑑:⟨𝐶𝑥,𝑥⟩>𝑡}=√𝑡𝐴1
• 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}=∫𝑒−𝐼(𝑥)
𝐴𝑡𝑑𝑥
Specific Case
Assume the components 𝑋𝑖 of 𝑋 are i.i.d. with density:
𝑤𝛼(𝑥)=𝛼1−1
𝛼
2𝛤(1
𝛼)exp(−|𝑥|𝛼
𝛼), 𝑥∈ℝ,𝛼>1
Conjecture 8.1.1: If 𝛼≠2 and 𝐶+𝐶𝑇 has no vanishing eigenvalue, then ∑ |𝑥𝑖|𝛼
𝑑
𝑖=1 admits a
finite number of minima in 𝐴1, and det𝐺𝐴1 is non-zero at these minima.
Results
For 𝛼≠2:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 𝛼𝑑−𝑑
𝛼
2𝑑𝛤(1
𝛼)𝑑𝑐1𝑒−𝑡𝛼/2𝐼(𝐴1)𝑡−(𝛼−2)𝑑
4−𝛼
4
where
𝑐1=(2𝜋)𝑑−1
2∑|𝐷𝐼(𝑥)|−𝑑+1
2
𝑥∈𝐷𝐴1(det𝐺𝐴1)−1
2
Note: 𝐷𝐼(𝑥)=(sign(𝑥𝑖)|𝑥𝑖|𝛼−1)1≤𝑖≤𝑑 for 𝛼 >1
Special Case: 𝛼=2
Let 𝜆 be the largest eigenvalue of 𝐶+𝐶𝑇 (assumed positive), and 𝐻={𝑥:(𝐶+𝐶𝑇)𝑥 =𝜆𝑥}
be the associated eigenspace.
Theorem 8.1.2
For 𝛼=2 and 𝜆>0:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 1
𝜆𝑘−1
2𝛤(𝑘+1
2)(det𝑀)1
2𝑒−𝑡/𝜆𝑡𝑘−1
2
where 𝑘=dim𝐻−1 and 𝑀 is the compression of 𝐼𝑑−𝜆−1(𝐶+𝐶𝑇) to 𝐻⊥.
Proof outline:
• 𝐷𝐴1 is the sphere of radius √2/𝜆 centered at the origin in 𝐻
• Apply Theorem 7.1
• Calculate 𝐼(𝐴1)=1/𝜆
• Determine 𝐺𝐴1 using second fundamental forms of 𝐼(𝐴1) and ∂𝐴1
These notes discuss the decay of probability 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡} as 𝑡 approaches infinity, where
𝑋 is a random vector in ℝ𝑑 and 𝐶 is a real 𝑑×𝑑 matrix.
Key points:
• The decay depends on the distribution of 𝑋 and matrix 𝐶
• Two types of distributions are considered: symmetric Weibull-like and Student-like
• Weibull-like tails are handled using Theorem 7.1
• Student-like tails are handled using a change of variable technique and Theorem 5.1
Light Tail Distribution Example
Setup
Consider a random vector 𝑋=(𝑋1,…,𝑋𝑑) in ℝ𝑑 with density 𝑓=𝑒−𝐼, where 𝐼 is a convex,
𝛼-positively homogeneous function on ℝ𝑑.
Important:
• 𝐴𝑡={𝑥∈ℝ𝑑:⟨𝐶𝑥,𝑥⟩>𝑡}=√𝑡𝐴1
• 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}=∫𝑒−𝐼(𝑥)
𝐴𝑡𝑑𝑥
Specific Case
Assume the components 𝑋𝑖 of 𝑋 are i.i.d. with density:
𝑤𝛼(𝑥)=𝛼1−1
𝛼
2𝛤(1
𝛼)exp(−|𝑥|𝛼
𝛼), 𝑥∈ℝ,𝛼>1
Conjecture 8.1.1: If 𝛼≠2 and 𝐶+𝐶𝑇 has no vanishing eigenvalue, then ∑ |𝑥𝑖|𝛼
𝑑
𝑖=1 admits a
finite number of minima in 𝐴1, and det𝐺𝐴1 is non-zero at these minima.
Results
For 𝛼≠2:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 𝛼𝑑−𝑑
𝛼
2𝑑𝛤(1
𝛼)𝑑𝑐1𝑒−𝑡𝛼/2𝐼(𝐴1)𝑡−(𝛼−2)𝑑
4−𝛼
4
where
𝑐1=(2𝜋)𝑑−1
2∑|𝐷𝐼(𝑥)|−𝑑+1
2
𝑥∈𝐷𝐴1(det𝐺𝐴1)−1
2
Note: 𝐷𝐼(𝑥)=(sign(𝑥𝑖)|𝑥𝑖|𝛼−1)1≤𝑖≤𝑑 for 𝛼 >1
Special Case: 𝛼=2
Let 𝜆 be the largest eigenvalue of 𝐶+𝐶𝑇 (assumed positive), and 𝐻={𝑥:(𝐶+𝐶𝑇)𝑥 =𝜆𝑥}
be the associated eigenspace.
Theorem 8.1.2
For 𝛼=2 and 𝜆>0:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 1
𝜆𝑘−1
2𝛤(𝑘+1
2)(det𝑀)1
2𝑒−𝑡/𝜆𝑡𝑘−1
2
where 𝑘=dim𝐻−1 and 𝑀 is the compression of 𝐼𝑑−𝜆−1(𝐶+𝐶𝑇) to 𝐻⊥.
Proof outline:
• 𝐷𝐴1 is the sphere of radius √2/𝜆 centered at the origin in 𝐻
• Apply Theorem 7.1
• Calculate 𝐼(𝐴1)=1/𝜆
• Determine 𝐺𝐴1 using second fundamental forms of 𝐼(𝐴1) and ∂𝐴1
These notes discuss the decay of probability 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡} as 𝑡 approaches infinity, where
𝑋 is a random vector in ℝ𝑑 and 𝐶 is a real 𝑑×𝑑 matrix.
Key points:
• The decay depends on the distribution of 𝑋 and matrix 𝐶
• Two types of distributions are considered: symmetric Weibull-like and Student-like
• Weibull-like tails are handled using Theorem 7.1
• Student-like tails are handled using a change of variable technique and Theorem 5.1
Light Tail Distribution Example
Setup
Consider a random vector 𝑋=(𝑋1,…,𝑋𝑑) in ℝ𝑑 with density 𝑓=𝑒−𝐼, where 𝐼 is a convex,
𝛼-positively homogeneous function on ℝ𝑑.
Important:
• 𝐴𝑡={𝑥∈ℝ𝑑:⟨𝐶𝑥,𝑥⟩>𝑡}=√𝑡𝐴1
• 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}=∫𝑒−𝐼(𝑥)
𝐴𝑡𝑑𝑥
Specific Case
Assume the components 𝑋𝑖 of 𝑋 are i.i.d. with density:
𝑤𝛼(𝑥)=𝛼1−1
𝛼
2𝛤(1
𝛼)exp(−|𝑥|𝛼
𝛼), 𝑥∈ℝ,𝛼>1
Conjecture 8.1.1: If 𝛼≠2 and 𝐶+𝐶𝑇 has no vanishing eigenvalue, then ∑ |𝑥𝑖|𝛼
𝑑
𝑖=1 admits a
finite number of minima in 𝐴1, and det𝐺𝐴1 is non-zero at these minima.
Results
For 𝛼≠2:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 𝛼𝑑−𝑑
𝛼
2𝑑𝛤(1
𝛼)𝑑𝑐1𝑒−𝑡𝛼/2𝐼(𝐴1)𝑡−(𝛼−2)𝑑
4−𝛼
4
where

𝑐1=(2𝜋)𝑑−1
2∑|𝐷𝐼(𝑥)|−𝑑+1
2
𝑥∈𝐷𝐴1(det𝐺𝐴1)−1
2
Note: 𝐷𝐼(𝑥)=(sign(𝑥𝑖)|𝑥𝑖|𝛼−1)1≤𝑖≤𝑑 for 𝛼 >1
Special Case: 𝛼=2
Let 𝜆 be the largest eigenvalue of 𝐶+𝐶𝑇 (assumed positive), and 𝐻={𝑥:(𝐶+𝐶𝑇)𝑥 =𝜆𝑥}
be the associated eigenspace.
Theorem 8.1.2
For 𝛼=2 and 𝜆>0:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 1
𝜆𝑘−1
2𝛤(𝑘+1
2)(det𝑀)1
2𝑒−𝑡/𝜆𝑡𝑘−1
2
where 𝑘=dim𝐻−1 and 𝑀 is the compression of 𝐼𝑑−𝜆−1(𝐶+𝐶𝑇) to 𝐻⊥.
Proof outline:
• 𝐷𝐴1 is the sphere of radius √2/𝜆 centered at the origin in 𝐻
• Apply Theorem 7.1
• Calculate 𝐼(𝐴1)=1/𝜆
• Determine 𝐺𝐴1 using second fundamental forms of 𝐼(𝐴1) and ∂𝐴1
These notes discuss the decay of probability 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡} as 𝑡 approaches infinity, where
𝑋 is a random vector in ℝ𝑑 and 𝐶 is a real 𝑑×𝑑 matrix.
Key points:
• The decay depends on the distribution of 𝑋 and matrix 𝐶
• Two types of distributions are considered: symmetric Weibull-like and Student-like
• Weibull-like tails are handled using Theorem 7.1
• Student-like tails are handled using a change of variable technique and Theorem 5.1

Light Tail Distribution Example
Setup
Consider a random vector 𝑋=(𝑋1,…,𝑋𝑑) in ℝ𝑑 with density 𝑓=𝑒−𝐼, where 𝐼 is a convex,
𝛼-positively homogeneous function on ℝ𝑑.
Important:
• 𝐴𝑡={𝑥∈ℝ𝑑:⟨𝐶𝑥,𝑥⟩>𝑡}=√𝑡𝐴1
• 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}=∫𝑒−𝐼(𝑥)
𝐴𝑡𝑑𝑥
Specific Case
Assume the components 𝑋𝑖 of 𝑋 are i.i.d. with density:
𝑤𝛼(𝑥)=𝛼1−1
𝛼
2𝛤(1
𝛼)exp(−|𝑥|𝛼
𝛼), 𝑥∈ℝ,𝛼>1
Conjecture 8.1.1: If 𝛼≠2 and 𝐶+𝐶𝑇 has no vanishing eigenvalue, then ∑ |𝑥𝑖|𝛼
𝑑
𝑖=1 admits a
finite number of minima in 𝐴1, and det𝐺𝐴1 is non-zero at these minima.
Results
For 𝛼≠2:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 𝛼𝑑−𝑑
𝛼
2𝑑𝛤(1
𝛼)𝑑𝑐1𝑒−𝑡𝛼/2𝐼(𝐴1)𝑡−(𝛼−2)𝑑
4−𝛼
4
where
𝑐1=(2𝜋)𝑑−1
2∑|𝐷𝐼(𝑥)|−𝑑+1
2
𝑥∈𝐷𝐴1(det𝐺𝐴1)−1
2
Note: 𝐷𝐼(𝑥)=(sign(𝑥𝑖)|𝑥𝑖|𝛼−1)1≤𝑖≤𝑑 for 𝛼 >1
Special Case: 𝛼=2
Let 𝜆 be the largest eigenvalue of 𝐶+𝐶𝑇 (assumed positive), and 𝐻={𝑥:(𝐶+𝐶𝑇)𝑥 =𝜆𝑥}
be the associated eigenspace.
Theorem 8.1.2
For 𝛼=2 and 𝜆>0:
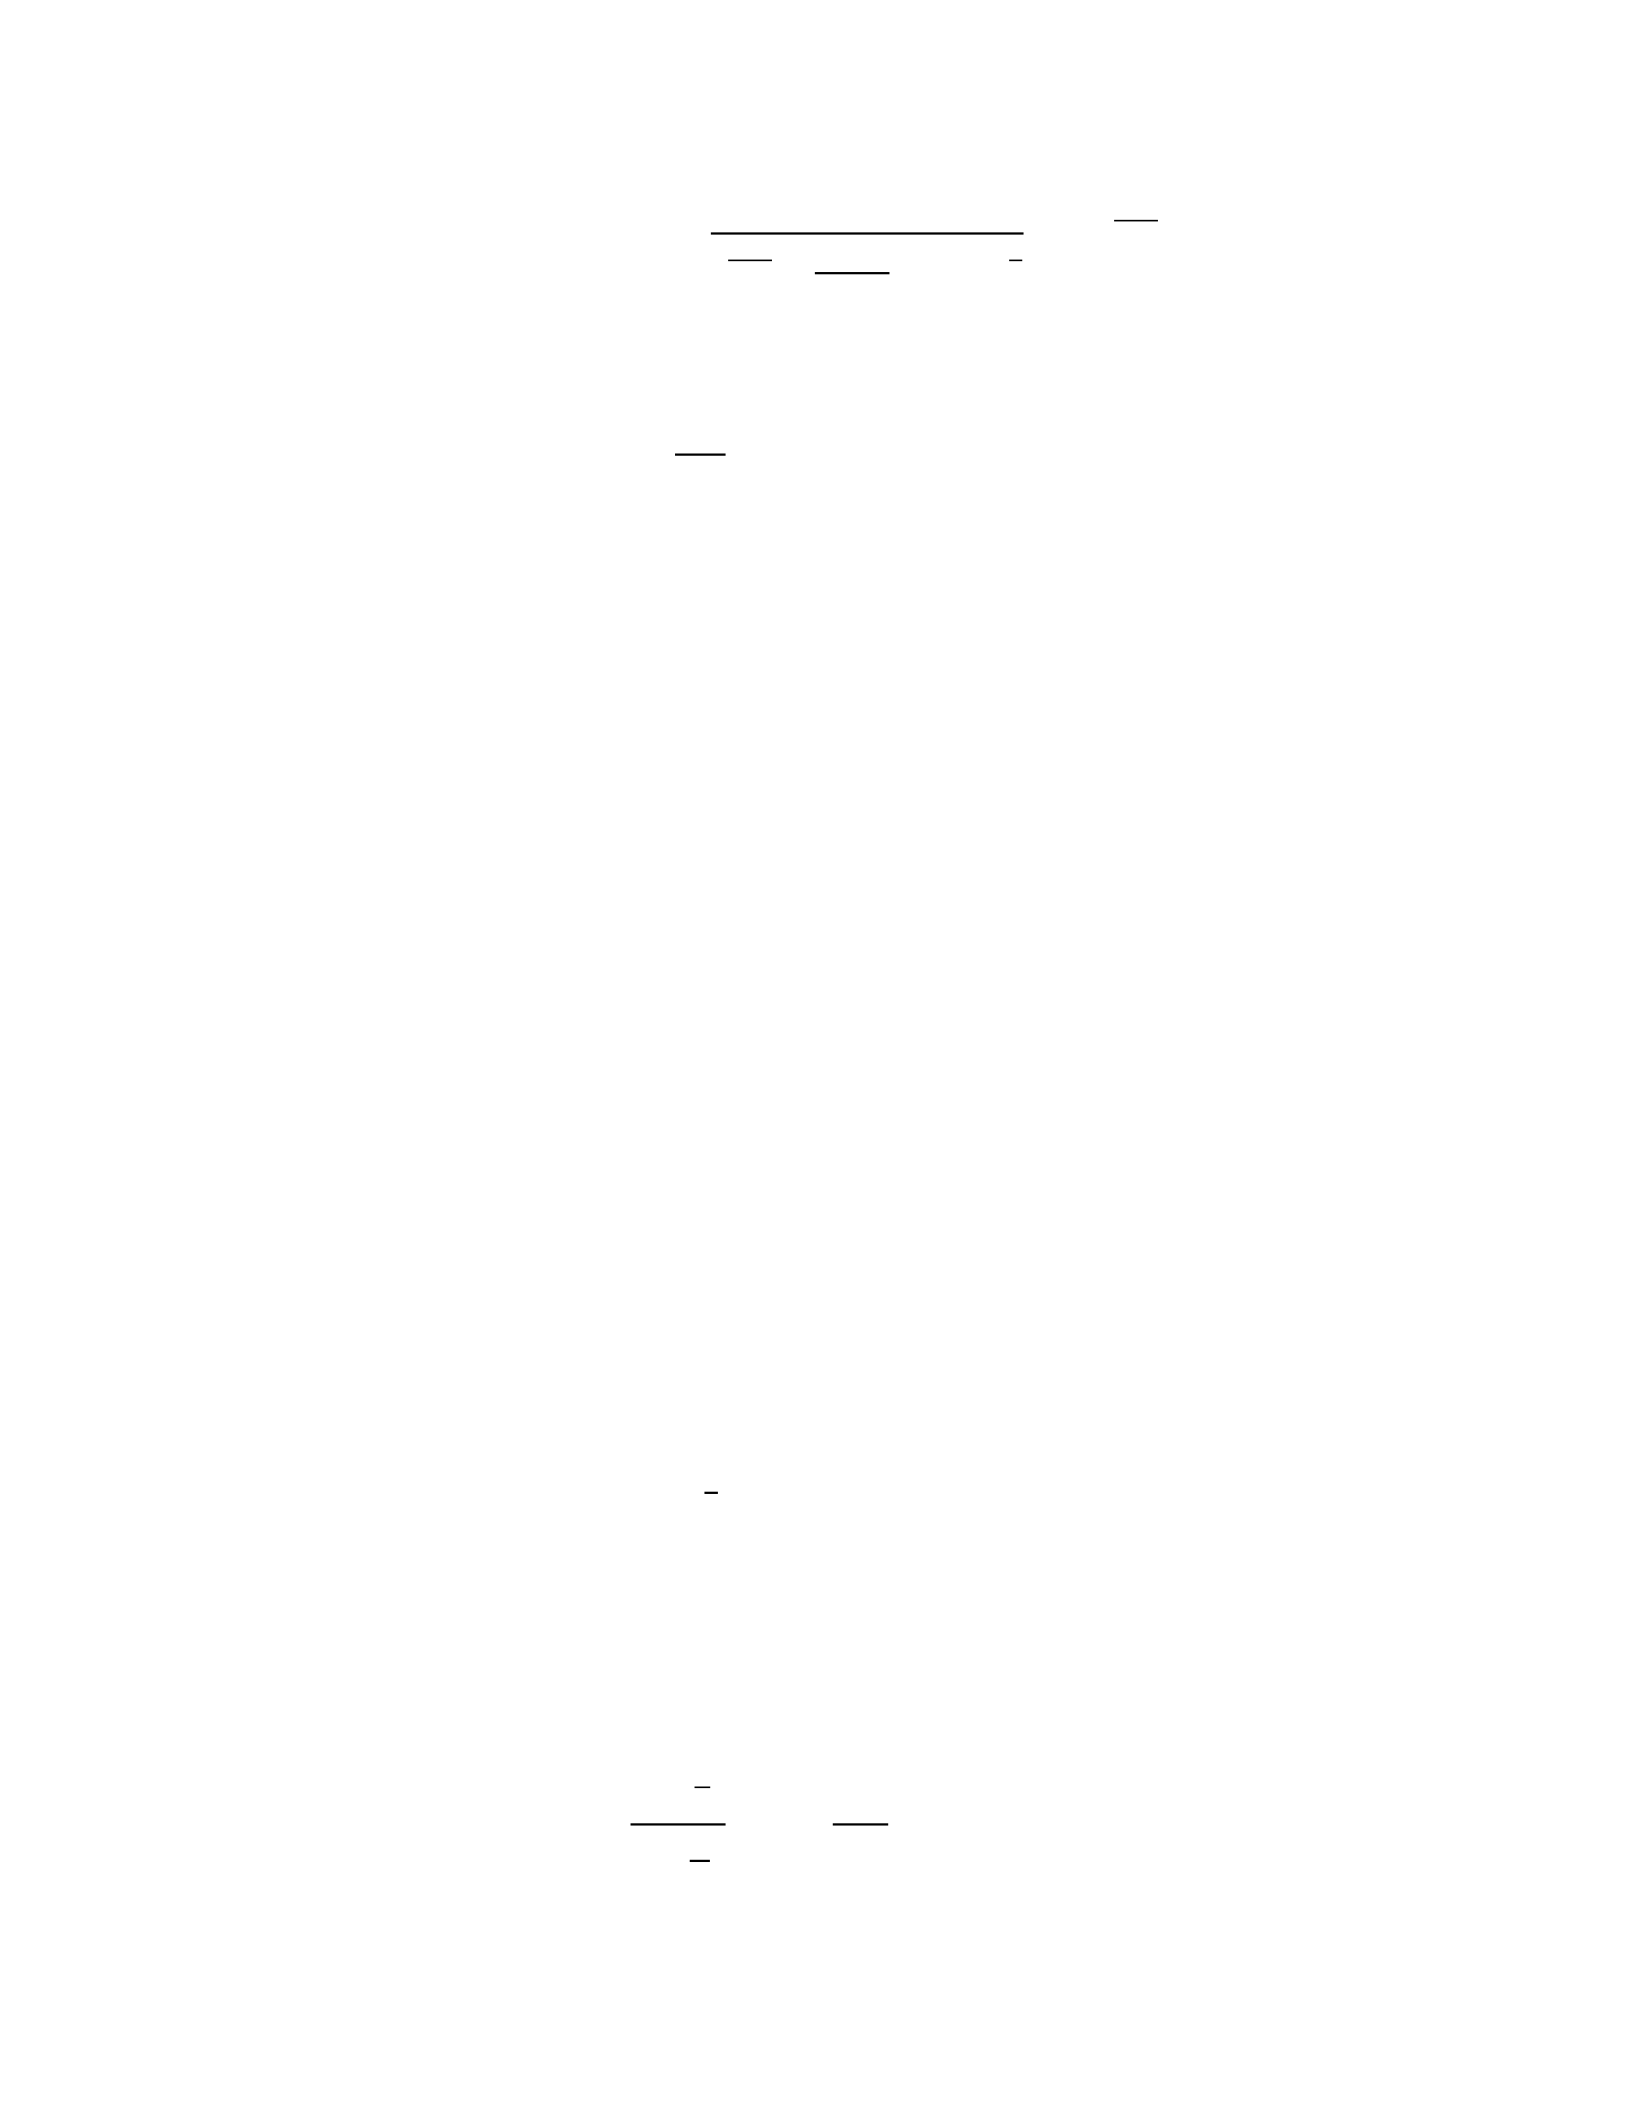
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 1
𝜆𝑘−1
2𝛤(𝑘+1
2)(det𝑀)1
2𝑒−𝑡/𝜆𝑡𝑘−1
2
where 𝑘=dim𝐻−1 and 𝑀 is the compression of 𝐼𝑑−𝜆−1(𝐶+𝐶𝑇) to 𝐻⊥.
Proof outline:
• 𝐷𝐴1 is the sphere of radius √2/𝜆 centered at the origin in 𝐻
• Apply Theorem 7.1
• Calculate 𝐼(𝐴1)=1/𝜆
• Determine 𝐺𝐴1 using second fundamental forms of 𝐼(𝐴1) and ∂𝐴1
These notes discuss the decay of probability 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡} as 𝑡 approaches infinity, where
𝑋 is a random vector in ℝ𝑑 and 𝐶 is a real 𝑑×𝑑 matrix.
Key points:
• The decay depends on the distribution of 𝑋 and matrix 𝐶
• Two types of distributions are considered: symmetric Weibull-like and Student-like
• Weibull-like tails are handled using Theorem 7.1
• Student-like tails are handled using a change of variable technique and Theorem 5.1
Light Tail Distribution Example
Setup
Consider a random vector 𝑋=(𝑋1,…,𝑋𝑑) in ℝ𝑑 with density 𝑓=𝑒−𝐼, where 𝐼 is a convex,
𝛼-positively homogeneous function on ℝ𝑑.
Important:
• 𝐴𝑡={𝑥∈ℝ𝑑:⟨𝐶𝑥,𝑥⟩>𝑡}=√𝑡𝐴1
• 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}=∫𝑒−𝐼(𝑥)
𝐴𝑡𝑑𝑥
Specific Case
Assume the components 𝑋𝑖 of 𝑋 are i.i.d. with density:
𝑤𝛼(𝑥)=𝛼1−1
𝛼
2𝛤(1
𝛼)exp(−|𝑥|𝛼
𝛼), 𝑥∈ℝ,𝛼>1
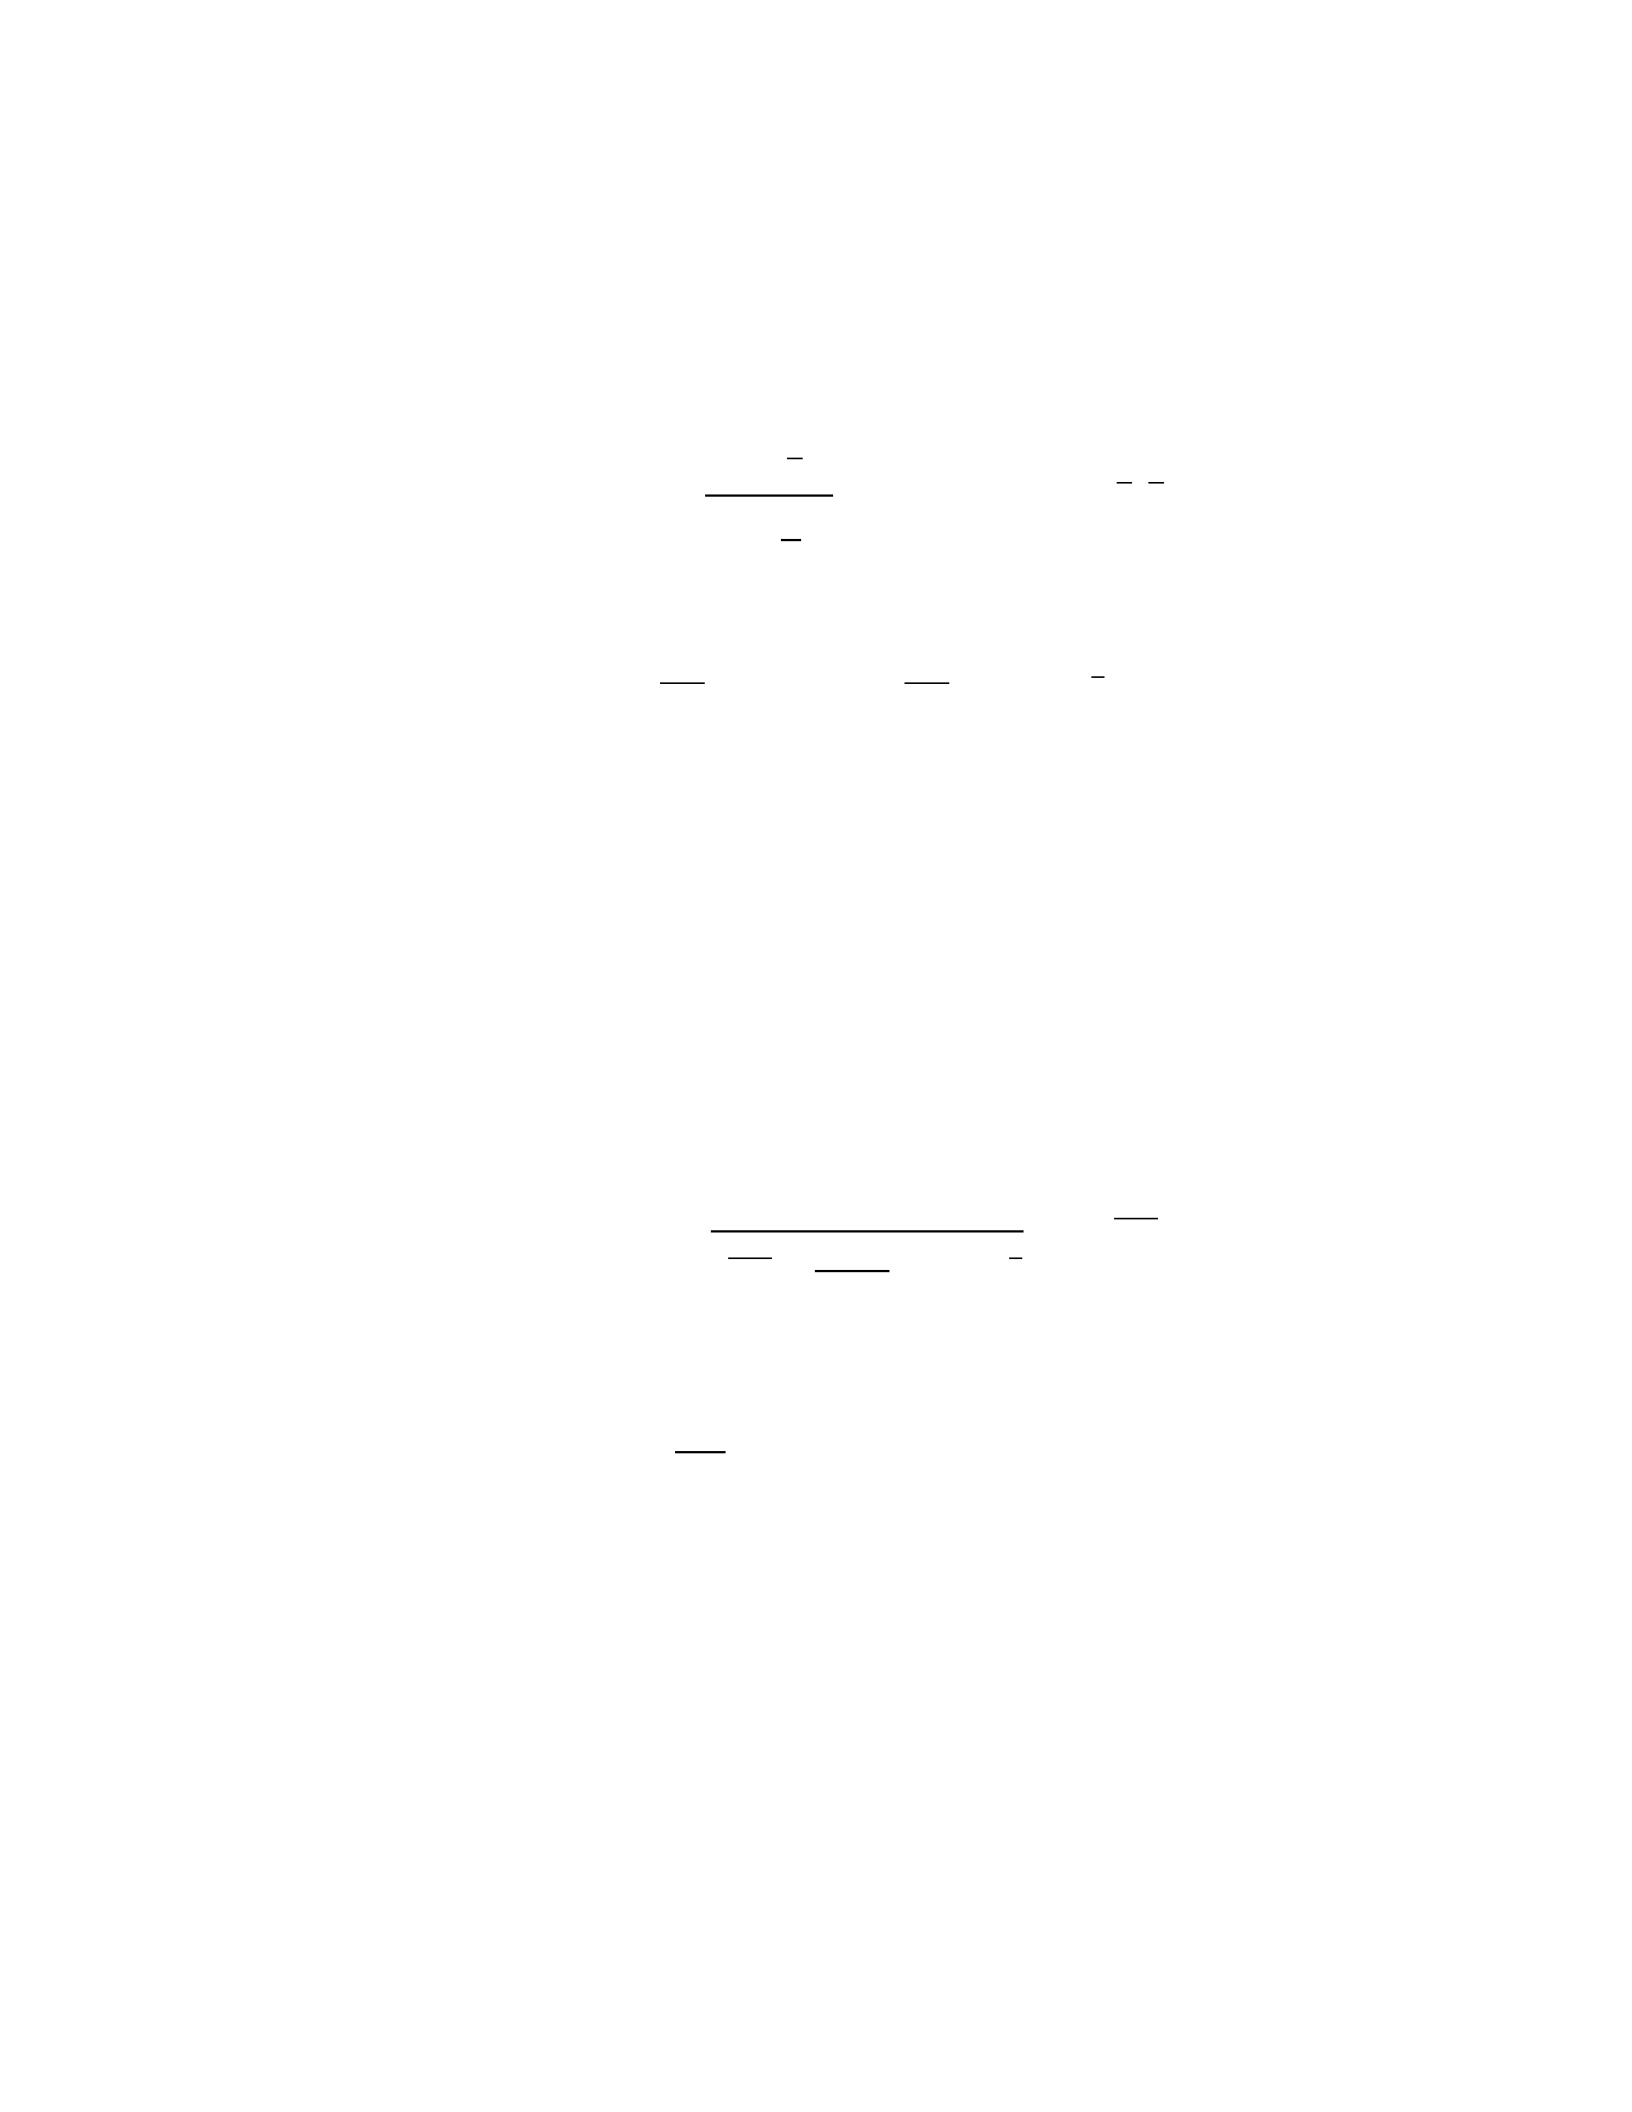
Conjecture 8.1.1: If 𝛼≠2 and 𝐶+𝐶𝑇 has no vanishing eigenvalue, then ∑ |𝑥𝑖|𝛼
𝑑
𝑖=1 admits a
finite number of minima in 𝐴1, and det𝐺𝐴1 is non-zero at these minima.
Results
For 𝛼≠2:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 𝛼𝑑−𝑑
𝛼
2𝑑𝛤(1
𝛼)𝑑𝑐1𝑒−𝑡𝛼/2𝐼(𝐴1)𝑡−(𝛼−2)𝑑
4−𝛼
4
where
𝑐1=(2𝜋)𝑑−1
2∑|𝐷𝐼(𝑥)|−𝑑+1
2
𝑥∈𝐷𝐴1(det𝐺𝐴1)−1
2
Note: 𝐷𝐼(𝑥)=(sign(𝑥𝑖)|𝑥𝑖|𝛼−1)1≤𝑖≤𝑑 for 𝛼 >1
Special Case: 𝛼=2
Let 𝜆 be the largest eigenvalue of 𝐶+𝐶𝑇 (assumed positive), and 𝐻={𝑥:(𝐶+𝐶𝑇)𝑥 =𝜆𝑥}
be the associated eigenspace.
Theorem 8.1.2
For 𝛼=2 and 𝜆>0:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 1
𝜆𝑘−1
2𝛤(𝑘+1
2)(det𝑀)1
2𝑒−𝑡/𝜆𝑡𝑘−1
2
where 𝑘=dim𝐻−1 and 𝑀 is the compression of 𝐼𝑑−𝜆−1(𝐶+𝐶𝑇) to 𝐻⊥.
Proof outline:
• 𝐷𝐴1 is the sphere of radius √2/𝜆 centered at the origin in 𝐻
• Apply Theorem 7.1
• Calculate 𝐼(𝐴1)=1/𝜆
• Determine 𝐺𝐴1 using second fundamental forms of 𝐼(𝐴1) and ∂𝐴1
These notes discuss the decay of probability 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡} as 𝑡 approaches infinity, where
𝑋 is a random vector in ℝ𝑑 and 𝐶 is a real 𝑑×𝑑 matrix.
Key points:
• The decay depends on the distribution of 𝑋 and matrix 𝐶
• Two types of distributions are considered: symmetric Weibull-like and Student-like
• Weibull-like tails are handled using Theorem 7.1
• Student-like tails are handled using a change of variable technique and Theorem 5.1
Light Tail Distribution Example
Setup
Consider a random vector 𝑋=(𝑋1,…,𝑋𝑑) in ℝ𝑑 with density 𝑓=𝑒−𝐼, where 𝐼 is a convex,
𝛼-positively homogeneous function on ℝ𝑑.
Important:
• 𝐴𝑡={𝑥∈ℝ𝑑:⟨𝐶𝑥,𝑥⟩>𝑡}=√𝑡𝐴1
• 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}=∫𝑒−𝐼(𝑥)
𝐴𝑡𝑑𝑥
Specific Case
Assume the components 𝑋𝑖 of 𝑋 are i.i.d. with density:
𝑤𝛼(𝑥)=𝛼1−1
𝛼
2𝛤(1
𝛼)exp(−|𝑥|𝛼
𝛼), 𝑥∈ℝ,𝛼>1
Conjecture 8.1.1: If 𝛼≠2 and 𝐶+𝐶𝑇 has no vanishing eigenvalue, then ∑ |𝑥𝑖|𝛼
𝑑
𝑖=1 admits a
finite number of minima in 𝐴1, and det𝐺𝐴1 is non-zero at these minima.
Results
For 𝛼≠2:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 𝛼𝑑−𝑑
𝛼
2𝑑𝛤(1
𝛼)𝑑𝑐1𝑒−𝑡𝛼/2𝐼(𝐴1)𝑡−(𝛼−2)𝑑
4−𝛼
4
where
𝑐1=(2𝜋)𝑑−1
2∑|𝐷𝐼(𝑥)|−𝑑+1
2
𝑥∈𝐷𝐴1(det𝐺𝐴1)−1
2
Note: 𝐷𝐼(𝑥)=(sign(𝑥𝑖)|𝑥𝑖|𝛼−1)1≤𝑖≤𝑑 for 𝛼 >1

Special Case: 𝛼=2
Let 𝜆 be the largest eigenvalue of 𝐶+𝐶𝑇 (assumed positive), and 𝐻={𝑥:(𝐶+𝐶𝑇)𝑥 =𝜆𝑥}
be the associated eigenspace.
Theorem 8.1.2
For 𝛼=2 and 𝜆>0:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 1
𝜆𝑘−1
2𝛤(𝑘+1
2)(det𝑀)1
2𝑒−𝑡/𝜆𝑡𝑘−1
2
where 𝑘=dim𝐻−1 and 𝑀 is the compression of 𝐼𝑑−𝜆−1(𝐶+𝐶𝑇) to 𝐻⊥.
Proof outline:
• 𝐷𝐴1 is the sphere of radius √2/𝜆 centered at the origin in 𝐻
• Apply Theorem 7.1
• Calculate 𝐼(𝐴1)=1/𝜆
• Determine 𝐺𝐴1 using second fundamental forms of 𝐼(𝐴1) and ∂𝐴1
These notes discuss the decay of probability 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡} as 𝑡 approaches infinity, where
𝑋 is a random vector in ℝ𝑑 and 𝐶 is a real 𝑑×𝑑 matrix.
Key points:
• The decay depends on the distribution of 𝑋 and matrix 𝐶
• Two types of distributions are considered: symmetric Weibull-like and Student-like
• Weibull-like tails are handled using Theorem 7.1
• Student-like tails are handled using a change of variable technique and Theorem 5.1
Light Tail Distribution Example
Setup
Consider a random vector 𝑋=(𝑋1,…,𝑋𝑑) in ℝ𝑑 with density 𝑓=𝑒−𝐼, where 𝐼 is a convex,
𝛼-positively homogeneous function on ℝ𝑑.
Important:
• 𝐴𝑡={𝑥∈ℝ𝑑:⟨𝐶𝑥,𝑥⟩>𝑡}=√𝑡𝐴1
• 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}=∫𝑒−𝐼(𝑥)
𝐴𝑡𝑑𝑥
Specific Case
Assume the components 𝑋𝑖 of 𝑋 are i.i.d. with density:
𝑤𝛼(𝑥)=𝛼1−1
𝛼
2𝛤(1
𝛼)exp(−|𝑥|𝛼
𝛼), 𝑥∈ℝ,𝛼>1
Conjecture 8.1.1: If 𝛼≠2 and 𝐶+𝐶𝑇 has no vanishing eigenvalue, then ∑ |𝑥𝑖|𝛼
𝑑
𝑖=1 admits a
finite number of minima in 𝐴1, and det𝐺𝐴1 is non-zero at these minima.
Results
For 𝛼≠2:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 𝛼𝑑−𝑑
𝛼
2𝑑𝛤(1
𝛼)𝑑𝑐1𝑒−𝑡𝛼/2𝐼(𝐴1)𝑡−(𝛼−2)𝑑
4−𝛼
4
where
𝑐1=(2𝜋)𝑑−1
2∑|𝐷𝐼(𝑥)|−𝑑+1
2
𝑥∈𝐷𝐴1(det𝐺𝐴1)−1
2
Note: 𝐷𝐼(𝑥)=(sign(𝑥𝑖)|𝑥𝑖|𝛼−1)1≤𝑖≤𝑑 for 𝛼 >1
Special Case: 𝛼=2
Let 𝜆 be the largest eigenvalue of 𝐶+𝐶𝑇 (assumed positive), and 𝐻={𝑥:(𝐶+𝐶𝑇)𝑥 =𝜆𝑥}
be the associated eigenspace.
Theorem 8.1.2
For 𝛼=2 and 𝜆>0:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 1
𝜆𝑘−1
2𝛤(𝑘+1
2)(det𝑀)1
2𝑒−𝑡/𝜆𝑡𝑘−1
2
where 𝑘=dim𝐻−1 and 𝑀 is the compression of 𝐼𝑑−𝜆−1(𝐶+𝐶𝑇) to 𝐻⊥.
Proof outline:
• 𝐷𝐴1 is the sphere of radius √2/𝜆 centered at the origin in 𝐻
• Apply Theorem 7.1
• Calculate 𝐼(𝐴1)=1/𝜆

• Determine 𝐺𝐴1 using second fundamental forms of 𝐼(𝐴1) and ∂𝐴1
These notes discuss the decay of probability 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡} as 𝑡 approaches infinity, where
𝑋 is a random vector in ℝ𝑑 and 𝐶 is a real 𝑑×𝑑 matrix.
Key points:
• The decay depends on the distribution of 𝑋 and matrix 𝐶
• Two types of distributions are considered: symmetric Weibull-like and Student-like
• Weibull-like tails are handled using Theorem 7.1
• Student-like tails are handled using a change of variable technique and Theorem 5.1
Light Tail Distribution Example
Setup
Consider a random vector 𝑋=(𝑋1,…,𝑋𝑑) in ℝ𝑑 with density 𝑓=𝑒−𝐼, where 𝐼 is a convex,
𝛼-positively homogeneous function on ℝ𝑑.
Important:
• 𝐴𝑡={𝑥∈ℝ𝑑:⟨𝐶𝑥,𝑥⟩>𝑡}=√𝑡𝐴1
• 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}=∫𝑒−𝐼(𝑥)
𝐴𝑡𝑑𝑥
Specific Case
Assume the components 𝑋𝑖 of 𝑋 are i.i.d. with density:
𝑤𝛼(𝑥)=𝛼1−1
𝛼
2𝛤(1
𝛼)exp(−|𝑥|𝛼
𝛼), 𝑥∈ℝ,𝛼>1
Conjecture 8.1.1: If 𝛼≠2 and 𝐶+𝐶𝑇 has no vanishing eigenvalue, then ∑ |𝑥𝑖|𝛼
𝑑
𝑖=1 admits a
finite number of minima in 𝐴1, and det𝐺𝐴1 is non-zero at these minima.
Results
For 𝛼≠2:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 𝛼𝑑−𝑑
𝛼
2𝑑𝛤(1
𝛼)𝑑𝑐1𝑒−𝑡𝛼/2𝐼(𝐴1)𝑡−(𝛼−2)𝑑
4−𝛼
4
where
𝑐1=(2𝜋)𝑑−1
2∑|𝐷𝐼(𝑥)|−𝑑+1
2
𝑥∈𝐷𝐴1(det𝐺𝐴1)−1
2
Note: 𝐷𝐼(𝑥)=(sign(𝑥𝑖)|𝑥𝑖|𝛼−1)1≤𝑖≤𝑑 for 𝛼 >1
Special Case: 𝛼=2
Let 𝜆 be the largest eigenvalue of 𝐶+𝐶𝑇 (assumed positive), and 𝐻={𝑥:(𝐶+𝐶𝑇)𝑥 =𝜆𝑥}
be the associated eigenspace.
Theorem 8.1.2
For 𝛼=2 and 𝜆>0:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 1
𝜆𝑘−1
2𝛤(𝑘+1
2)(det𝑀)1
2𝑒−𝑡/𝜆𝑡𝑘−1
2
where 𝑘=dim𝐻−1 and 𝑀 is the compression of 𝐼𝑑−𝜆−1(𝐶+𝐶𝑇) to 𝐻⊥.
Proof outline:
• 𝐷𝐴1 is the sphere of radius √2/𝜆 centered at the origin in 𝐻
• Apply Theorem 7.1
• Calculate 𝐼(𝐴1)=1/𝜆
• Determine 𝐺𝐴1 using second fundamental forms of 𝐼(𝐴1) and ∂𝐴1
These notes discuss the decay of probability 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡} as 𝑡 approaches infinity, where
𝑋 is a random vector in ℝ𝑑 and 𝐶 is a real 𝑑×𝑑 matrix.
Key points:
• The decay depends on the distribution of 𝑋 and matrix 𝐶
• Two types of distributions are considered: symmetric Weibull-like and Student-like
• Weibull-like tails are handled using Theorem 7.1
• Student-like tails are handled using a change of variable technique and Theorem 5.1
Light Tail Distribution Example
Setup
Consider a random vector 𝑋=(𝑋1,…,𝑋𝑑) in ℝ𝑑 with density 𝑓=𝑒−𝐼, where 𝐼 is a convex,
𝛼-positively homogeneous function on ℝ𝑑.
Important:
• 𝐴𝑡={𝑥∈ℝ𝑑:⟨𝐶𝑥,𝑥⟩>𝑡}=√𝑡𝐴1
• 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}=∫𝑒−𝐼(𝑥)
𝐴𝑡𝑑𝑥
Specific Case
Assume the components 𝑋𝑖 of 𝑋 are i.i.d. with density:
𝑤𝛼(𝑥)=𝛼1−1
𝛼
2𝛤(1
𝛼)exp(−|𝑥|𝛼
𝛼), 𝑥∈ℝ,𝛼>1
Conjecture 8.1.1: If 𝛼≠2 and 𝐶+𝐶𝑇 has no vanishing eigenvalue, then ∑ |𝑥𝑖|𝛼
𝑑
𝑖=1 admits a
finite number of minima in 𝐴1, and det𝐺𝐴1 is non-zero at these minima.
Results
For 𝛼≠2:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 𝛼𝑑−𝑑
𝛼
2𝑑𝛤(1
𝛼)𝑑𝑐1𝑒−𝑡𝛼/2𝐼(𝐴1)𝑡−(𝛼−2)𝑑
4−𝛼
4
where
𝑐1=(2𝜋)𝑑−1
2∑|𝐷𝐼(𝑥)|−𝑑+1
2
𝑥∈𝐷𝐴1(det𝐺𝐴1)−1
2
Note: 𝐷𝐼(𝑥)=(sign(𝑥𝑖)|𝑥𝑖|𝛼−1)1≤𝑖≤𝑑 for 𝛼 >1
Special Case: 𝛼=2
Let 𝜆 be the largest eigenvalue of 𝐶+𝐶𝑇 (assumed positive), and 𝐻={𝑥:(𝐶+𝐶𝑇)𝑥 =𝜆𝑥}
be the associated eigenspace.
Theorem 8.1.2
For 𝛼=2 and 𝜆>0:
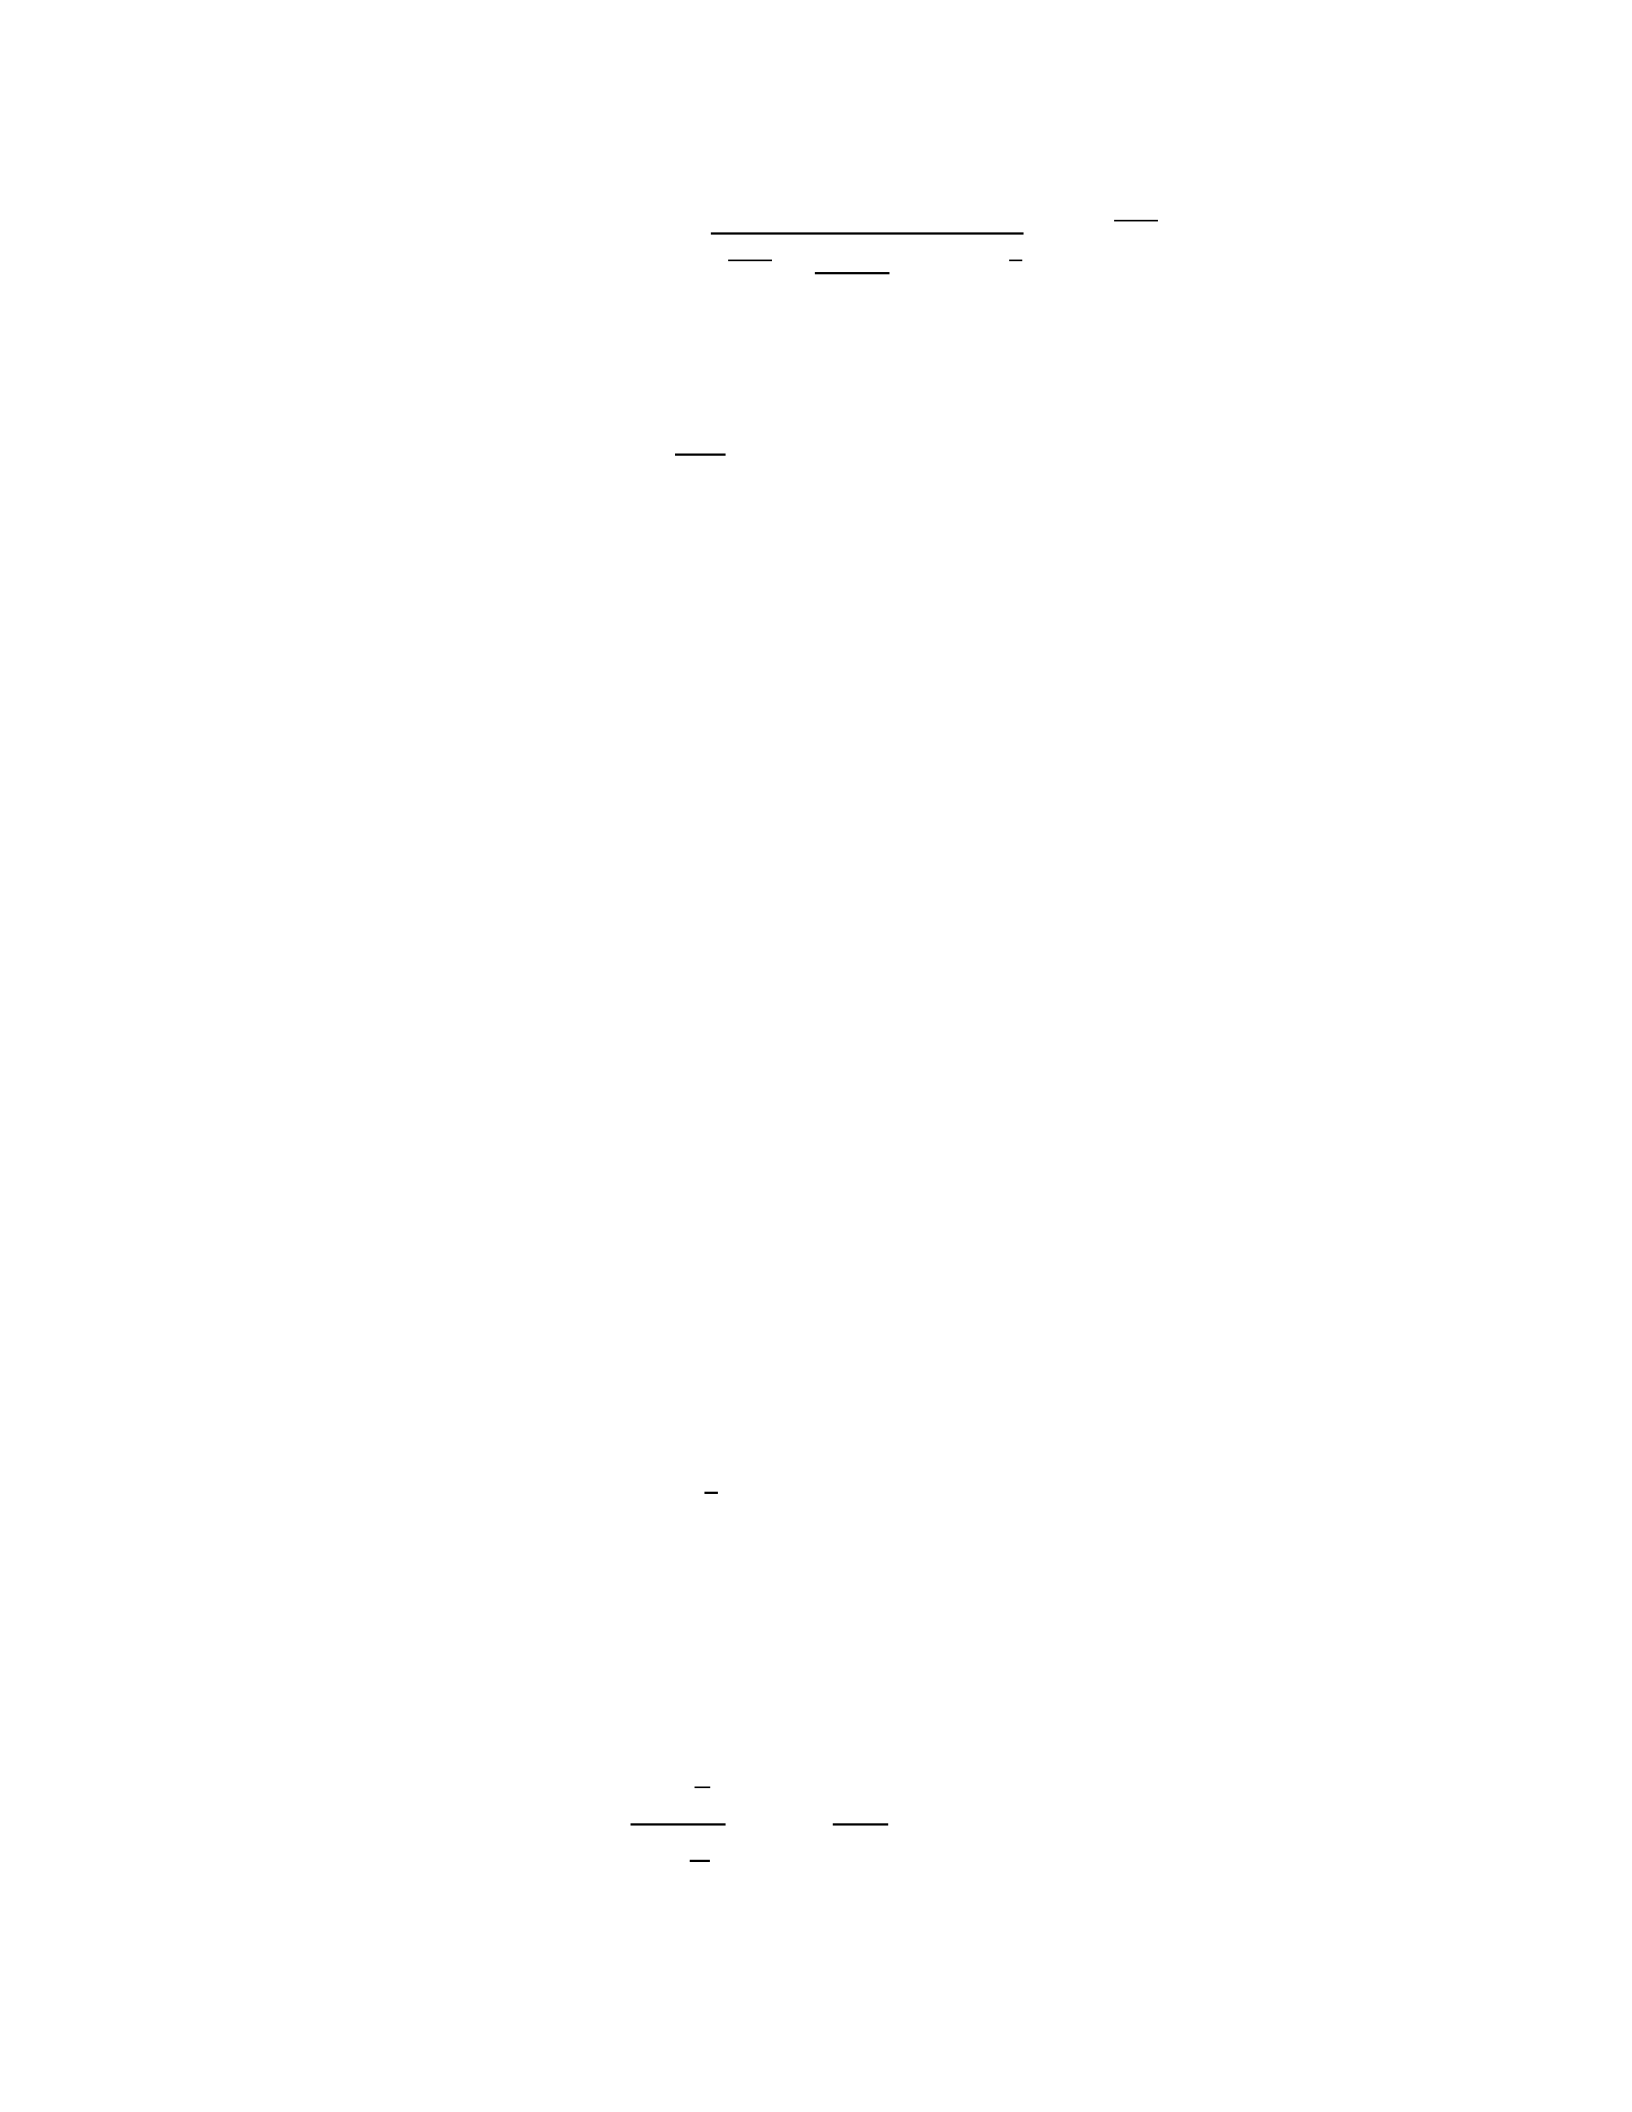
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 1
𝜆𝑘−1
2𝛤(𝑘+1
2)(det𝑀)1
2𝑒−𝑡/𝜆𝑡𝑘−1
2
where 𝑘=dim𝐻−1 and 𝑀 is the compression of 𝐼𝑑−𝜆−1(𝐶+𝐶𝑇) to 𝐻⊥.
Proof outline:
• 𝐷𝐴1 is the sphere of radius √2/𝜆 centered at the origin in 𝐻
• Apply Theorem 7.1
• Calculate 𝐼(𝐴1)=1/𝜆
• Determine 𝐺𝐴1 using second fundamental forms of 𝐼(𝐴1) and ∂𝐴1
These notes discuss the decay of probability 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡} as 𝑡 approaches infinity, where
𝑋 is a random vector in ℝ𝑑 and 𝐶 is a real 𝑑×𝑑 matrix.
Key points:
• The decay depends on the distribution of 𝑋 and matrix 𝐶
• Two types of distributions are considered: symmetric Weibull-like and Student-like
• Weibull-like tails are handled using Theorem 7.1
• Student-like tails are handled using a change of variable technique and Theorem 5.1
Light Tail Distribution Example
Setup
Consider a random vector 𝑋=(𝑋1,…,𝑋𝑑) in ℝ𝑑 with density 𝑓=𝑒−𝐼, where 𝐼 is a convex,
𝛼-positively homogeneous function on ℝ𝑑.
Important:
• 𝐴𝑡={𝑥∈ℝ𝑑:⟨𝐶𝑥,𝑥⟩>𝑡}=√𝑡𝐴1
• 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}=∫𝑒−𝐼(𝑥)
𝐴𝑡𝑑𝑥
Specific Case
Assume the components 𝑋𝑖 of 𝑋 are i.i.d. with density:
𝑤𝛼(𝑥)=𝛼1−1
𝛼
2𝛤(1
𝛼)exp(−|𝑥|𝛼
𝛼), 𝑥∈ℝ,𝛼>1
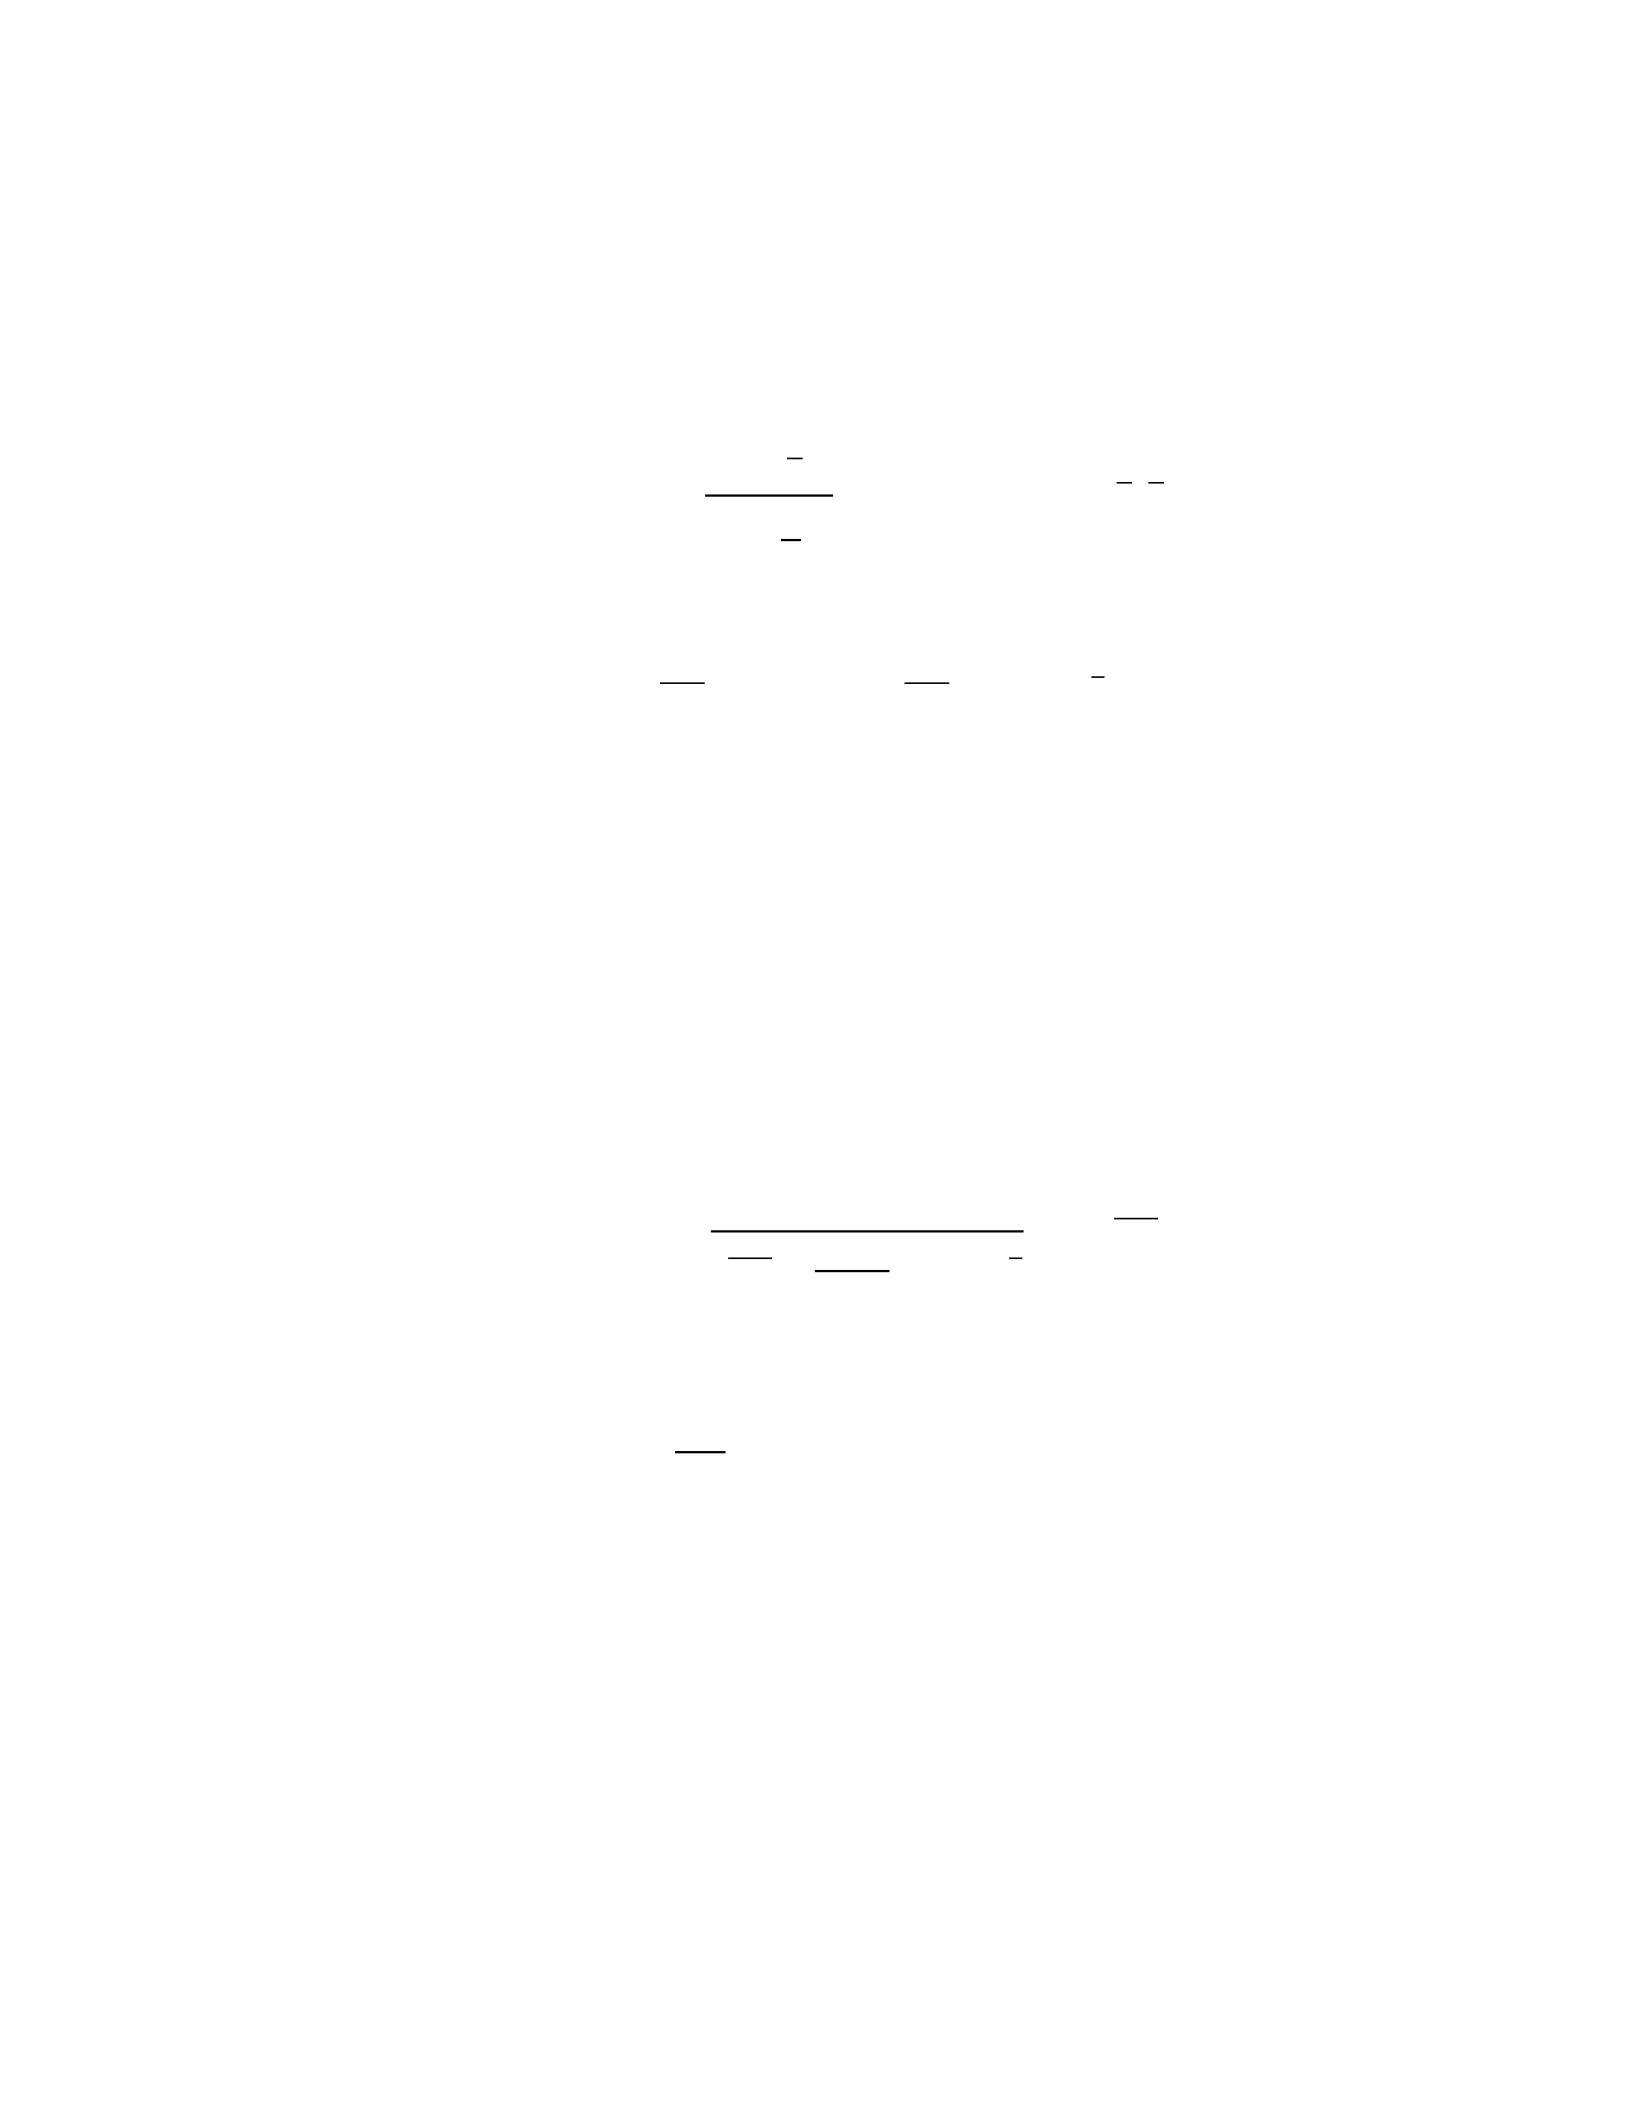
Conjecture 8.1.1: If 𝛼≠2 and 𝐶+𝐶𝑇 has no vanishing eigenvalue, then ∑ |𝑥𝑖|𝛼
𝑑
𝑖=1 admits a
finite number of minima in 𝐴1, and det𝐺𝐴1 is non-zero at these minima.
Results
For 𝛼≠2:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 𝛼𝑑−𝑑
𝛼
2𝑑𝛤(1
𝛼)𝑑𝑐1𝑒−𝑡𝛼/2𝐼(𝐴1)𝑡−(𝛼−2)𝑑
4−𝛼
4
where
𝑐1=(2𝜋)𝑑−1
2∑|𝐷𝐼(𝑥)|−𝑑+1
2
𝑥∈𝐷𝐴1(det𝐺𝐴1)−1
2
Note: 𝐷𝐼(𝑥)=(sign(𝑥𝑖)|𝑥𝑖|𝛼−1)1≤𝑖≤𝑑 for 𝛼 >1
Special Case: 𝛼=2
Let 𝜆 be the largest eigenvalue of 𝐶+𝐶𝑇 (assumed positive), and 𝐻={𝑥:(𝐶+𝐶𝑇)𝑥 =𝜆𝑥}
be the associated eigenspace.
Theorem 8.1.2
For 𝛼=2 and 𝜆>0:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 1
𝜆𝑘−1
2𝛤(𝑘+1
2)(det𝑀)1
2𝑒−𝑡/𝜆𝑡𝑘−1
2
where 𝑘=dim𝐻−1 and 𝑀 is the compression of 𝐼𝑑−𝜆−1(𝐶+𝐶𝑇) to 𝐻⊥.
Proof outline:
• 𝐷𝐴1 is the sphere of radius √2/𝜆 centered at the origin in 𝐻
• Apply Theorem 7.1
• Calculate 𝐼(𝐴1)=1/𝜆
• Determine 𝐺𝐴1 using second fundamental forms of 𝐼(𝐴1) and ∂𝐴1
These notes discuss the decay of probability 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡} as 𝑡 approaches infinity, where
𝑋 is a random vector in ℝ𝑑 and 𝐶 is a real 𝑑×𝑑 matrix.
Key points:
• The decay depends on the distribution of 𝑋 and matrix 𝐶
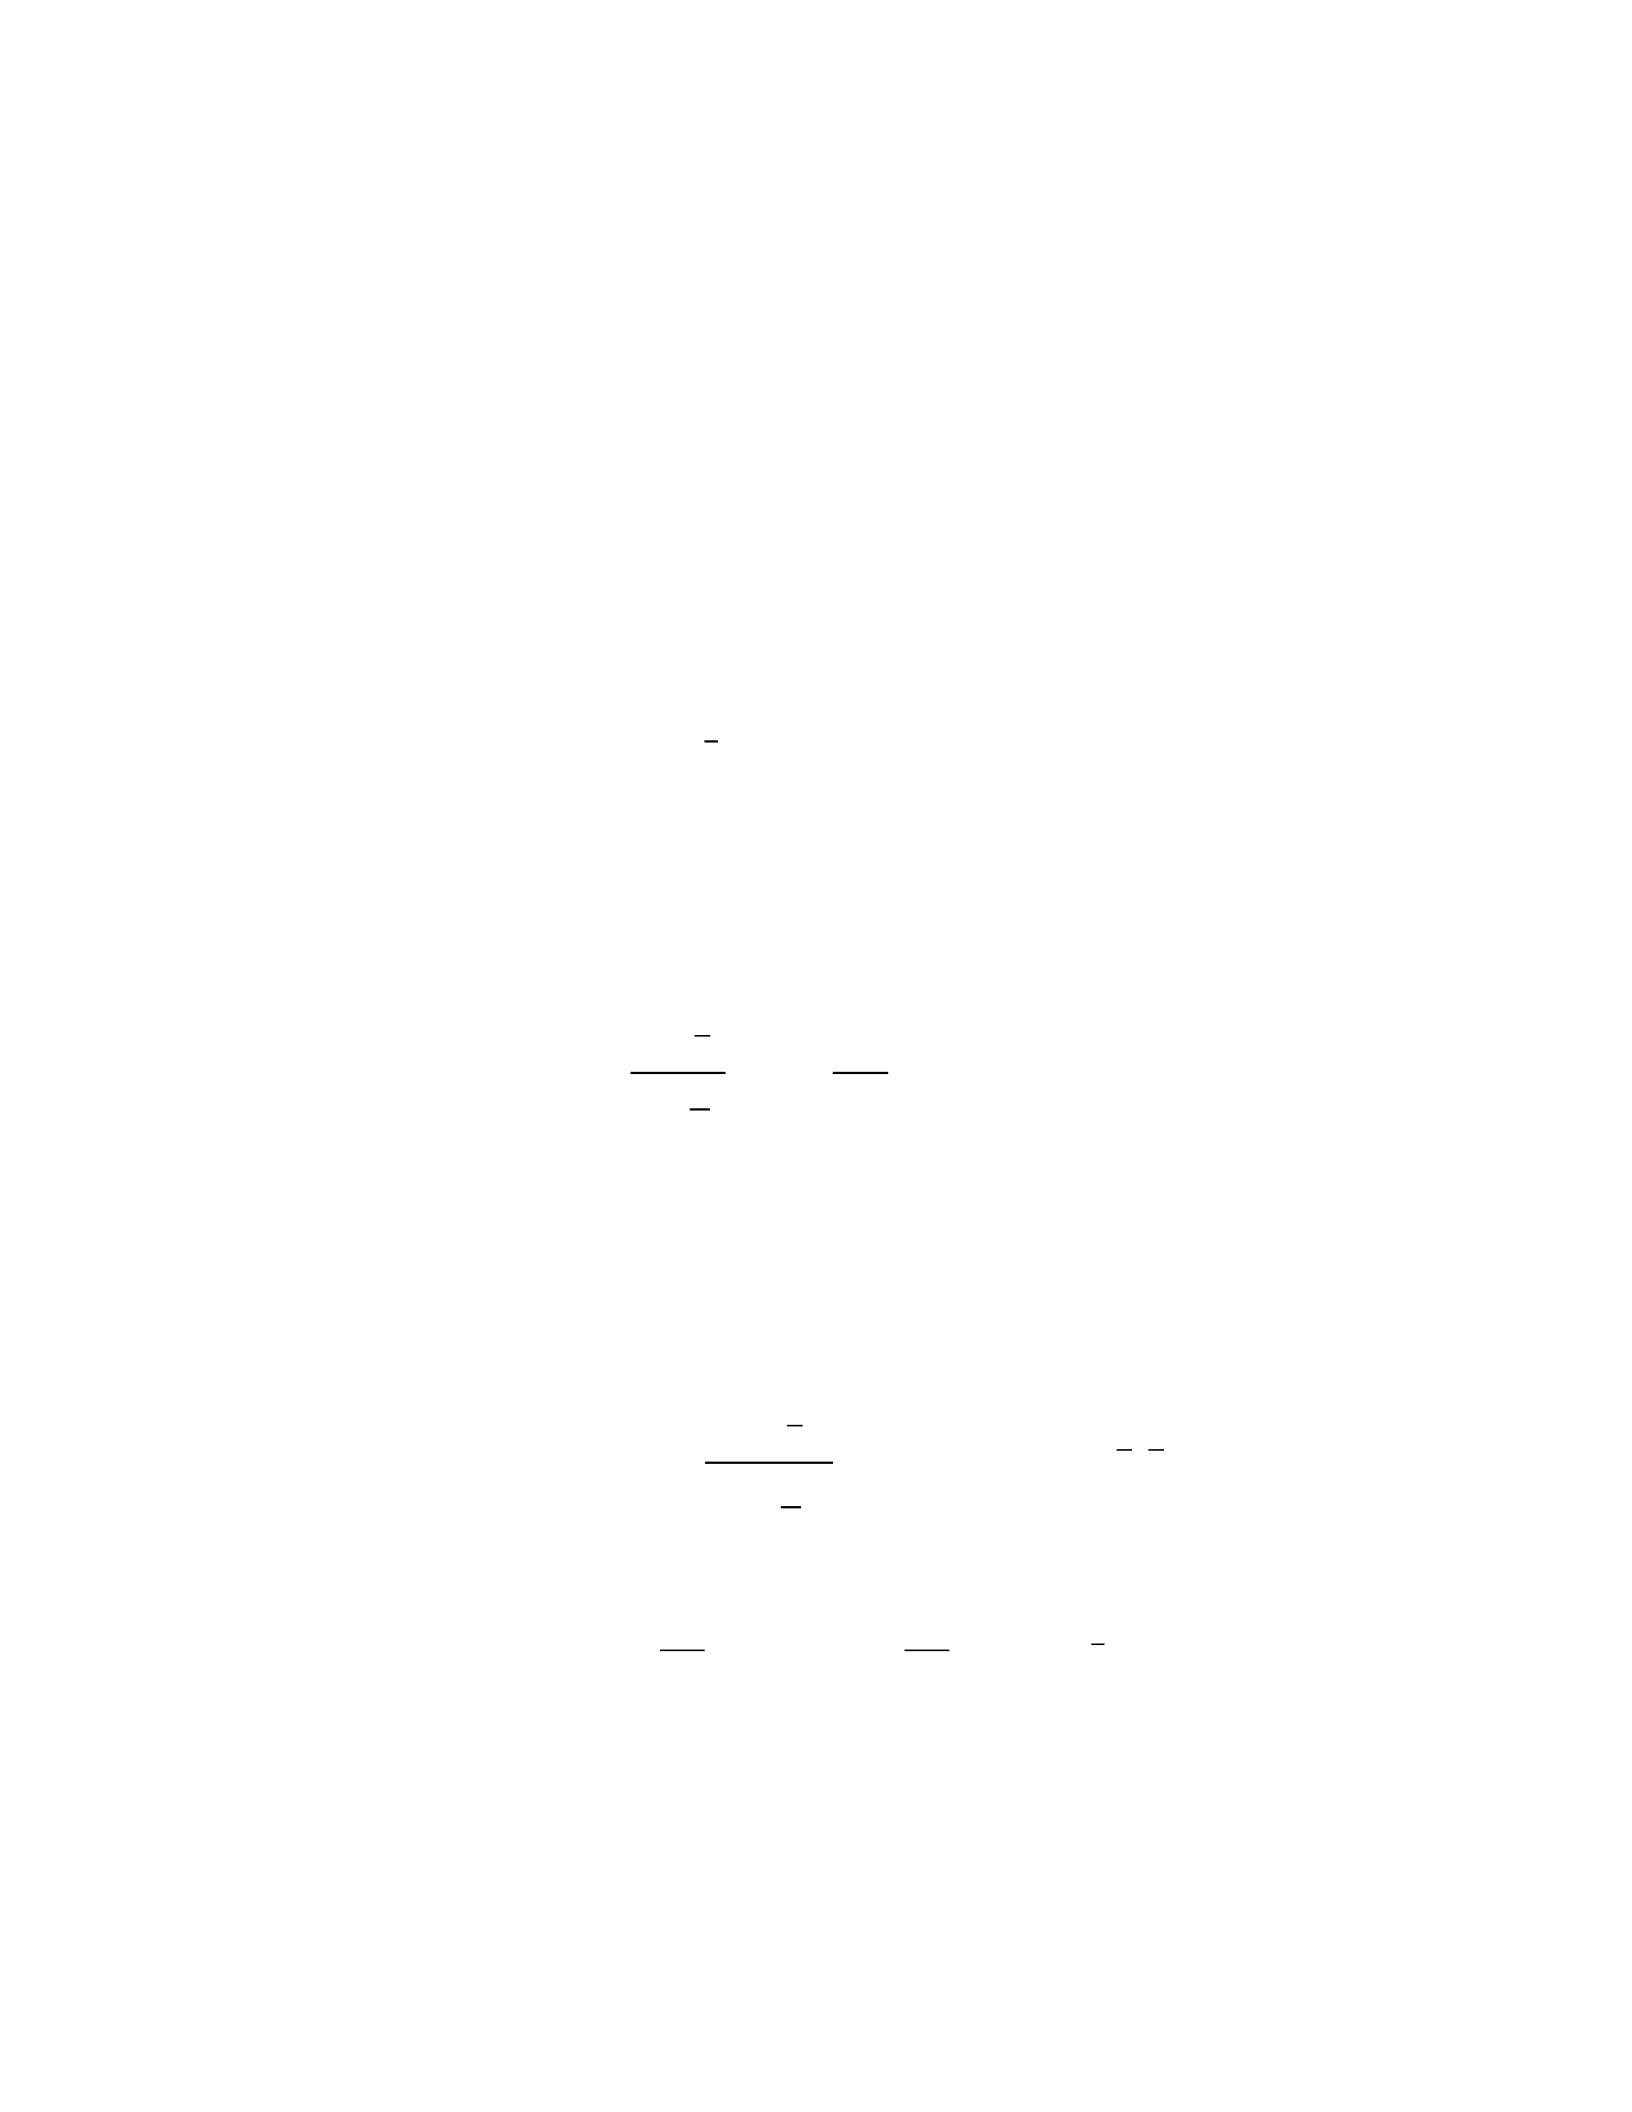
• Two types of distributions are considered: symmetric Weibull-like and Student-like
• Weibull-like tails are handled using Theorem 7.1
• Student-like tails are handled using a change of variable technique and Theorem 5.1
Light Tail Distribution Example
Setup
Consider a random vector 𝑋=(𝑋1,…,𝑋𝑑) in ℝ𝑑 with density 𝑓=𝑒−𝐼, where 𝐼 is a convex,
𝛼-positively homogeneous function on ℝ𝑑.
Important:
• 𝐴𝑡={𝑥∈ℝ𝑑:⟨𝐶𝑥,𝑥⟩>𝑡}=√𝑡𝐴1
• 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}=∫𝑒−𝐼(𝑥)
𝐴𝑡𝑑𝑥
Specific Case
Assume the components 𝑋𝑖 of 𝑋 are i.i.d. with density:
𝑤𝛼(𝑥)=𝛼1−1
𝛼
2𝛤(1
𝛼)exp(−|𝑥|𝛼
𝛼), 𝑥∈ℝ,𝛼>1
Conjecture 8.1.1: If 𝛼≠2 and 𝐶+𝐶𝑇 has no vanishing eigenvalue, then ∑ |𝑥𝑖|𝛼
𝑑
𝑖=1 admits a
finite number of minima in 𝐴1, and det𝐺𝐴1 is non-zero at these minima.
Results
For 𝛼≠2:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 𝛼𝑑−𝑑
𝛼
2𝑑𝛤(1
𝛼)𝑑𝑐1𝑒−𝑡𝛼/2𝐼(𝐴1)𝑡−(𝛼−2)𝑑
4−𝛼
4
where
𝑐1=(2𝜋)𝑑−1
2∑|𝐷𝐼(𝑥)|−𝑑+1
2
𝑥∈𝐷𝐴1(det𝐺𝐴1)−1
2
Note: 𝐷𝐼(𝑥)=(sign(𝑥𝑖)|𝑥𝑖|𝛼−1)1≤𝑖≤𝑑 for 𝛼 >1
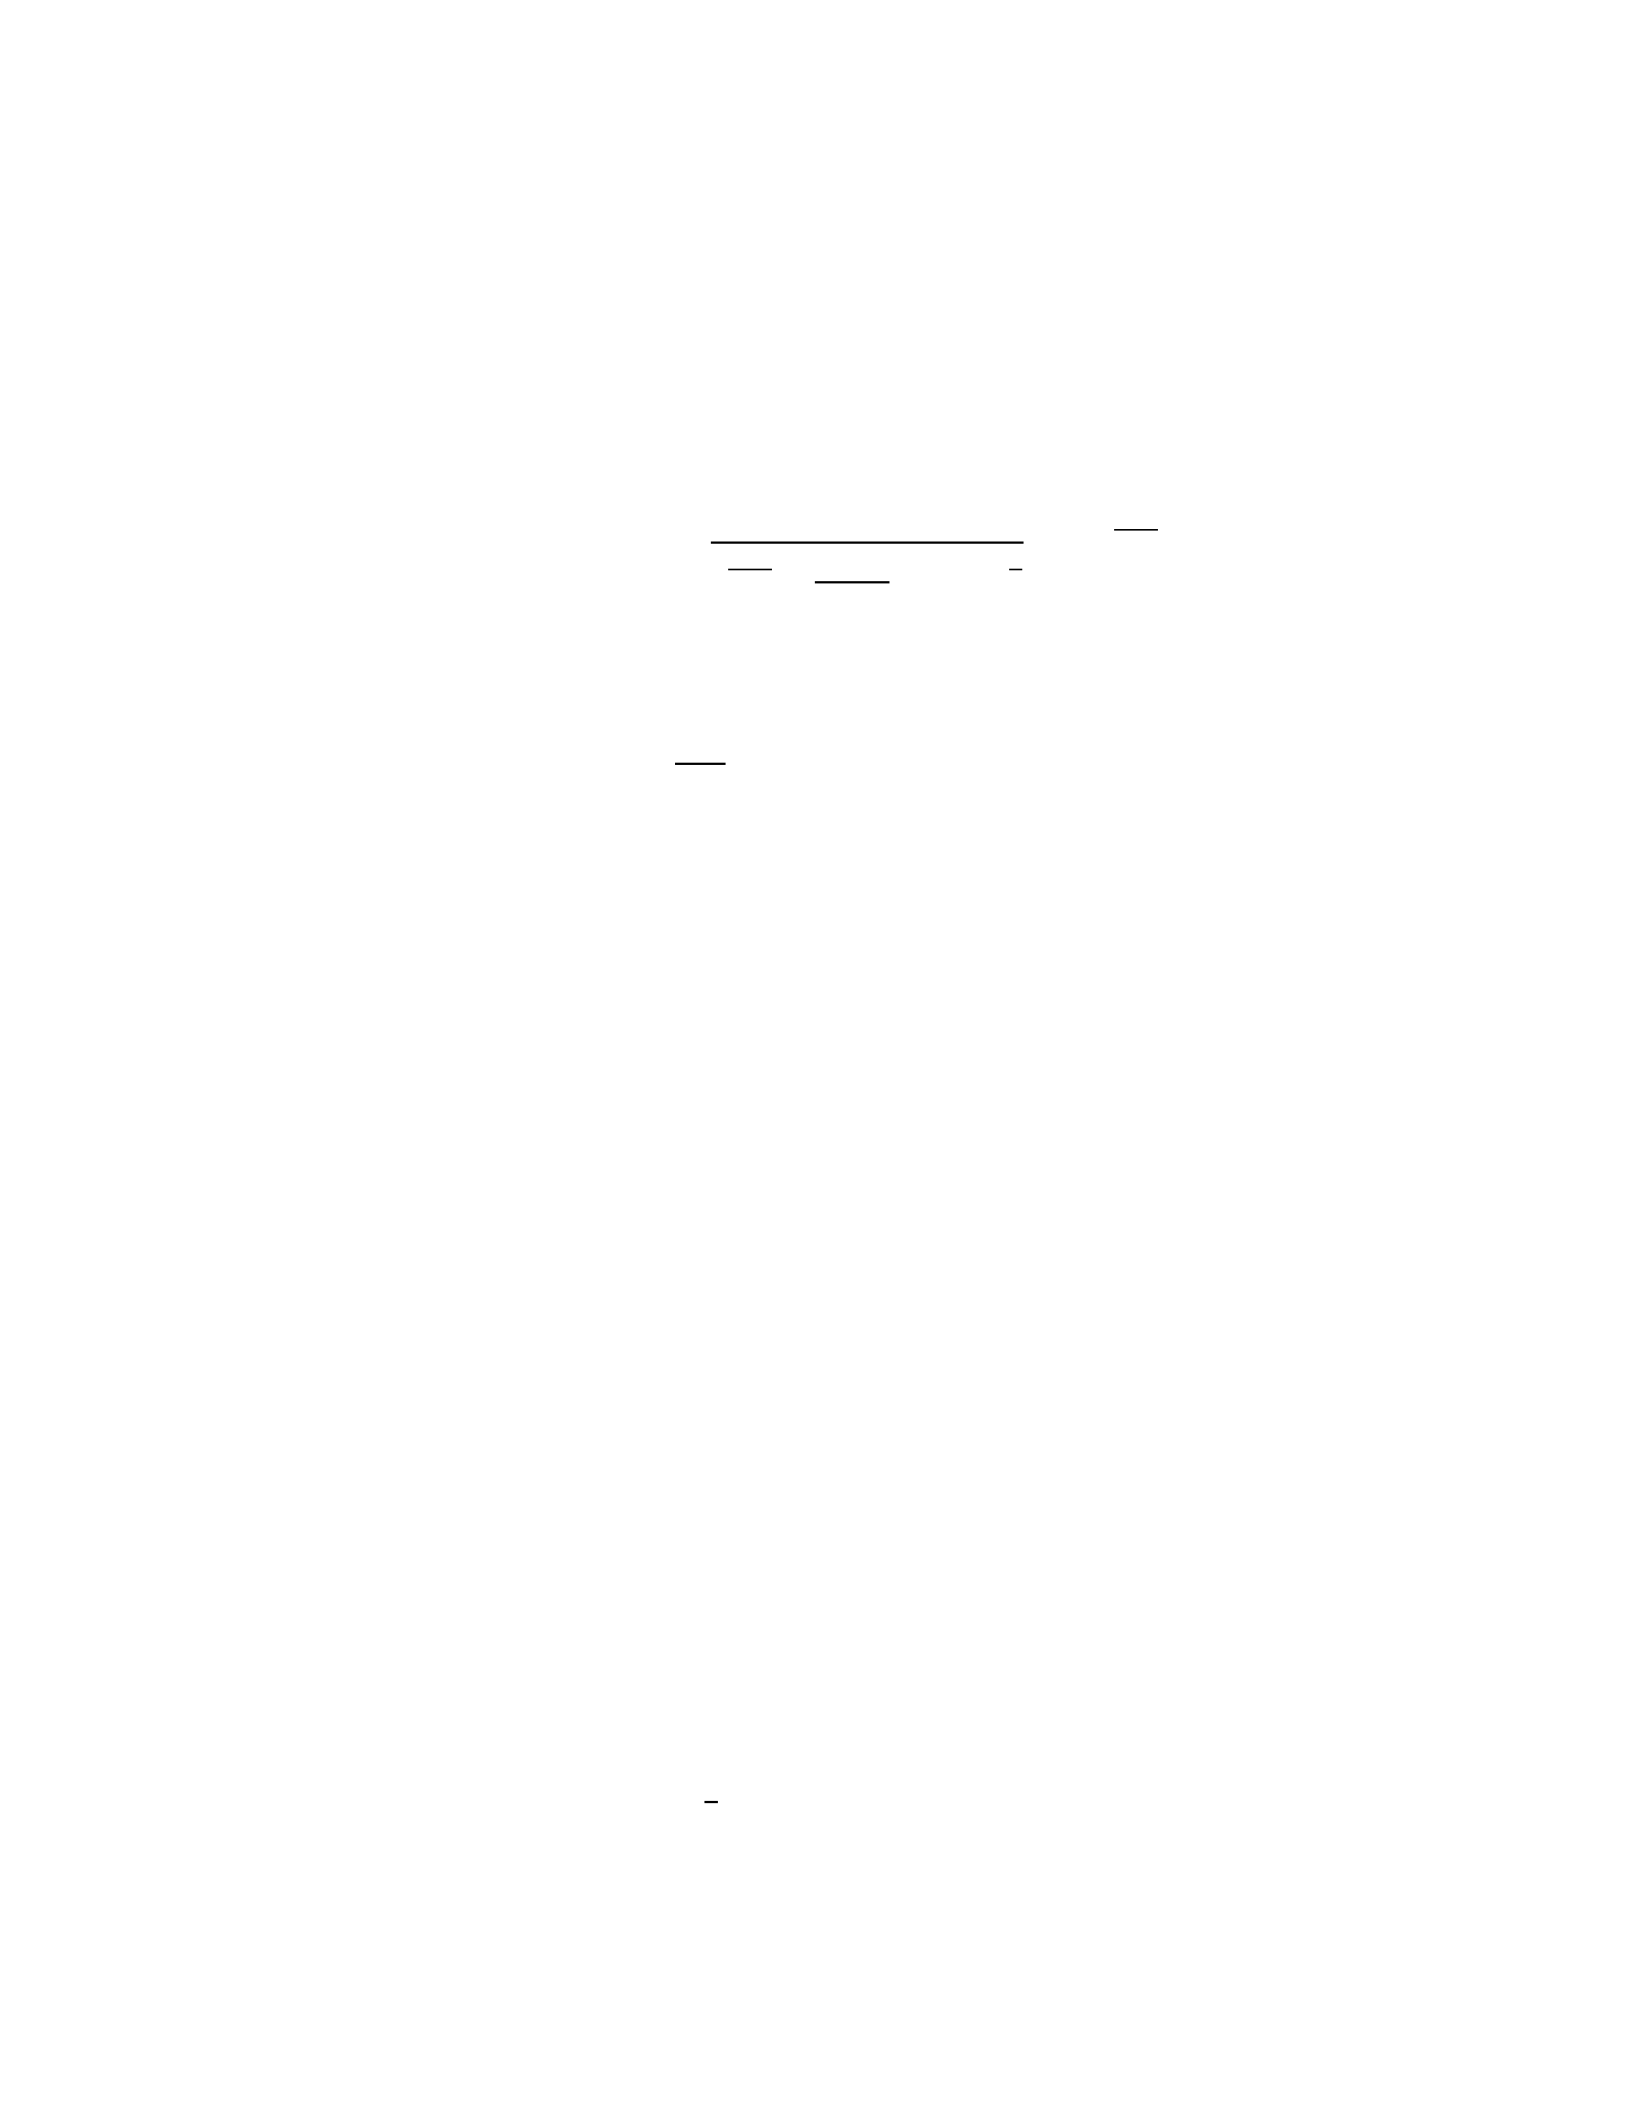
Special Case: 𝛼=2
Let 𝜆 be the largest eigenvalue of 𝐶+𝐶𝑇 (assumed positive), and 𝐻={𝑥:(𝐶+𝐶𝑇)𝑥 =𝜆𝑥}
be the associated eigenspace.
Theorem 8.1.2
For 𝛼=2 and 𝜆>0:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 1
𝜆𝑘−1
2𝛤(𝑘+1
2)(det𝑀)1
2𝑒−𝑡/𝜆𝑡𝑘−1
2
where 𝑘=dim𝐻−1 and 𝑀 is the compression of 𝐼𝑑−𝜆−1(𝐶+𝐶𝑇) to 𝐻⊥.
Proof outline:
• 𝐷𝐴1 is the sphere of radius √2/𝜆 centered at the origin in 𝐻
• Apply Theorem 7.1
• Calculate 𝐼(𝐴1)=1/𝜆
• Determine 𝐺𝐴1 using second fundamental forms of 𝐼(𝐴1) and ∂𝐴1
These notes discuss the decay of probability 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡} as 𝑡 approaches infinity, where
𝑋 is a random vector in ℝ𝑑 and 𝐶 is a real 𝑑×𝑑 matrix.
Key points:
• The decay depends on the distribution of 𝑋 and matrix 𝐶
• Two types of distributions are considered: symmetric Weibull-like and Student-like
• Weibull-like tails are handled using Theorem 7.1
• Student-like tails are handled using a change of variable technique and Theorem 5.1
Light Tail Distribution Example
Setup
Consider a random vector 𝑋=(𝑋1,…,𝑋𝑑) in ℝ𝑑 with density 𝑓=𝑒−𝐼, where 𝐼 is a convex,
𝛼-positively homogeneous function on ℝ𝑑.
Important:
• 𝐴𝑡={𝑥∈ℝ𝑑:⟨𝐶𝑥,𝑥⟩>𝑡}=√𝑡𝐴1
• 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}=∫𝑒−𝐼(𝑥)
𝐴𝑡𝑑𝑥

Specific Case
Assume the components 𝑋𝑖 of 𝑋 are i.i.d. with density:
𝑤𝛼(𝑥)=𝛼1−1
𝛼
2𝛤(1
𝛼)exp(−|𝑥|𝛼
𝛼), 𝑥∈ℝ,𝛼>1
Conjecture 8.1.1: If 𝛼≠2 and 𝐶+𝐶𝑇 has no vanishing eigenvalue, then ∑ |𝑥𝑖|𝛼
𝑑
𝑖=1 admits a
finite number of minima in 𝐴1, and det𝐺𝐴1 is non-zero at these minima.
Results
For 𝛼≠2:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 𝛼𝑑−𝑑
𝛼
2𝑑𝛤(1
𝛼)𝑑𝑐1𝑒−𝑡𝛼/2𝐼(𝐴1)𝑡−(𝛼−2)𝑑
4−𝛼
4
where
𝑐1=(2𝜋)𝑑−1
2∑|𝐷𝐼(𝑥)|−𝑑+1
2
𝑥∈𝐷𝐴1(det𝐺𝐴1)−1
2
Note: 𝐷𝐼(𝑥)=(sign(𝑥𝑖)|𝑥𝑖|𝛼−1)1≤𝑖≤𝑑 for 𝛼 >1
Special Case: 𝛼=2
Let 𝜆 be the largest eigenvalue of 𝐶+𝐶𝑇 (assumed positive), and 𝐻={𝑥:(𝐶+𝐶𝑇)𝑥 =𝜆𝑥}
be the associated eigenspace.
Theorem 8.1.2
For 𝛼=2 and 𝜆>0:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 1
𝜆𝑘−1
2𝛤(𝑘+1
2)(det𝑀)1
2𝑒−𝑡/𝜆𝑡𝑘−1
2
where 𝑘=dim𝐻−1 and 𝑀 is the compression of 𝐼𝑑−𝜆−1(𝐶+𝐶𝑇) to 𝐻⊥.
Proof outline:
• 𝐷𝐴1 is the sphere of radius √2/𝜆 centered at the origin in 𝐻
• Apply Theorem 7.1
• Calculate 𝐼(𝐴1)=1/𝜆
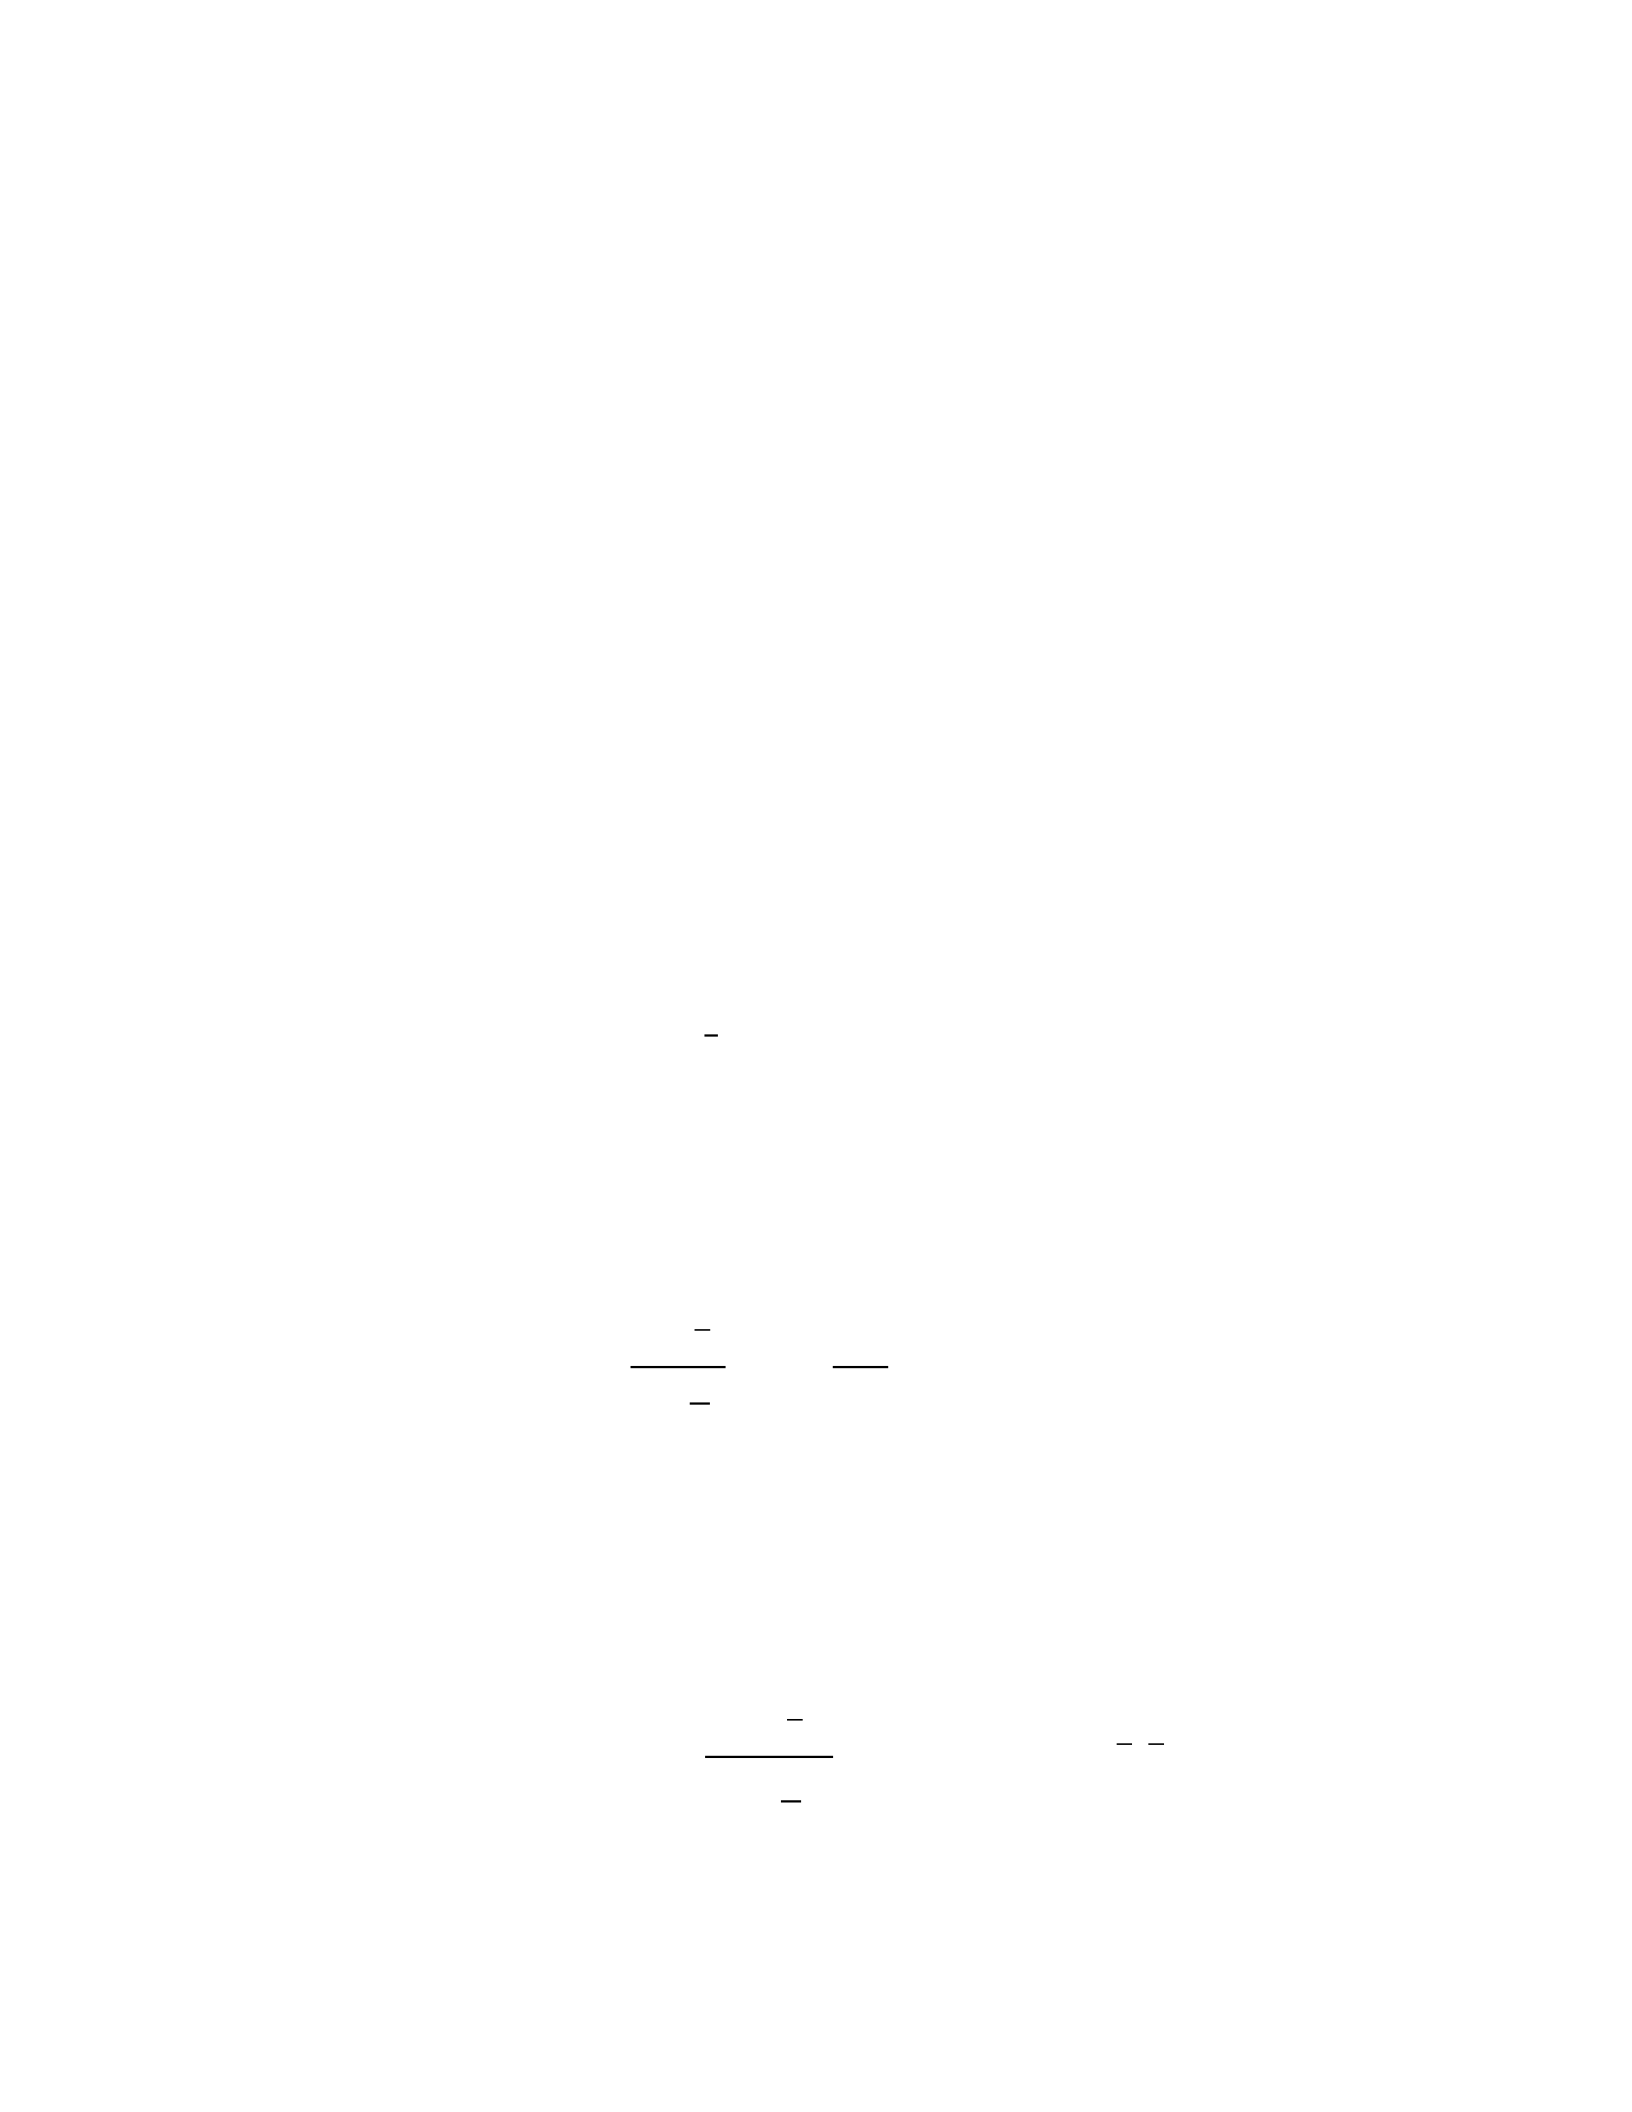
• Determine 𝐺𝐴1 using second fundamental forms of 𝐼(𝐴1) and ∂𝐴1
These notes discuss the decay of probability 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡} as 𝑡 approaches infinity, where
𝑋 is a random vector in ℝ𝑑 and 𝐶 is a real 𝑑×𝑑 matrix.
Key points:
• The decay depends on the distribution of 𝑋 and matrix 𝐶
• Two types of distributions are considered: symmetric Weibull-like and Student-like
• Weibull-like tails are handled using Theorem 7.1
• Student-like tails are handled using a change of variable technique and Theorem 5.1
Light Tail Distribution Example
Setup
Consider a random vector 𝑋=(𝑋1,…,𝑋𝑑) in ℝ𝑑 with density 𝑓=𝑒−𝐼, where 𝐼 is a convex,
𝛼-positively homogeneous function on ℝ𝑑.
Important:
• 𝐴𝑡={𝑥∈ℝ𝑑:⟨𝐶𝑥,𝑥⟩>𝑡}=√𝑡𝐴1
• 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}=∫𝑒−𝐼(𝑥)
𝐴𝑡𝑑𝑥
Specific Case
Assume the components 𝑋𝑖 of 𝑋 are i.i.d. with density:
𝑤𝛼(𝑥)=𝛼1−1
𝛼
2𝛤(1
𝛼)exp(−|𝑥|𝛼
𝛼), 𝑥∈ℝ,𝛼>1
Conjecture 8.1.1: If 𝛼≠2 and 𝐶+𝐶𝑇 has no vanishing eigenvalue, then ∑ |𝑥𝑖|𝛼
𝑑
𝑖=1 admits a
finite number of minima in 𝐴1, and det𝐺𝐴1 is non-zero at these minima.
Results
For 𝛼≠2:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 𝛼𝑑−𝑑
𝛼
2𝑑𝛤(1
𝛼)𝑑𝑐1𝑒−𝑡𝛼/2𝐼(𝐴1)𝑡−(𝛼−2)𝑑
4−𝛼
4
where

𝑐1=(2𝜋)𝑑−1
2∑|𝐷𝐼(𝑥)|−𝑑+1
2
𝑥∈𝐷𝐴1(det𝐺𝐴1)−1
2
Note: 𝐷𝐼(𝑥)=(sign(𝑥𝑖)|𝑥𝑖|𝛼−1)1≤𝑖≤𝑑 for 𝛼 >1
Special Case: 𝛼=2
Let 𝜆 be the largest eigenvalue of 𝐶+𝐶𝑇 (assumed positive), and 𝐻={𝑥:(𝐶+𝐶𝑇)𝑥 =𝜆𝑥}
be the associated eigenspace.
Theorem 8.1.2
For 𝛼=2 and 𝜆>0:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 1
𝜆𝑘−1
2𝛤(𝑘+1
2)(det𝑀)1
2𝑒−𝑡/𝜆𝑡𝑘−1
2
where 𝑘=dim𝐻−1 and 𝑀 is the compression of 𝐼𝑑−𝜆−1(𝐶+𝐶𝑇) to 𝐻⊥.
Proof outline:
• 𝐷𝐴1 is the sphere of radius √2/𝜆 centered at the origin in 𝐻
• Apply Theorem 7.1
• Calculate 𝐼(𝐴1)=1/𝜆
• Determine 𝐺𝐴1 using second fundamental forms of 𝐼(𝐴1) and ∂𝐴1
These notes discuss the decay of probability 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡} as 𝑡 approaches infinity, where
𝑋 is a random vector in ℝ𝑑 and 𝐶 is a real 𝑑×𝑑 matrix.
Key points:
• The decay depends on the distribution of 𝑋 and matrix 𝐶
• Two types of distributions are considered: symmetric Weibull-like and Student-like
• Weibull-like tails are handled using Theorem 7.1
• Student-like tails are handled using a change of variable technique and Theorem 5.1

Light Tail Distribution Example
Setup
Consider a random vector 𝑋=(𝑋1,…,𝑋𝑑) in ℝ𝑑 with density 𝑓=𝑒−𝐼, where 𝐼 is a convex,
𝛼-positively homogeneous function on ℝ𝑑.
Important:
• 𝐴𝑡={𝑥∈ℝ𝑑:⟨𝐶𝑥,𝑥⟩>𝑡}=√𝑡𝐴1
• 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}=∫𝑒−𝐼(𝑥)
𝐴𝑡𝑑𝑥
Specific Case
Assume the components 𝑋𝑖 of 𝑋 are i.i.d. with density:
𝑤𝛼(𝑥)=𝛼1−1
𝛼
2𝛤(1
𝛼)exp(−|𝑥|𝛼
𝛼), 𝑥∈ℝ,𝛼>1
Conjecture 8.1.1: If 𝛼≠2 and 𝐶+𝐶𝑇 has no vanishing eigenvalue, then ∑ |𝑥𝑖|𝛼
𝑑
𝑖=1 admits a
finite number of minima in 𝐴1, and det𝐺𝐴1 is non-zero at these minima.
Results
For 𝛼≠2:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 𝛼𝑑−𝑑
𝛼
2𝑑𝛤(1
𝛼)𝑑𝑐1𝑒−𝑡𝛼/2𝐼(𝐴1)𝑡−(𝛼−2)𝑑
4−𝛼
4
where
𝑐1=(2𝜋)𝑑−1
2∑|𝐷𝐼(𝑥)|−𝑑+1
2
𝑥∈𝐷𝐴1(det𝐺𝐴1)−1
2
Note: 𝐷𝐼(𝑥)=(sign(𝑥𝑖)|𝑥𝑖|𝛼−1)1≤𝑖≤𝑑 for 𝛼 >1
Special Case: 𝛼=2
Let 𝜆 be the largest eigenvalue of 𝐶+𝐶𝑇 (assumed positive), and 𝐻={𝑥:(𝐶+𝐶𝑇)𝑥 =𝜆𝑥}
be the associated eigenspace.
Theorem 8.1.2
For 𝛼=2 and 𝜆>0:
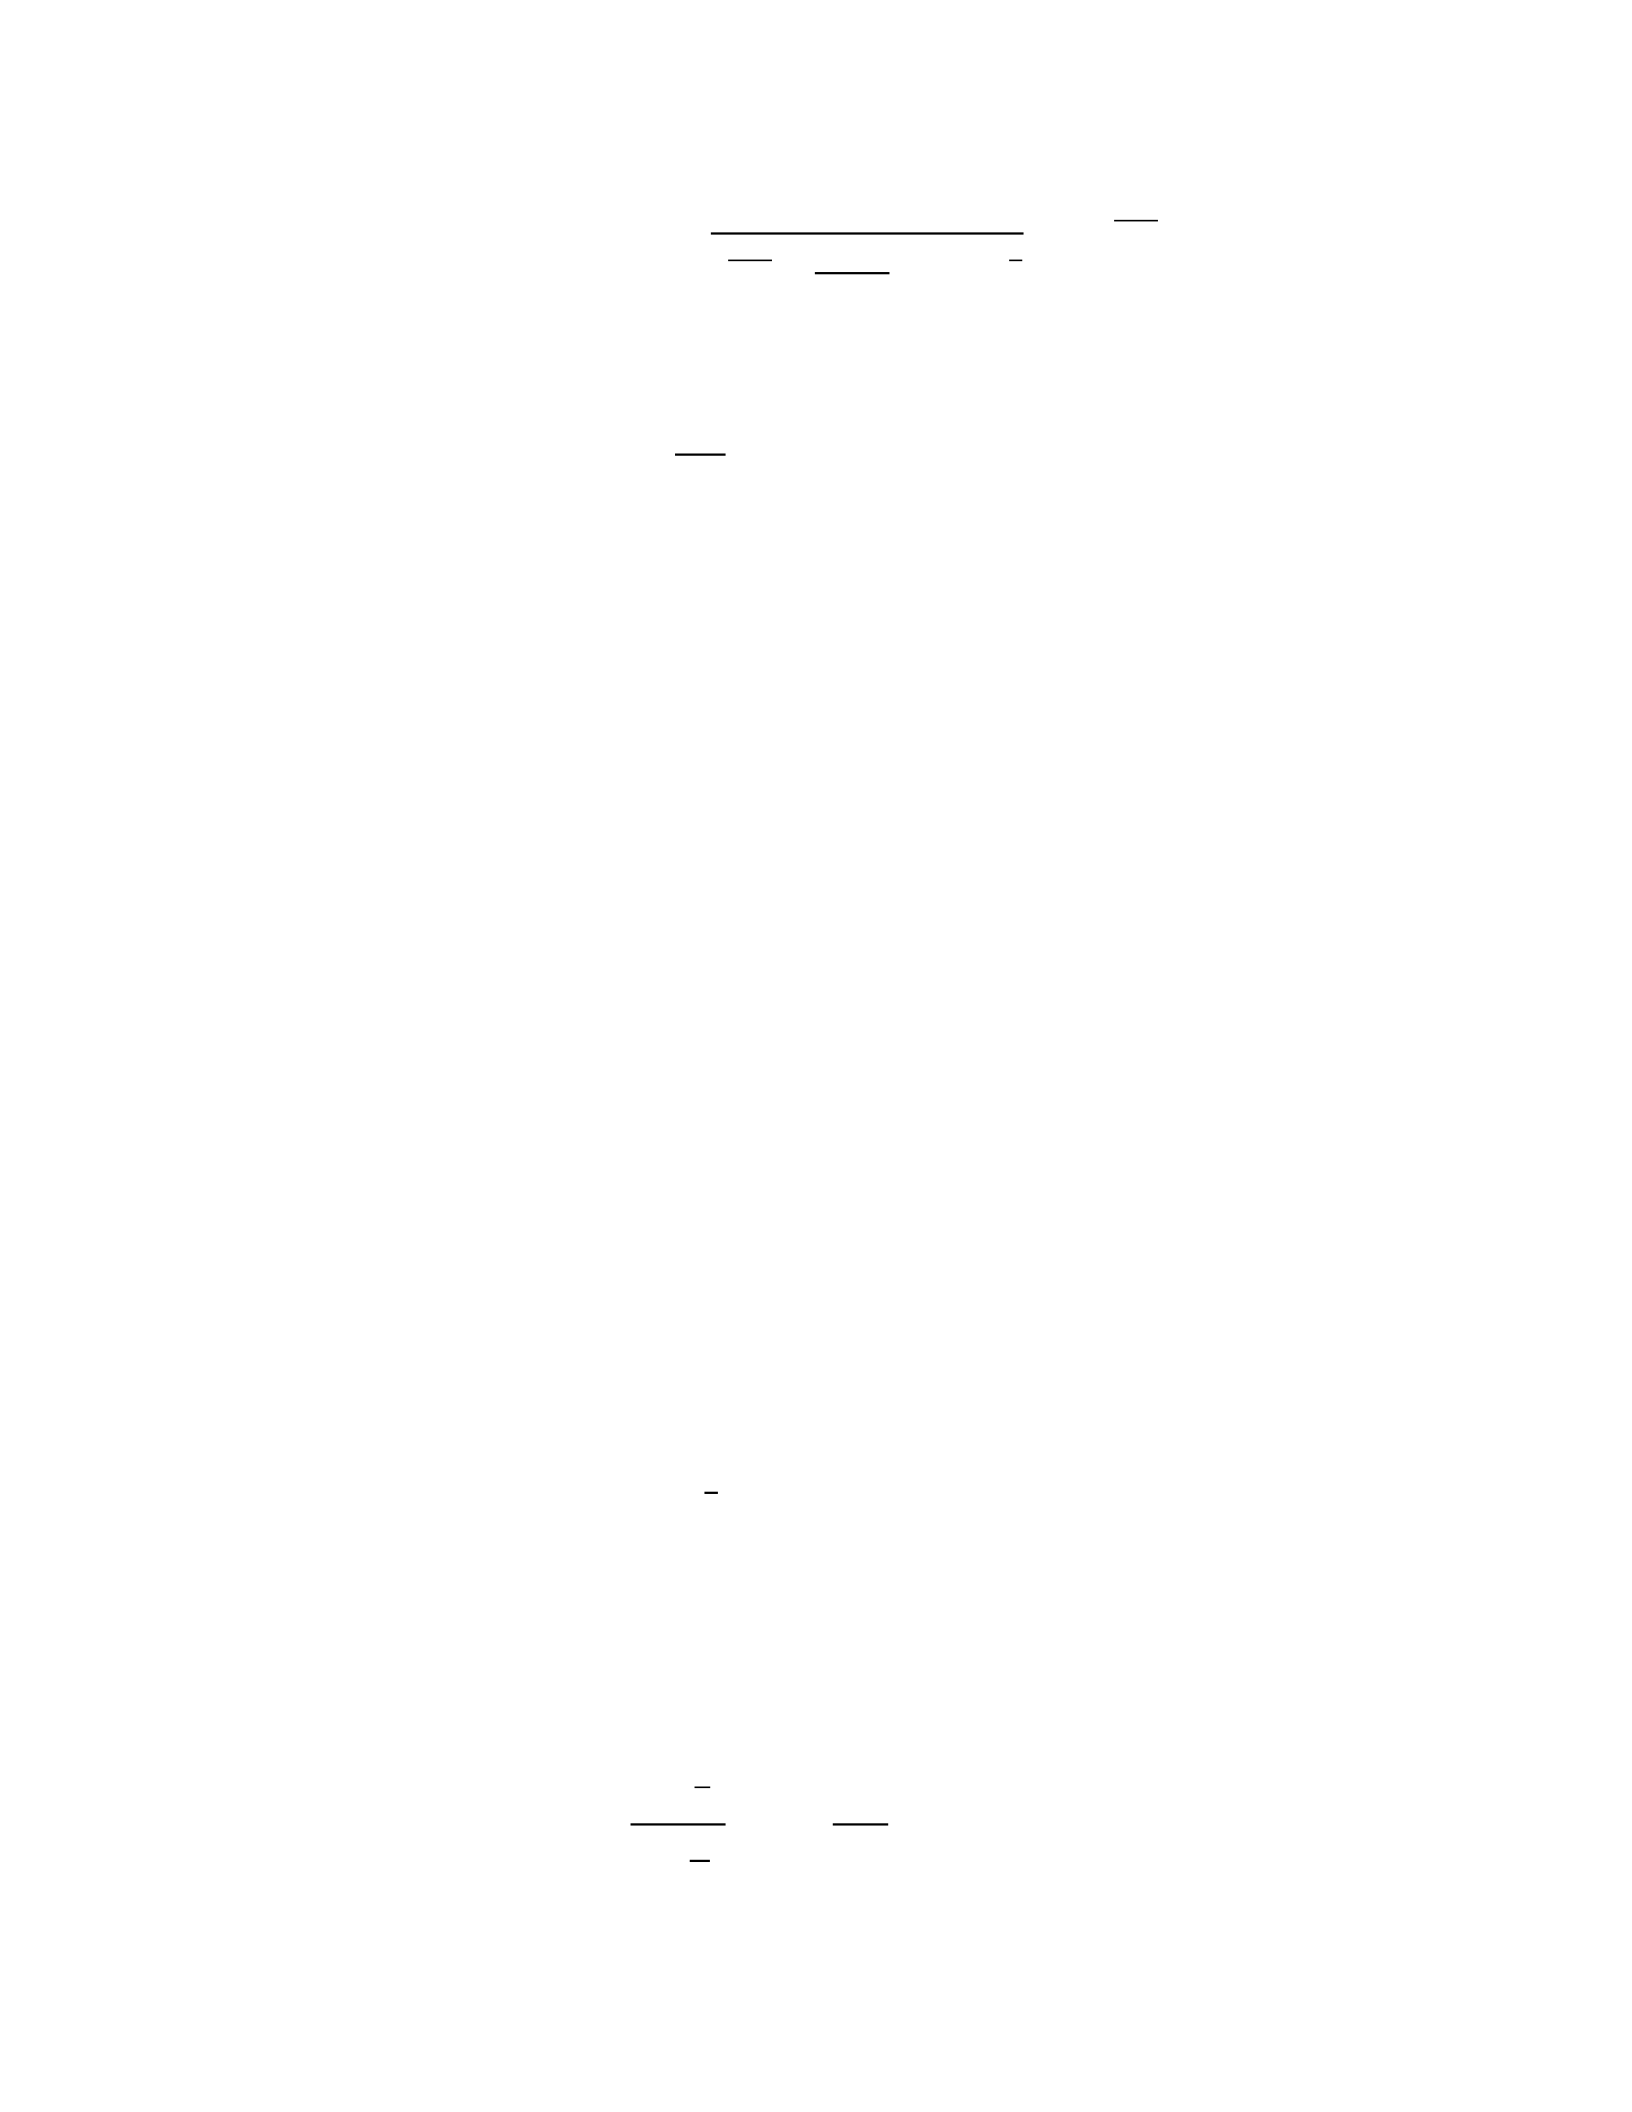
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 1
𝜆𝑘−1
2𝛤(𝑘+1
2)(det𝑀)1
2𝑒−𝑡/𝜆𝑡𝑘−1
2
where 𝑘=dim𝐻−1 and 𝑀 is the compression of 𝐼𝑑−𝜆−1(𝐶+𝐶𝑇) to 𝐻⊥.
Proof outline:
• 𝐷𝐴1 is the sphere of radius √2/𝜆 centered at the origin in 𝐻
• Apply Theorem 7.1
• Calculate 𝐼(𝐴1)=1/𝜆
• Determine 𝐺𝐴1 using second fundamental forms of 𝐼(𝐴1) and ∂𝐴1
These notes discuss the decay of probability 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡} as 𝑡 approaches infinity, where
𝑋 is a random vector in ℝ𝑑 and 𝐶 is a real 𝑑×𝑑 matrix.
Key points:
• The decay depends on the distribution of 𝑋 and matrix 𝐶
• Two types of distributions are considered: symmetric Weibull-like and Student-like
• Weibull-like tails are handled using Theorem 7.1
• Student-like tails are handled using a change of variable technique and Theorem 5.1
Light Tail Distribution Example
Setup
Consider a random vector 𝑋=(𝑋1,…,𝑋𝑑) in ℝ𝑑 with density 𝑓=𝑒−𝐼, where 𝐼 is a convex,
𝛼-positively homogeneous function on ℝ𝑑.
Important:
• 𝐴𝑡={𝑥∈ℝ𝑑:⟨𝐶𝑥,𝑥⟩>𝑡}=√𝑡𝐴1
• 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}=∫𝑒−𝐼(𝑥)
𝐴𝑡𝑑𝑥
Specific Case
Assume the components 𝑋𝑖 of 𝑋 are i.i.d. with density:
𝑤𝛼(𝑥)=𝛼1−1
𝛼
2𝛤(1
𝛼)exp(−|𝑥|𝛼
𝛼), 𝑥∈ℝ,𝛼>1

Conjecture 8.1.1: If 𝛼≠2 and 𝐶+𝐶𝑇 has no vanishing eigenvalue, then ∑ |𝑥𝑖|𝛼
𝑑
𝑖=1 admits a
finite number of minima in 𝐴1, and det𝐺𝐴1 is non-zero at these minima.
Results
For 𝛼≠2:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 𝛼𝑑−𝑑
𝛼
2𝑑𝛤(1
𝛼)𝑑𝑐1𝑒−𝑡𝛼/2𝐼(𝐴1)𝑡−(𝛼−2)𝑑
4−𝛼
4
where
𝑐1=(2𝜋)𝑑−1
2∑|𝐷𝐼(𝑥)|−𝑑+1
2
𝑥∈𝐷𝐴1(det𝐺𝐴1)−1
2
Note: 𝐷𝐼(𝑥)=(sign(𝑥𝑖)|𝑥𝑖|𝛼−1)1≤𝑖≤𝑑 for 𝛼 >1
Special Case: 𝛼=2
Let 𝜆 be the largest eigenvalue of 𝐶+𝐶𝑇 (assumed positive), and 𝐻={𝑥:(𝐶+𝐶𝑇)𝑥 =𝜆𝑥}
be the associated eigenspace.
Theorem 8.1.2
For 𝛼=2 and 𝜆>0:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 1
𝜆𝑘−1
2𝛤(𝑘+1
2)(det𝑀)1
2𝑒−𝑡/𝜆𝑡𝑘−1
2
where 𝑘=dim𝐻−1 and 𝑀 is the compression of 𝐼𝑑−𝜆−1(𝐶+𝐶𝑇) to 𝐻⊥.
Proof outline:
• 𝐷𝐴1 is the sphere of radius √2/𝜆 centered at the origin in 𝐻
• Apply Theorem 7.1
• Calculate 𝐼(𝐴1)=1/𝜆
• Determine 𝐺𝐴1 using second fundamental forms of 𝐼(𝐴1) and ∂𝐴1
These notes discuss the decay of probability 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡} as 𝑡 approaches infinity, where
𝑋 is a random vector in ℝ𝑑 and 𝐶 is a real 𝑑×𝑑 matrix.
Key points:
• The decay depends on the distribution of 𝑋 and matrix 𝐶

• Two types of distributions are considered: symmetric Weibull-like and Student-like
• Weibull-like tails are handled using Theorem 7.1
• Student-like tails are handled using a change of variable technique and Theorem 5.1
Light Tail Distribution Example
Setup
Consider a random vector 𝑋=(𝑋1,…,𝑋𝑑) in ℝ𝑑 with density 𝑓=𝑒−𝐼, where 𝐼 is a convex,
𝛼-positively homogeneous function on ℝ𝑑.
Important:
• 𝐴𝑡={𝑥∈ℝ𝑑:⟨𝐶𝑥,𝑥⟩>𝑡}=√𝑡𝐴1
• 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}=∫𝑒−𝐼(𝑥)
𝐴𝑡𝑑𝑥
Specific Case
Assume the components 𝑋𝑖 of 𝑋 are i.i.d. with density:
𝑤𝛼(𝑥)=𝛼1−1
𝛼
2𝛤(1
𝛼)exp(−|𝑥|𝛼
𝛼), 𝑥∈ℝ,𝛼>1
Conjecture 8.1.1: If 𝛼≠2 and 𝐶+𝐶𝑇 has no vanishing eigenvalue, then ∑ |𝑥𝑖|𝛼
𝑑
𝑖=1 admits a
finite number of minima in 𝐴1, and det𝐺𝐴1 is non-zero at these minima.
Results
For 𝛼≠2:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 𝛼𝑑−𝑑
𝛼
2𝑑𝛤(1
𝛼)𝑑𝑐1𝑒−𝑡𝛼/2𝐼(𝐴1)𝑡−(𝛼−2)𝑑
4−𝛼
4
where
𝑐1=(2𝜋)𝑑−1
2∑|𝐷𝐼(𝑥)|−𝑑+1
2
𝑥∈𝐷𝐴1(det𝐺𝐴1)−1
2
Note: 𝐷𝐼(𝑥)=(sign(𝑥𝑖)|𝑥𝑖|𝛼−1)1≤𝑖≤𝑑 for 𝛼 >1

Special Case: 𝛼=2
Let 𝜆 be the largest eigenvalue of 𝐶+𝐶𝑇 (assumed positive), and 𝐻={𝑥:(𝐶+𝐶𝑇)𝑥 =𝜆𝑥}
be the associated eigenspace.
Theorem 8.1.2
For 𝛼=2 and 𝜆>0:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 1
𝜆𝑘−1
2𝛤(𝑘+1
2)(det𝑀)1
2𝑒−𝑡/𝜆𝑡𝑘−1
2
where 𝑘=dim𝐻−1 and 𝑀 is the compression of 𝐼𝑑−𝜆−1(𝐶+𝐶𝑇) to 𝐻⊥.
Proof outline:
• 𝐷𝐴1 is the sphere of radius √2/𝜆 centered at the origin in 𝐻
• Apply Theorem 7.1
• Calculate 𝐼(𝐴1)=1/𝜆
• Determine 𝐺𝐴1 using second fundamental forms of 𝐼(𝐴1) and ∂𝐴1
These notes discuss the decay of probability 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡} as 𝑡 approaches infinity, where
𝑋 is a random vector in ℝ𝑑 and 𝐶 is a real 𝑑×𝑑 matrix.
Key points:
• The decay depends on the distribution of 𝑋 and matrix 𝐶
• Two types of distributions are considered: symmetric Weibull-like and Student-like
• Weibull-like tails are handled using Theorem 7.1
• Student-like tails are handled using a change of variable technique and Theorem 5.1
Light Tail Distribution Example
Setup
Consider a random vector 𝑋=(𝑋1,…,𝑋𝑑) in ℝ𝑑 with density 𝑓=𝑒−𝐼, where 𝐼 is a convex,
𝛼-positively homogeneous function on ℝ𝑑.
Important:
• 𝐴𝑡={𝑥∈ℝ𝑑:⟨𝐶𝑥,𝑥⟩>𝑡}=√𝑡𝐴1
• 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}=∫𝑒−𝐼(𝑥)
𝐴𝑡𝑑𝑥

Specific Case
Assume the components 𝑋𝑖 of 𝑋 are i.i.d. with density:
𝑤𝛼(𝑥)=𝛼1−1
𝛼
2𝛤(1
𝛼)exp(−|𝑥|𝛼
𝛼), 𝑥∈ℝ,𝛼>1
Conjecture 8.1.1: If 𝛼≠2 and 𝐶+𝐶𝑇 has no vanishing eigenvalue, then ∑ |𝑥𝑖|𝛼
𝑑
𝑖=1 admits a
finite number of minima in 𝐴1, and det𝐺𝐴1 is non-zero at these minima.
Results
For 𝛼≠2:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 𝛼𝑑−𝑑
𝛼
2𝑑𝛤(1
𝛼)𝑑𝑐1𝑒−𝑡𝛼/2𝐼(𝐴1)𝑡−(𝛼−2)𝑑
4−𝛼
4
where
𝑐1=(2𝜋)𝑑−1
2∑|𝐷𝐼(𝑥)|−𝑑+1
2
𝑥∈𝐷𝐴1(det𝐺𝐴1)−1
2
Note: 𝐷𝐼(𝑥)=(sign(𝑥𝑖)|𝑥𝑖|𝛼−1)1≤𝑖≤𝑑 for 𝛼 >1
Special Case: 𝛼=2
Let 𝜆 be the largest eigenvalue of 𝐶+𝐶𝑇 (assumed positive), and 𝐻={𝑥:(𝐶+𝐶𝑇)𝑥 =𝜆𝑥}
be the associated eigenspace.
Theorem 8.1.2
For 𝛼=2 and 𝜆>0:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 1
𝜆𝑘−1
2𝛤(𝑘+1
2)(det𝑀)1
2𝑒−𝑡/𝜆𝑡𝑘−1
2
where 𝑘=dim𝐻−1 and 𝑀 is the compression of 𝐼𝑑−𝜆−1(𝐶+𝐶𝑇) to 𝐻⊥.
Proof outline:
• 𝐷𝐴1 is the sphere of radius √2/𝜆 centered at the origin in 𝐻
• Apply Theorem 7.1
• Calculate 𝐼(𝐴1)=1/𝜆

• Determine 𝐺𝐴1 using second fundamental forms of 𝐼(𝐴1) and ∂𝐴1
These notes discuss the decay of probability 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡} as 𝑡 approaches infinity, where
𝑋 is a random vector in ℝ𝑑 and 𝐶 is a real 𝑑×𝑑 matrix.
Key points:
• The decay depends on the distribution of 𝑋 and matrix 𝐶
• Two types of distributions are considered: symmetric Weibull-like and Student-like
• Weibull-like tails are handled using Theorem 7.1
• Student-like tails are handled using a change of variable technique and Theorem 5.1
Light Tail Distribution Example
Setup
Consider a random vector 𝑋=(𝑋1,…,𝑋𝑑) in ℝ𝑑 with density 𝑓=𝑒−𝐼, where 𝐼 is a convex,
𝛼-positively homogeneous function on ℝ𝑑.
Important:
• 𝐴𝑡={𝑥∈ℝ𝑑:⟨𝐶𝑥,𝑥⟩>𝑡}=√𝑡𝐴1
• 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}=∫𝑒−𝐼(𝑥)
𝐴𝑡𝑑𝑥
Specific Case
Assume the components 𝑋𝑖 of 𝑋 are i.i.d. with density:
𝑤𝛼(𝑥)=𝛼1−1
𝛼
2𝛤(1
𝛼)exp(−|𝑥|𝛼
𝛼), 𝑥∈ℝ,𝛼>1
Conjecture 8.1.1: If 𝛼≠2 and 𝐶+𝐶𝑇 has no vanishing eigenvalue, then ∑ |𝑥𝑖|𝛼
𝑑
𝑖=1 admits a
finite number of minima in 𝐴1, and det𝐺𝐴1 is non-zero at these minima.
Results
For 𝛼≠2:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 𝛼𝑑−𝑑
𝛼
2𝑑𝛤(1
𝛼)𝑑𝑐1𝑒−𝑡𝛼/2𝐼(𝐴1)𝑡−(𝛼−2)𝑑
4−𝛼
4
where

𝑐1=(2𝜋)𝑑−1
2∑|𝐷𝐼(𝑥)|−𝑑+1
2
𝑥∈𝐷𝐴1(det𝐺𝐴1)−1
2
Note: 𝐷𝐼(𝑥)=(sign(𝑥𝑖)|𝑥𝑖|𝛼−1)1≤𝑖≤𝑑 for 𝛼 >1
Special Case: 𝛼=2
Let 𝜆 be the largest eigenvalue of 𝐶+𝐶𝑇 (assumed positive), and 𝐻={𝑥:(𝐶+𝐶𝑇)𝑥 =𝜆𝑥}
be the associated eigenspace.
Theorem 8.1.2
For 𝛼=2 and 𝜆>0:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 1
𝜆𝑘−1
2𝛤(𝑘+1
2)(det𝑀)1
2𝑒−𝑡/𝜆𝑡𝑘−1
2
where 𝑘=dim𝐻−1 and 𝑀 is the compression of 𝐼𝑑−𝜆−1(𝐶+𝐶𝑇) to 𝐻⊥.
Proof outline:
• 𝐷𝐴1 is the sphere of radius √2/𝜆 centered at the origin in 𝐻
• Apply Theorem 7.1
• Calculate 𝐼(𝐴1)=1/𝜆
• Determine 𝐺𝐴1 using second fundamental forms of 𝐼(𝐴1) and ∂𝐴1
These notes discuss the decay of probability 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡} as 𝑡 approaches infinity, where
𝑋 is a random vector in ℝ𝑑 and 𝐶 is a real 𝑑×𝑑 matrix.
Key points:
• The decay depends on the distribution of 𝑋 and matrix 𝐶
• Two types of distributions are considered: symmetric Weibull-like and Student-like
• Weibull-like tails are handled using Theorem 7.1
• Student-like tails are handled using a change of variable technique and Theorem 5.1

Light Tail Distribution Example
Setup
Consider a random vector 𝑋=(𝑋1,…,𝑋𝑑) in ℝ𝑑 with density 𝑓=𝑒−𝐼, where 𝐼 is a convex,
𝛼-positively homogeneous function on ℝ𝑑.
Important:
• 𝐴𝑡={𝑥∈ℝ𝑑:⟨𝐶𝑥,𝑥⟩>𝑡}=√𝑡𝐴1
• 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}=∫𝑒−𝐼(𝑥)
𝐴𝑡𝑑𝑥
Specific Case
Assume the components 𝑋𝑖 of 𝑋 are i.i.d. with density:
𝑤𝛼(𝑥)=𝛼1−1
𝛼
2𝛤(1
𝛼)exp(−|𝑥|𝛼
𝛼), 𝑥∈ℝ,𝛼>1
Conjecture 8.1.1: If 𝛼≠2 and 𝐶+𝐶𝑇 has no vanishing eigenvalue, then ∑ |𝑥𝑖|𝛼
𝑑
𝑖=1 admits a
finite number of minima in 𝐴1, and det𝐺𝐴1 is non-zero at these minima.
Results
For 𝛼≠2:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 𝛼𝑑−𝑑
𝛼
2𝑑𝛤(1
𝛼)𝑑𝑐1𝑒−𝑡𝛼/2𝐼(𝐴1)𝑡−(𝛼−2)𝑑
4−𝛼
4
where
𝑐1=(2𝜋)𝑑−1
2∑|𝐷𝐼(𝑥)|−𝑑+1
2
𝑥∈𝐷𝐴1(det𝐺𝐴1)−1
2
Note: 𝐷𝐼(𝑥)=(sign(𝑥𝑖)|𝑥𝑖|𝛼−1)1≤𝑖≤𝑑 for 𝛼 >1
Special Case: 𝛼=2
Let 𝜆 be the largest eigenvalue of 𝐶+𝐶𝑇 (assumed positive), and 𝐻={𝑥:(𝐶+𝐶𝑇)𝑥 =𝜆𝑥}
be the associated eigenspace.
Theorem 8.1.2
For 𝛼=2 and 𝜆>0:

𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 1
𝜆𝑘−1
2𝛤(𝑘+1
2)(det𝑀)1
2𝑒−𝑡/𝜆𝑡𝑘−1
2
where 𝑘=dim𝐻−1 and 𝑀 is the compression of 𝐼𝑑−𝜆−1(𝐶+𝐶𝑇) to 𝐻⊥.
Proof outline:
• 𝐷𝐴1 is the sphere of radius √2/𝜆 centered at the origin in 𝐻
• Apply Theorem 7.1
• Calculate 𝐼(𝐴1)=1/𝜆
• Determine 𝐺𝐴1 using second fundamental forms of 𝐼(𝐴1) and ∂𝐴1
These notes discuss the decay of probability 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡} as 𝑡 approaches infinity, where
𝑋 is a random vector in ℝ𝑑 and 𝐶 is a real 𝑑×𝑑 matrix.
Key points:
• The decay depends on the distribution of 𝑋 and matrix 𝐶
• Two types of distributions are considered: symmetric Weibull-like and Student-like
• Weibull-like tails are handled using Theorem 7.1
• Student-like tails are handled using a change of variable technique and Theorem 5.1
Light Tail Distribution Example
Setup
Consider a random vector 𝑋=(𝑋1,…,𝑋𝑑) in ℝ𝑑 with density 𝑓=𝑒−𝐼, where 𝐼 is a convex,
𝛼-positively homogeneous function on ℝ𝑑.
Important:
• 𝐴𝑡={𝑥∈ℝ𝑑:⟨𝐶𝑥,𝑥⟩>𝑡}=√𝑡𝐴1
• 𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}=∫𝑒−𝐼(𝑥)
𝐴𝑡𝑑𝑥
Specific Case
Assume the components 𝑋𝑖 of 𝑋 are i.i.d. with density:
𝑤𝛼(𝑥)=𝛼1−1
𝛼
2𝛤(1
𝛼)exp(−|𝑥|𝛼
𝛼), 𝑥∈ℝ,𝛼>1
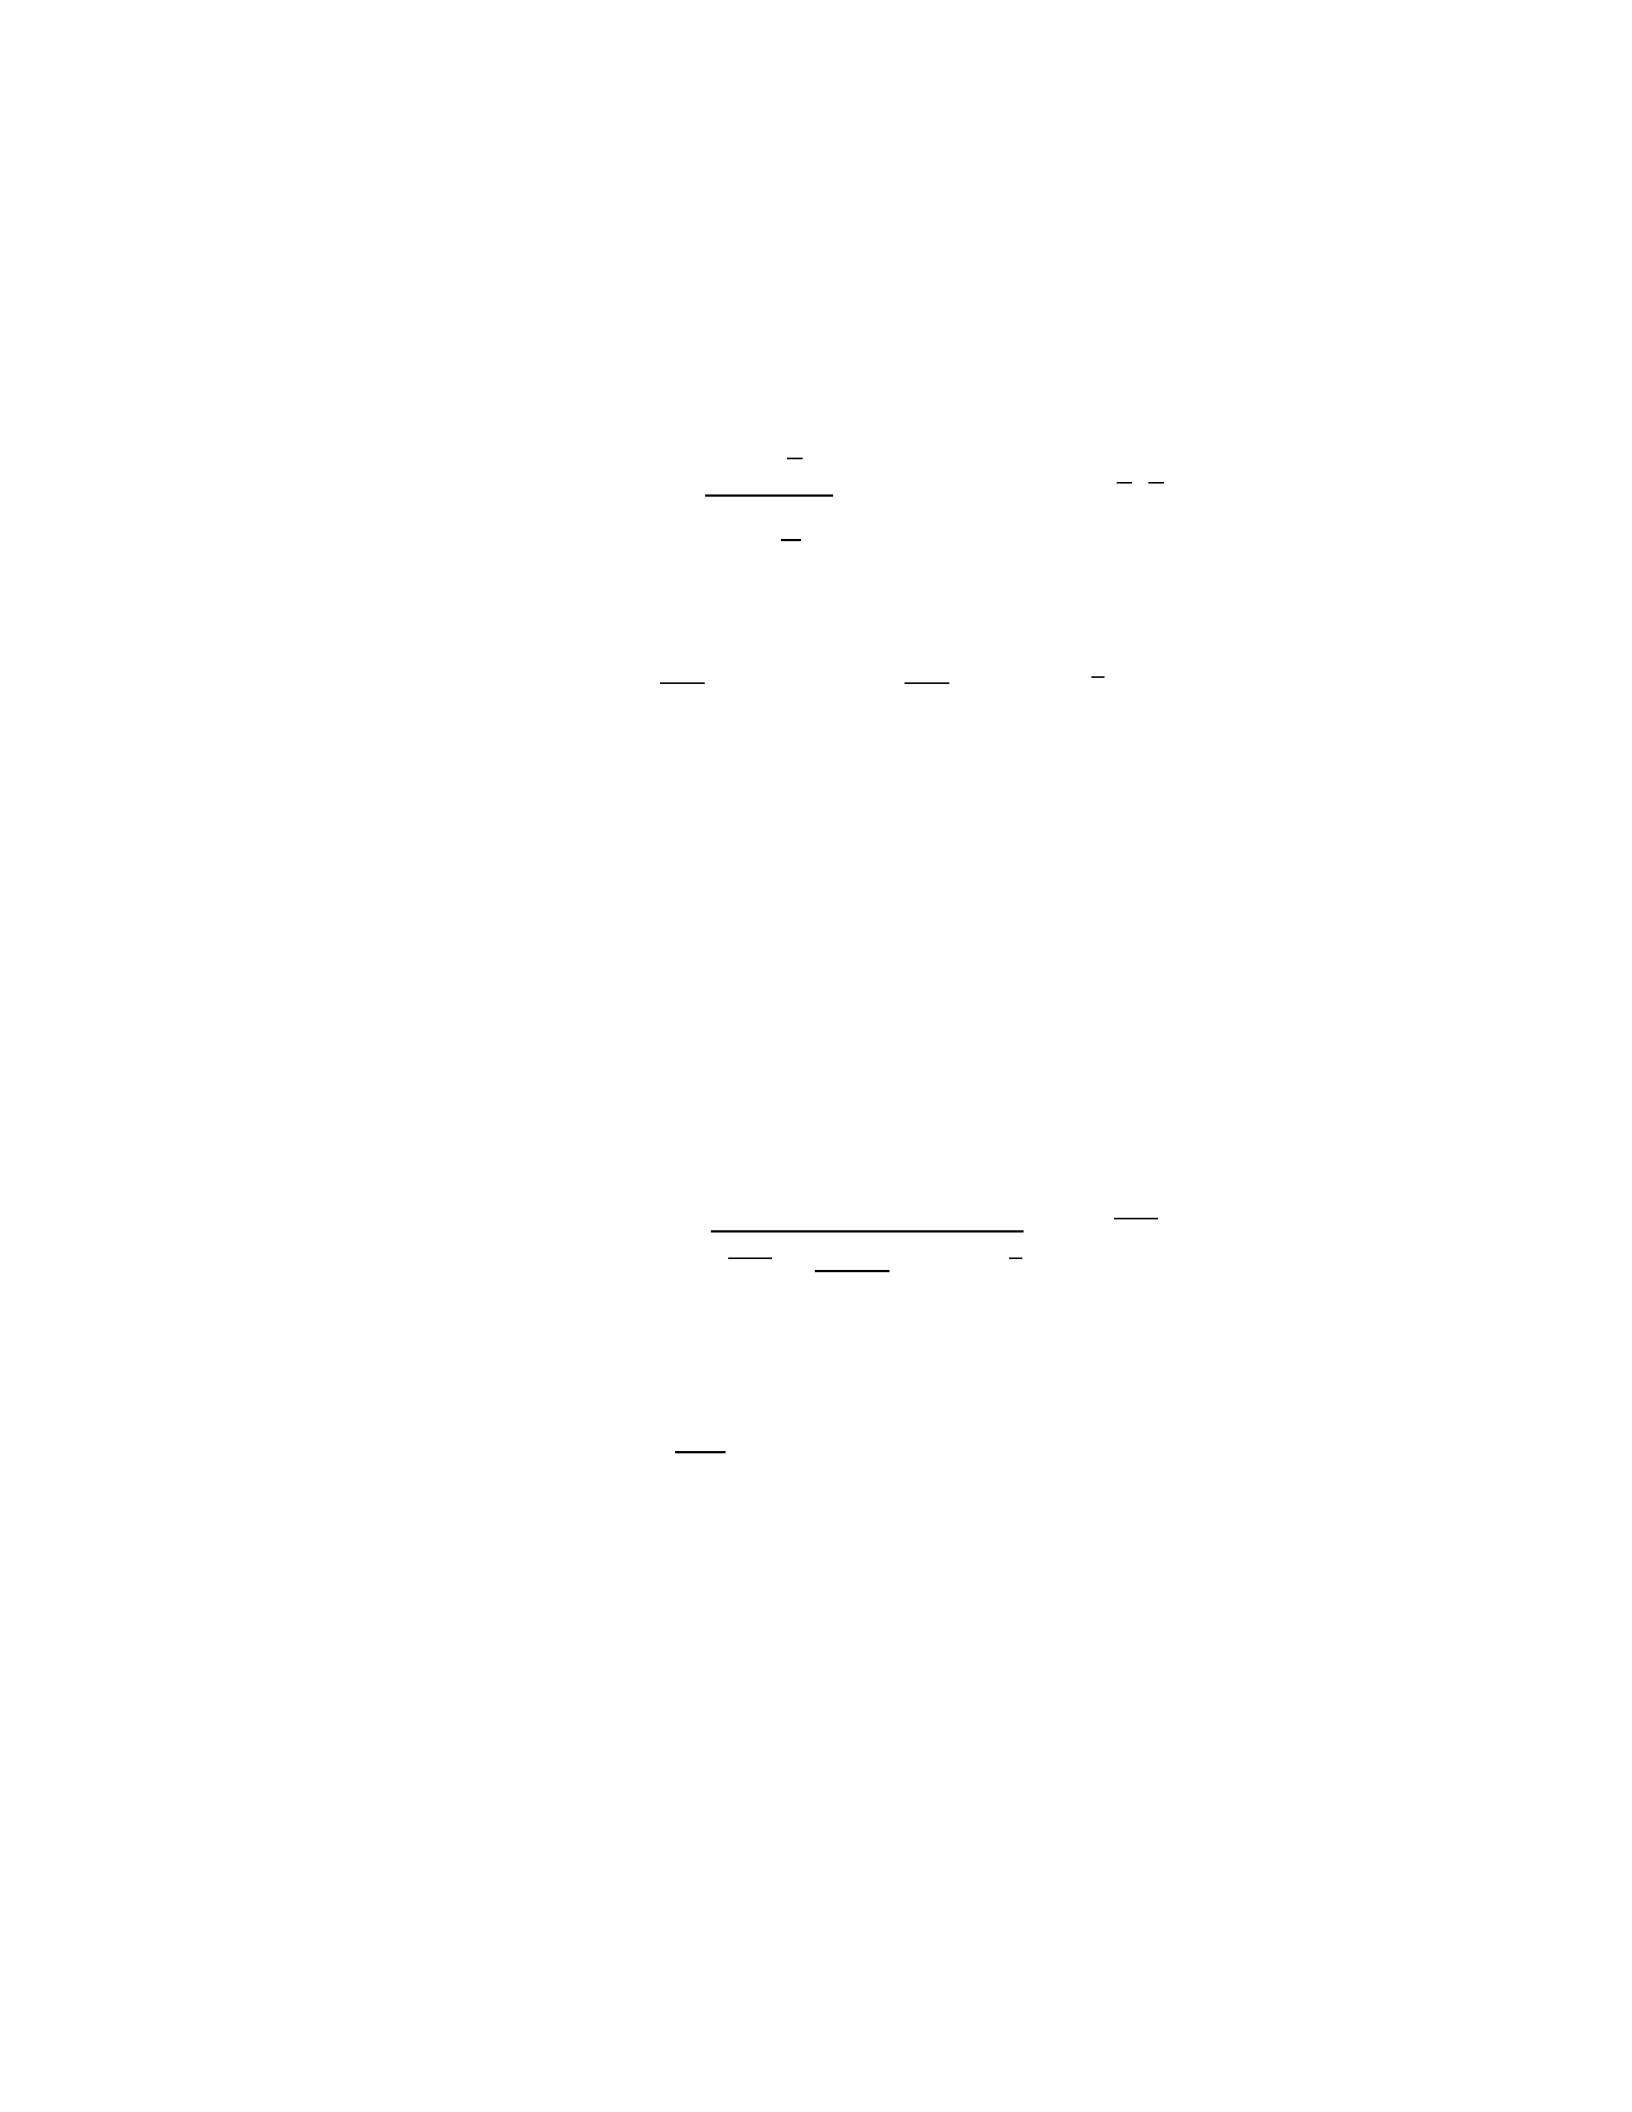
Conjecture 8.1.1: If 𝛼≠2 and 𝐶+𝐶𝑇 has no vanishing eigenvalue, then ∑ |𝑥𝑖|𝛼
𝑑
𝑖=1 admits a
finite number of minima in 𝐴1, and det𝐺𝐴1 is non-zero at these minima.
Results
For 𝛼≠2:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 𝛼𝑑−𝑑
𝛼
2𝑑𝛤(1
𝛼)𝑑𝑐1𝑒−𝑡𝛼/2𝐼(𝐴1)𝑡−(𝛼−2)𝑑
4−𝛼
4
where
𝑐1=(2𝜋)𝑑−1
2∑|𝐷𝐼(𝑥)|−𝑑+1
2
𝑥∈𝐷𝐴1(det𝐺𝐴1)−1
2
Note: 𝐷𝐼(𝑥)=(sign(𝑥𝑖)|𝑥𝑖|𝛼−1)1≤𝑖≤𝑑 for 𝛼 >1
Special Case: 𝛼=2
Let 𝜆 be the largest eigenvalue of 𝐶+𝐶𝑇 (assumed positive), and 𝐻={𝑥:(𝐶+𝐶𝑇)𝑥 =𝜆𝑥}
be the associated eigenspace.
Theorem 8.1.2
For 𝛼=2 and 𝜆>0:
𝑃{⟨𝐶𝑋,𝑋⟩>𝑡}∼ 1
𝜆𝑘−1
2𝛤(𝑘+1
2)(det𝑀)1
2𝑒−𝑡/𝜆𝑡𝑘−1
2
where 𝑘=dim𝐻−1 and 𝑀 is the compression of 𝐼𝑑−𝜆−1(𝐶+𝐶𝑇) to 𝐻⊥.
Proof outline:
• 𝐷𝐴1 is the sphere of radius √2/𝜆 centered at the origin in 𝐻
• Apply Theorem 7.1
• Calculate 𝐼(𝐴1)=1/𝜆
• Determine 𝐺𝐴1 using second fundamental forms of 𝐼(𝐴1) and ∂𝐴1
•

