


1
Chapter 1
INTRODUCTION
1.1 THE AUTOMATION PROBLEM
By design, the Internet supports a perpetually evolving patchwork of networked
applications and services. Popular applications include the World Wide Web,
online commerce and banking, email, instant messaging, blogging, multimedia
streaming, and multiplayer online video games. Practically all networked applica-
tions have a common objective: to directly or indirectly process requests generated
by humans. Specifically, the above applications all directly inform, entertain, or
transact business with human users. Other fundamental Internet services like the
Domain Name System (DNS) [81] or the Network Time Protocol (NTP) [80] are
used by those higher level applications and thus indirectly process human requests;
users rarely query them directly.
Malicious Users Automate Their Participation. Often malicious (i.e.,
adversarial) users of network applications employ automation to gain an advantage
over or simply frustrate the non-automated users. That advantage translates
to unfair access to the service, sometimes completely denying human users any
access at all. Such adversaries have political, reputational, or fiscal motivations for
employing automation. Adversaries have little legal disincentive to automate since
they can simply operate in jurisdictions with weak cyber-laws and enforcement.
Exacerbating the situation, there are few technological barriers to automate as
the automation of network applications is inexpensively achieved through software
agents commonly referred to as “Internet robots,” or simply as “bots.”

2
Adversary Automation Impacts Application Viability. Adversarial
automation affects not only legitimate users but it also threatens the very viability
of networked applications. An application’s developer or proprietor (hereon
referred to as the “service provider”) runs the application to distribute ideas or
goods. Adversarial automation makes the application less accessible, less efficient,
and more costly for the average user and consequently results in lost revenue for
the service provider.
Some adversaries intentionally attack the availability of a service. Adversaries
perform these attacks (referred to as denial-of-service attacks) out of some grudge
for the service provider or when hired to do so by a competitor of the service
provider. When the service is unavailable, the service provider loses potential
customers and the corresponding revenues. Other adversaries unintentionally
lower the efficiency of an application while performing their automation. For
example, email spammers intend to solicit business rather than disrupt legitimate
correspondence. Other adversaries, like automated ticket scalpers, drive up the
cost of popular commodities. While the scalpers turn a quick profit, legitimate
customers pay a higher price for the tickets than they otherwise would have. The
price represents revenue that could have been captured by the original vendor, yet
may have been forgone in an effort to make the tickets available to a wider market.
Additionally, the perception of automated adversaries running rampant within
an application (e.g., cheaters in online games) hurts the reputation of the service
provider. In saturated and very competitive markets, a service provider’s tarnished
reputation will discourage participation by legitimate users and can cause the
application to fail even though it may be accessible, efficient, and inexpensive.
While we oppose adversarial automation, we support service provider au-
tomation as it stands to make applications more accessible, more efficient, and
less expensive for users. Specifically, we argue that service providers must have
an automated approach to mitigating automated adversaries. This dissertation
presents methods for mitigating adversarial automation in networked applications.

3
Legitimate Automation Exists. While uncommon, not all client au-
tomation is harmful. In fact, some types of client automation are beneficial
when properly identified and operated according to directives laid out by the
service provider. One notable example is the prevalence of “web crawlers” which
algorithmically index the World Wide Web on behalf of search engines such as
Google. When restrained from overwhelming a website’s resources, web crawlers
benefit a website as it becomes locatable through web-searches by potentially
interested users. The important distinction is that legitimate automation supports
rather than undermines the goals defined by the service provider.
1.1.1 Examples of Adversarial Automation
This section discusses specific examples of adversarial automation which negatively
impacts various network applications. These examples are classified by the main
advantage that each type of automation provides: repetition, accurate timing,
or action precision. Some examples demonstrate that clever adversaries apply a
hybrid human-software approach; automating all possible tasks of the application
and merely engaging a human to circumvent existing anti-automation mechanisms.
Table 1.1 on page 14 summarizes these examples.
Repetition-Based Automation
Repetition-based automation performs very simple, structurally repetitive tasks
tirelessly, more quickly, and less expensively than hired humans could do alone.
Repetition is the dominant advantage that automation provides to adversaries as
evidenced by the breadth of the examples presented next.
Port Scans. At the network and transport layers of the Internet [130], port
scans are often a precursor to other network-level attacks. A port scan is an
automatically-generated sequence of packets sent to a target network in order to
probe and enumerate its connected hosts. The port scan lists all the networked
machines and the network services running on each of them.

4
Port scans are effective because network services are commonly built upon one
of two transport layer protocols: the Transmission Control Protocol (TCP) [91] or
the User Datagram Protocol (UDP) [90]. Both protocols rely upon ports (hence the
name “port scan”) to identify and partition traffic to different network applications
running on the same machine. Network services wait for client requests at well-
defined application-specific ports. By probing and eliciting a response from a
specific port, a port scanner can determine whether or not a specific application is
running on the target machine.
The adversary perpetrating an automated port scan is often searching for
computers running application software with an unpublished or unrepaired exploit
which they intend to attack before it is fixed. This type of port scan, called a “port
sweep,” probes a small number of ports across a large number of machines. At a
later time, the adversary may manually subvert one or more of the vulnerable
machines as a gateway into the private network (e.g., corporate, military, or
government networks) or use a large set of vulnerable hosts as the initial hit-list
of machines to infect with an automated network worm [107].
By themselves, port scans do not catastrophically disrupt the applications they
probe. However, by mitigating port scans an application service provider can
reduce the likelihood of being targeted by an imminent attack that might bring
down their application or co-opt their machines into attacking other network hosts
or applications.
Network Worms. A network worm is a self-replicating malicious computer
program. The worm has two functions: to infect additional network hosts and to
deliver a malicious payload programmed by the adversary. The first function often
involves port scans to search for new network hosts with identical vulnerabilities.
While the occasional port scan is not disastrous, a worm’s port scan traffic grows
exponentially as more network hosts are infected. As demonstrated by the Slammer
Worm in January 2003 [82], this can have a crippling effect on the network and
impact the accessibility of all network applications.

5
The second function of the worm is to execute its malicious payload. In a
growing number of cases, the payload directly assaults the privacy of the machine
owner and is hence referred to as “spyware.” This payload seeks out and reports
back any sensitive personal information found on the machine. Specialized spyware
known as a “key-loggers” record passwords entered by users via their keyboards.
Most commonly though, worms install a simple process that awaits commands
issued by the adversary at a future time. In effect, the adversary uses the worm to
create an army of subservient networked machines (referred to as a “botnet”) ready
to perpetrate other repetitious attacks. Botnet machines (individually referred to
as “zombies”) are co-opted without their owner’s knowledge and the adversary
attempts to operate them in a manner that minimizes the likelihood that owners
discover and remove the zombie processes. Botnets range in size from hundreds to
tens of thousands of zombie machines. In some remarkable cases, botnets consisting
of hundreds of thousands of zombies have been recorded [21, 23].
Denial-of-Service Attacks. Denial-of-Service (DOS) attacks directly
assault the accessibility of an application by overwhelming the service provider
with bogus requests. The unrelenting barrage of bogus requests exhausts all the
service provider’s resources so that it cannot respond to legitimate user requests.
Distributed Denial-of-Service (DDOS) attacks often leverage botnets to radically
scale the resource imbalance in the adversary’s favor. This also allows the adversary
to assign the attack effort over many zombie machines to reduce the likelihood
that individual zombies are discovered and repaired. Vulnerable service provider
resources include network bandwidth, computation cycles, and machine memory.
Regardless of the application, network bandwidth is a vulnerable service
provider resource. As an expensive ongoing operating cost, service providers
rationally provision only enough bandwidth to handle the expected client load
for the application with some bandwidth to spare. When an adversary has greater
bandwidth at their disposal than the service provider (e.g., the adversary controls
a large botnet), it can swamp the application with a flood of network packets.
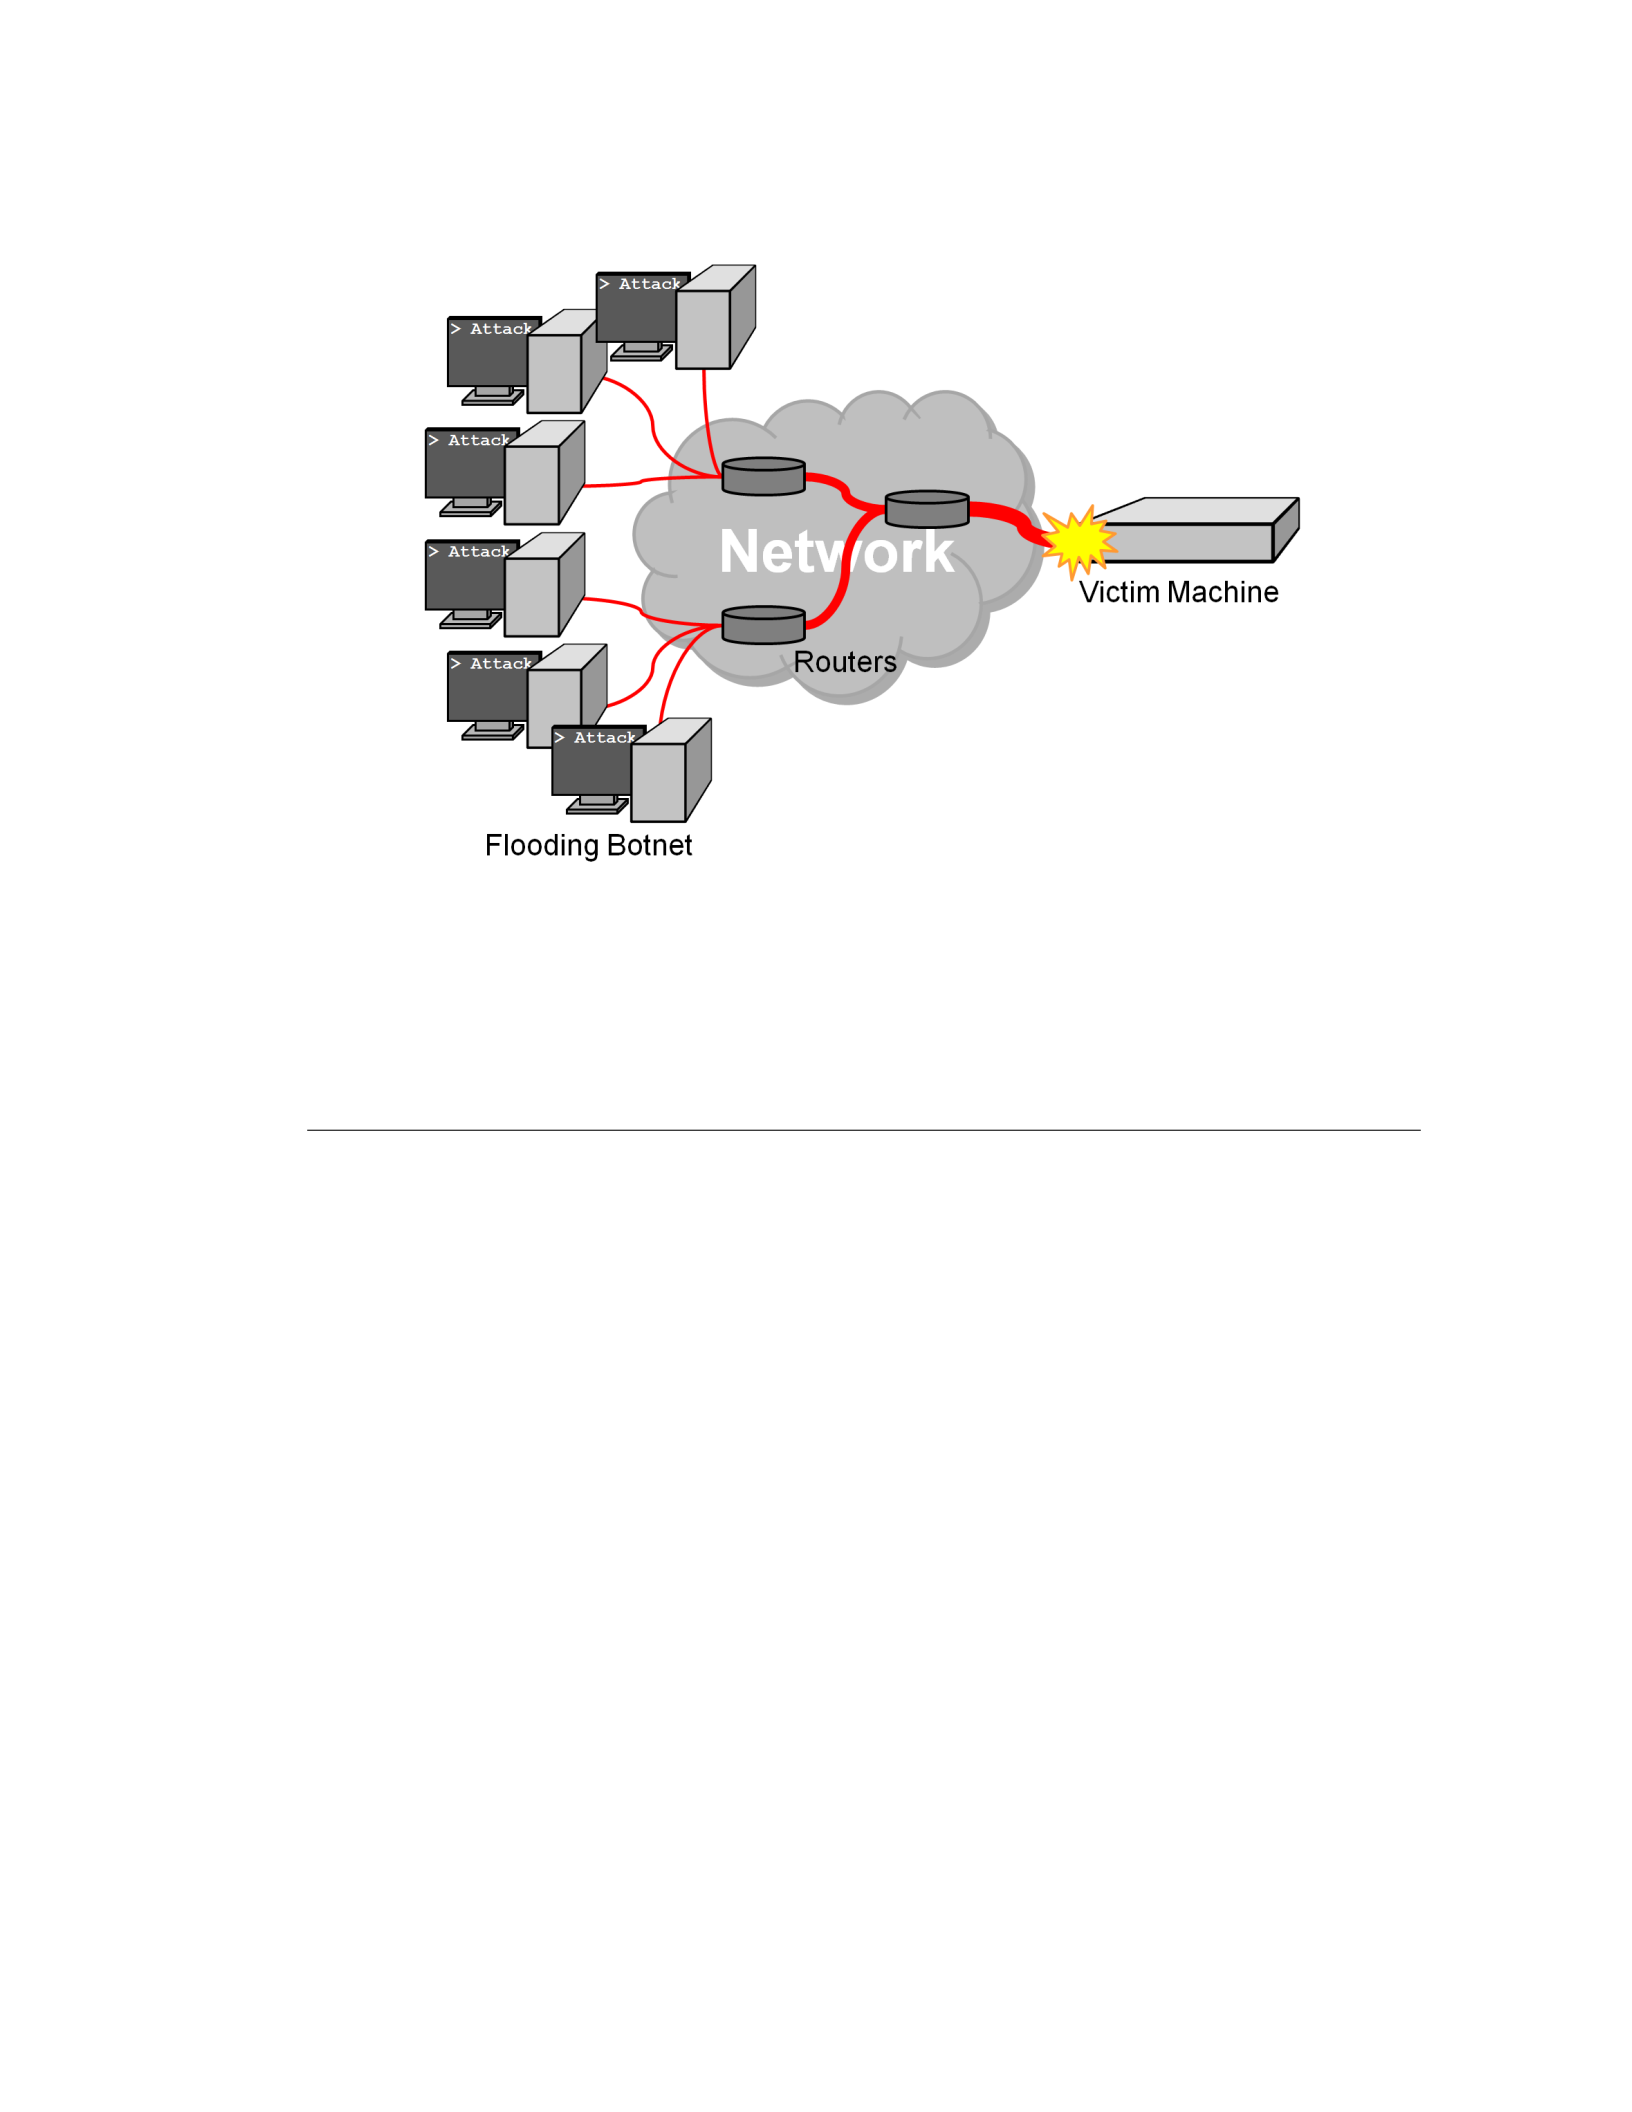
6
Figure 1.1: Example of flooding-based Distributed Denial-of-Service attack.
Each zombie machine generates a small, steady, packet flow. The flows converge as
they approach the victim and eventually fully congest a network link to the point
where packets, including those from legitimate users, are discarded.
The attack congests the service provider’s connection to the Internet as illustrated
by Figure 1.1. In this state, network packet buffers are filled to capacity and
are forced to discard packets. During a persistent packet flood, many packets
belonging to legitimate clients are discarded, thereby disrupting or completely
denying communication with the service provider.
To orchestrate a computation-depletion DOS attack, an adversary employs
automation to repeatedly send application-specific requests that are difficult for
the service provider to process. These requests are often easy for the adversary
to generate but are hard for the service provider to dismiss outright since they
adhere to the application’s protocol. The complex yet bogus requests consume a
disproportionately large amount of the service provider’s processor cycles, reducing
the cycles it has left to process legitimate requests. This critically lowers the
application’s efficiency and negatively impacts its accessibility.

7
Memory consumption attacks operate in much the same manner. An intent
adversary repeatedly sends application-specific requests to participate in the
application’s protocol just to the point where the service provider allocates some of
its limited memory to transacting with the adversary. Using only a few machines,
an adversary can keep all of the service provider’s memory resources committed
to connections waiting for further correspondence that will not come. Although
those connections will eventually timeout and be reset, the adversary can continue
to reconnect and reoccupy the resources as frequently as they timeout.
Email and Instant Messaging Spam. Spam is a nuisance that practically
every email user has experienced at some time or another. Spam is any unwanted
solicitous or duplicitous electronic message. While widely recognized as a problem
for email, spam is also a problem for other electronic communication methods,
including instant messaging and messaging within online video games. Solicitous
spam often advertises goods at unbelievably low prices in an attempt to sell
imitation goods to the victim or to outright defraud them. Deceptive spam
messages, known as “phishing” attacks, trick recipients into believing that the
sender is the administrator of their email account, online bank account, or another
web-based account. Through this deception, the adversary elicits victims to
reveal their passwords or other personal information. An adversary on a spam
campaign typically employs a botnet to generate and deliver messages to a large,
indiscriminate set of recipients en masse. While the success rate for any single
message is low, the success of even a small fraction of messages makes this
automation immensely profitable for the adversary.
Comment Spam. Similar to spam, adversaries flood websites that allow
users to submit comments with solicitous messages. Often an adversary uses a
specialized web crawler to locate websites that accept user comments and then
automatically enter the spam message. This nuisance is colloquially referred to
as “crap-flooding” by bloggers frustrated about the impact of this indiscriminant
attack on their blogs.
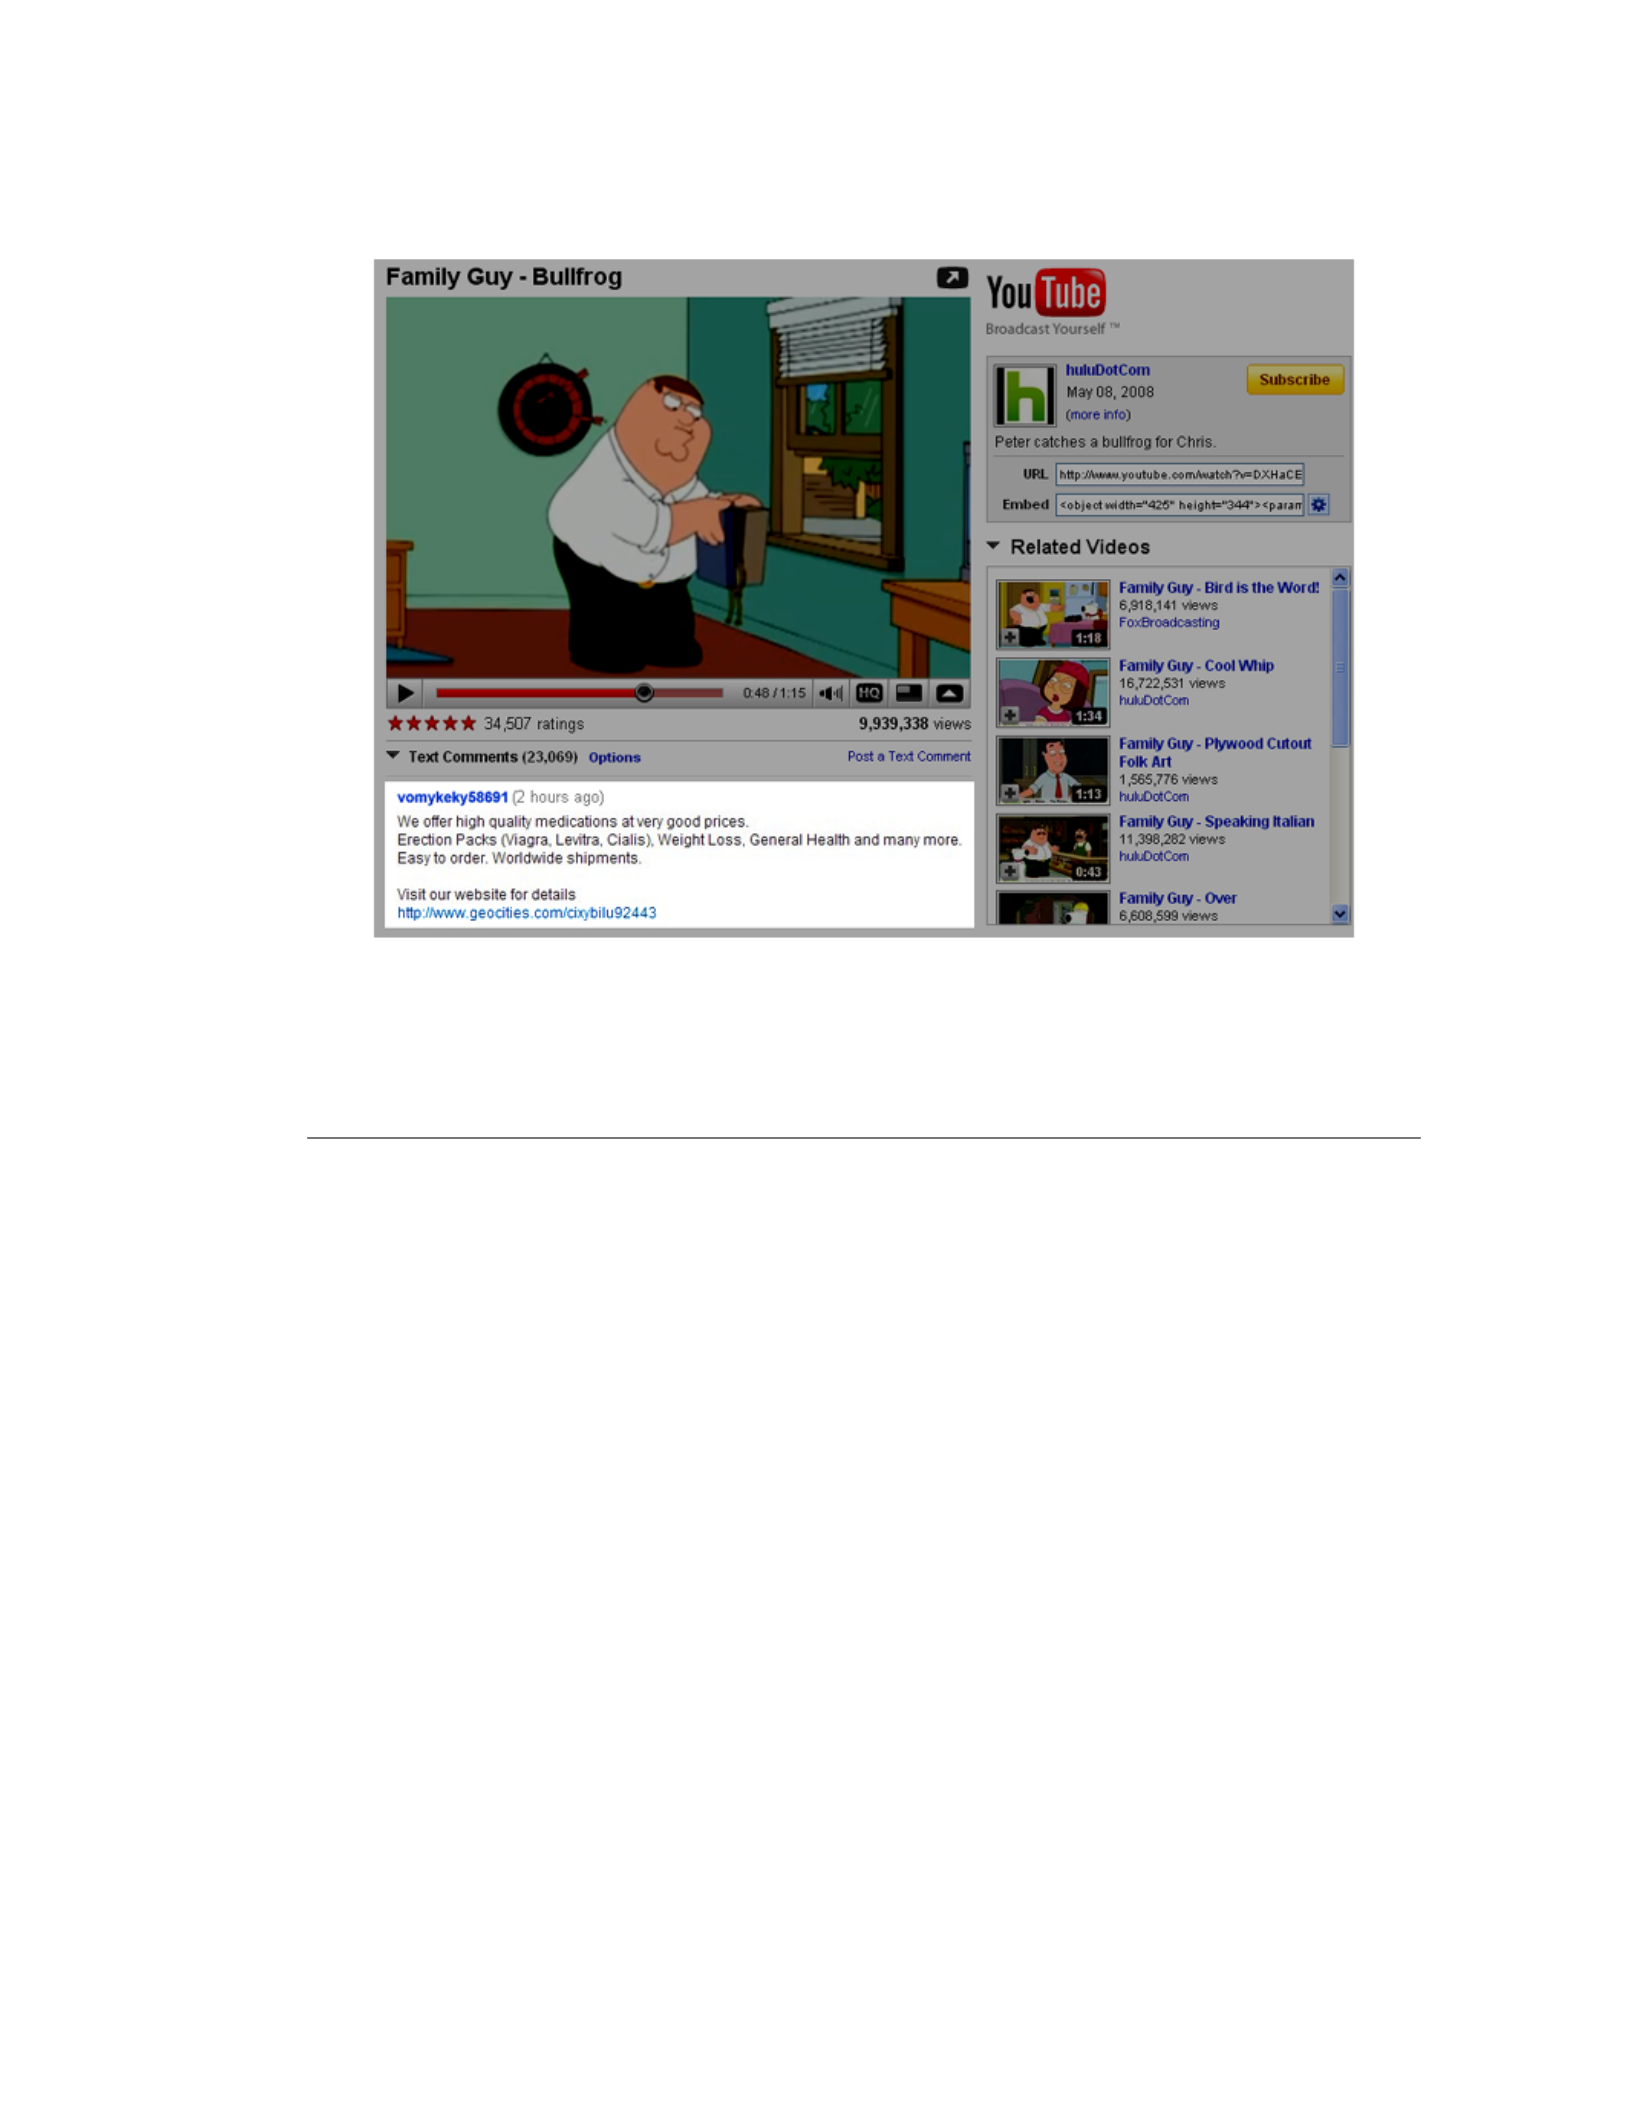
8
Figure 1.2: Solicitous spam comment posted on YouTube. The comment
(highlighted in the lower left corner of the image) is advertising “quality
medications at very good prices” by following a link to a temporary website.
While comment spammers may be trying to solicit business directly from
readers, spammers also have another goal which is unique to this application:
bolstering the rank of their website in search engine results. Specifically, they
intend to improve their rank within Google search results, hence this attack is
also known as “Google bombing.” This motivation exists because the PageRank
algorithm [87] that powers the Google search engine sorts search results partially
by how well each webpage is connected to the rest of the Internet. In particular,
a result is biased towards the top of the results list if other popular websites
link to it numerous times, effectively favorably endorsing it. Ironically YouTube,
which is owned by Google, is a fashionable website for adversaries to comment
spam as shown in Figure 1.2. Those comment spammers hope to transform some
of YouTube’s massive popularity into improved ranking of their own temporary,
commercial website.
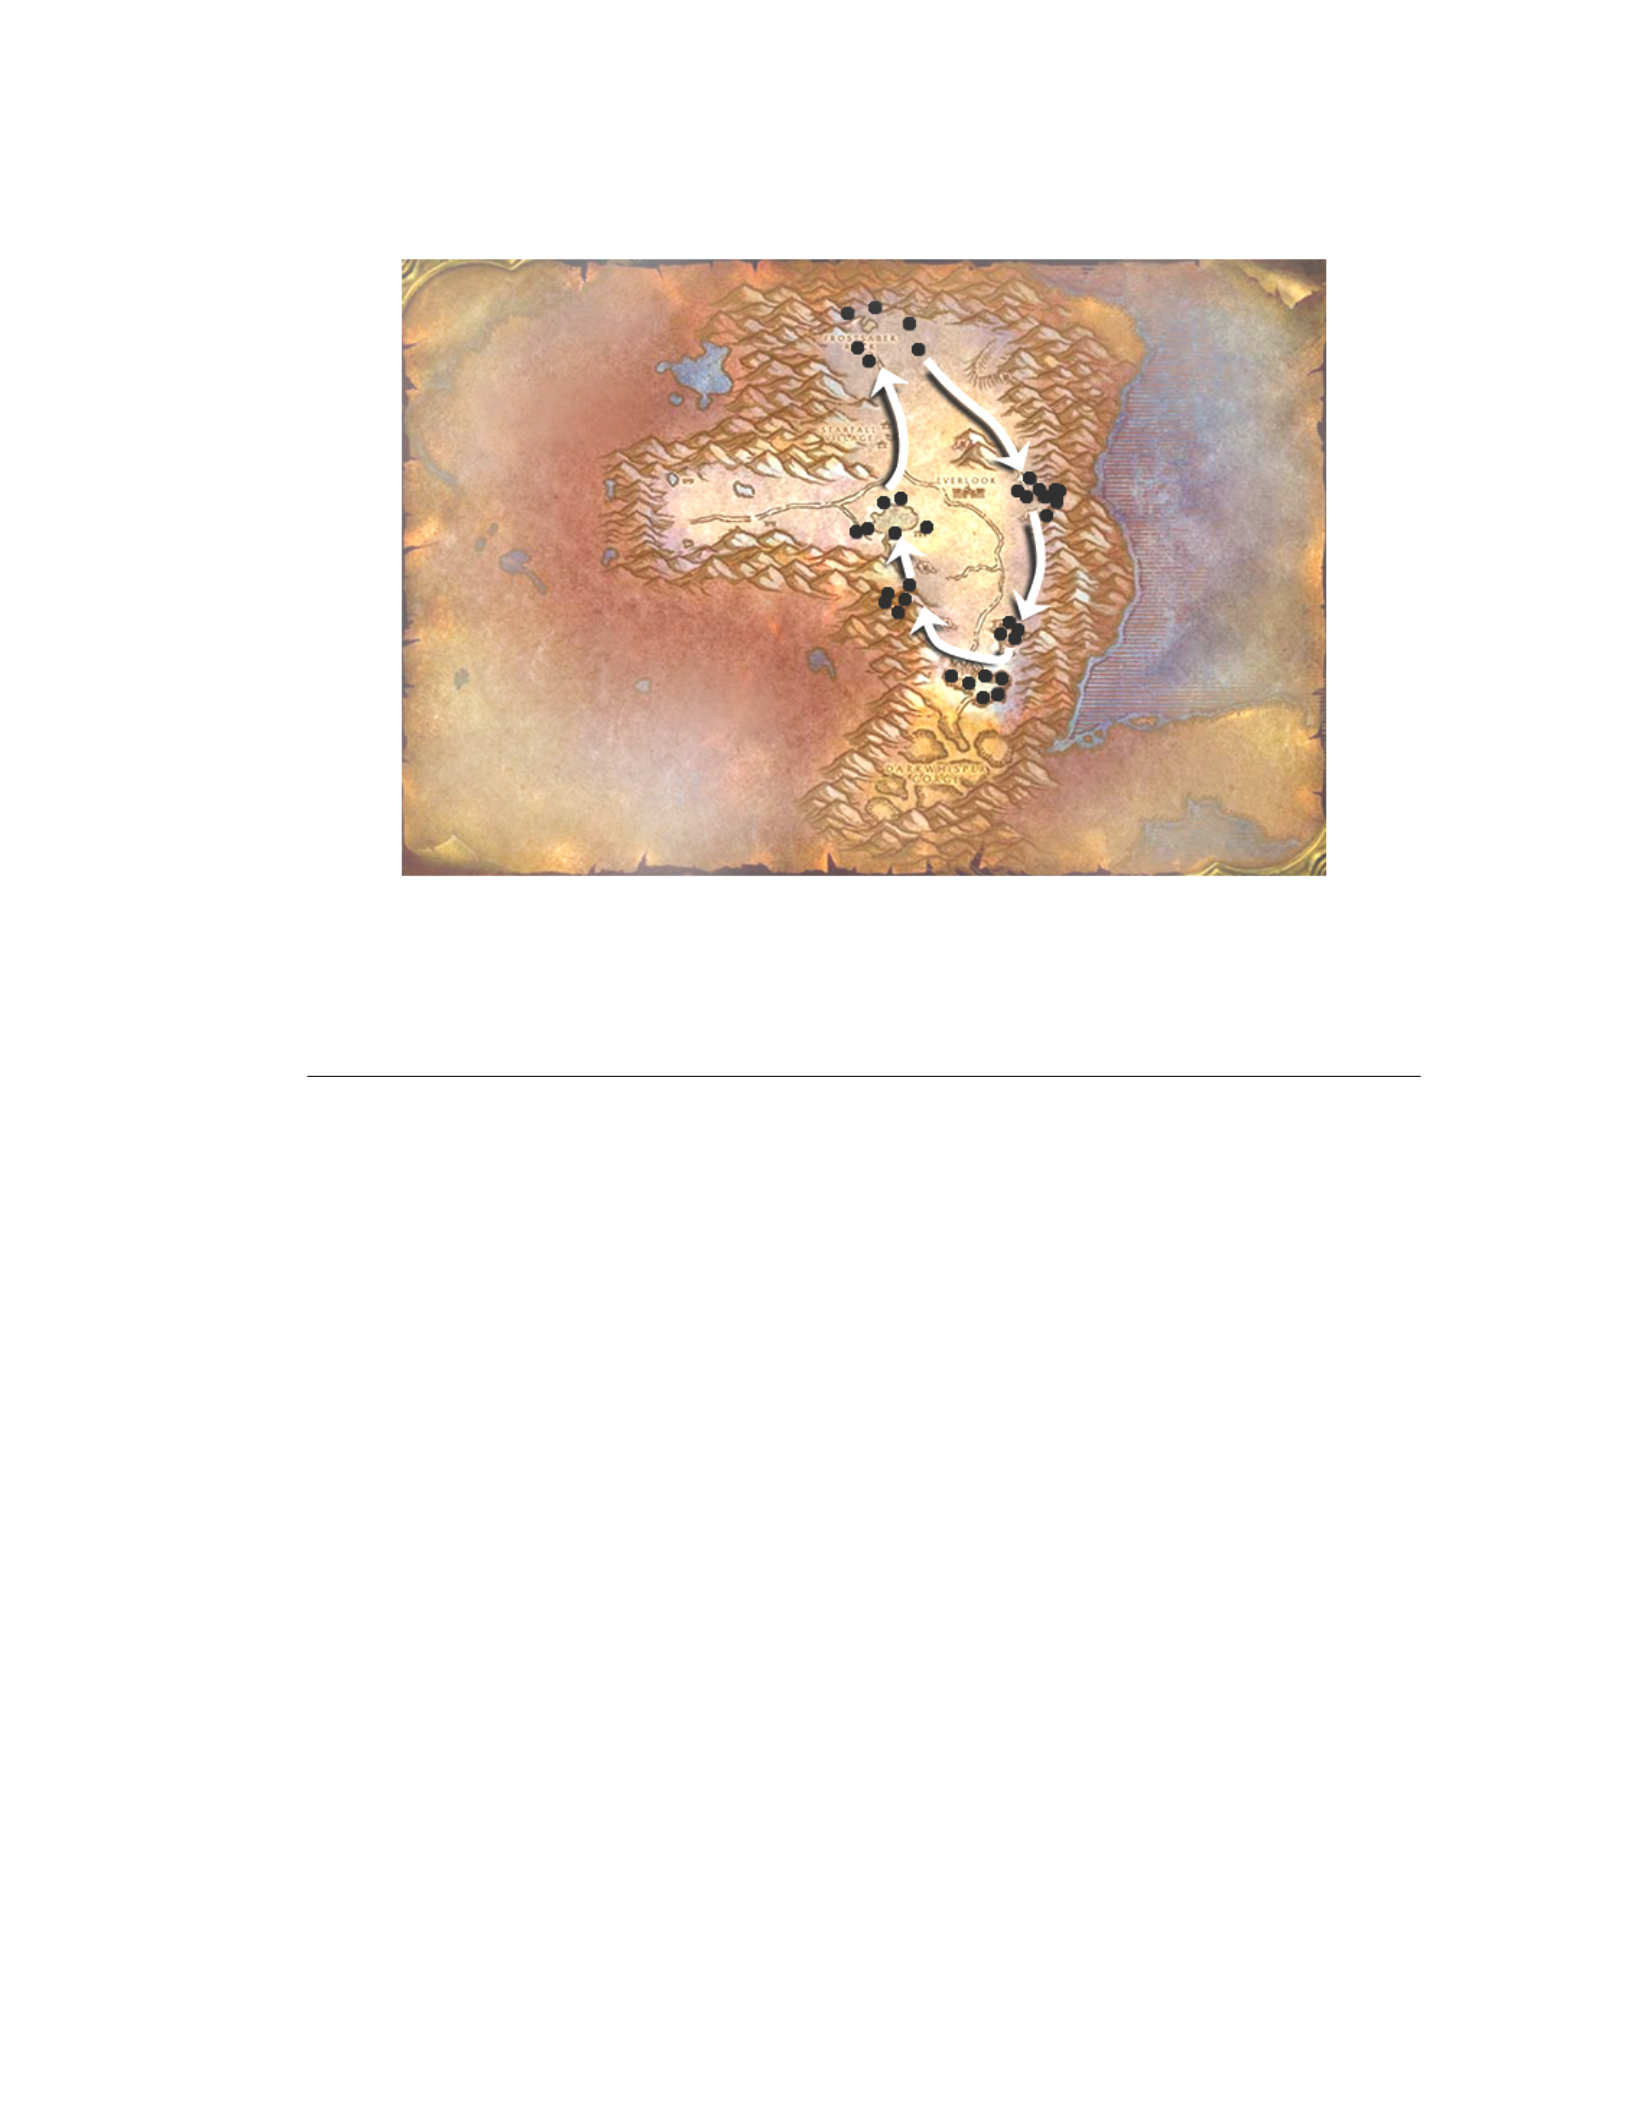
9
Figure 1.3: Gold farmer botting path. This path was historically used by gold
farming bots to mine valuable ore in the World of Warcraft zone Winterspring.
Dots indicate the spawn locations of precious Rich Thorium Ore nodes.
Leveling & Grinding Bots. In massively multiplayer online role playing
games (MMORPGs) like World of Warcraft [13], a player’s social status is closely
tied to the exceptionality of their in-game avatar. Specifically, players strive
to have high-level avatars with rare equipment. Game developers make this
goal non-trivial so that players must continue to play the game (while paying
a monthly subscription fee) to accomplish this. Furthermore, to keep the game
interesting, the developer periodically patches the game to include new, more
powerful equipment and allow avatars to attain new, previously unattainable levels.
Individuals without the patience to play the game and achieve these goals resort
to automated software to play their avatar on their behalf. The act of mindlessly
and continuously hunting virtual monsters is referred to as “grinding.” Automated
software that grinds character levels, in-game currency, or virtual loot are called
“gliders” and are of great concern to game developers because they shorten the
normal life cycle of virtual assets.

10
Game automation spawned the Real Money Trade market (RMT) [108] where
virtual gold and items are exchanged for real currencies. Enterprising individuals
in foreign countries exploit cheap labor to manage the automation of multiple
avatars simultaneously [58]. The laborers (disparagingly referred to as “gold
farmers”) dislodge avatars that get stuck on terrain obstacles, avoid vigilante
players attempting to disrupt them, and dispute game moderators investigating
player-generated reports about their automated behavior. Figure 1.3 shows a
circuit within a World of Warcraft zone used at one time by gold farming bots
to gather precious ore and gems.
Besides undermining the game’s enjoyment for legitimate players, the contin-
uous stream of complex in-game actions that gold farming bots undertake has
significant resource implications for the service provider. A recent campaign to
eliminate gold farmers in the MMORPG entitled EVE Online discovered that 2% of
the total player accounts were involved in gold farming. After those accounts were
banned from the game, the game’s developer observed a dramatic 30% reduction
in computation load [17].
Leveling characters and grinding virtual goods using automated programs has
very high profit margins. As a consequence, the RMT market has become so
saturated with competing adversaries that they have resorted to spamming in-
game communication channels to advertise cheap gold or avatar leveling services.
Referred to as “gold spamming,” this activity demonstrates the willingness of
adversaries to apply additional automation techniques to the target application
in order to selfishly increase their own benefit.
Furthermore, the unexpected and popular RMT market has so far gone
unregulated. As a result, numerous illegal and more morally reprehensible
behaviors have become rampant: activities such as theft of account information,
money, or credit card numbers, and even money laundering. While some nations
are considering virtual property ownership laws, addressing the root problem of
automation would be a first step towards safeguarding consumers in that market.

11
Click Fraud. Website advertising often uses the pay-per-click model in which
advertisers pay websites for each user that clicks on an ad and is redirected to the
advertised website. While the monetary amount paid per user is small (roughly a
few cents per click-through), adversaries have learned how automation can exploit
this through “click fraud.” There are two click fraud variations that an adversary
may employ. The first approach directly benefits the adversary by using an
automated script to simulate clicks on the ad as if it was a legitimate user. Through
this approach, the adversary defrauds advertisers with ads placed on their website
since they collect payment for user click-throughs that did not actually occur.
The second approach is less direct in that an adversary will seek ads from their
competitors. Using a specialized web crawler, the adversary targets competitor ads
with fraudulent clicks in an effort to deplete the competitor’s advertising budget
before many legitimate users see the ads.
Timing-Based Automation
Timing-based automation performs online tasks at the exact moment that
maximizes benefit for the adversary. This may involve coordinating many network
machines or simply executing the protocol more precisely than humanly possible.
Auction Sniping. Adversaries use automation software called an “auction
sniper” to monitor online timed auctions. The software places a winning bid at
the last moment possible (often only seconds before the auction closes) giving
other potential bidders no opportunity to outbid the adversary. This allows the
adversary to purchase the item without engaging in a bidding war with other
interested parties. While not illegal in every jurisdiction or explicitly against rules
laid out by many online auction websites, automated auction sniping is frowned
upon by many users because it cheats sellers out of higher sale prices and means
that goods are not sold for what they are truly worth. This in turn negatively
affects the profits of the service provider as a portion of their revenue is realized
as percentage-based transaction fees for auction sales.
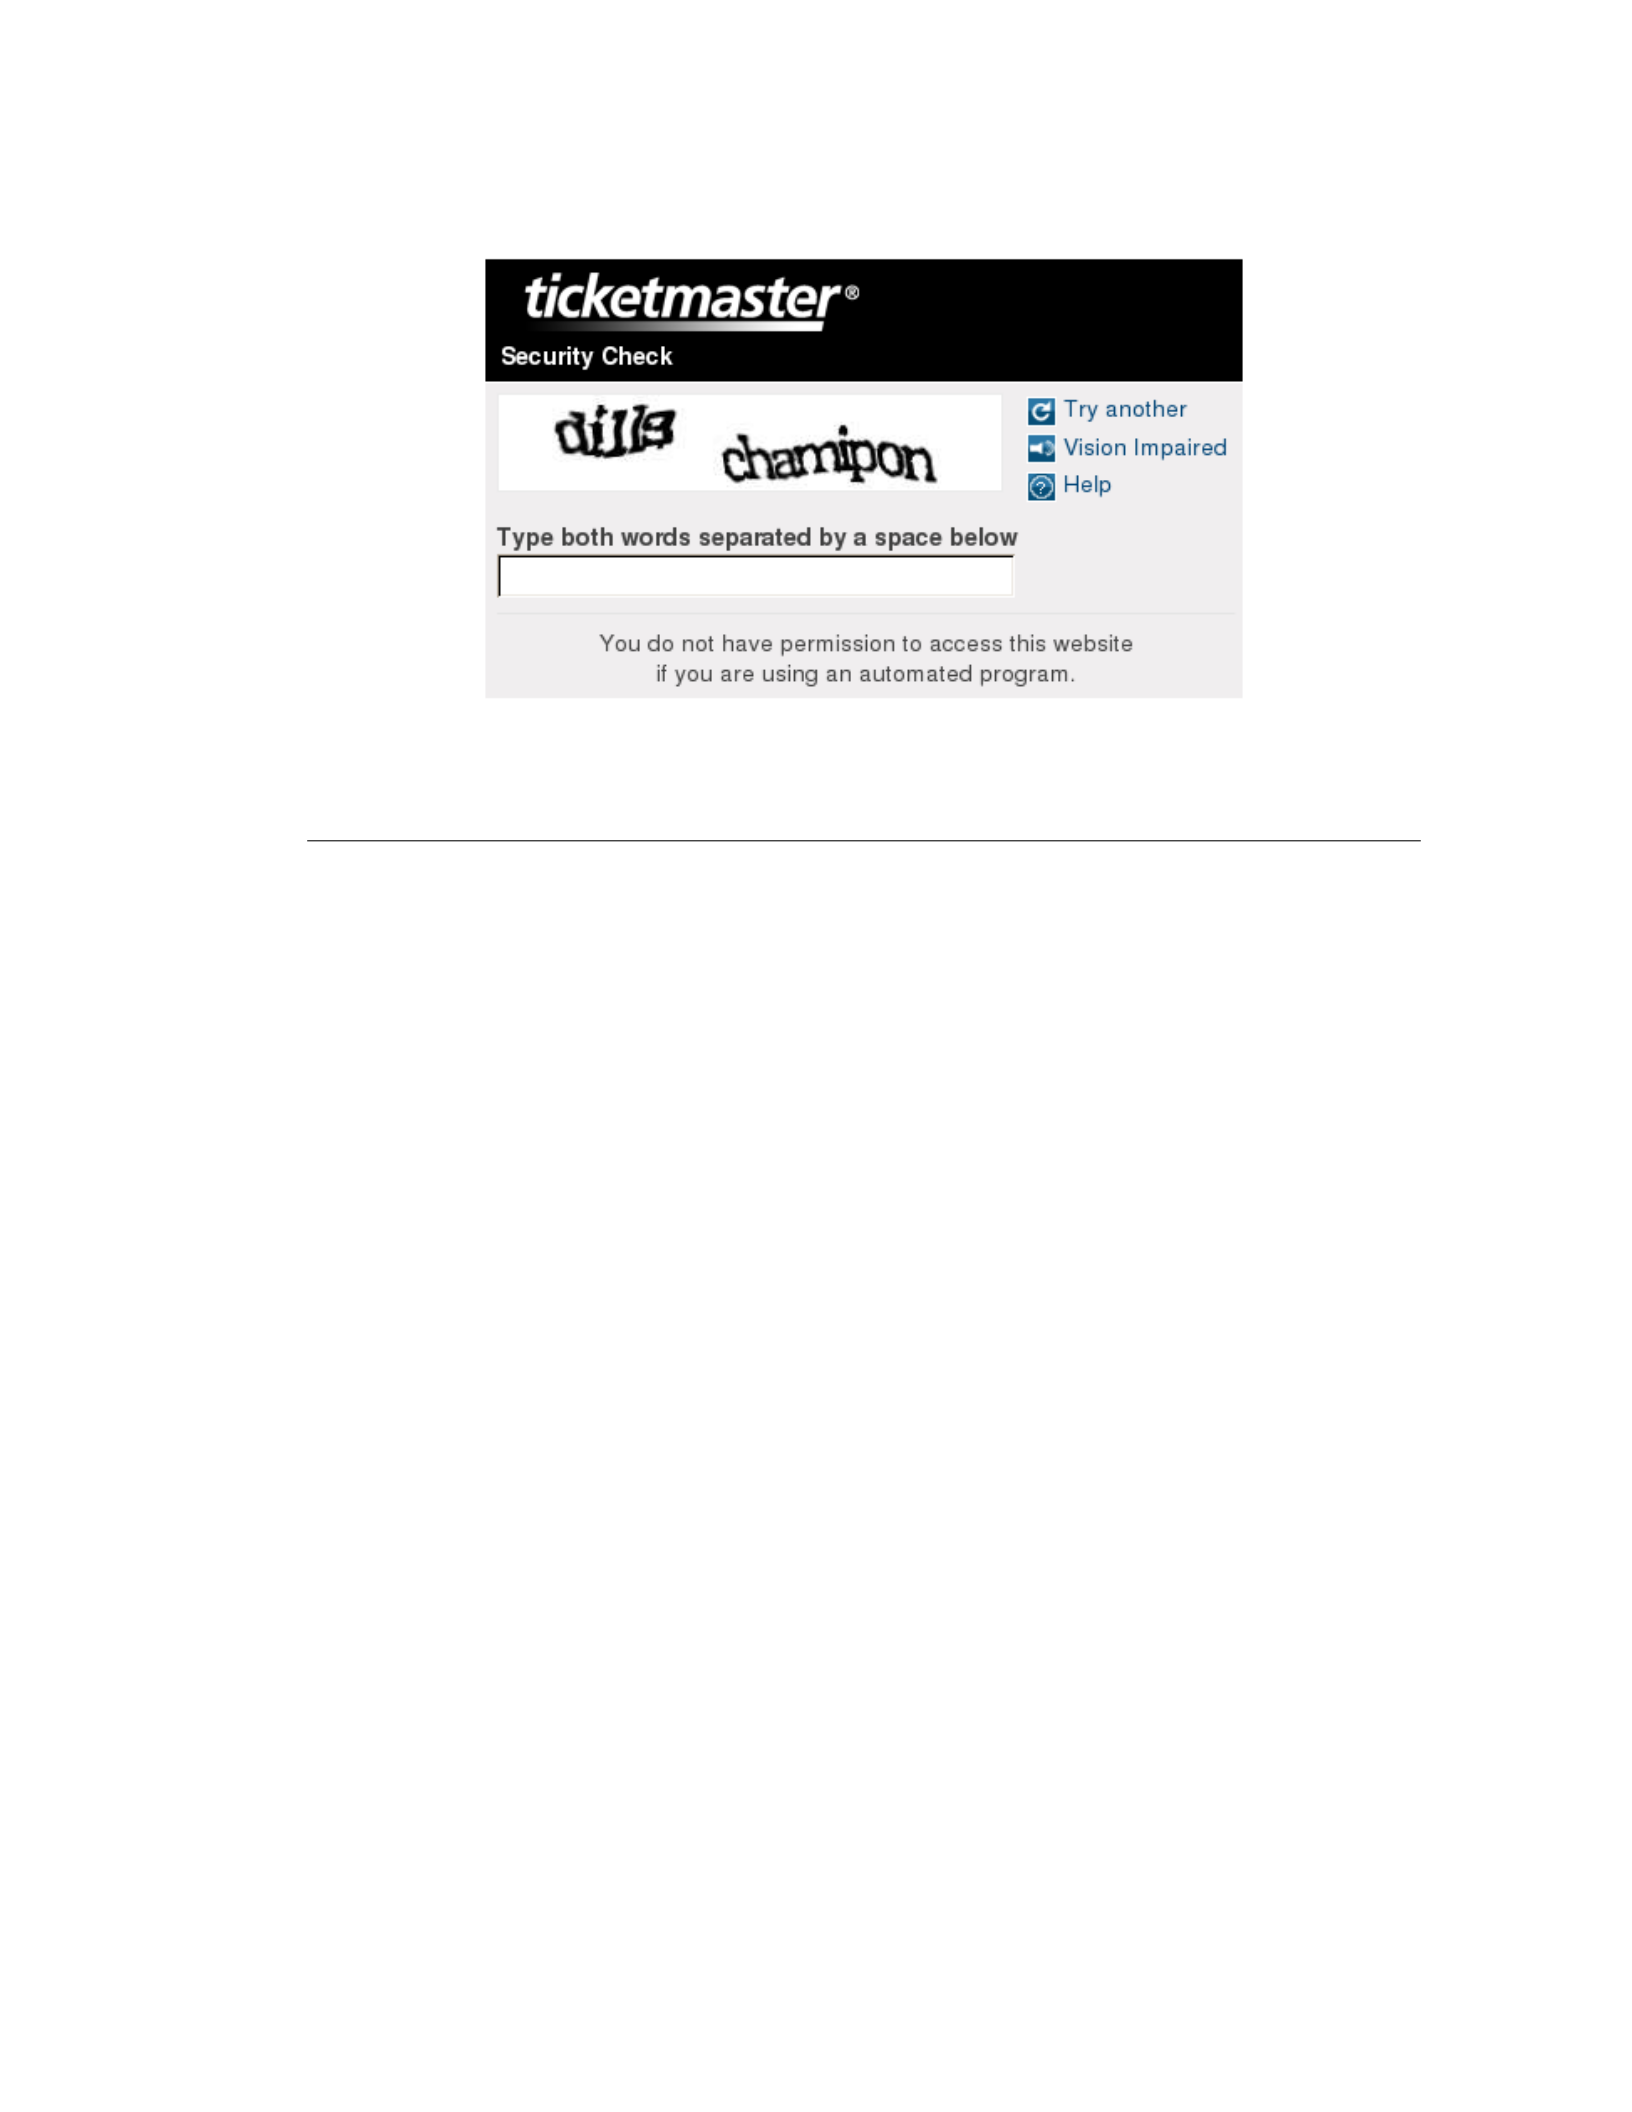
12
Figure 1.4: Example TicketMaster CAPTCHA. This challenge was presented to
a user attempting to purchase event tickets online.
Ticket Bots. When tickets for popular events such as Hannah Montana
concerts go on sale online, they sell out almost instantly. Unfortunately, a
significant number of the tickets are purchased by scalpers looking to turn a quick
profit [110]. The scalpers use world-wide botnets to automate the navigation of the
vendor’s website and engage in transactions to purchase all tickets within minutes
of them becoming available. Many ticket vendors fruitlessly employ CAPTCHAs
(Completely Automated Public Turing tests to tell Computers and Humans
Apart [117]) like the one shown in Figure 1.4 to deter automated adversaries.
Scalpers resort to hybrid human-machine approaches that automates the entire
transaction except for outsourcing the task of CAPTCHA solution to inexpensive
foreign labor willing to solve them quickly and for less than a penny each [43].
While the scalpers turn a quick profit, legitimately interested concertgoers must
pay a higher price for the tickets than they otherwise would have. This increased
price clearly represents revenue that could have been captured by the original ticket
vendor or performers, yet may have been forgone in an effort to make the event
available to a wider audience. Consequently ticket scalpers are not simply “finding
the true market value for the tickets” as they might claim, but instead are directly
undermining the ticket vendor.

13
Precision-Based Automation
Precision-based automation performs application tasks with better precision than
humans could possibly achieve unaided or reveals secret information that allows
humans to interact with the application more precisely than intended by design.
Aim Bots. Some automation scripts called “aim bots” improve a player’s aim
within First Person Shooter (FPS) games. At the extreme end, these bots yield
perfect aim where every shot the player takes is fatal for their opponents. This
becomes frustrating (and easy to observe) for their honest opponents. Aim bots
are considered cheating and their use is strictly against game rules. Rampant
cheating, including the use of aim bots, can destroy the reputation of the game
and dissuade potential players from purchasing the game.
Map & Wall Hacks. Some programs automatically reveal secret game data
to the player which they definitely should not know. For example, “map hacks” are
used by cheaters in Real Time Strategy (RTS) games to reveal the entire layout
of the battlefield and precisely indicate the location and status of opponent units.
In FPS games, “wall hacks” operate similarly by allowing the cheater to see their
opponents through opaque walls. This is not only useful for strategic purposes, but
also allows the cheater to precisely target opponents and subsequently kill them
using powerful weapons that can shoot through walls. Like the aim bot nuisance,
cheaters using map hacks or wall hacks have an unfair competitive advantage over
their opponents, negatively impacting the game adoption and sales.
Poker Odds Bots. Automated programs called poker odds bots reveal the
odds of winning and recommend a course of action to online poker players. These
bots essentially reveal card statistics in a more straightforward fashion than those
shown to their opponents. Using this automation, the adversary gains a precision
advantage which helps them make fewer uncertain actions, thereby giving them
an unfair advantage. This automation is used as the gateway automation to fully
automated bots that play the game and collude to defraud human players.
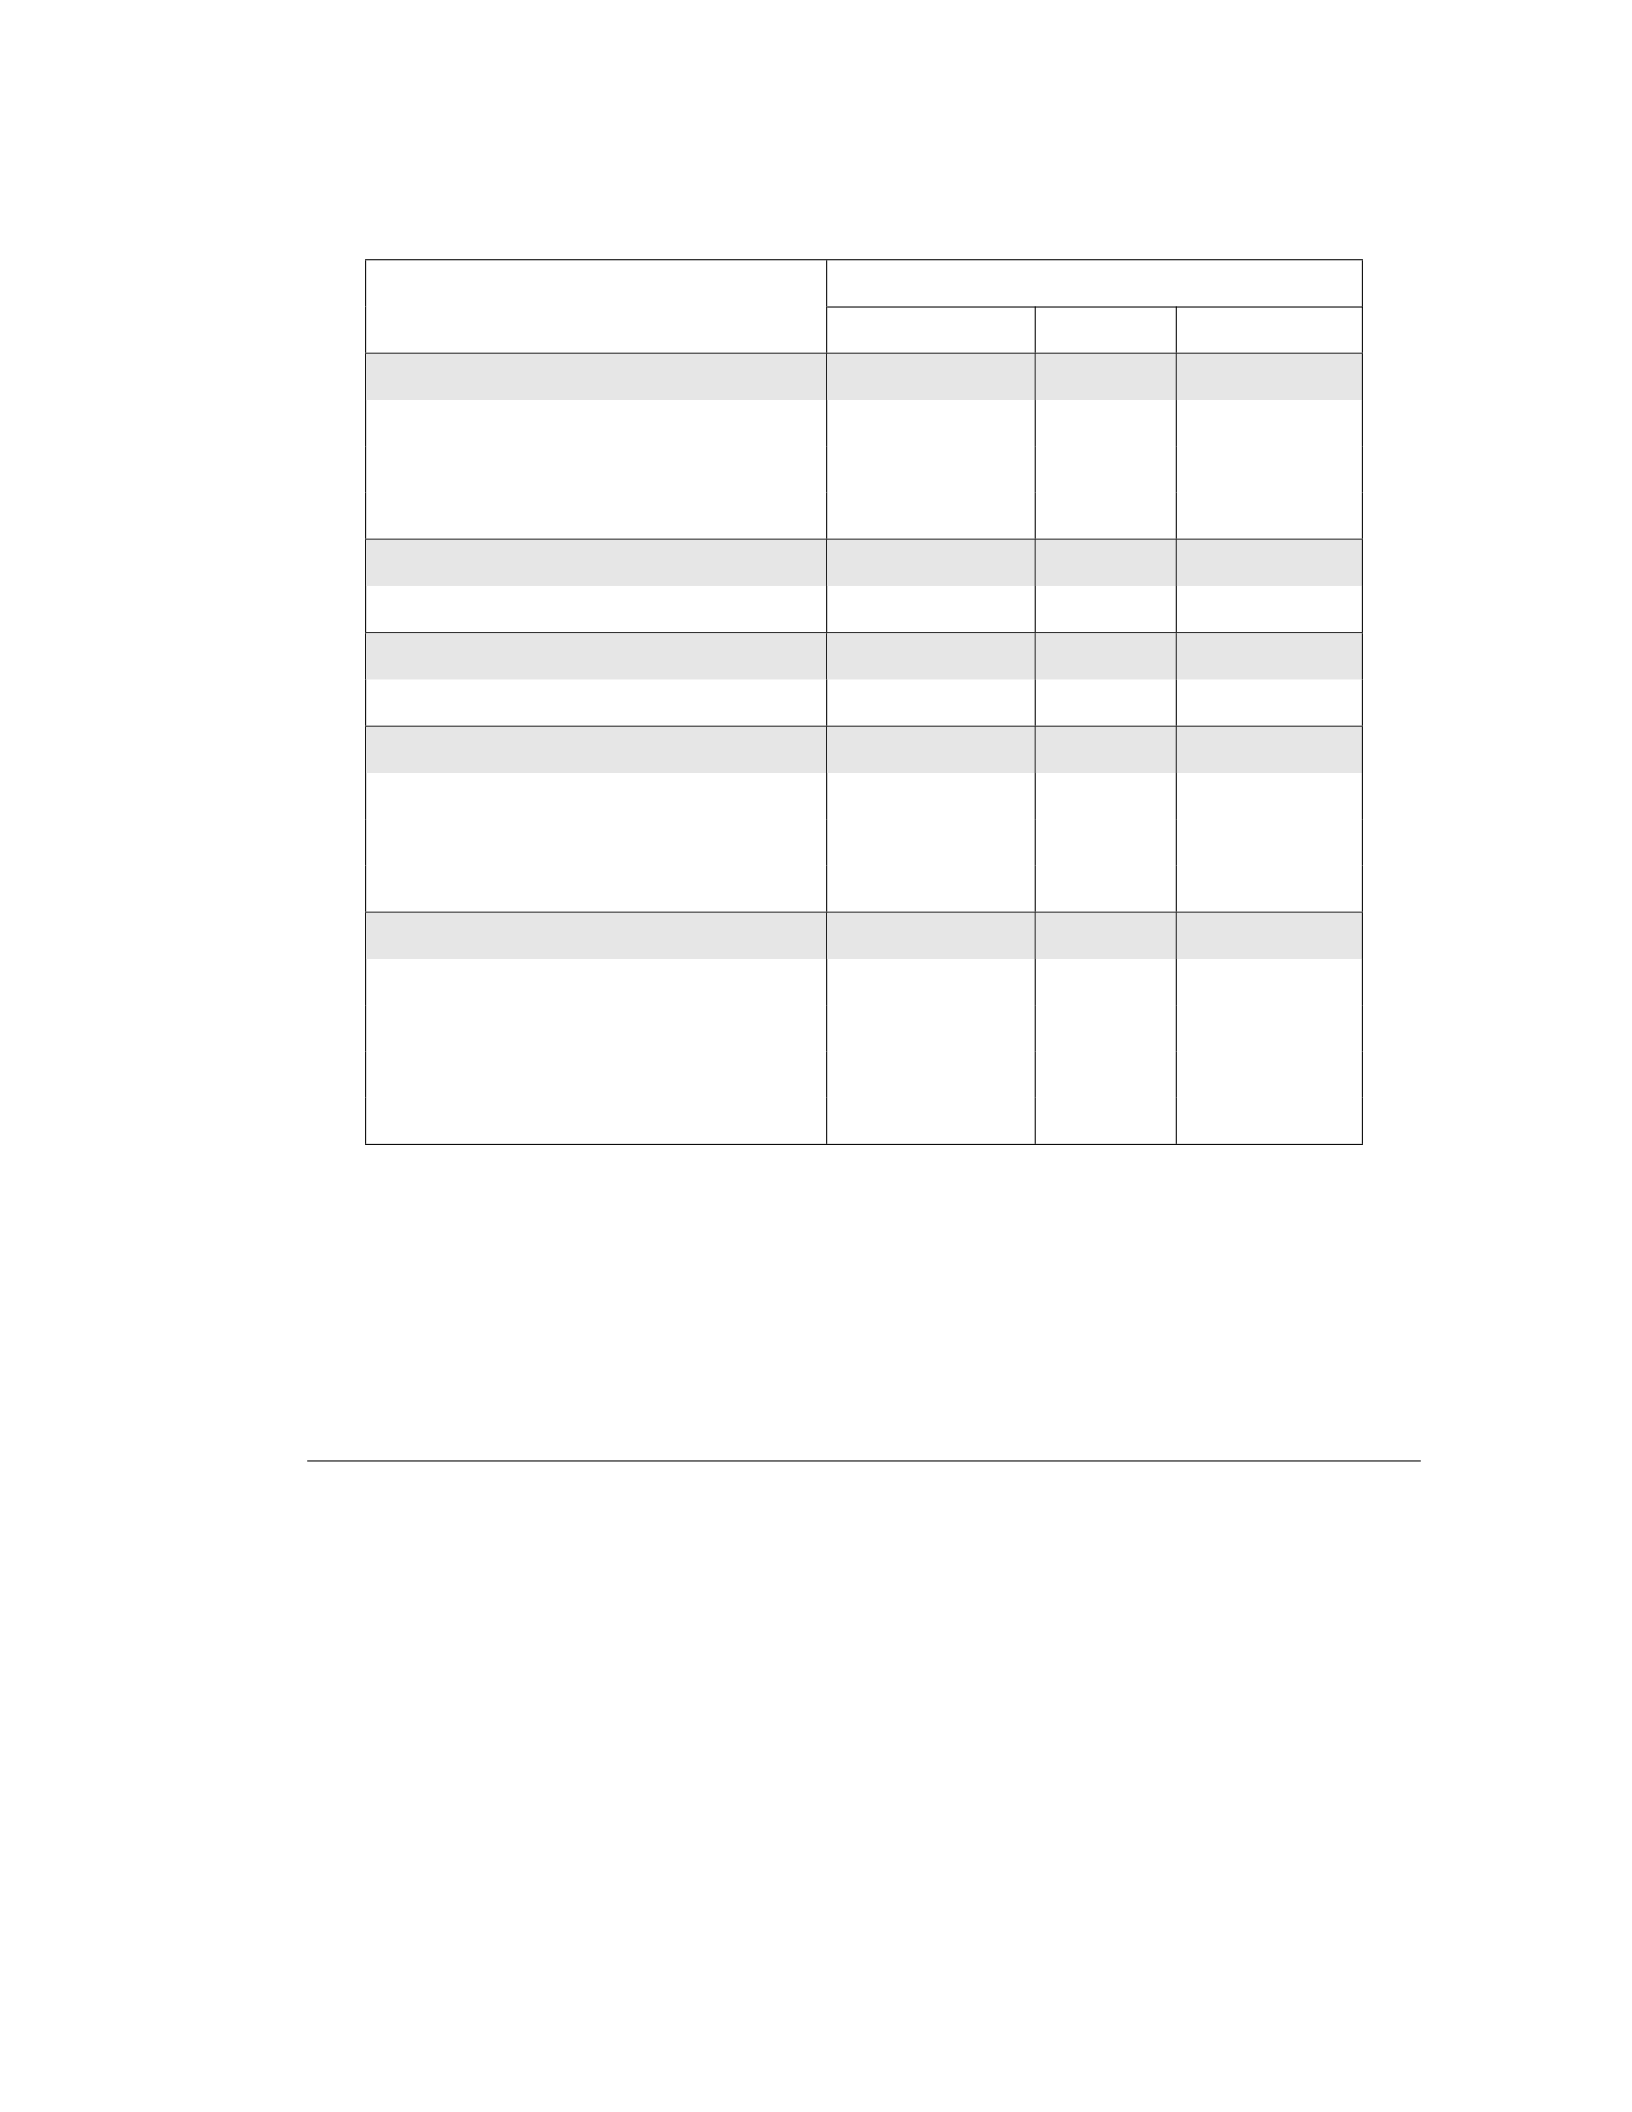
14
Application & Automation Type
Adversarial Approach Repetition Timing Precision
All Network Applications
Port Scans ✓
Network Worms ✓
Denial-of-Service Attacks ✓
Email & Instant Messaging
Spam ✓
World Wide Web
Comment Spam ✓
Online Commerce
Click Fraud ✓
Ticket Bots ✓ ✓
Auction Snipers ✓
Multiplayer Video Games
Leveling & Grinding Bots ✓
Aim Bots ✓
Map & Wall Hacks ✓
Poker Odds Bots ✓
Table 1.1: Summary of adversarial automation examples. The examples are
grouped by the various applications they affect. A few examples attack at the
network protocol level, thus any network application may be vulnerable to such an
automated attack. The remaining automation examples exploit features specific
to the various applications.
Example Summary
Table 1.1 summarizes the automation examples discussed, grouped by the types
of network applications which they affect. Most adversarial automation performs
highly repetitive tasks and, similar to industrial automation, those tasks become
immensely profitable at large scales. Techniques and methods for mitigating
the discussed automation examples are presented through the course of this
dissertation.

15
1.1.2 Root Causes of Adversarial Automation
The End-to-End Principle [97] is a central design principle of the Internet. In
brief, the principle states that network and application protocol features are only
justified at the lower layers of the network system if they optimize network-wide
performance, all other complexity should be in the end hosts. This principle yields
the lightweight and stateless Network Layer (Layer 3 in the OSI model [130])
which has allowed the Internet to become the dynamic patchwork of innovative
applications that it is today. Unfortunately, the resulting properties of the Internet
that make novel network applications possible without reengineering the network
are the very same properties that facilitate adversarial automation. This section
highlights these properties and argues that an application service provider cannot
prevent adversarial automation, only detect and disincentivize it.
No Central Administrative Authority. Since the underlying Internet
network architecture comprises an amalgamation of communication networks
owned by organizations with radically different objectives (e.g., governments,
companies, and academic institutions) there does not exist a single administrative
authority over the entire Internet. Specifically, no one organization can guarantee
that a host’s entry point to the Internet (i.e., one of the many communication
networks) will monitor and police the data packets that it sends. This is
particularly true of packets destined for remote networks due to the phenomenon
known as “hot-potato routing,” a policy where each network forwards packets to
the next nearest network, only performing the minimum amount of routing and
processing required. Furthermore, no one organization can guarantee or mandate
that all network hosts must run anti-virus software or do not run known-malicious
applications. Consequently, the Internet lacks strict host attribution and it is
practically impossible to stop adversarial behavior at its source. This is even
more apparent when considering dynamic IP assignment, where an adversary may
use a new network address each time they connect to the Internet.

16
Unpoliced Internet Architecture. The Internet was designed to
extensibly support new and unpredicted applications. Since applications operate
with different goals, behavior that may be desirable for one application may be
intolerable for another application. Thus, no global definition or consensus exists
to dictate exactly what constitutes adversarial behavior, automated or otherwise.
Insofar as an application’s clients do not interrupt or impede other applications,
defining undesired behavior is left up to the individual service providers. As a
result of the open architecture and the lack of a central administrative authority,
anyone can send any data to any recipient claiming to be any sender and regarding
the inbound data it is largely up to the recipients to deem what is inappropriate.
Uncertainty About Host Automation. Even if communication networks
had the incentive or desire to monitor and filter all communication from hosts
connected to it, since the distinction between wanted and unwanted network
packets is defined by an application service provider at a distant network location
it would be impractical to query for each packet. This means that intermediate
network devices generally cannot know with certainty whether data packets will be
accepted or discarded, or even if the packet results from adversarial automation. To
exacerbate the problem, adversaries do not confess when caught, but instead attack
new victims or adapt their adversarial approach. Furthermore, a network host
may not be malicious in all contexts and they might not even know that they are
malicious in some contexts (consider the case of a user trying to browse a website
while they are unknowingly also running zombie software attacking that same
website). Finally, evidence of prior malicious behavior and correct classification as
an adversary may only be temporarily valid because the network host could reform
(consider the above case after the user discovers and removes the zombie software
running on the machine).
For these three main reasons, adversarial automation cannot be prevented at
the adversary’s network ingress. Instead, each application must learn to detect
and disincentivize adversarial behavior as it applies to that specific application.

17
1.2 RESEARCH CHALLENGES
This dissertation seeks to address adversarial automation. The task of mitigating
adversarial automation presents the following three research challenges:
1.2.1 What methods can be used to detect automated behavior?
Quickly and accurately detecting automated behavior is the fundamental challenge
to thwarting automated adversaries. Since the adversaries outperform humans,
there must exist some characteristic of their operation that allows them to do
so. Distinguishing this characteristic and determining how to detect it is the first
challenge to towards thwarting adversarial automation of that application.
1.2.2 How can detectors be combined to best identify adversaries?
There may be more than one method to detect the adversary, and each of those
detection methods may be individually inconclusive. For any given application,
the service provider may have a number of individually inconclusive detectors at
their disposal. The next challenge involves how to best combine them to create
a single metric with a more conclusive result. Specifically, what is sought is a
single value that ranges from “not adversarial” to “adversarial” (i.e., a probability
∈[0.0,1.0]) to describe each client. This prediction value must be calculable in
an accurate and efficient manner.
1.2.3 How can adversarial automation best be disincentivized?
Provided prediction values regarding adversarial automation, the service provider
may leverage this knowledge to discourage such behaviors. Specifically, the
challenge is how to disincentivize automated behavior so that adversaries behave
indistinguishably from and thus have no advantage over non-automated human
peers. Of particular interest are mitigation approaches that gracefully handle cases
where the prediction value is gaining certainty but is not yet conclusive.

18
1.3 DISSERTATION OUTLINE
This dissertation explores the outlined challenges using research on two popular
networked applications where the service provider has varying access to the client:
multiplayer online video games and web-based services. In multiplayer online video
games, the game’s service provider (hereon referred to as the “game developer”)
implements and releases the only client software that is authorized to interact with
the server software. This means the game developer has firm control over what all
legitimate client operation looks like.
In contrast, web-based services operate over the HyperText Transfer Protocol
(HTTP) [40] which simply dictates request and response formats. Any web browser
that adheres to the HTTP protocol can therefore access the service. Behavior
outside of the protocol (e.g., how frequently to request data or what to do with it)
is browser-dependent and varies amongst browser implementations and browser-
addons. As such, a web service provider has little control over exactly what
legitimate client operation looks like.
This dissertation is divided into chapters focusing on each of the three research
challenges. Chapter 2 investigates the detection of adversarial automation that
manifests itself as cheating in online multiplayer video games. In this application,
banning adversary accounts is a proven, effective, automation disincentive since
the adversary loses their software purchase as well as the subscription fees and
time invested up to that point. However, existing detection approaches are error-
prone, inefficient, non-automated, and expensive to maintain. Exploiting the game
developer’s direct access to the game client, we explore a novel approach to video
game cheat detection: anomaly-based detection. In this approach, the application
automatically learns how the client operates on different machines through partial
client emulation. Using continued, random, and remote audits, the server validates
client execution and flags unexpected execution as possible cheat behavior. The
evaluation of this research focuses on detection accuracy and integrity.

19
Chapter 3 investigates the combination of individual detectors to create a
predictor likely to produce a conclusive result. Specifically, the chapter looks at
reducing a set of heterogeneous detectors within multiplayer online video games
to establish a metric for identifying malicious, automated players. This research
is realized as a novel reputation system for multiplayer online games. Treating a
player’s peers as detectors (i.e., each peer’s observations provide clues regarding
the maliciousness of other peers), the disincentive simply follows: players will avoid
known malicious peers, peers who will at the same time garner unwanted scrutiny
from the game developer. The reputation system is designed to minimize need for
direct access to the game client to enforce trustworthy operation. The evaluation
of this research explores both its efficiency and collusion resistance, properties
necessary for combining largely untrusted detectors. Experiment results indicate
that this approach may be applicable to the web-based applications, like those
discussed in the next chapter.
Chapter 4 investigates the use of proof-of-work to disincentivize automated
adversaries of web-based applications. In this setting, service providers have no
access to monitor the operation of client software so they must rely upon detectors
completely external to the client software. Given an established accurate predictor
regarding the probability a client is automated, we show that service providers
can wield proof-of-work challenges to quickly thwart adversaries. The proof-of-
work paradigm requires clients to solve computational puzzles which are scaled
in difficulty proportionally to the adversarial metric. More adversarial clients are
given very difficult puzzles to solve, while less adversarial clients are given trivial
puzzles to solve. This approach disincentivizes automated adversarial behaviors
by computationally taxing them. The evaluation of this research explores the
effectiveness of the approach in isolating automated adversaries.
Chapter 5 reviews the contributions of this dissertation and summarizes some
of the key findings of this research.

20
1.3.1 Thesis Statement
The research discussed throughout this dissertation is guided by the following
thesis statement:
There exist methods to detect automated behaviors with which an
application’s service provider can identify and disincentivize automated
adversaries.

21
Chapter 2
DETECTION METHODS
2.1 INTRODUCTION
The fundamental challenge to thwarting automated adversaries is to quickly and
accurately detect their automated behavior. Towards this goal, this chapter
explores the problem of cheating in multiplayer online games. Multiplayer online
games serve as the ideal application for research focused on developing methods
to detect adversarial automation. In this application, a well established and
proven disincentive already exists: adversaries are banned, forfeiting their software
purchase as well as the subscription fees and time they have invested up to
that point. Given such an effective disincentive, the only challenge to defeating
automation plaguing multiplayer online games is accurate detection.
Unfortunately, existing cheat detection approaches [31, 76, 115] are error
prone, inefficient, and expensive to maintain. These approaches require the game
developer to identify, obtain, catalog, and then continuously search for cheat
software operating on the client machine. In addition to the above shortcomings,
those approaches are completely incapable of detecting cheats which the developer
cannot obtain and catalog.
Since the game developer has a thorough understanding of the game client
software, it follows that the developer could instead focus detection efforts on
abnormal client execution. In this chapter, we show that such an approach is both
more efficient and accurate, and able to detect cheats which the developer cannot
easily catalogue. Throughout the chapter, we refer to the adversary as a “cheater”
and the service provider as a “game developer” or “developer.”

22
2.2 THE CHEATING PROBLEM
Multiplayer online games simulate complex virtual environments. Due to the
expense of server computation resources as well as the player’s sensitivity to
network latency, games are designed to offload as much computation as possible to
the game client. That client software is expected to run accurately and keep secret
game state hidden from the player. Cheat software violates this trust by altering
the simulation locally to give the cheater an unfair advantage (e.g., perfect aim,
X-ray vision, or teleportation).
While the motives vary from game to game, cheating has become widespread.
Many underground communities write and sell cheats ranging from automated
bots that treasure hunt virtual items, level up characters, and attain ranks for
cheaters unwilling to play the game, to cheats that provide perfect aim and reveal
secret knowledge for cheaters unable to win unaided. Studies have shown that
such automated bots behave in a repetitious fashion consuming a disproportionate
amount of the costly server computation resources [17]. Furthermore, legitimate
players are frustrated by cheaters to the point where they seek other games that
are more robust to cheating. Since losing existing and potential paying players
directly impacts revenue, developers have a second powerful incentive to thwart
automated cheating in their games.
2.2.1 A Distinct Security Problem
Cheaters have one clear advantage over developers – they control the machines on
which they cheat. This means that the cheater can grant the cheat software all
the necessary privileges and may run it before anti-cheat software is ever loaded.
State-of-the-art cheats conceal their presence by modifying the operating system,
disabling or spoofing anti-cheat software, and even cloaking their code just before
routine anti-cheat software runs. Fortunately, cheats are a weak threat compared
to other security problems like rootkits, botnets, and worms.

23
First, most cheats embed themselves within the game process to easily access
game data and functionality and this drastically limits their ability to conceal their
presence, let alone remain hidden indefinitely. For these reasons, game developers
can focus their efforts on a small search space yet detect a majority of cheaters.
Second, at the level of individual cheaters, the problem is not urgent. The
problem only becomes catastrophic for game developers if cheating becomes
widespread or is believed by most players to be largely unaddressed. As a result,
there is no need for rigorous cheat prevention or immediate containment; sensitive
information (such as passwords and personal information) is not being stolen and
the machine is not being used to attack other network hosts.
Third, cheating damage is easily undone once discovered. By confiscating a
cheater’s ill-gotten gains and disabling their account, the cheater can no longer
affect legitimate gameplay. The full extent of cheating damage is easily determined
since game developers keep transactional logs regarding persistent virtual world
state (character levels, wealth, and win-loss records) so cleanup is comprehensive.
Since disabling the cheater’s account annuls all invested time and confiscates both
the software purchase and paid subscription fees, cleanup directly punishes the
cheater. To an automation-based adversary of networked applications, this is an
uncommon, severe consequence for being detected.
Finally, due to the long-term connected nature of online games, the server has
many lengthy client interactions during which the cheater need only be detected
once to halt their disruption. Reversing an adversary’s traditional advantage, the
cheater must anticipate and guard against every detection technique to succeed while
the developer need only detect a single unauthorized change to thwart them. With
no need for urgency, being able to eventually detect the cheater is sufficient to
address the cheating problem, which is supported by the widespread use of cheat
detection. The next section discusses the various methods which cheaters employ
to modify and automate the game client.
24
2.2.2 Cheating Methods
To further understand the cheating problem, it is important to survey the methods
that are currently being used by adversaries to cheat1. At present, most computer-
based video games (and hence most cheats) are implemented for the Windows
operating system. The cheat techniques described in this section are illustrated
using Windows functions, however, the methods are general and apply to other
operating systems. In practice, the methods presented are typically used in
conjunction with each other to implement cheat software.
Authorized, Automated Data Read
This method automates the collection of information that is presented and available
to the cheater. Such cheats typically use legitimate APIs to learn game data
without directly interacting with the game process. Because the APIs serve
legitimate purposes (mostly for accessibility), their abuse is difficult to detect.
Using the Graphics Device Interface (specifically BitBlt() and GetPixel())
to dump pixel information from the screen and discern game state.
This method is used by bots that automate actions, like FishBuddy for World of
Warcraft which automates the casting, hooking, and storing of virtual fish.
Unauthorized Data Read
This method, also known as “information exposure,” accesses hidden game data
that should not be revealed to the player. Specific techniques include:
Using a packet sniffer to extract game data from unencrypted network traffic.
Using APIs (such as ReadProcessMemory()) to remotely read game memory.
Using a thread within the game process to access game data.
1This research appeared as a survey in NetGames 2008 [38].
25
Cheats that employ this method include map-hacks that reveal the location of
enemy units behind the “fog of war” in Warcraft III, wall-hacks that reveal the
exact locations of enemy players behind walls in Counter-Strike, and Kick-Ass Map
that reveals mob locations beyond the player’s view in World of Warcraft.
Unauthorized Data Write
One of the simplest methods to alter game behavior is to directly modify data
within the game process. By changing the data that the game uses, cheaters can
gain abilities that their opponents cannot. Techniques for performing unauthorized
data writes include:
Using APIs (like WriteProcessMemory()) to remotely rewrite game data.
Using a thread within the game process to modify game data.
Cheats that use static data writes include modifying the gravity constant so
that cheaters can climb walls in World of Warcraft and modifying memory-mapped
wall textures to make them transparent in Counter-Strike. While these examples
are extremely easy to detect since they modify data to invalid values for the
duration of the cheat, other cheats dynamically toggle data between valid values
in an illegitimate way. For example, a cheat for Battlefield 2 continuously changes
the team the cheater is on in order to trick the game client into revealing enemy
locations via the radar.
Cheat Engine [18] is a tool that uses this method to locate and dynamically
modify game data. In particular, it modifies the cheater’s coordinates and direction
to implement teleport cheats, Z-hack cheats (where the cheater is kept a fixed
distance from the opponent during battle), and direction cheats (where the cheater
is made to face the opponent at all times). Cheat Engine is also used to illegally
modify a character’s attributes such as experience or health level.
26
Code Injection
Many cheats change the operation of the game by altering the game code or running
their own code within the game process. To achieve this, cheaters can inject their
code into the process during the loading of the game or from an external process
while the game is running. There are a myriad of ways that code can be injected
including:
Using WriteProcessMemory() to hotpatch (i.e., overwrite) game code to
implement new functionality or make particular game operations always or
never happen. For example, one can disable flash grenade blinding effects
in Counter-Strike by changing jump instructions that call the flash effect
into NOPs. Hotpatching is feasible if the changes can be done within the size
constraints of the original function.
Using WriteProcessMemory() to write to code-caves, pockets of allocated
but unused memory between existing game functions. The use of code-caves
provides some stealth if the anti-cheat only scans the game’s original code
locations.
Allocating new memory using VirtualAllocEx() and writing to it using
WriteProcessMemory(). This is not stealthy, but it facilitates injecting an
arbitrary amount of cheat code into the game process.
Loading a Dynamic Link Library (DLL) containing the cheat payload by
either using LoadLibrary(), by hooking LoadLibrary() as it is called for
other game DLLs, or by modifying registry entries such as AppInit DLL
to have the payload DLL loaded automatically with the game. Tools that
support this technique include Winject and INJLIB.
Cheats that inject code are prevalent and include aiming automation tools
like BlackOmega [11] for Battlefield 2, Ecstatic [30] for Counter-Strike, and
HL2 Hook [48] for Half-Life 2.
27
Thread Manipulation
Once cheat code is injected into the game, it must be executed. The most common
techniques involve manipulating threads within the game process by:
Using detours (or trampolines) to temporarily hijack an existing game
thread [53]. The detour redirects game function calls to injected cheat
code by hotpatching a handful of bytes at the beginning of game functions.
The overwritten bytes include a jump instruction that points to previously
injected cheat code. Depending on the intention, some detours will execute
part or all of the game function after executing the cheat code.
Injecting a new thread via CreateRemoteThread() to execute cheat code
alongside the game’s normally operating threads.
Direct Function Calls
Many cheats change the operation of the game by directly calling operating system
or game functions as needed for the desired behavior. This is especially true for
automation bots which take input from authorized or unauthorized reads, make
decisions, and then directly call game code to take action. Techniques include:
Using I/O APIs (keybd event() or mouse event()) to directly generate
game input signals which would otherwise be sent by the keyboard/mouse
interrupt handler.
Using an injected or hijacked thread to directly call functions from within
the game process.
The use of direct function calls is prevalent in bots and is a key component of
Hoglund’s World of Warcraft Implant bot [52].
28
Function Pointer Hooks
Similar to detours, cheats may modify function pointers in the game or operating
system in order to redirect execution to cheat code. Function pointers are prevalent
in any running process whether it is within the game’s code, the libraries it uses,
or the operating system. By overwriting function pointers in order to execute
injected cheat code rather than modifying the functions themselves, this method
passes integrity checks that only examine the game’s code. Techniques include:
Return address hooks that modify pointers stored in the stack so that
functions return to injected code rather than their caller. This technique
is the basis for return-to-libc attacks [106].
Overwriting function pointers in game code that implement run-time binding
of operations or jump table implementations of switch statements in C/C++.
Import Address Table (IAT) hooks that replace the game process’ table of
function pointers for functions exported by loaded DLLs such as DirectX,
DirectInput, WinSock, or kernel DLLs.
Hooks that replace entries in system tables such as the Interrupt Descriptor
Table (IDT), the System Service Dispatch Table (SSDT), or the I/O Request
Packet (IRP) Function Table.
Structured Exception Handler (SEH) hooks that replace exception handler
pointers on the stack with addresses for cheat code.
Using the Windows API to hook message handlers across all running
processes via SetWindowsHookEx().
Function pointer hooks are prevalent in bots across all game genres such as
HL2Hook/CSHook and speed hacks implemented using Cheat Engine [18].
29
External Processes
In this method, the cheater employs an external process that modifies or tampers
with the game process. Instances of this method include:
Using previously described operating system APIs to access and tamper with
the game process such as ReadProcessMemory(),WriteProcessMemory(),
CreateRemoteThread(), and VirtualAllocEx().
Sending Windows messages such as mouse and keyboard events to the
game process via APIs like SendMessage(). For example, in first-person
shooters, automated events are sent in order to perform recoil suppression
(e.g., WM MOUSEMOVE).
Using DebugActiveProcess() to attach to the game process as a debugger
and completely control its execution. This technique can be used to either
change the game code itself or to hijack game process threads to load cheat
code from libraries.
Examples include recoil suppression cheats in first-person shooters that inject
mouse events from a remote process and any cheats that use the debugger interface
to gain control of the game process.
File Replacement
In this method, the cheater modifies the game binary, the game’s data files, the
libraries the game uses, or kernel modules on disk before they are loaded. While
this method has been used in the past, file integrity checks by anti-cheat software
have rendered this less popular. Specific examples include wall hacks in first-person
shooters that replace game texture files with transparent alternatives.
30
Hardware Facilities
Due to the difficulty in correctly measuring hardware state from software, some
cheats like Cheat Engine and Hoglund’s Governor exploit hardware features. The
following methods are specific to Intel processors but are applicable to other
processors.
Cheats may tamper with the Interrupt Descriptor Table Register (IDTR)
of the CPU which stores a pointer to where the Interrupt Descriptor Table
(IDT) resides. This leaves the original table intact yet points to a completely
different table containing pointers to cheat code.
Processors typically support hardware debug registers that stop execution
and cause an exception to occur whenever particular code locations are
reached or when particular memory locations are accessed. By using this
facility, cheat software can hijack game execution without explicitly injecting
debugger interrupt instructions into the original game code.
To access game memory, cheats can tamper with the memory management
subsystem of a processor including its control and segment registers. For
example, tampering with IA-32 control registers (CR0-CR3) allows a cheat
to modify read-only pages or hide memory pages where cheat code resides.
Model Specific Registers (MSRs) can also be used to tamper with the game
and operating system in a variety of ways. One specific example is the
SYSENTER EIP MSR register on IA-32 CPUs that holds the address of the
“fast” system call function. By modifying this register, a cheat can hook
essential system calls underneath a game.
Another stealthy method is to have the game run virtualized and implement
the cheat into the virtual machine or hypervisor. With hardware support for
virtualization, such an approach can make detection extremely difficult [131].
31
ControllerAuditor
Game
Client
Game
Server
Player
Account
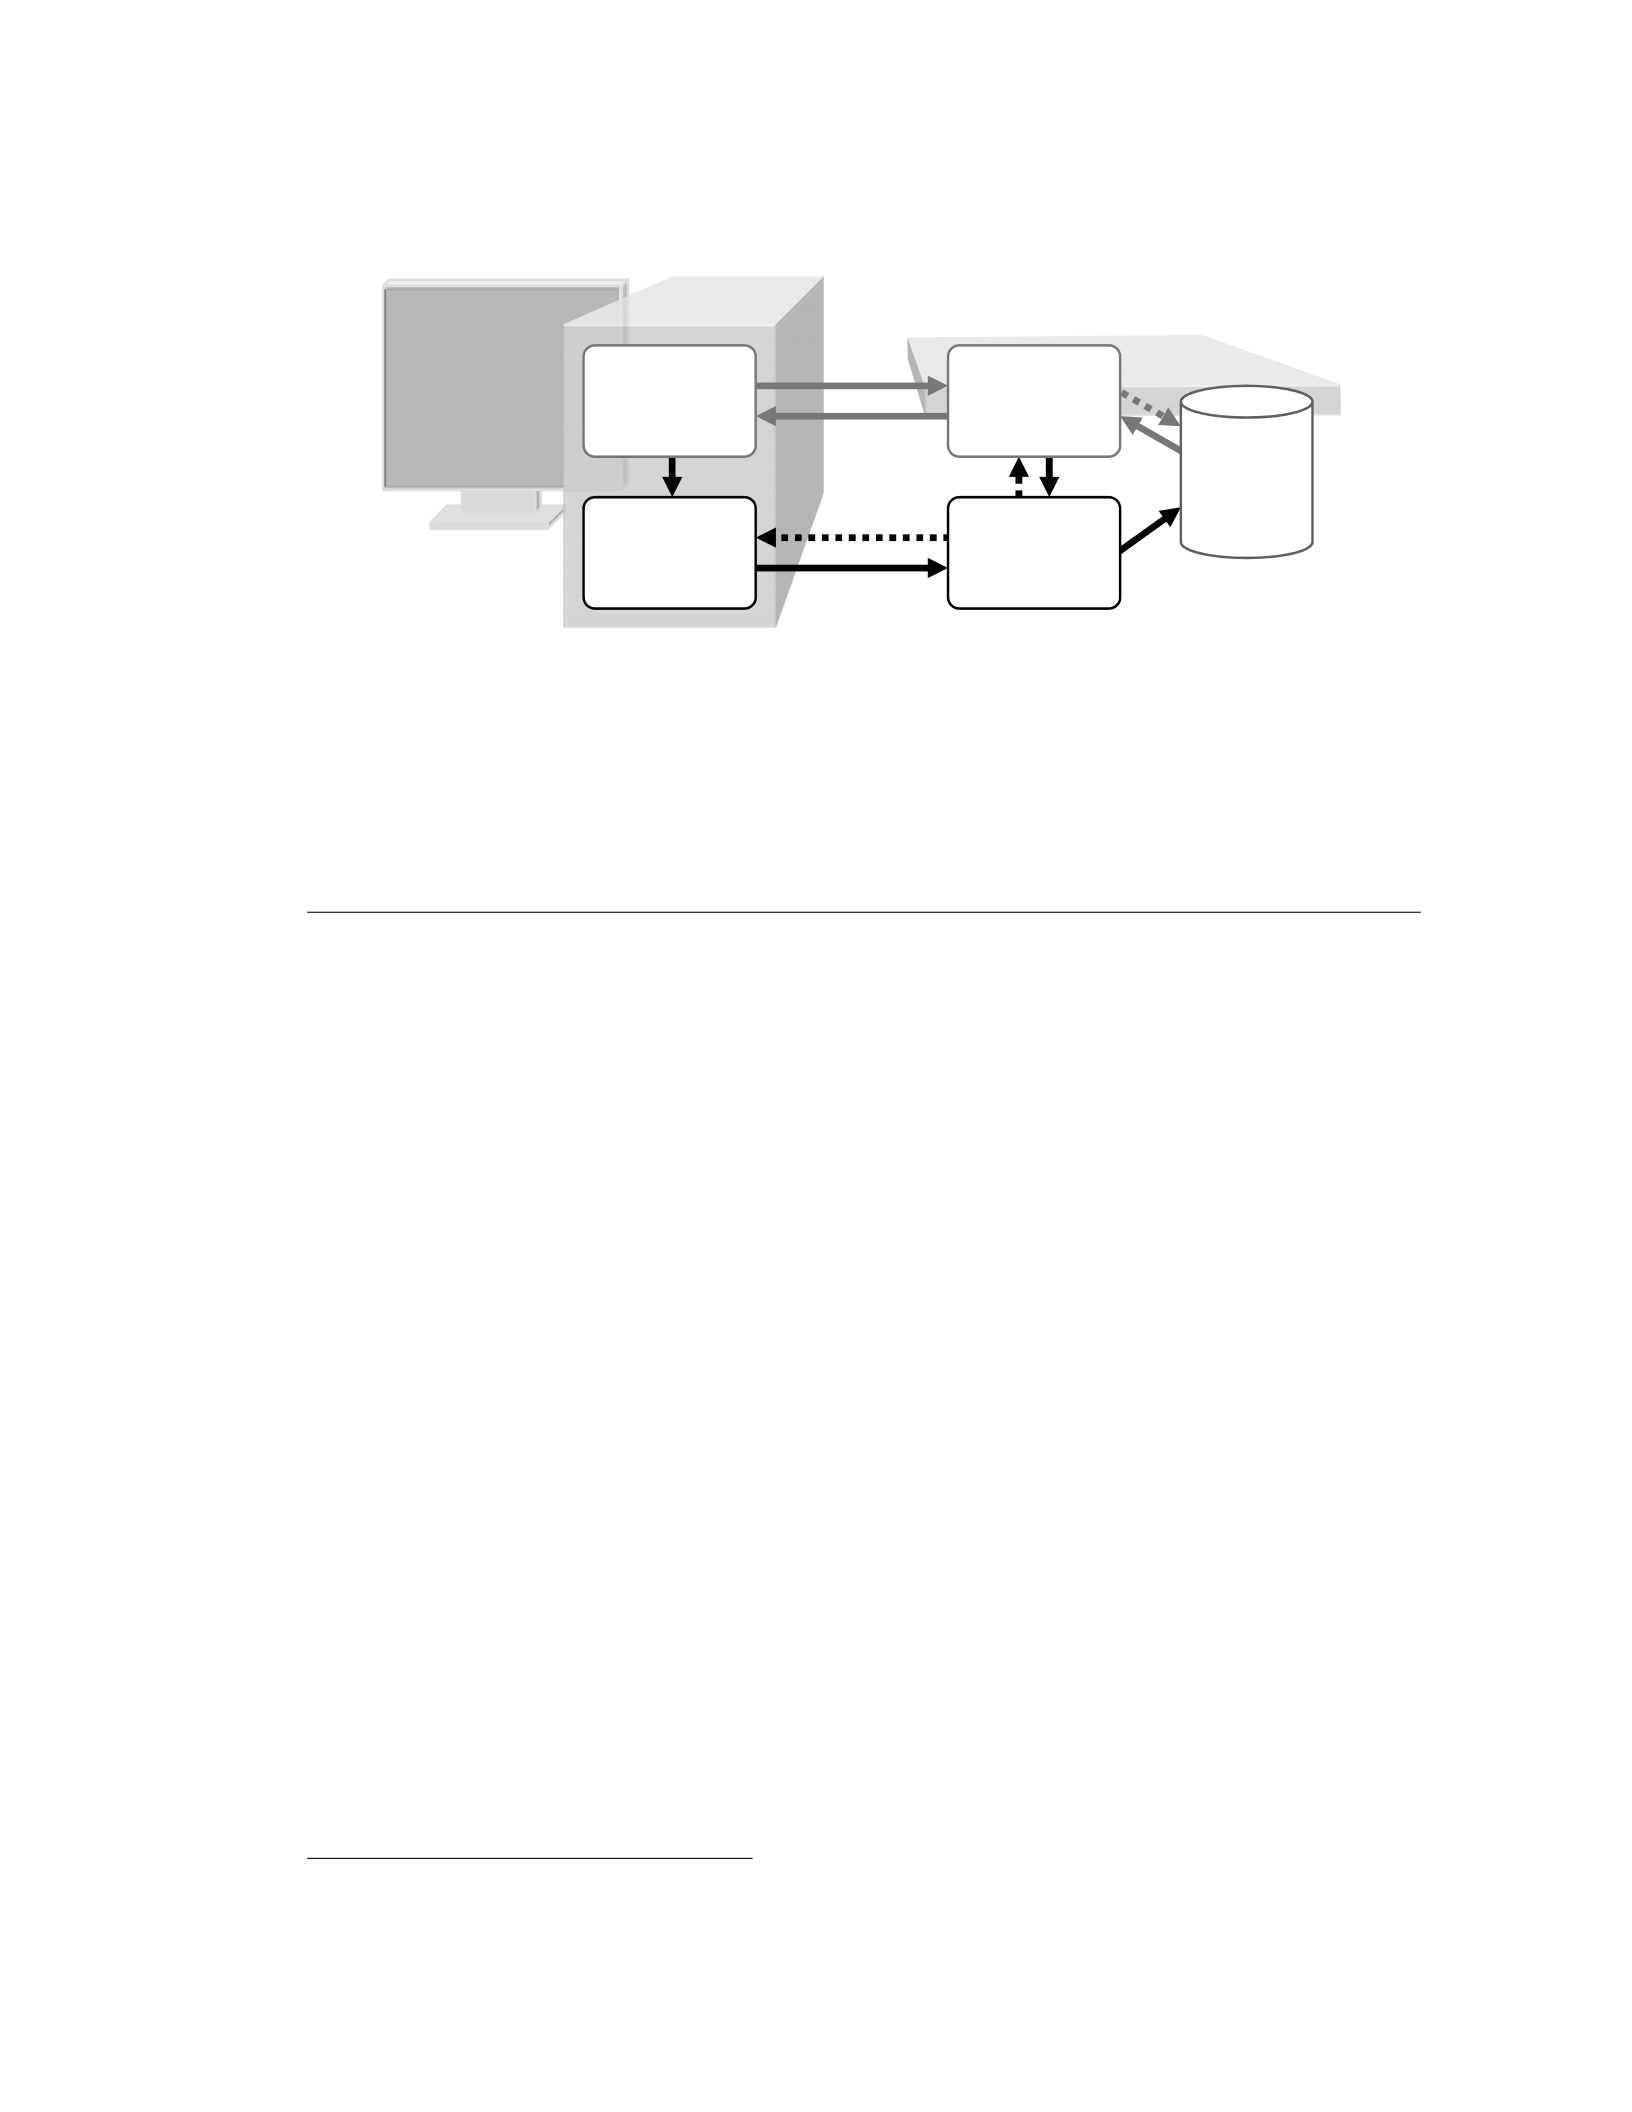
Figure 2.1: Addition of Fides to the client-server game architecture. Interaction
between the game and the Fides Auditor and Controller is shown: dashed arrows
represent request traffic while solid ones represent data flow. Any detected cheating
is recorded to the player account so that the developer can respond appropriately.
2.3 THE FIDES APPROACH
Our approach for cheat detection is the Fides approach2,3which, to our knowledge,
is the first anomaly-based software-integrity detection approach in the literature
that is useable on commercial-off-the-shelf online games. The Fides system (shown
in Figure 2.1) dovetails with prevalent client-server game architectures to minimize
the modifications necessary while efficiently detecting cheats that directly modify
game clients. Cheats completely external to the game process (e.g., cheating
through collusion or mechanical “roboting”) is not addressed by this approach.
Fides is a generalized cheat detection approach that is game-independent; the
approach works across games, game genres, operating systems, and hardware
architectures. Fides adapts anomaly-based application integrity research to the
game domain, thereby avoiding the detractions of existing approaches. Specifically,
Fides does not require human intensive maintenance and can quickly detect cheats
without first knowing their operational minutia.
2Fides was the goddess of trust in Roman mythology.
3This research appeared in a paper at ACM CCS 2009 [67].

32
Anomaly-Based Cheat Detection. There are two possible cheat detection
approaches: signature-based detection and anomaly-based detection. Signature-
based detection learns what cheats look like and actively searches for these patterns
while the game is running – scanning not only the game but every active process
on the system. Anti-spyware advocates observe that this maintenance-heavy
methodology is the current choice of game developers [51], likely because it can be
implemented after game release.
In contrast, anomaly-based detection learns how the legitimate unmodified
game client operates and periodically audits it, searching for unexpected deviations
that indicate the presence of cheat software. This detection approach only inspects
the client process which is feasible since most cheats embed themselves in the client
process rather than manifest as an external process. As a result the search space
is well bounded and other processes running concurrently affect neither the speed
nor the accuracy of this methodology.
Restricting the search space to the game process yields security benefits too.
Foremost there is no risk of privacy breach [76]; sensitive data that exists in
unrelated software processes is not read and cannot be leaked. Additionally,
adversaries cannot exploit the scanning of unfamiliar processes by injecting false
positives. This avoids attacks similar to the case in which a message containing
the binary pattern of a cheat signature was broadcast to an IRC channel belonging
to a prominent game clan, was falsely detected by signature-based detection
(Punkbuster [31]), and caused 300 legitimate players to be incorrectly banned [85].
Anomaly-based detection is cheat-independent and requires fewer developer
resources (i.e., manpower and storage) to maintain since the game is readily
accessible for study by its own developers. Cheats do not need to be captured
and studied to create signatures as only knowledge about the game is used. The
perpetually increasing collection of cheats, cheat variations, and polymorphic
cheats does not inflate the knowledgebase which only changes when the game
software is updated (i.e., patched).

33
Furthermore, anomaly-based detection is not reactionary. Signature-based
detection relies on manually finding cheats and cataloging their signatures which
causes a lag between when a cheat is first used and when its signature can first be
detected. This lag is often artificially increased by the developer to avoid tipping
off cheaters as to when and how they were caught. Legitimate players, however,
may perceive that personally observed cheating behavior goes unpunished.
For anomaly-based detection to work properly, all host variation that affects
the game client (i.e., library versions and their memory locations) must be
accommodated to ensure that all legitimate game operation is recognized and
not misclassified as cheat behavior. With such accommodations, anomaly-based
detection is advantageous in terms of efficiency, maintenance costs, and accuracy.
Continued Random Remote Measurement. A novel Fides feature is
that it performs continued random remote measurements of the game client during
gameplay. The system comprises a simple client-side Auditor that is directed by a
robust server-side Controller. The Auditor supports a selection of parameterized
functions to measure client state and return the results to the Controller. The
system complexity is located in the Controller which dictates the audit strategy
(i.e., what gets measured as well as when) and validates all measurements taken.
This continued sampling approach reduces client-side overhead.
Minimizing the Auditor’s complexity facilitates strengthening it against attack.
The use of techniques like execution entanglement, rapid polymorphism, and
lightweight tamper-resistant coprocessors can provide stronger assurances about
the Auditor’s integrity and measurement accuracy.
Additionally, employing a partially randomized strategy and placing it in
the Controller avoids telegraphing audits and allows the developer to change
strategy surreptitiously. The “fear of the unknown,” specifically not knowing
when cheat techniques believed to be detection-proof become obsolete, has been
an effective deterrent for would-be cheaters [52]. Continued random measurements
will eventually detect a persistent cheater due to the always-on nature of the game.

34
Partial Client Emulation. Another novel feature of the Fides system
is that the Controller partially emulates the game client to accommodate any
client system variation that would affect measurement validation. The Controller
includes routines (explained in detail later) for mapping the client’s virtual memory
and learning its execution patterns during player logon. This compiled knowledge
is relevant for the duration of gameplay and is used to validate each Auditor
measurement; deviation indicates the presence of cheat software.
Static game data and code are learned by parsing the game client’s binary and
library files, and rebasing them to match the layout on the client machine. The
Auditor or client (via the server) must relate those pertinent library details to the
Controller at client logon. Dynamic data is semantically identified using source
code and debugger files so that the Controller may query the server to corroborate
those values. For this approach to validate dynamic data values, the server design
must be adapted to respond to local queries about player state.
Client execution patterns are learned by disassembling the mapped code
sections and creating a graph of legitimate execution describing the range of and
relationship between all client functions. This knowledge allows the Controller
to know what code should be executing given an instruction pointer, and whether
specific code locations represent CALL instructions linking two legitimate functions.
To better learn commercial-off-the-shelf games (which may be obfuscated to
prevent reverse engineering and may not supply its source code) that run in
common machine environments, the emulator includes tools for sampling and
profiling legitimate client execution in a secure server-side environment. These
tools can provide client understanding where static learning routines cannot.
While the Auditor and Controller in Figure 2.1 are shown separate from the
game components, they could be implemented within the game client and game
server. Locating the Auditor in the client enables polymorphic patching discussed
in detail in Section 2.4.3 on page 60. Locating the Controller in the server
streamlines the validation of dynamic data.
35
Sample
Memory
Hash
Page
Trace
Stack
Detect
Debugger
EIPn
0x8CC70208
0x90BEFFFA
0xA4506CEB
0xBEF9A3F7
0xC67178F2 yes / no
r / w / x
00 00 00 00 00 00 00 00 0 0
00 00 00 00 00 00 00 00 0 0
00 00 00 00 00 00 00 00 0 0 00
00 00 00 00 00 00 00 00 0 0 00
00 00 00 00 00 00 00 00 0 0 00
00 00 00 00 00 00 00 00 0 0 00
00 00 00 00 00 00 00 00 0 0 00
00 00 00 00 00 00 00 00 0 0 00
00 00 00 00 00 00 00 00 0 0 00
00 00 00 00 00 00 00 00 0 0 00
00 00 00 00 00 00 00 00 0 0 00
00 00 00 00 00 00 00 00 0 0 00
00 00 00 00 00 00 00 00 0 0 00
00 00 00 00 00 00 00 00 0 0 00
00 00 00 00 00 00 00 00 0 0 00
00 00 00 00 00 00 00 00 0 0 00
Game
Data
...
r / w / x
Game Client
Controller
EIP0
Digest
Auditor
Request
Processor
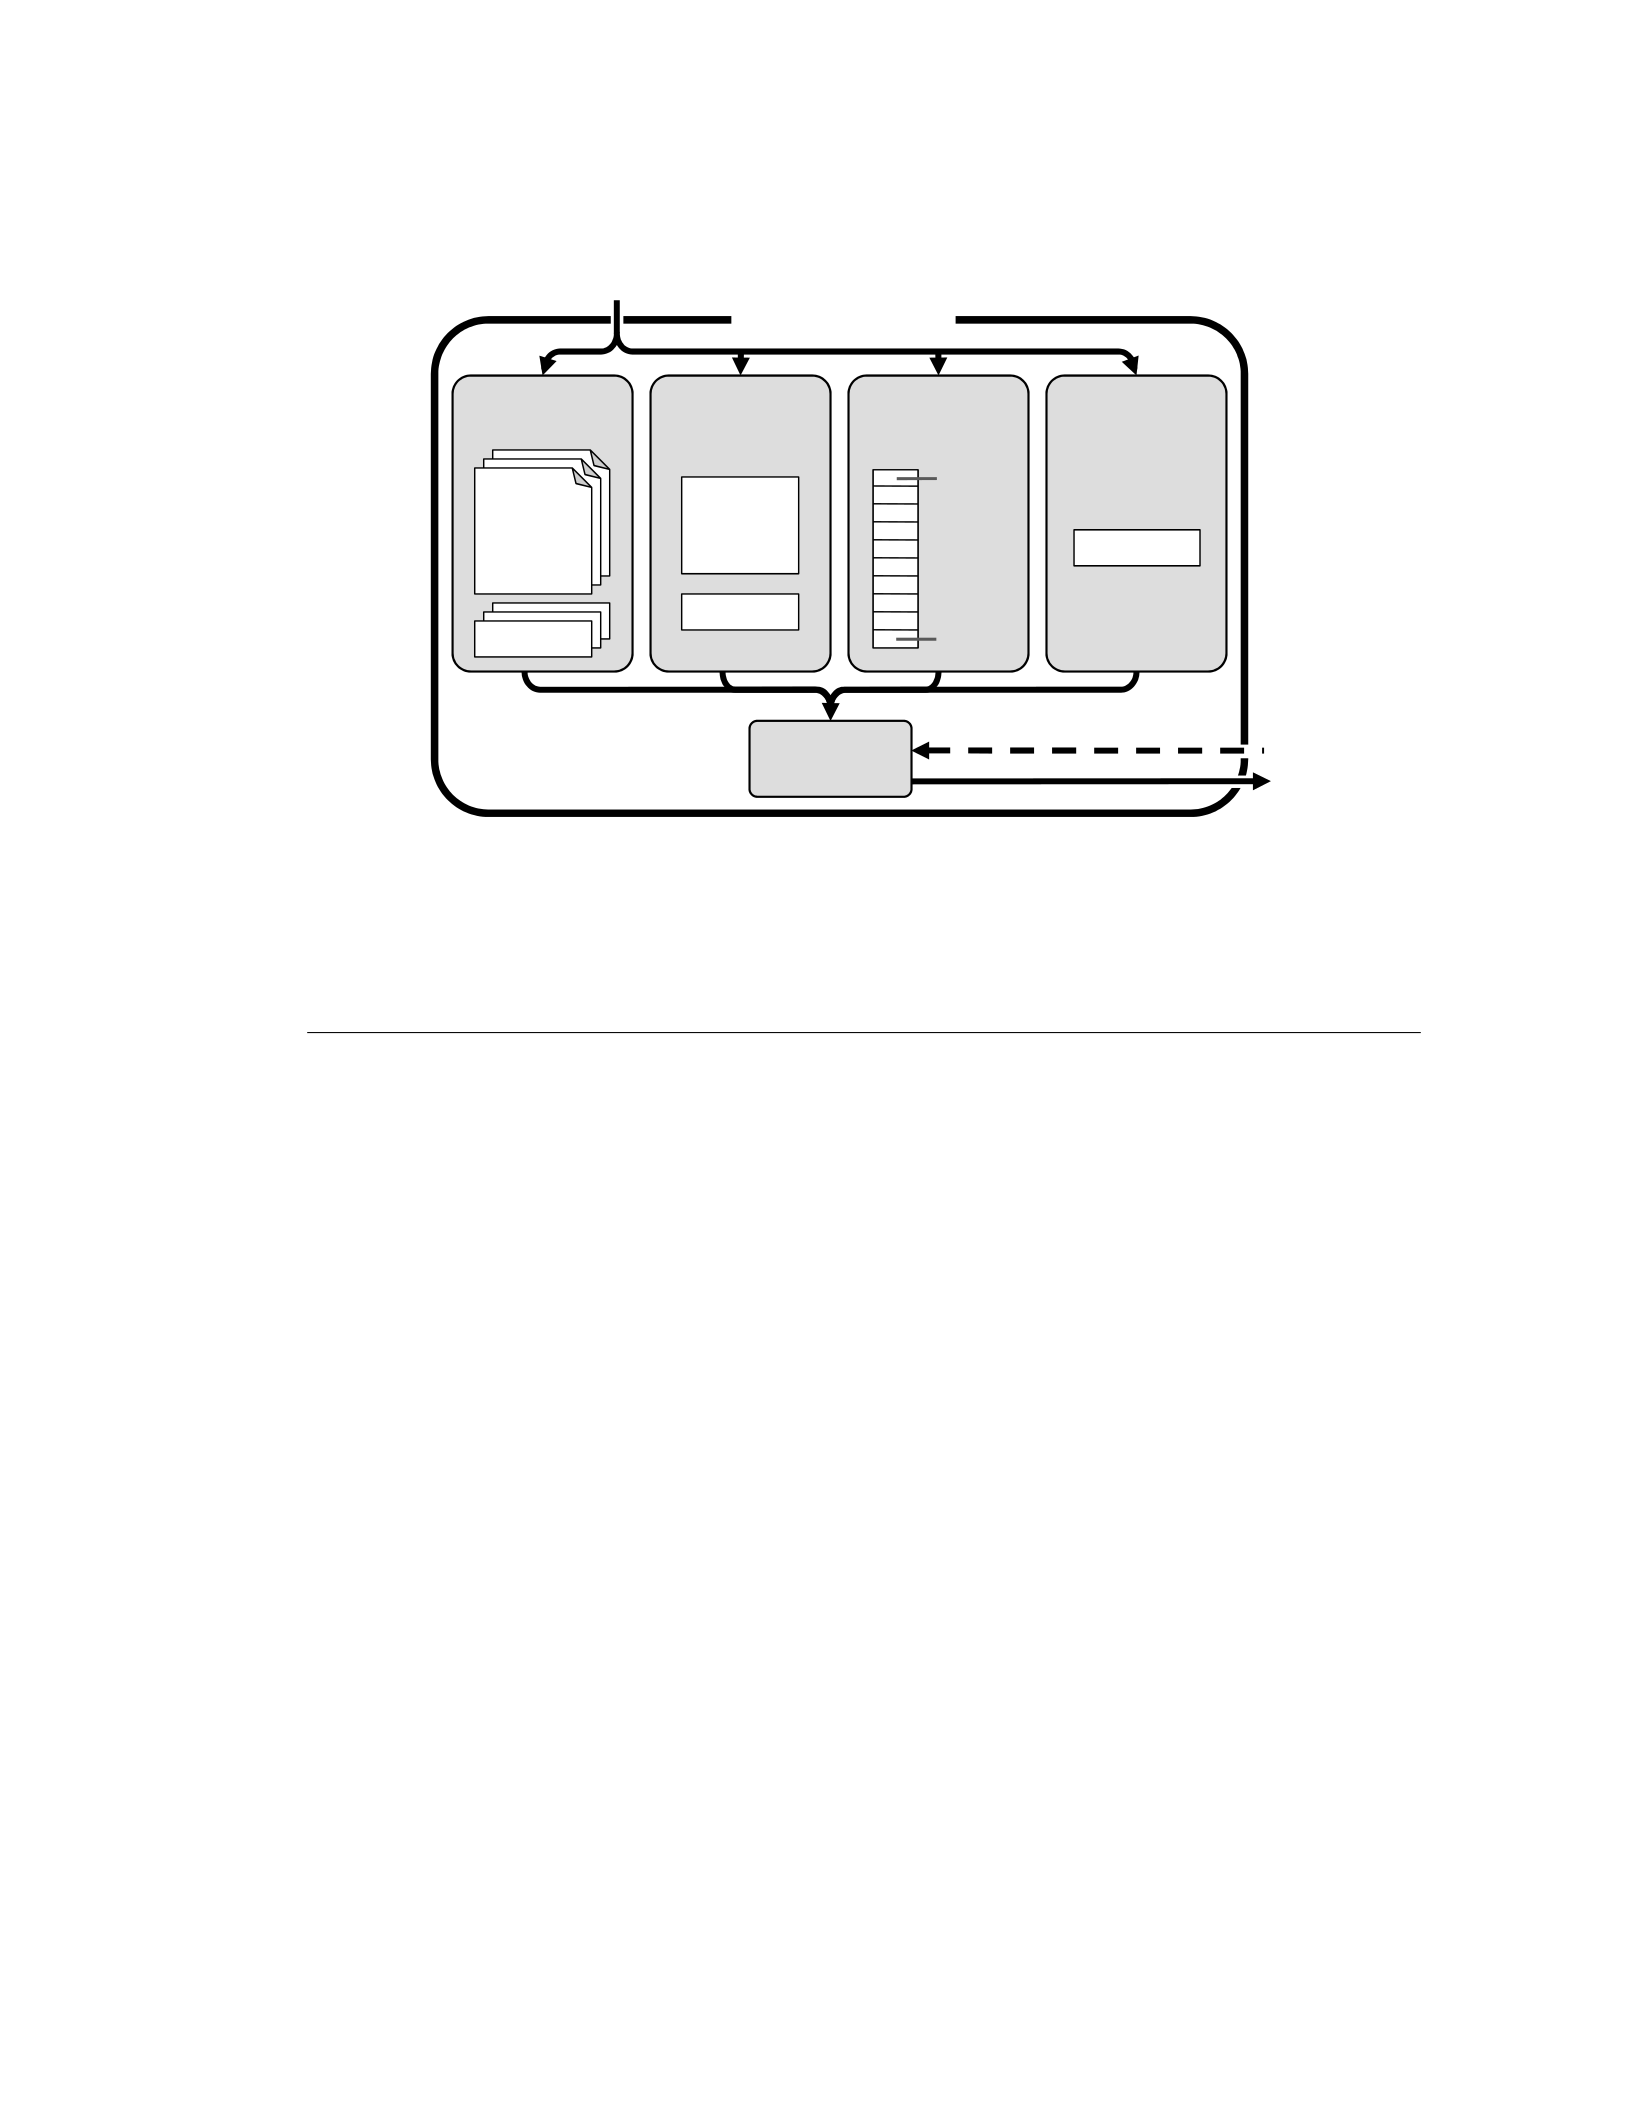
Figure 2.2: Internal structure of the Fides Auditor. The Auditor responds to
requests from the Controller and executes one of the four supported measurement
routines that collect client state directly from the game client process.
2.3.1 The Auditor
The Fides approach predominantly involves server-side software since it is the
game developer who is interested in the detection results. However, to audit the
game client requires the addition of a client-side component. That component is
the Auditor (shown in Figure 2.2) which accepts instructions from the server-side
Controller, performs the requested measurements, and returns the results.
The Auditor is intentionally kept very simple for three reasons. First, game-
specific features are kept out of its design so that it may be used by any number
of game developers to audit their games, or even by other service providers to
audit their network applications. Second, its simplicity allows one to assure
its correct operation, reducing the likelihood that incorrect operation will later
be discovered and require correction. Third, its simplicity facilitates the use of
expensive cryptographic integrity-assuring operations like entanglement or tamper-
resistant coprocessors to verify its integrity.

36
Auditor Measurements
The Auditor currently supports four measurement routines which are described
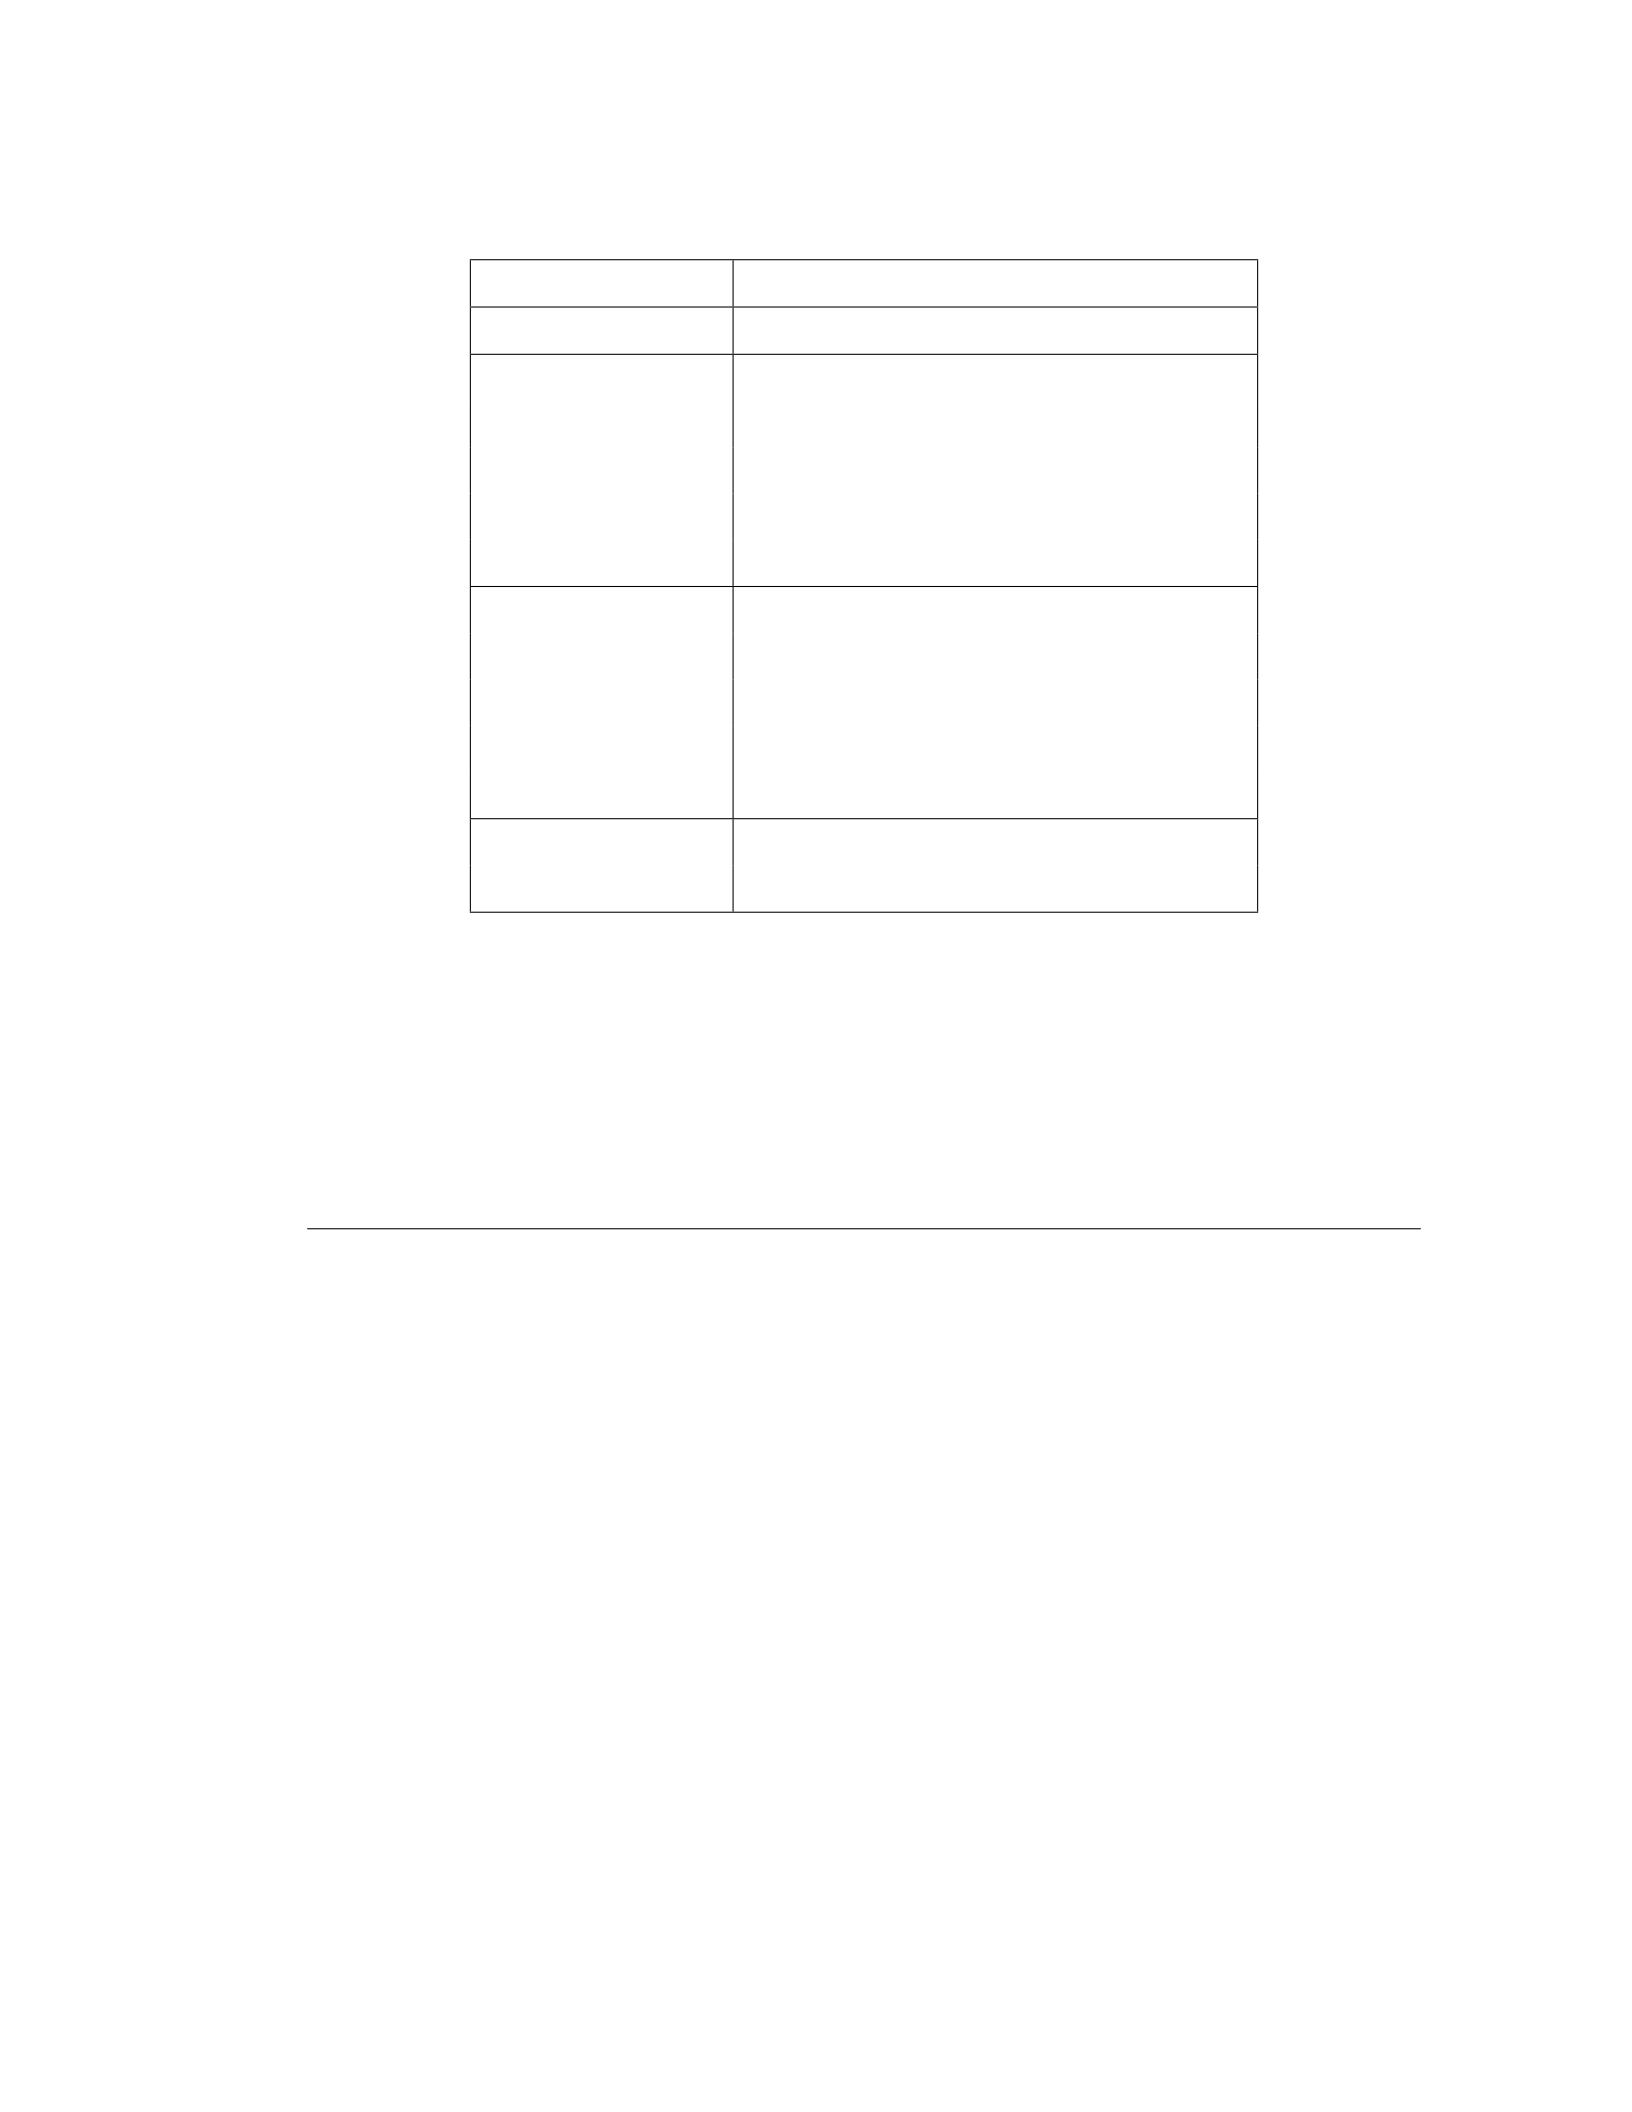
in detail below. Table 2.1 shows the cheat methods best detected by each of the
measurement routines.
Sample Memory. This routine returns the contents and read-write-execute
permission flags of a specified range of the game client’s virtual memory. This
routine is best used to detect cheats that modify dynamic data. Since the specified
memory range is expected to contain dynamic data, every game client thread must
be briefly suspended to get a quiescent reading.
Hash Page. This routine uses a cryptographic hash function (e.g., SHA1 [84])
to hash the specified memory page and return the digest along with the page’s
permission flags, facilitating efficient detection of cheats targeting static data and
code. If unspecified, the page currently executed by a randomly selected thread is
hashed. This measurement does not require suspending any game client threads
because the target memory page should be static. Whenever possible, use of this
routine is preferable over memory sampling because it saves network bandwidth
and minimizes the server-side state necessary to validate the results.
Trace Stack. This routine suspends one client thread, chosen at random if
unspecified, and obtains the current instruction pointer (EIP) and stack pointer
(EBP) which are the representative registers of the stack frame (i.e., client function
executed). Recording all encountered instruction pointers, the routine recursively
descends the stack, obtaining each previous stack frame by dereferencing the stack
pointer of the current frame, until it reaches the frame corresponding to the thread
entry point (i.e., EBP =null) at which point the measurement is done and the
client thread may be resumed. The nrecorded instruction pointers list the function
calls that the client thread used to get from the entry point to the current point of
execution and are returned, facilitating the detection of any cheats that hijack game
execution (redirecting it to unrecognized locations or between unrelated functions).
37
Measurement Cheat Methods Detected
Sample Memory Dynamic Data Manipulation
Hash Page
Static Data Manipulation
Code Manipulation
Code & DLL Injection
File Replacement
Memory Management Manipulation
Trace Stack
Thread Injection
Thread Hijacking
Function Pointer Hooking
Direct Function Calls
Register Manipulation
Detect Debugger Software Debugging
Hardware Debugging
Table 2.1: Cheat methods best detected by Auditor measurements. In general,
page hashing and stack tracing are the preferred measurements. Page hashing can
detect all the static cheat methods that memory sampling can, yet is much more
efficient in terms of network bandwidth. Stack tracing can detect all the cheat
methods that alter game execution.
Detect Debugger. This routine detects whether the game client is being
manipulated by a cheat attached to it as a debugger, and returns the Boolean result
to the Controller. If the game client has a debugger attached, the corresponding
flag in its Process Execution Block (PEB) should be set to true (although the
first thing such cheats do is set the flag to false) which can be tested via the
CheckRemoteDebuggerPresent() function. Alternatively, the routine attaches
to the game client as a debugger using DebugActiveProcess() which always
fails if another debugger is already present. Attaching as debugger is relatively
expensive (roughly 9ms) and should only be done if the first test is negative.
This measurement routine detects all software debugger cheats and most hardware
debugger cheats.
38
Client
Emulator
Controller
Code
Disassembler Binary
Parser
Memory
Layout
Code
Patterns
Game Server
Cheaters
Dynamic
Data
Emulated
Client State
Client
Layout
Audit
Validator
Audit
Strategist
Auditor
Game
Binary
Libraries
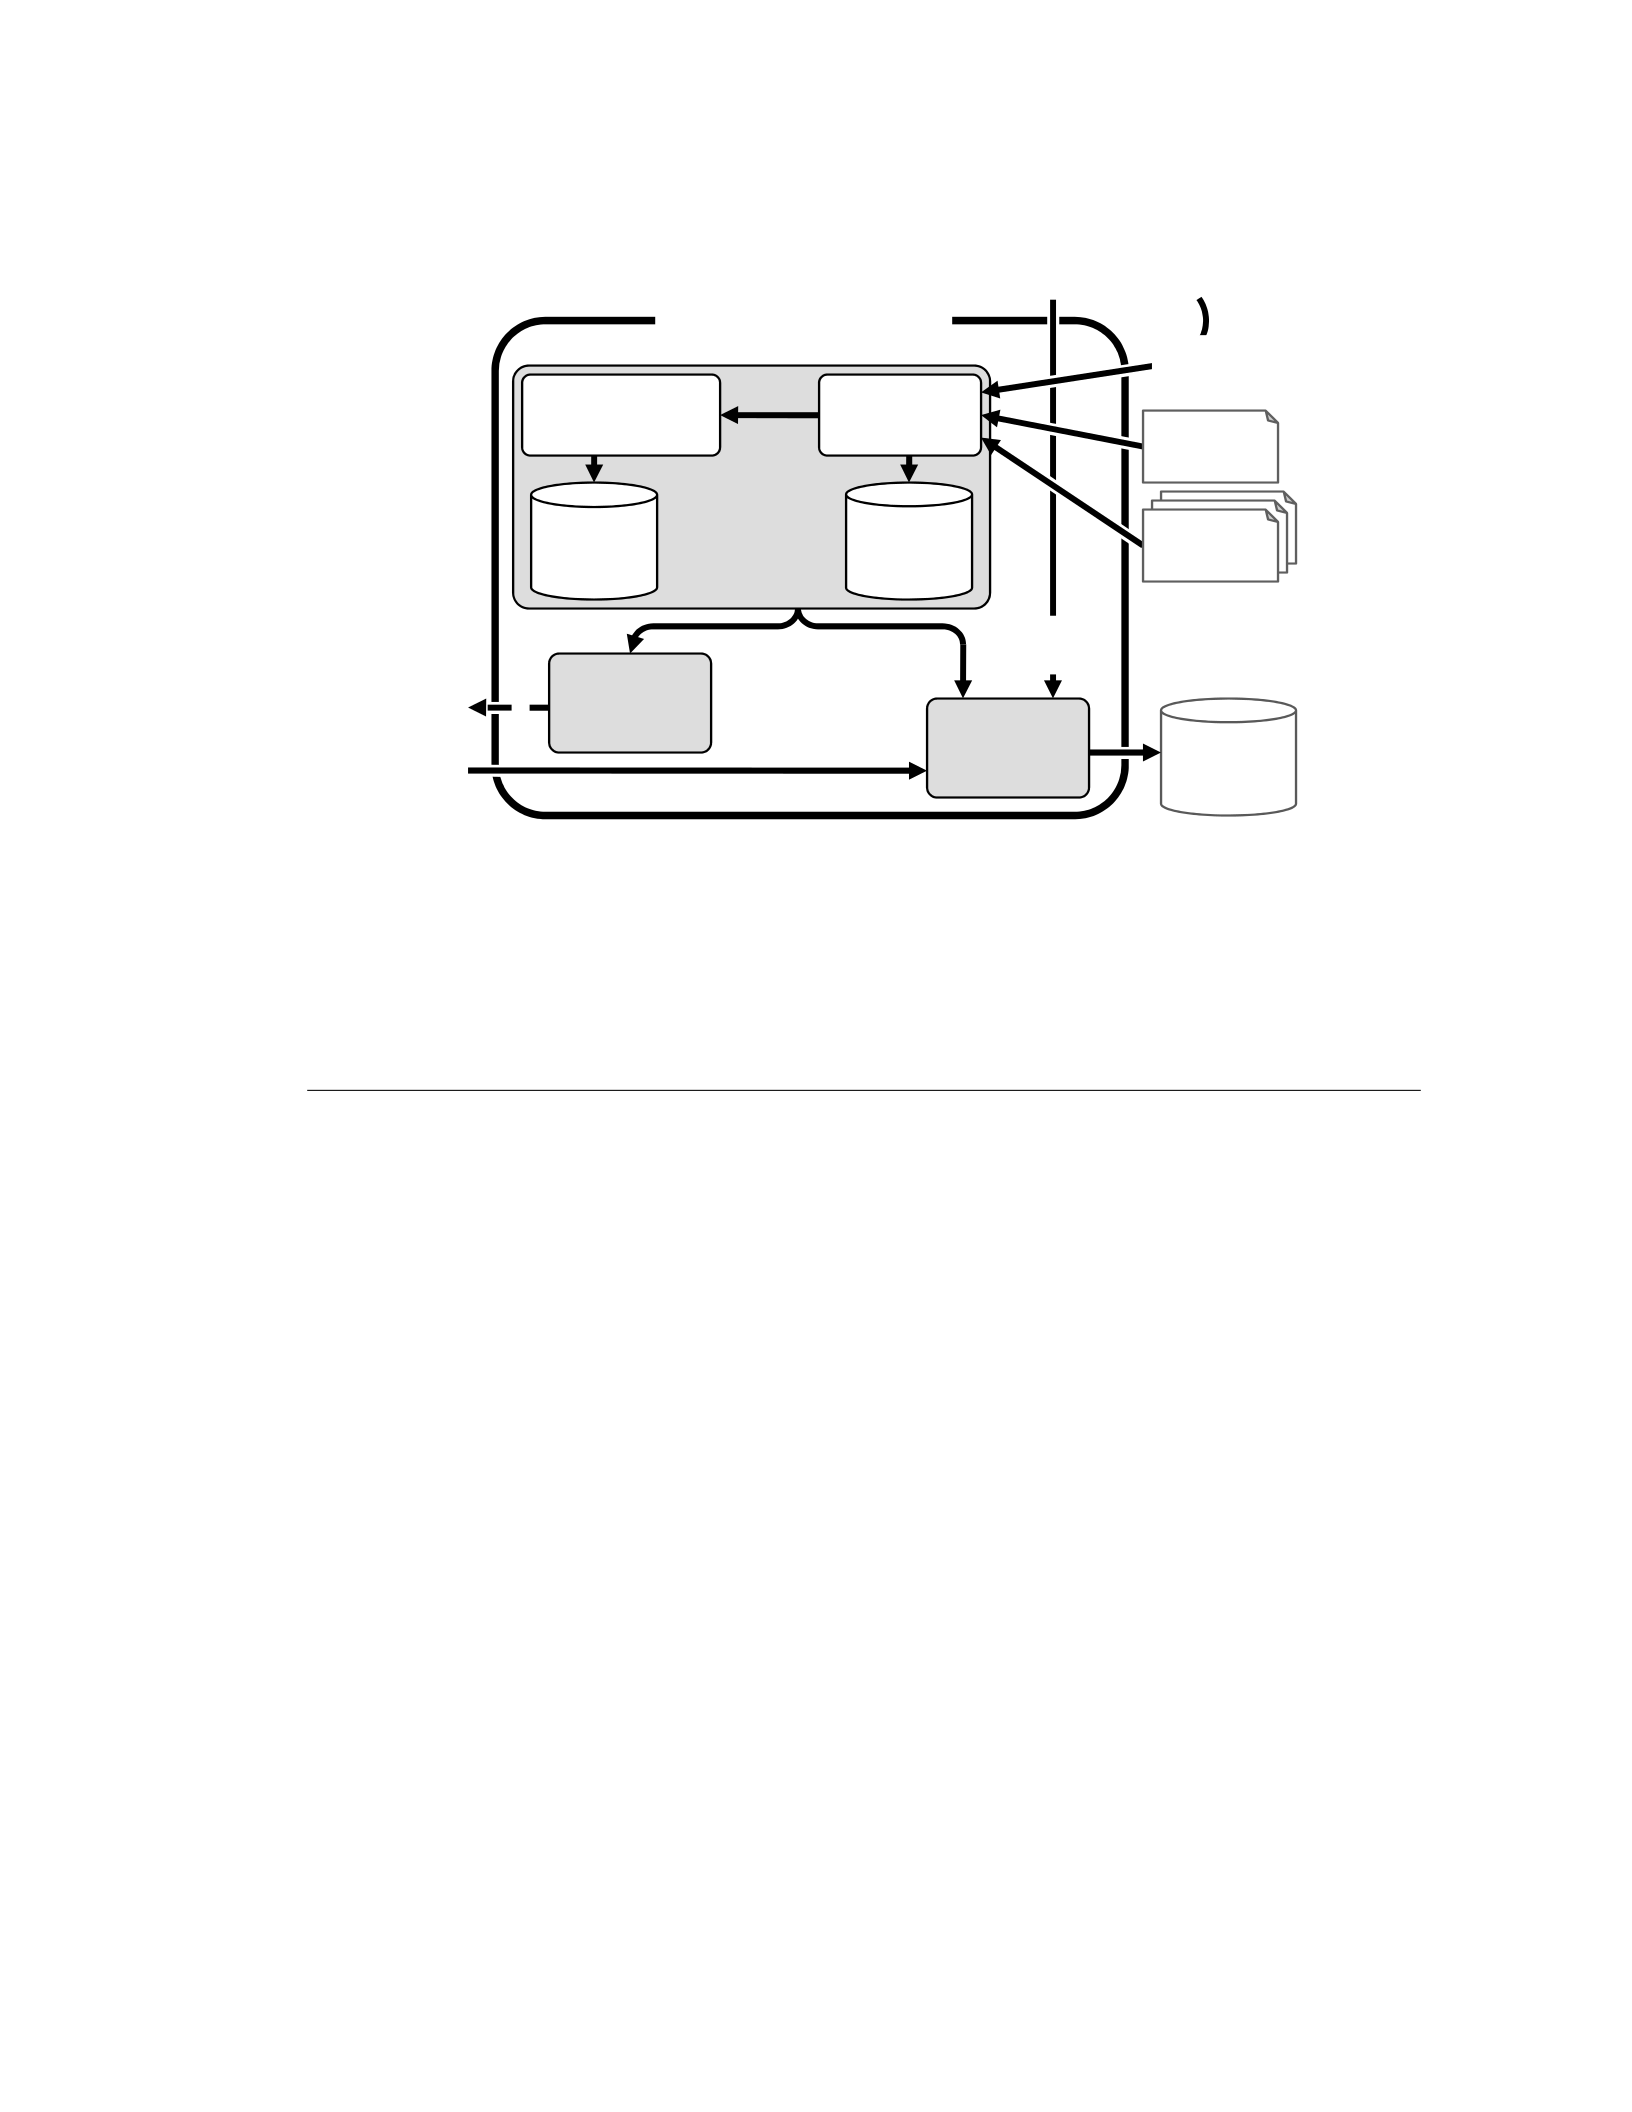
Figure 2.3: Internal structure of the Fides Controller. The Controller hosts all
of the system complexity and dictates what should be measured by the Auditor.
Arrows show the data flow between external data sources and the Client Emulator,
Audit Strategist, and Audit Validator components.
2.3.2 The Controller
The Controller (shown in Figure 2.3) hosts the complexity of the Fides system,
the bulk of which is the Client Emulator. The Client Emulator learns the
game client properties that remain constant (i.e., static data, code, and function
relationships) and identifies dynamic data sections. The Audit Strategist uses
the compiled knowledge to create an audit strategy (possibly tailored to the game)
and orchestrates the strategy during gameplay. The Audit Validator uses emulated
state to directly verify audits of static game client data and code. To verify audits
of dynamic game client state, the semantics of the sampled memory are extracted
from the emulated state so that the actual values can be validated by what the
server dictates they should be at that time. This accommodates most susceptible
dynamic variables since they normally change slowly (i.e., on the order of seconds
or minutes) and smoothly (e.g., character movement, health, and ammunition).

39
Client Emulator
The hardware and software of the machine on which the client runs varies from
player to player, and even changes between play sessions for individuals who play
on different machines. Such variation affects the memory layout and contents of
the client process. For example, the libraries loaded by the game differ between
operating systems and system versions. Additionally, memory layout differs
between executions on systems that randomly rebase libraries via Address Space
Layout Randomization (ASLR) [101].
The Client Emulator accommodates for host variation by thoroughly mapping
the code and static data and identifying the dynamic data for each client at logon.
Pertinent clients layout details (i.e., the name, version, and base location of every
library loaded) must be communicated to the Controller either by the Auditor or
by the client via the server. The emulator owns a copy of all known and authorized
legitimate libraries so no files need to be transferred from the client machine to the
Controller. If the client (rather than the Auditor) is tasked to exchange its layout
details, it is behooved to accurately report those details otherwise inconsistencies
will be instantly detected and classified as cheating.
Game clients may run on operating systems without ASLR (or may be compiled
with ASLR disabled – a decision the developer may elect) and share common
library content and layout. Specifically, core system libraries (e.g., KERNEL32.DLL
and NTDLL.DLL) often contain thousands of small functions that comprise much
of any client application’s complexity. The emulator can leverage commonality
to reuse significant portions of the emulated state between clients, and learn only
truly variable client structure at logon.
The Client Emulator uses two routines for learning client structure: a Binary
Parser and a Code Disassembler. The emulator also contains an Execution Sampler
and an Execution Profiler to better understand if the client application can be run
in a cheat-free virtual machine using a consistent layout.
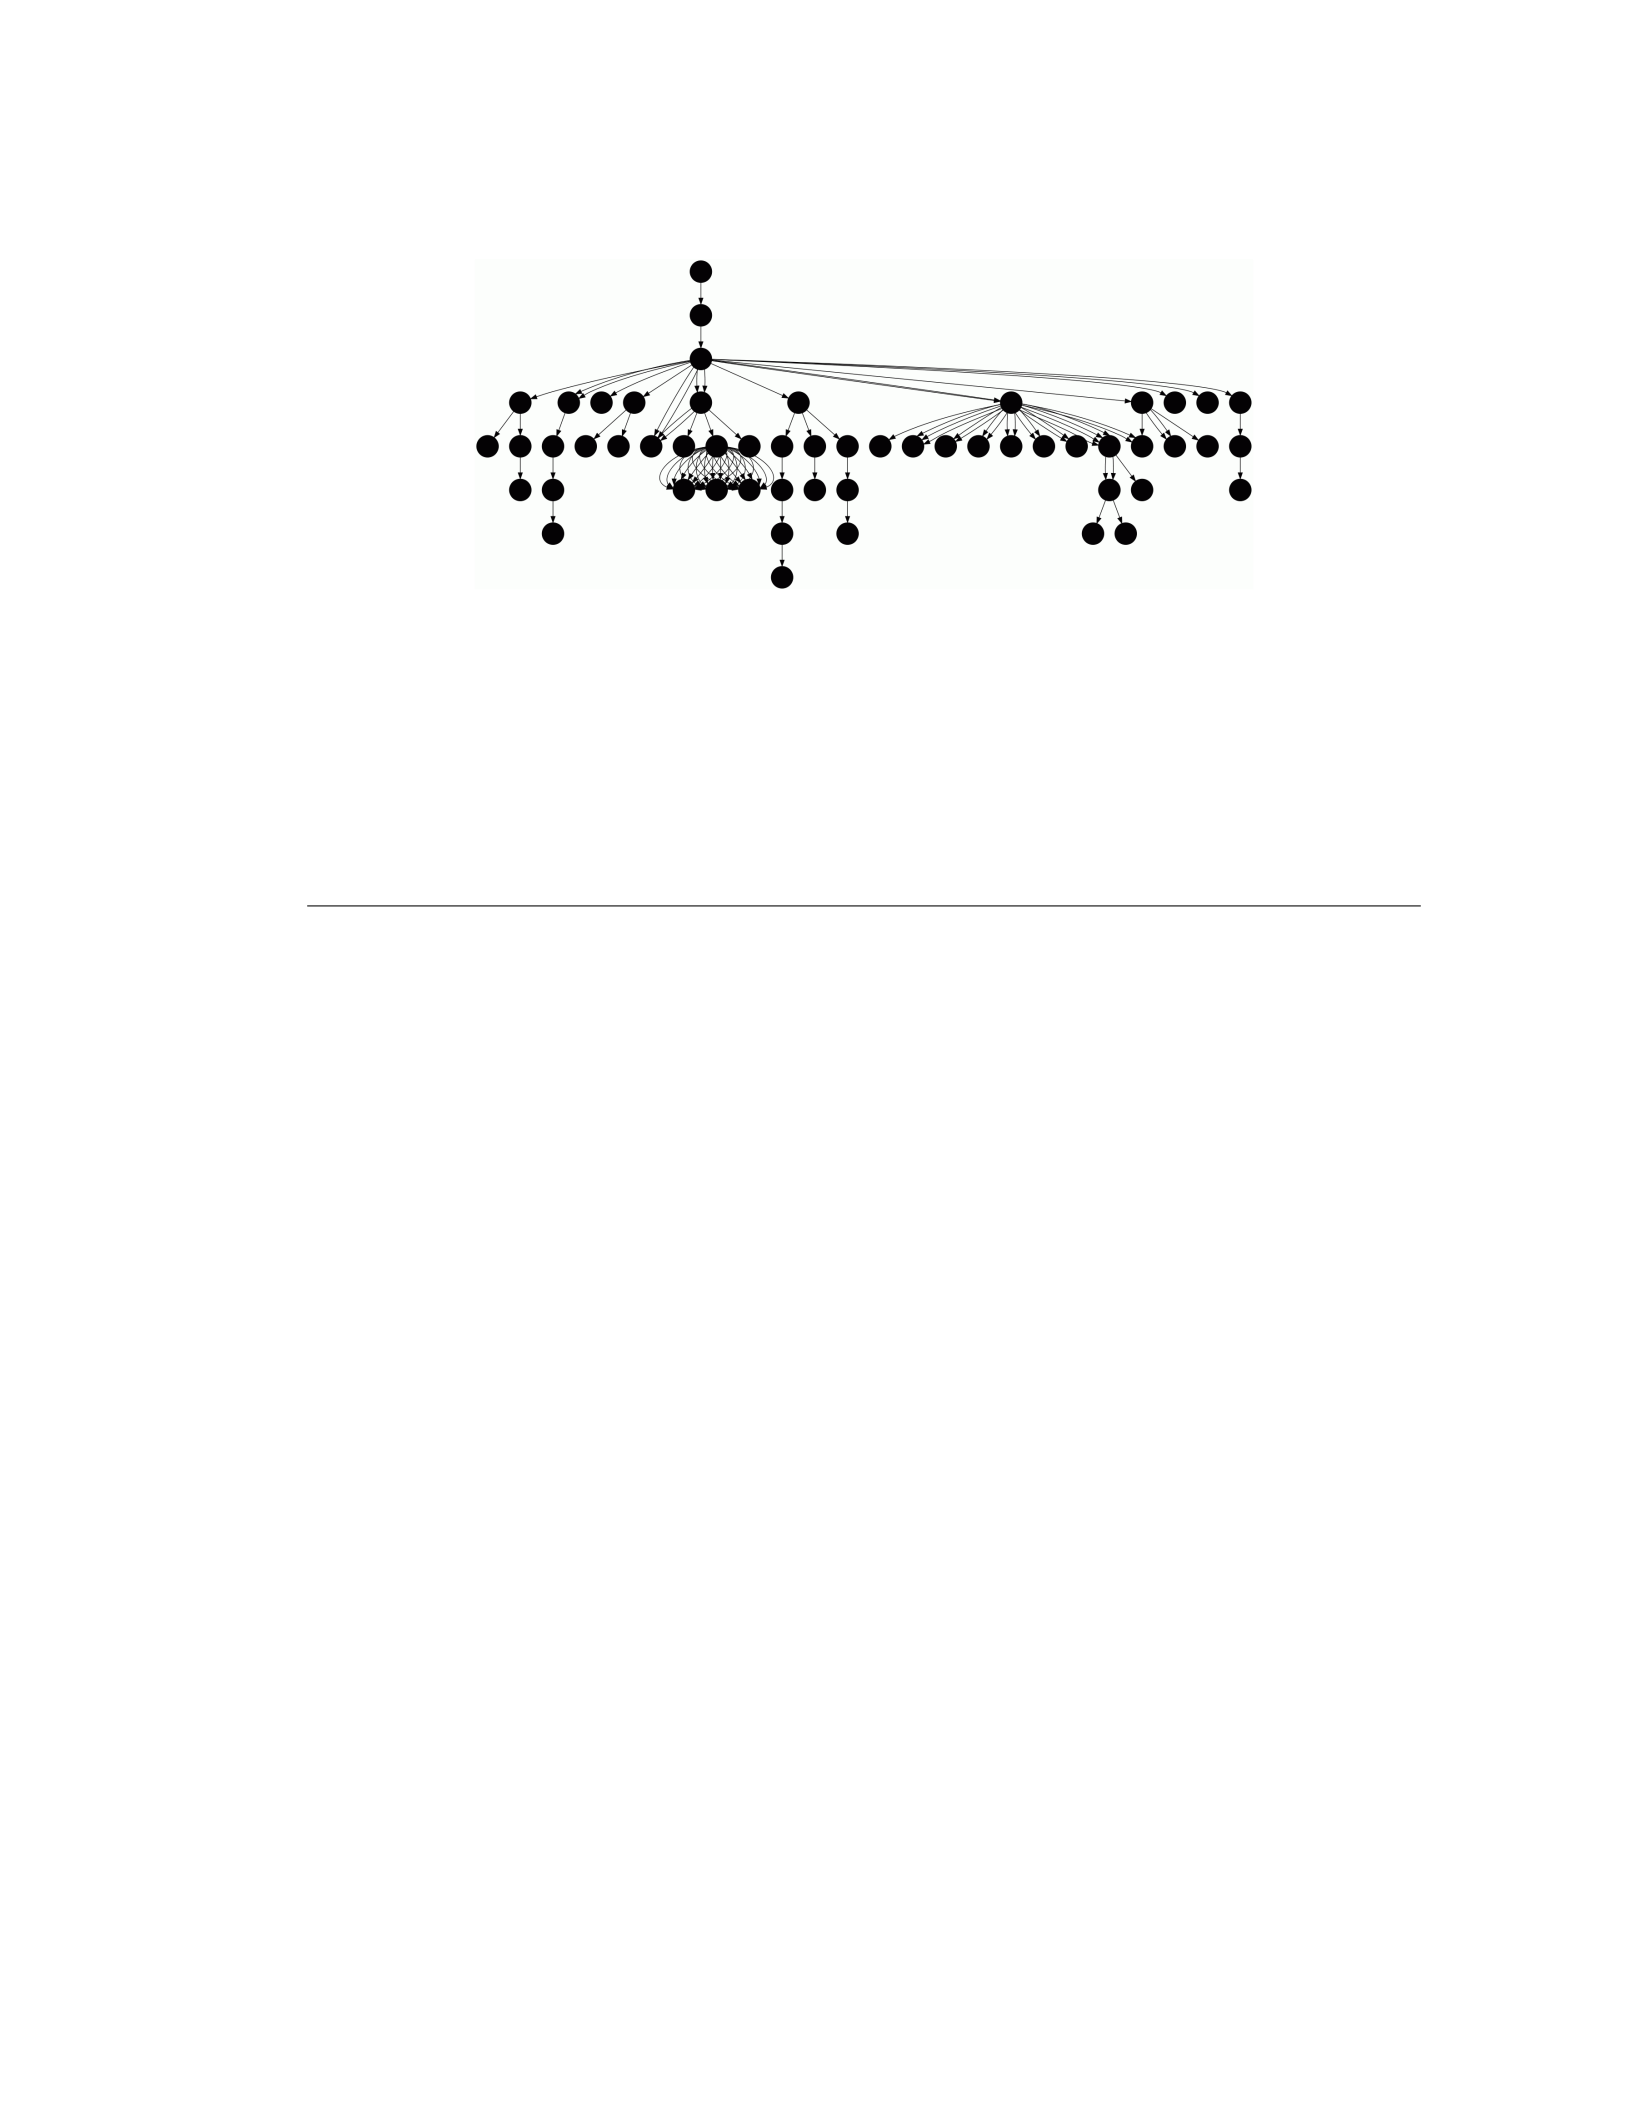
40
Figure 2.4: Example execution call graph. This partial graph shows the function
dependencies originating from the initialization routine of our Homebrew game.
Nodes represent functions while directed edges represent specific memory locations
(i.e., CALL instructions) that relate two functions. Often a second function is called
several times, hence the multiple edges connecting any two functions.
Binary Parser. The first learning routine is the Binary Parser which maps
the client virtual memory from the executable, all linked libraries, and data files.
Using the client-provided layout information, the routine rebases the libraries to
know the location and properties (i.e., read-write-execute permissions) of every
memory section in the client. Function pointers (e.g., IAT pointers) are corrected
so that page hashes may be generated for static data and code sections, reducing
emulator state for that data to a small digest per page. If available, the emulator
uses source code and debugger database files to learn the semantics of variables in
dynamic data sections so the Controller may intelligently query the server for the
correct values of a memory sample.
Code Disassembler. The second learning routine is the Code Disassembler
which uses the code sections mapped by the Binary Parser to learn the range of and
relationship between every function in the game client. The routine starts at the
entry point of the executable and traverses the code, observing the memory range
of each function and the location of instructions that relate functions, creating
an execution graph (like the one shown in Figure 2.4) similar to the “callgraph”
model [119]. This knowledge is used when validating stack trace audits.

41
Execution Sampler. The above routines are sufficient to learn client
applications for games designed to work well with Fides, however, to better learn
commercial-off-the-shelf games (which may be obfuscated and for which one may
not have source code) running in non-ASLR environments the emulator includes
an Execution Sampler. The tool executes the client application in a cheat-free
environment, like that which the actual client should be running in. The sampler
then exhaustively hashes all the non-writeable pages of the game, furnishing the
knowledge to the emulator so it may be used to validate page hash audits of the
actual client.
Execution Profiler. The emulator also includes an Execution Profiler
to learn the instruction range of and the relationship between client functions
(specifically observing indirect function calls), reinforcing the execution graph used
to validate stack trace audits. This tool executes the client application in a secure,
cheat-free environment, attaches to it as a debugger, and uses hardware debugging
routines (i.e., register manipulation and single-step interrupts) to step through
its execution. The profiler records details about instruction counts, code timing,
and function execution frequencies. These execution patterns may also be used to
improve audit strategies.
Audit Strategist
The Audit Strategist orchestrates the detection strategy, dictating the ordering,
timing, and details of every audit request. Locating all the strategy in the
Controller avoids telegraphing measurements, allows the developer to change
strategy surreptitiously, and minimizes Auditor complexity. The strategy may be
game-specific using developer intuition regarding data or code likely to be attacked,
however, a good strategy must employ some randomization to prevent cheaters
from predicting audits and developing a successful cloaking routine. As cheaters
will be audited countless times while they are online, a strategy with randomness
will, with good probability, eventually catch them.

42
Audit Validator
After measurements have been returned to the Controller, the Audit Validator
validates them through different means according to their type as follows.
Hash Page. These audits measure static data, so they should remain
unchanged. The validator does a simple binary comparison of the audited digest
against the stored digest. Any bitwise difference means that the page has been
modified, an indication of tampering.
Sample Memory. Although an easy audit to perform, validating sampled
dynamic data is difficult and involves server corroboration. The validator must
determine the semantics of the data (i.e., which variable it represents) and query
the server regarding what the proper value or range of values should be. Consider
the cheat which toggles the team variable to reveal enemy locations via the radar.
To validate that variable, the server must share which team the player is on. This
is straightforward because there are few valid values and the variable changes
infrequently. Next, consider teleport cheats that adjust the character’s in-game
coordinates. In this case, there are innumerable valid values, the value changes
frequently, and due to their use of dead-reckoning techniques, clients will be strides
ahead of what the server has recorded. Consequently, the server must provide a
range of locations where the player could legitimately be according to game rules.
Stack Trace. Validating a stack audit involves walking the execution graph
according to the sequential list of instruction pointers returned by the audit. Client
execution has been hijacked if any instruction pointer calls an unknown location
in memory (i.e., referencing a nonexistent node) or represents an unrecognized
function call (i.e., referencing a nonexistent edge). Indirect function calls are
handled by validating every direct call up to it and immediately hash auditing
the functions after it ensuring they have not been detoured.
Detect Debugger. The simplest audit to validate; a detect debugger audit
should be false otherwise the client is being manipulated by a debugger.

43
2.4 EVALUATION
To demonstrate the utility and easy deployment of the Fides approach, a software
prototype was implemented consisting of two applications (corresponding to the
Auditor and Controller) that communicate through a TCP socket. The prototype
is game-agnostic and has been tested successfully on a number of games.
Auditor Details. The Auditor employs functions of the Windows debugging
API to conveniently read client virtual memory using ReadProcessMemory() and
access the client’s registers using GetThreadContext(). When necessary, the
Auditor suspends a client thread using SuspendThread() since it is three orders
of magnitude faster than attaching as a debugger.
Controller Details. The Binary Parser processes files of the Windows
Portable Executable (PE) format, maps those files to virtual addresses, fixes the
links in each file, and hashes the static sections with SHA1. The implementation
challenges included resolving circular linking dependencies, evaluating forwarded
exports, handling aliased functions, and locating anonymous import tables. When
available, the parser also processes files of the Program Database (PDB) format
to uncover un-exported function symbols and identify dynamic data variables.
The Code Disassembler is a basic x86 disassembler which walks client code
starting at the entry point of the binary and follows function calls to determine
the range of and relationship between client functions. Implementation challenges
included resolving functions that terminate in inconsistent ways, functions that use
discontinuous memory, and functions that embed return instructions in the middle
(in particular those protected by the Windows implementation of StackGuard [22]).
To better understand the game client structure, the Execution Sampler uses
CreateProcess() to run the client application local to the Controller since the
client and Controller use common non-ASLR operating systems (i.e., Windows XP
SP3). The sampler exhaustively hashes every user-space page between 0x00000000
and 0x7FFFF000 that is static (i.e., allocated and non-writeable).

44
The Execution Profiler also runs the client, but attaches to it as a hardware
debugger to learn the function frequency and indirect function calls unhandled
by the disassembler. The implementation challenges included avoiding the
game’s anti-debugging techniques, resolving timing delays caused by the debugger
interrupts, and guiding the game into its gameplay loop to be measured.
Measurement Strategy. The Controller uses a straightforward game-
independent audit strategy that takes measurements at a specified interval.
To avoid predictability, random timing jitter is added, uniformly distributed
between -5% and +5% of the interval length. Throughout each experiment, the
chosen measurement routine was held constant but the target of each individual
measurement was left unspecified. For stack trace audits, this means a thread was
selected at random. For page hash audits, this means a thread was selected at
random and its executing code page was hashed.
2.4.1 Experimentation
Benchmarking
The Fides Auditor and Controller were benchmarked to evaluate whether the
approach is suitable for commercial-off-the-shelf games (in this case the game
was Warcraft III [12]) without imposing a significant negative compute burden
in exchange for its cheat detection benefits. Using a 2.39GHz Intel Core2 machine,
each routine was executed 1,000,000 times recording the average and variance in the
number of cycles to complete them. The efficiency of the Auditor and Controller
routines are shown respectively in Table 2.2 and Table 2.3.
Warcraft III imports 17 DLLs representing 4,103 total functions, many of which
belong to system libraries and are unused. The memory sections represent 1,649
total pages of which 1,619 are flagged as static. This indicates library layout
commonality (specifically on non-ASLR systems) could save the Controller from
executing the full learning routines for every client.
45
Auditor Task Cycles Time
Null 82 ±18% 34.6ns
Sample Memory 87,941 ±21% 36.8µs
Suspend Threads 54,960 ±22% 22.9µs
Read Memory 11,947 ±35% 5.0µs
Fetch Page Flags 21,854 ±30% 9.1µs
Resume Thread 4,249 ±97% 1.8µs
Hash Page 112,885 ±21% 47.2µs
Suspend Thread 4,843 ±33% 2.0µs
Get EIP 19,760 ±44% 8.3µs
Resume Thread 4,153 ±65% 1.7µs
Read Page 15,597 ±32% 6.5µs
Hash Contents 55,391 ±23% 23.2µs
Fetch Page Flags 11,031 ±42% 4.6µs
Trace Stack 64,399 ±27% 26.9µs
Suspend Thread 4,844 ±25% 2.0µs
Get EIP & EBP 26,042 ±45% 10.9µs
Get Stack Range 15,782 ±42% 6.6µs
Traverse Stack 13,462 ±37% 5.6µs
Resume Thread 4,292 ±31% 1.8µs
Detect Debugger 23,246,056 ±1.5% 9.7ms
Test Debug Flag 2,998 ±43% 1.3µs
Attach Debugger 21,411,428 ±1.2% 8.9ms
Detach Debugger 1,828,041 ±7.0% 0.8ms
Table 2.2: Efficiency of Auditor routines. The average and variance in the number
of processor cycles to complete the routines was measured and converted to time.
The results demonstrate that the Auditor’s measurements complete very
quickly. The three most common routines (sample memory, hash page, and trace
stack) operate on the order of tens of microseconds, adding imperceptible overhead
(0.05% when auditing roughly once every 100ms) to the game. The most expensive
routine (detect debugger) takes 9.7ms and only adds a perceptible hiccup to the
game if performed frequently in a tight loop.
46
Controller Task Cycles Time
Null 85 ±19% 35.6ns
Parse Binaries 236,322,896 ±0.1% 98.8ms
(single file) 17,221,136 ±2.5% 7.2ms
Memory Map File 741,448 ±5.0% 0.3ms
Identify Sections 4,774 ±20% 2.0µs
Allocate IAT 388,067 ±19% 0.2ms
Populate IAT 5,193,318 ±2.1% 2.2ms
(single entry) 58,517 ±4.4% 24.5µs
Hash Sections 10,893,211 ±4.5% 4.6ms
(single page) 46,908 ±6.7% 19.6µs
Disassemble Code 205,290,560 ±0.2% 85.9ms
Isolate Function 1,165,818 ±6.3% 0.5ms
Validate Result varies as follows ...
Sample Memory data dependent
Hash Page 3,170 ±20% 1.3µs
Trace Stack 10,808,131 ±10% 4.5ms
Detect Debugger 130 ±21% 52.4ns
Table 2.3: Efficiency of Controller routines. The average and variance in the
number of processor cycles to complete the routines was measured and then
converted to time for convenient analysis.
The Controller’s learning routines take under 100ms and do not impose a
meaningful burden to the game considering they are only run once at client logon.
The number of subtasks to learn a game depends on its complexity – this game is
reasonably complex. Similarly, the validation routines are very quick. Validating
a hash page audit involves a binary comparison of the 20B digest and validating a
debugger audit evaluates the Boolean value, both very efficient routines. Validating
a stack trace audit is more involved because each instruction pointer in the list
must be looked up as to which function it belongs to, and if it can legally call the
next function. The effort to validate such an audit depends on the stack depth
and the number of functions in the game.

47
Homebrew Game
This section evaluates Fides on our Homebrew (i.e., of our own creation) game and
four cheats employing different techniques in order to compare the effectiveness of
stack trace audits and hash page audits. The game is a simple networked two-
dimensional arena combat game in which players jump to-and-from a number of
platforms while shooting at each other. The game is single-threaded and uses the
Simple Directmedia Library (SDL.DLL) which facilitated fast game development
by conveniently wrapping graphics functions (in OPENGL32.DLL), network functions
(in WSOCK32.DLL and SECUR32.DLL), and system functions (in KERNEL32.DLL). The
game client executes a short gameplay loop where it checks for input, communicates
changes to the server, renders the world, and then sleeps. In total the loop takes
25.8ms to complete, equivalent to an average frame rate of 38.8fps.
To simplify cheating, the game client stores sensitive data (i.e., opponent
positions) at fixed locations in memory. The game client also performs shooting
actions through the ShootGun(x,y) function which fires a shot from the player’s
current coordinates to the specified (x,y)-coordinates. Four game cheats using
different cheating techniques were implemented to exploit this function in order to
automatically aim the cheater’s shots.
The first cheat uses a small hotpatch which statically replaces the input to the
ShootGun() function with the static coordinates of a target at time of patching
– clearly not a very intelligent cheat yet done in place without allocating any
additional client memory. The second cheat injected a DLL which detours the
ShootGun() function to injected code which dynamically aims the shot at an
opponent. The third cheat injects a DLL that trampolines the ShootGun()
function to a CheatShootGun() function (contained within the injected DLL)
which uses game state to better aim all shots. The fourth cheat injected a DLL
and a new game thread to run the injected code. The injected the code loops
indefinitely, intelligently executing the ShootGun() function every 100ms.
48
Code Page Executed
KERNEL32.DLL
Sleep()
SDL.DLL
OPENGL32.DLL
0x80000000
0x70000000
0x60000000
0x50000000
0x40000000
0.0
5.0
10.0
15.0
20.0
25.0
Code Page Executed
0x00000000
GAME CODE
0x30000000
0x20000000
0x10000000
0.0
5.0
10.0
15.0
20.0
25.0
Time (ms)
Figure 2.5: Execution profile of the Homebrew gameplay loop. Most of the
pages executed represent game code and just a few other DLLs – predominantly
KERNEL32.DLL because of the Sleep() function.
Game Profile. Using the Execution Profiler, the execution pattern of the
gameplay loop is illustrated in Figure 2.5. The code pages executed throughout
the gameplay loop are shown. Note that there are 65,536 pages between y-axis
labels and dots are disproportionately large for legibility. When actively running
simulation code, the game frequently calls short library functions that return
quickly to the game code. No significant amount of contiguous time is spent on
any single code page although many of the executed code pages are clustered in
close proximity to each other. Once the loop calls the Sleep() function, execution
is suspended on that single code page for a significantly large amount of time.
Specifically, the gameplay loop spends 76% of its time in KERNEL32.DLL almost
entirely due to that function.
49
60
70
80
90
100
110
120
130
Average Audits to Detect Cheat
0
10
20
30
40
50
60
10.0
100.0
1000.0
Average Audits to Detect Cheat
Detour
Trampoline
Thread Injection
10.0
100.0
1000.0
Auditing Period (log10 ms)
Figure 2.6: Stack trace audits required to detect cheats for the Homebrew game.
Three of the four cheats are detectable by stack traces; only in situ hotpatches
cannot be detected. In constrast, thread injection is particularly susceptible to
detection by stack traces.
Cheat Detection. Figure 2.6 shows the average number of stack trace audits
required to detect the cheats. For the cheats that hijack execution, more audits
are required for detection because the ShootGun() function where the cheats
manifest is infrequently executed. Not surprisingly, stack trace audits cannot
detect hotpatches which do not change execution flow, but stack trace audits
do very well in detecting thread injection. This is because the stack trace has
a uniform x
x+yprobability of selecting the cheat thread (which is immediately
detected as unrecognized, even when idle), where there are xcheat threads and y
game threads. In this case the probability of selecting the injected thread is 1
2and
supports the two audits on average required to detect the thread injection cheat.
50
5
6
7
8
9
10
Average Audits to Detect Cheat
Detour
Trampoline
Thread Injection
Hotpatch
0
1
2
3
4
10.0 100.0 1000.0
Average Audits to Detect Cheat
Auditing Period (log10 ms)
Figure 2.7: Page hash audits required to detect cheats for the Homebrew game.
All four cheats are quickly detected by page hashes.
Figure 2.7 shows the average number of page hash audits required to detect the
cheats. Each cheat is detected quickly using roughly four audits – expected since
the game is single-threaded and spends about a quarter of its time in game code.
These results are an order of magnitude faster than the stack trace audits. The
small code footprint contributes to the fast cheat detection; while the game does
not execute the ShootGun() function frequently, other more common functions
reside on the same code page so audits indirectly catch the cheat.
This leads to the observation that careful client design can trade some memory
performance for quicker anomaly-based detection. Hash page audits are able to
quickly, sometimes indirectly, catch these cheats not because they modified a lot
of code but because the code they did modify was located on the same memory
page as frequently executed code.

51
Commercial-Off-The-Shelf Game: Warcraft III
The Fides approach works best on games designed with it in mind. However,
to evaluate that the Fides approach works on commercially-deployed games, this
section explores the detection of cheats for the popular Real Time Strategy
(RTS) game Warcraft III [12]. The game was released in 2002 and has remained
extremely popular since then, especially as the game of choice for professional
video game competitions. Weekly, thousands of players continue to play it
online in competitive, ladder-ranked matches. The game’s developer, Blizzard
Entertainment, has patched the game regularly throughout the years to fine-tune
game balance and attempt to stay ahead of cheaters. This experimentation was
done in October 2008 immediately following a patch release. Within one week, new
cheats were released in response to the patch and Fides readily detected them. A
month later, the preeminent cheat was released and Fides swiftly detected it.
Warcraft III has several security features that make it complex. The game client
is designed so that the executable is merely a launcher: all game functionality
is located in a library appropriately named GAME.DLL. This library is loaded at
runtime via the Windows LoadLibrary() function and is obfuscated to hinder
disassembly. Similar to the Homebrew game, Warcraft III executes a short
gameplay loop where its threads check for input, communicate with the server,
render the world, and then sleep. In total, the loop takes only 15.6ms to complete,
equivalent to an average frame rate of 64.2fps.
The game client is heavily multi-threaded, employing 22 threads of which
only 8 are active during normal gameplay. Threads have assigned tasks that
include rendering the world, loading map and texture info, gathering player input,
managing network connections, running artificial intelligence routines for path
planning and non-player (i.e., computer) opponent strategy, stub server routines
for hosting games locally, and routines for performing some anti-cheating and anti-
debugging techniques (it attempts to kill any process that attaches as a debugger).
52
Code Page Executed
GAME.DLL
WaitForSingleObject()
System DLLs
0x80000000
0x70000000
0x60000000
0x50000000
0x40000000
OPENGL32.DLL
0.0 5.0 10.0 15.0
Code Page Executed
0x00000000
MSS32.DLL
STORM.DLL
0x30000000
0x20000000
0x10000000
Time (ms)
Figure 2.8: Execution profile of the Warcraft III gameplay loop. Like the
Homebrew game, the pages executed represent game code and a few other DLLs
– predominantly KERNEL32.DLL due to the WaitForSingleObject() function.
Game Profile. Using the Execution Profiler, the profiles of the threads active
during the gameplay loop are shown collectively in Figure 2.8. Game threads
execute system functions (in NTDLL.DLL and KERNEL32.DLL), core game functions
(in GAME.DLL), render graphics (in OPENGL32.DLL), process audio (in MSS32.DLL),
and access game data (Blizzard games use STORM.DLL to load map data from
disk). The game uses WaitForSingleObject() to sleep while waiting for I/O; if
an input event occurs, the function returns early, otherwise it sleeps for the full
duration. Without active input, the game threads spend roughly 94% of the loop
sleeping. With 22 threads to randomly choose from when auditing the game, the
odds of auditing game code modified by a Warcraft III cheat is relatively low when
compared to the simple Homebrew game cheats analyzed earlier.

53
1000
1200
1400
1600
1800
Average Audits to Detect Cheat
Bendik's MapHack
Kolkoo's MapHack
Revealer MapHack
Simple MapHack
Nemesis MapHack
0
200
400
600
800
10.0
100.0
1000.0
Average Audits to Detect Cheat
10.0
100.0
1000.0
Auditing Period (log10 ms)
Figure 2.9: Page hash audits required to detect Warcraft III maphack cheats.
The five representative cheats shown are easily detectable by page hashes.
Cheat Detection. Several communities are dedicated to cheating in
Warcraft III. They produce and sell numerous cheat binaries, very rarely revealing
actual source code. Advanced cheats for popular games often have price tags that
rival the purchase price of the game itself. Since cheat-software sales are at stake,
cheat authors compete to be the first to publish a cheat that works against the
newest patch level of the game. Ironically, many authors steal other authors’ cheat
codes and techniques to spread them to new communities claiming them as their
own work – there truly is little honor among cheaters.
When this experimentation was performed Warcraft III was recently patched,
meaning a spectrum of first-to-release cheats were readily available. Each cheat
was run in isolation by hosting non-ranked Local Area Network (LAN) games to
avoid disturbing legitimate players. Fides was able to detect every cheat collected;
54
the five most prominent cheats (i.e., all original software, not variants rebranding
stolen code) being: Bendik’s MapHack which is very minimalist and reveals no
more than hidden units on the main map, Kolkoo’s MapHack which patches code
over a few pages, the Revealer MapHack which hotpatches a small number of bytes
over fewer pages but also injects code that hooks game input functions so that it
may be toggled on or off, the Simple MapHack which hotpatches a mere 61 bytes
but over a number of pages, and Perma’s Nemesis MapHack which is the prominent
success of this experiment.
Perma is viewed in many communities as the foremost Warcraft III cheat
author. His Nemesis MapHack (which he advertises as “undetectable”) is the
sequel to his infamous Zerocraft cheat which went undetectable for just short of
two years before it was discontinued because Blizzard finally obtained a copy and
developed a signature that could detect it. In an attempt to prevent Blizzard
from obtaining a copy of the Nemesis MapHack, the procedure to obtain a copy
requires one to have a profile with good standing in his home cheat community4
and purchase the cheat for
$
25. Amazingly, this is more than the current purchase
price of the game. The Nemesis MapHack has more features than the other cheats
mentioned and is heavily obfuscated to prevent Blizzard (as well as rival cheat
authors) from learning its tricks.
Figure 2.9 shows that the Warcraft III cheats are detected using upwards of
two hundred Hash Page audits, which is not surprising given that the game has 22
threads and sleeps roughly 94% of the time. At this scale, one can see a trend that
the number of audits required to detect a cheat tapers off. This occurs because at
larger audit frequencies the inter-arrival randomness grows to the point where the
randomness (between ±5% of the frequency) surpasses the loop duration of 15.6ms
so that the probability of detection asymptotically approaches the probability to
detect the cheat with a single random audit.
4We used an account that had been established for previous anti-cheating research.

55
The probability of detecting a cheat grows with respect to the quantity of
changes that the cheat makes to the game (i.e., a cheat that modifies more code
pages becomes easier to detect). This makes the feature-rich “undetectable”
Nemesis MapHack among the easiest cheats for Fides to detect. Fides did not
need to reverse engineer it. The number of audits required to detect Nemesis
taper off somewhere around 300, meaning it can be detected in about 5 minutes
when auditing at a leisurely frequency of once per second, or in 20 seconds when
auditing at a more aggressive frequency of once every 100ms. In contrast, Bendik’s
MapHack which few changes to the game would take 22 minutes to detect when
auditing once per second, or 2 minutes to detect when auditing once every 100ms.
Memory Layout Commonality
While benchmarking the Fides approach, we observed that commonly loaded
libraries to common locations (specifically on non-ASLR systems) could spare
the Controller from generating and storing new emulation state for each client.
This experiment evaluates how consistently game-client memory is laid out in a
commercial game (i.e., Warcraft III again) to show that significant potential exists
for reuse of emulation state.
A small program was implemented to execute the game client and then measure
its virtual memory layout. The game client’s memory regions are flagged with
read, write, and executable permissions when allocated and may be altered during
execution. In general, virtual memory is either code (i.e., flagged as executable),
static data (i.e., flagged readable but neither writable nor executable), or dynamic
data (i.e., flagged readable and writeable but not executable). Of particular
interest to this evaluation are memory regions that should remain constant
throughout gameplay: code and static data. Those regions are stored as page
hashes during emulation so any commonality between clients means fewer hashes
need to be stored. In contrast, dynamic data regions require server corroboration
so the associated emulation state is already reduced to only meta-data.
56
50%
60%
70%
80%
90%
100%
Allocation Percentage
Code
Static Data
Dynamic Data
0%
10%
20%
30%
40%
0x00000000 0x20000000 0x40000000 0x60000000 0x80000000
Allocation Percentage
Memory Address
Figure 2.10: Warcraft III virtual memory usage. The percentage (stacked) of
each type of page usage within 512-page regions. Here dynamic data includes
reserved, but presently unused memory.
The program ran the Warcraft III game client 1,000 times through the same
map on two different Windows XP SP3 machines. Figure 2.10 shows the memory
layout by type in Warcraft III. The first observation is that the memory space is
truly sparse: less than 10% of the available virtual memory is used. Many libraries
select default base addresses that are far from other libraries so that they will not
likely conflict when loaded, resulting in the spread out code observed.
Typical of most Windows applications, the executable entry point is located
at address 0x40000 which accounts for that spike of code amid the static and
dynamic data. Below it resides some language localization files and stack space
for each game thread. Above the entry point is the heap, which in this game is
predominantly used for map data.
57
Memory Type Machine #1 Machine #2 Both
Code 1.4% 1.4% 1.4%
constant 100.0% 96.2% 90.8%
Static Data 1.0% 1.0% 1.0%
constant 98.8% 94.6% 87.2%
Dynamic Data 3.9% 3.0% 3.5%
similar 29.5% 55.6% 11.3%
Reserved Memory 3.5% 3.4% 3.5%
similar 64.6% 93.5% 49.4%
Unallocated 90.3% 91.2% 90.6%
Table 2.4: Memory layout commonality. Memory allocation is broken down by
type. The table shows how consistently each type is laid out.
Table 2.4 presents the memory breakdown for the 1,000 runs on each of the two
machines and how they compare to each other. The results show that code and
static data occupy 1.4% and 1.0% of virtual memory, respectively. As expected,
both code and static data are allocated consistently on the same machine and
are roughly 90% consistent between the two machines. This confirms that indeed
significant portions of emulation state (i.e., hash page digests) may be reused
between sessions and between clients.
Dynamic data and reserved memory (i.e., virtual memory set aside but not
yet allocated on physical storage) each occupy roughly 3.5% of virtual memory.
Dynamic data predominantly represents map data and reserved memory is saved
for map data that has yet to be loaded. The range and size of these dynamic data
sections vary considerably between executions and machines. This may be partially
due to the fact that in each game execution, the player’s homebase is randomly
assigned to one of eight possible locations and means different map data may be
loaded initially. Map data is essentially static since it is loaded from static game
files on disk and it could be loaded to specific locations and have write-permissions
removed so that it can be audited by page hashes.

58
2.4.2 Limitations
This section recognizes the following limitations to the Fides approach:
Attacks on the Auditor. Cheaters own the systems on which they
cheat so they may tamper with any component to evade detection. Likely an
adversary would directly target the Auditor by replacing the results it returns to
the Controller with clean measurements. This is an easier problem to handle than
securing the game client itself because the Auditor is less complex. Furthermore,
a number of techniques infeasible for protecting the game client could be used
to bolster Fides against such attacks including directly accessing memory, audit
entanglement, Auditor and client polymorphism, or leveraging tamper-resistant
coprocessors. These techniques are elaborated further in the discussion.
Elementary Measurements. While the measurements presented in this
paper detect current and foreseeable cheats, cheaters may evolve methods that the
measurements cannot detect efficiently. It is important to note that Fides is not
restricted to the four presented measurements and can easily be extended to include
new measurement types. In particular, one might consider memory watchpoints
and code timing if hardware support became available. Memory watchpoints would
observe how frequently code or variables are accessed and could detect cheats that
operate external to the game client through unauthorized data reads. Similarly,
code timing would observe abnormally long execution of game functions or the
entire gameplay loop. This can detect cheats that manipulate the game through a
debugger or virtual machine.
Timing Difficulties. Network latency and jitter add timing inaccuracy at a
resolution several magnitudes greater than that which code executes at, preventing
any remote software integrity system (not only Fides) from predicting a client’s
exact execution state upon receiving an audit packet. Such systems are thus forced
to validate the correctness of whichever state the client software is observed to be
in rather than demand that the client be in precisely one state.

59
External Cheats. Fides focuses on cheats that affect the proper execution
of the game client and does not address cheating external to it. For example,
online poker cheaters collude by sharing private information (i.e., the cards in their
hand) through side-channels in order to defraud legitimate players. Other cheaters
employ robotic peripherals to automate repetitive or precision-based gameplay
(e.g., the Guitar Hero robot [125]). Cheats that never modify the client cannot be
caught by detection of anomalous client execution but instead may be caught
by detection of anomalous player behavior (e.g., observing wins correlated to
unusual gameplay, abnormal grouping patterns, highly erratic player skill, or even
abnormally precise game input).
Poor Game Design. Cheat detection may not address behavior that is
against the spirit-of-the-game yet is possible without ever modifying the client
or employing external devices. For example, many networked games incorporate
“player achievements” that are noteworthy in-game objectives (publicized when-
ever a player accomplishes one) but when implemented improperly are trivialized
by players who design custom levels to do so. Such problems should be solved by
better game design, in this case disallowing players from attaining achievements
while playing custom levels vetted by the game developer.
Macros and Keybindings. Many developers relax the prohibition on
automation by allowing players to customize their game interfaces with macros
and keybindings for authorized game commands. Games like World of Warcraft
use execution-tainting mechanisms to distinguish permitted customization from
excessive automation [126]. For accurate anomaly detection, these interface
customizations should be isolated to well-defined regions of client memory where
they will not interfere with audits of game code or data. Indirect jumps that access
them can be easily validated if the jumps are restricted into those isolated regions.
Furthermore, the client must commit to the customizations (i.e., send them to the
server) before using them so that the server may verify their legality and Fides
may validate that they are not modified at inappropriate times during gameplay.

60
2.4.3 Discussion
Future Work
There are a number of techniques that could be explored to strengthen the Fides
approach (specifically the Auditor) against evasion by the cheater.
Direct Access. Locating the Auditor within the client process provides
direct access to its virtual memory without relying upon system functions like
ReadProcessMemory(). This sidesteps attacks that hook those system calls in
order to return bogus measurements. At the same time, eliminating function calls
for reading process memory speeds up the Auditor meaning that audits which
suspend client threads will have even less impact on performance. However, this is
only a partial solution since the Auditor will become easily preemptable and thus
vulnerable to cloaked cheats like the Governor [51].
Audit Entanglement. Fides may authenticate audited data by entangling
the Auditor’s measurement routines with time-sensitive cryptographic computa-
tions, similar to Pioneer [100]. Each entangled computation would depend upon
a random nonce (sent as part of the audit request) and be constructed such
that modification to the measurement routine must alter either the correctness or
timeliness of the generated entanglement token. Using entanglement, an Auditor
response would only be valid if both the measured data and the correctly computed
entanglement token are returned within the time limit. Invalid or late entanglement
tokens would indicate the client’s use of cheat software.
Auditor Polymorphism. Rather than support defined measurement types,
the Auditor could instead accept and execute short auditing routines crafted
arbitrarily by the Controller. The measurement types and targets may be changed
surreptitiously at any time, dynamically adjusting how the client is audited.
Cheaters cannot evade detection by simply using static virtualization; they must
understand precisely what each audit routine is measuring and formulate coherent
responses (through their own client emulation).

61
To effectively manipulate data collected by the Auditor, cheaters must
completely interpret every audit routine and emulate legitimate client operation
sufficiently to generate correct responses on the fly. This is challenging for cheaters
to accomplish in a timely fashion, especially when auditor polymorphism is used in
conjunction with audit entanglement. Cheaters who fail to completely cloak their
changes or virtualize the entire system will be detected by the first measurement
that cannot be spoofed, similar to how “undetectable” virtualized rootkits (e.g.
BluePill [95]) are detected when unpredicted system functions (like cpuid() [92])
behave erratically.
Auditor polymorphism would make the Fides approach more like the Warden
system [76] in that frequent updates to client-side detection software keeps
cheaters on guard. This allows the system to remain agile enough to adopt new
measurements in order to detect new cheat techniques.
Client Polymorphism. Using this technique, the game server periodically
instructs the game clients to shuffle their memory layouts by rebasing loaded
libraries to arbitrarily specified new locations. This changes the structure of the
client without affecting legitimate operation, dynamically adjusting how the client
must be targeted by cheats. Runtime library rebasing may be done similarly to
how in-memory or reflective DLL injection [39, 104] loads libraries from within the
process’ memory (i.e., not from disk) at runtime.
Each time a new client layout is specified, cheaters must adjust their software
accordingly, particularly code hotpatching long jumps or code overwritten during
the rebasing. Cheaters attempting to manipulate measurement data must quickly
correct their own emulation and system virtualization to remain consistent with
legitimate clients. The Controller has an advantage since it can update its emulated
state before making the changes known to clients, however, cheaters cannot respond
until after they know the layout changes. Additionally, this technique could reduce
emulator state by dictating the same new layout for all clients using common
libraries.
62
CPU Memory
Controller
Memory
Auditor (ME) I/O Controller Network
Controller
Peripherals Interfaces
OS
Game
Figure 2.11: One functional location of Intel’s Manageability Engine (ME). In
the memory controller, it has unimpeded access to all game memory and I/O.
Hardware-Based Stealth Measurements. The Fides system was
designed so that the Auditor could leverage a hardware component within the
client machine for providing tamper-resistant measurements of the game. The
hardware component must be isolated from the host processor so that it cannot
be affected by the system owner, yet it must have sufficient access to measure the
system to determine if cheat software has compromised the game client.
The Intel Active Management Technology (AMT) [56] platform is one such
suitable hardware component. Figure 2.11 shows the current architecture of the
AMT, specifically the location of the trusted Manageability Engine (ME). While
the ME is not a full-blown CPU (i.e., it lacks the speed and features necessary
to run the game client), it has been used to detect rootkits [32] and peripheral
automation cheats [98]. The ME would be a good location for the Auditor because
it has access to the entire contents of physical memory, it is controllable through a
secure (i.e., authenticated and encrypted) network connection, and it only executes
signed code thereby assuring players that their privacy is safe.
While challenges remain to employing such a hardware component (e.g., register
and memory caching, and virtual memory to real memory mapping), hardware
support could facilitate additional measurements for detecting more subtle forms
of cheating. Specifically, the addition of memory watchpoints and code timing
would allow the Auditor to observe unusual memory accesses in terms of timing,
source process, and frequency.

63
2.5 RELATED WORK
Anomaly-Based Detection. Anomaly-based detection has been explored as
a solution in research to many strong security problems like intrusion and rootkit
detection [55, 71, 88, 120]. In such applications, the detector must understand
the characteristics of a complex multi-faceted system. Extensive knowledge is
required to perfectly characterize all legitimate operation, so these approaches
instead accept a small misclassification rate in exchange for more manageable state
and quick detection results. In contrast, the cheating problem has a limited search
space (i.e., the well-defined game client software) which can be efficiently learned
using static analysis, and the game application tolerates slower adversary detection
over the misclassification of legitimate players.
The branch of research most related to our approach is anomaly-based
application integrity checking [16, 34, 50, 99, 119], which validates application
behavior from the vantage point of a secure operating system. These approaches
work well when an adversary has difficulty infiltrating the host system, however,
they are inappropriate for the cheating problem where the adversary owns the
machine and can readily alter the operating system to disable detection tools.
Other research applies anomaly detection to player behavior [19, 44, 74, 129].
These approaches detect suspicious player behavior (e.g., colluding) without
verifying game state by instead analyzing high-level player behaviors and win-loss
statistics. While those approaches can be used in combination with our approach
or integrity-based approaches, they are very game-dependent and require a deep
understanding of the game rules, game maps, and what normal behaviors look
like. Acquiring an understanding of “normal” player behaviors often requires a
large volume of trusted gameplay samples and can be expensive in terms of human
involvement. This difficulty is exacerbated in persistent games (such as massively
multiplayer online games) where the popularity of in-game activities changes over
time (sometimes in unpredictable ways) as the virtual world evolves.

64
Anti-Cheat Software. Many game developers use anti-cheat software;
Blizzard games (e.g., Diablo II, StarCraft, Warcraft III, and World of Warcraft)
use the Warden system [76] and Valve games (e.g., Counter-Strike, Left4Dead, and
Team Fortress) use the Valve Anti-Cheat (VAC) [115]. Numerous other games
(e.g., Battlefield 1942, Call of Duty, and Quake) support the use of third party
anti-cheat systems like PunkBuster [31]. Unfortunately, existing commercial anti-
cheating systems use signature-based detection, promiscuously scanning each and
every process on the client machine which leads to accuracy errors and real attacks
on the detection mechanisms [85].
Trusted Computing. Trusted computing approaches leverage secure
cryptographic software, virtual machines, or hardware components to verify that
the application code is operating as intended on the remote machine. Sometimes
referred to as a “root-of-trust,” the trusted system is used as the starting point to
assure the integrity of the application. Prominent systems include Terra [41], the
TPM architecture [96], and Pioneer [100]. While trusted computing approaches
quickly discover changes made to the application, they add overhead to the
application’s execution that may be prohibitively expensive for the real-time
demands of responsive gameplay. Instead, trusted computing approaches could
be used to guarantee the proper operation of the Auditor which is smaller, has
fewer real-time requirements, and can be used to audit any game.
Proof-of-Correctness. Proof-of-correctness approaches focus on cheat
prevention rather than cheat detection [10], ensuring that the game client is running
according to game rules and physics. While proof-of-correctness approaches
prevent some unauthorized manipulation of client state, they can only slow or
frustrate cheating efforts since the adversary controls the hardware and operating
system of the machine. Even for console gaming systems, where the developer has
a better understanding of and design input regarding the underlying hardware,
cheating has proven impossible to eradicate and detection remains a vital tool at
the game developer’s disposal.
65
2.6 CONCLUSION
This chapter investigated the problem of detecting automated and adversarial
behavior in the context of detecting cheaters in multiplayer online video games. In
this application, cheaters own the hardware that the client software runs on and
as a result have a clear advantage over game developers in terms of control over
system operation. The research contributions of this chapter are:
We clearly defined the cheating problem affecting multiplayer online games
and identified properties that distinguish this problem from other traditional
security problems. The chief differences are that cheats target specific, well
understood software, do not demand urgent response, and inflict damage
that is easily repaired once discovered.
We enumerated the state-of-the-art in cheating methods. Cheat techniques
range from data manipulation to code injection and execution manipulation.
Most cheats do not leverage hardware techniques such as register manipula-
tion or hardware debugging at present, but that may change in the future.
We proposed and evaluated a novel anomaly-based cheat detection approach
for multiplayer online games through remote validation of client execution.
The Fides system comprises a server-side Controller which specifies how and
when a client-side Auditor measures the game client. To accurately validate
measurements, the Controller partially emulates the client and collaborates
with the game server. In evaluation, we showed that Fides is able to efficiently
detect several existing cheats including one advertised as “undetectable.”
Likely, the Auditor may become the next target of attack by cheaters. Future
work involves research into a number of techniques that may bolster it against
attack, including locating it on secure tamper-resistant hardware, entangling it
with cryptographic computations, or adding run-time client polymorphism.

66
While an application service provider may possess an efficient automation
detector like Fides, it may not be sufficient to identify every adversary. Improved
adversary identification may require combining multiple detectors. It may also
involve cooperation between service providers, whether those service providers
support similar or different applications. It may also involve input from clients.
The next chapter discusses how to combine multiple detectors to better identify
adversaries. This research focuses on an approach which treats clients as detectors
but also explains how the approach may be extended to leverage strong detection
systems like Fides.

67
Chapter 3
ADVERSARY IDENTIFICATION
3.1 INTRODUCTION
The previous chapter explored an approach for definitive detection of automation
and software tampering. Like many real-world adversaries (e.g., in sports, business,
and daily interactions), network adversaries find that behaving outside the defined
rules is beneficial so rather than be deterred by accurate detection methods,
they instead adapt to avoid the most prominent detection method. As a result,
application service providers must resort to multiple means to detect adversarial
automation. How to aggregate detectors to make a definitive decision is an
important research problem. This chapter investigates a method to do this.
Despite the fact that accurate detection methods exist, rule enforcers have
limited resources and cannot observe all infractions. Legitimate participants are
obliged to help by reporting malicious behaviors but they are often intimidated
into silence. In team sports like cycling, this is known as the doping dilemma [102]:
athletes who play by the rules are intimidated by teammates and trainers into
remaining silent while athletes who break the rules continue to get ahead.
Participants expect rule enforcers to catch and punish the rule breakers, yet
without their participation that does not always happen. Our approach is to
leverage the power of the masses as accurate detectors to allow them to congregate
exclusively with like-minded individuals. This approach would allow legitimate
participants who want a level playing field to disassociate with rule breakers and
compete against legitimate competitors. In such a system, humans are effectively
very abundant, yet individually inconclusive adversary detectors.

68
Given a collection of adversary detectors that may individually be inconclusive
or untrustworthy, the next research challenge addressed by this dissertation
involves how to best combine detectors to increase the likelihood of a predictive and
conclusive result. Specifically, this research seeks a single metric that ranges from
“not adversarial” to “adversarial” (i.e., a probability ∈[0.0,1.0]) to describe each
client. This provides an analog control that can operate disincentive mechanisms
based on how adversarial or automated each client’s behavior appears.
This chapter explores this research challenge by federating a set of homogenous
independent detectors. This work is realized through the creation of a reputation
system for multiplayer online games. Again, the multiplayer online game
application is ideal for research since well established disincentives exist. The
application is particularly suited for research into reputation systems because the
players themselves are abundant detectors and require little game developer effort
to harness. By treating every player’s peers as detectors (i.e., their observations
provide clues regarding the maliciousness of other peers) the most basic disincentive
follows: players will dissociate with and cease to play with players who are known
to behave badly.
Legitimate players have in some cases created guilds whose primary goal
is to locate automated gold farmers within massively multiplayer online games
through word-of-mouth reports. Provided with better tools like a reputation
system, those guilds may become more efficient at tracking automated players. By
analyzing the resulting social patterns, the game developer may focus man-powered
investigation on the most suspicious players, identifying not just antisocial players
but also those players employing automation to cheat. This allows the developer
to institute harsh disincentives like systematically segregating adversaries from
legitimate players, confiscate ill-gotten gains, and impose temporary or permanent
bans. Furthermore, if game developers insist on using signature-based automation
detection, a reputation system would give developers a more efficient method for
finding and cataloging cheats being used.

69
3.2 THE PROBLEM WITH ONLINE BEHAVIOR
Like the users of many other network applications, players of multiplayer online
games interact with each other using aliases which may be graphically represented
by customizable avatars. An alias hides the player’s real-world identity and allows
them to be immersed in the virtual world. Players invest considerable time, effort,
and even money improving the noteworthiness of their in-game persona – taking
pride in any renown that they achieve (colloquially referred to as “e-fame”).
Unfortunately, the anonymity provided by aliases also leads to a number
of antisocial behaviors [113]. Of particular concern are players who cheat by
automating the acquisition of wealth and items, or automating their actions
to misrepresent their abilities and receive false recognition from peers. Other
examples include players who scam their peers (often exploiting a poorly designed
facet of the user-interface) to steal virtual wealth or items. Sometimes powerful
players “grief” weaker players by playing in a manner that makes the game
unenjoyable for them (e.g., “corpse-camping” a victim who must resurrect at the
same location). Disgruntled players harass their peers through in-game text or
voice chat. Some players simply act selfishly with poor sportsmanship (e.g., “rage
quitting” the game when it greatly inconveniences their peers).
Although these behaviors are against the spirit of the game and many of its
rules, limited policing resources mean that only the most grievous infractions
are ever investigated. Often the virtual community is so large that a malicious
player may negatively affect many peers before sufficient complaints are raised
to warrant developer attention. Even then, the game rules regarding in-game
actions, especially social behavior, are so vague that infringing players are given
several warnings before incurring significant repercussions. Innocent players are
thus posed with a dilemma: either they only play with peers they know and trust
“in real-life” (i.e., from outside the game) or they must risk playing with peers
they meet in-game who may behave poorly.

70
3.2.1 The Case for Reputation Systems
Reputation systems are commonly used in Web applications where the service
provider acts as a broker between participants. Often those parties are selling items
or services as independent vendors (e.g., eBay auctioneers and Amazon affiliates).
Increasingly, reputation systems are being used in applications where clients do
not have commercial relationships with each other, but instead judge the veracity
of information shared by one another (e.g., Slashdot.org forums).
The appeal of such systems is that they grant clients self-determination about
who they will interact with or trust, yet are relatively simple for service providers
to implement. At the same time, reputation systems indentify clients who exhibit
exceptionally negative behavior so that moderators may efficiently investigate
them. This reduces an application’s reliance on trouble-ticket systems which
preoccupy game moderators with assuring complainants that the perpetrators
are being investigated rather than focusing all their efforts on investigation. As
discussed in more detail later, reputation systems could incorporate information
from other sources, such as an anomaly-based detector.
Definitions
The complete set of game players is denoted by P layers. A rating is the value
corresponding to the opinion of one player (the rater,i∈P layers) about another
player (the ratee,j∈P layers) and is denoted by ri,j ∈[−1.0,1.0], where a negative
rating corresponds to dislike or distrust, and a positive rating corresponds to like
or trust. A rating of 0.0 represents an unknown or neutral relationship.
The ratings for a given ratee jare combined to formulate their reputation,
denoted by Rj∈[−1.0,1.0]with a similar interpretation of affinity. A rater’s
reputation dictates how influential their ratings are in determining the reputation
of their peers: disliked raters will have little or no influence while liked raters will
have more influence.
71
Figure 3.1: Addition of PlayerRating to the game system at large. Each client
using a PlayerRating agent combines ratings from liked (i.e., trusted) peers to form
a personalized view of reputations regarding all other peers.
3.3 THE PLAYERRATING APPROACH
Our approach is the PlayerRating system1which is, to our knowledge, the first
distributed reputation system specifically designed for online games. The intuition
behind the system is that a person trusts the opinions of their friends and friends-
of-friends about unmet peers. Furthermore, each opinion is weighed based on their
respect for the friend claiming the opinion; close friends will have more influence
than mere acquaintances. The system (shown in Figure 3.1) has participating
players run PlayerRating agents within their game clients. Each agent enables
a player to rate peers and leverage ratings from liked peers to determine the
reputability of unmet peers. The player-specific reputations are bound to in-game
aliases (preserving real-world anonymity) and provide a best effort prediction of
the type of behavior one might expect from one’s peers. This allows well-behaved
players to more easily congregate and avoid antisocial players.
1This research appeared in NetGames 2009 [65].

72
The novel features of PlayerRating are:
Experience Sharing. While some in-game mechanisms exist for recording
social relationships (e.g., friend-list and ignore-list) that data is never propa-
gated. PlayerRating transparently shares player relationship data using strictly
authenticated in-game channels to avoid Sybil attacks [26]. Sharing data allows
a player to warn peers about malicious peers. In return, peers rate other peer’s
behavior which allows the player to learn of malicious peers without having to
personally encounter them. This reduces the likelihood that a legitimate player
will inadvertently interact with a malicious peer.
Personal Perspective. Using shared relationship data, PlayerRating
locally learns the game’s social network from each player’s perspective: players
determine where they fit into the network by rating peers that they like or dislike.
The system propagates trust through positive ratings to predict the player’s
perceived reputation of peers that they have yet to meet. As we show in the
evaluation (and have observed in practice) the system works well without knowing
every rating, but improves as more ratings are learned.
Fine Granularity. Existing in-game social tools are too coarse, restricting
player relationships to like, dislike, or ambivalence. In the PlayerRating system,
player relationships are analog, allowing a player to express their like or dislike
of each peer to different degrees on a Real-valued spectrum. As such, the
PlayerRating system could sort and better match players for group play, and focus
expensive non-automated policing resources on the most disruptive players.
Distributed Operation. The PlayerRating system operates in a distributed
fashion: each participating player runs a PlayerRating agent within their game
client that determines the reputation of their peers, accounting for their personal
perspective based on who they like and dislike. Participation is optional in the
sense that a player may choose not to rate their peers, however, they cannot
prevent their peers from rating them. Furthermore, a player must accurately rate
their peers before the agent can accurately calculate meaningful peer reputations.
73
F1
self
F2
+
A1F3
F4F5
A3
A2
+
−
Figure 3.2: Example social network of players. The observer (self) belongs to a
clique with friends F1and F2. Friend F1dislikes A1so the observer will probably
also dislike A1and her clique. Friend F2likes F3so the observer will probably like
F3and her friends F4and F5, although with less certainty.
Assumptions
An assumption underlying all reputation systems is that past performance is a
reliable indicator of future behavior. However, another assumption at the core
of reputation systems is that players may reform and improve their conduct at a
later time although this will not excuse past transgressions. The player population
forms a weighted directed graph (like the example shown in Figure 3.2) where
each vertex represents an individual player (uniquely identified by a player ID) and
edges represent ratings. The following assumptions are made:
Ratings are subjective. Each player is allowed only one rating for each peer
yet the rating should encompass the rater’s perception of every interaction
with the ratee. How the rater judges interactions and assigns ratings is
subjective and entirely up to them. To accommodate new interactions, a
rating may be updated or withdrawn by the rater at any time.
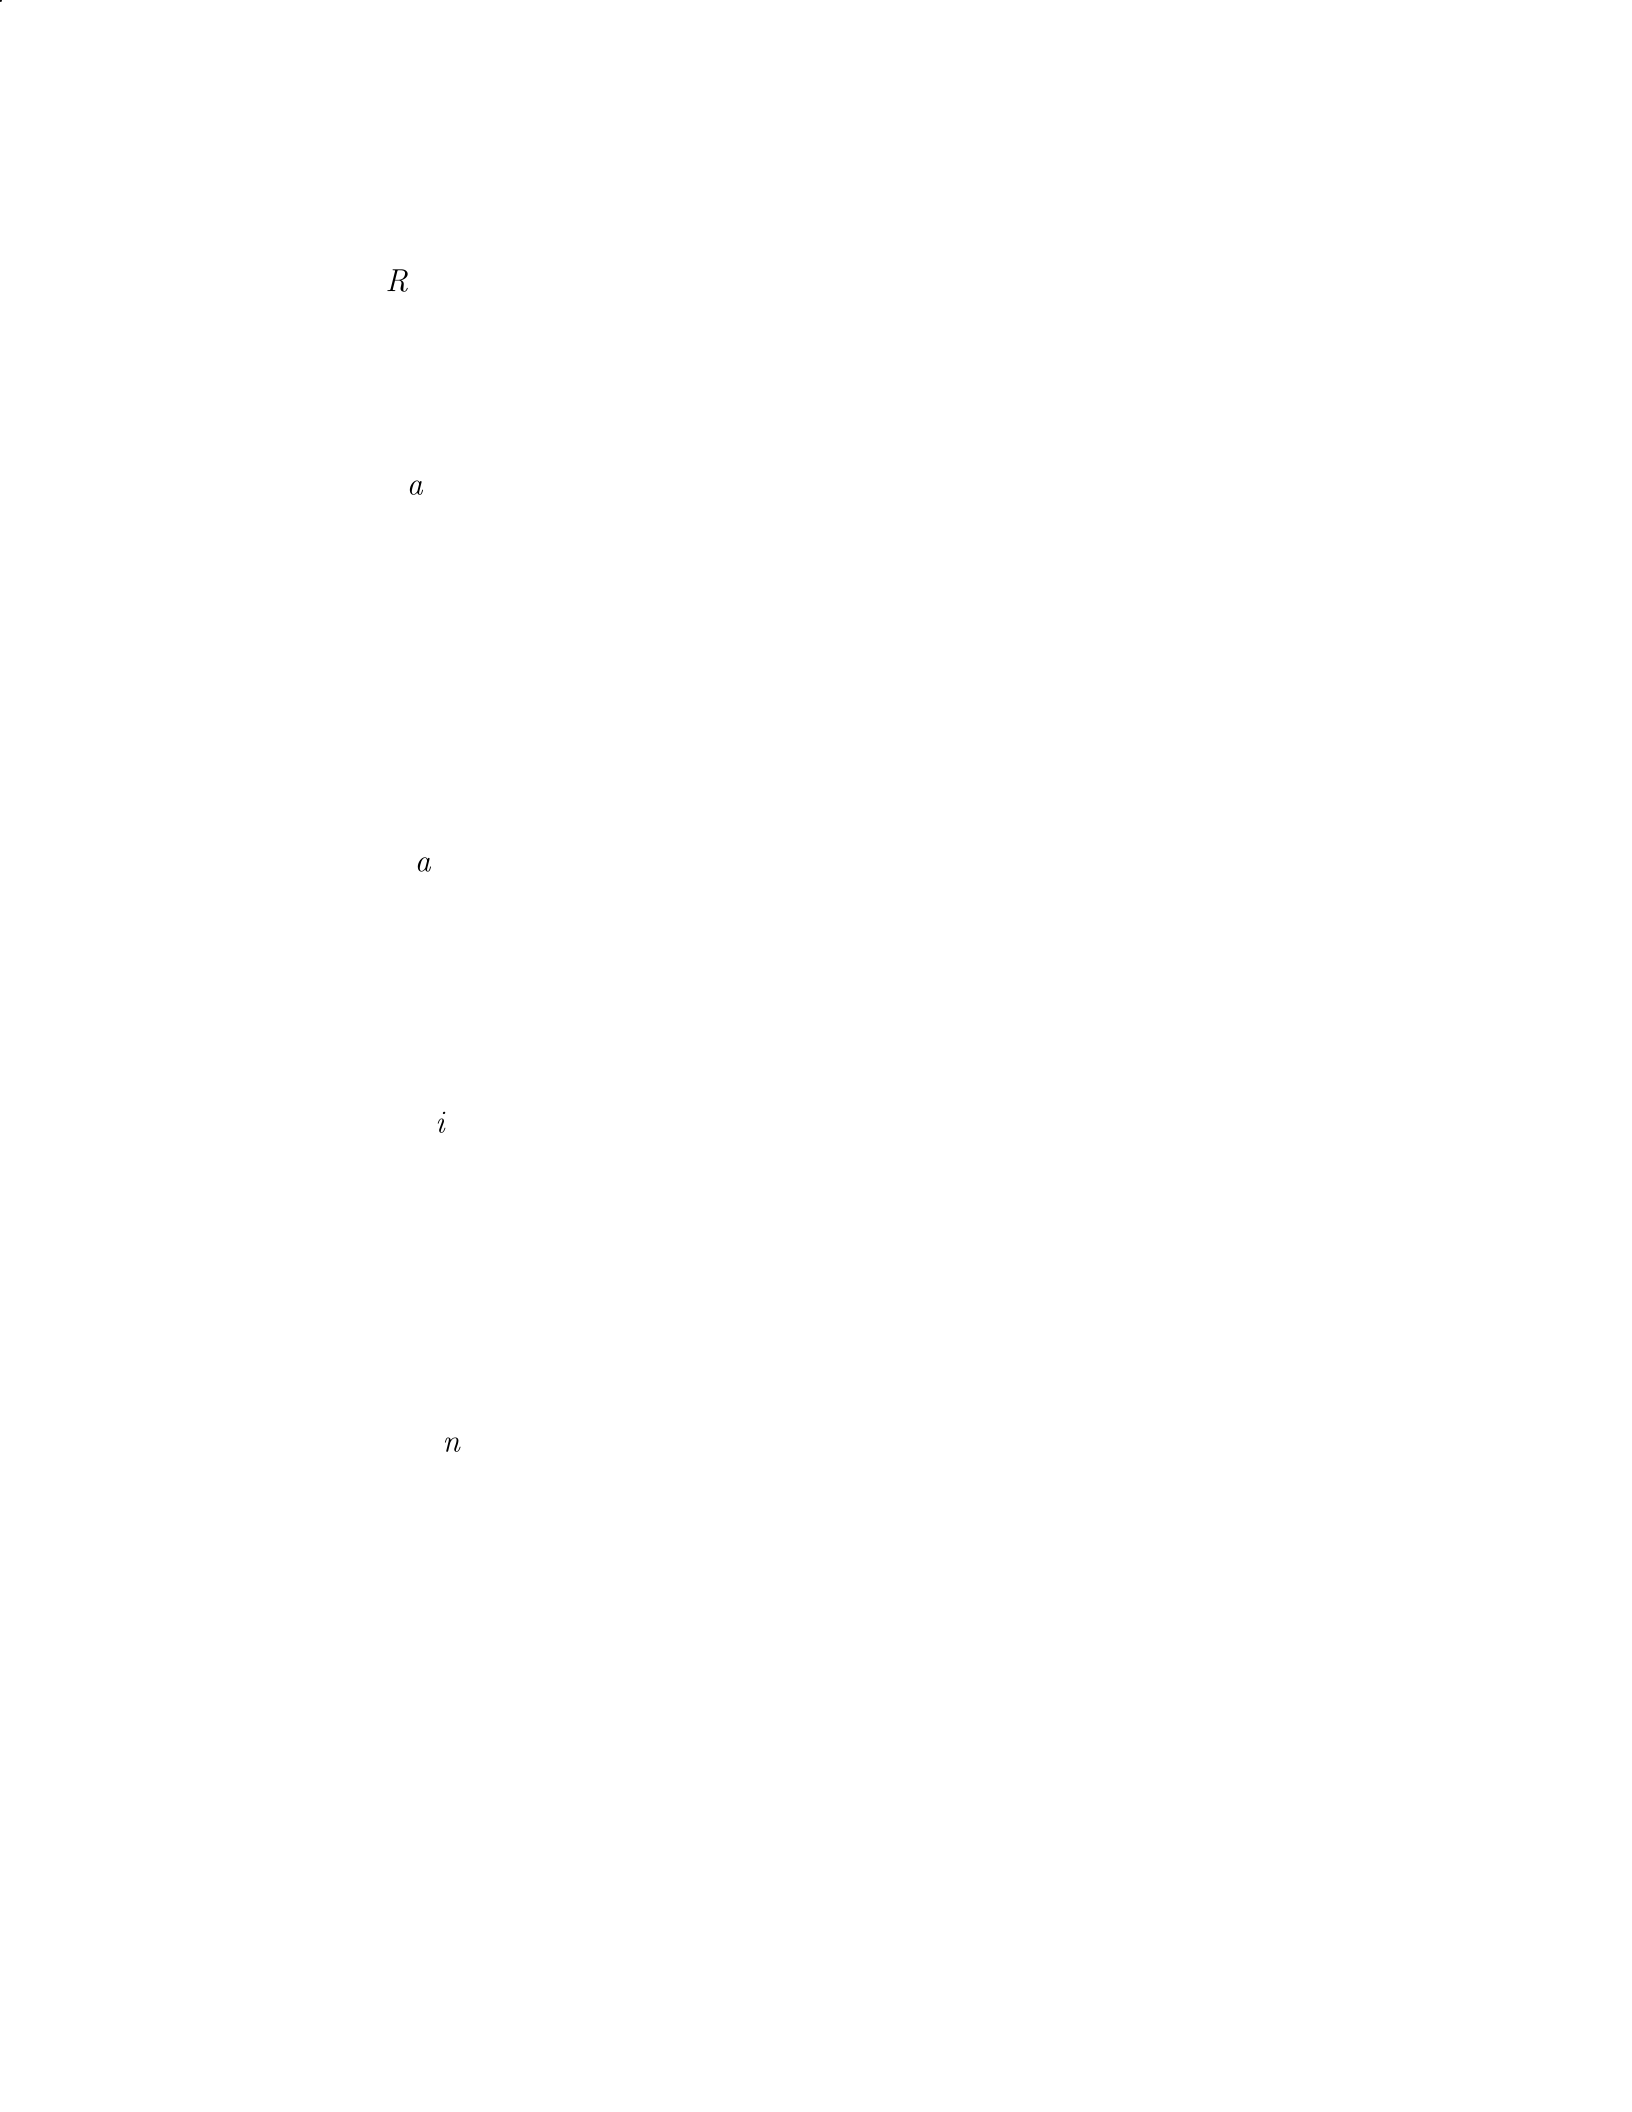
74
Ratings are asymmetrical. A related assumption is that any two players may
have different opinions of each other and their peers. Even the very best of
friends often have different opinions regarding their peers.
Raters are authenticated. Interplayer communication passes through the
game server in practically all online games. At the server, each message
is authenticated with respect to the sender’s (i.e., rater’s) player ID. For
this reason, the approach only accepts firsthand ratings and does not accept
“hearsay ratings” (i.e., forwarded ratings) since they cannot be authenticated
in the same way.
Players are self-esteemed. It is assumed that all players always view
themselves with the highest regard: as absolutely likeable and trustworthy
so Rself =1.0. Similarly, ratings from peers about themselves (i.e., ri,j where
i=j) are ignored since they will always be 1.0.
Positive ratings are transitive. Insofar as positive ratings represent trust,
positive ratings and reputations are transitive. Specifically, a peer trusted
by a trusted peer (i.e., a friend of a friend) becomes trusted, albeit with less
certainty. The opposite may not be true, so the ratings from distrusted peers
are not necessarily useful.
Ratings follow a power-law distribution. Players will self-organize following
a power-law distribution [2] like other social systems [9, 15, 72, 93]. Much
of the graph will be sparse as most players will create few ratings – even in
systems with monetary incentive (e.g., eBay) only 60% of users ever generate
ratings [25]. However, the power-law-based “small-world” model of Watts
and Strogatz [124] indicates that a few well-connected players will result in
a short average path length between any two players (i.e., only a few degrees
of separation). These few well-connected players are fundamental for the
system to yield predictions for many of the peers a player may encounter.
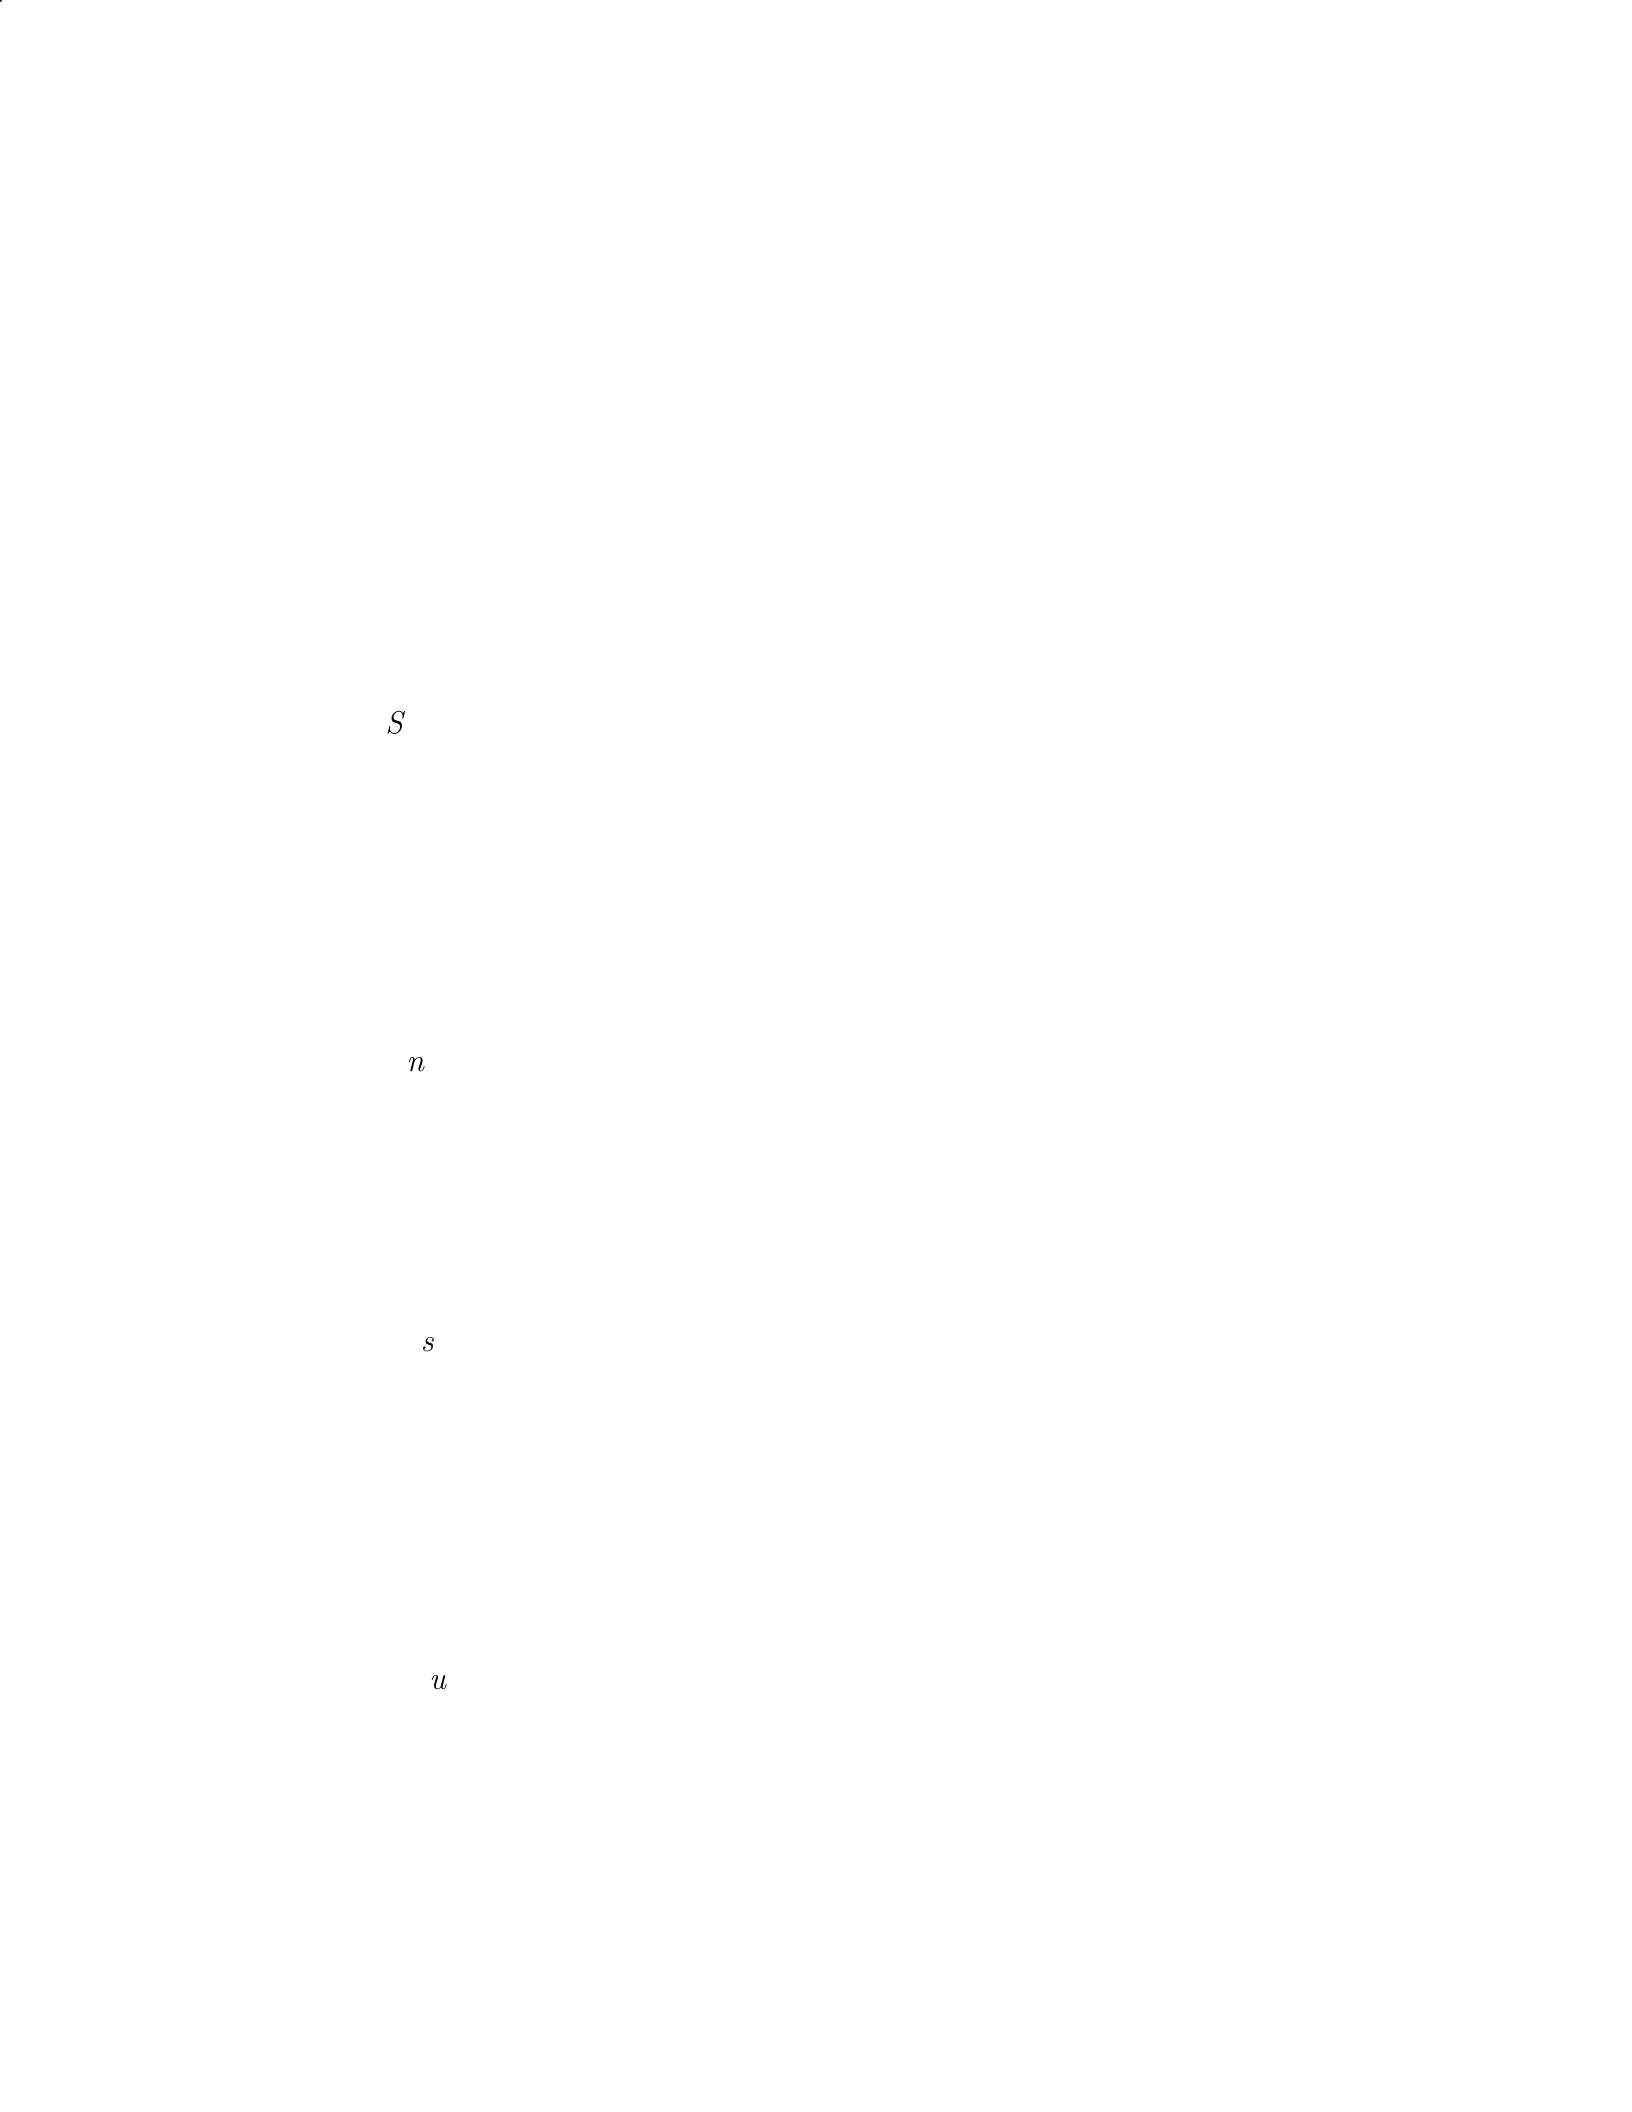
75
Design Goals
Players in multiplayer online games compete over recognition and limited in-game
resources. Often they will adopt any tools that make the game more enjoyable or
help them outperform their peers. To be suitable for this application, a reputation
system should facilitate more positive player interactions yet also prevent abuse.
Specifically the system should:
Support Incremental Deployment. As a new tool, the system must accom-
modate gradual adoption, otherwise no one will use it in the first place.
Specifically, the system must calculate peer reputations as accurately as
possible given only partial graph information. Graph updates may be sent
frequently to quickly increase the utility of the system for new adopters.
Encourage Participation. Players cannot be expected to rate every player
they interact with, yet reputation systems become more accurate with more
ratings. Related to the previous requirement, the system must encourage
participation by being easy to use and immediately beneficial.
Resist Abuse. While encouraging participation is important, preventing
abuse is equally important. Malicious players should not be able to increase
their own reputation, even through collusion. Otherwise ill-gotten reputation
could be used to slander legitimate players, or worse, lure trusting players
into scams.
Incur Minimal Overhead. As the goal of the system is to improve the overall
gameplay experience, it must not distract players at inopportune times or
degrade game performance. This means the system should mostly operate
in the background and be efficient in terms of computation, storage, and
communication.

76
3.3.1 Agent Algorithms
The PlayerRating system operates in a distributed fashion: each participating
player runs a PlayerRating agent within their game client that determines the
reputation of their peers, accounting for their personal perspective based on who
they like and dislike. This section illustrates system features using a World of
Warcraft [13] user-interface implementation [60], however, the system can easily
be adapted to other games and game genres.
The system is intentionally designed so that players may optionally participate;
they may choose not to rate their peers but they cannot prevent their peers from
rating them. Furthermore, a player must accurately rate their peers before their
agent can accurately calculate meaningful peer reputations.
Each player rates their peers when it is convenient to do so, presumably while
socially interacting with the ratee or shortly thereafter. Ratings are shared with
peers and expired periodically. Using all currently known ratings, the PlayerRating
agent calculates each ratee’s reputation as the average of every rating about them,
weighted by the influence (a function of reputation) of the corresponding raters.
Ratings are not absolute, but instead express a ratee’s reputation relative to that
of the rater. Thus, a ratee cannot be more reputable than the most reputable
rater who rated them, preventing collusion via positive feedback loops. These
calculations are done in an iterative fashion (similar to how Google PageRank [87]
operates) through repeated calls to the UpdateReputations() function.
Initialization
The Initialization() routine of a PlayerRating agent is executed only once,
when the player first installs the PlayerRating agent. The routine simply involves
zeroing all data (ratings, reputations, and related variables) and setting the player’s
own reputation Rself to 1.0. This routine need not be executed each time the player
executes the game client because the data will persist between play sessions.
77
Figure 3.3: User interface addition for rating peers. The PlayerRating rating
slide-bar was added to the peer interaction menu in World of Warcraft. The menu
is only displayed when the player chooses to interact socially with a peer.
Recording Ratings
The PlayerRating agent unobtrusively extends the game’s user interface (like the
World of Warcraft interface addition shown in Figure 3.3) to enable the player to
easily rate their peers. As defined earlier, ratings run along a single dimension
and represent the rater’s overall impression of the ratee. It is possible to extend
ratings to other dimensions corresponding to criteria specific to player skills (e.g.,
how good the player is at a particular role like being the team healer ri,j,healer)
or specific behaviors (e.g., negatative actions like intentionally killing teammates
ri,j,team killer or excessively swearing ri,j,swearing). Adding extra dimensions would
linearly increase system state, computation, and communication overheads. Some
criteria may not be useful enough to justify such overhead and warrant further
investigation.
The recording routine, RecordRating(), is used to record both personally
created ratings and those ratings disseminated by one’s peers. The freshness of
a peer’s rating ri,j is indicated by setting a corresponding time-to-live variable
ttli,j to the maximum value ttl max and it may be expired if it later becomes
irrelevant. Subsequent receipt of a previously recorded peer rating reaffirms the
peer’s commitment to that rating, so the rating is updated and the corresponding
time-to-live value is reset to the maximum value. By doing so, relevant ratings
survive the expiration process.

78
Sharing Ratings
Ratings are disseminated transparently via data channels which exist to support
game modification (“modding”) and operate similar to in-game chat channels. Only
personally-created ratings are broadcast on the PlayerRating channels. All peers
listening to the channel may record ratings. A peer may record ratings from an
unknown rater (i.e., Ri=0.0) with the idea that in the future either they or
someone they trust might determine that the rater is also trustworthy.
Communication is strongly-authenticated since each message must go through
the server which validates the sender’s alias. To mitigate flooding, the server
restricts message length to a couple hundred bytes and limits senders to a few
messages every 10 seconds. PlayerRating agents may further limit the ratings
they accept to control the growth of their knowledgebase.
Dissemination Policy. The ShareRatings() function executes a game-
tailored policy to share ratings as quickly as possible and introduce some
redundancy over time. Redundant broadcasts ensure that peers who may have
been offline during the original broadcasts are notified and reaffirm the continued
conviction in previously shared ratings (otherwise they will be expired and
discarded by one’s peers). Ratings must be shared in a fashion that minimizes
the required communication, so retransmission should not be too aggressive.
Strategies used by the World of Warcraft PlayerRating implementation include:
broadcasting a rating as it is created or updated, broadcasting the rating after
interacting with the ratee, and periodically broadcasting ratings sequentially. In
this game, ratings are broadcast to hundreds of players at once so the policy is
careful to not overwhelm recipients. Other strategies may include broadcasting
ratings randomly or through bulk broadcast when joining a zone, small server, or
playgroup. These strategies are particularly useful for First Person Shooter (FPS)
games where players join small servers of 8 to 32 players for short durations. In
this case a more aggressive policy has less risk of overwhelming recipients.
79
Expiring Stale Peer Ratings
The persistent nature of online games means that a lot can change while a player
is offline. In particular, a player’s friends and peers may continue to play the game
and interact with other peers whom the player should know about. This affects the
PlayerRating system in that one’s peers may change or revoke previously shared
ratings, or quit playing the game altogether (obviating ratings created by or about
them). To handle the possibility that the PlayerRating agent may obliviously
possess stale peer ratings, the ratings collected from peers are slowly expired to
ensure that each player’s knowledgebase only contains relevant data.
Expiry Policy. The ExpireRatings() function is run periodically with
period Tdec. The function ages ratings by decrementing their associated time-
to-live values. If a time-to-live value reaches zero, the agent has not received
any reaffirmation of the peer’s conviction behind the corresponding rating, so
it is expired and removed from the knowledgebase. Since players have accurate
knowledge of their own ratings, those ratings do not need to be expired. The
maximum lifetime of a peer’s rating which is not reaffirmed is limited to:
maximum rating lifetime =Tdec ×ttl max (3.1)
As a part of the game client, the PlayerRating agent only runs while the player
is online so rating lifetime is measured in terms of played time (referred to as
“pTime” with units “pHours”, “pDays”, etc.). While both Tdec and ttl max are
currently default system settings set to a common value for all agents, players can
individually adjust their local values to change the maximum lifetime of ratings,
thereby controlling the amount of state kept by their PlayerRating agent. To be
clear, locally modifying either Tdec or ttl max does not affect in any way how the
player’s peers store, use, or share ratings.
By associating a time-to-live value with each rating, the PlayerRating agent
is able to determine how old each rating is at any particular moment. The next
routine exploits this to infer how recent and thus how relevant each rating is.
80
Algorithm 1 Pseudocode for the UpdateReputations() function.
1: R′, w ⇐∅
2: for all i∈P layers do
3: w∆⇐Influence(Ri)
4: for all j∈P layers,ri,j ≠0.0 and ¬IsSelf(j)do
5: R′
∆⇐(ri,j ×Ri×Decay(ttli,j ))−R′
j
6: wj⇐wj+w∆
7: R′
j⇐R′
j+(R′
∆×w∆
wj)
8: end for
9: end for
10: R⇐R′
Calculating Reputations
The core routine of the PlayerRating system, UpdateReputations() shown in
Algorithm 1, uses all known ratings to determine the reputations of one’s peers.
The algorithm calculates the reputations R′and updates Ronly once the entire
graph has been processed, meaning only line 10 must be atomic. As the bulk of
the algorithm is non-atomic, the algorithm may be periodically and incrementally
executed with low priority to avoid sudden computation spikes that may result in
degraded gameplay at inopportune times.
One iteration of the algorithm loops over all the players (lines 2-9) and their
ratings (lines 4-8). Each rater’s influence is calculated (line 3) by a monotonically
non-decreasing function of their reputation: the Influence() function. In the
World of Warcraft implementation, this function calculates influence as the square
of positive reputation and as zero otherwise:
Influence(Ri)=⎧
⎪
⎪
⎨
⎪
⎪
⎩(Ri)2if Ri>0.0
0.0 otherwise (3.2)
Using this influence function, disliked and unknown peers have no influence (all
their ratings may be skipped) while liked peers have quadratically more influence.
81
For each non-zero rating where the ratee jis not the actual player running
the agent self (ratings about the player are ignored), the relative rating is decayed,
weighted, and averaged (lines 5-7) with all other ratings about the ratee used to
formulate the ratee’s new reputation R′
j. Averaging relative ratings (ri,j ×Ri)
means that a ratee cannot be more reputable than their most reputable rater and
that reputations will always fall on the same scale as ratings (i.e., [−1.0,1.0]).
The ratings are weighted by the rater’s influence.
More recent interactions (and thus ratings) are more important than older
ones. Since the rating’s age is already maintained via its time-to-live value, the
time relevance of the rating is logically calculated using the Decay() function which
should be monotonically non-increasing with respect to older (i.e., smaller) time-
to-live values. The World of Warcraft implementation uses a linear decay to avoid
large changes when ratings are expired and removed from the knowledgebase:
Decay(ttli,j )=ttli,j
ttl max (3.3)
The UpdateReputations() routine is designed so that peers who are further
away (i.e., have more degrees of separation) from the player will be more likely
to have reputations that approach zero (i.e., unknown). The reasons for this are
twofold. First, with more degrees of separation between any two people comes
less familiarity and trust, so those peers really are relatively unknown. Second,
this prevents distant peers with a few highly positive ratings from becoming
disproportionately influential with regards to the ratings they create, especially
when compared to peers closer to the player (i.e., one’s close friends).
Furthermore, the routine is designed to equilibrate to stable values for all
reputations as the routine is iterated. The routine requires iteration because the
social network is in constant flux: ratings may be added, changed, or removed at
any point in time by one’s peers.
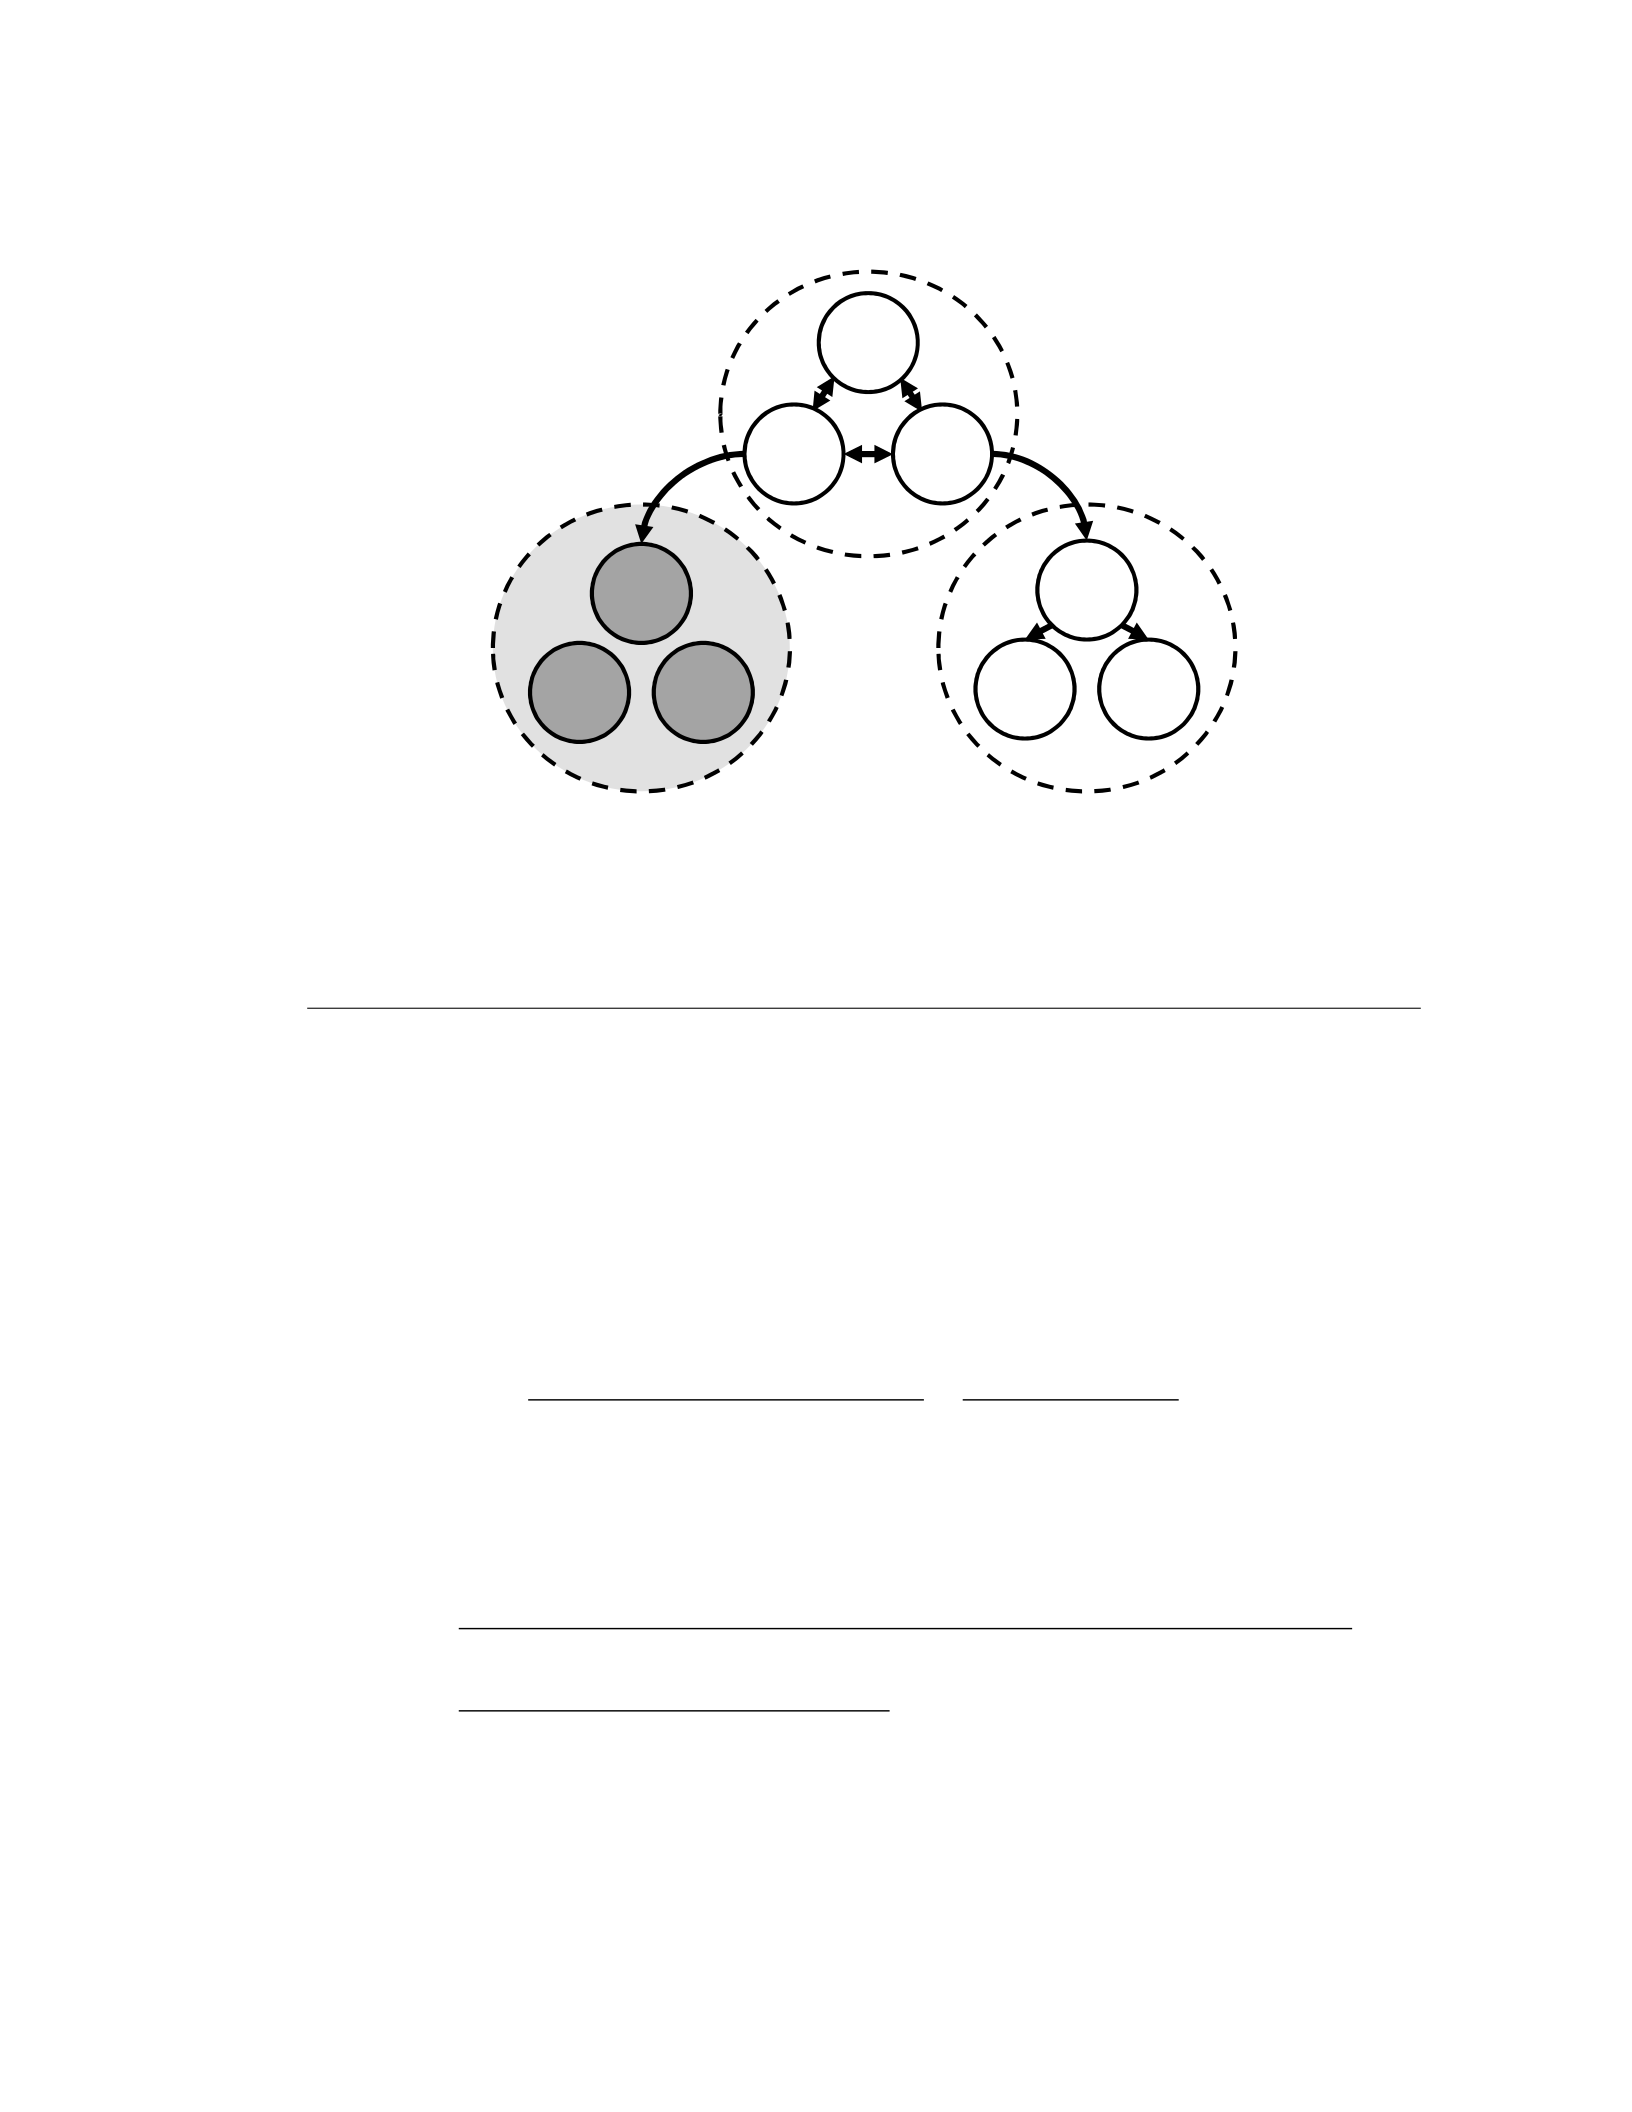
82
A1
-0.25
F1
0.5
self
1.0
F3
0.25
F4
0.125 F5
0.125
F2
0.5
A3
0
A2
0
+0.5
+1.0
+0.5
+0.5
+0.5 +0.5
-0.5
Figure 3.4: Iterating UpdateReputations() over the example social network.
Labeled edges are ratings and labeled vertices are the reputations (from the point
of view of self) achieved upon reaching equilibrium in three iterations.
Figure 3.4 numerically illustrates the example network from Figure 3.2 after
reputations calculated by self have reached equilibrium. Before the first iteration,
Rself =1.0 and all other reputations are 0. After one iteration, the two peers
closest to self have RF1=RF2=0.5 and all other peer reputations remain at 0. In
the second iteration, the PlayerRating agent calculates the reputation for A1by:
RA1=rF1,A1×RF1×Influence(F1)
Influence(F1)=−0.5×0.5×0.25
0.25 =−0.25
The positive reputation for F3is calculated similarly through F2. The reputations
for F1and F2only remain unchanged because of the example numbers used:
RF1=rself,F1×Rself ×Influence(self)+rF2,F1×RF1×Influence(F1)
Influence(self)+Influence(F1)
=0.5×1.0×1.0+1.0×0.5×0.25
1.0+0.25 =0.5
In the third iteration, F4and F5are discovered and none of the previously
calculated reputations change. At this point, the network is discovered as fully
as possible given the two ratings self created.
83
Figure 3.5: Peer reputation displayed in a tooltip. This World of Warcraft tooltip
is displayed when the player places the cursor over the peer’s character.
Reputation Lookup
The LookupReputation() function simply returns Rj(or 0.0 if the peer is
completely unknown). It is helpful to remind the player of their rating for that
peer at the same time by returning rself,j . Both lookups are inexpensive and the
information can be presented in many graphical and numerical ways, such as the
addition to a player tooltip shown in Figure 3.5.
3.4 EVALUATION
The PlayerRating system design facilitates incremental deployment since a player
does not need to rate peers and choosing not to participate does not prevent peers
from rating them. The system also encourages participation since a player can
only benefit from accurate peer predictions if they first accurately rate their peers.
This section evaluates the system in terms of meeting the two measurable design
requirements: resistance to abuse and low system overhead.
For evaluation, the system was implemented as an offline C++ application
that was optimized for speed. This allowed experiments to be run without
impacting real players and demonstrates how efficient the system might be if
implemented directly within the game client. When implemented as a user-
interface modification, it would be written in the game’s scripting language. In
World of Warcraft, that language is Lua which roughly uses the same memory
footprint but executes at 1
30 of the speed of C++ for equivalent programs [20].
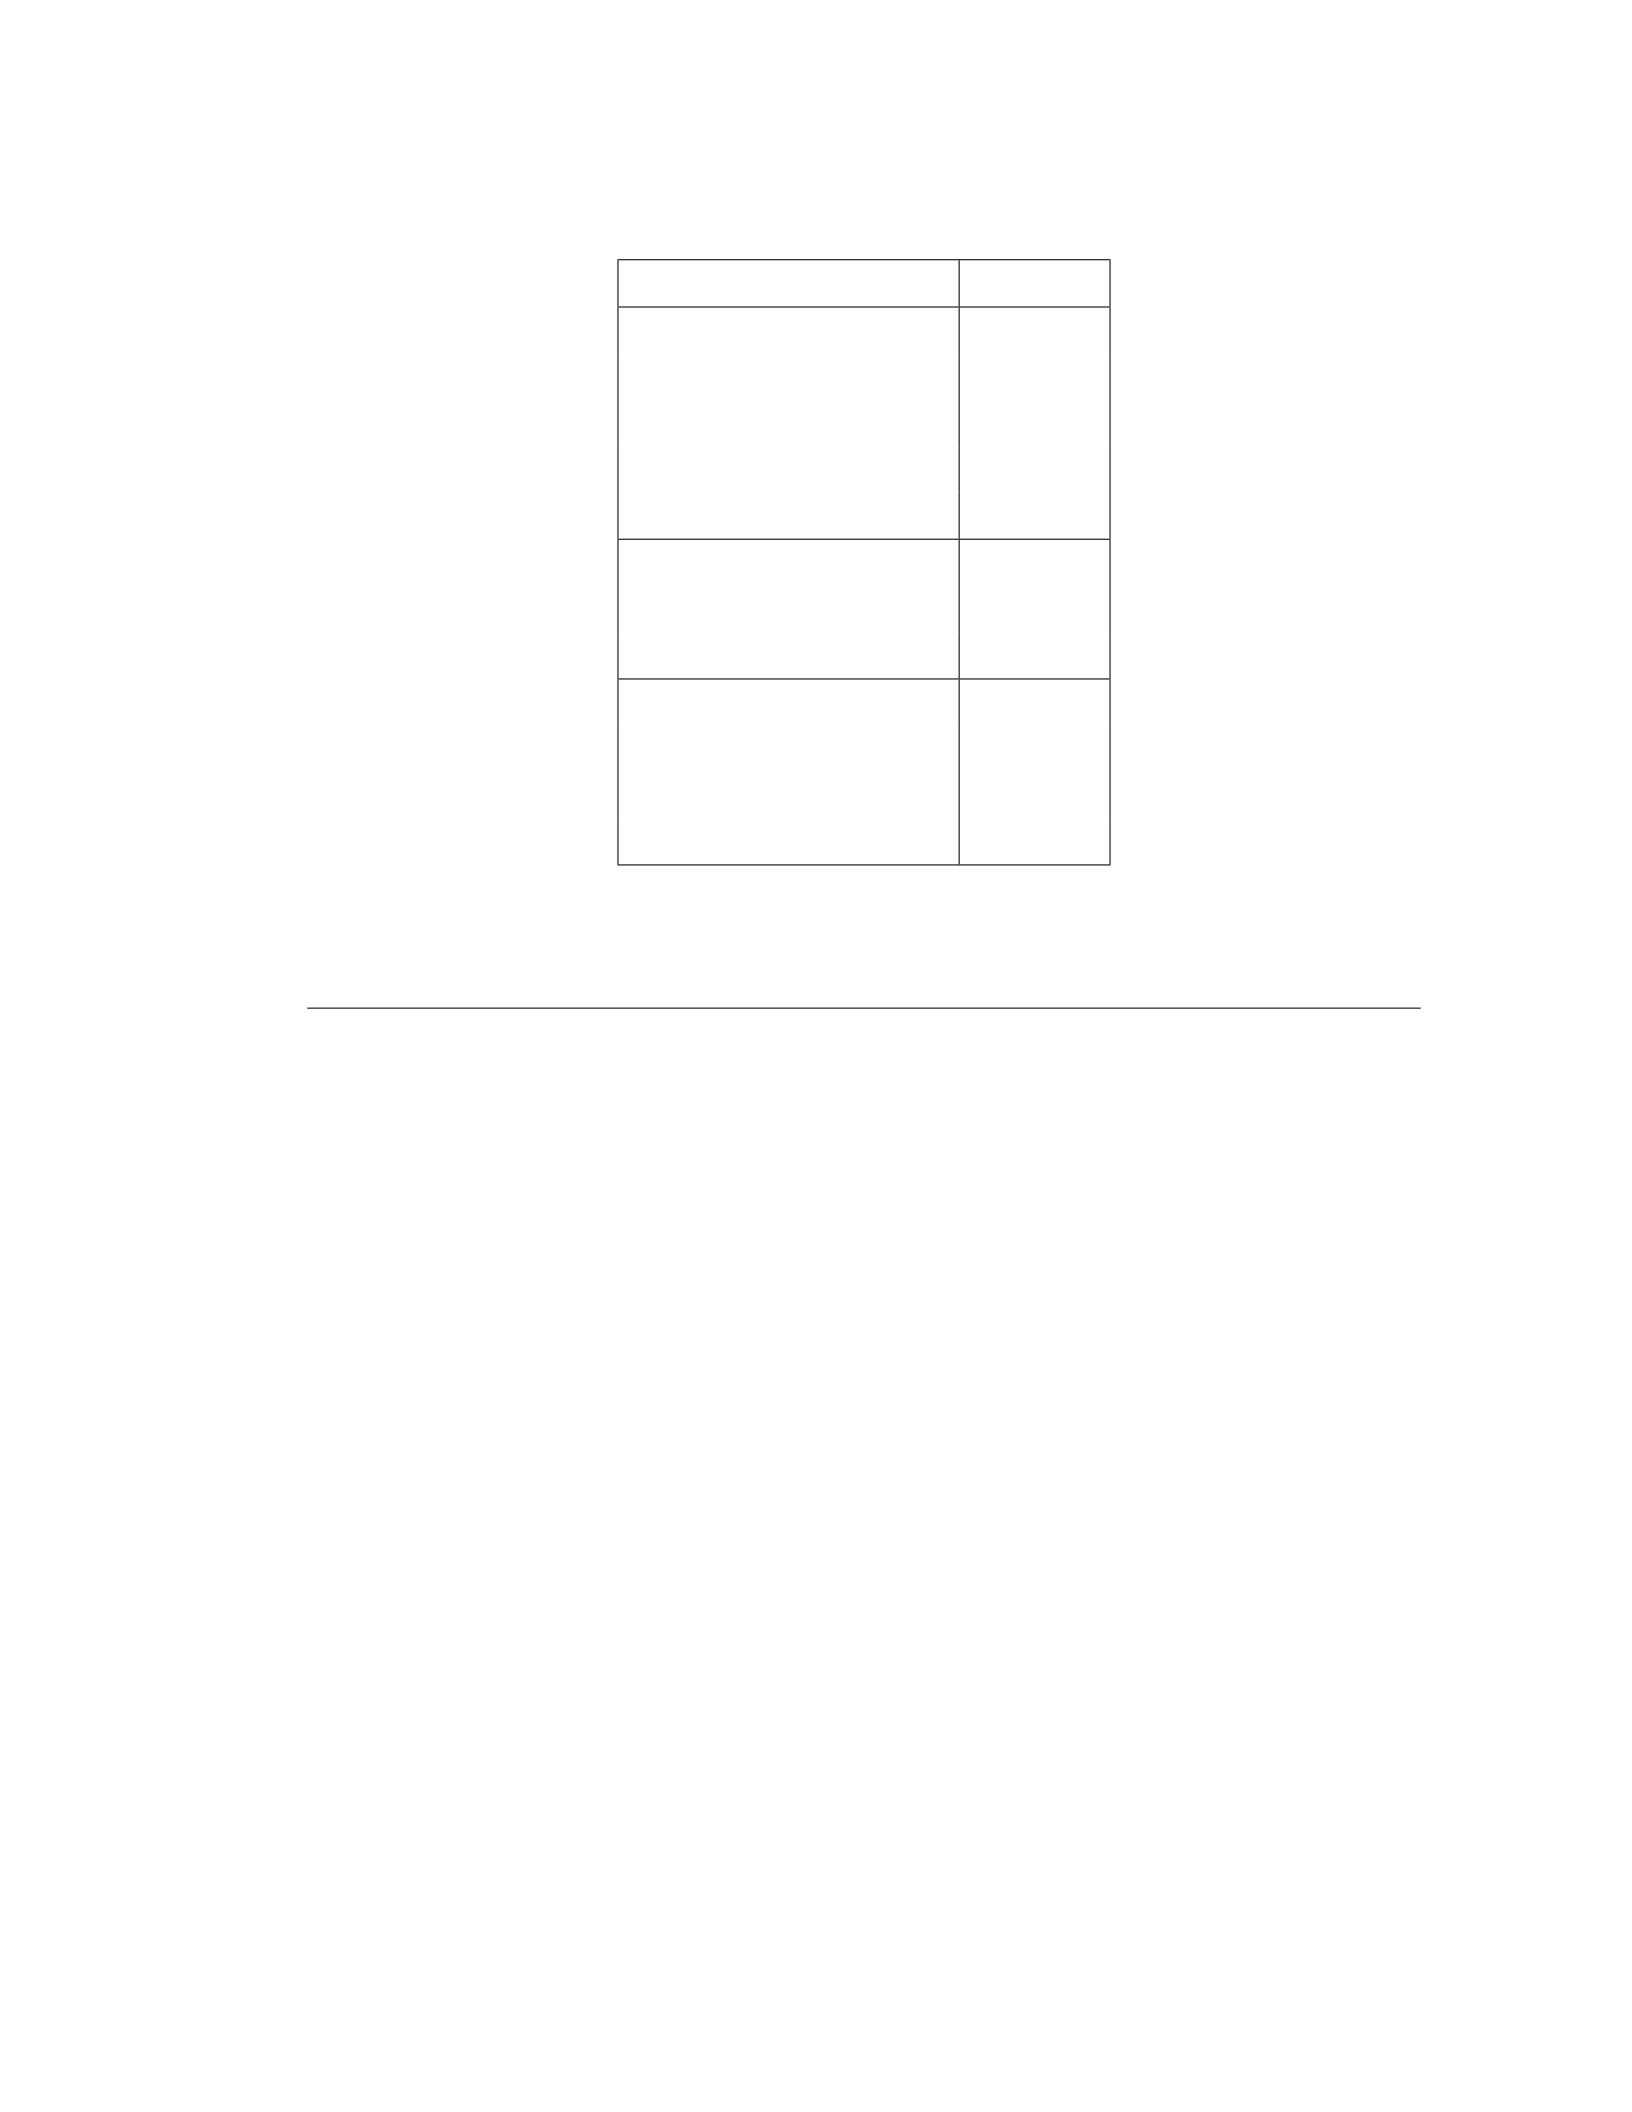
84
Characteristic Value
Ratees 30,000
Raters 3,919
1≤outlinks ≤10 2,402
10 <outlinks ≤100 1,230
100 <outlinks 287
Ratings 101,842
positive 76,101
negative 25,741
Mean Ratings 3.4
positive 2.5
negative 0.9
Sparseness 0.000113
Table 3.1: Characteristics of the Slashdot Zoo subset. Raters follow a power-law
distribution with respect to their outlinks.
3.4.1 Experimentation
To demonstrate the efficiency and collusion resistance of the PlayerRating system,
experiments were performed on an emulated player population constructed using
30,000 identities from the Slashdot Zoo [72]. This is a reasonable number of player
identities since World of Warcraft census indicate that realms support up to this
many players [122]. Summarized in Table 3.1, this subset preserves the power-law
characteristics of the original set.
Convergence to Equilibrium
This experiment shows how quickly PlayerRating agents converge to equilibrium in
the worst case: when all ratings are learned instantly. In normal operation, fewer
ratings update simultaneously due to limits of the communication channel. Within
one agent, reputation instability is measured as the root-mean-square-difference
(RMSD) between iterations of the UpdateReputations() function calculated by:
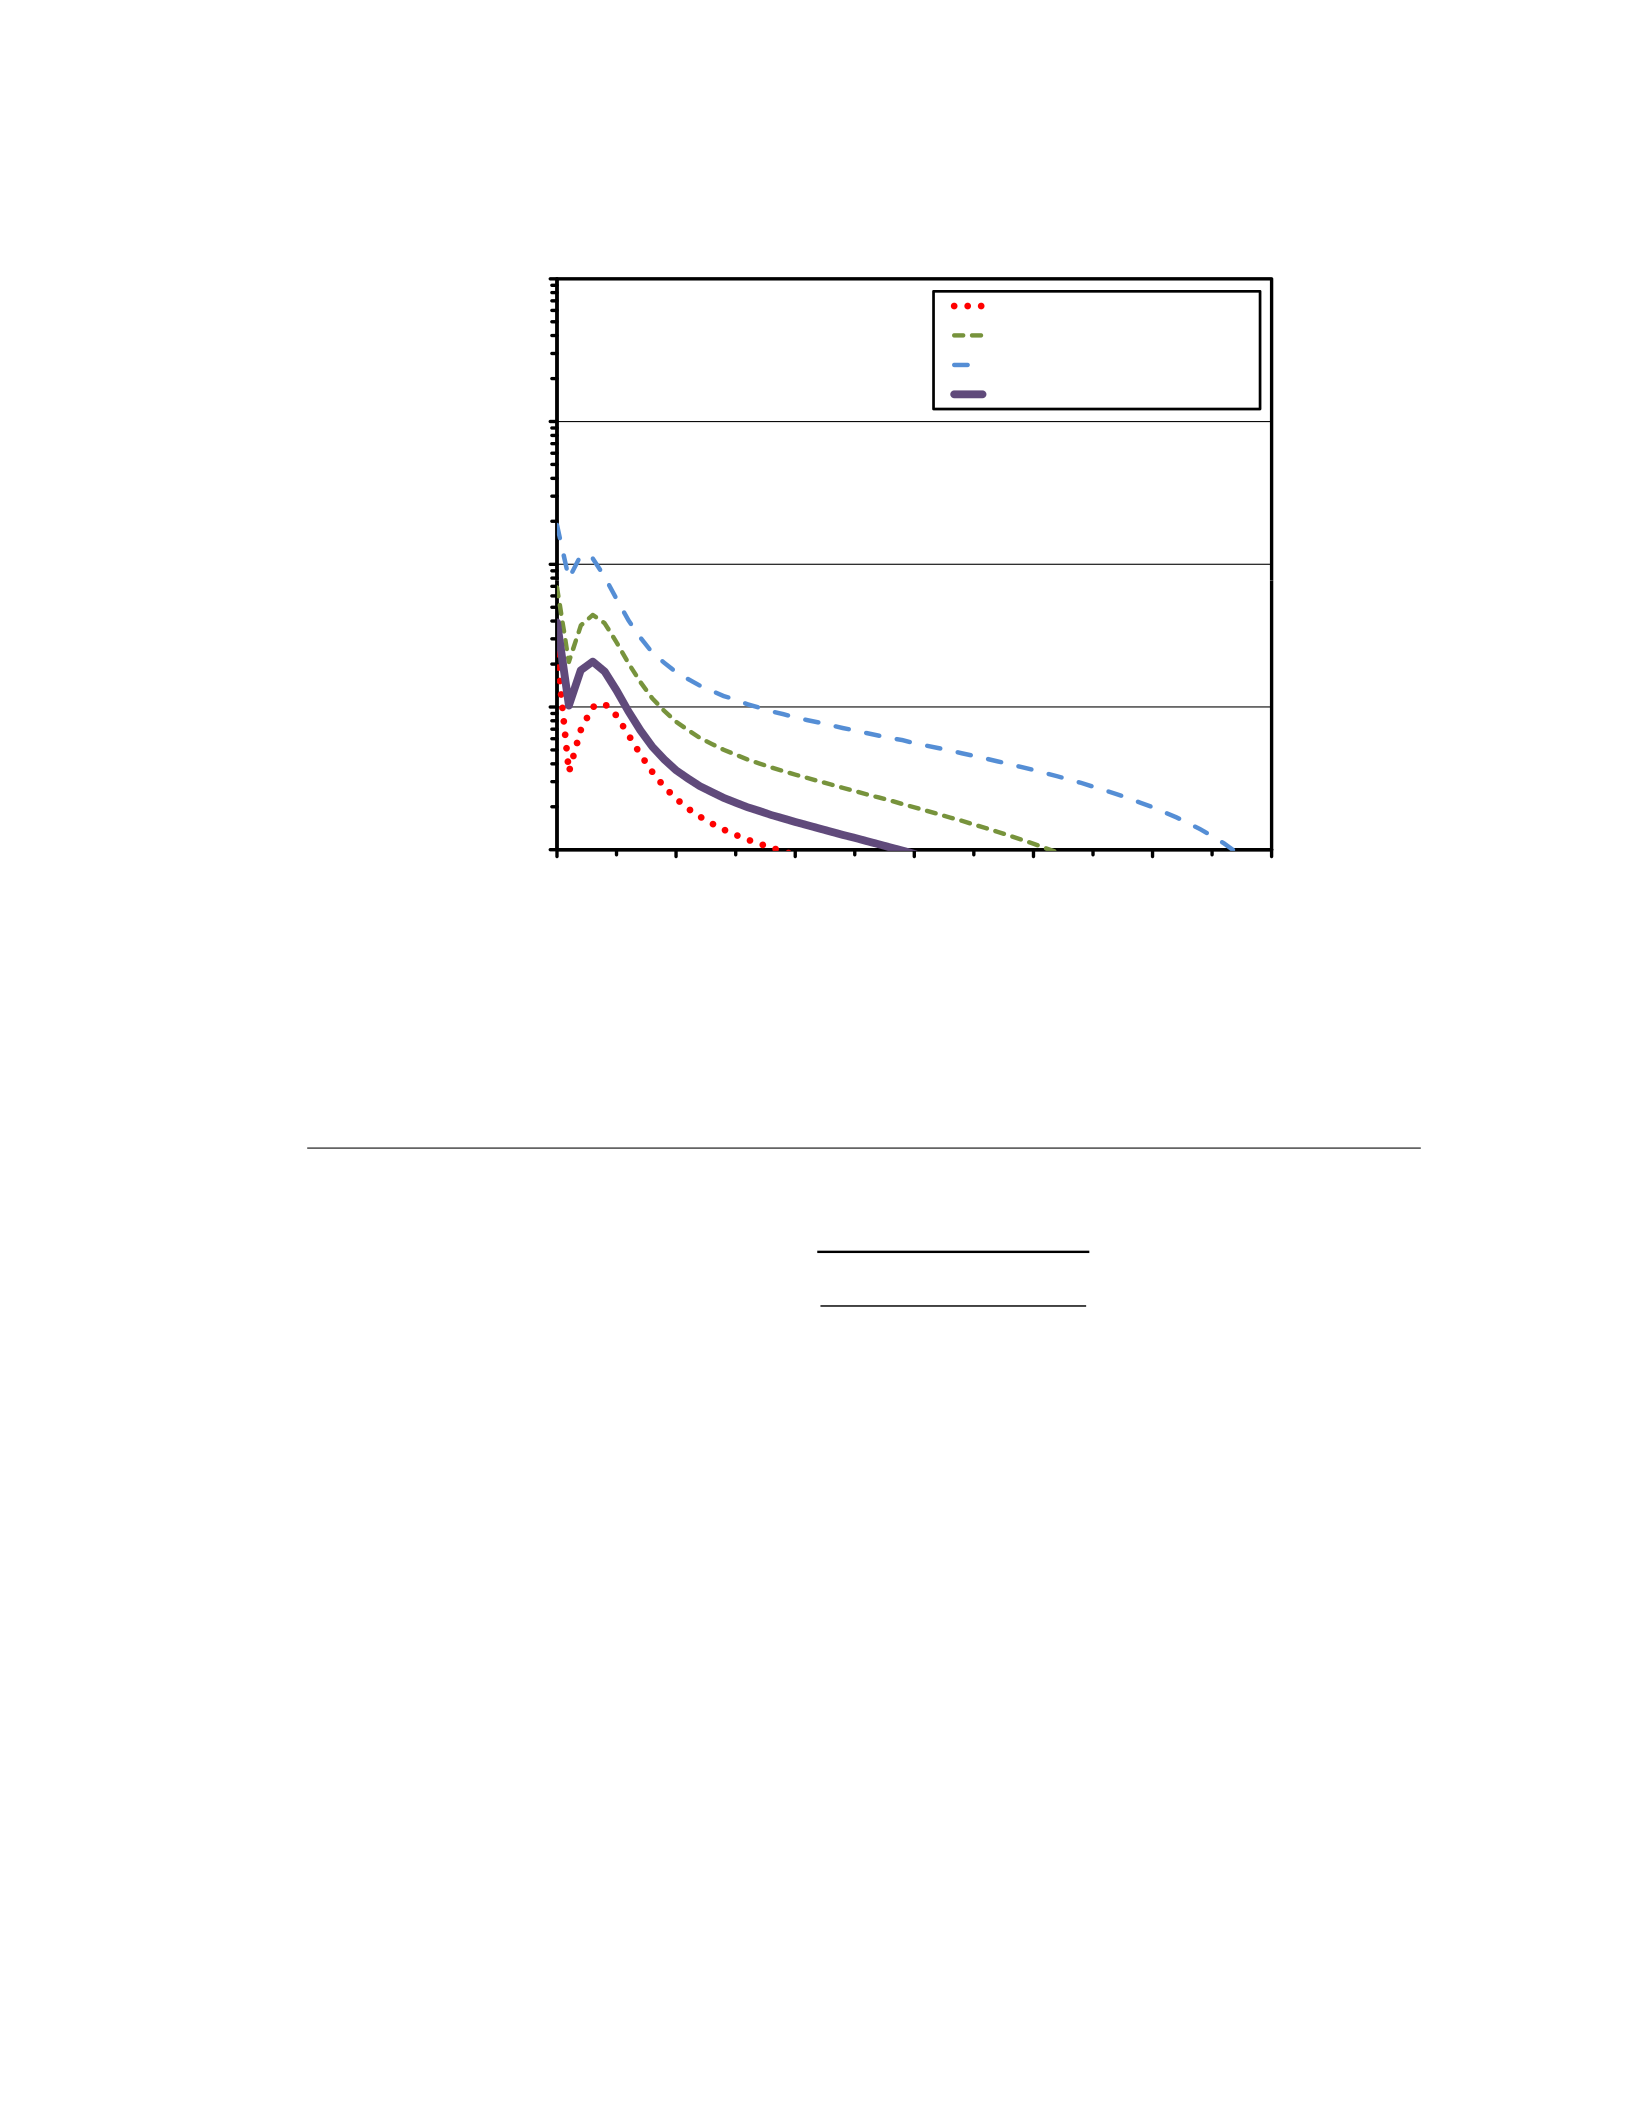
85
0.0100
0.1000
1.0000
Root Mean Squared Difference
1 < outlinks ≤ 10
10 < outlinks ≤ 100
100 < outlinks
Overall
0.0001
0.0010
0 10 20 30 40 50 60
Root Mean Squared Difference
Iteration
Figure 3.6: PlayerRating reputation convergence. The average RMSD for
players with at least one rating, after instantaneously discovering the ratings graph,
converges towards equilibrium as the UpdateReputations() function is iterated.
RMSD =¿
Á
Á
À∑i∈P layers (R′
i−Ri)2
∣P layers∣(3.4)
where a value of zero means the system has completely reached equilibrium and
any other value indicates that some reputations are still in flux.
Figure 3.6 shows the average RMSD for various players with at least one
rating. The results indicate that overall the average participant system converges
quickly. Players who rate fewer peers converge quickly since their connected graph
is generally smaller, while players who rate many peers converge more slowly since
their connected graph is larger. These results mean that malicious peers cannot
generate a number of ratings that would cause instability. The small bump occurs
at iteration 3 because that is the first iteration that can uncover a cycle in a
completely new graph, possibly propagating trust back to a known peer.
86
60%
80%
100%
Adversaries with Positive Reputation
30 Adversaries ( 0.1%)
300 Adversaries ( 1.0%)
3000 Adversaries (10.0%)
0%
20%
40%
0% 20% 40% 60% 80% 100%
Adversaries with Positive Reputation
Ratings about Adversaries that are Accurate
Figure 3.7: PlayerRating collusion resistance. The percentage of colluding
adversaries that incorrectly obtain positive reputation as viewed by the average
player is plotted against the percentage of accurate (i.e., negative) ratings about
individuals in the adversary population.
Collusion Resistance
This experiment shows the ability of PlayerRating agents to accurately identify and
isolate a population of colluding adversaries (i.e., correctly assign them negative
reputation). Initially, the colluding adversaries join the game and immediately
establish a fully connected positive rating sub-graph among themselves. Then, the
adversaries play in an entirely legitimate fashion in order to obtain positive ratings
from the original player population (assigned randomly according to the power-law
distribution and sparseness of the original ratings). The leftmost data plotted in
Figure 3.7 shows that at this early stage all the adversaries have obtained positive
reputation as expected because they have not yet acted maliciously, betraying their
earned trust.

87
As adversaries begin to betray their previously-earned positive reputation by
committing malicious acts, they acquire negative ratings (which reverse some
previously-obtained positive ratings). As the percentage of positive ratings
decreases, the percentage of negative (i.e., accurate) ratings increases and fewer
adversaries retain positive reputations. Eventually, the last adversaries abuse their
earned trust and are re-identified with negative ratings, leaving no adversaries with
positive reputations.
The figure shows that larger colluding populations retain positive reputation
longer than smaller colluding populations. This occurs because the colluding
population is fully connected, meaning that their rating links grow quadratically
and quickly outnumber the original rating links. In the largest adversary
population of 3,000 colluding adversaries (which represents 10% of the original
player population) the rating links vastly outnumber the original links: adversary
outlinks =3,000 ×2,999 =8,997,000 =88.3 times the original outlinks.
Computation Overhead
The PlayerRating agent runs within the game client process which requires fast
execution to minimize any impact on the game’s performance. Specifically,
the agent absolutely must not affect the game’s playability at critical gameplay
moments. To measure the PlayerRating agent’s speed, benchmarks of its various
functions were performed on an Intel Core 2 Quad system (Q6600/2.4GHz). The
results shown in Table 3.2 each represent an average of 10,000 executions. Most of
the agent’s functions operate on the order of µs. The slowest operations are merely
on the order of ms. They are the ExpireRatings() function which must iterate
over all stored ratings to decrement their time-to-live values and the portion of the
UpdateReputations() function that commits R′to R. Fortunately, these both
of these operations are infrequently performed (at periods greater than a pHour)
and may be scheduled to coincide with the next logon, loading screen, or idle time
when they will impact the player’s gameplay the least.
88
Function Theoretical Experimental
Bounds Cycles Time
Initialization() O(1)473 0.2µs
RecordRating() O(1)33,539 14.0µs
ShareRatings() O(outlinks)policy dependent
ExpireRatings() O(∣r∣) 30,267,923 12.7ms
UpdateReputations() O(∣r∣) 18,300,514 7.7ms
process rating O(1)300 0.1µs
process rater O(∣P layers∣) 26,089 10.9µs
commit R′O(∣P layers∣) 10,047,723 4.2ms
LookupReputation() O(1)752 0.3µs
Table 3.2: Efficiency of PlayerRating routines. The theoretical bounds and
experimentally measured computation cycles (also expressed as time for analysis)
to execute the various routines of a PlayerRating agent are given.
Memory Overhead
With many gaming machines having gigabytes of physical memory and game
client’s leaving so much virtual memory unused, having a small memory footprint
is less important than being fast. While memory overhead is a lesser concern,
PlayerRating agents require extremely little state. Specifically, neutral/unknown
ratings (i.e., with value 0.0) are not useful and need not be stored. Furthermore,
ratings from peers with negative reputations will not be used so they can be
discarded. Similarly, ratings about the player will have no bearing on any of
the algorithms (recall Rself =1.0 always) so they need not be stored either.
In summary, a PlayerRating agent’s state is reduced simply to the number of
relevant ratings kept and the peer reputations. This is far less than the square of
the number of players due to the sparseness of the social graph:
total state =∣r∣+∣R∣≪∣P layers∣2(3.5)
For example, the ratings and reputations throughout the evaluation merely require
2.4MB of application memory.

89
3.4.2 Limitations
The current limitations of PlayerRating involve changes to player account in-
formation that is not public and therefore is not accessible by a user-interface
modification. Specifically, a player may quit the game, transfer their character
to another server, or rename their character (although only to another unique
name). While large-scale Sybil attacks are not possible due to restrictions on how
frequently these actions may be performed, some system inaccuracy (i.e., rating
duplication may exist until those ratings expire). Such temporary inaccuracies
could be avoided if the system was aware of relevant changes to peer accounts and
peer ratings made while the player was offline. This would obviate the need for
rating expiration in the first place.
External to the game, peers sometimes sell their accounts for profit, although
this practice is often against the game’s Terms of Service Agreement. Characters
changing ownership in this fashion may have an abrupt change in behavior, making
existing ratings about them obsolete. Players with positive ratings about these
peers may be briefly misled until those ratings are corrected.
Finally, adversaries may attempt small-scale Sybil attacks [26] by creating
additional game accounts. In general, this is prohibitively expensive because
creating a game account involves purchasing a copy of the game and paying a
subscription fee. However, some games like World of Warcraft offer temporary
trial accounts (10-day trial accounts are already abused for gold spamming) which
may facilitate short-term Sybil attacks. This may be addressed by incorporating
the character’s level in the Influence() function (i.e., ratings from high-level
characters are more relevant than ratings from low-level characters). This would
immediately mitigate trial accounts since those accounts expire before an adversary
could reach maximum character level (it takes roughly 300 pHours to reach
maximum level). If PlayerRating were built into the game, ratings from trial
accounts would be easy to ignore and need not be propagated at all.

90
3.4.3 Discussion
There are several possible PlayerRating applications. Currently the system is
publicly available as a World of Warcraft mod [60] and may be adopted by any
player willing to do so. We used the system (along with in-game and real-life
friends) for a number of years before quitting the game. It is our experience
that the system successfully warns players when first interacting with peers who
have behaved badly in the past. If implemented within game algorithms that
match players for group play, reputation scores could be compared to weigh the
likelihood that the group will get along well. In this sense, PlayerRating could
completely replace existing friends-list and ignore-list tools by simply treating peers
with positive ratings as friends and ignoring peers with negative ratings.
Platforms that support multiple game titles (e.g., Sony’s PlayStation Network
or Valve’s Steam) may trivially build a recommender system on top of PlayerRating
to focus online marketing at players with friends (i.e., peers they rate highly) who
enjoy other titles or specific DownLoadable Content (DLC). This would effectively
state: “your friend from game X also plays game Y, you might enjoy it too.”
Furthermore, such a system could recommend User Generated Content (UGC) –
especially if a rating dimension was applied to modders (ri,j,modder) regarding the
quality of their creations. Ultimately, this may become an effective approach to
reduce a game developer’s time and expense in creating content for new games.
Reputation systems like PlayerRating may be used to federate adversary
detectors in other applications where the clients do not directly interact with and
rate each other. For example, independent Web services may use such a system
to learn which of its clients are bots participating in a denial-of-service attack.
In this setting, the system may incorporate ratings from peers and input from
other detectors like Fides. Since these sources of information are not being rated
by the same criteria with which they rate clients, the system could augment the
Influence() function to account for the historical accuracy of each rating source.

91
3.5 RELATED WORK
Existing In-game Tools. Many games offer simple tools for tracking peers
that a player likes (e.g., friend-list) or dislikes (e.g., ignore-list). Extensions like
PlayerNotes [86] add annotation capabilities to those tools so that the player
may be reminded why they befriended or ignored peers. While these tools are
easy to implement and are present in many online games, they do not share such
preferences and thus cannot predict whether or not a player will like a peer they
meet in-game for the first time.
Reputation and Recommender Systems. A common approach to
improving online social interaction is the use of reputation systems, such as eBay’s
Feedback system [29] or Slashdot’s Karma system [105]. Related to reputation
systems are recommender systems (where value is assessed for objects rather than
people), the most notable of which is the PageRank system that powers the
Google search engine [87]. The PageRank system determines the popularity or
rank of a webpage as the sum of all supporting evidence (i.e., hyperlinks pointing
to it) weighted by the rank of the referring webpages and a decay factor. The
algorithm iteratively updates each webpage’s rank through random walks of the
Web, eventually reaching Web-wide equilibrium. So long as a webpage has many
references from popular pages, it will also have a high PageRank.
Deployed reputation and recommender systems, like PageRank, evaluate the
global perception of persons or objects yielding rough predictions that do not
account for personal preference. For personalization, some approaches (e.g.,
TrustRank [46] and Personal PageRank [57]) extend PageRank while others
(e.g., EigenTrust [68] and email filtering [45]) implement systems that operate
in a distributed fashion. Personalized approaches allow people with similar
interests (e.g., players who dislike profanity) to congregate and form cliques. Such
approaches record peers that one likes or dislikes, and extrapolates personal and
shared ratings to predict like and dislike for peers not personally met.
92
The PlayerRating approach is architecturally similar to the PageRank system,
but is computed in a distributed fashion. PlayerRating calculations are tailored
to better suit online games and direct exposure to players. PlayerRating leverages
both positive and negative ratings, as well as bounding reputations, so that they
remain on a fixed scale and can be more easily interpreted by players.
3.6 CONCLUSION
In many networked applications, clients interact using aliases which unfortunately
enable a number of antisocial behaviors, including automation. This chapter
investigated the problem of identifying adversaries using a federation of abundant,
yet sometimes inaccurate and individually inconclusive detectors in the context
of identifying misbehaving players in multiplayer online video games. This
application is ideal for such research since established disincentives exist and
treating players as detectors harnesses abundant information sources. The research
contributions of this chapter are:
We briefly outlined the problem with online behavior. Basically anonymity
in an (even indirectly) competitive application or environment invites
participants to behave badly towards one another. Fueled by financial
incentive, automated and adversarial behaviors become ever more common.
We proposed and evaluated a novel reputation system for multiplayer online
games. The PlayerRating system runs an agent within each participating
player’s game client and extends the user interface to noninvasively allow
the player to rate their peers. Using the player’s ratings along with the
ratings shared by their peers, a PlayerRating agent calculates reputations
for all peers from that player’s perspective. By design, the system facilitates
incremental deployment and encourages participation. In evaluation, we
showed that the PlayerRating system resists abuse and imposes minimal
overhead.

93
There are a number of ways which a reputation system could be used in
multiplayer games. Besides the original purpose of identifying malicious players
to avoid, such a system could provide the basis for focused in-game advertising
and evaluating both downloadable and user-generated content. Furthermore,
reputation systems like PlayerRating could be used to federate adversary detectors
in other applications where the clients do not directly interact with and rate each
other.
The next chapter discusses how an application service provider may leverage an
analog metric (like player reputation) to best disincentivize automated adversaries
of Web-based applications. That research focuses on maximizing the application’s
service for legitimate clients while minimizing service granted to mostly adversarial
clients.

94
Chapter 4
DISINCENTIVIZING ADVERSARIAL AUTOMATION
4.1 INTRODUCTION
The previous chapters explored approaches to detect automated behavior and
combine detectors in order to identify application adversaries. Applications that
authenticate clients through some form of real-world credibility (e.g., multiplayer
online video games which bind player accounts to a credit card or software
purchase) can immediately leverage these approaches to penalize and thus
disincentivize malicious behavior. In contrast, applications which are susceptible
to adversarial automation before they can conveniently authenticate the client
(e.g., Web-based commerce) cannot leverage these approaches as easily and must
establish a disincentive mechanism which may work even in the absence of strong
client authentication. This chapter investigates how to do this.
We explore a Proof-of-Work (POW) approach that leverages the various
available information sources (including client geographic location) to differentiate
clients and thus disincentivize adversarial automation behavior in the context of
resource consumption attacks on Web-based applications. Most Internet commerce
is done through Web-based applications so they experience a wide variety of
resource consumption campaigns against them such as denial-of-service, ticket
scalping, comment spam, and click fraud. Web applications are ideal for adversary
disincentivization research since they have access to many sources of information
about client behavior including load metrics and network address blacklists yet
lack effective disincentive mechanisms. We show that our proof-of-work approach
is efficient, transparent to human users, and straight-forward to implement.

95
4.2 THE RESOURCE CONSUMPTION PROBLEM
Service providers use Web-based applications to distribute ideas or sell goods.
Rationally, a service provider only provisions enough computation and network
resources to handle the expected client load for the application, with some extra to
spare. Unfortunately, in most Web-based applications there is a resource imbalance
between the server and clients, both in terms of the resources each have available
and that each must commit in order to complete a transaction. Specifically, a client
may simply send a single request (i.e., network packet) to initiate the protocol,
however, the server may need to retrieve data from disk or a database, perform a
non-trivial computation, or generate a webpage from dynamic content.
In times of unexpectedly high legitimate interest (referred to as “flash crowds”
or as the “Slashdot effect”), it is possible for the server to be overwhelmed and cease
to adequately service any requests. This underscores the resource consumption
problem: with or without it being their motivation, automated adversaries (i.e.,
large botnets) can easily consume all the Web server’s resources, often in early
stages of the application protocol. Automated attacks on Web-based applications
remain a significant problem on the Internet, despite vast efforts to combat them.
Examples include comment spam on Web-based forums [89], ticket-purchasing
robots [110], click-fraud robots, and denial-of-service attacks.
There are two disadvantages that a Web server has in dealing with this problem.
First, network clients are weakly authenticated; it is often not until the very end
of a transaction that the client’s real-world identity must be revealed, so it is
difficult to stop adversaries from consuming server resources in the early stages of
the protocol and aborting just before they must commit their own resources or
identity. Second, Web applications seek a general audience which is not known a
priori, so the server expects that most clients engaging in the protocol intend to
complete the transaction.
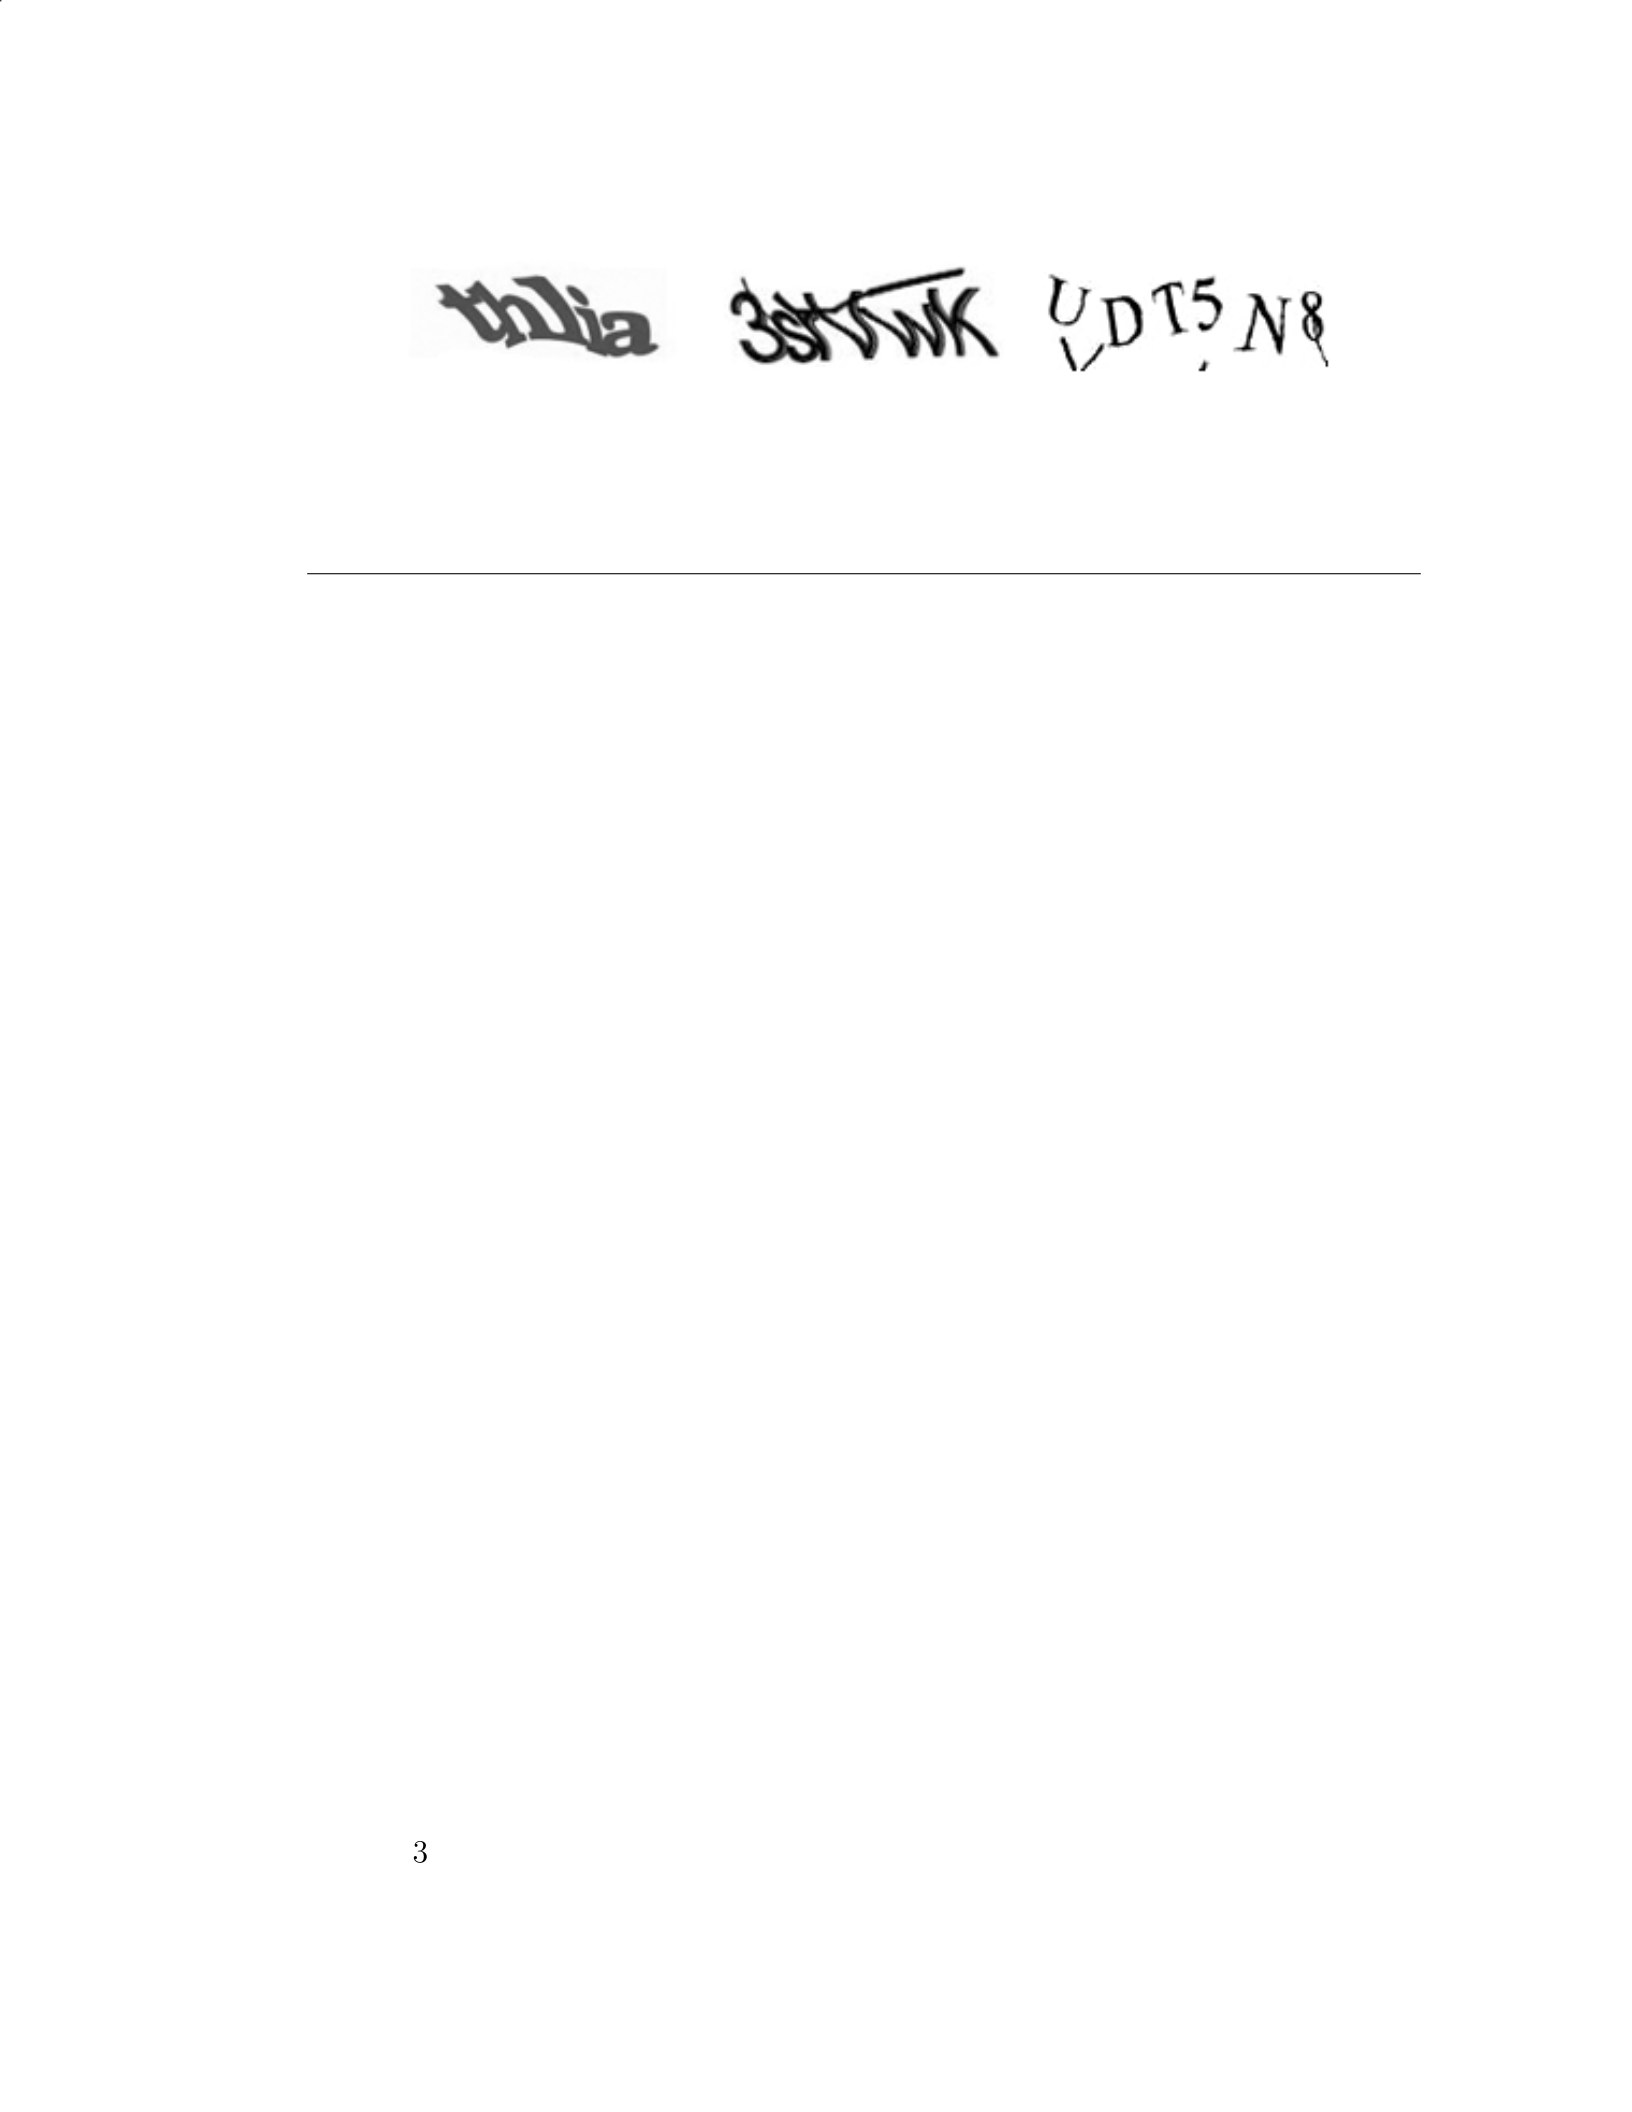
96
a) Google b) Yahoo! c) Microsoft Live
Figure 4.1: Unintelligible CATPCHAs. Found on three of the largest Internet
websites, these examples represent the sole challenge to creating an online account.
4.2.1 The Shortcomings of CAPTCHAs
A common approach to address the automated resource consumption problem
is the use of image-based Completely Automated Public Turing Tests to Tell
Computers and Humans Apart (CAPTCHAs) [117]. Each CAPTCHA is a small
server-generated image consisting of skewed representations of letters and numbers
(like the examples shown in Figure 4.1) that a user must correctly interpret before
they are granted access to the protected service.
There are several disadvantages of using CAPTCHAs. One drawback is
the user-interface problem they impose [70]; users who are visually impaired
are unable to solve the challenge and are thus denied access to the service.
Even visually unimpaired users find it increasingly frustrating to solve challenges
correctly because they are becoming less readable in order to thwart automated
solving software. A second drawback is that automated solvers are improving
at an alarming rate and can efficiently defeat most human-readable CAPTCHA
constructions [49]. The final and probably most important drawback is that the
fixed-difficulty challenge that CAPTCHAs represent fatally limits their utility.
CAPTCHAs are designed so the typical user can solve one in roughly 10 to 20
seconds. Enterprising adversaries have outsourced the solving of CAPTCHAs to
low-cost foreign data entry specialists who will solve 1,000 challenges per hour for
under
$
3 [43]. From an economic standpoint, the inability to change the “price”
of access makes the approach unable to protect valuable online resources [75].

97
4.2.2 The Case for Proof-of-Work
Proof-of-Work (POW) protocols are an alternative to CAPTCHAs. A few proof-
of-work protocols have been proposed in the literature [7, 8, 24, 28, 35, 121, 123]. A
proof-of-work (also known as “cryptographic puzzles” or “client puzzles”) protocol
extends a client-server request-driven application protocol so that the server issues
prospective clients computational challenges of client-specific difficulty. Each client
must solve their own computational challenge and return a correct answer to the
server before they will be granted service. Every POW protocol is designed such
that issuing and verifying challenges is trivial for the server to do, yet solving the
challenges is arbitrarily difficult (as set by the server) for the clients to do.
The challenge-response nature of POW protocols makes them similar to
CAPTCHA protocols except that POW challenges are solved by the client machine
rather than the human user. In removing the human from the protocol, POW
protocols may more readily differentiate service on a per-client basis according to
the likelihood that each client is adversarial (i.e., through demonstrated behaviors
or other detection methods). Clients that are more likely to be adversaries are
given extremely taxing challenges to solve, while clients unlikely to be adversaries
are given easy challenges to solve. In contrast to the uniform price applied to all
clients in CAPTCHA protocols, the server can accurately price individual access
to the service using a POW protocol.
While POW approaches are highly configurable in terms of workload, few
have made progress towards being deployed. The biggest hurdle to adopting the
previously proposed approaches is that they require changes to standard protocols
and wide-scale adoption of special client software in order to operate properly,
denying all clients who have not installed it. This chapter describes kaPOW, a
novel POW approach that is transparent to clients, and POW difficulty policies
for disincentivizing automated adversary behaviors using two different information
sources: per-client request history and client geolocation.
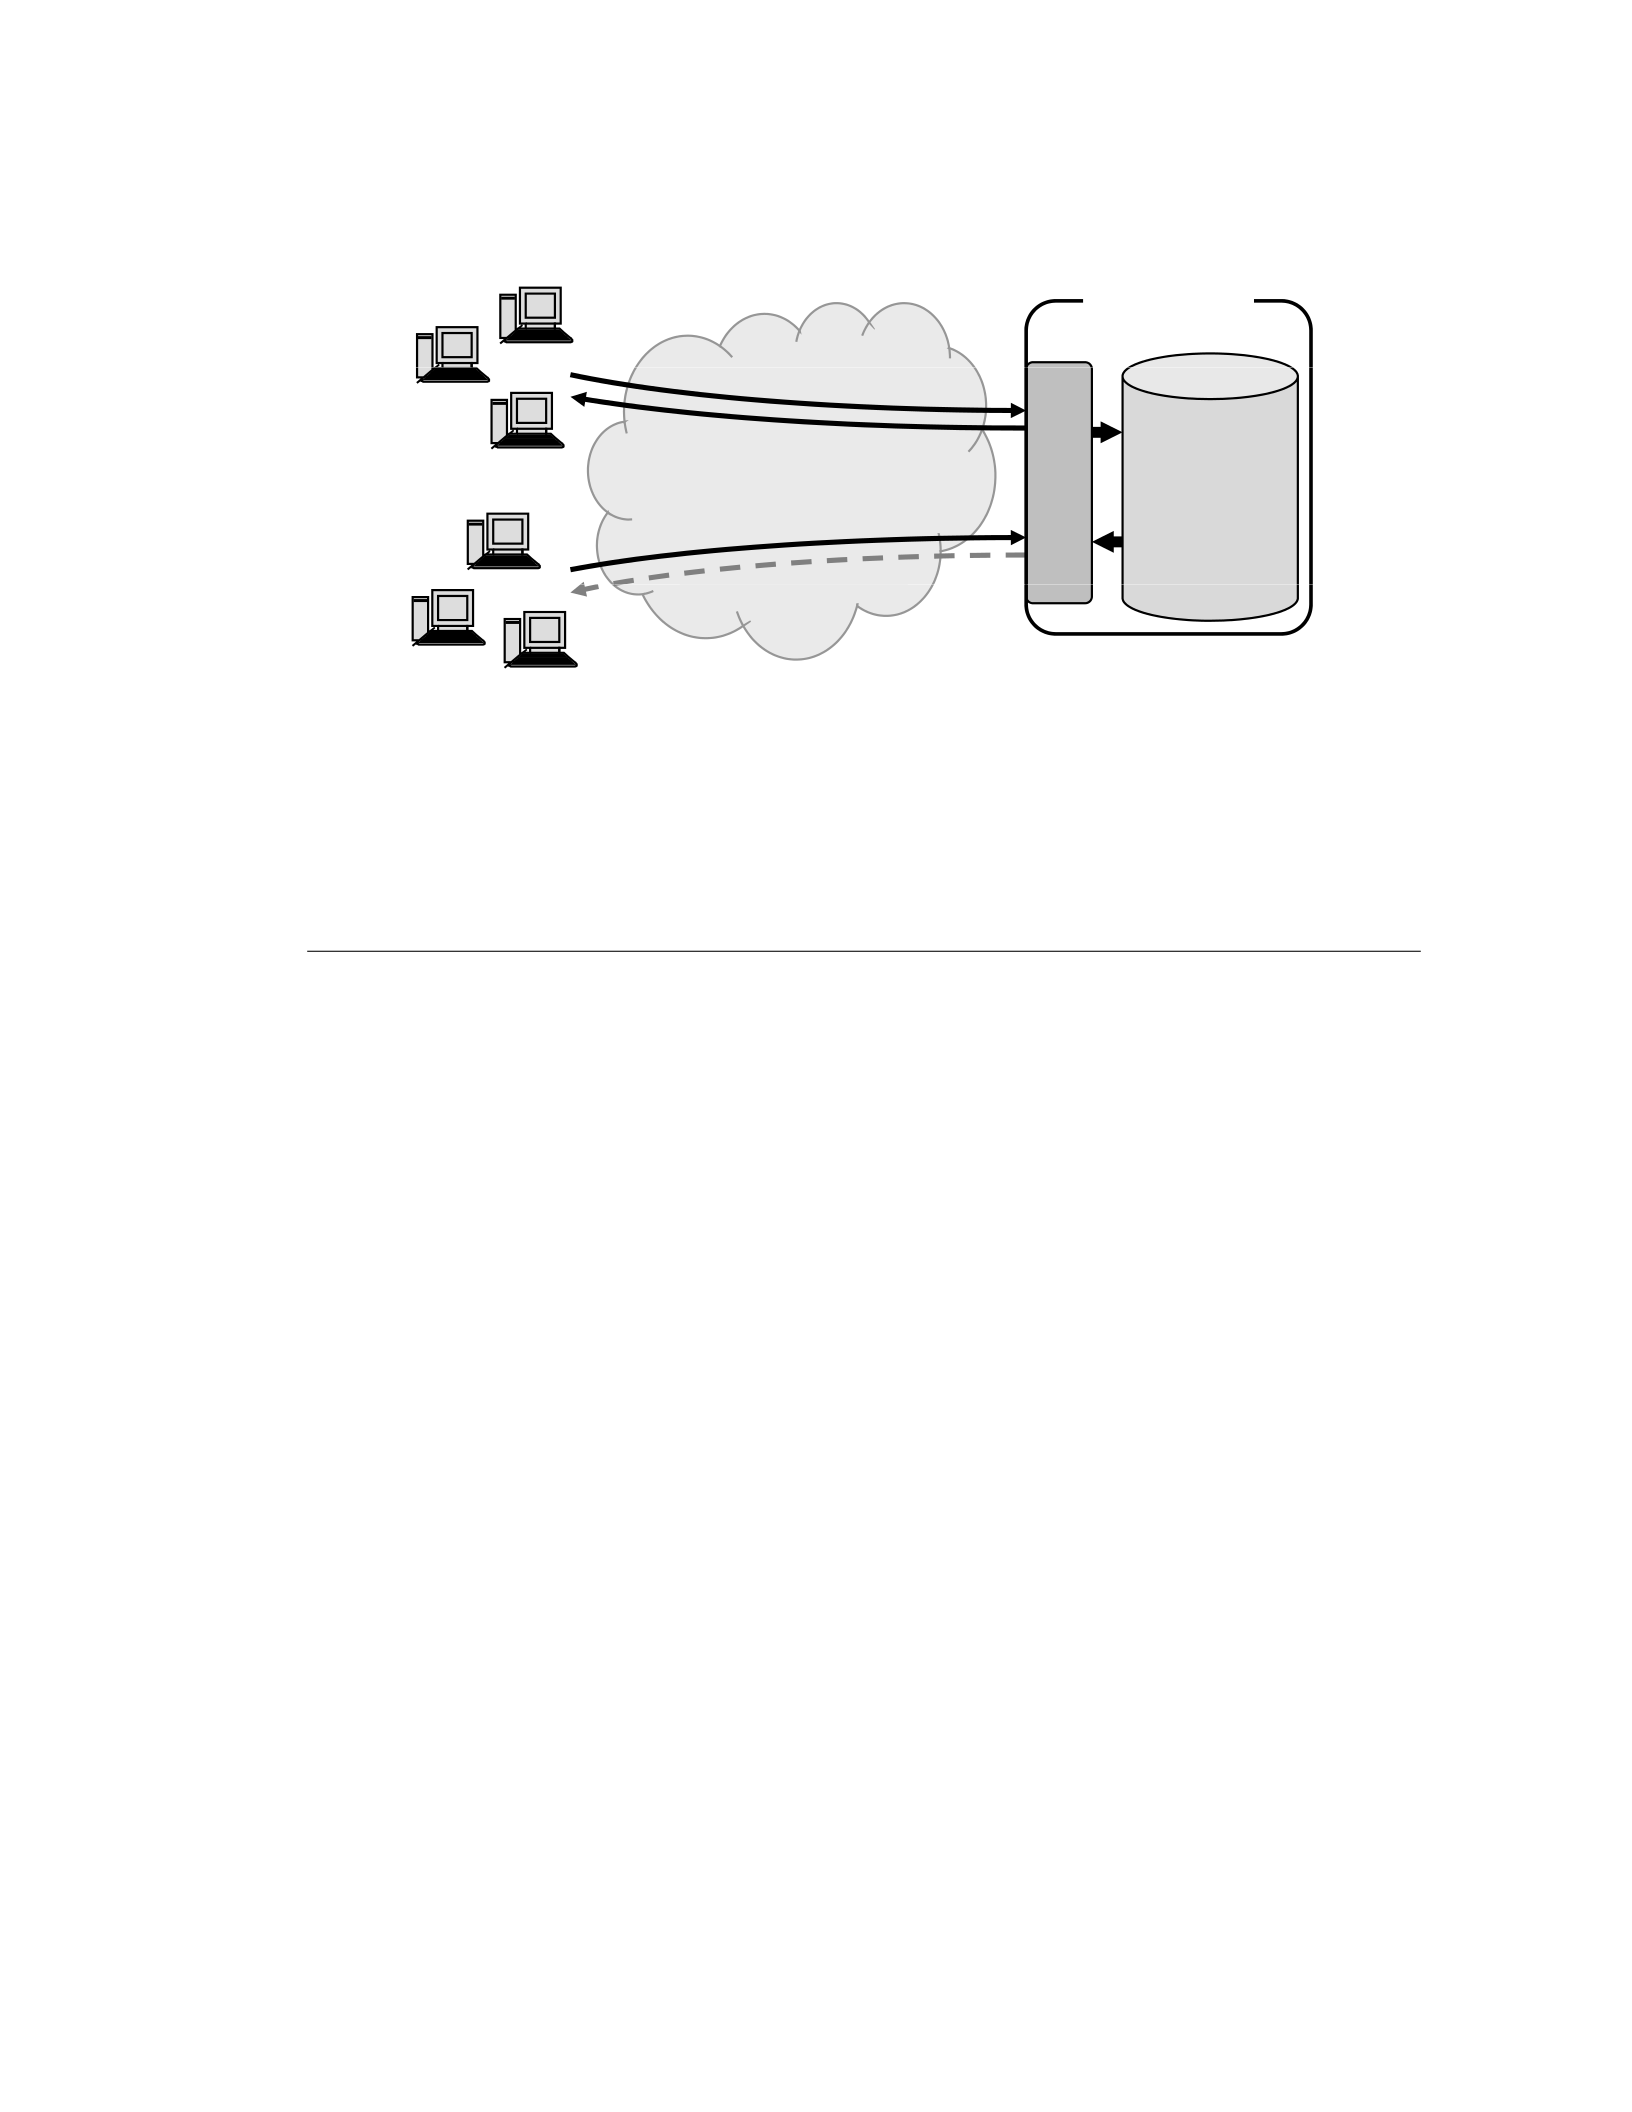
98
URL
with
valid
POW
Web Server
URL
with
valid
POW
System
Clients
Content
Content
kaPOW
System
Clients
URL without valid POW
Error Page
Content
kaPOW
Error Page
Figure 4.2: Addition of kaPOW to Web server. Clients who attach a valid proof-
of-work solution to their requests are granted the content they seek, while clients
without a valid solution are ignored and issued a new proof-of-work challenge,
server resources permitting.
4.3 THE KAPOW APPROACH
Proof-of-work approaches proposed in the literature [7, 8, 24, 28, 35, 121, 123]
have demonstrated the feasibility of implementing proof-of-work systems at the
network and transport layers. While the approaches have experimentally proved
their effectiveness against portscans and network-level packet-flooding denial-of-
service attacks, they have all met resistance to adoption due to one fundamental
detraction: they require both clients and servers to adopt specialized software in
order to adhere to the protocol.
This led us to develop the kaPOW approach which is the first transparent proof-
of-work approach in literature or in practice (it currently protects the project’s
webpage [62]). The kaPOW approach (shown in Figure 4.2) protects Web-based
applications by incorporating a simple proof-of-work module at the server. To
make the approach transparent to clients, the approach leverages JavaScript which
is nearly ubiquitous as recent measurements have shown that JavaScript is enabled
in upwards of 95% of all Web browsers [118].
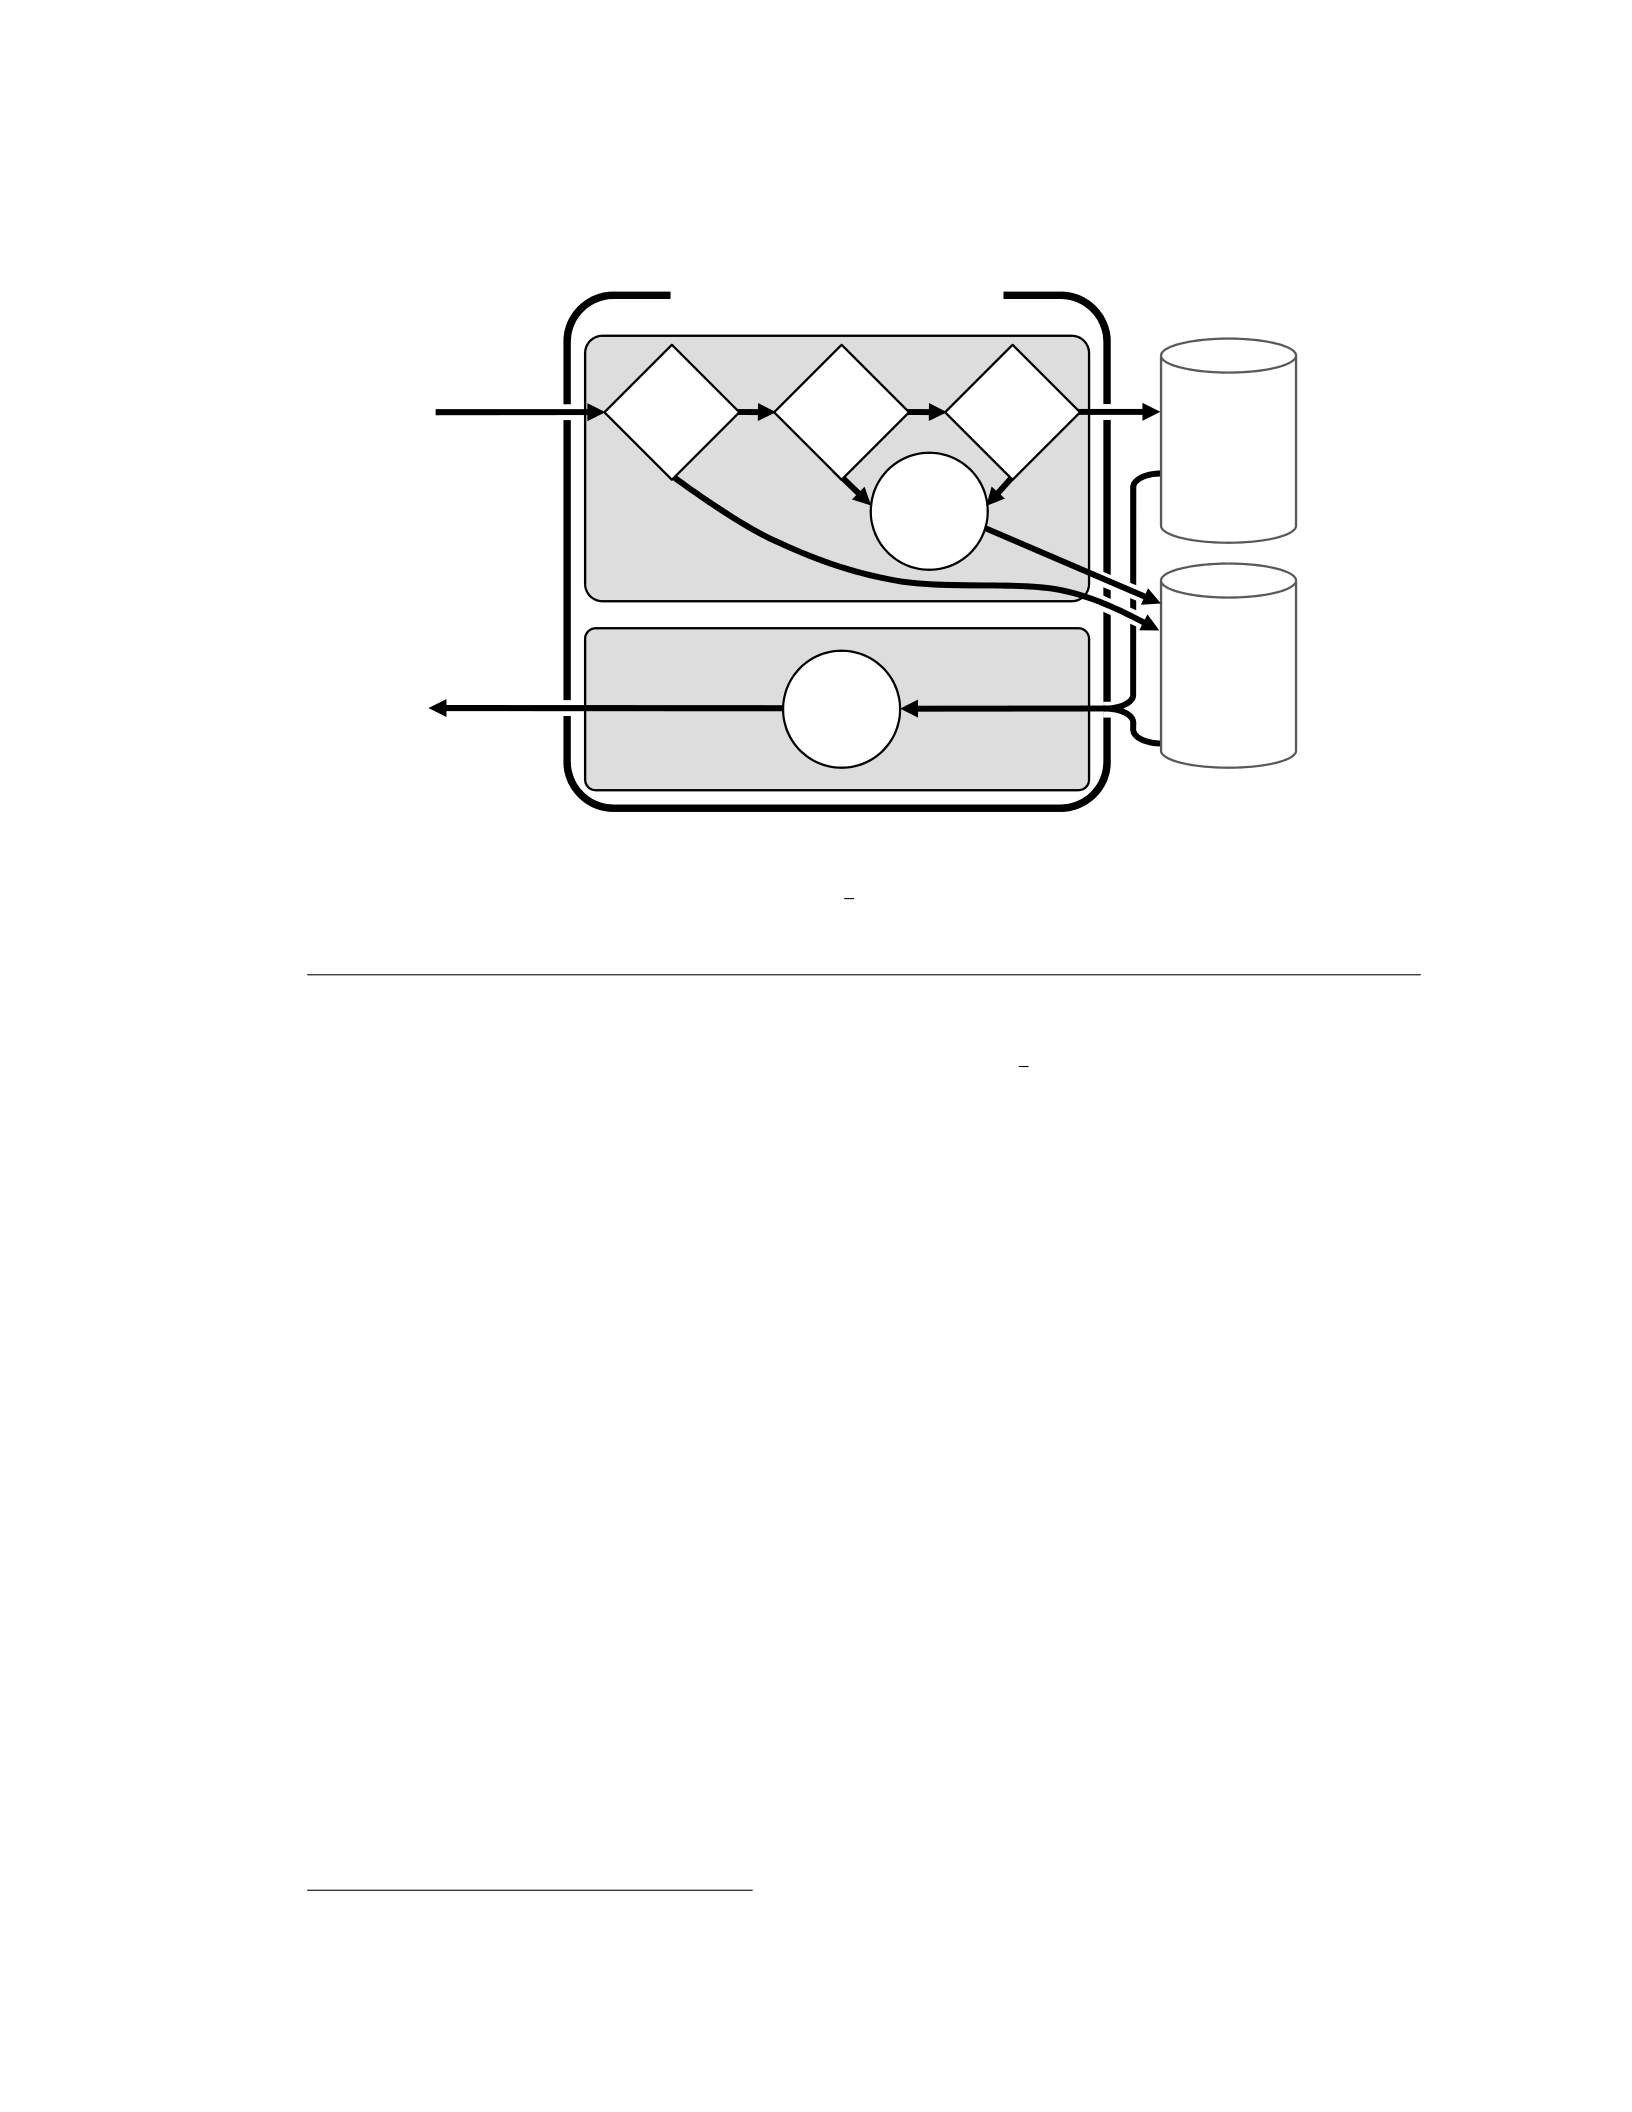
99
Issuing
Filter
Verifying
Filter
mod
_
kaPOW
High
Priority
Content
Low
Priority
Content
Request
URL
Content Append
POWs
No No
NoYes Yes
Yes
Error
Page
Dc= 0 Absent
Nc/Dc
Valid A
Figure 4.3: Internal structure of mod kaPOW. The system is an Apache module
which processes POW-protected URLs and the corresponding content.
The kaPOW approach was implemented as mod kaPOW1, the Apache [5] Web
server module shown in Figure 4.2. The system protects Web content by embedding
POW challenges (“work functions”) in Uniform Resource Locators (URLs) as new
query parameters. As webpages are served, the URLs found in any HyperText
Markup Language (HTML) tags are updated to include a fresh work function.
When a client’s Web browser encounters a POW-protected link, it runs a
server-provided JavaScript routine to solve the work function and append the
solution to the URL before attempting to follow the link. As elaborated upon
later, clients without JavaScript (or with it disabled) are not necessarily prevented
from accessing the content.
Upon receiving a request, the server verifies that the URL contains a valid
work function and solution before servicing it. If either the work function is stale
or the solution is incorrect, the server denies the request and returns an error page
containing a link with a new challenge.
1This research appeared in a paper at Global Internet 2008 [63].
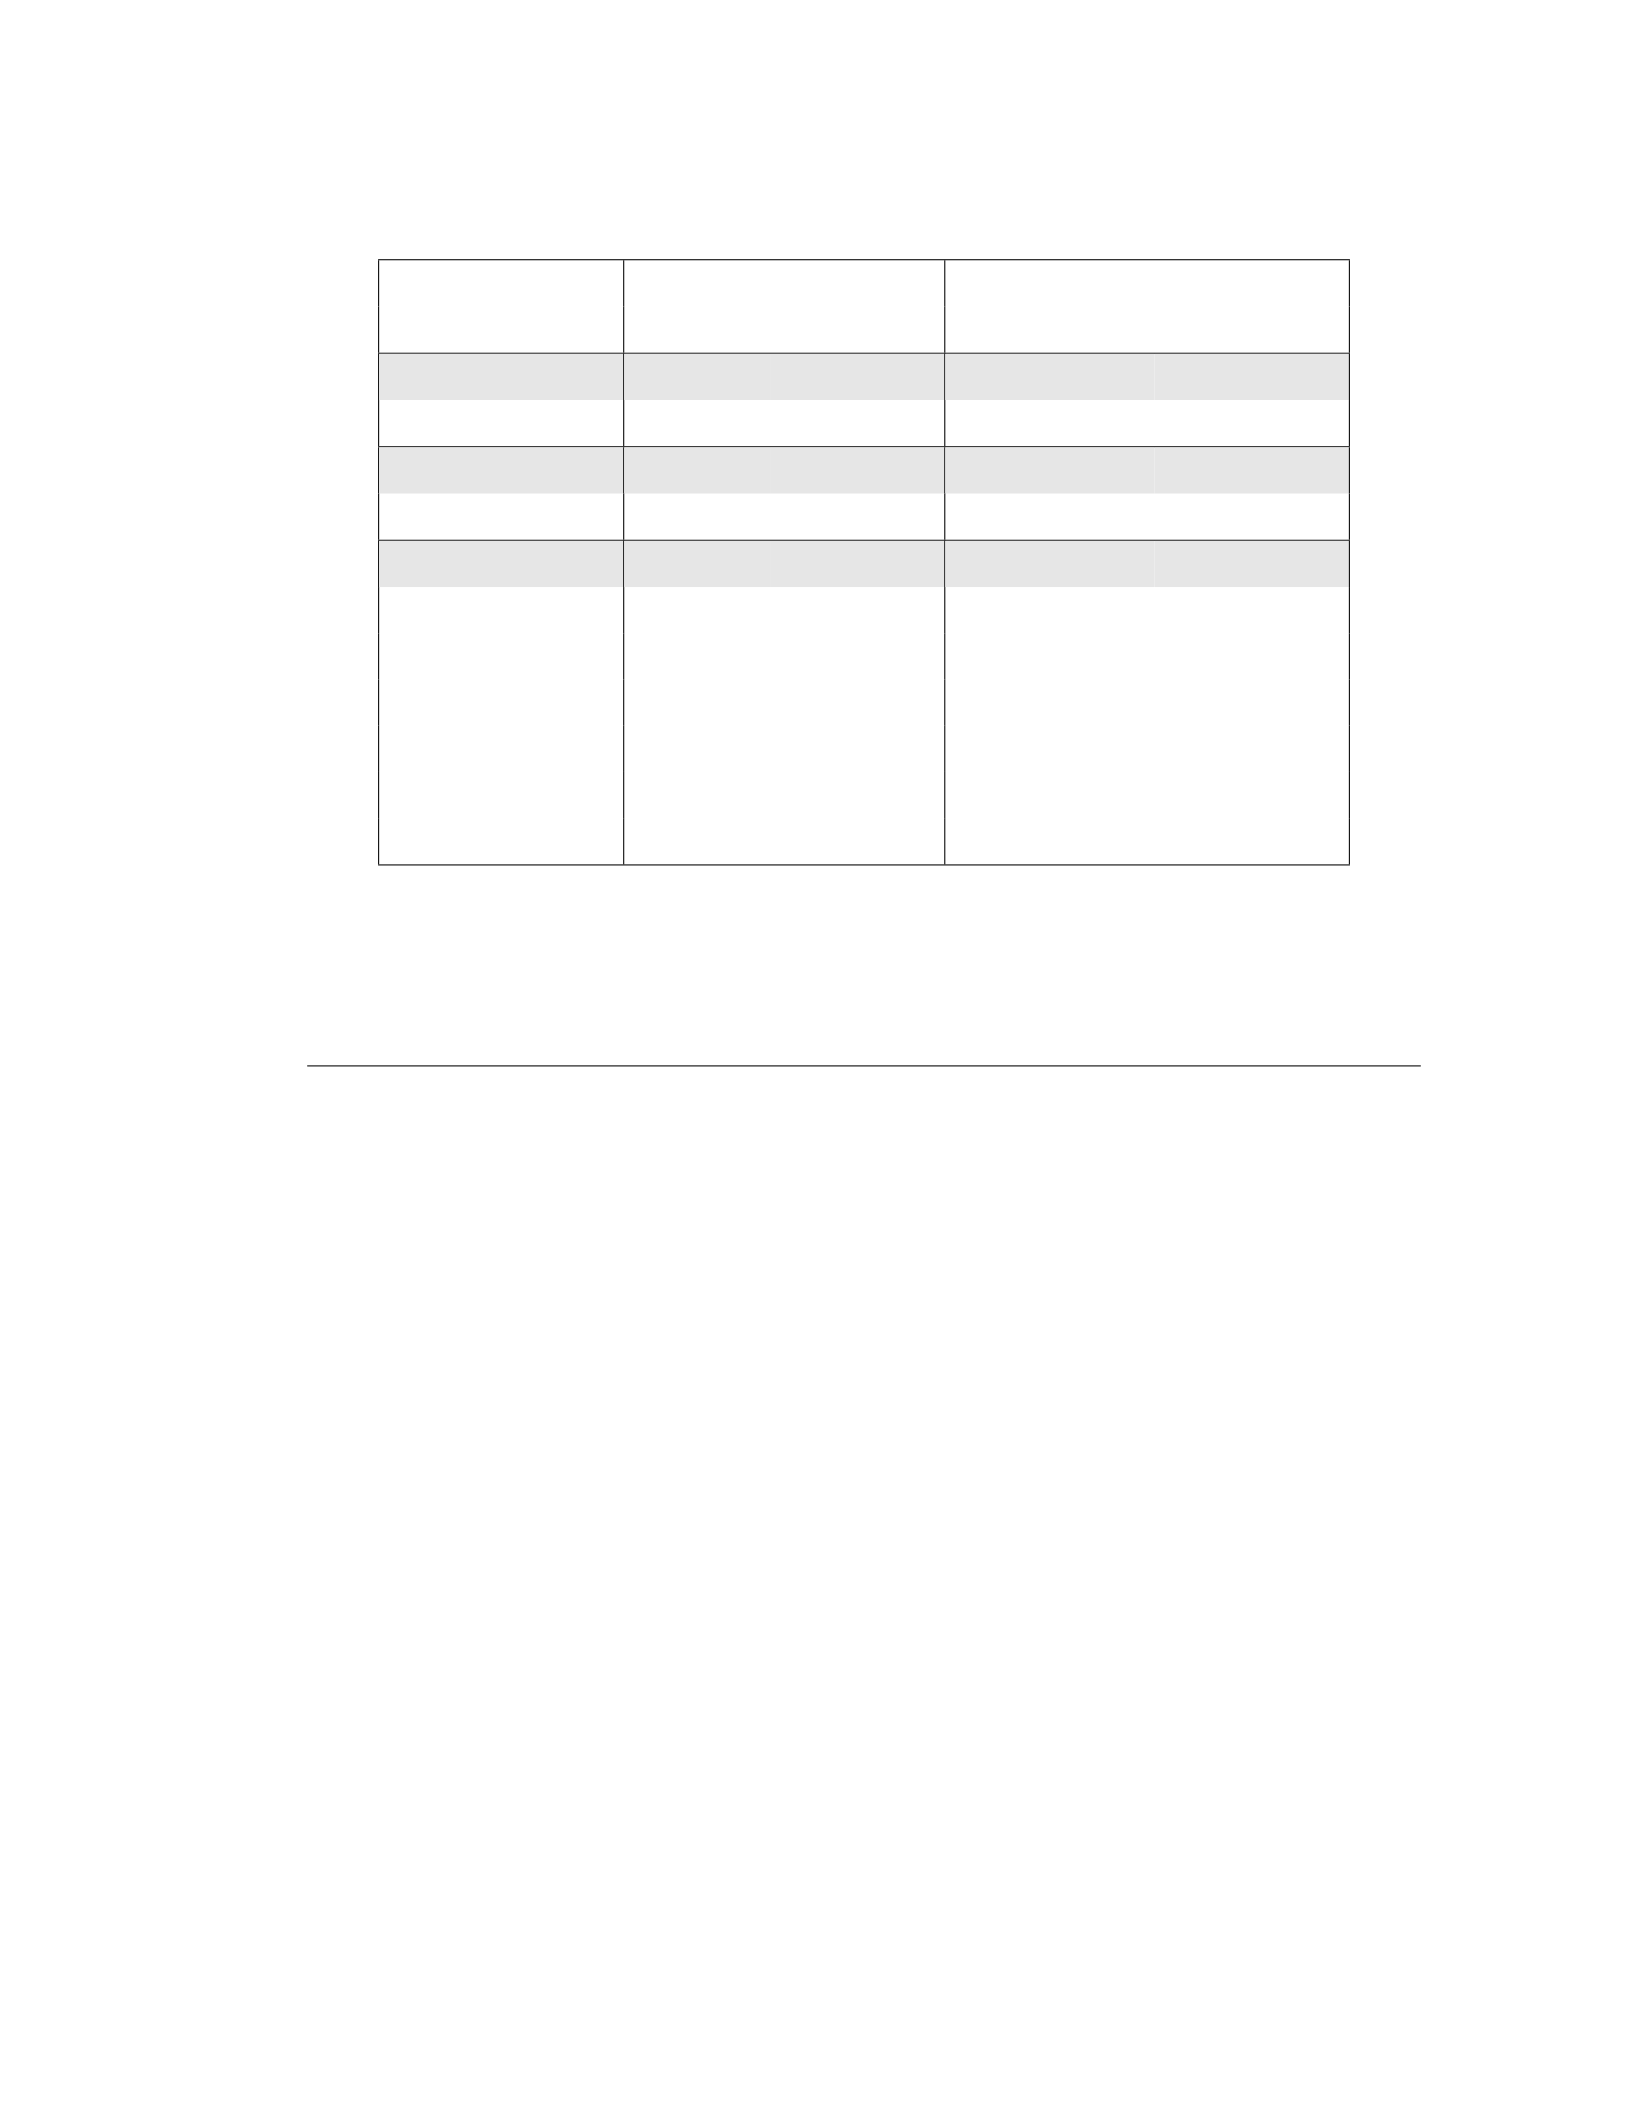
100
Work Server Effort Client Effort
Function Issue() Verify() Solve()
Exponential
Time-Lock 2,500µs 1.1µs deterministic Dc
Hash Collision
MicroMint – Dc×1.1µs probabilistic Dc×∣range∣
Hash Reversal
Basic – 1.1µs probabilistic 2Dc
kSub-Puzzles 1.1µs k ×1.1µs probabilistic k×2Dc
TLS 1.1µs –probabilistic 2Dc
Hashcash – 1.1µs probabilistic 2Dc
Hint-Based 2.1µs 1.1µs probabilistic Dc
Targeted – 1.1µs probabilistic Dc
Table 4.1: Comparison of work function constructions. All of them, save for the
Time-Lock construction, are hash based and use probabilistic solution algorithms.
The Hint-Based and Targeted Hash Reversal constructions are our contributions.
The Work Function
Before describing the internal operation of the system, we present the construction
of the work function employed by this approach. It is important to note that while
this work function is currently the best candidate for the kaPOW approach, the
approach is not dependent on this work function and could readily adopt another
work function construction if necessary for a particular Web application.
There are a number of work function constructions throughout the literature,
most of which are hash based. Table 4.1 compares the work functions in terms of
the effort to Issue() challenges and Verify() solutions, as well as the number
of “units of work” (as a function of the client-specific difficulty Dc) required to
Solve() them. For hash-based constructions, a unit of work is one execution of
the hash function which takes 1.09µs. For the Time-Lock construction, a unit of
work is squaring one integer modulo a large pseudo-prime which takes 0.75µs.
101
1,000
10,000
100,000
1,000,000
Hashes Required to
Solve()
MicroMint
Basic, TLS, Hashcash
Hint-Based, Targeted
1
10
100
1,000
1
10
100
1,000
10,000
100,000
Hashes Required to
1
10
100
1,000
10,000
100,000
Difficulty Setting (Dc)
Figure 4.4: Comparison of hash-based work functions. Shown are the hashes
required in practice to solve the various work functions across a range of difficulties.
The computationally expensive issuance of the Time-Lock work function
makes the construction impractical for combating resource consumption attacks,
in particular attacks that flood request packets. In contrast, hash-based work
functions are easy to issue and verify. Figure 4.4 shows the effort required to solve
the various hash-based work functions. Each data point represents the average
number of hashes to solve 10,000 work functions of that particular difficulty.
The MicroMint, Basic, TLS, and HashCash constructions require effort
exponentially proportional to the difficulty Dc. At high difficulty values the coarse
work-resolution prevents a policy from accurately setting a client’s effort. Consider
that after difficulty Dc=20 (requiring 1 million hashes or roughly 1 second to solve)
the constructions cannot issue work functions with intra-second granularity and
after difficulty Dc=29 (requiring 73 seconds to solve) the constructions cannot
issue work functions with intra-minute granularity.
102
In contrast, the Hint-Based Hash Reversal and Targeted Hash Reversal
constructions are able to issue work functions with fine-grained solution effort
through the full range of difficulties. The Hint-Based construction achieves this
by selecting a solution and giving a hint within Dcsteps from that solution. This
requires more effort to issue work functions than the Targeted construction, making
it comparatively weaker when combating resource consumption attacks such as
those based on request flooding.
For efficient issuance and verification, and finely targeted solution effort, the
mod kaPOW prototype employs our Targeted Hash Reversal construction2. The
work function is of the form:
H(Nc∣∣ Dc∣∣ A)≡0mod Dc(4.1)
where His a pre-image resistant hash function with output uniformly-distributed
(e.g., SHA1 [84]), Ncis a client-specific nonce generated by the module, Dcis the
client-specific difficulty set by the module, and Ais the solution that the client’s
JavaScript solver must find. Since both Ncand Dcare fixed by the issuer and H
is pre-image resistant, this work function requires the solver to perform a brute-
force search to find a value for Athat satisfies the equation. The probability that
any given value for Asatisfies the equation is 1
Dc, and the expected number of
attempts to find a valid value are geometrically distributed with a mean of Dc.
This is experimentally validated in Figure 4.4.
This work function is a good candidate because it is efficiently implementable.
Specifically, it requires no hashes to issue and an answer can be verified in a single
hash. Using a hash function like SHA1 with a sufficiently large digest, this takes
only 1.09µs in software [37]. Additionally, the work function can be expressed
compactly: the issuer simply has to send Dcand Nc, and a verifier only needs
those parameters and the solution Ato verify that the equation is satisfied.
2This construction was presented in a paper at Global Internet 2007 [36].
103
The Server Module
The intelligence of the mod kaPOW system is within an Apache Web server module.
Apache provides a rich interface for writing modules that range from those
that control how a client accesses a server (such as mod rewrite) to those that
dynamically generate content (such as mod include). As a result, Apache lends
itself well to supporting a proof-of-work module3. The module has two filters;
an issuing filter that embeds work functions into outbound HTML content and
averifying filter that prioritizes inbound requests based on whether or not they
contain a correct answer to a valid work function.
To prioritize requests, the server is configured with two virtual hosts. The
default low-priority virtual host does not support persistent HyperText Transfer
Protocol (HTTP) connections, and tears down any connection after servicing
a single request. Only a limited number of low-priority requests are handled
concurrently; all excess low-priority requests are rejected with HTTP error code
503:Service Temporarily Unavailable. Any request demonstrating a correct
answer to a valid work function is redirected to the high-priority virtual host which
supports more concurrent requests and allows persistent connections. If a client
sends a subsequent request with an incorrect answer or an invalid work function,
the connection is transferred to the low-priority virtual host to be terminated.
Client-Specific Variables
During the course of their operation, the issuing and verifying filters refer to the
client-specific difficulty Dcand nonce Nc. To establish Dc, the module uses a
counting Bloom filter [14, 33] to track the load imposed (i.e., requests sent) by each
client. The counting Bloom filter is an efficient data structure that offers a tradeoff
between its size and the probability of incorrectly assigning a high difficulty to a
client. It has no false negatives (i.e., a malicious client will never be issued a trivial
3The Apache module naming-convention inspired the name “mod kaPOW”.
104
work function) and the probability of a false positive can be driven arbitrarily low
with additional memory.
Given that the Bloom filter uses kdifferent hash functions to index into an array
of ncounters, the probability of misclassifying a single client from an estimated
population of mclients is approximately (1−e−km
n)k. Using a value of kthat
minimizes that equation, the error is approximated by 0.6185 n
m. Thus to achieve a
misclassification rate of less than 0.1% of 20,000 clients, the Bloom filter requires
288,000 counters or a total of 1.2MB when using 32-bit counters. The Bloom filter
is updated every 10 seconds so that the difficulty is held constant long enough
to give clients a chance to respond, but short enough so that the difficulty can
respond to sudden changes in load. When the structure is updated, each counter
cin the filter is updated according to the following logic:
ct+1=⎧
⎪
⎪
⎨
⎪
⎪
⎩
ct+rt−decay rt≤decay
ct+1.01rt−decay otherwise (4.2)
which states that the difficulty decays linearly from one time window to the next
unless the requests rtin the latest time period tare greater than the rate of decay,
in which case those extra requests exponentially increase the difficulty.
The client-specific nonce Ncis created by concatenating the client’s identity
IPc, the original unmodified U RL, and a server nonce Ns:
Nc=IPc∣∣ URL ∣∣ Ns(4.3)
binding the client nonce and thus the entire work function to the client and specific
content for a fixed window of time. When the server nonce changes the client nonces
also expire, meaning solutions cannot be reused indefinitely. The unpredictable
server nonce prevents attacks where adversaries solve work functions offline and
stockpile valid answers. The server can update its nonce independently from the
Bloom filter and as frequently as needed to keep client solutions fresh, however,
the prototype presently updates the nonce and Bloom filter simultaneously.
105
<HTML>
<HEAD>
<SCRIPT TYPE='text/javascript' SRC='kaPoW.js'></SCRIPT>
<TITLE>Sample Content Page</TITLE>
</HEAD>
<BODY>
<H1>Sample Content Page</H1>
This webpage demonstrates an image and link protected by
proof-of-work.<BR><BR>
<IMG SRC='test.jpg?Dc=0'Nc=a53b6145 Dc=10> are solved when
the page is loaded to avoid delay.<BR> In contrast,
<A HREF='/?Dc=0'Nc=52a6c561 Dc=10>
POW-protected links</A> are solved only when the link is clicked.
</BODY>
</HTML>
Figure 4.5: HTML markup of modified example document. The link to the
solution JavaScript file and the added work function variables are highlighted.
The Issuing Filter
The issuing filter scans and parses HTML documents as they are served. It adds
work functions to all tags containing URLs as well as a link to the JavaScript solver
necessary for the client’s browser to solve the work functions. The modification to
an example document is shown in Figure 4.5.
The issuing filter includes the solution instructions for work functions through
the addition of a link to a JavaScript file (kaPOW.js) at the head of the document
so that it is retrieved first (if not already cached) and the script may work as
the remaining tags are incorporated into the client’s in-memory Document Object
Model (DOM). Despite containing a URL, this tag does not have a work function
because clients need this resource before they can possibly solve any work function.
The issuing filter incorporates work functions into tags by adding the variables
Ncand Dcas tag attributes. To avoid accidentally triggering HTML escape
sequences, the values are transmitted in hexadecimal. It is important to observe
that Ncdiffers between tags because it is calculated from the original unmodified
URL in each tag. The filter also appends a default difficulty of zero (“Dc=0”) to
the actual URL so that clients without JavaScript enabled can follow the link and
indicate to the server that they cannot solve work functions. Before sending the
content, the issuing filter updates the Bloom filter to note the client’s request.
106
The Verifying Filter
The verifying filter parses request URLs and extracts any appended proof-of-work
variables. If the request URL contains the variables Ncand Dc, they must be
verified as current and correct before the module does computationally expensive
operations such as hashing. If Ncand Dcare valid, the verifier proceeds to check
that Asatisfies the work function. If everything checks out, the request is accepted
by the high-priority virtual host and the content is sent to the client.
There are three reasons why a client’s request might be rejected by the verifying
filter: the URL has no work function or solution attached, the work function
parameters are not current, or the attached solution is not valid. The first two
failures may have occurred for a variety of legitimate reasons and are not necessarily
indicative of a malicious client.
If the request URL contains no POW parameters, then the client may have been
linked to this resource from an external server that has not yet adopted the kaPOW
system and hence did not issue a work function to the client. It is also possible that
the client arrived at this website by manually entering the URL into the address
bar of their Web browser – users are not expected to know nor manually append
work function parameters and a solution into URLs since it would be incredibly
impractical for them to do so.
If the request URL contains POW parameters but they are invalid, the client
may have been directed to this site from an external server that appended its
own, different values for Ncand Dc. Alternatively, the user may have spent long
enough reading the last webpage that the server has since updated its nonce Ns
and has thus expired the stale client nonces Ncembedded in that webpage. The
mod kaPOW module ensures that old webpages which may be cached expire at the
same frequency that clients do. This is done by updating the HTTP ETag value (a
metadata string that represents the version of the webpage content) for webpages
whenever the server nonce changes.
107
<HTML>
<HEAD>
<SCRIPT TYPE='text/javascript' SRC='kaPOW.js'></SCRIPT>
<TITLE>Error: Invalid POW</TITLE>
</HEAD>
<BODY ONLOAD='Solve(document.links[0]);
window.location.replace(document.links[0].href)'>
<H1>Invalid POW</H1>
The requested URL did not have a valid proof-of-work attached.<BR>
If you are reading this page, it is likely that you do not have
JavaScript enabled.<BR><BR> If you would still like to try to
access the content, please click the following link:
<A HREF='http://maes.cs.pdx.edu/?Dc=0' Nc=52a6c561 Dc=10>
http://maes.cs.pdx.edu/</A><BR><BR><HR>
</BODY>
</HTML>
Figure 4.6: HTML markup of kaPOW error page. This page is sent in response
to a URL that had an invalid work function or an incorrect solution. The script
redirecting the Web browser to use current POW parameters is highlighted.
Regardless of the reason, when a request is denied the filter returns an error
page to the client such as the one in Figure 4.6. The error page contains some
text explaining the error and a single link to the requested content. After it has
been processed by the issuing filter, it has a work function embedded into it.
The key feature is highlighted; the error page includes an OnLoad() script which
immediately solves the work function and redirects the browser to use the proper
URL. The client’s Web browser is instructed to omit this error page from the
browsing history so the user may never actually see this page displayed.
A notable exception is this error page will not automatically redirect clients who
do not have JavaScript enabled. Recall that the issuing filter embeds “Dc=0” into
all URLs found within HTML tags. If a client’s browser does not have JavaScript
enabled it will not solve the work function and will instead use the URL verbatim.
When the verifying filter observes a URL with the variable Dcset to zero, it
will conclude that the client cannot solve the work function and will accept the
request on the low-priority virtual host. This allows non-JavaScript clients to
access the content they seek (although there is a chance that the low-priority server
is inundated with requests and may not be able to service theirs) without giving
adversaries a means to disturb clients who correctly solve the work functions.
108
The Client Solver
While the client end of the system can be computationally demanding, particularly
for malicious clients, it is functionally simple. The browser executes a few scripts
found in the JavaScript file (kaPOW.js) linked at the head of the HTML document.
The Solve() script is used to solve individual work functions that the browser
encounters. The script takes a tag with a URL as input and extracts the
variables Ncand Dcand systematically hashes them with various values for Auntil
Equation 4.1 is satisfied. The script removes existing POW variables embedded in
the URL (specifically the “Dc=0”) and appends the new Nc,Dc, and Ato the URL
stored in memory for when the browser needs to fetch the referenced resource.
Another script runs as soon as the HTML file is read and hooks into the event
triggered when tag elements are added to the DOM. As content tags (such as
<IMG>) are added, this script calls Solve() so that the URL in the tag is valid
before the browser fetches that content. As hyperlink tags (<A>) are added, they
have their ONCLICK attribute modified to call Solve() so those work functions are
only solved if the user chooses to follow the link.
4.4 EVALUATION
To evaluate the effectiveness of the kaPOW approach, mod kaPOW was implemented
in C as an Apache v2.0 module. The module supports a simple load-based difficulty
policy using a Bloom filter. The Bloom filter’s counters start at zero and are
updated every 10 seconds to count the request activity in the previous 10 seconds.
The Bloom filter’s decay constant is set to 10 so that as long as a client sends fewer
than 10 requests every 10 seconds they will not be issued a work function (i.e., Dc
will remain zero). If a client sends more than 10 requests every 10 seconds, the
surplus requests exponentially increase the counters so the client will subsequently
be required to solve very difficult work functions in order to receive service. The
prototype is Web accessible and was demonstrated at SIGCOMM 2008 [62, 64].
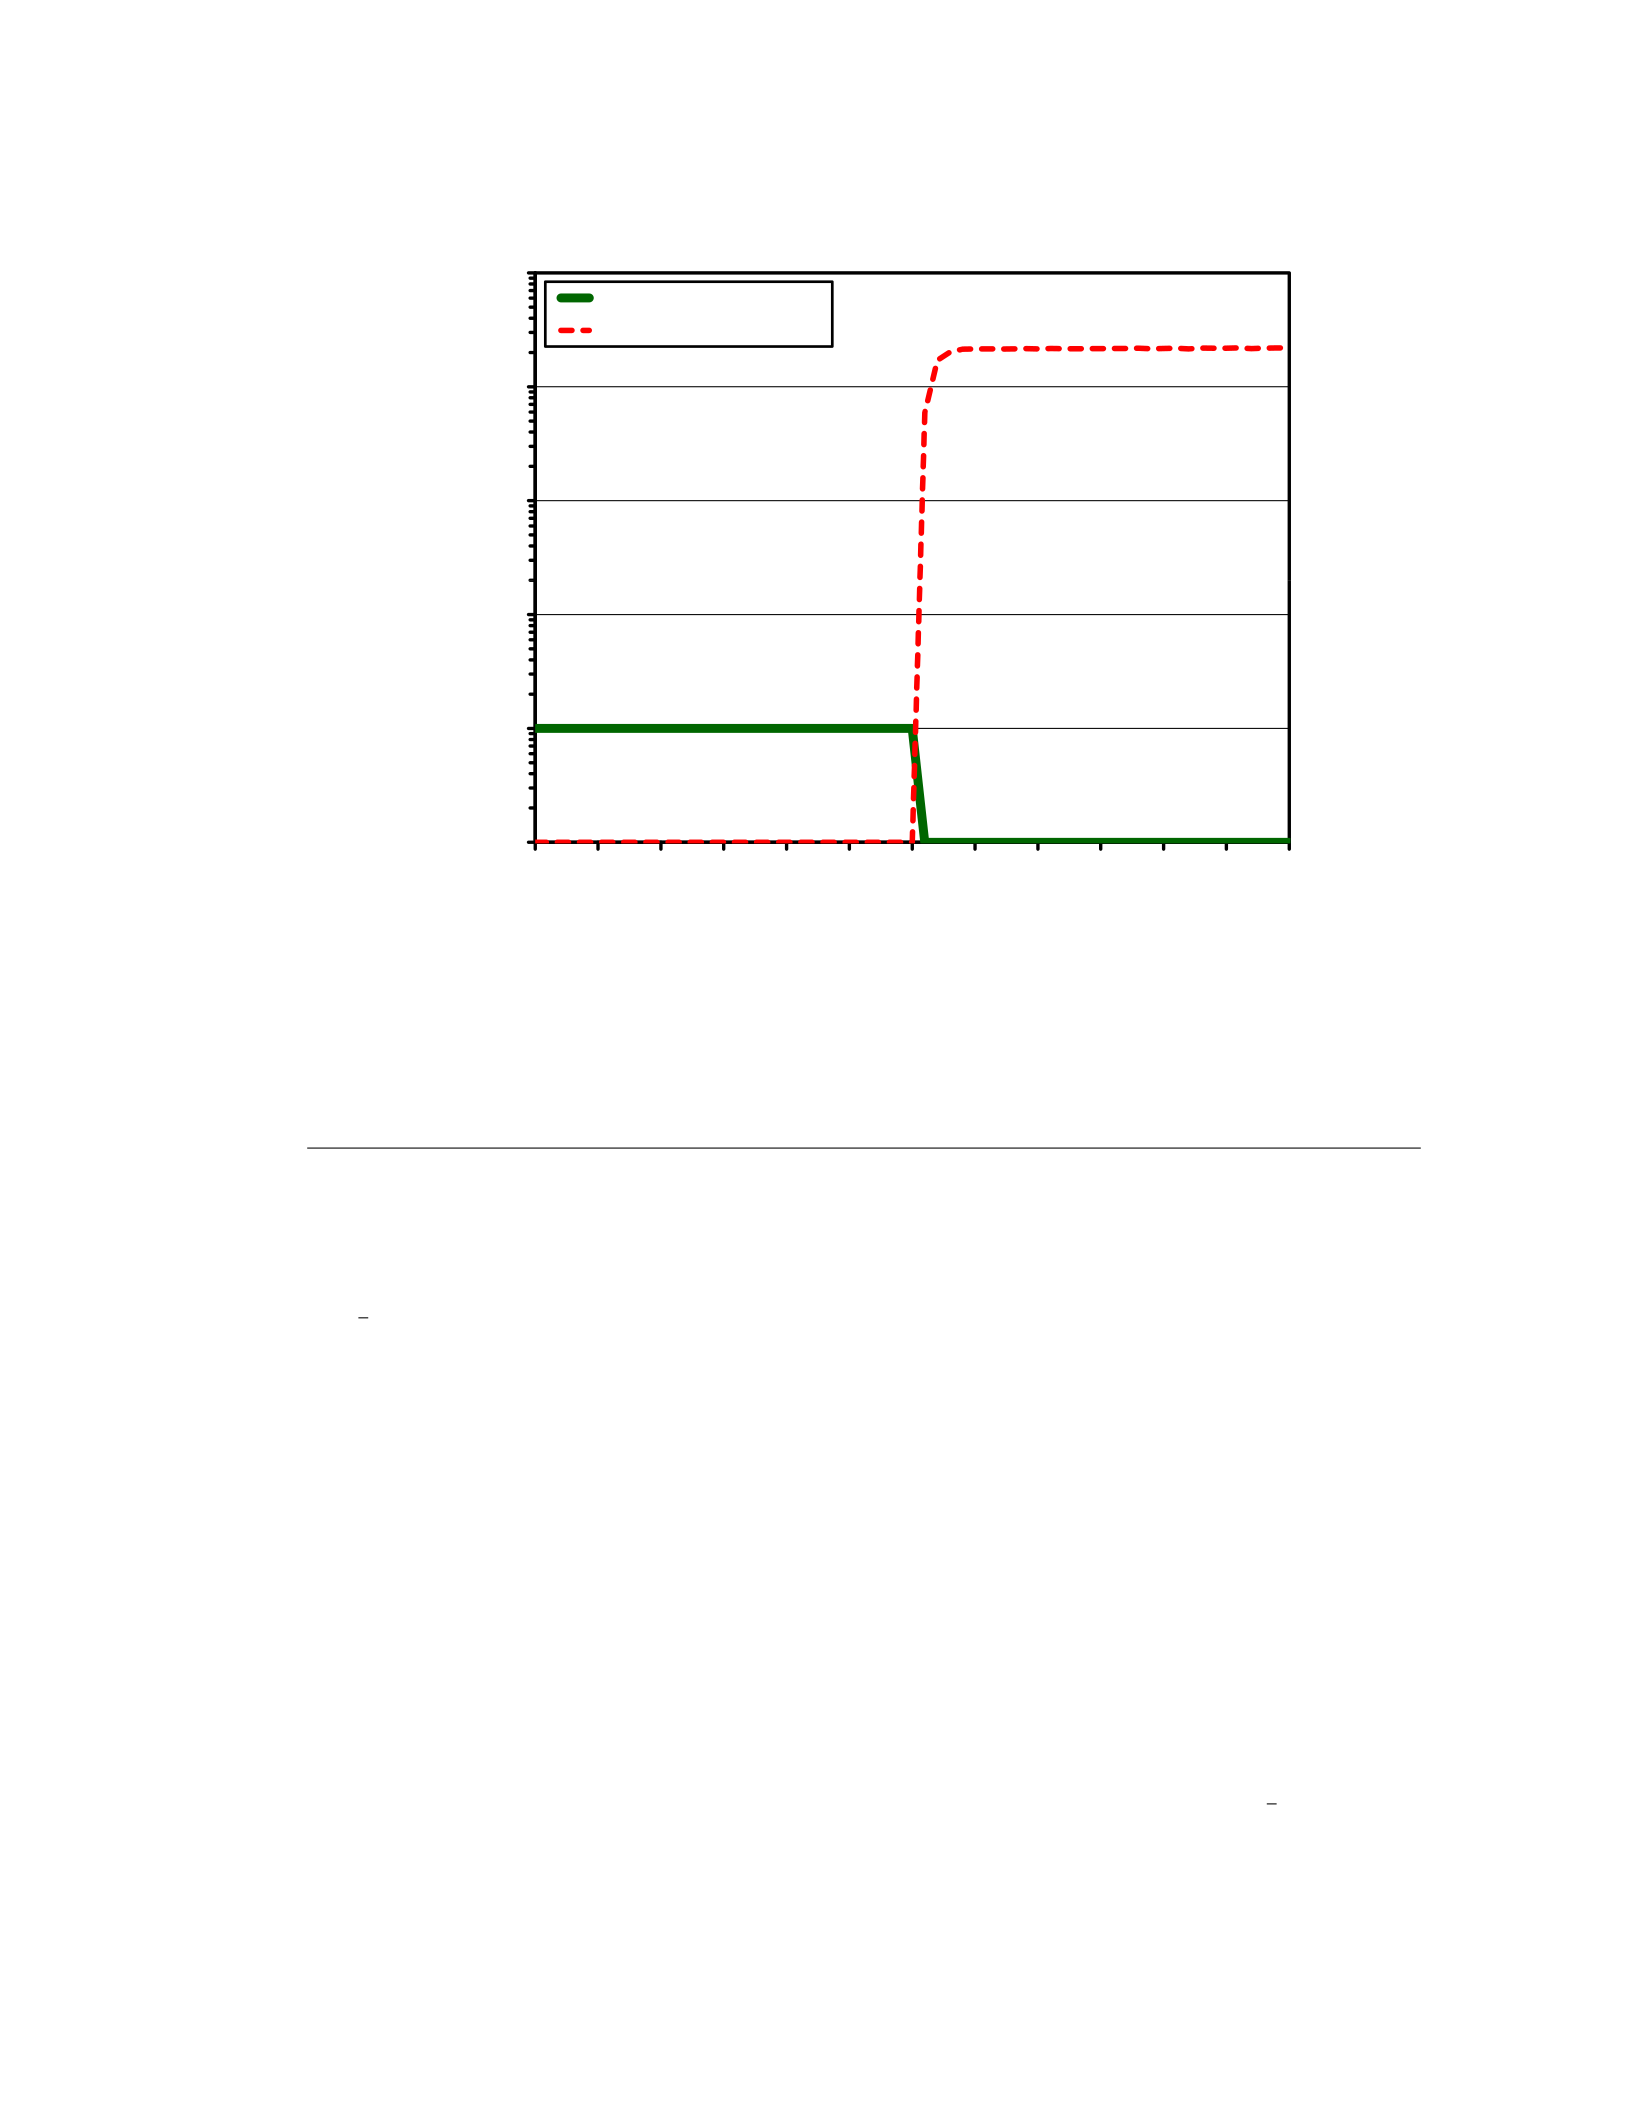
109
100
1,000
10,000
Requests per second
Good Client
Aggregate Adversaries
0
1
10
0 5 10 15 20 25 30 35 40 45 50 55 60
Requests per second
Time (s)
Figure 4.7: Flooders vs. default Web server. Starting at time t=30, the
unprotected server is saturated by the flooders who connect and continuously send
requests as fast as possible; the good client cannot get any more requests serviced.
4.4.1 Experimentation
mod kaPOW Thwarting Flooders
In this experiment, we set up a network of six 1.8GHz dual processor Intel Xeon
machines connected by Gigabit Ethernet interfaces: a server running Apache v2.0,
a good client which requests a webpage once every second, and four flooding
adversaries that attempt to saturate the server with requests. While this setup is
far from the magnitude of a real botnet, the server is configured to give adversaries
an advantage over the good client by only accepting four persistent connections.
This means if the four adversaries connect and remain connected, they will deny
service to the good client as demonstrated in Figure 4.7. Without mod kaPOW, the
adversaries occupy the server indefinitely, sustaining 2,150 requests per second, yet
the good client cannot establish a connection to get a single request serviced.

