


Summative Assessment 2
Benta Wanjiru Irungu
R2311D17355747
Quantitative Data Analysis
UEL-DS-7006
Part 1: Summative Assessment 2
Due date: 30th June, 2024

SECTION A
Introduction
This section covers some case studies that we will evaluate and critique. The case studies aim to
test how best we understand the concept of data analysis from data collection, sampling methods
and techniques, analysis, and conclusion. In this section, we will critically analyze the two case
studies to identify the shortcomings in the data analysis process, provide critical
recommendations, and showcase our understanding of and ability to interpret statistical
inferences and results correctly.
Assess the researcher's analysis and conclusions on the case study to determine the
relationship between social class and a number of books read in a year.
This case study details research conducted to determine the relationship between social class and
the number of books read in a year. We will critically analyze how the researcher conducted the
research, including data collection, statistical analysis, inference generation, and interpretation.
Sampling method
The researcher interviewed 100 people in a library from their home town on a first come basis,
which describes the convenience sampling method. According to Emmerson (2021, pp.76-77),
convenience sampling is a non-probability sampling method that involves collecting data from
members of the population who are readily available to participate in the study. The first
accessible primary data source is utilized for the research without further criteria. The
convenience sampling method is prone to bias and misrepresentation as the sample conveniently
selected for the study is only sometimes a true reflection of the study population. In our case, the
100 people conveniently chosen from the library do not represent the actual population of the
people in the researcher's hometown. The method is also biased because the people selected from
the library probably represent some folds of the social class classification, leaving out others in
the different folds. The bias and misrepresentation caused by convenience sampling make it
impossible to generalize the study results. The researcher would have used stratified random
sampling to achieve inclusivity in this study. Stratified random sampling is a technique in which
researchers initially split a population into smaller subgroups, or strata, based on common
characteristics among the members. The researcher then randomly selects individuals from each

subset to create the final sample (Berndt, 2020, pp. 224-226). In our case, the researcher would
have split the population into four strata containing the four folds of the social class
classifications, then randomly selected individuals from the four strata to form the sample size,
which would have ensured inclusivity, reduced bias and enabled for generalization of the study
results.
Statistical analysis method
The type of data used in this study is the classification of social class, which includes the upper
middle class, lower middle class, upper working class and lower working class, which is
categorical data. Categorical data describing social class, in this case, is qualitative data which
cannot be analyzed using Pearson's r method. The Pearson correlation coefficient is a descriptive
statistic that summarizes the characteristics of a dataset. It is particularly suitable when both
variables involved are quantitative (Obilor & Amadi, 2018, pp. 11-23). The researcher should
have adopted the ANOVA to achieve the best results while analyzing categorical data in this
study. According to Kim (2017, p. 22), the ANOVA statistical method is used to determine if
there are significant differences between the means of three or more independent groups. It is
beneficial for comparing multiple groups, such as our study's fourfold social class classification.
Statistical interpretation
The statistical analysis results using Pearson’s r indicated a correlation level (r) of 0.73. The
researcher interpreted this as 73% of the variation in the number of books read being accounted
for by social class. This interpretation is wrong as the researcher did not consider the coefficient
of determination, R squared. According to Obilor & Amadi (2018, pp. 11-83), R-squared
assesses how well a model fits the study data. It quantifies the proportion of variability in the
dependent variable (Y, in our case, number of books read) that can be explained by the
independent variable (X, in our case, social class). The R squared of our coefficient is 0.5329,
which is obtained by r^2 (0.73^2). This means that 53.29% of the variation in the number of
books read is explained by social class and not 73%, as indicated by the researcher.
Validity
Validity is the degree to which conclusions drawn from a research study can be deemed accurate
and dependable based on a statistical test (Dwork et al., 2015, pp117-126). The researcher used

the wrong sampling and statistical analysis methods, as indicated earlier in this critique. Due to
the use of the wrong methodology, the study's results cannot be termed valid.
Correlation and causation
In statistical analysis, correlation does not mean causation. This means that although there is a
correlation between the two variables, that does not indicate that the number of books read is
impacted or explained purely by social class (Barrowman, 2014, pp. 23-44). Other factors that
affect the number of books read in the town include access to the library, education level,
passion, age, income, and occupation, among others. This means that the researcher should
consider all other factors that explain the number of books read in the town.
Factors influencing the statistical significance of correlation coefficients: question 2 case
study.
This case study question aims to determine our understanding of the factors that affect the
statistical significance of the correlation coefficient. The case study describes a correlation
between income and scale measuring interest where, in one scenario, Pearson's r is 0.55 when the
level of significance is 0.05, rendering it insignificant. The other scenario describes a correlation
between income and scale measuring interest, where Pearson's r was 0.46, and the significance
level was 0.001, which was significant. Various factors affect the statistical significance of the
coefficients, and these determinates will be used to explain why the larger correlation is
insignificant while the smaller correlation is rendered significant.
Sample size
Correlations are calculated using samples from populations. The accuracy of a sample correlation
in representing the true situation in the total population depends on the sample size. Generally,
larger samples yield more stable and reliable correlations. Conversely, correlations derived from
small samples tend to be less reliable, increasing the probability of obtaining an artificially high
correlation coefficient (Schober, Boer & Schwarte, 2018, pp.1763-1768). In our case, the first
study indicated a high correlation of 0.55, which could have been attributed to the sample size
used is relatively small, rendering it non-significant as it makes it challenging to confidently
assert that the observed correlation is not a result of random variations. The second study
indicated a correlation of 0.46, which is lower than the one recorded in the first study but was

rendered significant. Despite the correlation being lower than, the significance of the correlation
in this study could be attributed to the study using a larger sample size. A larger sample size
enables a more accurate estimation of the true relationship between the variables.
P-Value
A p-value is a measure of probability used in hypothesis testing to determine whether sufficient
evidence supports a specific hypothesis about your data. In hypothesis testing, we formulate two
hypotheses: the null hypothesis and the alternative hypothesis. For correlation analysis, the null
hypothesis usually states that the observed relationship between the variables is due to chance.
The alternative hypothesis posits that the measured correlation is genuinely present in the data.
The correlation coefficient, r, is a unit-free value ranging from -1 to 1, with statistical
significance indicated by the p-value. The closer r is to zero, the weaker the linear relationship
(Biau, Jolles & Porcher, 2010, pp. 885-892). In our first study, a correlation coefficient 0.55
signifies a moderate positive relationship between the variables. However, since the p-value
exceeds 0.05, it suggests that the observed correlation might have arisen due to random chance,
thus the non-significance of the correlation. In our second study, the correlation coefficient is
0.46, indicating a weaker positive relationship than in the first study. Despite this, the coefficient
is deemed significant as the p-value is less than 0.001, suggesting that the observed correlation is
unlikely to have occurred by random chance.
Measurement variability
The two studies differ in how income and interest in work are measured and defined. People may
define the variables of income and interest in work differently in both studies, leading to
differences in the correlation (Li, Chen & Zhu, 2019, p. 527). People may define income
differently as this may mean only the monetary aspect, while others may consider other factors
besides the financial aspect, such as insurance and education benefits, among others. The context
of interest in work may also differ for people in various locations based on their beliefs and
social status. In a population where income is a key motivation for attaining interest in work,
there would be a positive correlation between the study variables as opposed to a population
where interest in work is mainly associated with other aspects such as work-life balance, where
the correlation may be low. Differences in sample demographics, employment status, and
industry sectors could influence the observed correlation in the two studies. In the first study, the

data variability could have been high due to bias in the sample. This could have been due to only
using individuals with high income in the sample, which made the correlationneeding to be more
significant. In the second study, although the correlation was less compared to the first study, it
remained statistically significant, possibly due to low variability in the dataset used. The low
variability comes from using a sample that is inclusive and unbiased.
Conclusion
In this section, we covered different aspects of correlation analysis, mainly using the Pearson's r
method. The first scenario we were able to critically analyze the results of the researcher's
analysis on the relationship between social class and number of books read in a year. From the
critical analysis we identified various aspects that influences the result while at the same time
questioning the methods used for data collection and analysis. we concluded that the results of
the analysis were not valid as the researcher used the wrong method of sampling and analysis.
The researcher also wrongly interpreted the statistical results which also invalidated the results.
From the 1st scenario, we able to identify the importance of using the correct sampling and
analysis method in analysis and we were able to correctly interpret the results of a Pearson’s r
method of analysis. The second scenario entailed explaining how a larger correlation could be
non-significant and the smaller correlation be significant. The stronger correlation observed in
the first study might not be statistically significant, indicated by a p-value greater than 0.05. This
suggests that the observed correlation could have occurred by chance, possibly due to the use of
small sample size or high data variability. Therefore, it is challenging to conclude that the
observed correlation is not as a result of random chance. In the second scenario, the study has
smaller correlation than the first study which was considered significant. The significance of the
correlation could have been attributed to using a larger sample size, using a p-value less than
0.001 and low data variability which indicates that the correlation did not happen by chance.
SECTION B
Introduction

In this section, we will demonstrate clear understanding of statistical analysis methods and their
applicability. We will provide a key understanding of the job survey data and provide the most
suitable method to study the relationship between ‘prody’ and ‘commit’ in the dataset. R is a
programing software which is key for performing statistical analysis. in this section we will use
R, to study the relationship between ‘prody’ and ‘commit’ and generate the necessary estimates
and fitting regression equations.
Statistical analysis of the relationship between ‘prody’ and ‘commit’ in the job survey data.
Data understanding
This statistical analysis uses the job survey data which includes data gathered from employees
across different organizations, encompassing various variables such as identification number,
gender, income, age, years of service, satisfaction levels, autonomy, job routine, attendance
records, skills, productivity, quality, and absenteeism.
Study variables
This study focuses on determining the relationship between two variables, ‘prody’ and ‘commit’.
‘Prody’ variable in the dataset indicates the rated productivity of employees in various
organization. Productivity is rated on a scale of 0-5 with 0 being least productive and 5 being
most productive rate. ‘commit’ variable in the dataset indicates the organizational commitment of
employees to various organization. The commitment is measured on a scale of 0-5, with 0 being
the least organizational commitment and 5 being the most organizational commitment. This
study therefore seeks to determine the relationship between rated productivity and organizational
commitment of employees in the job survey data. Both variable data have a natural ranking
which is on a scale of 0-5 with 0 indicating lowest rate and 5 indicating highest rate. The natural
ranking of both variables makes them ordinal data. Ordinal variables typically encompass ratings
on opinions or perceptions, as well as demographic factors categorized into levels or brackets.
Statistical analysis
Statistical statistics is highly dependent on the variables data types and both ‘prody’ and
‘commit’ are ordinal variables. Ordinal variables can be statistically analyzed using descriptive
and inferential analysis. For the descriptive statistics, we could find the frequency distribution of
the variables, mode, median and range. For inferential statistics, which would aim to find the
relationship between the two study variables, we would use the Spearman’s rank correlation
coefficient method.
The spearman’s rank correlation coefficient method
Spearman's Rank correlation coefficient is a method used to summarize the strength and
direction (positive or negative) of the relationship between two variables. The resulting value
will always range between 1 and -1, where 1 represents a perfect positive correlation and -1
represents a perfect negative correlation (Sedgwick, 2014, pp. 349). The Spearman’s rank
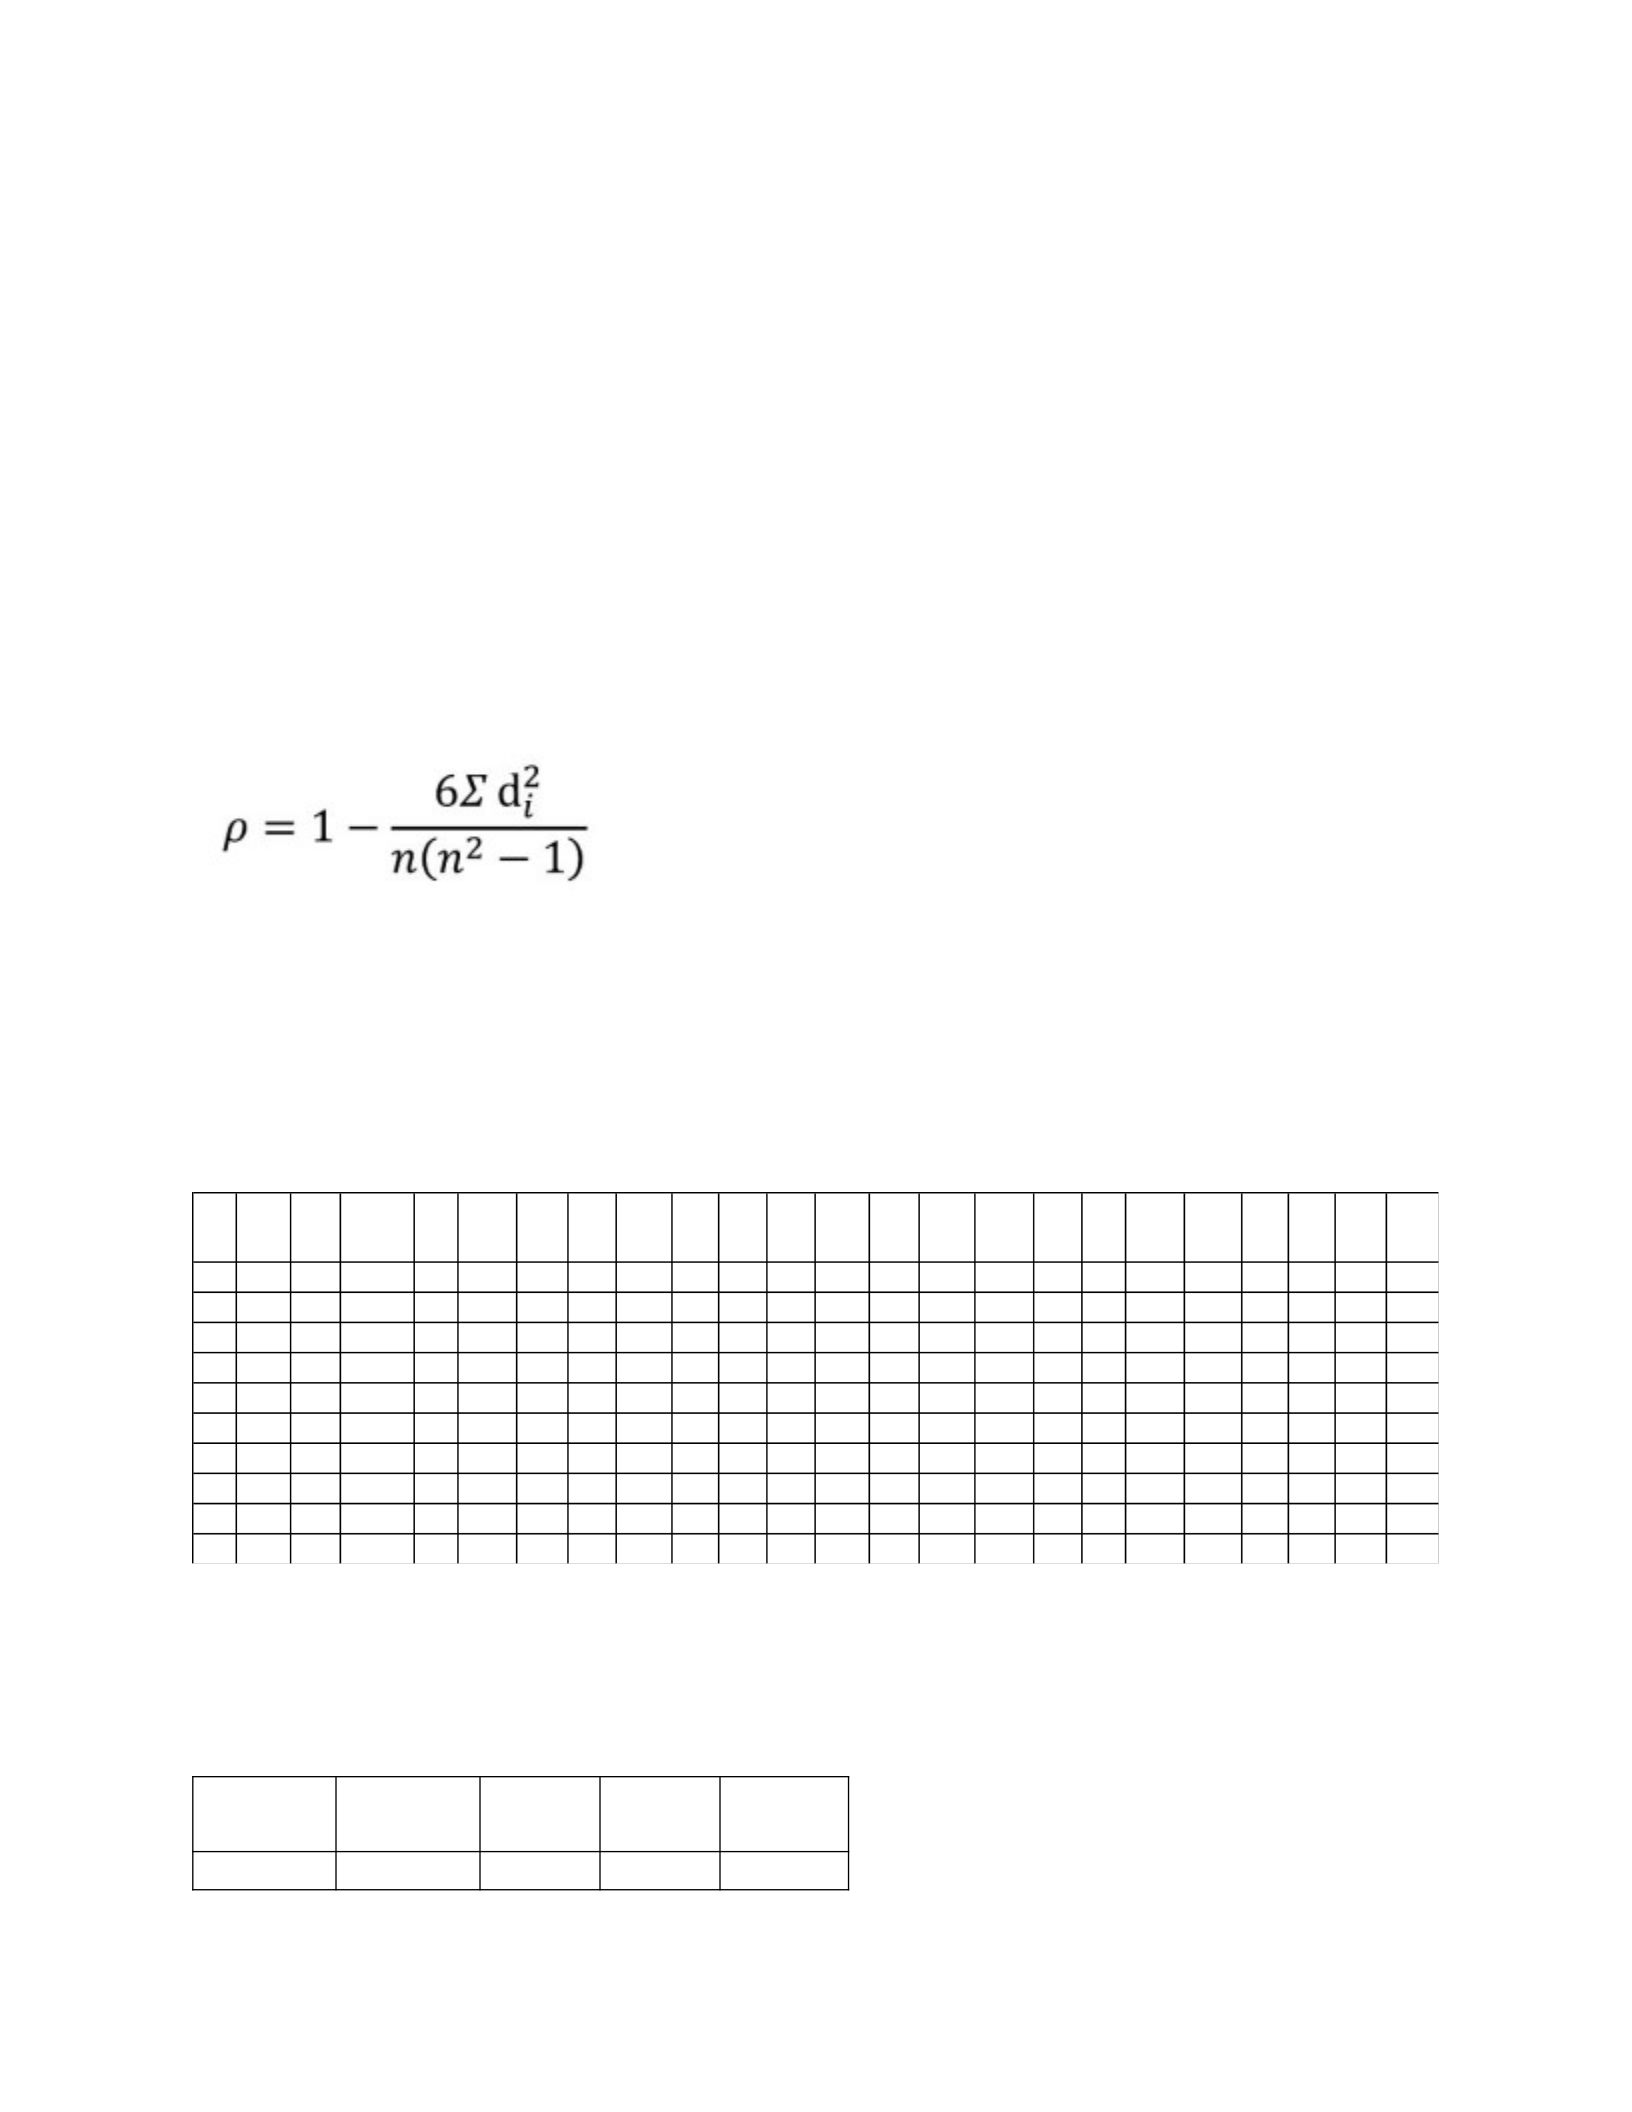
correlation formula is given by:
Where 𝝆 is the Spearman’s rank correlation coefficient, di represents the difference between the
two ranks of each observation and n is the number of observations (Sedgwick, 2014, pp. 349). To
mathematically calculate the spearman’s coefficient of our prody and commit in the job survey
data, we will use the first 10 entries of the data as follows.
id
ethn
icgp
gen
der
incom
e age years
com
mit
sati
s1
satis
2
sati
s3
sati
s4
aut
ono
m1
auto
nom
2
auto
nom
3
auto
nom
4
routi
ne1
rout
ine2
rou
tin
e3
routi
ne4
atten
d
skill
pro
dy
qual
abse
nse
1 1 1 1600 29 1 4 0 3 4 4 2 4 2 2 2 2 3 2 2 3 0 1 7
2 2 1 14600 26 5 2 0 0 2 3 2 2 1 2 3 4 4 4 1 3 4 4 8
3 3 1 17800 40 5 4 4 4 4 1 2 1 2 2 2 1 2 3 1 4 3 4 0
4 3 1 16400 46 15 2 2 5 2 4 1 2 2 2 3 2 2 3 2 3 3 4 4
5 2 2 18600 63 36 4 3 4 4 1 2 3 3 3 4 5 5 4 1 3 5 3 0
6 1 1 16000 54 31 2 2 5 3 3 2 1 1 2 4 4 4 4 1 1 3 4 1
7 1 1 16600 29 2 0 3 3 2 3 2 2 3 2 3 5 4 2 2 3 5 2 0
8 3 1 17600 35 2 5 2 2 4 2 3 4 3 2 3 3 3 2 2 3 4 4 2
9 2 2 17600 33 4 3 3 1 2 4 2 3 4 1 2 2 3 2 2 2 1 1 5
10 2 2 13800 27 6 4 3 2 3 3 2 1 3 2 3 4 3 5 1 2 2 4 4
The first step will be ranking, providing the rankings of both prody and commit. The second step
will be finding the difference between the two rankings and name the column d. the third step
will be finding the d squared. See the table below;
Id Commit Prody d d
squared
1 4 0 4 16
2 2 4 -2 4
3 4 3 1 1
4 2 3 -1 1
5 4 5 -1 1
6 2 3 -1 1
7 0 5 -5 25
8 5 4 1 1
9 3 1 2 4
10 4 2 2 4
The sum of d squared from the table above is 58
The fourth step will then involve applying our formula as follows;
𝝆 = 1- (6*58) / 10(100-1)
𝝆 = 0.65
The Spearman’s rank correlation coefficient of 0.65 indicates a moderately strong correlation
between prody and commit variables. The correlation suggests a moderately strong monotonic
relationship between employees rated productivity with the organizational commitment of
employees.
Statistical analysis of the relationship between ‘prody’ and ‘commit’ in the job survey data
using R
To perform statistical analysis of the prody and commit variables using R, we will follow the
following steps.
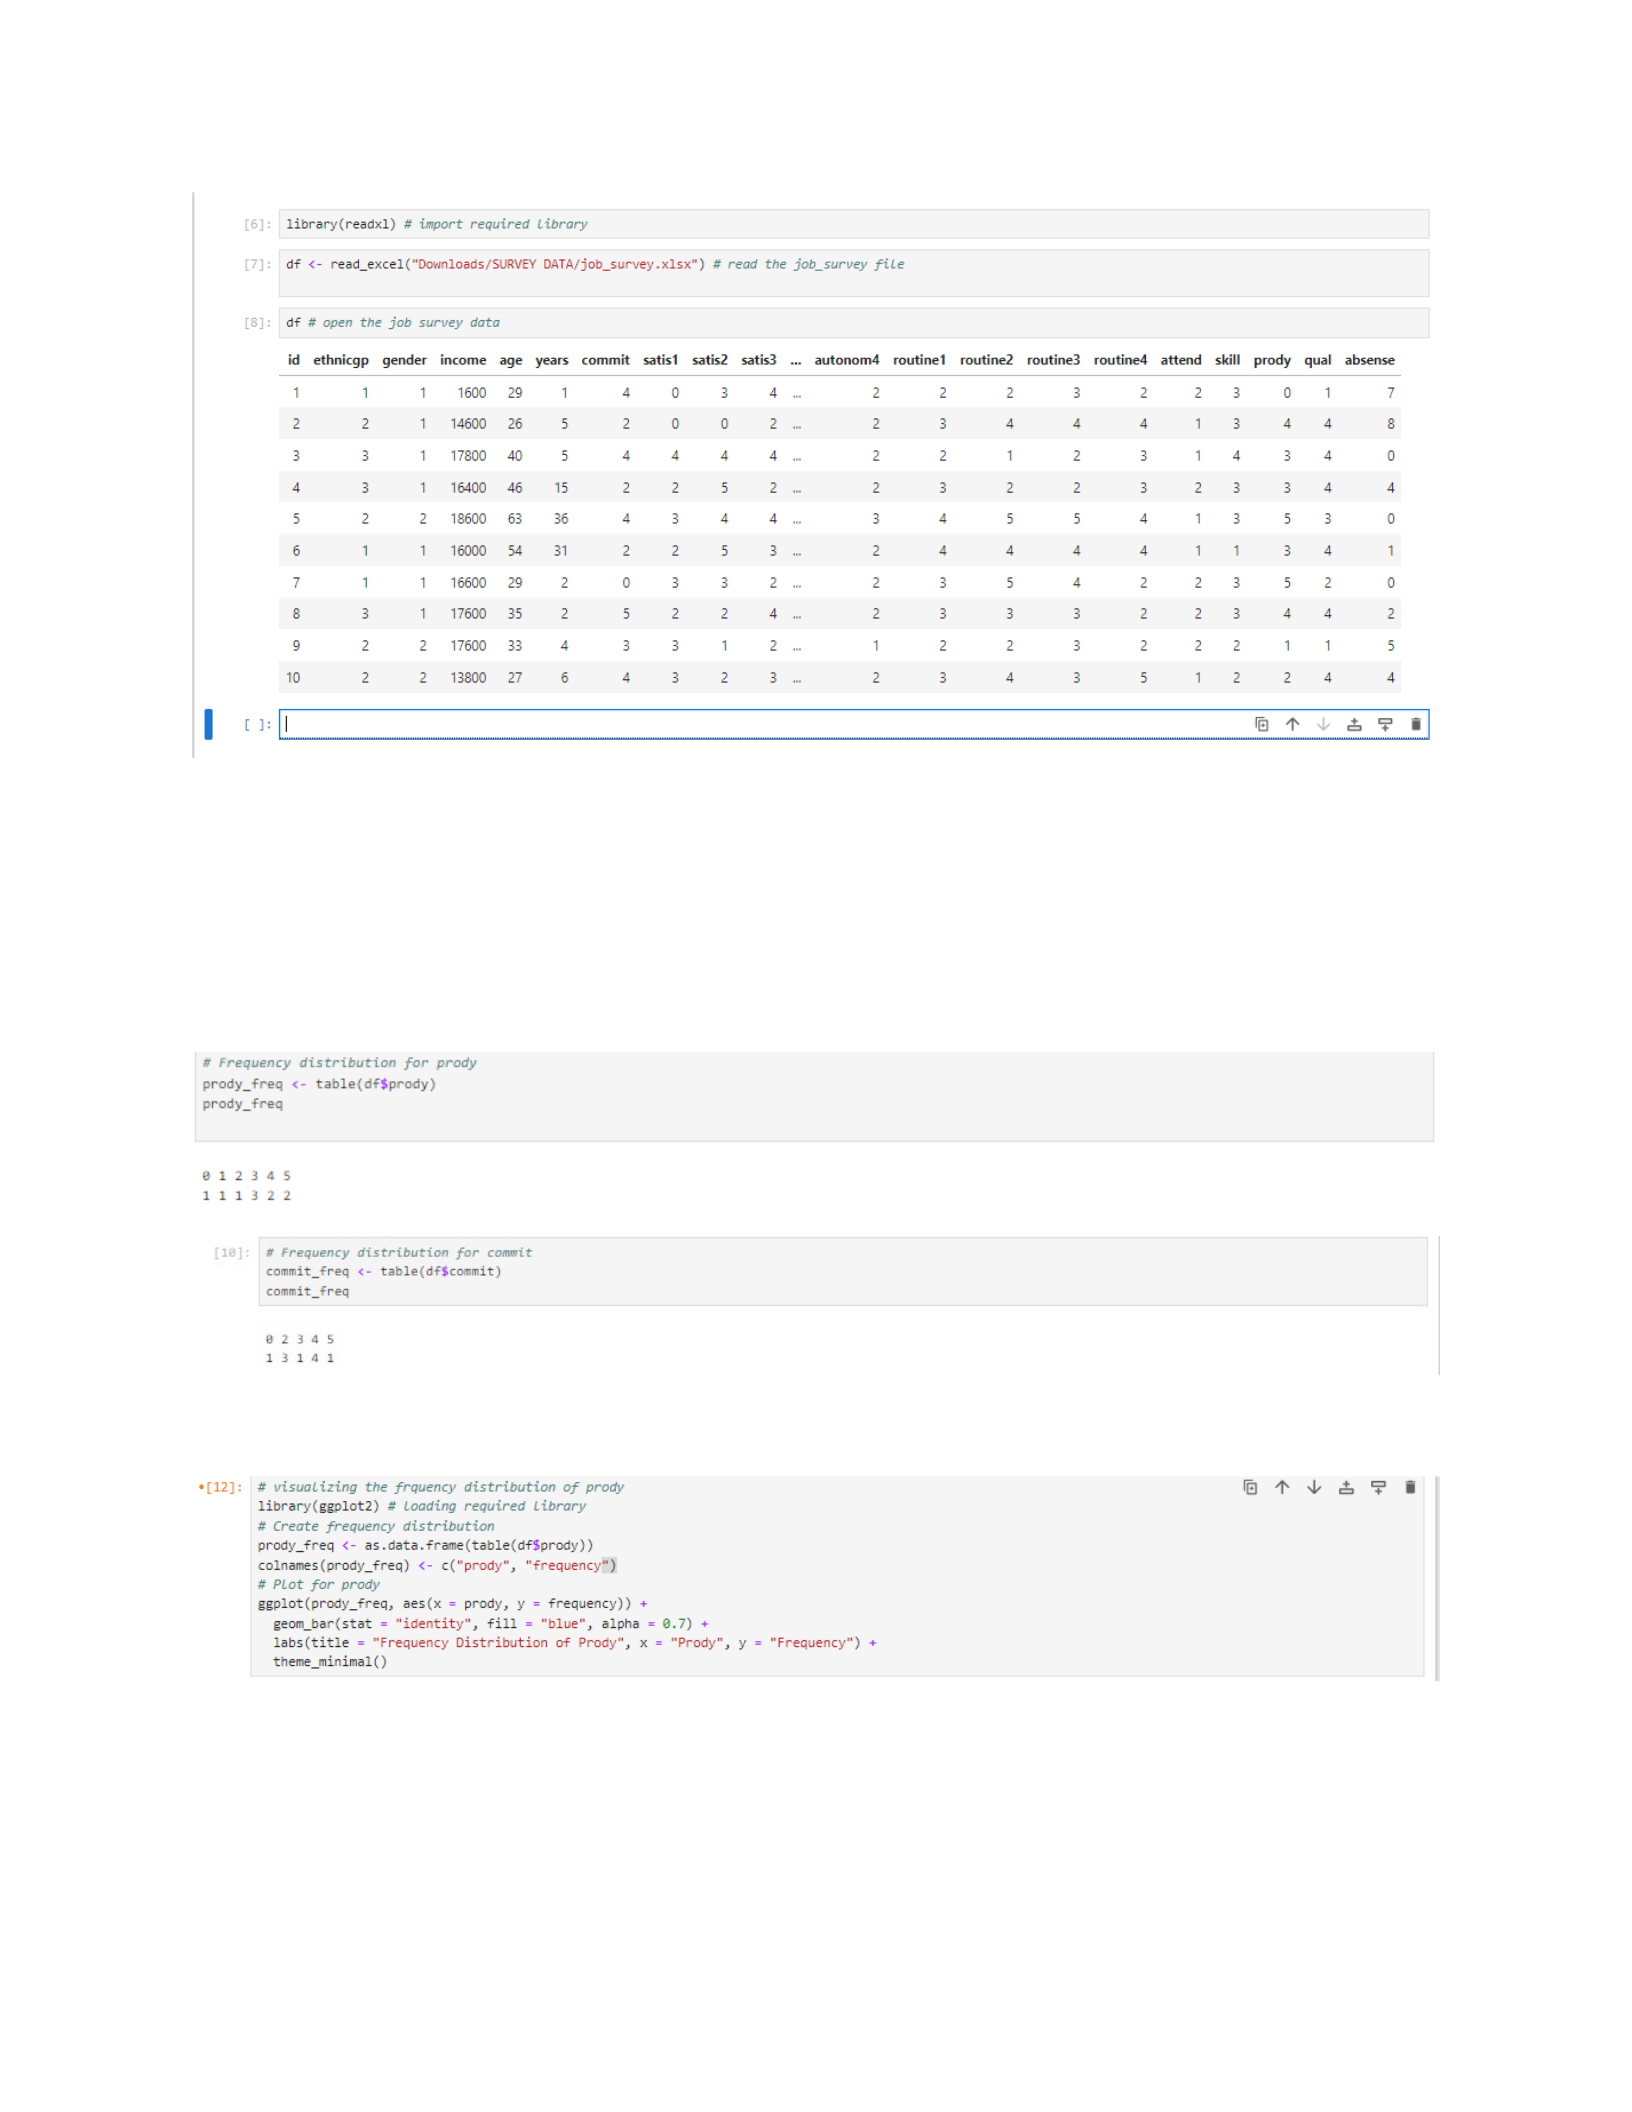
The first step entails creating an Excel file of at least ten employees with all the variables of the
job survey data. I used the information provided during the study describing the job survey data
in form of pdf and used the information collected from the 1st ten employees to create the excel
file. I opened a jupyter notebook running with an R kernel, and opened the file as a data frame as
shown below;
The second step entails performing the suggested descriptive statistics which include frequency
distribution, mode, median and range of the study variables.
Calculating the frequency distributions of prody and commit using the `table` function.
Visualizing the frequency distributions using the `ggplot2` package.
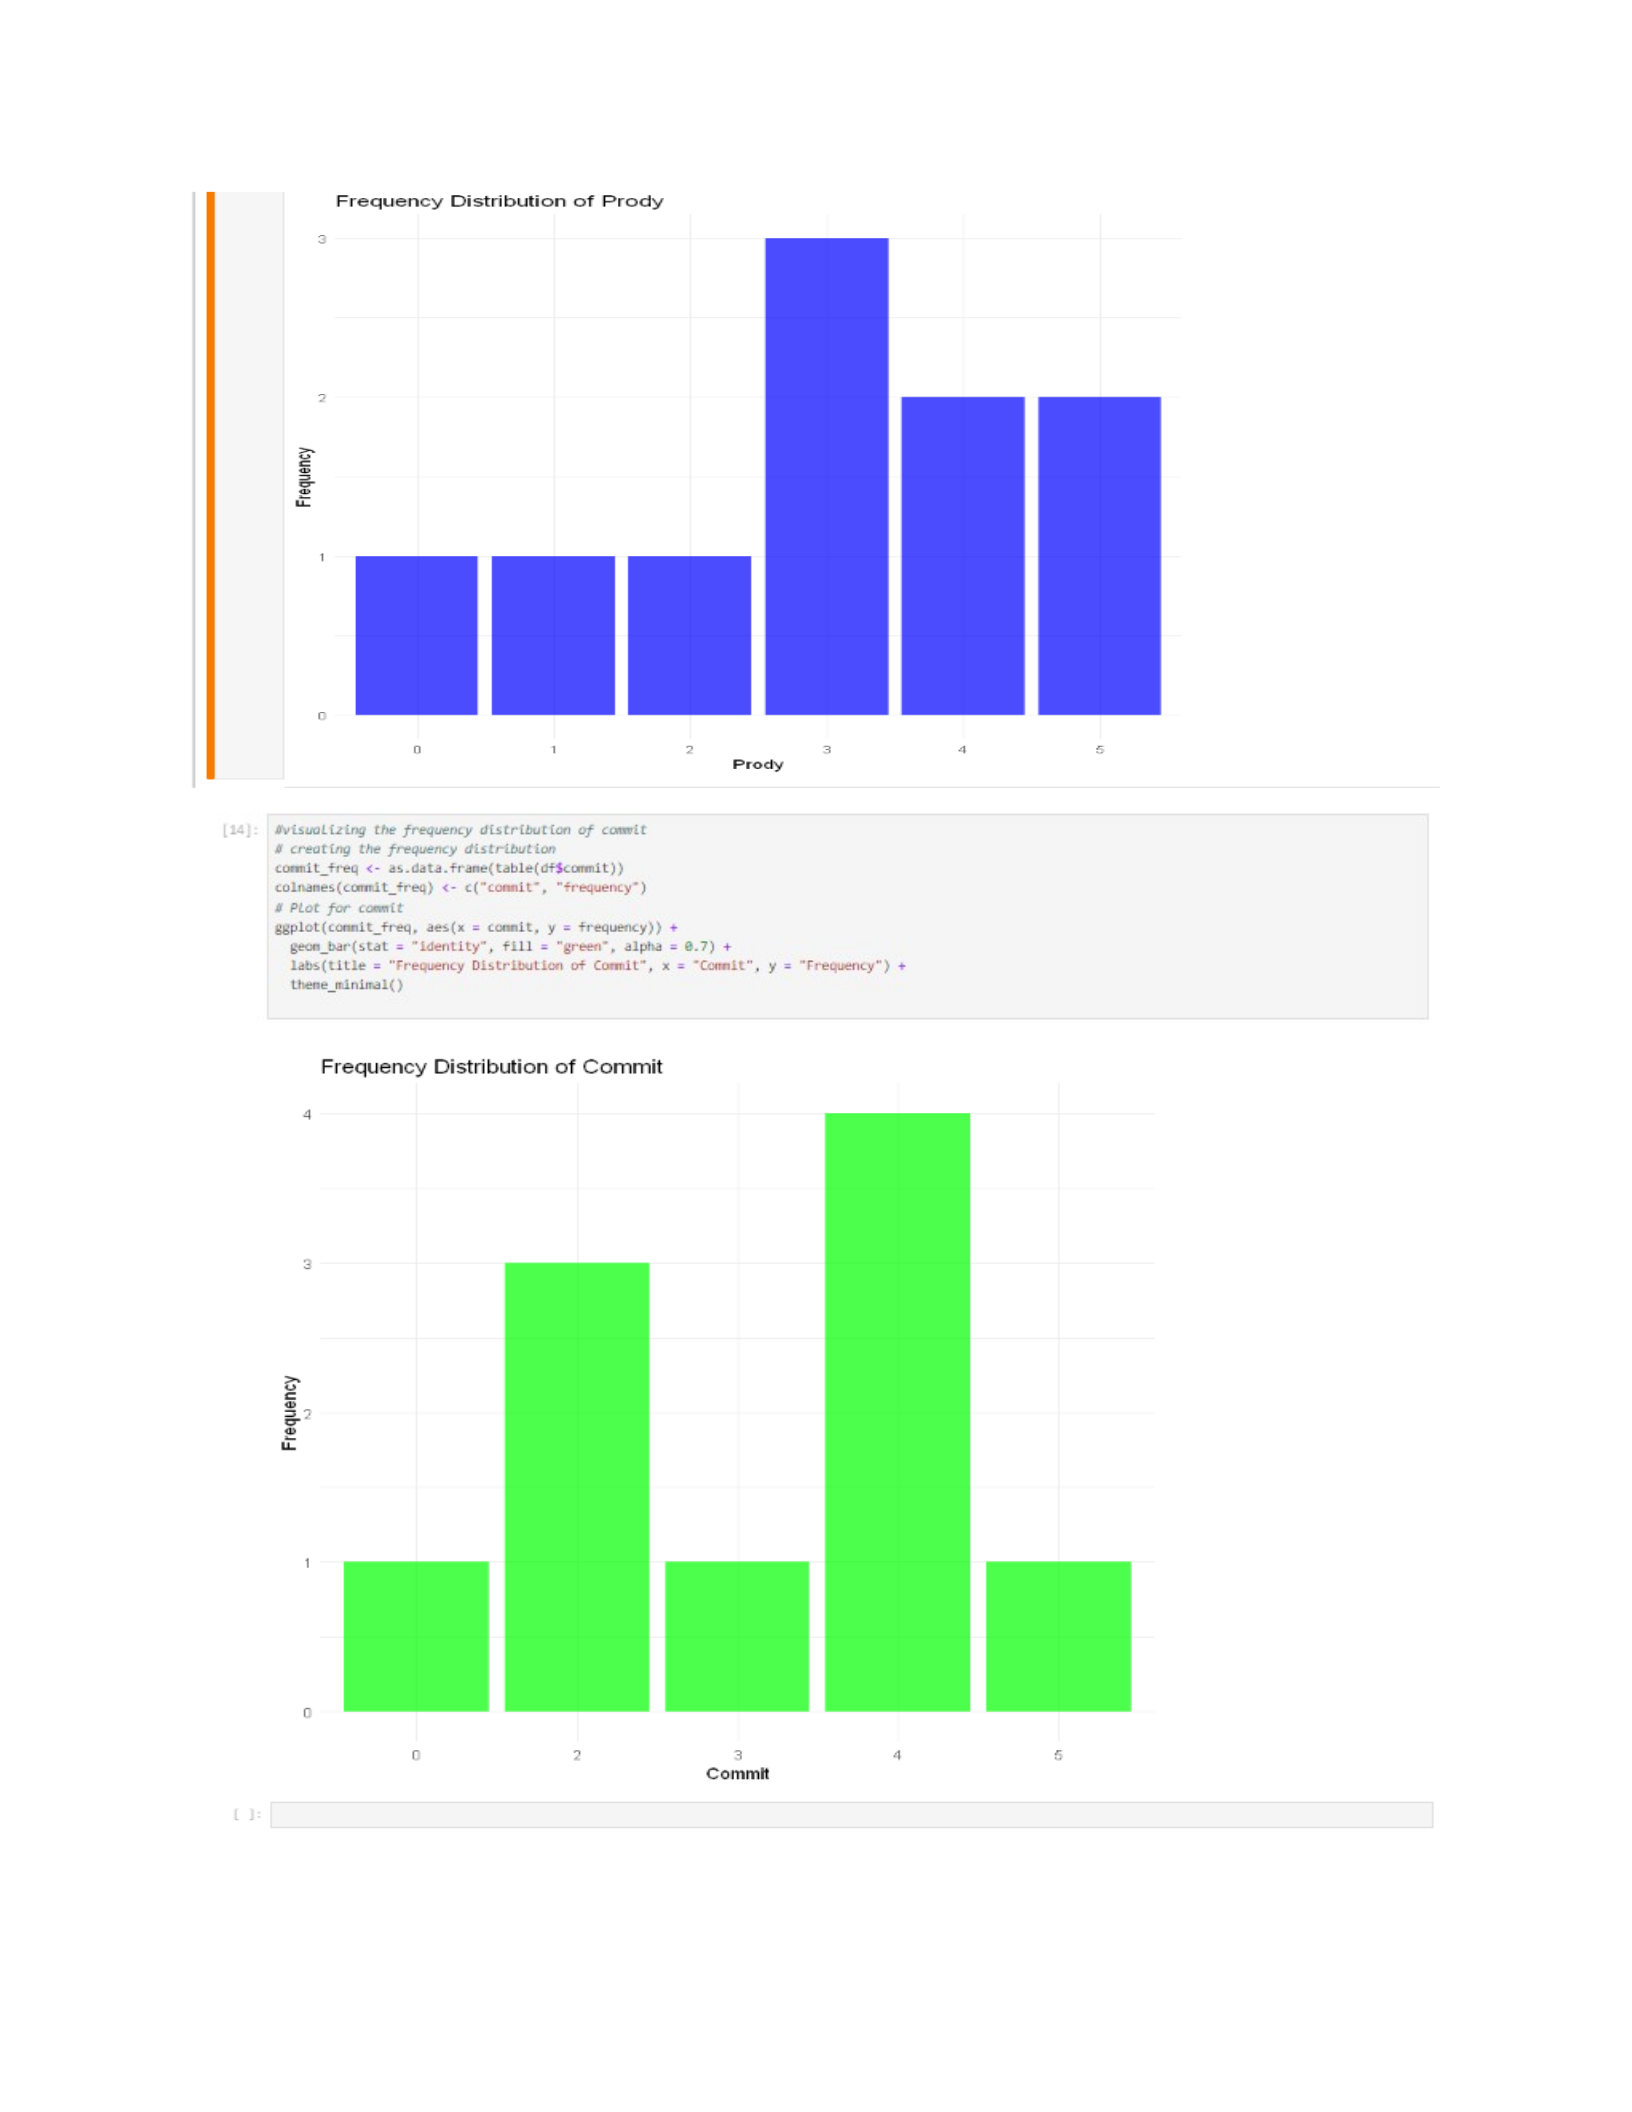
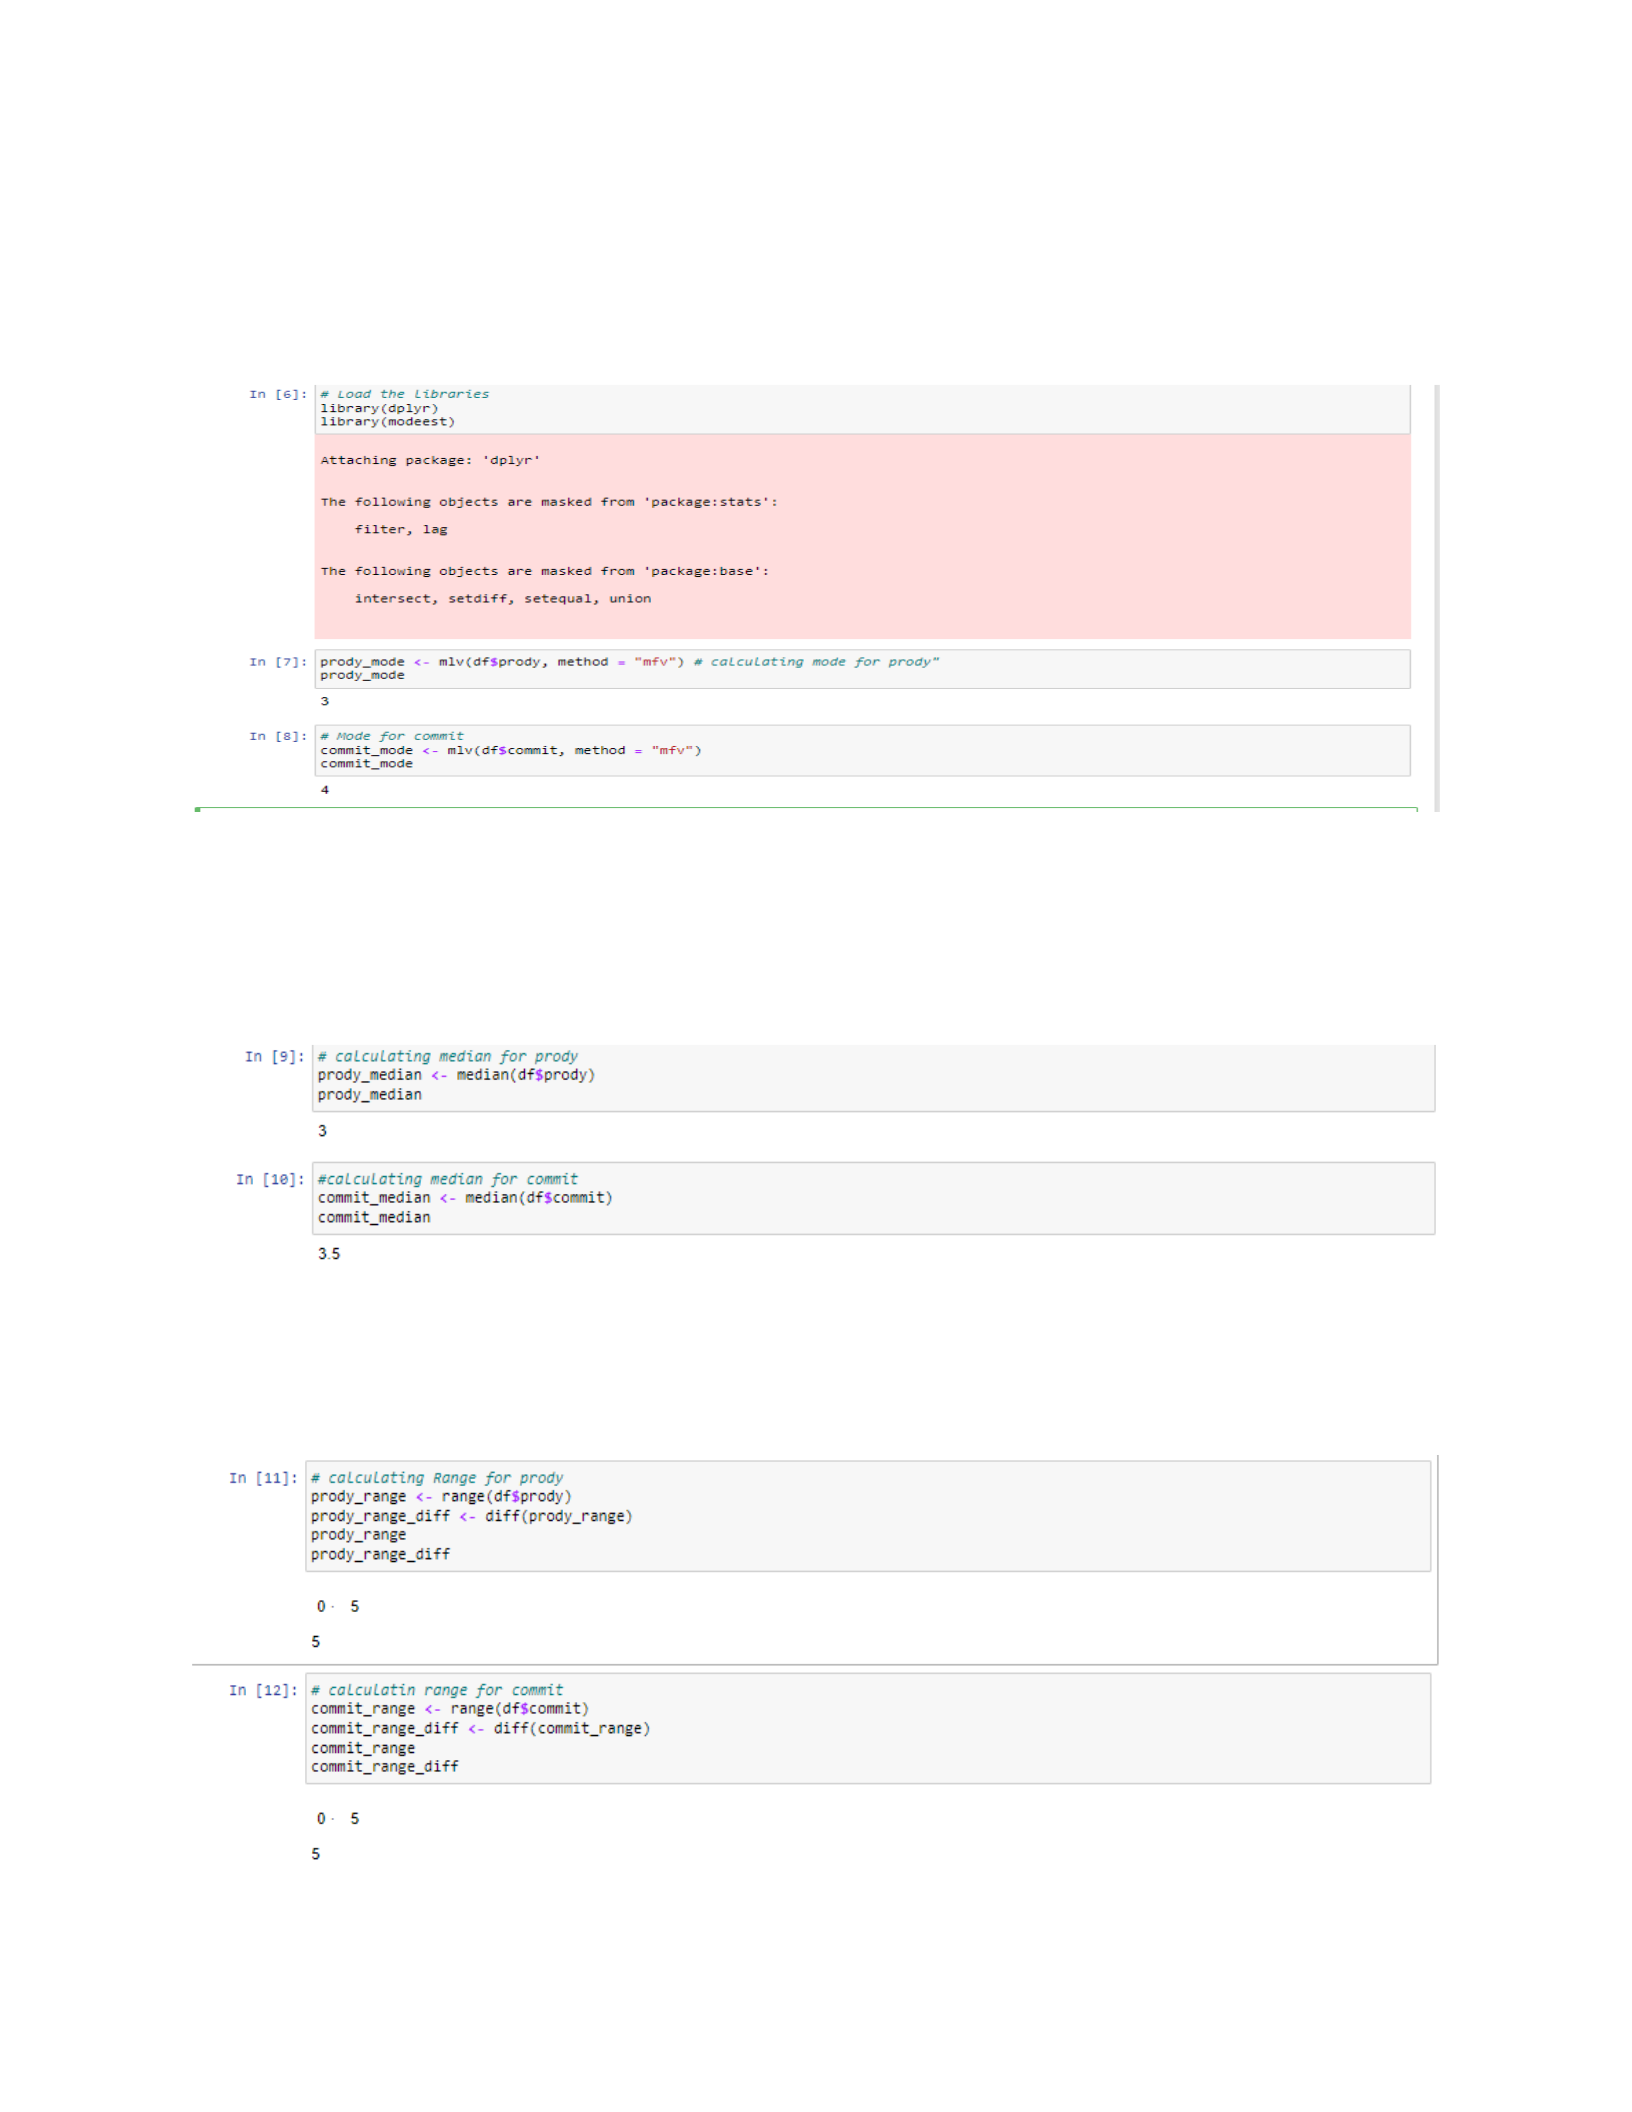
We will then use the `mlv` function to calculate the mode, the `median` function to calculate the
median, and the `range` function to calculate the range of the variables as shown below;
Mode
From the above code, we can see that the mode for prody and commit variables are 3 and 4
respectively.
Median
From the code above, the median for prody and commit variables is 3 and 3.5 respectively.
Range
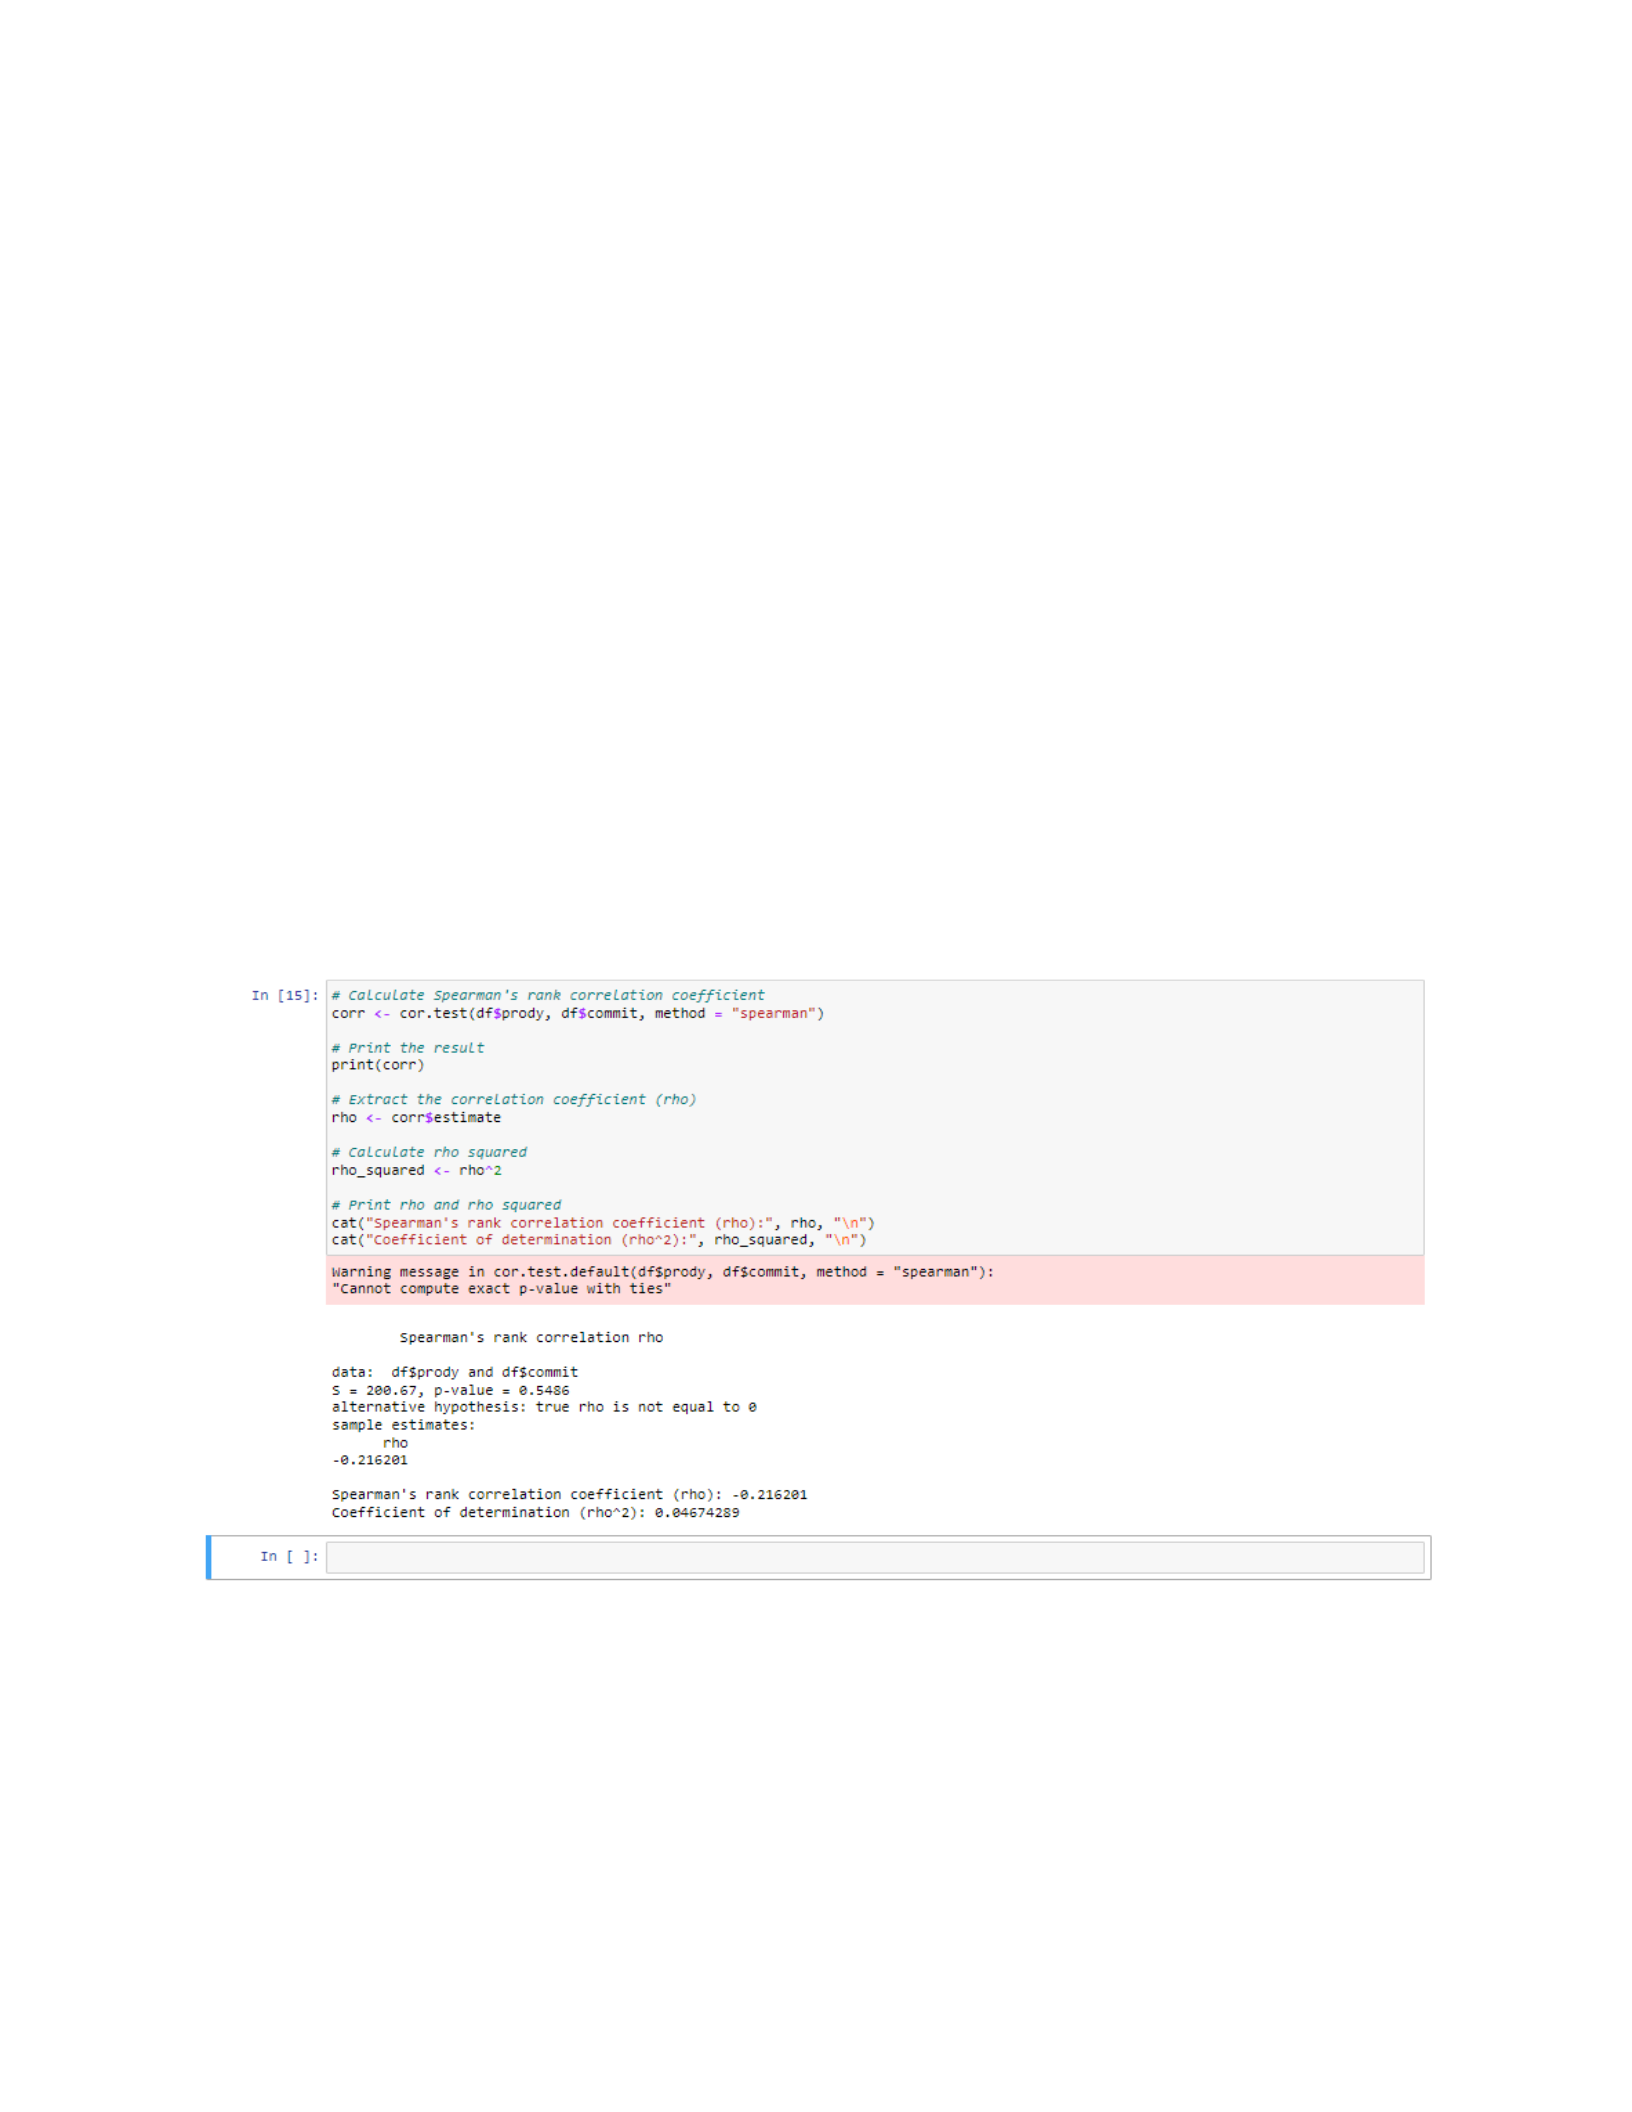
From the above code cells, the range and range difference of prody and commit are 0,5 &5.
Range is relevant as it provides the variability details of the data.
Inferential statistics
This involves using the Spearman’ rank square to determine the strength of the relationship
between prody and commit variables in the job survey data. To calculate the correraltion using R,
we will use the cor.test() function, and the argument; method= “spearman”. The figure below
shows how the same is implemented in R. The spearman’s correlation as indicated in the cells
below is -0.22, coefficient of determination is 0.4674 and a p-value of 0.55. With a coefficient of
determination of 0.04674, this means 4.67% variance in ‘prody’ can be explained by ‘commit’
variable. A rho of -0.22 indicates a weak negative correlation between the two study variables.
The study’s p-value of 0.55 is greater than the standard 0.05, which indicates that the correlation
is not statistically significant.
Regression equation for the relationship between age and autonomy
In this scenario, the regression is given with two variable autonomy and age with autonomy as
the dependent variable and age as the independent variable. The equation is autonom = 6.964 +
0.06230age r = 0.28. A simple linear regression equation is given by Y=β0+β1×X+ϵ where Y is

the dependent variable, β0 is the intercept, β1 is the slope, X is the independent variable, and ϵ is
the error term.
In our equation, 6.964 represents the β0 which is the intercept of the true regression line which is
given by the average of Y when X is zero. β0 is vital in simple linear regression analysis as it
serves as the first point where the regression line in the Y axis. This means that 6.964 is the first
point of the regression Line in Y-axis, when X is zero.
0.06230 in our equation represents β1which is the slope. The slope indicates the rate for change
in Y for every unit of change in X. In other words, β1 can be seen as the regression coefficient as
it shows the expected change in Y when X increases. This coefficient indicates that for every
one-unit increase in the independent variable age, the dependent variable autonomy is expected
to increase by 0.06230 units.
According to Das (2019, pp. 75-108), the "Goodness of Fit" in a linear regression model aims to
address how effectively the model aligns with a specific dataset or predicts future observations.
The coefficient of determination (R²) serves as a valuable metric for assessing the model's fit,
quantifying the extent to which the observed data points deviate from the optimal fitting line,
squared for accuracy. From our equation = 0.28 making R² to be 0.0784. A coefficient of
determination of 0.0784 means that only 7.84% of change in autonomy can be explained by age
variable. The low R² value of our equation indicates that the regression model poorly fits the data
implying that other factors other than age could be affecting autonomy.
The autonomy level for someone aged 54 can be determined by solving our equation.
autonom = 6.964 + 0.06230 * age
First, we will substitute age with 54;
autonom = 6.964 +0.06230* 54
autonom = 6.964+3.3642
autonom = 10.3282
from the calculation above, the autonomy level for someone aged 54 is 10.3282
simple linear regression using R
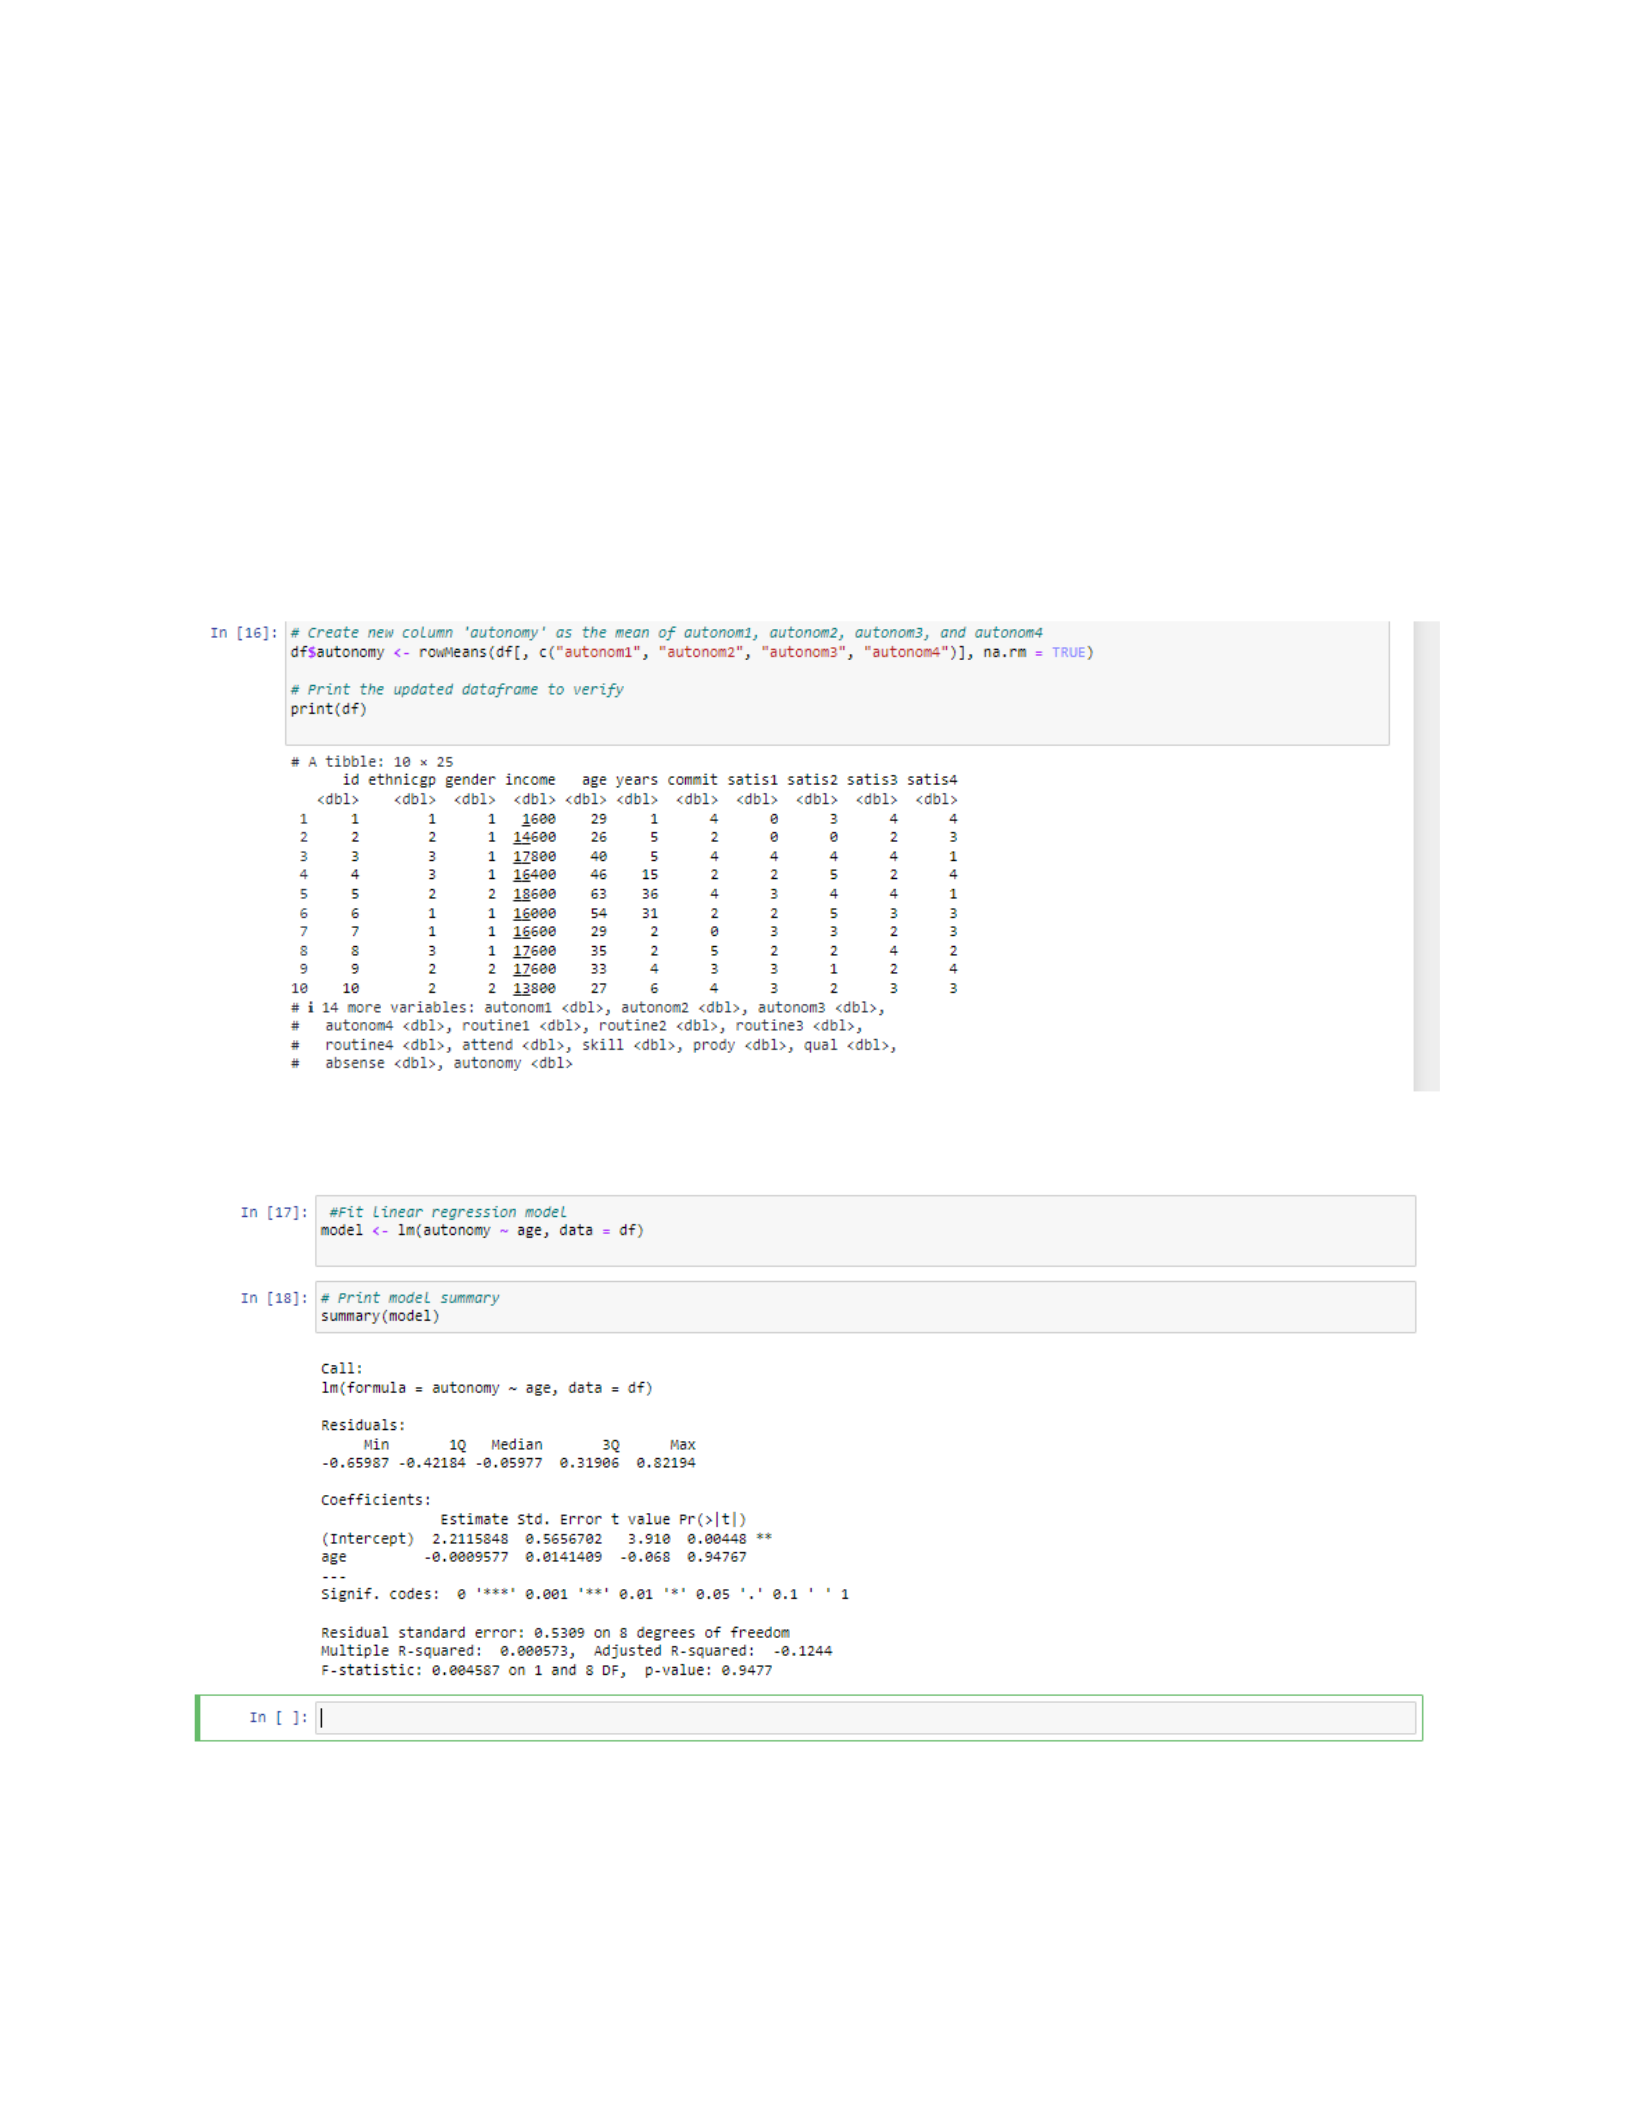
We will use the job_survey data to perform this task. We will start by creating a new column
named autonomy which is the mean of all the 4 autonom columns in the data set. We will then fit
a linear regression model into our data using the `lm()` function. We will the call the model using
the command `summary(model)` which will outline the model specifications including the
coefficient of determination. To determine the autonomy of a person aged 54, we will adjust he
age in our model to 54 then predict the autonomy. See the cells below;
Creating the autonomy column
Fitting in the linear regression model into the data and printing the model summary
From the model summary above, our linear regression model has an R squared of 0.000573
which indicates that only 0.573% of change in autonomy is explained by age. The low r squared
value indicates that the model does not fit well with the data, and that variations in autonomy can
be better explained by other factors.
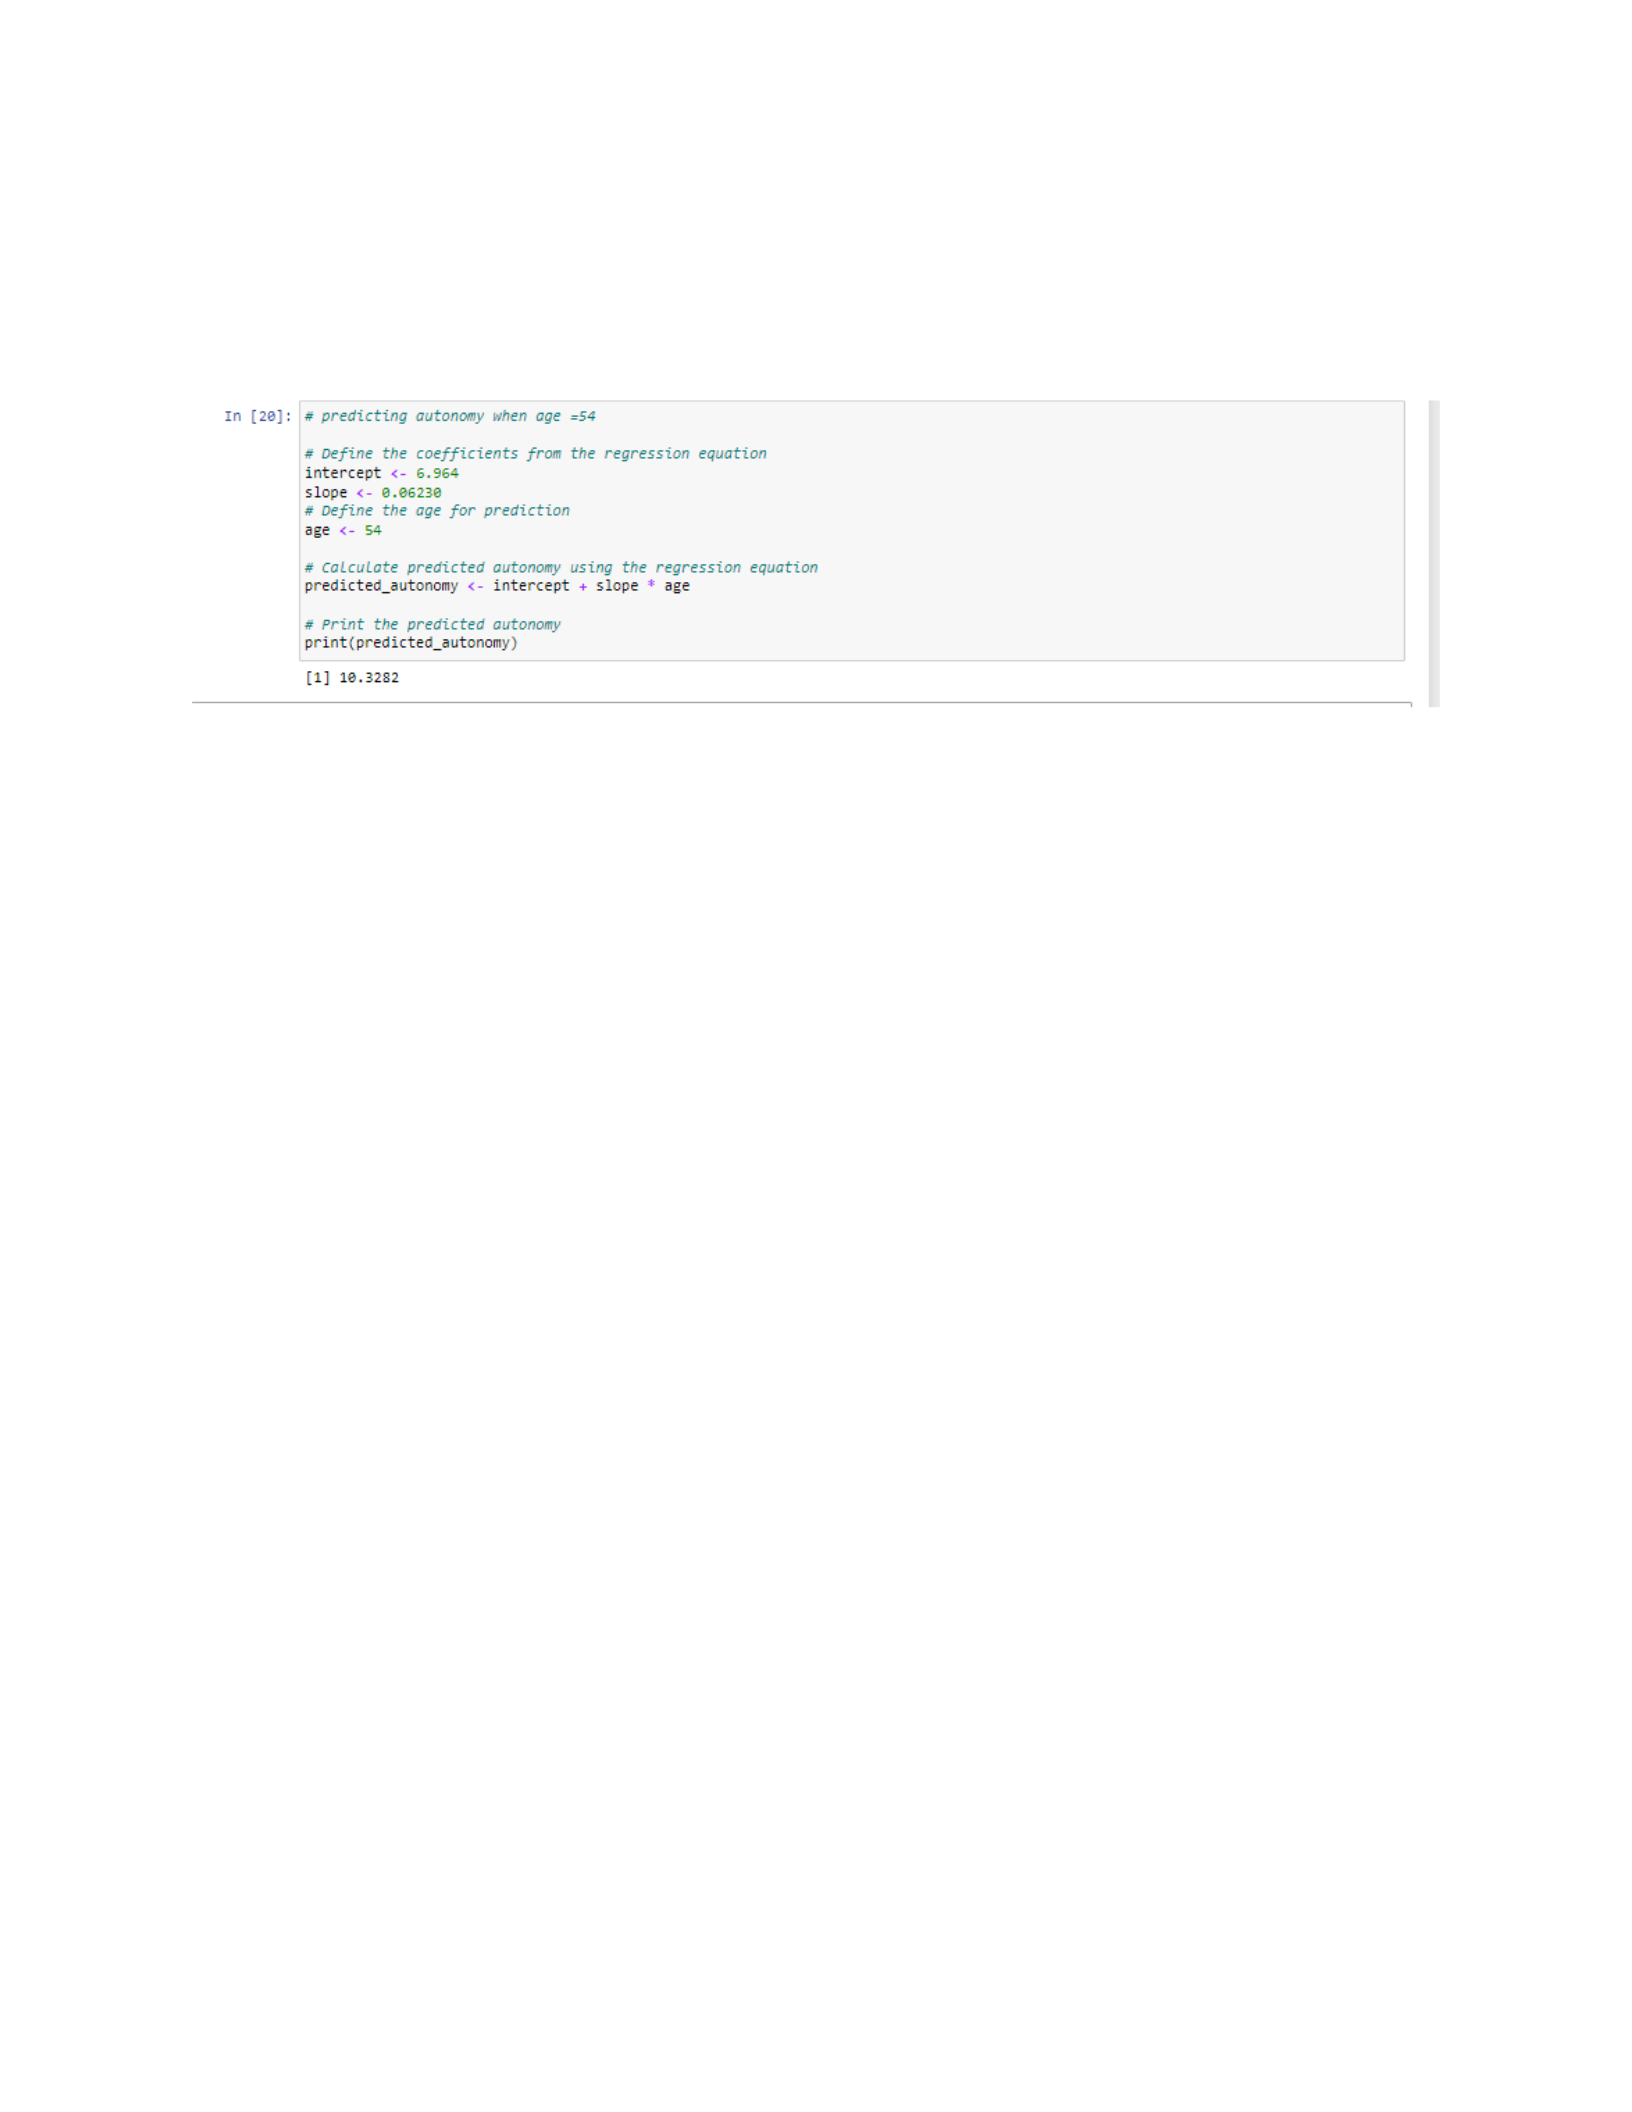
Predicting the autonomy when age is 54
From the results in the cell above, the autonomy when age =54 is predicted to be 10.3282.
Conclusion
This section has largely covered the practical use of R to perform statistical analysis. we have
successfully illustrated a thorough understanding of the software through uploading and reading
of files, data exploration through R, performing descriptive and inferential statistics, fitting in
models, and using models to make predictive insights.
Reference list
Barrowman, N., 2014. Correlation, causation, and confusion.WThe New Atlantis, pp.23-44.

Berndt, A.E., 2020. Sampling methods.WJournal of Human Lactation,W36(2), pp.224-226.
Biau, D.J., Jolles, B.M. and Porcher, R., 2010. P value and the theory of hypothesis testing: an
explanation for new researchers.WClinical Orthopaedics and Related Research®,W468(3),
pp.885-892.
Emerson, R.W., 2021. Convenience sampling revisited: Embracing its limitations through
thoughtful study design.WJournal of Visual Impairment & Blindness,W115(1), pp.76-77.
Das, P., 2019. Linear regression model: Goodness of fit and testing of hypothesis.
InWEconometrics
in Theory and Practice: Analysis of Cross Section, Time Series and Panel Data with Stata
15.1W(pp. 75-108). Singapore: Springer Singapore.
Dwork, C., Feldman, V., Hardt, M., Pitassi, T., Reingold, O. and Roth, A.L., 2015, June.
Preserving
statistical validity in adaptive data analysis. InWProceedings of the forty-seventh annual
ACM symposium on Theory of computingW(pp. 117-126).
Kim, T.K., 2017. Understanding one-way ANOVA using conceptual figures.WKorean journal of
anesthesiology,W70(1), p.22.
Li, H., Chen, Z. and Zhu, W., 2019. Variability: Human nature and its impact on measurement
and
statistical analysis.WJournal of Sport and Health Science,W8(6), p.527.
Obilor, E.I. and Amadi, E.C., 2018. Test for significance of Pearson’s correlation
coefficient.WInternational Journal of Innovative Mathematics, Statistics & Energy
Policies,W6(1), pp.11-23.
Sedgwick, P., 2014. Spearman’s rank correlation coefficient.WBmj,W349.
Schober, P., Boer, C. and Schwarte, L.A., 2018. Correlation coefficients: appropriate use and
interpretation.WAnesthesia & analgesia,W126(5), pp.1763-1768.

