


BIO 181 Lecture Note: Data Types, Analysis, and Visualization in
Experimental Biology
Arizona State University – Tempe, AZ
Course: BIO 181 (General Biology I)
Topic: From Raw Numbers to Scientific Conclusion: Data Analysis and Presentation
1. Introduction: The Bridge Between Experiment and Conclusion
Welcome back! Weve discussed the rigorous design of controlled experiments; now
we move to the final, critical step: Data Management and Interpretation. Raw
data, no matter how carefully collected, is meaningless until it is properly
categorized, processed, and presented. In biology, data serves as the empirical
evidence that either supports or refutes your hypothesis. Mismanaging this
evidence is the quickest path to an invalid conclusion. Mastering data handling is
mastering the language of objective science.
Core Learning Objectives:
Differentiate between Qualitative and Quantitative data and understand
the appropriate use of each.
Implement Standardized Protocols for recording data in a scientific
notebook.
Calculate and interpret the fundamental descriptive statistics: Mean and
Standard Deviation (
σ
).
Select the correct Visualization Tool (Line Graph vs. Bar Graph) based on
the independent variable type.
Extend the analysis to concepts of Statistical Significance and Error
Analysis.
2. Differentiating Data Types: The Qualitative vs. Quantitative Dichotomy
The first step in any analysis is categorizing the nature of the information you have
collected. This categorization dictates the subsequent statistical tools you can
legitimately employ.

2.1. Qualitative Data (The Descriptive Evidence)
Core Definition: Qualitative data consists of non-numerical observations or
descriptions. It categorizes or characterizes the attributes of a biological system.
Characteristics:
oNominal: Data that can be named or categorized without any
inherent order (e.g., Sex: male/female; Genotype:
AA /Aa/aa
).
oOrdinal: Data that can be ranked or placed in a defined order, but the
differences between the categories are not necessarily equal or
measurable (e.g., Disease severity: Mild, Moderate, Severe; Cellular
developmental stage: Prophase, Metaphase, Anaphase).
Examples in BIO 181:
oCell morphology (e.g., "Rod-shaped," "Spherical," "Budding").
oColor changes in a chemical assay (e.g., "Turned deep blue," "Faint
yellow").
oBehavioral observations (e.g., "Exhibits positive phototaxis").
Role in Research: Qualitative data is crucial for initial observation,
identifying patterns, and contextualizing the numerical results. However, it is
inherently subjective and cannot be analyzed using most standard
parametric statistical tests.
2.2. Quantitative Data (The Measurable Evidence)
Core Definition: Quantitative data consists of numerical measurements or counts.
It provides measurable magnitude and is the backbone of statistical inference.
Characteristics:
oDiscrete: Data that can only take specific, isolated values, typically
whole numbers or counts (e.g., Number of cells in a field of view,
Number of offspring).
oContinuous: Data that can take any value within a given range, often
limited only by the precision of the measuring instrument (e.g.,
Temperature,
pH
, Reaction time, Biomass).
Examples in BIO 181:
oReaction Rate: Measured in
Moles
per second (
mol /s
).
oCell Density: Measured in cells per milliliter (
cells /mL
).
oSpectrophotometry Reading: Absorbance units (
A
).
Role in Research: Quantitative data is the only type suitable for robust
statistical analysis, allowing researchers to determine the probability that
the observed effect is real and not due to random chance. This data drives the
rejection or failure-to-reject of the Null Hypothesis (
H0
).
3. Data Recording and Standardization Protocols
The integrity of your conclusion relies entirely on the integrity of your initial data
recording. Sloppy documentation is a fatal flaw in scientific inquiry.
3.1. Notebook Norms (The Unbreakable Rules)
Your lab notebook is a legal document—it must be an accurate, permanent record
of your work.
Immediate Recording: Data must be recorded directly into the notebook
as it is collected, not transcribed later from a temporary scrap of paper.
Permanent Medium: Use permanent, indelible ink. Never use pencil.
No Erasures: Errors are crossed out with a single line, remaining legible, and
the correction is written nearby. Initial the correction.
Full Context: Every data set must be accompanied by the following meta-
information:
oDate and Time of collection.
oExperimental Title/Topic.
oUnits of Measurement (e.g.,
mg /L
,
cells/mL
,
seconds
).
oReplicate Number (essential for
N
values).
3.2. Data Standardization: Precision and Significant Figures
Precision reflects the closeness of repeated measurements; accuracy reflects how
close a measurement is to the true value.
Consistency: All measurements within a dataset must be recorded to the
same degree of precision, which is determined by the least precise
instrument used.
oExample: If a pipette measures to
0.01 mL
and a balance measures to
0.001 g
, the pipette dictates the overall volume precision used in
calculations.
Significant Figures (Sig Figs): The number of significant figures in your
final calculations must reflect the least number of significant figures present
in the raw data used for the calculation. This prevents presenting a false
sense of precision.
4. Descriptive Statistics: Characterizing the Data Set
Once data is recorded, the first step in processing is using descriptive statistics to
summarize the central tendency and the variability.
4.1. Central Tendency: The Mean (
x
)
The Mean (
x
) is the arithmetic average and is the most common measure of central
tendency for quantitative data. It provides the best single estimate for the true
population parameter based on the sample data.
Formula: The sample mean (
x
) is calculated by summing all data points (
xi
)
and dividing by the number of data points (
n
):
x=
∑
i=1
n
xi
n
Professors Insight: While easy to calculate, the mean can be heavily
influenced by outliers (extreme data points). Always visually inspect your
raw data before relying solely on the mean.
4.2. Variability: The Standard Deviation (
σ
or
s
)
The Standard Deviation (
s
for a sample,
σ
for a population) is the measure of the
average amount of variability or dispersion in your dataset. It tells you how spread
out the data points are relative to the mean.
Formula (Sample Standard Deviation):
s=
√
∑
i=1
n
¿¿ ¿ ¿
Interpretation:
oA small
σ
indicates that the data points tend to be very close to the
mean (high precision, low variability within the group).
oA large
σ
indicates that the data points are spread out over a wide
range (low precision, high variability).
Biological Context: In biology, high
σ
often reflects the inherent biological
heterogeneity (variation) within a population, or simply poor experimental
technique.
5. Data Visualization: Choosing the Right Chart
The correct choice of graph is crucial for clear, objective communication. The graph
type is determined primarily by the Independent Variable (IV).
5.1. Bar Graphs (Histograms)
Applicable When: The Independent Variable is Categorical or Discrete
(i.e., named groups, or groups based on distinct, separate conditions).
Purpose: To compare the average value of the Dependent Variable (
x
) across
fundamentally distinct, non-continuous groups. The
x
-axis labels are
separate entities.
Examples:
oComparing the average height of pea plants of four different
genotypes (
AA
vs.
Aa
vs.
aa
).
oComparing the final biomass accumulation under three different, non-
sequential light colors (Red vs. Blue vs. Green).
Key Presentation: Each bar should include an error bar, typically
representing the Standard Deviation (
σ
) or the Standard Error of the
Mean (
SEM
), to show the variability around the mean.
5.2. Line Graphs (Scatter Plots)
Applicable When: The Independent Variable is Continuous or Sequential
(i.e., numerical data that flows on a continuum).
Purpose: To show the relationship, trend, or rate of change in the
Dependent Variable as the Independent Variable changes continuously. The
line implies that data exists between the measured points.
Examples:
oTracking Enzyme Reaction Rate as a continuous function of
Temperature (
10∘C
to
60∘C
).
oMonitoring Bacterial Population Size over Time (continuous
variable).
oMeasuring Absorption Spectrum across different Wavelengths of
light.
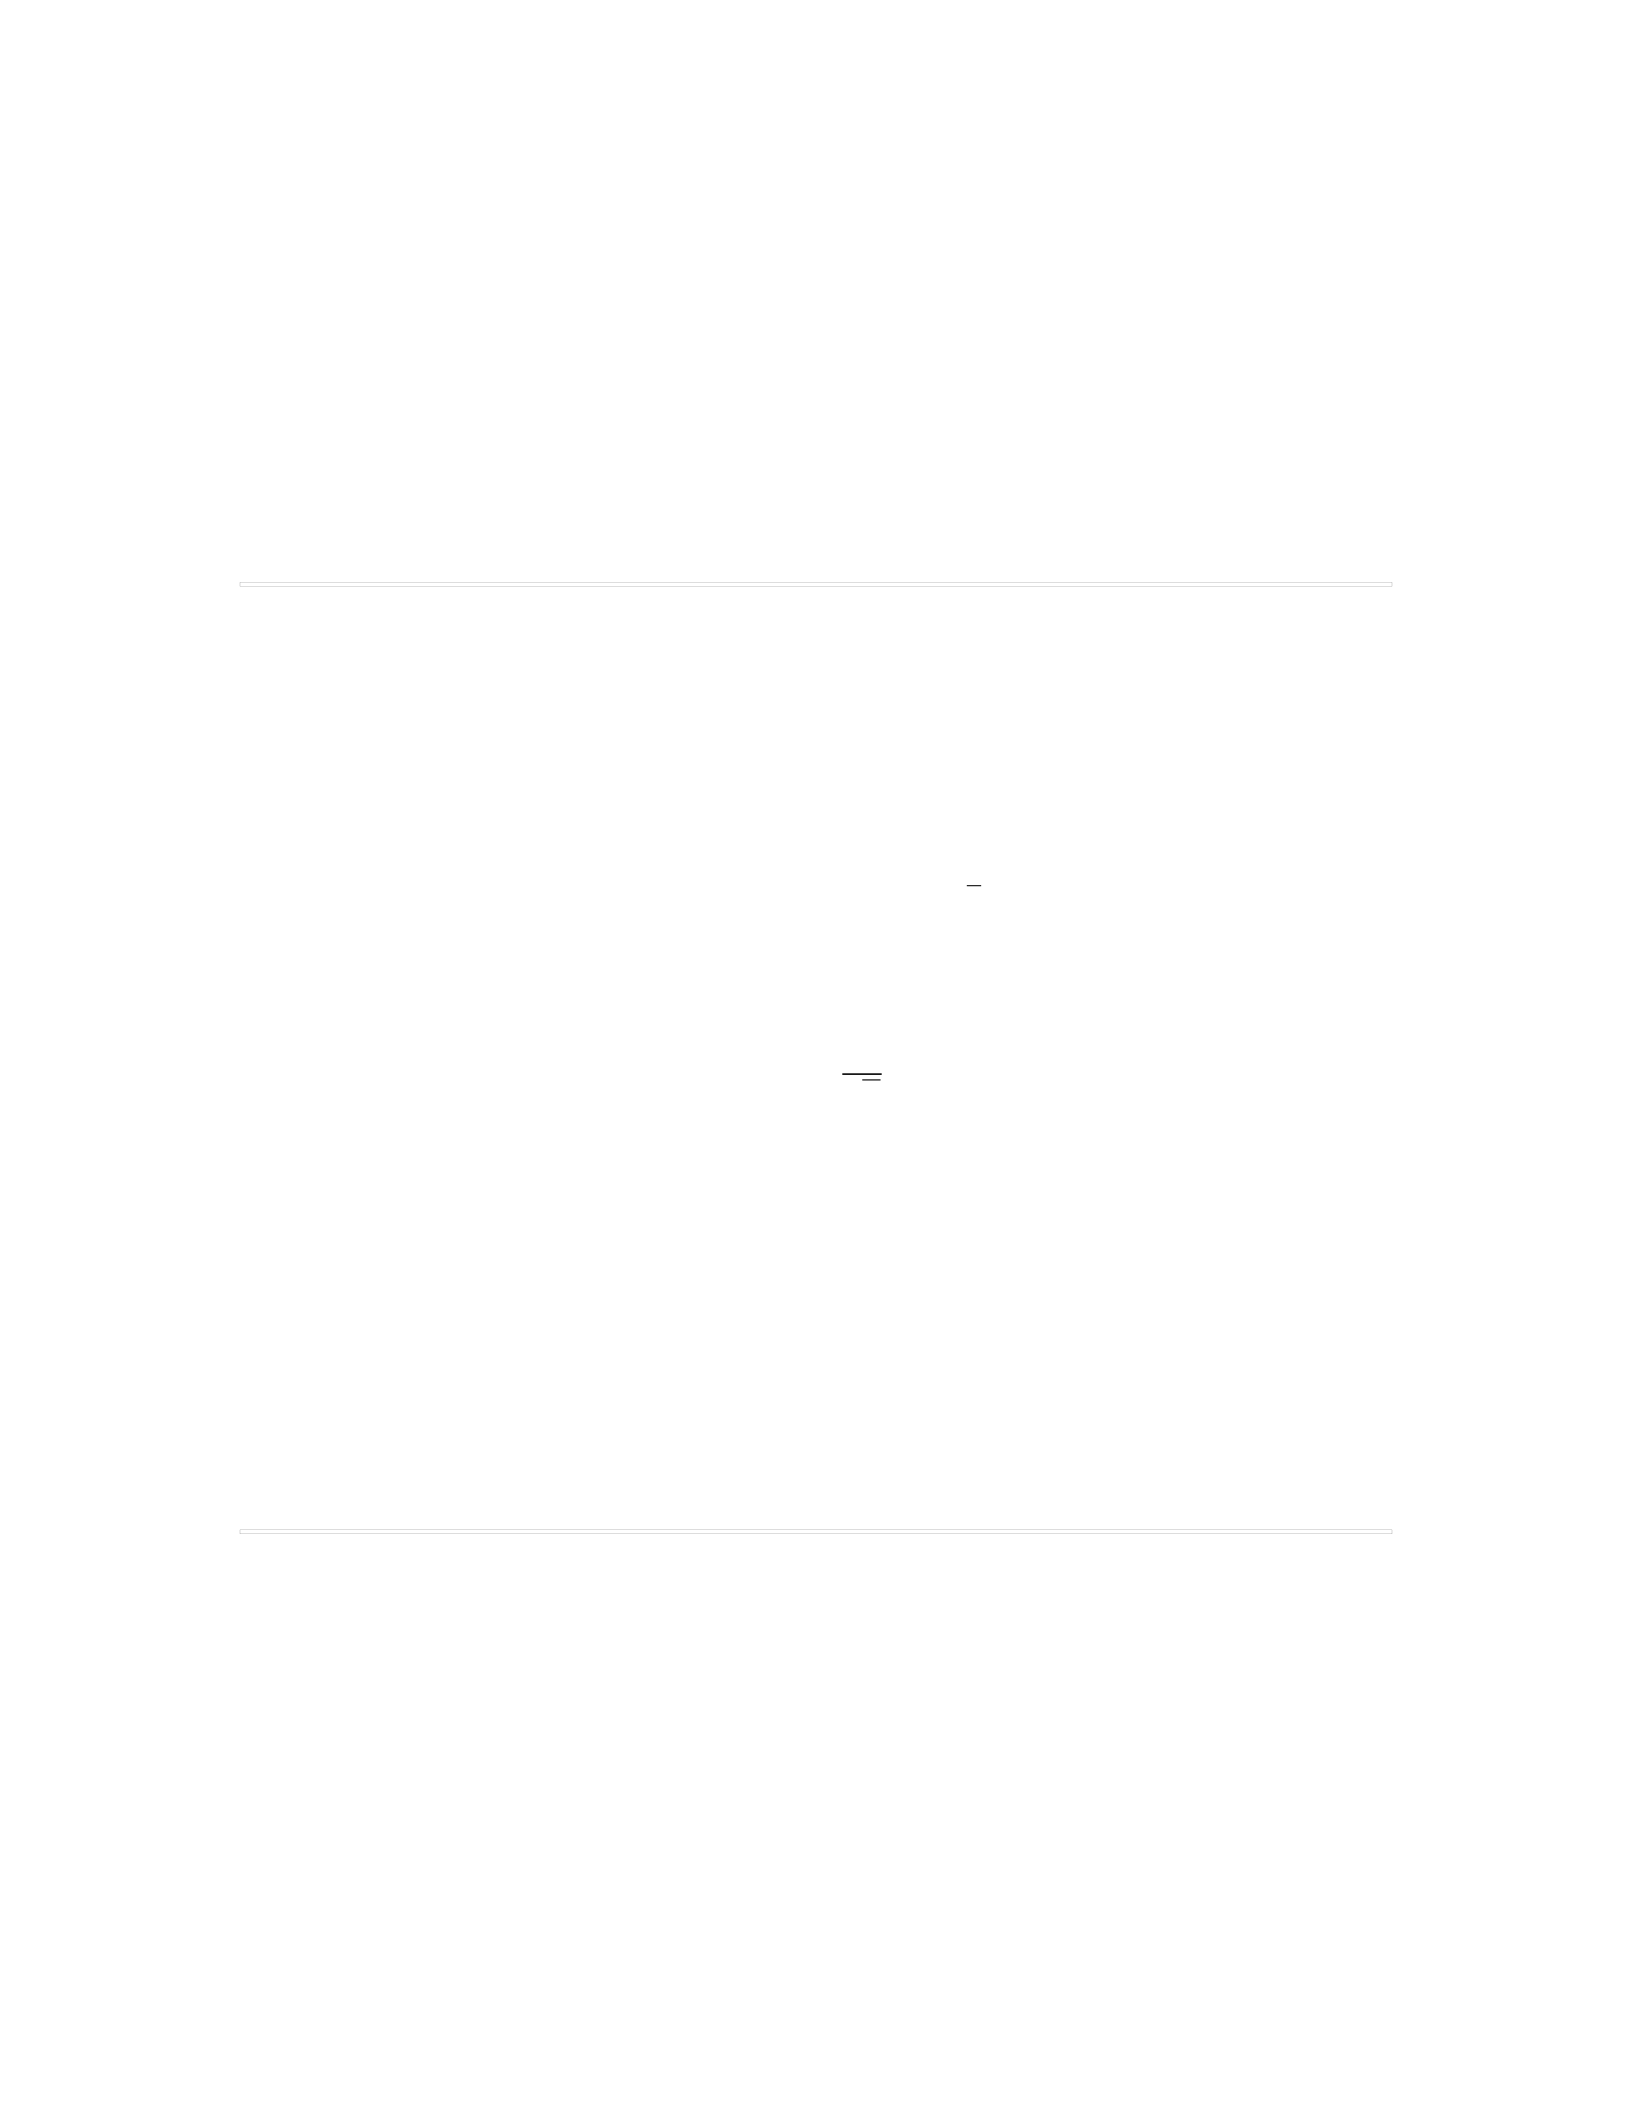
Key Presentation: The line connecting the points highlights the trend
(linear, exponential, saturation), and the data points should also include
vertical error bars (
σ
or
SEM
).
Pitfall C (Graphing Error): Students frequently use a line graph when they have
distinct categories. For example, comparing the growth of Plant A and Plant B at
20∘C
and
30∘C
. The plant type is categorical (A vs. B), and temperature is being
used as a category level, not a continuum. A bar graph comparing the four groups is
necessary unless the intent is to show the rate of change within Plant A as
temperature increases. The nature of the IV dictates the chart type.
6. Extension 1: Error Analysis and Standard Error of the Mean (
SEM
)
While
σ
describes the variability of the sample itself, the Standard Error of the
Mean (
SEM
) is often used in visualization as it addresses the precision of the mean.
6.1. The Standard Error of the Mean
The
SEM
is an estimate of how far the sample mean (
x
) is likely to be from the true
population mean (
μ
). It is always smaller than the Standard Deviation.
Formula:
SEM=s
√
n
Key Distinction:
σ
reflects the scatter of the data;
SEM
reflects the
confidence in the calculated mean. As the sample size (
n
) increases, the
SEM
decreases, meaning our sample mean gets closer to the true population
mean.
Graphing Convention: In academic publications (especially in fields like
neuroscience and genetics),
SEM
bars are often preferred because they
indicate the precision of the estimate used for statistical comparison. If the
SEM
bars of two means do not overlap, it is a strong visual indicator that
the difference between the two means may be statistically significant.
7. Extension 2: Inferential Statistics and Hypothesis Testing 🔬
Descriptive statistics (Mean,
σ
) merely summarize the data. To move from data
summary to a scientific conclusion, we must employ Inferential Statistics.
7.1. The
p
-Value and Statistical Significance
Inferential statistics allows us to test the Null Hypothesis (
H0
)—the assumption
that the Independent Variable had no effect.
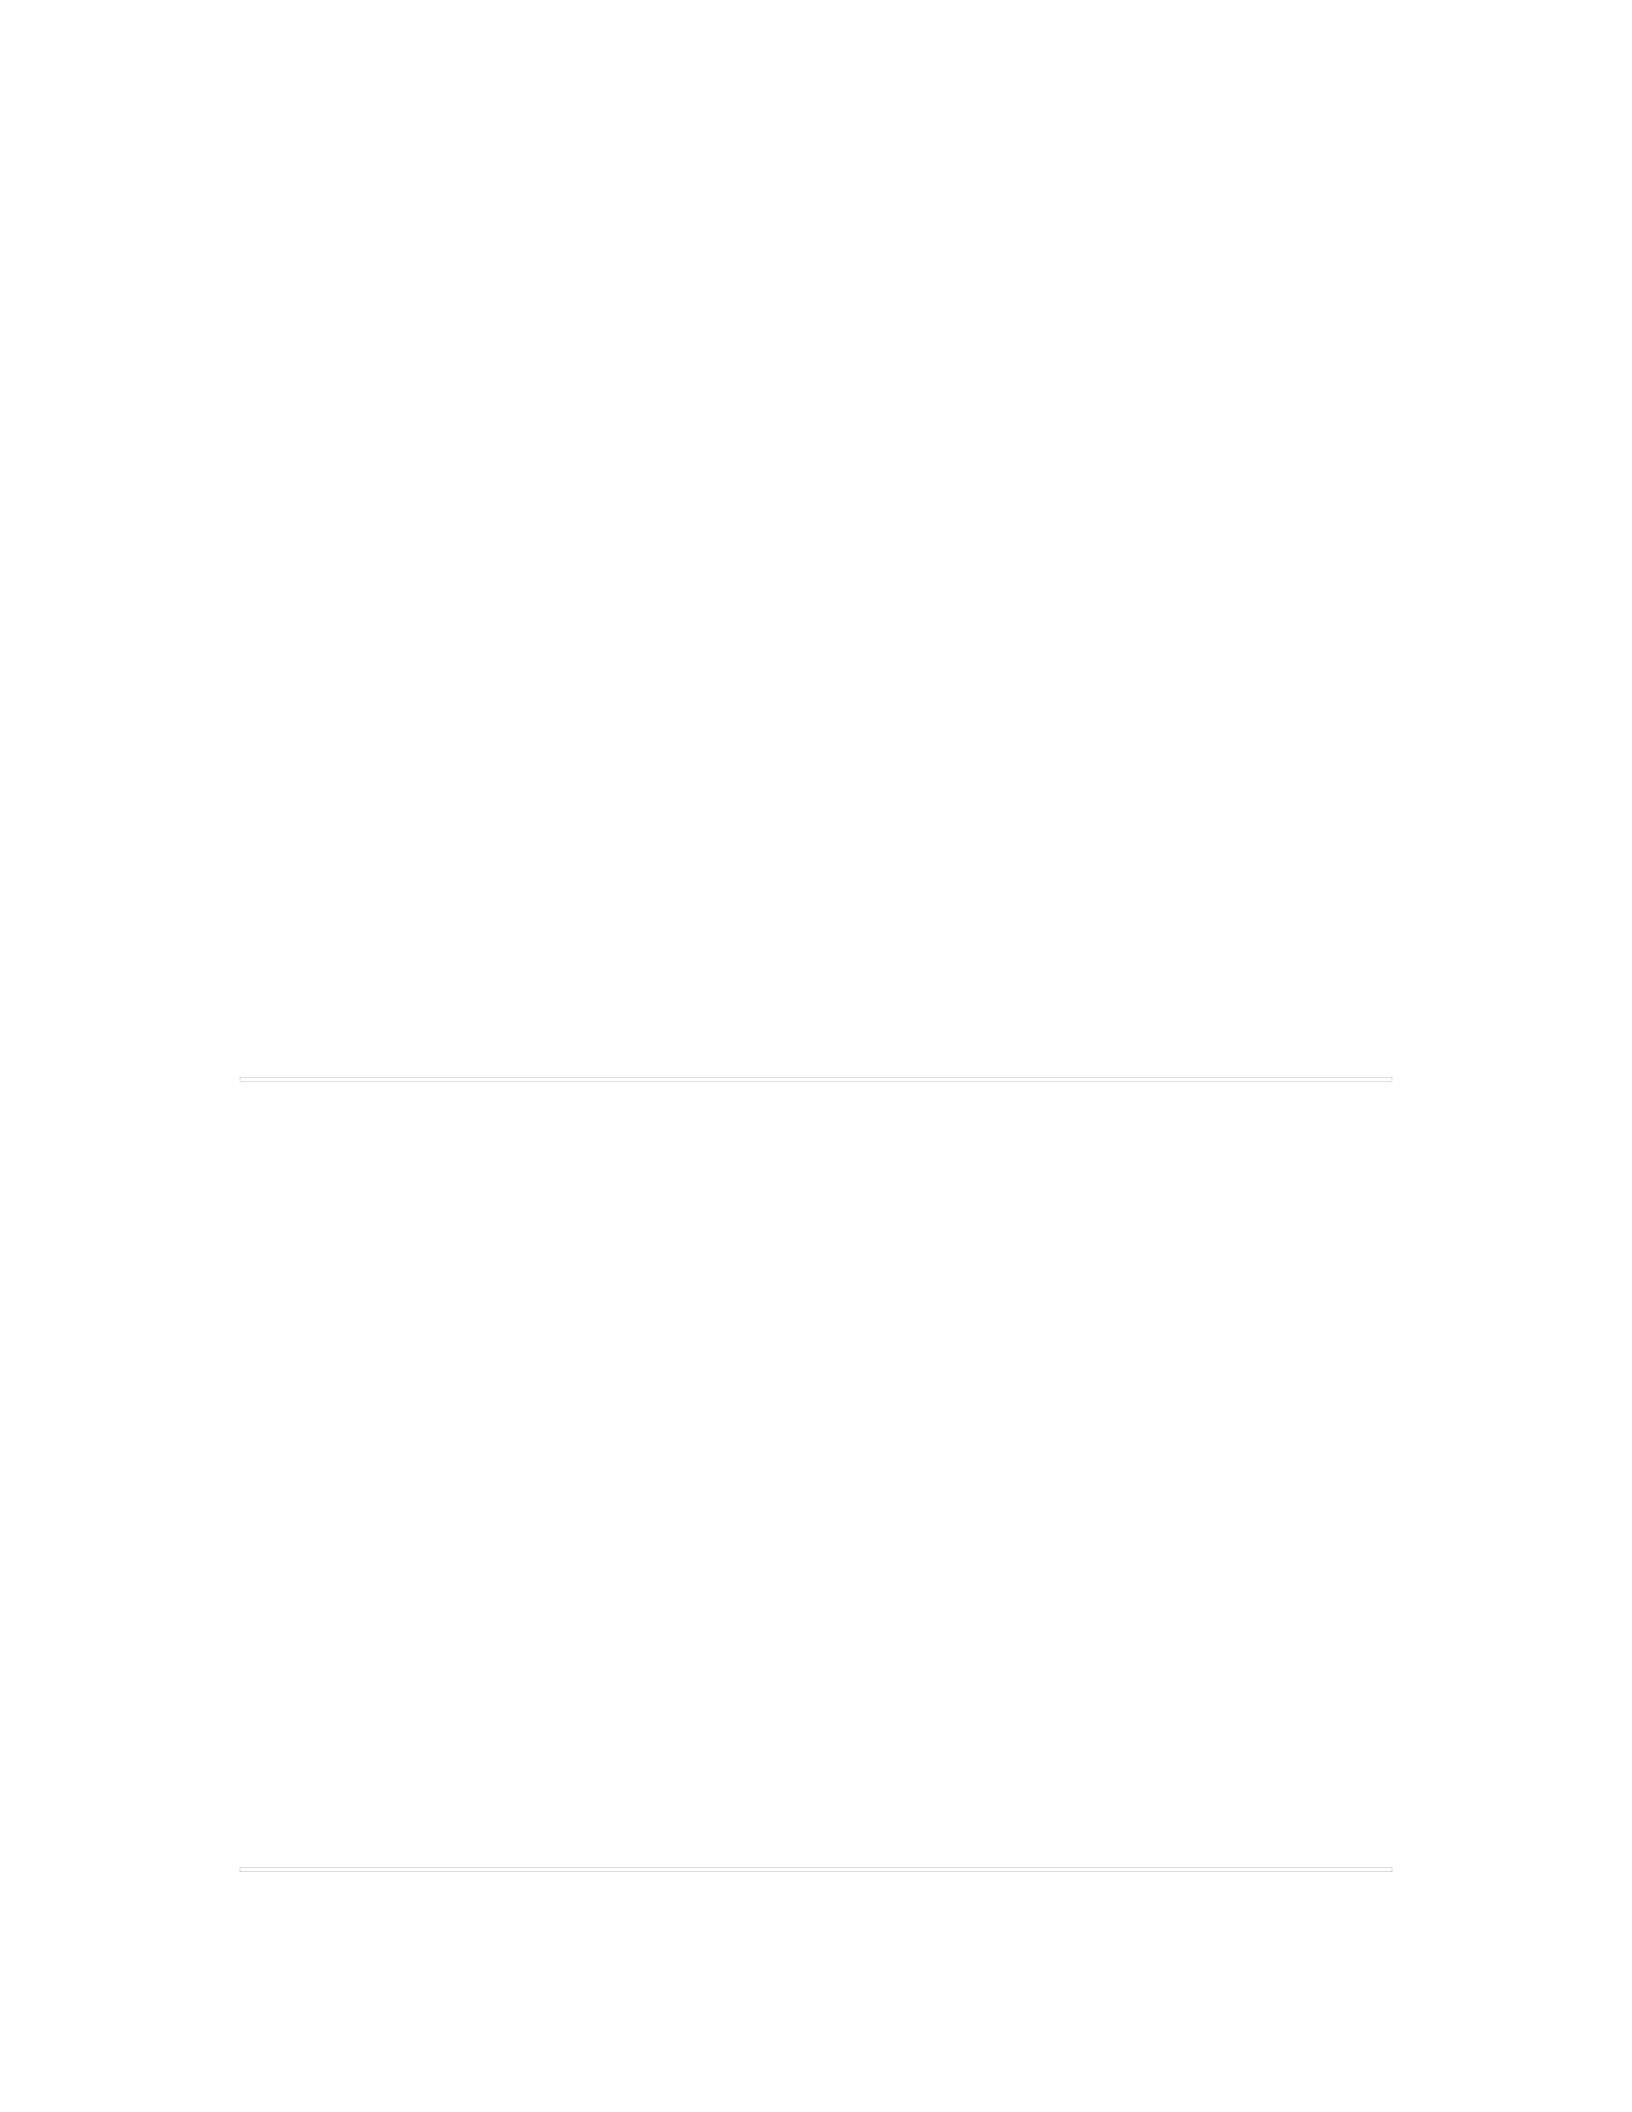
Test Statistic (e.g.,
t
-test, ANOVA): These tests calculate the likelihood of
observing the difference between your treatment means if the
H0
were
actually true.
p
-Value: This is the resulting probability. The
p
-value represents the
probability that the observed results (or more extreme results) occurred
purely by random chance.
Threshold: The conventional threshold for Statistical Significance in most
of biology is
α=0.05
.
oIf
p<0.05
(i.e., less than a
5 %
chance of occurring randomly), we
reject the
H0
. We conclude that the observed difference is statistically
significant and likely due to the
IV
.
oIf
p ≥0.05
, we fail to reject the
H0
. We conclude that the observed
difference could easily be due to random chance.
Professors Core Insight on Biological Significance: Remember that Statistical
Significance (
p<0.05
) does not automatically equate to Biological Significance. A
p
-value may indicate a statistically reliable effect, but that effect might be too small
to matter in a real-world biological context (e.g., a statistically significant
0.001∘C
change in body temperature is statistically significant but biologically irrelevant).
Both must be considered when drawing a final conclusion.
8. Extension 3: Data Integrity and Reproducibility
The final step in data analysis circles back to the core scientific principle of
Reproducibility (Replicability).
Data Availability: Modern biological science demands transparency. Raw
data files, alongside the statistical methods used, must be available upon
request to allow peers to verify the findings. This is a critical ethical
component of data integrity.
Robustness Check: A truly robust scientific finding is one where the
conclusion remains valid even when the data is analyzed using slightly
different, but appropriate, statistical methods (e.g., using a non-parametric
test instead of a parametric
t
-test).
Pitfall D (Cherry-Picking Data): The most serious ethical mistake is selectively
omitting data points ("outliers") without a clear, a priori (pre-established) objective,
and documented reason (e.g., a clear equipment failure). Every data point collected
must be reported and accounted for. Manipulating data to achieve a desired
p<0.05
result is scientific misconduct.
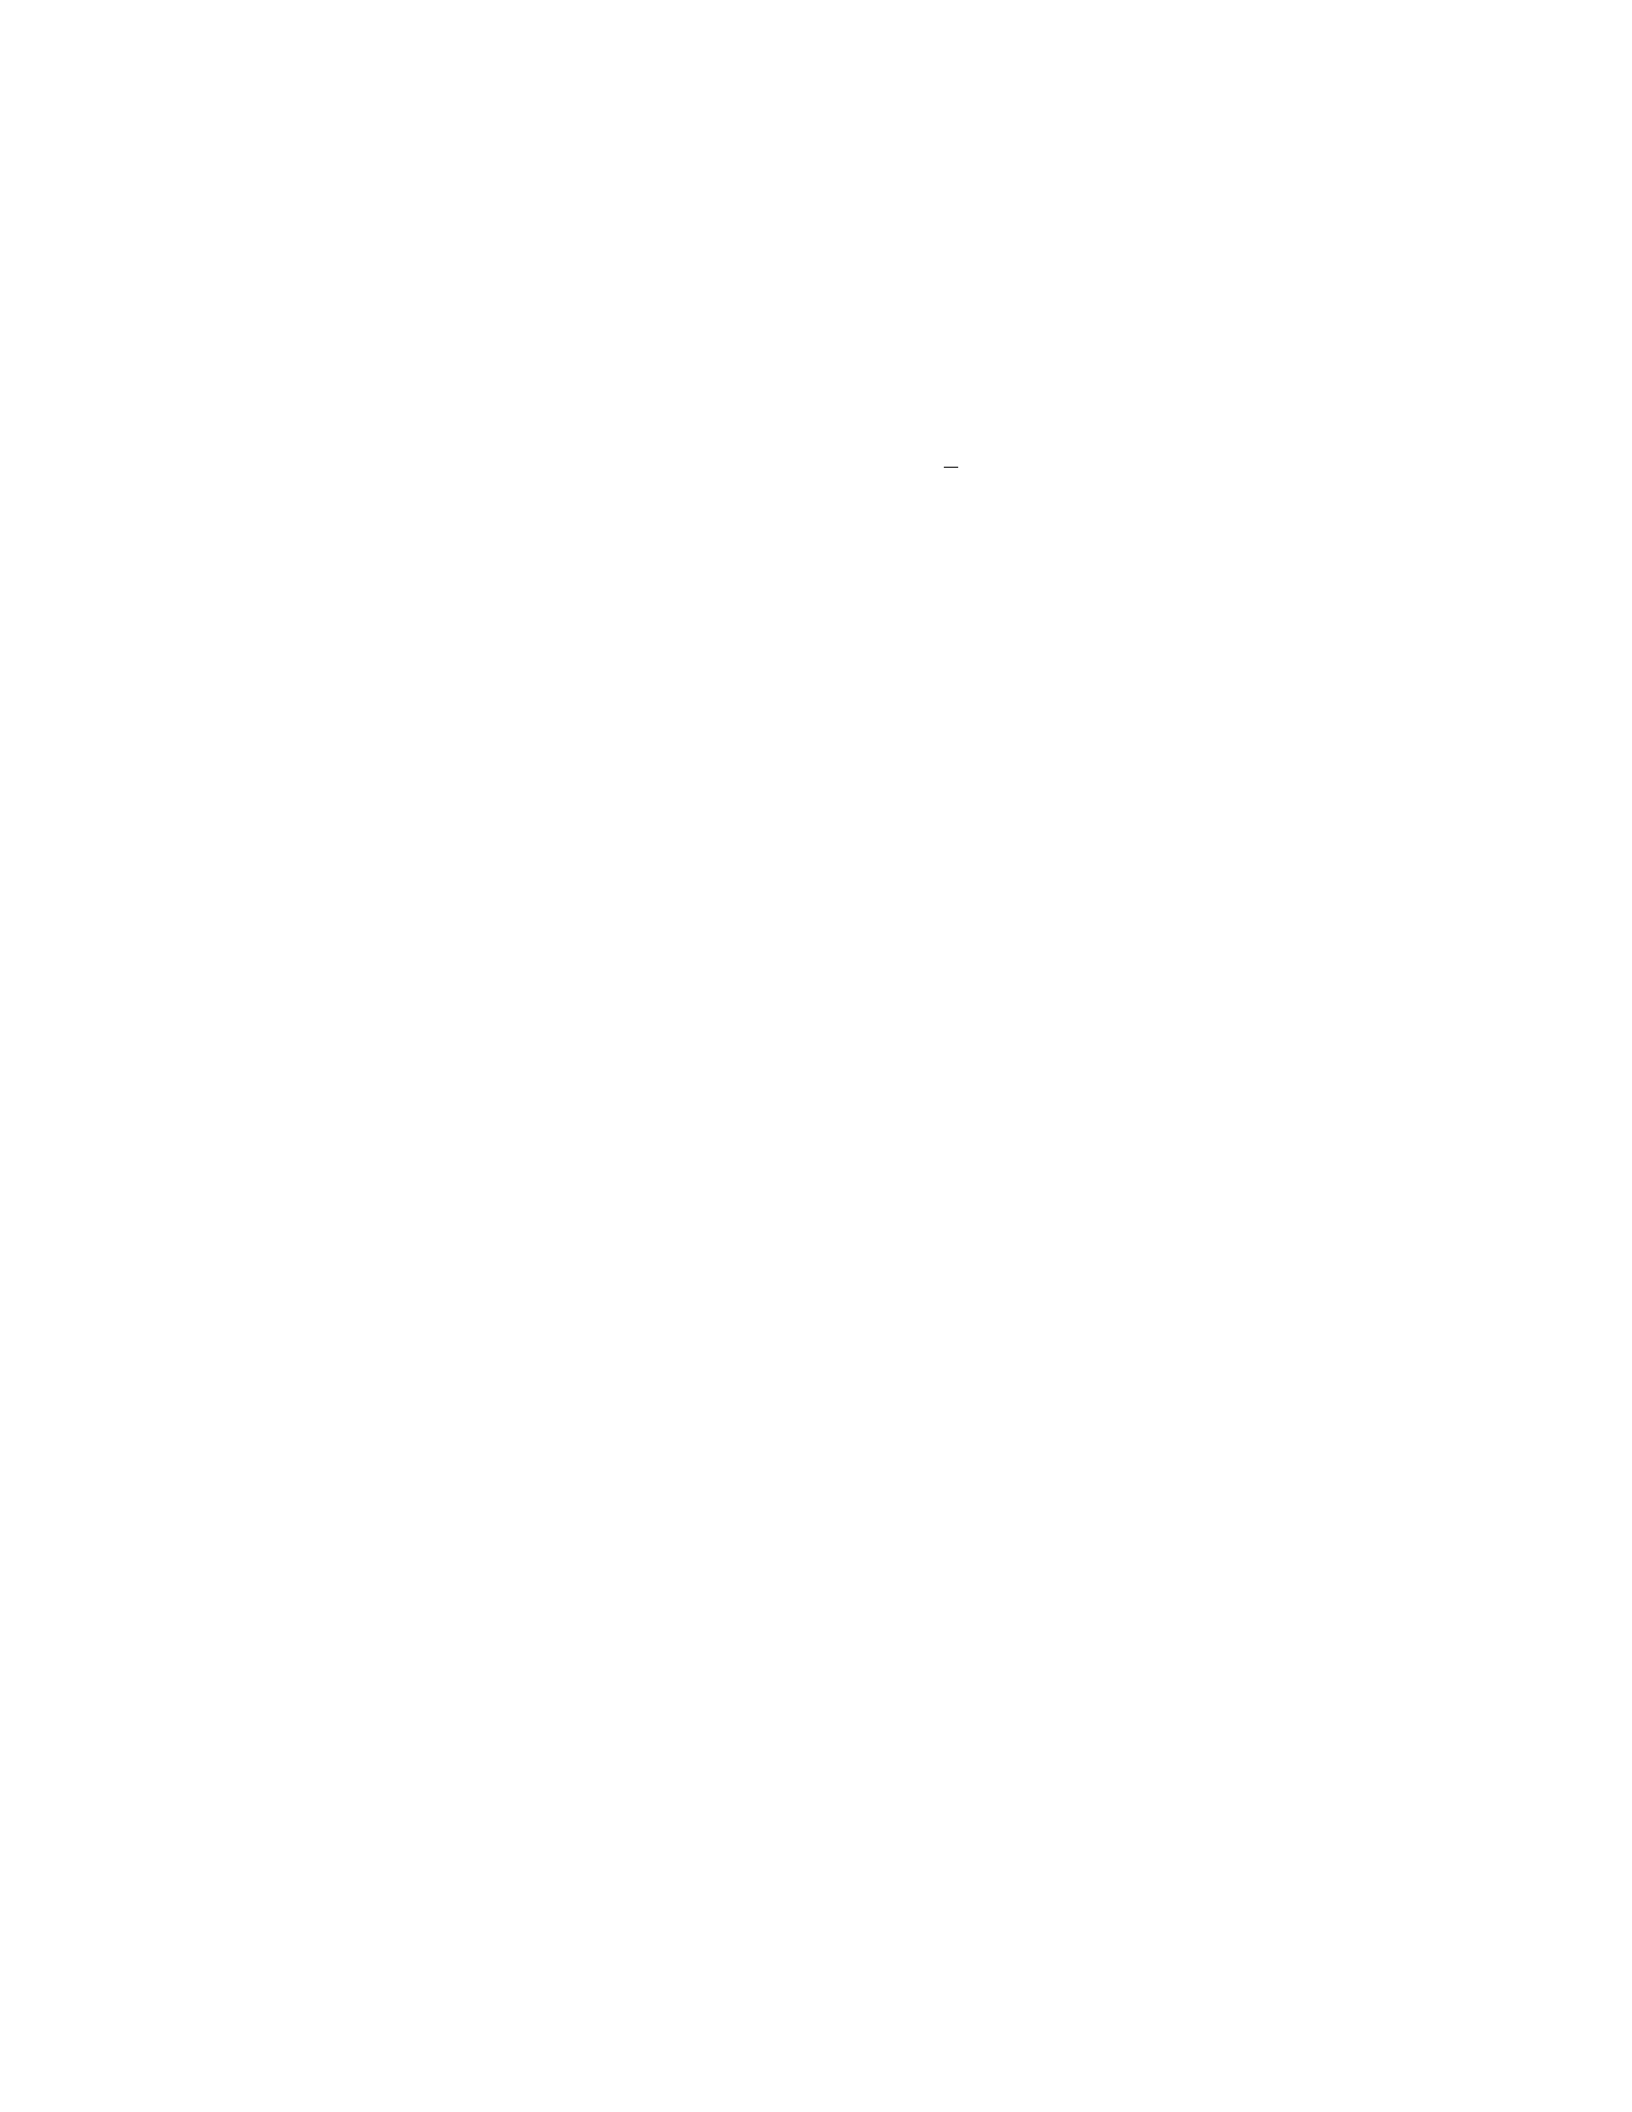
9. Final Review: The Data Analysis Checklist
To ensure your BIO 181 lab report is rigorous and valid, apply this checklist to your
data section:
Type Check: Have I correctly categorized the Independent Variable as
Continuous (Line Graph) or Categorical (Bar Graph)?
Central Value: Have I calculated the Mean (
x
) for all treatment groups?
Variability Check: Have I calculated and interpreted the Standard
Deviation (
s
) for all groups?
Visualization: Is the correct graph type used? Are both axes properly
labeled, including Units?
Error Bars: Are the error bars present and clearly defined (e.g.,
±1 SD
or
±1 SEM
)?
Inference: Have I used appropriate inferential statistics (e.g.,
t
-test) to
determine the
p
-value and addressed the Null Hypothesis?
Mastering this framework transforms you from a data collector into a true biological
scientist. Data is the story of life; your job is to tell that story clearly, honestly, and
statistically.

