


ENVR 370 - GEOGRAPHIC
INFORMATION SYSTEMS (GIS) -
Spatial data analysis and modeling
Question Bank - Set 2
Liberty University
Question 1
Question
Let X1, X2, X3, . . . , Xnbe a sequence of random variables representing the spa-
tial locations of trees in a forest. Assume that Xiand Xjare independent for
all i=j. If Xifollows a Poisson distribution with mean λfor all i, what is the
mean intensity of the point process defined by these random variables?
Solution
Step 1: The mean intensity of a point process is defined as the expected number
of points per unit area. In this case, we need to find the expected number of
points in a unit area.
Step 2: Since each Xifollows a Poisson distribution with mean λ, the ex-
pected number of points in a unit area is λ.
Step 3: Therefore, the mean intensity of the point process defined by X1, X2, X3, . . . , Xn
is λ.
Question 2
Question
Given a dataset of geographical coordinates representing the locations of var-
ious earthquakes, perform a spatial data analysis to identify any clustering or
patterns in the earthquakes. Use appropriate spatial analysis techniques and
provide a detailed explanation of your methodology.

Solution
To perform a spatial data analysis on the earthquake dataset, we will follow
these steps:
Step 1: Data Exploration - Begin by loading the earthquake dataset
containing geographical coordinates (latitude and longitude) into a software
tool such as R, Python, or QGIS. - Plot the earthquake locations on a map to
visualize the spatial distribution of the earthquakes. - Calculate basic descriptive
statistics such as mean, median, standard deviation of the earthquake locations
to understand their central tendencies.
Step 2: Spatial Autocorrelation Analysis - Conduct a spatial autocor-
relation analysis to determine if there is any clustering or spatial patterns in the
earthquake dataset. - Use statistical measures such as Moran’s I or Geary’s C
to quantify spatial autocorrelation. - Interpret the results of the spatial auto-
correlation analysis to identify significant spatial patterns.
Step 3: Spatial Clustering Analysis - Apply a spatial clustering algo-
rithm such as K-means clustering or DBSCAN to identify clusters of earthquakes
within the dataset. - Adjust parameters in the clustering algorithm to optimize
cluster detection and interpret the results. - Visualize the identified clusters on
a map to understand the spatial distribution of the earthquake clusters.
Step 4: Spatial Modeling - Develop a spatial model to predict the like-
lihood of future earthquakes based on the existing dataset. - Use techniques
such as spatial regression, spatial interpolation, or machine learning algorithms
to create the spatial model. - Evaluate the performance of the spatial model
using appropriate validation techniques.
By following these steps of data exploration, spatial autocorrelation analysis,
spatial clustering analysis, and spatial modeling, we can effectively analyze the
earthquake dataset to identify any clustering or patterns in the earthquakes.
Question 3
Question
Consider a dataset containing information about the average temperature in
different cities over the past decade. You are interested in analyzing the spatial
patterns of temperature variation across these cities. Describe how you would
approach this spatial data analysis and modeling, including the steps you would
take and the techniques you would use.
Solution
To analyze the spatial patterns of temperature variation across cities using spa-
tial data analysis and modeling, the following steps can be taken:
Step 1: Data Collection Collect the dataset containing information about
the average temperature in different cities over the past decade. Ensure that
2

the data is accurate and reliable. Include geographic coordinates (latitude and
longitude) of each city for spatial analysis.
Step 2: Data Exploration Explore the dataset using statistical tools and
visualization techniques to understand the distribution of temperature values
and identify any outliers or missing data. Plotting the data on a map can
provide insights into spatial patterns.
Step 3: Spatial Autocorrelation Analysis Conduct a spatial autocorre-
lation analysis to determine if there is any spatial dependence in the temperature
data. Use tools like Moran’s I or Geary’s C to quantify spatial autocorrelation.
Step 4: Spatial Interpolation Perform spatial interpolation to estimate
temperature values at locations where data is missing or to create continuous
surfaces of temperature distribution across cities. Common interpolation meth-
ods include Kriging, Inverse Distance Weighting, and Spline interpolation.
Step 5: Spatial Clustering Apply spatial clustering techniques to group
cities with similar temperature patterns together. Methods like K-means clus-
tering or hierarchical clustering can help identify spatial clusters of cities with
similar temperature characteristics.
Step 6: Spatial Regression Modeling Develop a spatial regression model
to analyze the relationship between temperature and other variables such as
altitude, latitude, longitude, and urbanization. Spatial regression techniques
account for spatial autocorrelation in the data.
Step 7: Model Validation Validate the spatial regression model using
techniques like cross-validation or split-sample validation to assess its predictive
accuracy and generalizability.
Step 8: Interpretation and Visualization Interpret the results of the
spatial data analysis and modeling to draw insights about the spatial patterns
of temperature variation across cities. Visualize the results using maps, scatter
plots, and other graphical tools to communicate findings effectively.
Question 4
Question
Suppose you are given a dataset consisting of the latitude and longitude co-
ordinates of various crime incidents in a city. The goal is to perform spatial
analysis on this dataset to identify hotspots of criminal activity. Explain the
steps involved in conducting a spatial analysis and modeling for this scenario.
Solution
To conduct a spatial analysis and modeling for identifying hotspots of criminal
activity in a city using latitude and longitude coordinates, the following steps
can be followed:
Step 1: Data Preprocessing - Clean the dataset by removing any missing
or irrelevant data points. - Convert the latitude and longitude coordinates into
3
a spatial object using appropriate spatial data structures.
Step 2: Exploratory Spatial Data Analysis (ESDA) - Calculate basic
statistical measures such as mean center, standard distance, and Moran’s Ito
understand the spatial distribution of the crime incidents. - Create plots such
as scatter plots, histograms, or spatial lag plots to visualize the distribution of
crime incidents.
Step 3: Spatial Autocorrelation Analysis - Use techniques like Moran’s
Ior Geary’s Cto examine the spatial autocorrelation in crime incident data.
- Determine if the distribution of crime incidents is clustered, dispersed, or
random.
Step 4: Hotspot Analysis - Apply techniques like Getis-Ord Gi* statistic
or Kernel density estimation to identify areas with statistically significant clus-
ters of high or low crime incidents. - Generate hotspot maps to visualize the
identified hotspots.
Step 5: Spatial Modeling - Build a spatial regression model to understand
the factors influencing the spatial patterns of crime incidents. - Include rele-
vant covariates such as population density, socioeconomic factors, or distance
to police stations in the model.
Step 6: Model Evaluation - Assess the goodness-of-fit of the spatial regres-
sion model using measures like R-squared, AIC, or BIC. - Validate the model
by checking for spatial autocorrelation in the residuals.
By following these steps, analysts can effectively identify hotspots of criminal
activity in a city and develop spatial models to understand the underlying factors
contributing to these patterns.
Question 5
Question
Suppose we have a dataset containing the locations of 100 different bird species
in a forest. Each species has a different preference for elevation, with some
preferring higher elevations and others preferring lower elevations. We are in-
terested in analyzing the spatial distribution of these species and creating a
model to predict the distribution of a new, unknown species based on elevation.
Describe the steps you would take to perform spatial data analysis and modeling
in this scenario.
Solution
To perform spatial data analysis and modeling in this scenario, we can follow
these steps:
Step 1: Data Collection
Gather data on the locations of the 100 different bird species in the forest.
Collect information on the elevations at each of these locations.
4
Step 2: Data Preprocessing
Check the data for any missing or erroneous entries.
Normalize the elevation data to ensure that all values are comparable.
Step 3: Exploratory Data Analysis
Plot the distribution of bird species across different elevations.
Use spatial visualization techniques such as heatmaps or choropleth maps
to visualize the spatial distribution.
Step 4: Spatial Analysis
Use spatial autocorrelation analysis to determine if there are any spatial
patterns in the data.
Perform spatial clustering to identify regions with similar species distri-
butions.
Step 5: Modeling
Choose a suitable modeling technique, such as spatial regression or ma-
chine learning algorithms.
Split the data into training and testing sets.
Train the model on the training set and evaluate its performance on the
testing set.
Step 6: Prediction
Use the trained model to predict the distribution of a new, unknown
species based on elevation data.
Validate the prediction by comparing it to actual observations of the new
species.
By following these steps, we can effectively analyze the spatial distribution
of bird species in the forest and create a model to predict the distribution of
new species based on elevation.
Question 6
Question
Consider a dataset containing information about the locations of 200 stores in a
city. You have been tasked with analyzing the spatial distribution of these stores
to identify any clustering patterns. Using spatial data analysis and modeling
techniques, determine if there is significant spatial clustering of these stores.
5
Solution
To analyze the spatial distribution of the stores and determine if there is sig-
nificant clustering, we can use spatial statistical techniques such as Ripley’s K
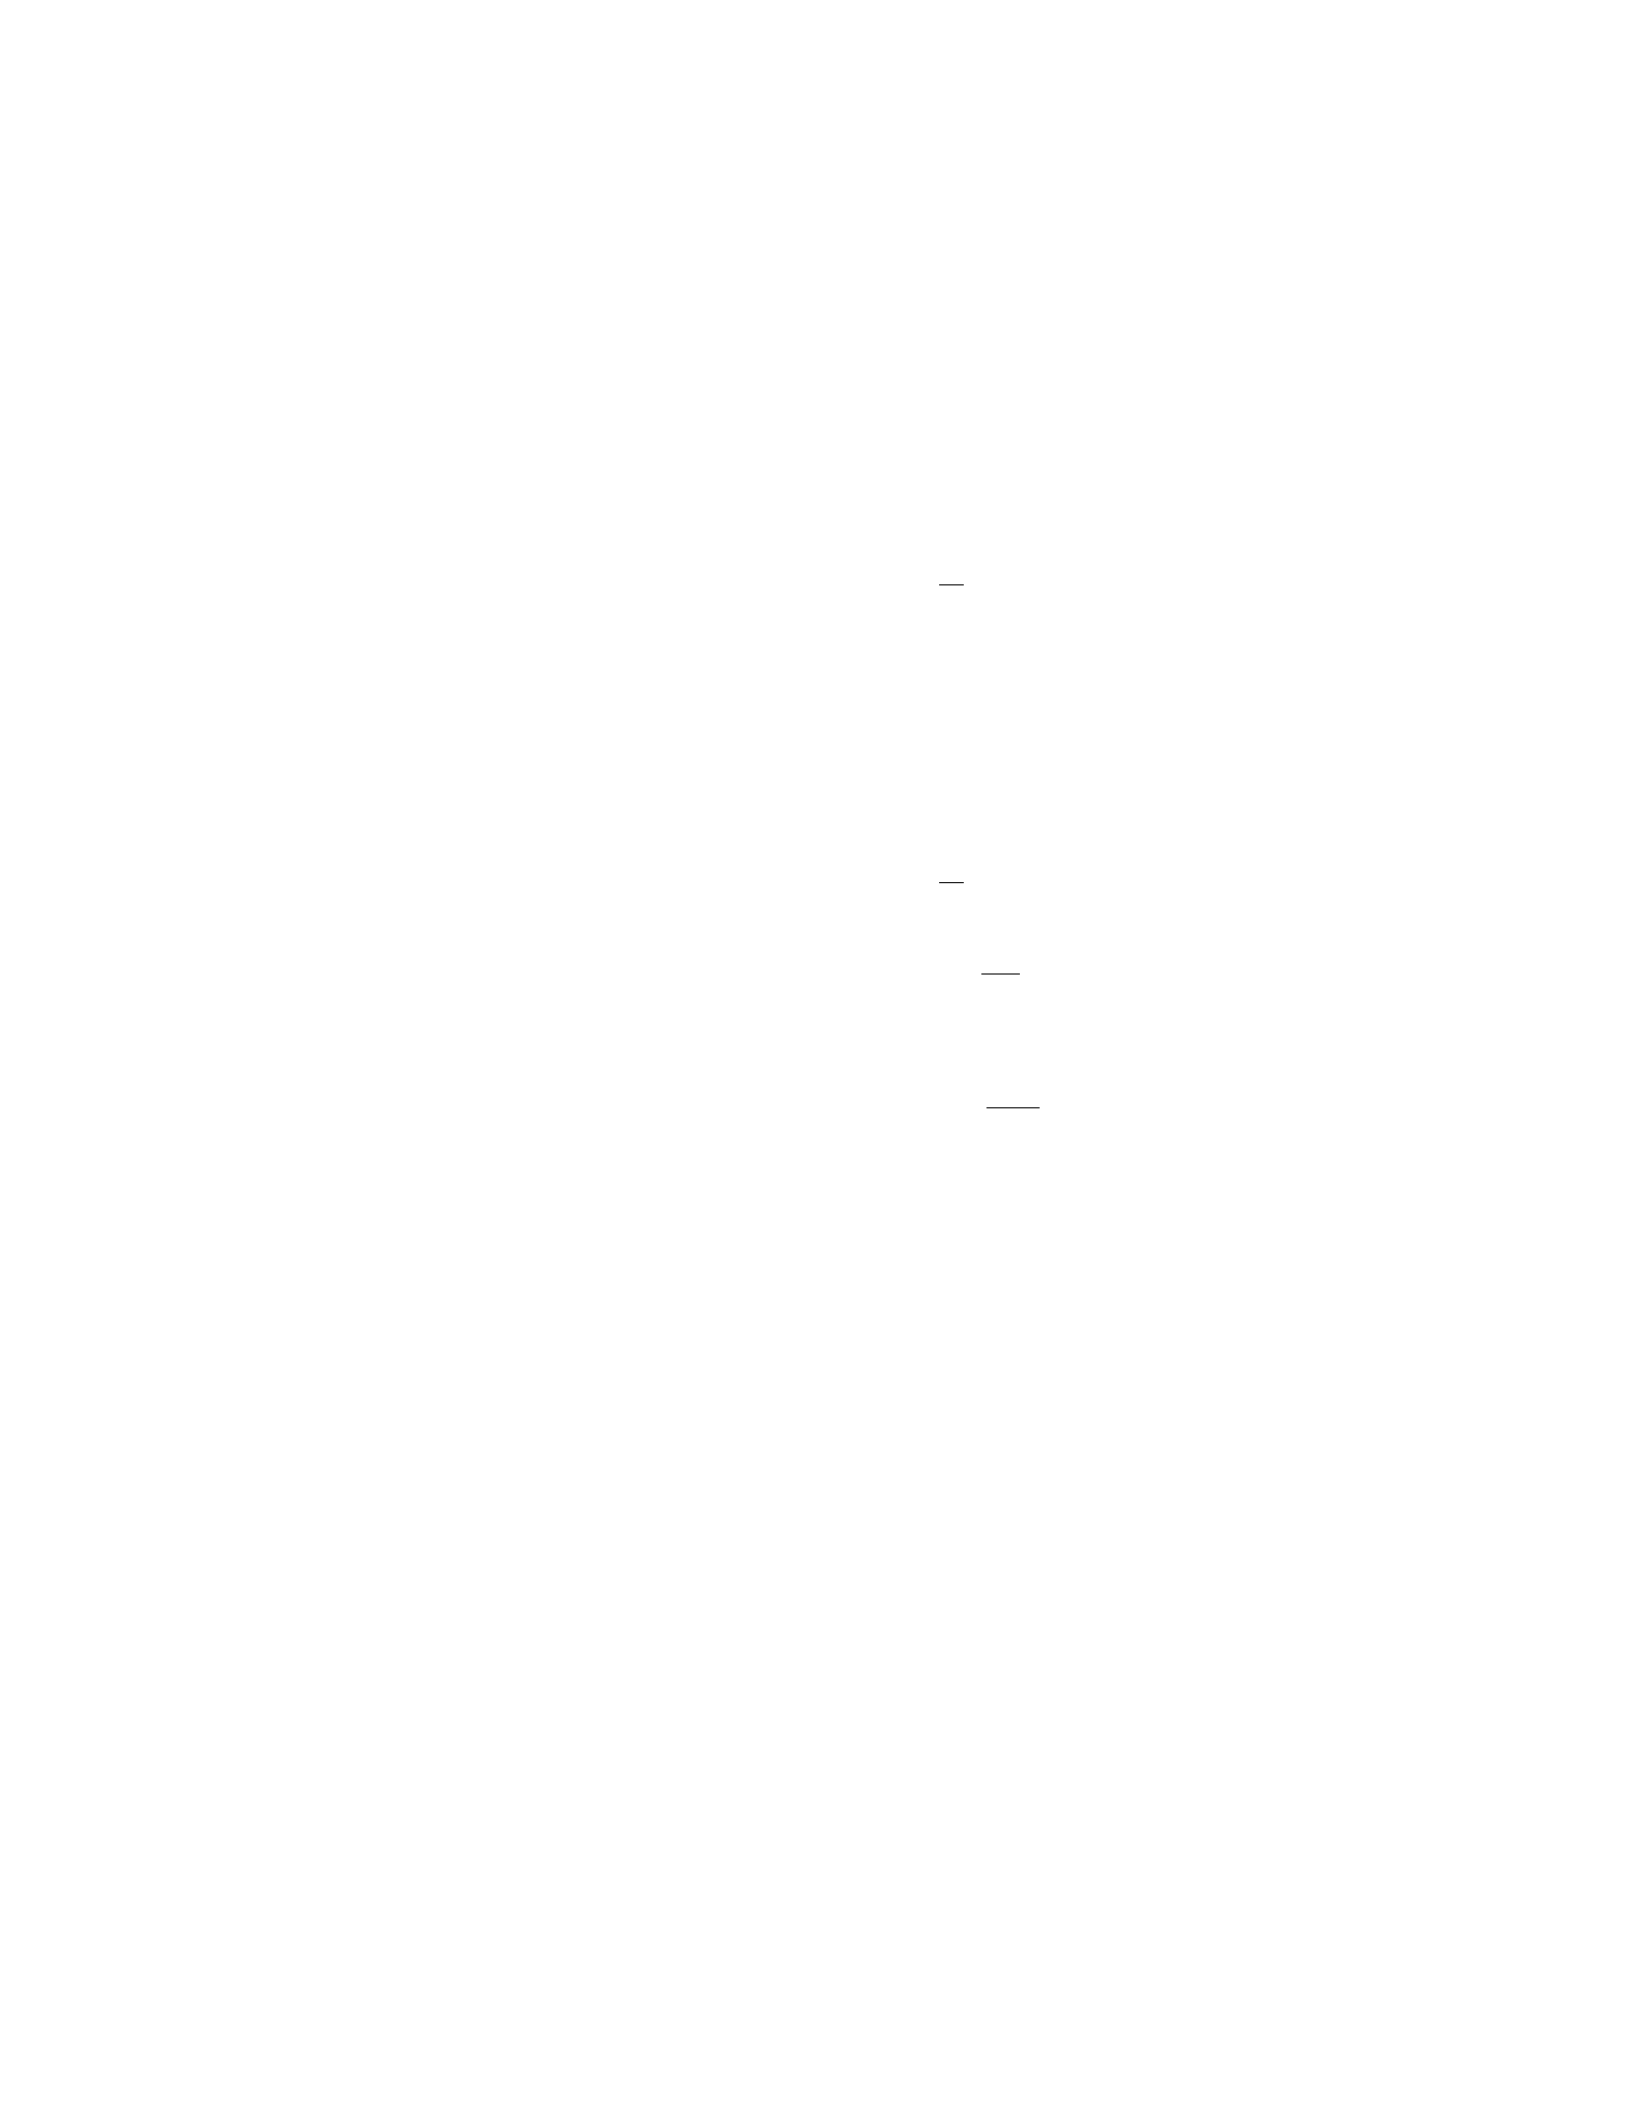
function.
Step 1: Define Hypotheses Let’s define the null and alternative hypothe-
ses: - Null Hypothesis (H0): The stores are distributed randomly in the city.
- Alternative Hypothesis (Ha): The stores exhibit clustering in their spatial
distribution.
Step 2: Compute Ripley’s K Function Ripley’s K function is a common
tool to assess spatial clustering. It evaluates whether the spatial distribution of
points is more clustered, dispersed, or random in comparison to a completely
spatially random distribution. By calculating K(r) for different distances r, we
can analyze the spatial pattern:
K(r) = A
n2
n
X
i=1
n
X
j=1
wij
Where: - Ais the total area of the study region. - nis the total number
of points (stores). - wij is a weighting function that depends on the distance
between points iand j.
Step 3: Compare Observed vs. Expected K Function We compare
the observed K function with the expected K function under the assumption of
complete spatial randomness (CSR). If the observed K function curves above
the upper envelope of the expected K function, it suggests clustering.
Step 4: Statistical Significance To determine the statistical significance
of the clustering pattern, we can use Monte Carlo simulation techniques. By
simulating many random point patterns under CSR and comparing their K
functions with the observed K function, we can calculate a p-value to assess if
the clustering is statistically significant.
By following these steps, we can analyze the spatial distribution of the stores
and determine if there is significant clustering present in the dataset.
Question 7
Question
Let Xbe a spatial data set consisting of npoints {x1,x2,...,xn}in a two-
dimensional space. The spatial weights matrix Wis defined such that wij =
exp(−∥xi−xj∥2)for i=jand wii = 0 for i= 1,2, . . . , n. Given that D=
diag({di}) is a diagonal matrix where di=Pn
j=1 wij , show that tr(W) = tr(D)
where tr(·) denotes the trace of a matrix.
6

Solution
Step 1: Compute tr(W).
tr(W) =
n
X
i=1
wii =
n
X
i=1
0=0
Step 2: Compute tr(D).
tr(D) =
n
X
i=1
di=
n
X
i=1
n
X
j=1
wij =
n
X
i=1
n
X
j=1
exp(−∥xi−xj∥2)
Step 3: Notice that wij = exp(−∥xi−xj∥2)=wji, implying Wis a
symmetric matrix. Thus, tr(W) = tr(D).
Question 8
Question
Suppose we have a dataset consisting of the longitude and latitude coordinates
of 100 different weather stations across a region. The goal is to perform spa-
tial interpolation to estimate the temperature at a location where there isn’t a
weather station. Explain the process of spatial interpolation using the Kriging
method.
Solution
To estimate the temperature at a location where there isn’t a weather station, we
can use spatial interpolation methods such as Kriging. Kriging is a geostatistical
method that provides optimal estimates of the variable of interest at unmeasured
locations based on the values of nearby measured locations.
Step 1: Define the problem We start by defining the problem, which
includes determining the variable to be estimated (temperature in this case),
selecting the appropriate spatial interpolation method (Kriging), and defining
the neighborhoods of each location.
Step 2: Semi-variogram Analysis Next, we calculate the semi-variogram
which describes the spatial autocorrelation of the variable of interest. The semi-
variogram provides information about the spatial structure and variability of the
data, which is crucial for Kriging.
Step 3: Model Fitting Based on the semi-variogram analysis, we fit a
variogram model to the empirical variogram. The variogram model represents
the spatial correlation structure of the data and helps in predicting values at
unmeasured locations.
Step 4: Kriging Estimation Using the variogram model, we perform
Kriging estimation to interpolate values at unmeasured locations. Kriging pro-
duces the best linear unbiased estimates by incorporating the spatial structure
of the data and the variogram model.
7
Step 5: Prediction After performing Kriging estimation, we can generate
a map of temperature values across the region, including the estimated values
at locations without weather stations. This provides a spatially continuous
representation of the variable of interest.
Step 6: Validation Finally, we should validate the Kriging model by com-
paring the predicted values with actual measurements at validation points. This
helps assess the accuracy and reliability of the spatial interpolation results.
Question 9
Question
Consider a dataset containing spatial coordinates (latitude and longitude) of
100 different locations. You are tasked with analyzing and modeling the spatial
pattern of a certain environmental variable (e.g., temperature, pollution levels)
measured at each location. Describe the steps you would take to carry out
spatial data analysis and modeling for this dataset.
Solution
To analyze and model the spatial pattern of the environmental variable in the
given dataset, we can follow these steps:
Step 1: Data Visualization
Plot the locations on a map using latitude and longitude coordinates to
visually inspect the spatial distribution of the data points.
Create a scatter plot with the environmental variable values to identify
any initial patterns or clusters.
Step 2: Exploratory Spatial Data Analysis (ESDA)
Conduct spatial autocorrelation analysis to determine if there is any spa-
tial dependency in the data.
Generate spatial correlograms or Moran’s I scatterplots to assess the de-
gree of spatial autocorrelation.
Use spatial interpolation techniques (e.g., kriging, inverse distance weight-
ing) to estimate environmental variable values at unsampled locations.
Step 3: Spatial Modeling
Choose an appropriate spatial regression model to quantify the relation-
ship between the environmental variable and other spatial predictors (if
available).
Fit the spatial regression model using techniques like Geographically Weighted
Regression (GWR) or Conditional Autoregressive (CAR) models to ac-
count for spatial autocorrelation.
8
Step 4: Model Evaluation
Evaluate the performance of the spatial model using measures like R-
squared, AIC, BIC, and Geographically Weighted R-squared.
Validate the model using cross-validation techniques to assess its predic-
tive accuracy.
Step 5: Interpretation
Interpret the results and draw conclusions about the spatial patterns of
the environmental variable based on the model outputs.
Visualize the model predictions on a map to communicate the spatial
distribution of the variable effectively.
Question 10
Question
Consider a dataset consisting of spatial coordinates of 100 different locations.
Each location has an associated value representing the air quality index at that
point. Perform the following steps: 1. Use a scatter plot to visualize the spatial
distribution of air quality indices. 2. Fit a spatial model to the data using
kriging estimation. 3. Generate a contour map of the predicted air quality
indices over the entire study area.
Solution
1. To visualize the spatial distribution of air quality indices, we can create a
scatter plot using the given dataset of 100 locations. Let’s denote the spatial
coordinates as (xi, yi) and the air quality index as Zifor i= 1,2, ..., 100.
2. Let’s fit a spatial model to the data using kriging estimation. Kriging
is a geostatistical interpolation technique that estimates values at unsampled
locations based on the spatial autocorrelation of the data. The kriging estimate
ˆ
Z(s0) at an unsampled location s0is given by:
ˆ
Z(s0) =
n
X
i=1
λiZ(si)
where λiare the kriging weights and siare the sampled locations.
3. Once the kriging estimation is performed, we can generate a contour map
of the predicted air quality indices over the entire study area. This contour
map will provide a spatial visualization of the predicted air quality indices at
different locations in the study area.
9

Question 11
Question
Let Xbe a spatial point process on a bounded region D⊂R2with intensity
function λ(x, y) = 1 + x+y, where (x, y)∈D. Given that the second moment
of the number of points falling in a region A⊂Dis Var(N(A)) = 3Area(A) +
9Perimeter(A), find the area and perimeter of D.
Solution
Step 1: Recall that the variance of the number of points in a region Afor a
Poisson point process with intensity λis given by Var(N(A)) = RAλ(x, y)dxdy.
Step 2: We have that Var(N(A)) = 3Area(A)+9Perimeter(A). Substituting
our intensity function λ(x, y) = 1 + x+yinto the formula, we get
ZA
(1 + x+y)dxdy = 3Area(A) + 9Perimeter(A).
Step 3: Integrating (1 + x+y) over the region Agives
ZZA
(1 + x+y)dxdy = Area(A) + 1
2Area(A) + 1
2Area(A) = 2Area(A).
Step 4: We obtain 2Area(A) = 3Area(A) + 9Perimeter(A). Rearranging this
equation gives 3Area(A) = 9Perimeter(A).
Step 5: Since Dis a bounded region in R2, we have the relation Area(D) =
1
2Perimeter(D). Thus, we can rewrite 3Area(D) = 9Perimeter(D).
Step 6: Solving these two equations simultaneously, we find Area(D)=3
and Perimeter(D) = 1. Therefore, the area of Dis 3 units2and the perimeter
of Dis 1 unit.
Question 12
Question
Suppose you are given a dataset containing the latitude and longitude coor-
dinates of various points of interest in a city. You are interested in building
a spatial regression model to predict the property prices in different neighbor-
hoods based on the distance to these points of interest. Explain the steps you
would take to perform spatial data analysis and modeling.
Solution
To perform spatial data analysis and modeling using the dataset provided, follow
these steps:
Step 1: Data Preprocessing
10
Clean the dataset by removing any missing or inconsistent data.
Convert the latitude and longitude coordinates into a spatial object (e.g.,
points) using a spatial package in the chosen programming language.
Check for spatial autocorrelation among the variables to understand the
spatial dependency in the dataset.
Step 2: Exploratory Data Analysis (EDA)
Conduct EDA to visualize the spatial distribution of the points of interest
and property prices on a map.
Use tools like spatial autocorrelation plots, Moran’s I statistic, or Geary’s
C test to check for spatial patterns and relationships.
Step 3: Spatial Regression Modeling
Choose an appropriate spatial regression model (e.g., Spatial Lag Model,
Spatial Error Model) based on the nature of spatial dependency observed
in the dataset.
Define the spatial weights matrix to incorporate the spatial relationships
between neighborhoods.
Fit the spatial regression model to predict property prices based on the
distance to points of interest while accounting for spatial autocorrelation.
Step 4: Model Evaluation
Evaluate the goodness of fit of the spatial regression model using metrics
like R-squared, AIC, and BIC.
Check for spatial autocorrelation in the residuals of the model using diag-
nostic tests like Moran’s I or Geary’s C.
Step 5: Prediction and Inference
Use the fitted spatial regression model to make predictions of property
prices in different neighborhoods based on the distance to points of inter-
est.
Conduct statistical inference to interpret the coefficients of the model and
assess the significance of the spatial effects.
By following these steps, you can successfully perform spatial data analysis
and modeling to predict property prices in different neighborhoods based on the
given dataset.
11
Question 13
Question
Let Xand Ybe two spatial point processes defined on a compact region D⊂R2.
Suppose Xand Yare from a Poisson point process with intensity functions
λX(u) and λY(u), respectively. Show that the joint probability density function
of finding a point of Xat uand a point of Yat vis given by
fX,Y (u, v) = λX(u)λY(v)e−RDλX(w)λY(w)dw
Solution
Step 1: Let NX(A) denote the number of points of Xin a region A⊂D, and
let NY(B) denote the number of points of Yin a region B⊂D. Since Xand Y
are Poisson point processes, the probability of finding nXpoints of Xin region
Aand nYpoints of Yin region Bis given by
P(NX(A) = nX, NY(B) = nY) = RAλX(u)dunXe−RAλX(u)du
nX!RBλY(v)dvnYe−RBλY(v)dv
nY!
Step 2: The joint probability density function of finding a point of Xat u
and a point of Yat vis given by
fX,Y (u, v) =
∞
X
nX=0
∞
X
nY=0
P(NX({u}) = nX, NY({v}) = nY)
Step 3: Substituting the expressions for P(NX({u}) = nX, NY({v}) = nY),
we have
fX,Y (u, v) =
∞
X
nX=0
∞
X
nY=0
λX(u)nXe−λX(u)
nX!
λY(v)nYe−λY(v)
nY!
Step 4: Simplifying the expression gives
fX,Y (u, v) = λX(u)λY(v)e−λX(u)−λY(v)
Step 5: Finally, we can express e−λX(u)−λY(v)as e−RDλX(w)λY(w)dw, which
gives the desired joint probability density function:
fX,Y (u, v) = λX(u)λY(v)e−RDλX(w)λY(w)dw
Question 14
Question
Consider a dataset containing the locations of 1000 trees in a forest. Each tree
is represented by its coordinates (x, y) where xand yare real numbers. You
12
are tasked with analyzing the spatial distribution of these trees to determine
if there are any clusters or patterns present in their distribution. Perform a
Spatial Point Pattern Analysis on this dataset using the Ripley’s K function.
Given that the expected number of trees in a circular region of radius r
around a point is λ= 0.1 trees per unit area, and the observed pattern is
defined by the Ripley’s K function K(r), where:
K(r) = πr2−λπr21 + r2
4
Calculate the estimated value of K(r) for r= 50 units and interpret the
results.
Solution
1. Substitute the given values into the formula for Ripley’s K function:
K(r) = πr2−λπr21 + r2
4
K(50) = π·502−0.1π·5021 + 502
4
2. Calculate the estimated value of K(50):
K(50) = 2500π−0.1·2500π·1 + 2500
4
K(50) = 2500π−0.1·2500π·(1 + 625)
K(50) = 2500π−0.1·2500π·626
K(50) = 2500π−15625π
K(50) = −13125π
3. Interpretation: The estimated value of K(50) is negative, which indicates
that the number of trees within a distance of 50 units is less than expected under
complete spatial randomness. This may suggest a clustering or pattern in the
spatial distribution of trees, with trees being more spaced out than if they were
randomly distributed.
Question 15
Question
Consider a dataset of air pollution levels measured at different locations in a
city. You are tasked with creating a spatial model to predict air pollution levels
at unmeasured locations. Explain the steps involved in spatial data analysis
and modeling to achieve this.
13
Solution
To create a spatial model to predict air pollution levels at unmeasured locations,
several steps in spatial data analysis and modeling need to be followed:
Step 1: Data Collection - Collect air pollution data from various locations
in the city. - Gather spatial covariates such as distance to major roads, land
use type, population density, etc. - Ensure that the data is clean and free from
errors.
Step 2: Exploratory Data Analysis (EDA) - Perform exploratory data
analysis to understand the spatial distribution of air pollution levels. - Check
for any patterns or trends in the data. - Use visualizations such as maps,
histograms, and scatter plots to explore the data.
Step 3: Spatial Autocorrelation Analysis - Conduct spatial autocor-
relation analysis to determine if there is spatial dependence in the data. - Use
techniques such as Moran’s I or Geary’s C to assess spatial autocorrelation. -
If spatial autocorrelation is present, consider incorporating spatial terms in the
model.
Step 4: Model Selection - Choose an appropriate spatial regression model
based on the nature of the data and the research question. - Common spatial
regression models include Spatial Autoregressive (SAR) models, Spatial Error
(SEM) models, and Geographically Weighted Regression (GWR).
Step 5: Model Estimation - Estimate the parameters of the selected spa-
tial regression model using maximum likelihood estimation or other appropriate
methods. - Perform diagnostics to check the goodness-of-fit of the model.
Step 6: Prediction - Use the fitted spatial model to predict air pollution
levels at unmeasured locations. - Validate the predictive performance of the
model using cross-validation or other techniques.
Step 7: Interpretation and Visualization - Interpret the results of the
spatial model in the context of the research question. - Visualize the predicted
air pollution levels on maps to communicate the findings effectively.
By following these steps in spatial data analysis and modeling, one can
develop an accurate spatial model to predict air pollution levels at unmeasured
locations in a city.
Question 16
Question
Let Xand Ybe two spatial processes defined on a region D⊆R2with con-
tinuous and bounded support. Given that the semivariogram of Xis γX(h) =
4−2 cos(h) and the semivariogram of Yis γY(h) = 5 sin(h), calculate the cross-
semivariogram of Xand Y,γXY (h).
Solution
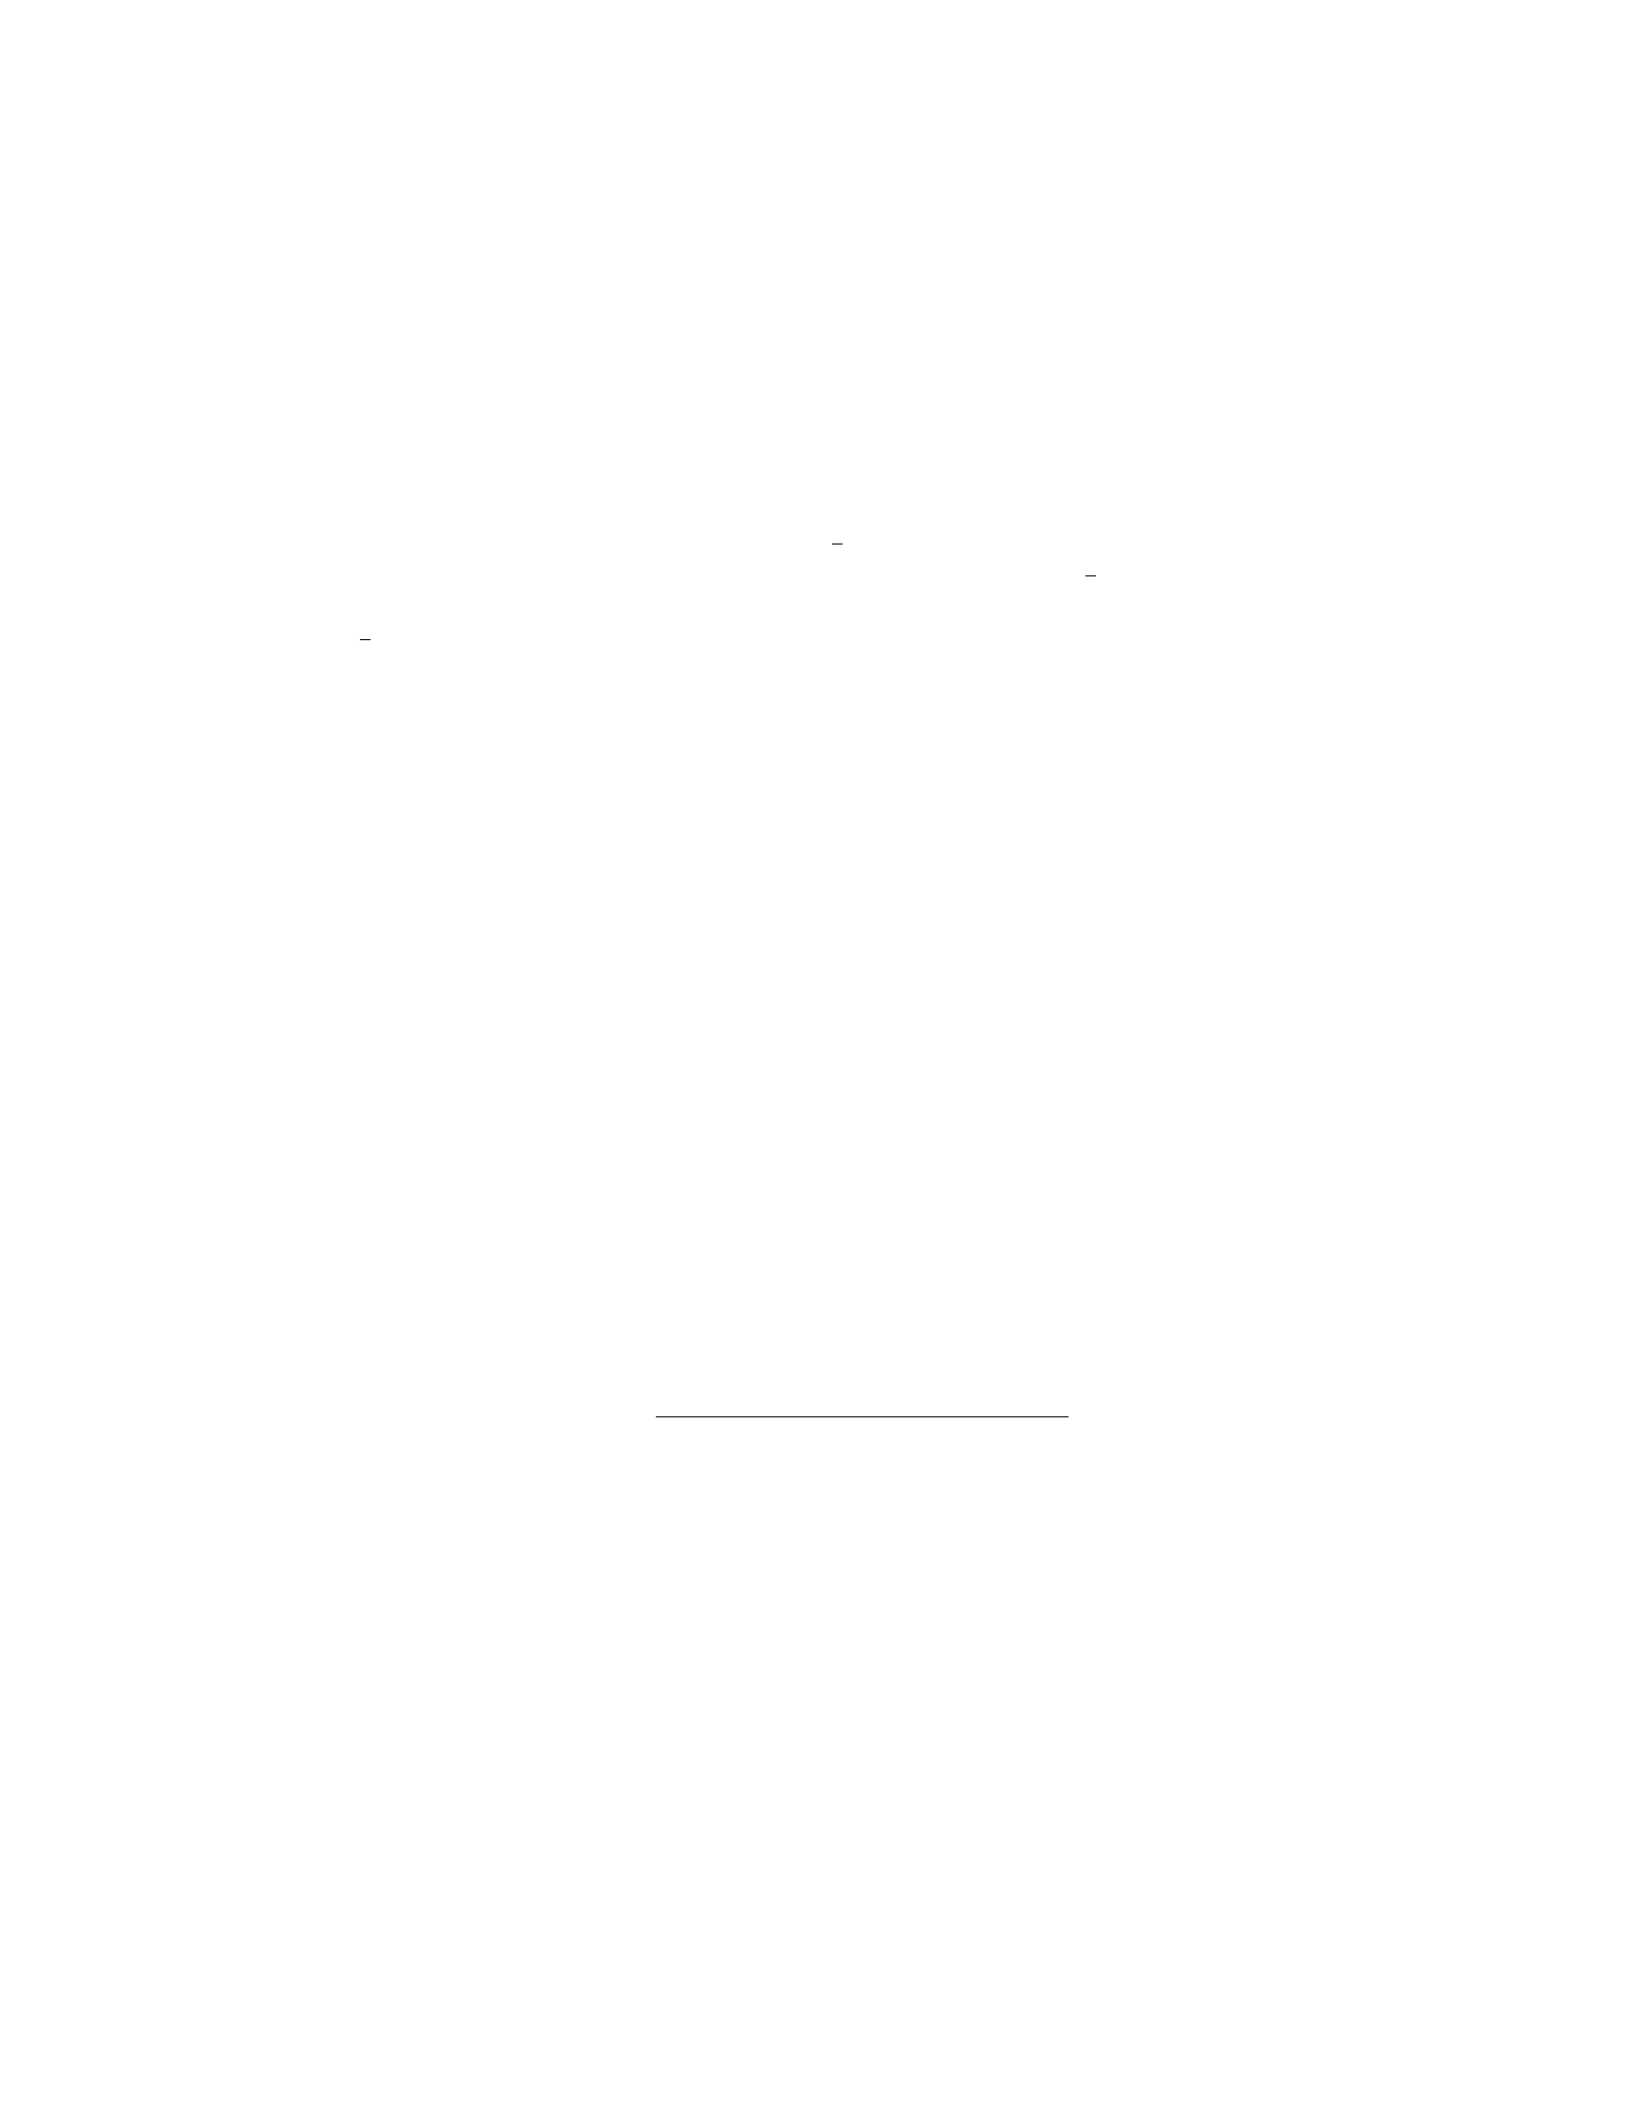
Step 1: The cross-semivariogram of Xand Yis defined as γXY (h) = 1
2(γX(h) + γY(h)−γX(0) −γY(0)).
14
Step 2: We are given that γX(h)=4−2 cos(h) and γY(h) = 5 sin(h).
Step 3: We need to find γX(0) and γY(0) to substitute into the formula for
the cross-semivariogram.
Step 4: Evaluating γX(0), we get γX(0) = 4 −2 cos(0) = 4 −2 = 2.
Step 5: Evaluating γY(0), we get γY(0) = 5 sin(0) = 0.
Step 6: Substituting γX(0) = 2 and γY(0) = 0 into the formula for the
cross-semivariogram, we have γXY (h) = 1
2(4 −2 cos(h) + 5 sin(h)−2−0).
Step 7: Simplifying further, we get γXY (h)=2−cos(h) + 5
2sin(h).
Therefore, the cross-semivariogram of Xand Yis γXY (h) = 2 −cos(h) +
5
2sin(h).
Question 17
Question
Suppose we have a dataset containing the spatial coordinates (latitude and
longitude) of various earthquake occurrences. You are asked to perform a spatial
analysis to determine if there is a clustering effect in the earthquake locations.
Using the information provided in the dataset, propose a suitable spatial analysis
model and explain the steps involved in the analysis.
Solution
To determine if there is a clustering effect in the earthquake locations, we can
utilize a spatial analysis model like the K-function. The K-function measures
the spatial correlation between points in a dataset and compares the observed
point pattern to a hypothetical random pattern of points. The steps involved
in this analysis are as follows:
Step 1: Define the Hypotheses -Null hypothesis (H0): The earthquake
occurrences are randomly distributed in space. - Alternative hypothesis (HA):
The earthquake occurrences exhibit clustering or dispersion.
Step 2: Calculate the K-function The K-function is defined as:
K(d) = Number of points within distance d
λ
Where dis the distance threshold, and λis the intensity of the point process.
Step 3: Calculate the Expected K-function (Kexp)Under the null
hypothesis of complete spatial randomness (CSR), Kexp(d) = πd2for a 2-
dimensional dataset.
Step 4: Calculate the Difference Function
D(d) = Kobs(d)−Kexp(d)
Step 5: Interpretation - If D(d)>0, there is clustering. - If D(d)<0,
there is dispersion. - If D(d)≈0, the pattern is random.
15

Step 6: Statistical Significance Testing Perform statistical tests (e.g.,
Monte Carlo simulation) to determine if the observed clustering or dispersion
is significant. If the p-value is less than the chosen significance level, we reject
the null hypothesis in favor of the alternative hypothesis.
By following these steps, we can effectively analyze the spatial pattern of
earthquake occurrences and determine if there is a clustering effect present in
the dataset.
Question 18
Question
Suppose you are analyzing the spatial distribution of COVID-19 cases in a city.
You have collected data on the number of cases in each neighborhood and want
to create a spatial model to predict the number of cases in a new neighborhood
based on its proximity to neighborhoods with high case counts. Explain the
steps you would take to build a spatial model for this prediction.
Solution
To build a spatial model to predict the number of COVID-19 cases in a new
neighborhood based on its proximity to neighborhoods with high case counts,
you can follow these steps:
Step 1: Data Collection
Collect data on the number of COVID-19 cases in each neighborhood in the city.
Additionally, gather spatial data such as latitude and longitude coordinates or
geographical boundaries of each neighborhood.
Step 2: Data Exploration
Analyze the collected data to understand the spatial distribution of COVID-19
cases in the city. Use exploratory spatial data analysis techniques to identify
any spatial patterns or correlations.
Step 3: Spatial Autocorrelation Analysis
Conduct spatial autocorrelation analysis to determine if there is a spatial depen-
dence between the number of COVID-19 cases in neighboring neighborhoods.
This analysis will help you understand the extent to which proximity to high
case count neighborhoods influences the number of cases in a given neighbor-
hood.
Step 4: Spatial Modeling
Choose an appropriate spatial modeling technique such as spatial regression,
kriging, or spatial interpolation to build a predictive model. This model should
consider the spatial relationships between neighborhoods and incorporate fac-
tors like distance to high case count neighborhoods.
Step 5: Model Validation
Validate the spatial model using techniques like cross-validation or split-sample
16

validation to ensure its accuracy and reliability in predicting COVID-19 cases
in new neighborhoods.
Step 6: Prediction
Apply the validated spatial model to predict the number of COVID-19 cases
in a new neighborhood based on its proximity to neighborhoods with high case
counts. This prediction can help in allocating resources and implementing tar-
geted interventions to prevent the spread of COVID-19.
Question 19
Question
Consider a dataset containing the coordinates of 50 trees in a forest. The goal
is to create a spatial model to predict the distribution of tree heights across the
entire forest based on the given data points. Develop a step-by-step plan to
analyze the spatial data, build a model, and validate its accuracy.
Solution
To create a spatial model to predict tree heights across the entire forest, we can
follow these steps: Step 1: Data Exploration - Plot the coordinates of the trees
on a map to visualize their spatial distribution. - Analyze the distribution of
the tree heights in the dataset.
Step 2: Spatial Data Analysis - Conduct spatial autocorrelation analysis
to check for any spatial patterns in the tree height data. - Perform spatial
interpolation to estimate tree heights at unsampled locations in the forest.
Step 3: Model Building - Select an appropriate spatial regression model (e.g.,
spatial autoregressive model) to relate tree heights to the spatial coordinates. -
Fit the model using the tree height data and spatial coordinates.
Step 4: Model Validation - Split the dataset into training and testing sets.
- Validate the model’s performance using metrics like mean squared error, R-
squared, and cross-validation.
Step 5: Prediction and Mapping - Use the trained model to predict tree
heights at unsampled locations in the forest. - Map the predicted tree heights
to visualize the distribution across the entire forest.
Step 6: Model Refinement - Analyze the model residuals to identify any
systematic patterns not captured by the model. - Refine the model by incorpo-
rating additional spatial variables or transforming the data if necessary.
By following these steps, we can develop a spatial model to predict the
distribution of tree heights across the entire forest, providing valuable insights
for forest management and conservation efforts.
17

Question 20
Question
Suppose you are given a dataset containing the coordinates of various wildlife
sightings in a conservation area. You are interested in creating a spatial model
to predict the probability of wildlife sightings in different regions of the area
based on various environmental factors. Discuss the steps involved in spatial
data analysis and modeling to achieve this goal.
Solution
To create a spatial model to predict the probability of wildlife sightings in
different regions of a conservation area, the following steps are typically involved
in spatial data analysis and modeling:
Step 1: Data Collection - Gather the dataset containing the coordinates
of wildlife sightings and relevant environmental factors such as vegetation type,
water sources, elevation, etc.
Step 2: Data Preprocessing - Check for missing values in the dataset
and handle them appropriately (e.g., imputation or removal). - Remove any
duplicate entries or outliers that could affect the modeling process. - Perform
any necessary transformations or scaling on the variables if needed.
Step 3: Exploratory Data Analysis (EDA) - Conduct EDA to un-
derstand the distribution of the data and relationships between variables. -
Use spatial visualization techniques such as scatter plots, heatmaps, and spatial
autocorrelation plots to explore the data.
Step 4: Spatial Interpolation - Use spatial interpolation techniques (e.g.,
kriging, inverse distance weighting) to estimate values at unsampled locations
based on the observed data.
Step 5: Model Selection - Choose an appropriate spatial statistical model
(e.g., spatial regression models, geostatistical models) based on the nature of
the data and the research question.
Step 6: Model Fitting - Fit the selected spatial model to the data and
evaluate its performance using metrics such as AIC, BIC, or cross-validation.
Step 7: Spatial Prediction - Use the fitted spatial model to predict the
probability of wildlife sightings at different locations in the conservation area.
- Evaluate the model predictions using validation techniques such as spatial
cross-validation.
Step 8: Model Interpretation - Interpret the results of the spatial model
to understand the relationships between environmental factors and wildlife sight-
ings. - Identify key factors driving wildlife presence in different regions of the
conservation area.
By following these steps in spatial data analysis and modeling, researchers
can create accurate and insightful spatial models to predict wildlife sightings
and inform conservation efforts.
18
Question 21
Question
Let Xbe a spatial point process in R2with intensity function λ(x, y) = 2+x2+y
for all (x, y)∈R2, where xand yare the coordinates. Find the expected number
of points in a region A= [0,1] ×[1,2].
Solution
Step 1: Calculate the expected number of points in a region using the intensity
function.
Step 1: λ(A) = Z1
0Z2
1
(2 + x2+y)dy dx
λ(A) = Z1
02y+xy +1
2y22
1
dx
λ(A) = Z1
0
(2 + 2x+3
2)dx
λ(A) = 2x+x2+3
2x1
0
λ(A) = 2 + 1 + 3
2=9
2
Step 2: Find the expected number of points in the region A.
Step 2: E(N(A)) = λ(A)·Area(A)
E(N(A)) = 9
2·(1 −0)(2 −1) = 9
2
Therefore, the expected number of points in the region A= [0,1] ×[1,2] is
9
2.
Question 22
Question
Consider a dataset containing geographical coordinates (latitude and longitude)
of various locations in a city. You are asked to analyze the spatial distribution
of these locations and create a spatial model to predict the location of a new
point based on its proximity to existing locations.
19
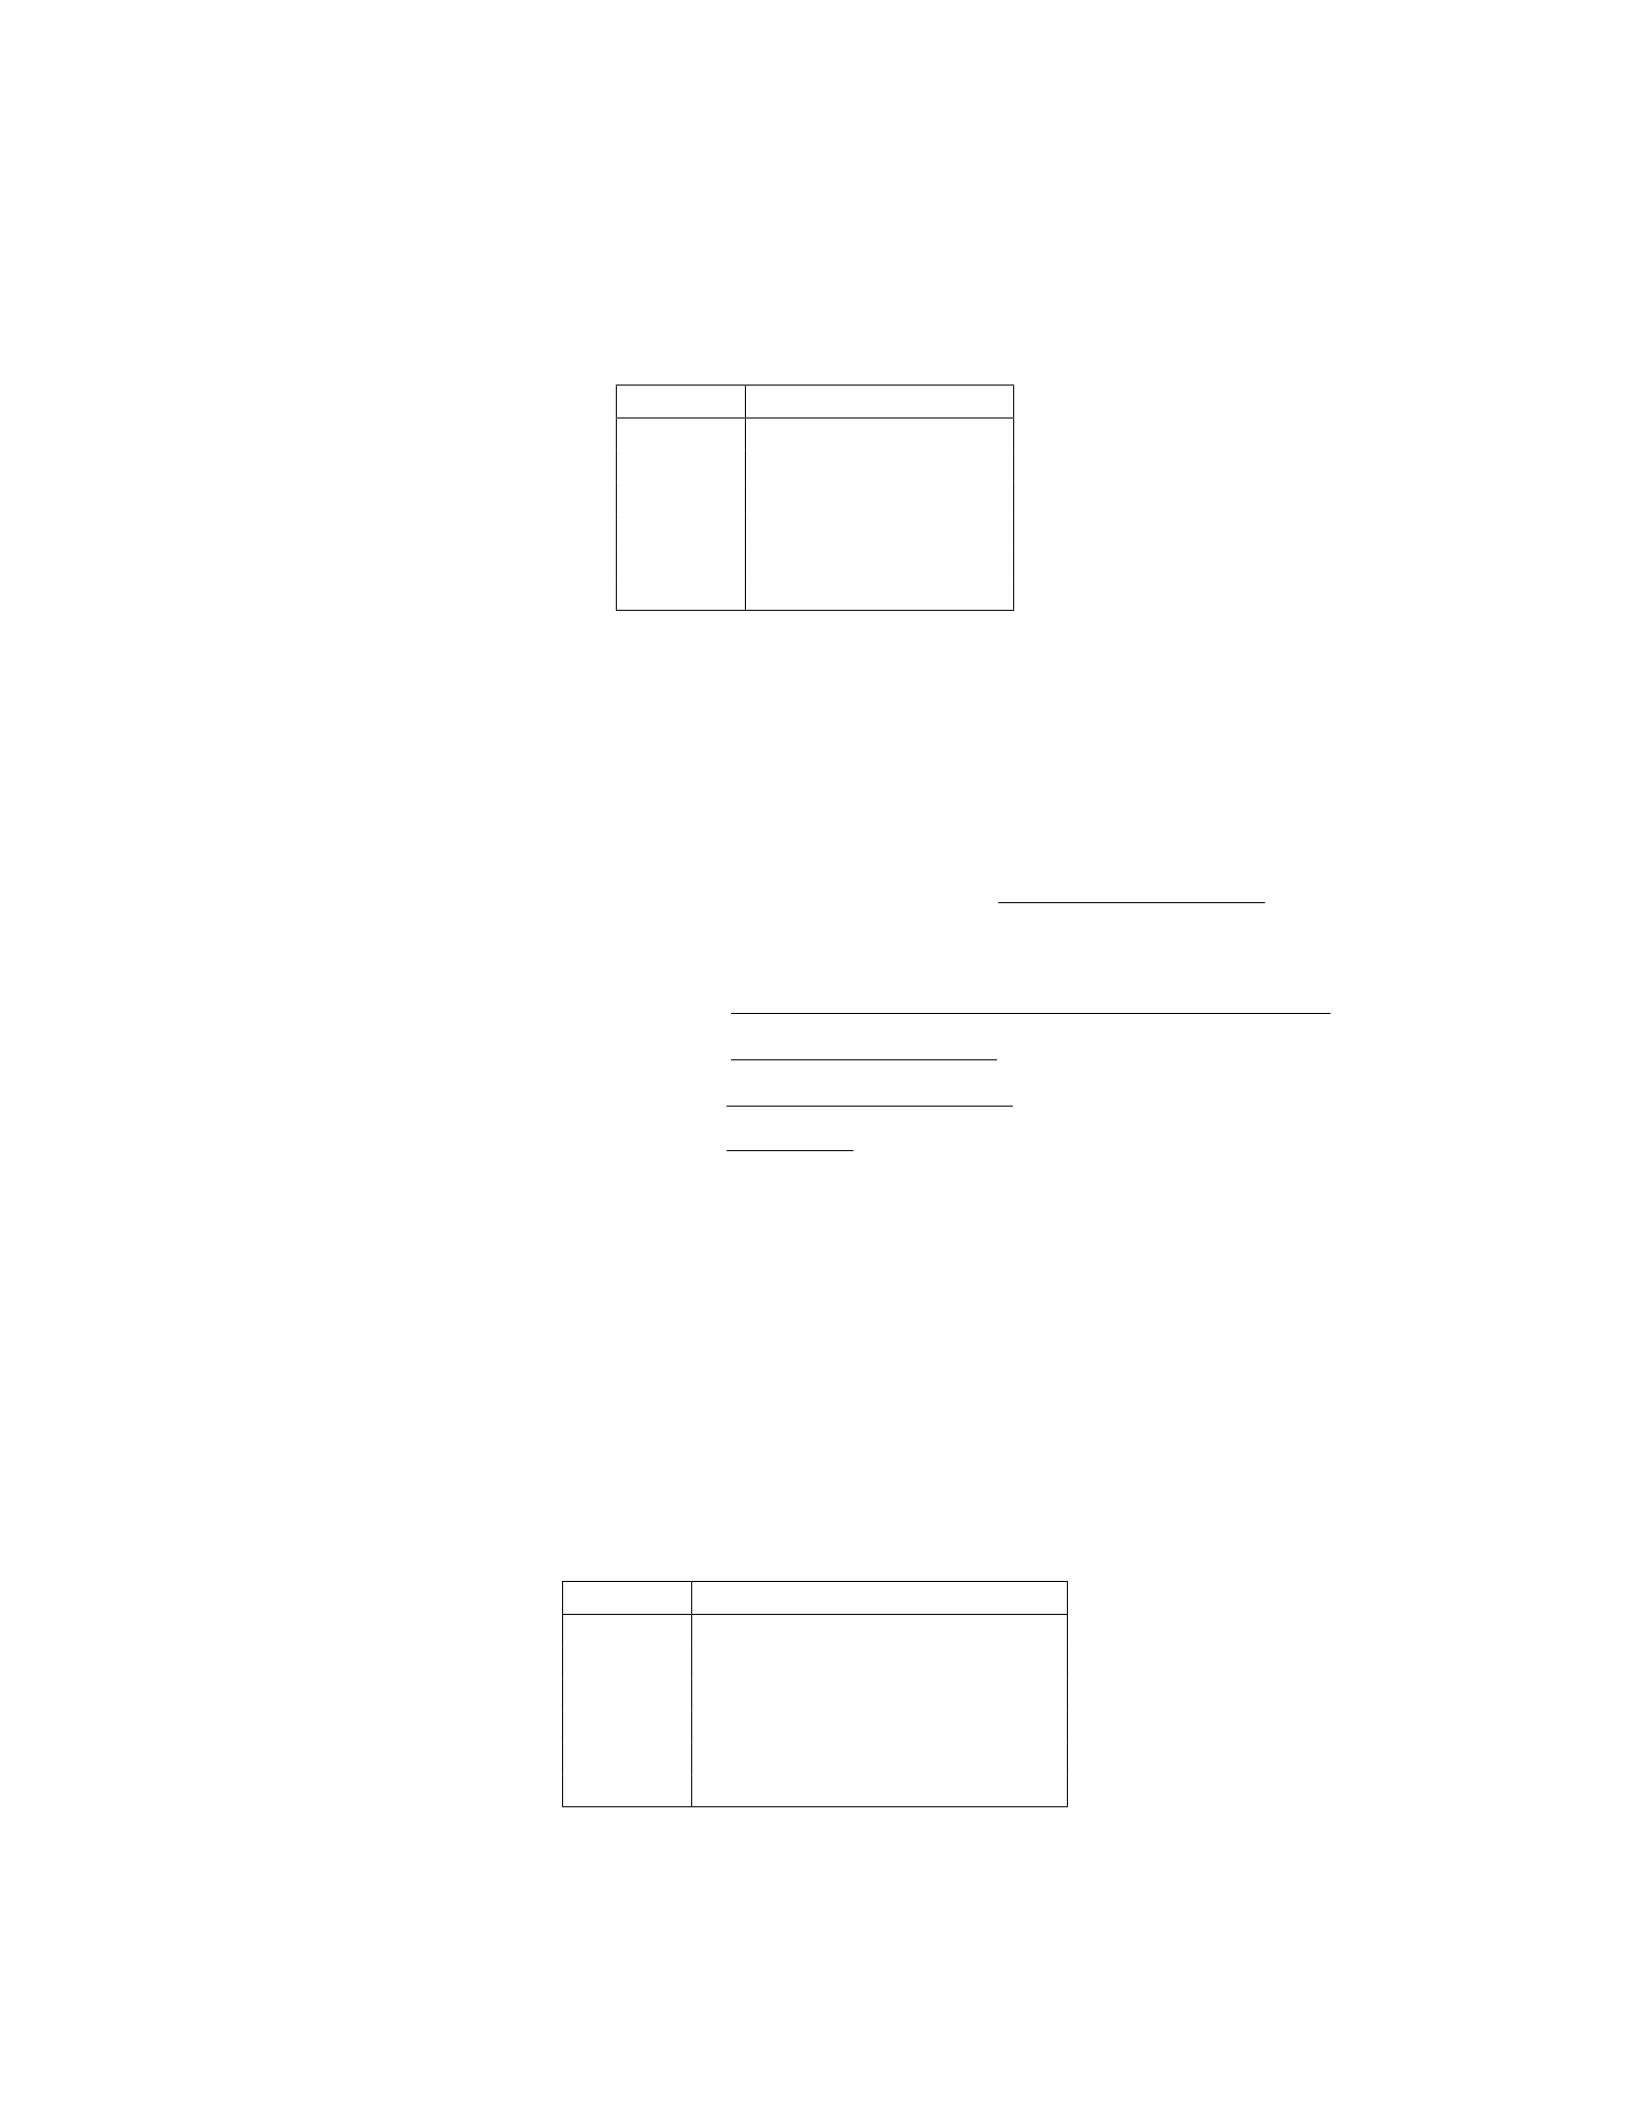
Given the dataset:
Location Coordinates
A(45.5231,−122.6765)
B(45.5189,−122.6793)
C(45.5122,−122.6587)
D(45.5124,−122.6553)
E(45.5194,−122.6686)
F(45.5175,−122.6779)
Assuming a Euclidean distance metric, calculate the distance between points
A and D. Then, using the coordinates of all points, create a spatial model to
predict the location of a new point with coordinates (45.525, -122.670).
Solution
Step 1: Calculate the distance between points A and D using the Euclidean
distance formula:
Distance between two points (x1, y1) and (x2, y2) = p(x2−x1)2+ (y2−y1)2
Plugging in the coordinates for points A and D:
Distance between A and D = p(−122.6553 −(−122.6765))2+ (45.5124 −45.5231)2
=p(0.0212)2+ (−0.0107)2
=√0.00044944 + 0.00011449
=√0.00056393 ≈0.02375
Therefore, the distance between points A and D is approximately 0.02375.
Step 2: To create a spatial model, we can use a k-nearest neighbors (k-NN)
algorithm. For our model, let’s use k=3, meaning we will consider the 3 closest
points to the new point for prediction.
The steps for the k-NN algorithm are as follows: 1. Calculate the Euclidean
distance between the new point and all existing points. 2. Sort the distances in
ascending order and select the k smallest distances. 3. Determine the location
of the majority of the k nearest neighbors as the predicted location for the new
point.
Let’s apply this algorithm to predict the location of the new point (45.525,
-122.670).
Location Distance to (45.525, -122.670)
A0.007491
B0.010828
C0.014210
D0.017280
E0.011725
F0.005084
20
The 3 closest points to (45.525, -122.670) are F, A, and E. Since the majority
of these points are around point A, we predict the location of the new point to
be near point A.
Question 23
Question
Let f(x, y) = e−x2−y2be a spatial covariance function. Find the range of f(x, y)
within a circular region defined by x2+y2≤1.
Solution
Step 1: Recall that the range of a spatial covariance function is the set of all
possible values that the function can take on within a specified region. In this
case, the specified region is the circular region defined by x2+y2≤1.
Step 2: To find the range of f(x, y) within the circular region, we need to
determine the maximum and minimum values of f(x, y) within the region.
Step 3: Since f(x, y) = e−x2−y2, we can rewrite f(x, y) in terms of r=
px2+y2:f(r) = e−r2.
Step 4: In the circular region x2+y2≤1, the maximum value of ris 1 (at
the boundary of the circle).
Step 5: Plug in r= 1 into f(r) = e−r2to find the maximum value of f(r)
within the circular region: f(1) = e−1.
Step 6: Since f(r) is a decreasing function of r, the minimum value of f(r)
within the circular region occurs at the center of the circle where r= 0.
Step 7: Plug in r= 0 into f(r) = e−r2to find the minimum value of f(r)
within the circular region: f(0) = e0= 1.
Step 8: Therefore, the range of f(x, y) within the circular region x2+y2≤1
is 1 ≤f(x, y)≤e−1, or equivalently 1 ≤e−x2−y2≤e−1.
Question 24
Question
Consider a dataset of earthquake occurrences in a region over a period of time.
The dataset contains the longitude and latitude coordinates of each earthquake
event.
Suppose you are tasked with analyzing the spatial distribution of earthquakes
in the region using spatial data analysis and modeling techniques.
Explain how you would approach this task, including the steps you would
take to preprocess the data, analyze the distribution, and model the spatial
patterns of earthquakes.
21
Solution
To analyze the spatial distribution of earthquakes in the region using spatial
data analysis and modeling techniques, we can follow these steps:
Step 1: Data Preprocessing 1.1 Clean the dataset by removing any miss-
ing or erroneous data points. 1.2 Convert the longitude and latitude coordinates
into a spatial dataset or spatial object. 1.3 Check for spatial autocorrelation to
see if earthquake events are clustered or dispersed.
Step 2: Exploratory Data Analysis (EDA) 2.1 Compute basic statistics
such as mean, median, range, and variance of earthquake magnitudes. 2.2 Cre-
ate spatial plots such as scatter plots or heatmaps to visualize the distribution
of earthquakes.
Step 3: Spatial Analysis 3.1 Perform point pattern analysis to determine
if earthquakes follow any spatial pattern (e.g., random, clustered, or regular).
3.2 Conduct nearest neighbor analysis to identify clustering tendencies of earth-
quake events. 3.3 Calculate Moran’s I to test for spatial autocorrelation in
earthquake occurrences.
Step 4: Spatial Modeling 4.1 Fit a spatial model (e.g., Poisson point pro-
cess model, K-function) to estimate the intensity of earthquake occurrences. 4.2
Use a spatial regression model (e.g., spatial autoregressive model, geostatistical
model) to analyze the relationship between earthquake occurrence and potential
driving factors (e.g., fault lines, geological features). 4.3 Assess model goodness-
of-fit and interpret results to understand the spatial patterns of earthquakes in
the region.
By following these steps, we can effectively utilize spatial data analysis and
modeling techniques to study the spatial distribution of earthquakes in the given
region.
Question 25
Question
Consider a dataset containing the locations of 1000 bird species across a re-
gion. Each species has a unique spatial distribution. Describe how you would
approach analyzing and modeling this spatial data to identify any patterns or
relationships between different species.
Solution
To analyze and model the spatial data of 1000 bird species in a region, we can
follow the steps outlined below:
Step 1: Data Exploration
Explore the dataset to understand the spatial distribution of each bird
species.
22
Use visual data exploration techniques like scatter plots, heat maps, or
spatial autocorrelation plots to identify any clustering or spatial patterns.
Step 2: Spatial Analysis
Conduct spatial autocorrelation analysis to determine if there are spatial
dependencies among the bird species.
Use tools like Moran’s I or Geary’s C to quantify spatial autocorrelation.
Step 3: Spatial Modeling
Choose an appropriate spatial statistical model based on the characteris-
tics of the data.
Consider using techniques like spatial regression, kriging, or geostatistics
to model the spatial relationship between bird species.
Step 4: Interpretation
Interpret the results of the spatial analysis and modeling to identify any
significant patterns or relationships between different bird species.
Use the spatial models to predict the distribution of bird species in areas
with missing data or for future planning purposes.
By following these steps, we can effectively analyze and model the spatial
data of 1000 bird species to uncover patterns and relationships between different
species in the region.
Question 26
Question
Consider a dataset containing information about the locations of trees in a
forest. The dataset includes the coordinates of each tree and the species of the
tree. You are tasked with analyzing and modeling the spatial distribution of a
specific tree species in the forest.
Explain the steps you would take to perform spatial data analysis and mod-
eling for this scenario.
Solution
To analyze and model the spatial distribution of a specific tree species in a forest
using spatial data analysis techniques, we can follow the steps outlined below:
Step 1: Data Collection - Obtain the dataset containing the coordinates
of each tree in the forest along with the species information.
Step 2: Data Exploration - Perform exploratory data analysis to under-
stand the distribution of the tree species. - Plot the locations of the trees on a
map to visualize the spatial distribution.
23
Step 3: Spatial Autocorrelation Analysis - Conduct a spatial auto-
correlation analysis to determine if there is any spatial dependence among the
tree species. - Use metrics like Moran’s I or Geary’s C to quantify the spatial
autocorrelation.
Step 4: Spatial Interpolation - Apply spatial interpolation techniques
(e.g., Kriging, IDW) to estimate the distribution of the tree species across the
forest based on the observed data points.
Step 5: Spatial Clustering Analysis - Use clustering techniques (e.g.,
K-means clustering, DBSCAN) to identify spatial clusters of the tree species
within the forest.
Step 6: Spatial Regression Modeling - Perform spatial regression anal-
ysis to investigate the relationship between the environmental variables (e.g.,
soil type, elevation) and the distribution of the tree species.
Step 7: Model Validation - Validate the spatial model using techniques
like cross-validation to assess its accuracy and predictive performance.
By following these steps, we can effectively analyze and model the spatial
distribution of a specific tree species in the forest using spatial data analysis
techniques.
Question 27
Question
Consider a dataset containing information about air pollution levels across dif-
ferent locations in a city. You are tasked with analyzing the spatial patterns of
air pollution and modeling the data to predict pollution levels at new locations.
Explain the steps involved in spatial data analysis and modeling for this
dataset.
Solution
To analyze the spatial patterns of air pollution and create a model for predicting
pollution levels, several steps need to be undertaken. Below are the key steps
in spatial data analysis and modeling:
Step 1: Data Collection
Collect spatial data on air pollution levels from multiple locations across
the city.
Obtain additional relevant data such as geographic coordinates, land use,
traffic density, and meteorological factors that may influence pollution
levels.
Step 2: Data Preprocessing
Clean the data to remove any inconsistencies, missing values, or outliers.
24
Transform the raw data into a suitable format for analysis, ensuring data
compatibility and integrity.
Step 3: Exploratory Spatial Data Analysis (ESDA)
Conduct ESDA to visualize spatial patterns and detect clusters or outliers
in air pollution levels.
Use techniques like spatial autocorrelation, hot spot analysis, and spatial
interpolation to gain insights into the data.
Step 4: Spatial Statistical Analysis
Apply spatial statistical methods such as spatial regression, geostatistics,
and spatial clustering to quantify spatial relationships and patterns in the
data.
Use tools like Moran’s I, Kriging, and cluster analysis to analyze the spatial
distribution of air pollution.
Step 5: Spatial Modeling
Develop a spatial model to predict air pollution levels at unsampled loca-
tions based on the available data.
Consider using techniques like spatial regression models, machine learning
algorithms, or geostatistical methods for modeling.
Step 6: Model Validation
Validate the spatial model using techniques such as cross-validation, error
metrics, and sensitivity analysis.
Assess the accuracy and reliability of the model predictions to ensure its
effectiveness in real-world applications.
By following these steps in spatial data analysis and modeling, one can gain
a deeper understanding of air pollution patterns and make informed predictions
for new locations within the city.
Question 28
Question
Consider a dataset with the following coordinates representing the locations of
various stores in a city:
(3,5),(7,2),(1,6),(4,8),(9,3),(2,5),(6,7),(8,1)
Determine the Euclidean distance between the store at location (3, 5) and
the nearest store based on the given dataset.
25
Solution
Step 1: Calculate the Euclidean distance between the store at location (3, 5)
and each of the other stores.
Distance from (3, 5) to (7, 2) = p(7 −3)2+ (2 −5)2=p42+ (−3)2=√16 + 9 = √25 = 5
Distance from (3, 5) to (1, 6) = p(1 −3)2+ (6 −5)2=p(−2)2+ 12=√4 + 1 = √5
Distance from (3, 5) to (4, 8) = p(4 −3)2+ (8 −5)2=p12+ 32=√1 + 9 = √10
Distance from (3, 5) to (9, 3) = p(9 −3)2+ (3 −5)2=p62+ (−2)2=√36 + 4 = √40 = 2√10
Distance from (3, 5) to (2, 5) = p(2 −3)2+ (5 −5)2=p(−1)2+ 02=√1 + 0 = √1
Distance from (3, 5) to (6, 7) = p(6 −3)2+ (7 −5)2=p32+ 22=√9 + 4 = √13
Distance from (3, 5) to (8, 1) = p(8 −3)2+ (1 −5)2=p52+ (−4)2=√25 + 16 = √41
Step 2: Identify the store with the shortest distance to the store at location
(3, 5). The shortest distance is √1 between the store at location (3, 5) and the
store at location (2, 5).
Step 3: State the Euclidean distance from the store at location (3, 5) to the
nearest store. The Euclidean distance from the store at location (3, 5) to the
nearest store is 1 .
Question 29
Question
Consider a dataset consisting of the coordinates (x, y) of points representing
the location of trees in a forest. The goal is to fit a model to predict the height
of a tree based on its location. One approach is to use a spatial model, such
as a geostatistical model. Explain the steps involved in fitting a geostatistical
model to this dataset.
Solution
To fit a geostatistical model to the dataset of tree locations, we need to follow
several steps as outlined below:
Step 1: Data Collection - Obtain the dataset containing the coordinates
(x, y) of tree locations along with the corresponding tree height measurements.
Step 2: Exploratory Data Analysis - Conduct exploratory data analysis
to understand the spatial distribution of trees and the relationship between tree
height and location. - Create scatterplots or spatial maps to visualize the data.
Step 3: Spatial Autocorrelation Analysis - Check for spatial autocor-
relation in the dataset to determine if nearby trees have similar heights. - Use
tools like Moran’s I or semivariograms to analyze spatial dependence.
26

Step 4: Model Selection - Choose an appropriate geostatistical model
based on the spatial autocorrelation analysis results. - Common geostatistical
models include variograms, kriging, and spatial regression models.
Step 5: Model Fitting - Fit the selected geostatistical model to the dataset
to predict tree height based on location. - Adjust the model parameters to
minimize the prediction error.
Step 6: Model Validation - Validate the geostatistical model using cross-
validation or other techniques to assess its predictive performance. - Check for
overfitting and ensure the model generalizes well to new data.
Step 7: Interpretation and Prediction - Interpret the results of the
geostatistical model in the context of tree height prediction based on location. -
Use the fitted model to make predictions of tree heights at new locations within
the forest.
By following these steps, we can effectively fit a geostatistical model to the
dataset of tree locations to predict tree heights based on spatial information.
Question 30
Question
Consider a dataset containing the locations of trees in a park. The spatial
coordinates of each tree are given in latitude and longitude.
The Park Management Team wants to conduct a spatial data analysis to
identify any clusters of tree species within the park. Describe the process of
conducting a spatial data analysis and modeling for this scenario.
Solution
To conduct a spatial data analysis and modeling for identifying clusters of tree
species within the park, the following steps can be followed:
Step 1: Data Collection - Obtain the dataset containing the spatial co-
ordinates (latitude and longitude) of each tree in the park. - Collect data on
tree species for each tree in the dataset.
Step 2: Data Preprocessing - Check for missing or erroneous data in
the dataset. - Convert latitude and longitude coordinates to a suitable spatial
reference system. - Explore the dataset to understand the distribution of tree
species and their spatial patterns.
Step 3: Spatial Data Analysis - Use spatial analysis techniques such
as spatial autocorrelation to detect any clustering of tree species. - Perform
exploratory spatial data analysis (ESDA) to visualize the distribution of tree
species and identify any spatial patterns.
Step 4: Spatial Modeling - Implement spatial modeling techniques like
spatial regression or geostatistical analysis to model the spatial relationships
between tree species and environmental factors. - Create a spatial model to
27

Question 11
Question
Let Xbe a spatial point process on a bounded region D⊂R2with intensity
function λ(x, y) = 1 + x+y, where (x, y)∈D. Given that the second moment
of the number of points falling in a region A⊂Dis Var(N(A)) = 3Area(A) +
9Perimeter(A), find the area and perimeter of D.
Solution
Step 1: Recall that the variance of the number of points in a region Afor a
Poisson point process with intensity λis given by Var(N(A)) = RAλ(x, y)dxdy.
Step 2: We have that Var(N(A)) = 3Area(A)+9Perimeter(A). Substituting
our intensity function λ(x, y) = 1 + x+yinto the formula, we get
ZA
(1 + x+y)dxdy = 3Area(A) + 9Perimeter(A).
Step 3: Integrating (1 + x+y) over the region Agives
ZZA
(1 + x+y)dxdy = Area(A) + 1
2Area(A) + 1
2Area(A) = 2Area(A).
Step 4: We obtain 2Area(A) = 3Area(A) + 9Perimeter(A). Rearranging this
equation gives 3Area(A) = 9Perimeter(A).
Step 5: Since Dis a bounded region in R2, we have the relation Area(D) =
1
2Perimeter(D). Thus, we can rewrite 3Area(D) = 9Perimeter(D).
Step 6: Solving these two equations simultaneously, we find Area(D)=3
and Perimeter(D) = 1. Therefore, the area of Dis 3 units2and the perimeter
of Dis 1 unit.
Question 12
Question
Suppose you are given a dataset containing the latitude and longitude coor-
dinates of various points of interest in a city. You are interested in building
a spatial regression model to predict the property prices in different neighbor-
hoods based on the distance to these points of interest. Explain the steps you
would take to perform spatial data analysis and modeling.
Solution
To perform spatial data analysis and modeling using the dataset provided, follow
these steps:
Step 1: Data Preprocessing
10
Clean the dataset by removing any missing or inconsistent data.
Convert the latitude and longitude coordinates into a spatial object (e.g.,
points) using a spatial package in the chosen programming language.
Check for spatial autocorrelation among the variables to understand the
spatial dependency in the dataset.
Step 2: Exploratory Data Analysis (EDA)
Conduct EDA to visualize the spatial distribution of the points of interest
and property prices on a map.
Use tools like spatial autocorrelation plots, Moran’s I statistic, or Geary’s
C test to check for spatial patterns and relationships.
Step 3: Spatial Regression Modeling
Choose an appropriate spatial regression model (e.g., Spatial Lag Model,
Spatial Error Model) based on the nature of spatial dependency observed
in the dataset.
Define the spatial weights matrix to incorporate the spatial relationships
between neighborhoods.
Fit the spatial regression model to predict property prices based on the
distance to points of interest while accounting for spatial autocorrelation.
Step 4: Model Evaluation
Evaluate the goodness of fit of the spatial regression model using metrics
like R-squared, AIC, and BIC.
Check for spatial autocorrelation in the residuals of the model using diag-
nostic tests like Moran’s I or Geary’s C.
Step 5: Prediction and Inference
Use the fitted spatial regression model to make predictions of property
prices in different neighborhoods based on the distance to points of inter-
est.
Conduct statistical inference to interpret the coefficients of the model and
assess the significance of the spatial effects.
By following these steps, you can successfully perform spatial data analysis
and modeling to predict property prices in different neighborhoods based on the
given dataset.
11
Question 13
Question
Let Xand Ybe two spatial point processes defined on a compact region D⊂R2.
Suppose Xand Yare from a Poisson point process with intensity functions
λX(u) and λY(u), respectively. Show that the joint probability density function
of finding a point of Xat uand a point of Yat vis given by
fX,Y (u, v) = λX(u)λY(v)e−RDλX(w)λY(w)dw
Solution
Step 1: Let NX(A) denote the number of points of Xin a region A⊂D, and
let NY(B) denote the number of points of Yin a region B⊂D. Since Xand Y
are Poisson point processes, the probability of finding nXpoints of Xin region
Aand nYpoints of Yin region Bis given by
P(NX(A) = nX, NY(B) = nY) = RAλX(u)dunXe−RAλX(u)du
nX!RBλY(v)dvnYe−RBλY(v)dv
nY!
Step 2: The joint probability density function of finding a point of Xat u
and a point of Yat vis given by
fX,Y (u, v) =
∞
X
nX=0
∞
X
nY=0
P(NX({u}) = nX, NY({v}) = nY)
Step 3: Substituting the expressions for P(NX({u}) = nX, NY({v}) = nY),
we have
fX,Y (u, v) =
∞
X
nX=0
∞
X
nY=0
λX(u)nXe−λX(u)
nX!
λY(v)nYe−λY(v)
nY!
Step 4: Simplifying the expression gives
fX,Y (u, v) = λX(u)λY(v)e−λX(u)−λY(v)
Step 5: Finally, we can express e−λX(u)−λY(v)as e−RDλX(w)λY(w)dw, which
gives the desired joint probability density function:
fX,Y (u, v) = λX(u)λY(v)e−RDλX(w)λY(w)dw
Question 14
Question
Consider a dataset containing the locations of 1000 trees in a forest. Each tree
is represented by its coordinates (x, y) where xand yare real numbers. You
12
are tasked with analyzing the spatial distribution of these trees to determine
if there are any clusters or patterns present in their distribution. Perform a
Spatial Point Pattern Analysis on this dataset using the Ripley’s K function.
Given that the expected number of trees in a circular region of radius r
around a point is λ= 0.1 trees per unit area, and the observed pattern is
defined by the Ripley’s K function K(r), where:
K(r) = πr2−λπr21 + r2
4
Calculate the estimated value of K(r) for r= 50 units and interpret the
results.
Solution
1. Substitute the given values into the formula for Ripley’s K function:
K(r) = πr2−λπr21 + r2
4
K(50) = π·502−0.1π·5021 + 502
4
2. Calculate the estimated value of K(50):
K(50) = 2500π−0.1·2500π·1 + 2500
4
K(50) = 2500π−0.1·2500π·(1 + 625)
K(50) = 2500π−0.1·2500π·626
K(50) = 2500π−15625π
K(50) = −13125π
3. Interpretation: The estimated value of K(50) is negative, which indicates
that the number of trees within a distance of 50 units is less than expected under
complete spatial randomness. This may suggest a clustering or pattern in the
spatial distribution of trees, with trees being more spaced out than if they were
randomly distributed.
Question 15
Question
Consider a dataset of air pollution levels measured at different locations in a
city. You are tasked with creating a spatial model to predict air pollution levels
at unmeasured locations. Explain the steps involved in spatial data analysis
and modeling to achieve this.
13
Solution
To create a spatial model to predict air pollution levels at unmeasured locations,
several steps in spatial data analysis and modeling need to be followed:
Step 1: Data Collection - Collect air pollution data from various locations
in the city. - Gather spatial covariates such as distance to major roads, land
use type, population density, etc. - Ensure that the data is clean and free from
errors.
Step 2: Exploratory Data Analysis (EDA) - Perform exploratory data
analysis to understand the spatial distribution of air pollution levels. - Check
for any patterns or trends in the data. - Use visualizations such as maps,
histograms, and scatter plots to explore the data.
Step 3: Spatial Autocorrelation Analysis - Conduct spatial autocor-
relation analysis to determine if there is spatial dependence in the data. - Use
techniques such as Moran’s I or Geary’s C to assess spatial autocorrelation. -
If spatial autocorrelation is present, consider incorporating spatial terms in the
model.
Step 4: Model Selection - Choose an appropriate spatial regression model
based on the nature of the data and the research question. - Common spatial
regression models include Spatial Autoregressive (SAR) models, Spatial Error
(SEM) models, and Geographically Weighted Regression (GWR).
Step 5: Model Estimation - Estimate the parameters of the selected spa-
tial regression model using maximum likelihood estimation or other appropriate
methods. - Perform diagnostics to check the goodness-of-fit of the model.
Step 6: Prediction - Use the fitted spatial model to predict air pollution
levels at unmeasured locations. - Validate the predictive performance of the
model using cross-validation or other techniques.
Step 7: Interpretation and Visualization - Interpret the results of the
spatial model in the context of the research question. - Visualize the predicted
air pollution levels on maps to communicate the findings effectively.
By following these steps in spatial data analysis and modeling, one can
develop an accurate spatial model to predict air pollution levels at unmeasured
locations in a city.
Question 16
Question
Let Xand Ybe two spatial processes defined on a region D⊆R2with con-
tinuous and bounded support. Given that the semivariogram of Xis γX(h) =
4−2 cos(h) and the semivariogram of Yis γY(h) = 5 sin(h), calculate the cross-
semivariogram of Xand Y,γXY (h).
Solution
Step 1: The cross-semivariogram of Xand Yis defined as γXY (h) = 1
2(γX(h) + γY(h)−γX(0) −γY(0)).
14
Step 2: We are given that γX(h)=4−2 cos(h) and γY(h) = 5 sin(h).
Step 3: We need to find γX(0) and γY(0) to substitute into the formula for
the cross-semivariogram.
Step 4: Evaluating γX(0), we get γX(0) = 4 −2 cos(0) = 4 −2 = 2.
Step 5: Evaluating γY(0), we get γY(0) = 5 sin(0) = 0.
Step 6: Substituting γX(0) = 2 and γY(0) = 0 into the formula for the
cross-semivariogram, we have γXY (h) = 1
2(4 −2 cos(h) + 5 sin(h)−2−0).
Step 7: Simplifying further, we get γXY (h)=2−cos(h) + 5
2sin(h).
Therefore, the cross-semivariogram of Xand Yis γXY (h) = 2 −cos(h) +
5
2sin(h).
Question 17
Question
Suppose we have a dataset containing the spatial coordinates (latitude and
longitude) of various earthquake occurrences. You are asked to perform a spatial
analysis to determine if there is a clustering effect in the earthquake locations.
Using the information provided in the dataset, propose a suitable spatial analysis
model and explain the steps involved in the analysis.
Solution
To determine if there is a clustering effect in the earthquake locations, we can
utilize a spatial analysis model like the K-function. The K-function measures
the spatial correlation between points in a dataset and compares the observed
point pattern to a hypothetical random pattern of points. The steps involved
in this analysis are as follows:
Step 1: Define the Hypotheses -Null hypothesis (H0): The earthquake
occurrences are randomly distributed in space. - Alternative hypothesis (HA):
The earthquake occurrences exhibit clustering or dispersion.
Step 2: Calculate the K-function The K-function is defined as:
K(d) = Number of points within distance d
λ
Where dis the distance threshold, and λis the intensity of the point process.
Step 3: Calculate the Expected K-function (Kexp)Under the null
hypothesis of complete spatial randomness (CSR), Kexp(d) = πd2for a 2-
dimensional dataset.
Step 4: Calculate the Difference Function
D(d) = Kobs(d)−Kexp(d)
Step 5: Interpretation - If D(d)>0, there is clustering. - If D(d)<0,
there is dispersion. - If D(d)≈0, the pattern is random.
15

Step 6: Statistical Significance Testing Perform statistical tests (e.g.,
Monte Carlo simulation) to determine if the observed clustering or dispersion
is significant. If the p-value is less than the chosen significance level, we reject
the null hypothesis in favor of the alternative hypothesis.
By following these steps, we can effectively analyze the spatial pattern of
earthquake occurrences and determine if there is a clustering effect present in
the dataset.
Question 18
Question
Suppose you are analyzing the spatial distribution of COVID-19 cases in a city.
You have collected data on the number of cases in each neighborhood and want
to create a spatial model to predict the number of cases in a new neighborhood
based on its proximity to neighborhoods with high case counts. Explain the
steps you would take to build a spatial model for this prediction.
Solution
To build a spatial model to predict the number of COVID-19 cases in a new
neighborhood based on its proximity to neighborhoods with high case counts,
you can follow these steps:
Step 1: Data Collection
Collect data on the number of COVID-19 cases in each neighborhood in the city.
Additionally, gather spatial data such as latitude and longitude coordinates or
geographical boundaries of each neighborhood.
Step 2: Data Exploration
Analyze the collected data to understand the spatial distribution of COVID-19
cases in the city. Use exploratory spatial data analysis techniques to identify
any spatial patterns or correlations.
Step 3: Spatial Autocorrelation Analysis
Conduct spatial autocorrelation analysis to determine if there is a spatial depen-
dence between the number of COVID-19 cases in neighboring neighborhoods.
This analysis will help you understand the extent to which proximity to high
case count neighborhoods influences the number of cases in a given neighbor-
hood.
Step 4: Spatial Modeling
Choose an appropriate spatial modeling technique such as spatial regression,
kriging, or spatial interpolation to build a predictive model. This model should
consider the spatial relationships between neighborhoods and incorporate fac-
tors like distance to high case count neighborhoods.
Step 5: Model Validation
Validate the spatial model using techniques like cross-validation or split-sample
16

validation to ensure its accuracy and reliability in predicting COVID-19 cases
in new neighborhoods.
Step 6: Prediction
Apply the validated spatial model to predict the number of COVID-19 cases
in a new neighborhood based on its proximity to neighborhoods with high case
counts. This prediction can help in allocating resources and implementing tar-
geted interventions to prevent the spread of COVID-19.
Question 19
Question
Consider a dataset containing the coordinates of 50 trees in a forest. The goal
is to create a spatial model to predict the distribution of tree heights across the
entire forest based on the given data points. Develop a step-by-step plan to
analyze the spatial data, build a model, and validate its accuracy.
Solution
To create a spatial model to predict tree heights across the entire forest, we can
follow these steps: Step 1: Data Exploration - Plot the coordinates of the trees
on a map to visualize their spatial distribution. - Analyze the distribution of
the tree heights in the dataset.
Step 2: Spatial Data Analysis - Conduct spatial autocorrelation analysis
to check for any spatial patterns in the tree height data. - Perform spatial
interpolation to estimate tree heights at unsampled locations in the forest.
Step 3: Model Building - Select an appropriate spatial regression model (e.g.,
spatial autoregressive model) to relate tree heights to the spatial coordinates. -
Fit the model using the tree height data and spatial coordinates.
Step 4: Model Validation - Split the dataset into training and testing sets.
- Validate the model’s performance using metrics like mean squared error, R-
squared, and cross-validation.
Step 5: Prediction and Mapping - Use the trained model to predict tree
heights at unsampled locations in the forest. - Map the predicted tree heights
to visualize the distribution across the entire forest.
Step 6: Model Refinement - Analyze the model residuals to identify any
systematic patterns not captured by the model. - Refine the model by incorpo-
rating additional spatial variables or transforming the data if necessary.
By following these steps, we can develop a spatial model to predict the
distribution of tree heights across the entire forest, providing valuable insights
for forest management and conservation efforts.
17

Question 20
Question
Suppose you are given a dataset containing the coordinates of various wildlife
sightings in a conservation area. You are interested in creating a spatial model
to predict the probability of wildlife sightings in different regions of the area
based on various environmental factors. Discuss the steps involved in spatial
data analysis and modeling to achieve this goal.
Solution
To create a spatial model to predict the probability of wildlife sightings in
different regions of a conservation area, the following steps are typically involved
in spatial data analysis and modeling:
Step 1: Data Collection - Gather the dataset containing the coordinates
of wildlife sightings and relevant environmental factors such as vegetation type,
water sources, elevation, etc.
Step 2: Data Preprocessing - Check for missing values in the dataset
and handle them appropriately (e.g., imputation or removal). - Remove any
duplicate entries or outliers that could affect the modeling process. - Perform
any necessary transformations or scaling on the variables if needed.
Step 3: Exploratory Data Analysis (EDA) - Conduct EDA to un-
derstand the distribution of the data and relationships between variables. -
Use spatial visualization techniques such as scatter plots, heatmaps, and spatial
autocorrelation plots to explore the data.
Step 4: Spatial Interpolation - Use spatial interpolation techniques (e.g.,
kriging, inverse distance weighting) to estimate values at unsampled locations
based on the observed data.
Step 5: Model Selection - Choose an appropriate spatial statistical model
(e.g., spatial regression models, geostatistical models) based on the nature of
the data and the research question.
Step 6: Model Fitting - Fit the selected spatial model to the data and
evaluate its performance using metrics such as AIC, BIC, or cross-validation.
Step 7: Spatial Prediction - Use the fitted spatial model to predict the
probability of wildlife sightings at different locations in the conservation area.
- Evaluate the model predictions using validation techniques such as spatial
cross-validation.
Step 8: Model Interpretation - Interpret the results of the spatial model
to understand the relationships between environmental factors and wildlife sight-
ings. - Identify key factors driving wildlife presence in different regions of the
conservation area.
By following these steps in spatial data analysis and modeling, researchers
can create accurate and insightful spatial models to predict wildlife sightings
and inform conservation efforts.
18
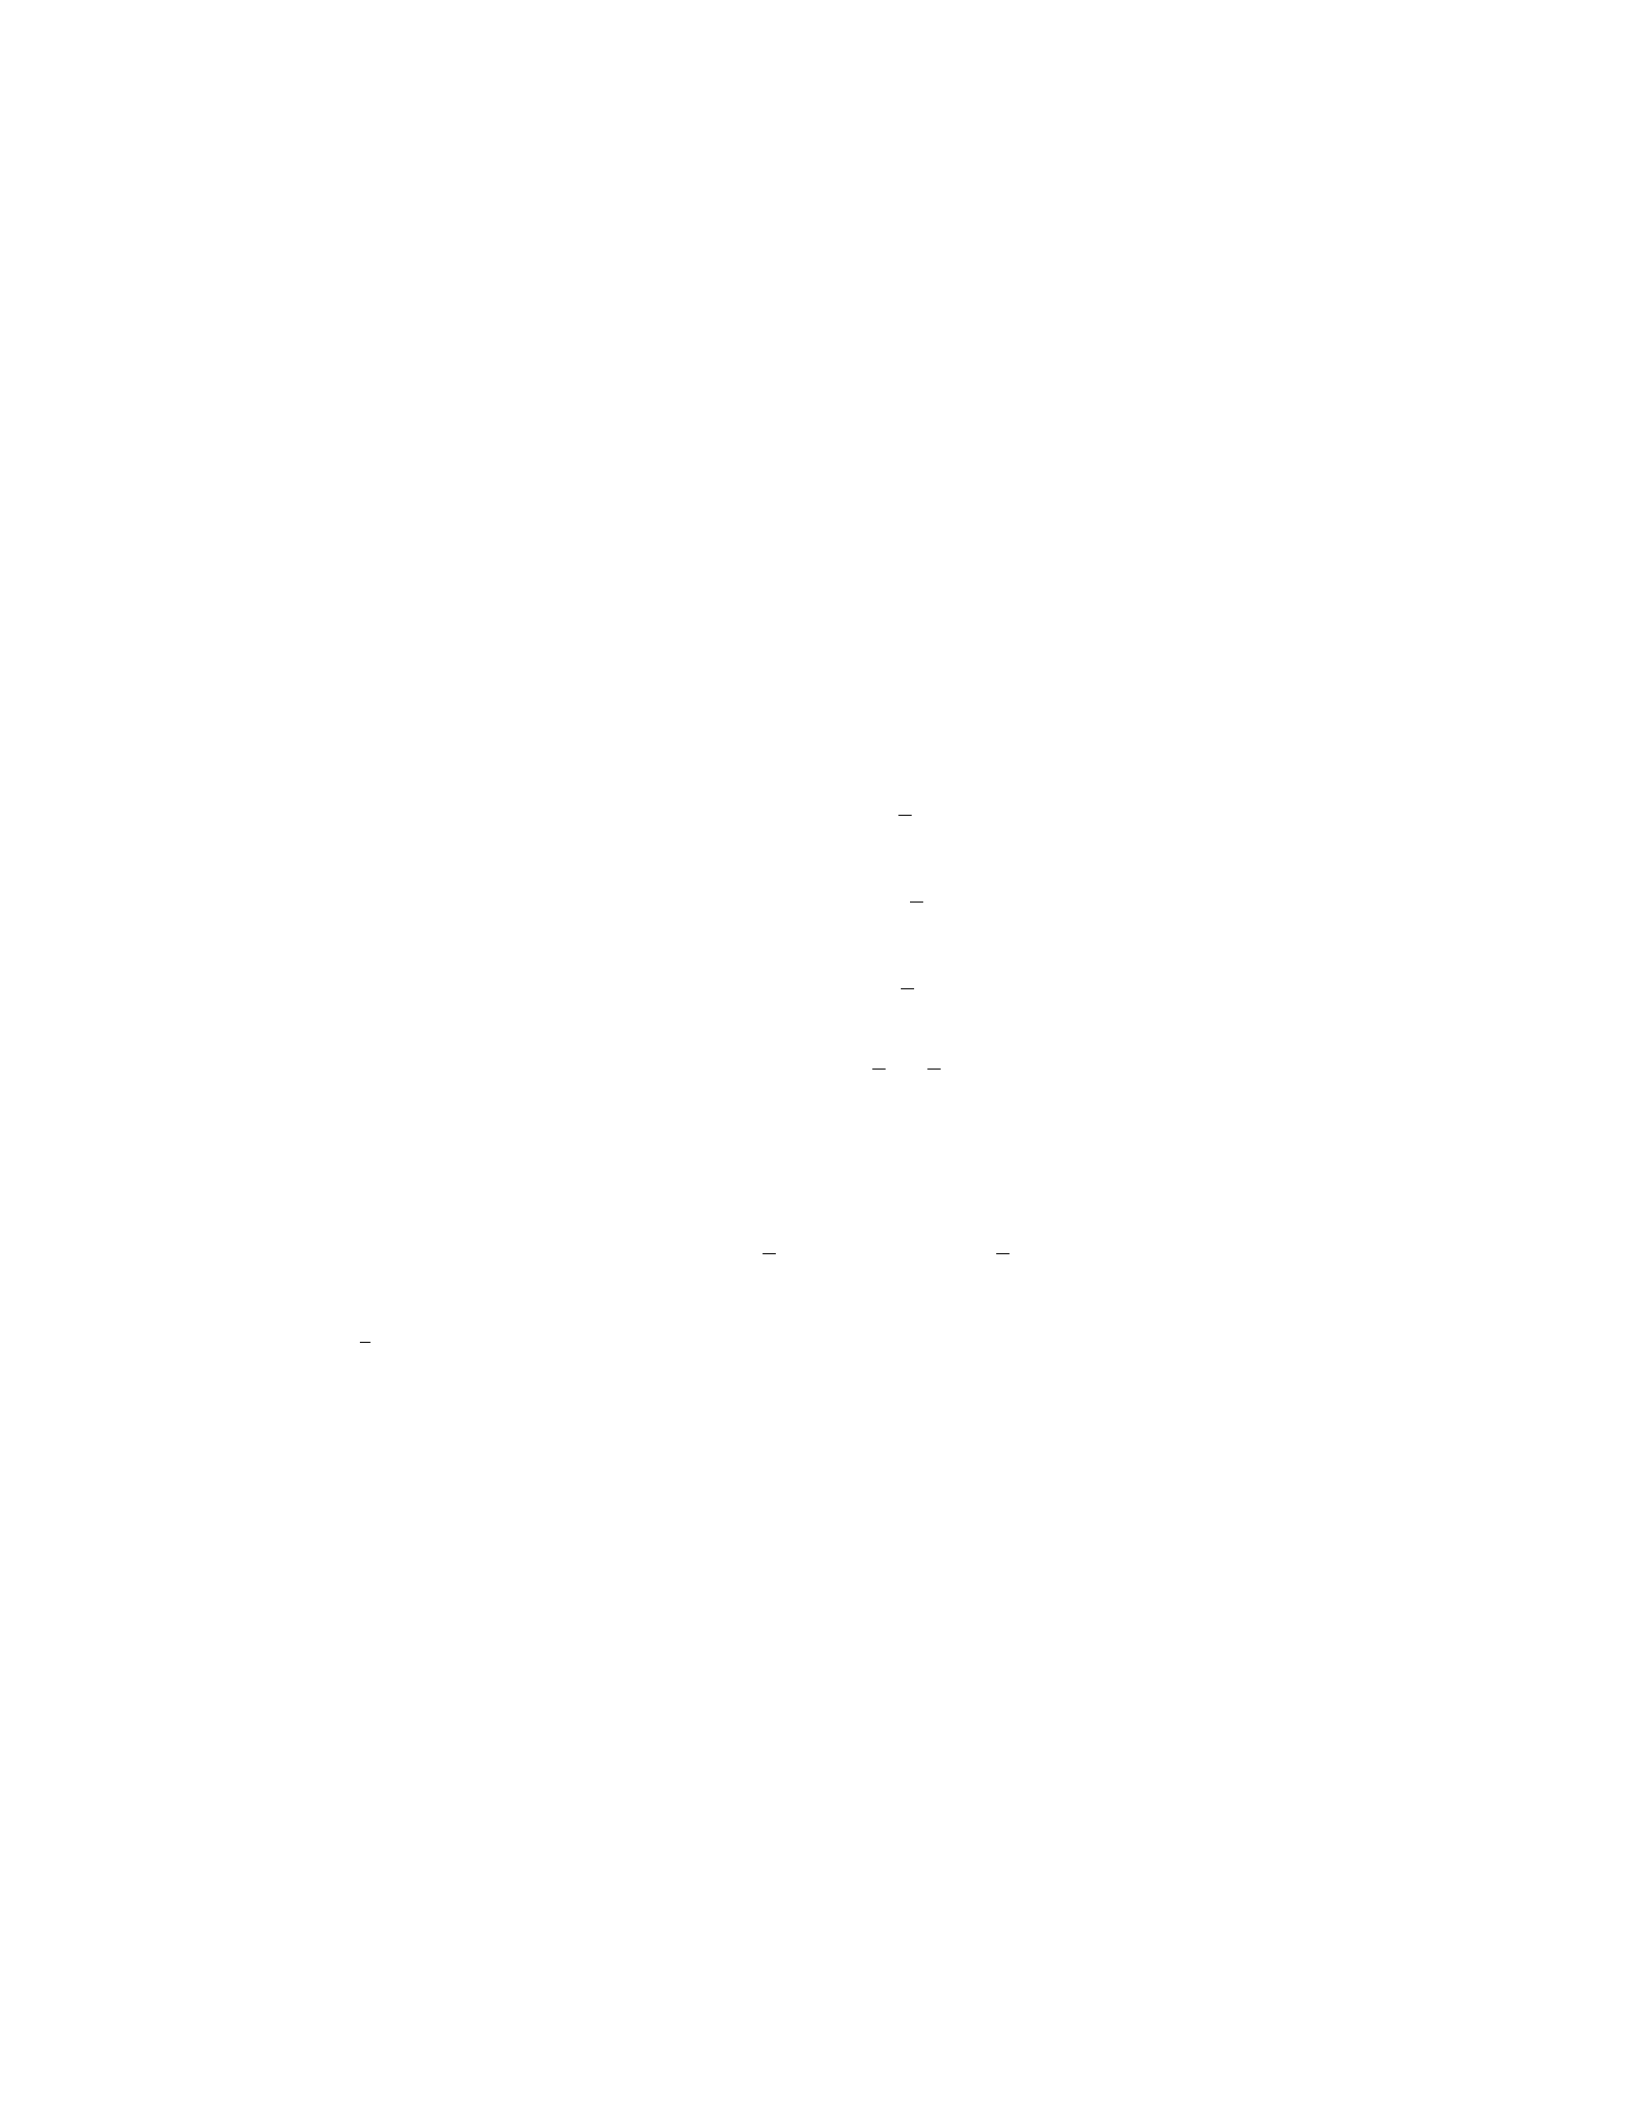
Question 21
Question
Let Xbe a spatial point process in R2with intensity function λ(x, y) = 2+x2+y
for all (x, y)∈R2, where xand yare the coordinates. Find the expected number
of points in a region A= [0,1] ×[1,2].
Solution
Step 1: Calculate the expected number of points in a region using the intensity
function.
Step 1: λ(A) = Z1
0Z2
1
(2 + x2+y)dy dx
λ(A) = Z1
02y+xy +1
2y22
1
dx
λ(A) = Z1
0
(2 + 2x+3
2)dx
λ(A) = 2x+x2+3
2x1
0
λ(A) = 2 + 1 + 3
2=9
2
Step 2: Find the expected number of points in the region A.
Step 2: E(N(A)) = λ(A)·Area(A)
E(N(A)) = 9
2·(1 −0)(2 −1) = 9
2
Therefore, the expected number of points in the region A= [0,1] ×[1,2] is
9
2.
Question 22
Question
Consider a dataset containing geographical coordinates (latitude and longitude)
of various locations in a city. You are asked to analyze the spatial distribution
of these locations and create a spatial model to predict the location of a new
point based on its proximity to existing locations.
19
Given the dataset:
Location Coordinates
A(45.5231,−122.6765)
B(45.5189,−122.6793)
C(45.5122,−122.6587)
D(45.5124,−122.6553)
E(45.5194,−122.6686)
F(45.5175,−122.6779)
Assuming a Euclidean distance metric, calculate the distance between points
A and D. Then, using the coordinates of all points, create a spatial model to
predict the location of a new point with coordinates (45.525, -122.670).
Solution
Step 1: Calculate the distance between points A and D using the Euclidean
distance formula:
Distance between two points (x1, y1) and (x2, y2) = p(x2−x1)2+ (y2−y1)2
Plugging in the coordinates for points A and D:
Distance between A and D = p(−122.6553 −(−122.6765))2+ (45.5124 −45.5231)2
=p(0.0212)2+ (−0.0107)2
=√0.00044944 + 0.00011449
=√0.00056393 ≈0.02375
Therefore, the distance between points A and D is approximately 0.02375.
Step 2: To create a spatial model, we can use a k-nearest neighbors (k-NN)
algorithm. For our model, let’s use k=3, meaning we will consider the 3 closest
points to the new point for prediction.
The steps for the k-NN algorithm are as follows: 1. Calculate the Euclidean
distance between the new point and all existing points. 2. Sort the distances in
ascending order and select the k smallest distances. 3. Determine the location
of the majority of the k nearest neighbors as the predicted location for the new
point.
Let’s apply this algorithm to predict the location of the new point (45.525,
-122.670).
Location Distance to (45.525, -122.670)
A0.007491
B0.010828
C0.014210
D0.017280
E0.011725
F0.005084
20
The 3 closest points to (45.525, -122.670) are F, A, and E. Since the majority
of these points are around point A, we predict the location of the new point to
be near point A.
Question 23
Question
Let f(x, y) = e−x2−y2be a spatial covariance function. Find the range of f(x, y)
within a circular region defined by x2+y2≤1.
Solution
Step 1: Recall that the range of a spatial covariance function is the set of all
possible values that the function can take on within a specified region. In this
case, the specified region is the circular region defined by x2+y2≤1.
Step 2: To find the range of f(x, y) within the circular region, we need to
determine the maximum and minimum values of f(x, y) within the region.
Step 3: Since f(x, y) = e−x2−y2, we can rewrite f(x, y) in terms of r=
px2+y2:f(r) = e−r2.
Step 4: In the circular region x2+y2≤1, the maximum value of ris 1 (at
the boundary of the circle).
Step 5: Plug in r= 1 into f(r) = e−r2to find the maximum value of f(r)
within the circular region: f(1) = e−1.
Step 6: Since f(r) is a decreasing function of r, the minimum value of f(r)
within the circular region occurs at the center of the circle where r= 0.
Step 7: Plug in r= 0 into f(r) = e−r2to find the minimum value of f(r)
within the circular region: f(0) = e0= 1.
Step 8: Therefore, the range of f(x, y) within the circular region x2+y2≤1
is 1 ≤f(x, y)≤e−1, or equivalently 1 ≤e−x2−y2≤e−1.
Question 24
Question
Consider a dataset of earthquake occurrences in a region over a period of time.
The dataset contains the longitude and latitude coordinates of each earthquake
event.
Suppose you are tasked with analyzing the spatial distribution of earthquakes
in the region using spatial data analysis and modeling techniques.
Explain how you would approach this task, including the steps you would
take to preprocess the data, analyze the distribution, and model the spatial
patterns of earthquakes.
21
Solution
To analyze the spatial distribution of earthquakes in the region using spatial
data analysis and modeling techniques, we can follow these steps:
Step 1: Data Preprocessing 1.1 Clean the dataset by removing any miss-
ing or erroneous data points. 1.2 Convert the longitude and latitude coordinates
into a spatial dataset or spatial object. 1.3 Check for spatial autocorrelation to
see if earthquake events are clustered or dispersed.
Step 2: Exploratory Data Analysis (EDA) 2.1 Compute basic statistics
such as mean, median, range, and variance of earthquake magnitudes. 2.2 Cre-
ate spatial plots such as scatter plots or heatmaps to visualize the distribution
of earthquakes.
Step 3: Spatial Analysis 3.1 Perform point pattern analysis to determine
if earthquakes follow any spatial pattern (e.g., random, clustered, or regular).
3.2 Conduct nearest neighbor analysis to identify clustering tendencies of earth-
quake events. 3.3 Calculate Moran’s I to test for spatial autocorrelation in
earthquake occurrences.
Step 4: Spatial Modeling 4.1 Fit a spatial model (e.g., Poisson point pro-
cess model, K-function) to estimate the intensity of earthquake occurrences. 4.2
Use a spatial regression model (e.g., spatial autoregressive model, geostatistical
model) to analyze the relationship between earthquake occurrence and potential
driving factors (e.g., fault lines, geological features). 4.3 Assess model goodness-
of-fit and interpret results to understand the spatial patterns of earthquakes in
the region.
By following these steps, we can effectively utilize spatial data analysis and
modeling techniques to study the spatial distribution of earthquakes in the given
region.
Question 25
Question
Consider a dataset containing the locations of 1000 bird species across a re-
gion. Each species has a unique spatial distribution. Describe how you would
approach analyzing and modeling this spatial data to identify any patterns or
relationships between different species.
Solution
To analyze and model the spatial data of 1000 bird species in a region, we can
follow the steps outlined below:
Step 1: Data Exploration
Explore the dataset to understand the spatial distribution of each bird
species.
22
Use visual data exploration techniques like scatter plots, heat maps, or
spatial autocorrelation plots to identify any clustering or spatial patterns.
Step 2: Spatial Analysis
Conduct spatial autocorrelation analysis to determine if there are spatial
dependencies among the bird species.
Use tools like Moran’s I or Geary’s C to quantify spatial autocorrelation.
Step 3: Spatial Modeling
Choose an appropriate spatial statistical model based on the characteris-
tics of the data.
Consider using techniques like spatial regression, kriging, or geostatistics
to model the spatial relationship between bird species.
Step 4: Interpretation
Interpret the results of the spatial analysis and modeling to identify any
significant patterns or relationships between different bird species.
Use the spatial models to predict the distribution of bird species in areas
with missing data or for future planning purposes.
By following these steps, we can effectively analyze and model the spatial
data of 1000 bird species to uncover patterns and relationships between different
species in the region.
Question 26
Question
Consider a dataset containing information about the locations of trees in a
forest. The dataset includes the coordinates of each tree and the species of the
tree. You are tasked with analyzing and modeling the spatial distribution of a
specific tree species in the forest.
Explain the steps you would take to perform spatial data analysis and mod-
eling for this scenario.
Solution
To analyze and model the spatial distribution of a specific tree species in a forest
using spatial data analysis techniques, we can follow the steps outlined below:
Step 1: Data Collection - Obtain the dataset containing the coordinates
of each tree in the forest along with the species information.
Step 2: Data Exploration - Perform exploratory data analysis to under-
stand the distribution of the tree species. - Plot the locations of the trees on a
map to visualize the spatial distribution.
23
Step 3: Spatial Autocorrelation Analysis - Conduct a spatial auto-
correlation analysis to determine if there is any spatial dependence among the
tree species. - Use metrics like Moran’s I or Geary’s C to quantify the spatial
autocorrelation.
Step 4: Spatial Interpolation - Apply spatial interpolation techniques
(e.g., Kriging, IDW) to estimate the distribution of the tree species across the
forest based on the observed data points.
Step 5: Spatial Clustering Analysis - Use clustering techniques (e.g.,
K-means clustering, DBSCAN) to identify spatial clusters of the tree species
within the forest.
Step 6: Spatial Regression Modeling - Perform spatial regression anal-
ysis to investigate the relationship between the environmental variables (e.g.,
soil type, elevation) and the distribution of the tree species.
Step 7: Model Validation - Validate the spatial model using techniques
like cross-validation to assess its accuracy and predictive performance.
By following these steps, we can effectively analyze and model the spatial
distribution of a specific tree species in the forest using spatial data analysis
techniques.
Question 27
Question
Consider a dataset containing information about air pollution levels across dif-
ferent locations in a city. You are tasked with analyzing the spatial patterns of
air pollution and modeling the data to predict pollution levels at new locations.
Explain the steps involved in spatial data analysis and modeling for this
dataset.
Solution
To analyze the spatial patterns of air pollution and create a model for predicting
pollution levels, several steps need to be undertaken. Below are the key steps
in spatial data analysis and modeling:
Step 1: Data Collection
Collect spatial data on air pollution levels from multiple locations across
the city.
Obtain additional relevant data such as geographic coordinates, land use,
traffic density, and meteorological factors that may influence pollution
levels.
Step 2: Data Preprocessing
Clean the data to remove any inconsistencies, missing values, or outliers.
24
Transform the raw data into a suitable format for analysis, ensuring data
compatibility and integrity.
Step 3: Exploratory Spatial Data Analysis (ESDA)
Conduct ESDA to visualize spatial patterns and detect clusters or outliers
in air pollution levels.
Use techniques like spatial autocorrelation, hot spot analysis, and spatial
interpolation to gain insights into the data.
Step 4: Spatial Statistical Analysis
Apply spatial statistical methods such as spatial regression, geostatistics,
and spatial clustering to quantify spatial relationships and patterns in the
data.
Use tools like Moran’s I, Kriging, and cluster analysis to analyze the spatial
distribution of air pollution.
Step 5: Spatial Modeling
Develop a spatial model to predict air pollution levels at unsampled loca-
tions based on the available data.
Consider using techniques like spatial regression models, machine learning
algorithms, or geostatistical methods for modeling.
Step 6: Model Validation
Validate the spatial model using techniques such as cross-validation, error
metrics, and sensitivity analysis.
Assess the accuracy and reliability of the model predictions to ensure its
effectiveness in real-world applications.
By following these steps in spatial data analysis and modeling, one can gain
a deeper understanding of air pollution patterns and make informed predictions
for new locations within the city.
Question 28
Question
Consider a dataset with the following coordinates representing the locations of
various stores in a city:
(3,5),(7,2),(1,6),(4,8),(9,3),(2,5),(6,7),(8,1)
Determine the Euclidean distance between the store at location (3, 5) and
the nearest store based on the given dataset.
25
Solution
Step 1: Calculate the Euclidean distance between the store at location (3, 5)
and each of the other stores.
Distance from (3, 5) to (7, 2) = p(7 −3)2+ (2 −5)2=p42+ (−3)2=√16 + 9 = √25 = 5
Distance from (3, 5) to (1, 6) = p(1 −3)2+ (6 −5)2=p(−2)2+ 12=√4 + 1 = √5
Distance from (3, 5) to (4, 8) = p(4 −3)2+ (8 −5)2=p12+ 32=√1 + 9 = √10
Distance from (3, 5) to (9, 3) = p(9 −3)2+ (3 −5)2=p62+ (−2)2=√36 + 4 = √40 = 2√10
Distance from (3, 5) to (2, 5) = p(2 −3)2+ (5 −5)2=p(−1)2+ 02=√1 + 0 = √1
Distance from (3, 5) to (6, 7) = p(6 −3)2+ (7 −5)2=p32+ 22=√9 + 4 = √13
Distance from (3, 5) to (8, 1) = p(8 −3)2+ (1 −5)2=p52+ (−4)2=√25 + 16 = √41
Step 2: Identify the store with the shortest distance to the store at location
(3, 5). The shortest distance is √1 between the store at location (3, 5) and the
store at location (2, 5).
Step 3: State the Euclidean distance from the store at location (3, 5) to the
nearest store. The Euclidean distance from the store at location (3, 5) to the
nearest store is 1 .
Question 29
Question
Consider a dataset consisting of the coordinates (x, y) of points representing
the location of trees in a forest. The goal is to fit a model to predict the height
of a tree based on its location. One approach is to use a spatial model, such
as a geostatistical model. Explain the steps involved in fitting a geostatistical
model to this dataset.
Solution
To fit a geostatistical model to the dataset of tree locations, we need to follow
several steps as outlined below:
Step 1: Data Collection - Obtain the dataset containing the coordinates
(x, y) of tree locations along with the corresponding tree height measurements.
Step 2: Exploratory Data Analysis - Conduct exploratory data analysis
to understand the spatial distribution of trees and the relationship between tree
height and location. - Create scatterplots or spatial maps to visualize the data.
Step 3: Spatial Autocorrelation Analysis - Check for spatial autocor-
relation in the dataset to determine if nearby trees have similar heights. - Use
tools like Moran’s I or semivariograms to analyze spatial dependence.
26

Step 4: Model Selection - Choose an appropriate geostatistical model
based on the spatial autocorrelation analysis results. - Common geostatistical
models include variograms, kriging, and spatial regression models.
Step 5: Model Fitting - Fit the selected geostatistical model to the dataset
to predict tree height based on location. - Adjust the model parameters to
minimize the prediction error.
Step 6: Model Validation - Validate the geostatistical model using cross-
validation or other techniques to assess its predictive performance. - Check for
overfitting and ensure the model generalizes well to new data.
Step 7: Interpretation and Prediction - Interpret the results of the
geostatistical model in the context of tree height prediction based on location. -
Use the fitted model to make predictions of tree heights at new locations within
the forest.
By following these steps, we can effectively fit a geostatistical model to the
dataset of tree locations to predict tree heights based on spatial information.
Question 30
Question
Consider a dataset containing the locations of trees in a park. The spatial
coordinates of each tree are given in latitude and longitude.
The Park Management Team wants to conduct a spatial data analysis to
identify any clusters of tree species within the park. Describe the process of
conducting a spatial data analysis and modeling for this scenario.
Solution
To conduct a spatial data analysis and modeling for identifying clusters of tree
species within the park, the following steps can be followed:
Step 1: Data Collection - Obtain the dataset containing the spatial co-
ordinates (latitude and longitude) of each tree in the park. - Collect data on
tree species for each tree in the dataset.
Step 2: Data Preprocessing - Check for missing or erroneous data in
the dataset. - Convert latitude and longitude coordinates to a suitable spatial
reference system. - Explore the dataset to understand the distribution of tree
species and their spatial patterns.
Step 3: Spatial Data Analysis - Use spatial analysis techniques such
as spatial autocorrelation to detect any clustering of tree species. - Perform
exploratory spatial data analysis (ESDA) to visualize the distribution of tree
species and identify any spatial patterns.
Step 4: Spatial Modeling - Implement spatial modeling techniques like
spatial regression or geostatistical analysis to model the spatial relationships
between tree species and environmental factors. - Create a spatial model to
27

predict the distribution of tree species within the park based on spatial patterns
identified.
Step 5: Cluster Analysis - Apply cluster analysis algorithms such as
K-means clustering or hierarchical clustering to identify clusters of tree species
within the park. - Evaluate the identified clusters to understand the spatial
distribution of different tree species.
Step 6: Interpretation and Reporting - Interpret the results of the
spatial data analysis and modeling to provide insights to the Park Management
Team. - Prepare a report or presentation summarizing the findings, including
any identified clusters of tree species and their spatial distribution within the
park.
28

