


ENVR 370 - GEOGRAPHIC
INFORMATION SYSTEMS (GIS) -
Spatial data analysis and modeling
Question Bank - Set 1
Liberty University
Question 1
Question
Let Z(s) = Y(s) + X(s), where Y(s) and X(s) are random processes with the
following properties: 1. Y(s) is a stationary process with variance Var[Y(s)] = 4
and covariance function CY(h) = 3 exp(−0.5|h|). 2. X(s) is a stationary process
with variance Var[X(s)] = 1 and covariance function CX(h) = 5 exp(−|h|).
Determine the variance and covariance function for Z(s).
Solution
Step 1: Variance of Z(s)
The variance of Z(s) can be found using the formula:
Var[Z(s)] = Var[Y(s) + X(s)] = Var[Y(s)] + Var[X(s)] + 2Cov[Y(s), X(s)]
Given that Var[Y(s)] = 4, Var[X(s)] = 1, and Cov[Y(s), X(s)] = CY X (h),
we can rewrite the formula as:
Var[Z(s)] = 4 + 1 + 2CY X (h)
Step 2: Covariance function of Z(s)
The covariance function of Z(s) can be found as follows:
CZ(h) = Cov[Z(s), Z(s+h)] = Cov[Y(s) + X(s), Y (s+h) + X(s+h)]
= Cov[Y(s), Y (s+h)]+Cov[Y(s), X(s+h)]+Cov[X(s), Y (s+h)]+Cov[X(s), X(s+h)]
Given the properties of Y(s) and X(s), we can substitute their covariance
functions into the formula and simplify to find CZ(h).

Question 2
Question
Consider a dataset containing the spatial coordinates (latitude and longitude)
of 100 different locations. You are tasked with analyzing this spatial data to
identify any spatial patterns or clusters. Discuss the steps you would take to
analyze this dataset using spatial data analysis and modeling techniques.
Solution
To analyze the spatial dataset containing the coordinates of 100 locations, we
can follow these steps: Step 1: Data Preparation Step 2: Exploratory Spatial
Data Analysis (ESDA) Step 3: Spatial Autocorrelation Analysis Step 4: Spatial
Clustering Analysis Step 5: Spatial Interpolation
Step 1: Data Preparation 1.1 Convert latitude and longitude coordinates
to a spatial object (e.g., points). 1.2 Check for missing or inconsistent data and
address them accordingly. 1.3 Define the spatial extent and projection of the
dataset.
Step 2: Exploratory Spatial Data Analysis (ESDA) 2.1 Calculate
the spatial weights matrix to define spatial relationships. 2.2 Calculate basic
descriptive statistics of the dataset including mean center, standard distance,
etc. 2.3 Create spatial plots (e.g., scatterplots, histograms) to visualize the
spatial distribution.
Step 3: Spatial Autocorrelation Analysis 3.1 Calculate spatial auto-
correlation measures (e.g., Moran’s I, Geary’s C) to assess spatial dependency.
3.2 Evaluate the significance of spatial autocorrelation measures.
Step 4: Spatial Clustering Analysis 4.1 Perform spatial clustering al-
gorithms (e.g., K-means, DBSCAN) to identify spatial patterns or clusters. 4.2
Evaluate the quality of spatial clusters using cluster validity indices.
Step 5: Spatial Interpolation 5.1 Apply spatial interpolation techniques
(e.g., kriging, IDW) to predict values at unsampled locations. 5.2 Validate the
accuracy of the interpolated values using cross-validation techniques.
By following these steps, we can effectively analyze the spatial dataset to
identify any spatial patterns or clusters present in the data.
Question 3
Question
Assume you have a dataset containing the locations of different tree species in
a forest. You want to analyze the spatial pattern of these tree species to better
understand their distribution. Describe the steps you would take to conduct a
spatial data analysis and modeling of this dataset.
2
Solution
To conduct a spatial data analysis and modeling of the dataset containing the
locations of different tree species in a forest, you can follow the steps outlined
below:
Step 1: Data Preprocessing
Remove any duplicate or irrelevant data points.
Check for and handle missing values in the dataset.
Step 2: Exploratory Spatial Data Analysis (ESDA)
Calculate basic statistics such as mean, median, and range of tree species
distributions.
Plot the locations of different tree species on a map to visualize spatial
patterns.
Use tools like Moran’s I and Geary’s C to assess spatial autocorrelation.
Step 3: Spatial Data Modeling
Choose an appropriate spatial data model based on the dataset charac-
teristics (e.g., point pattern analysis, spatial regression).
Implement the selected model to analyze the spatial relationships between
different tree species.
Step 4: Model Validation
Validate the spatial data model using techniques like cross-validation or
goodness-of-fit tests.
Check the residuals for any patterns or anomalies.
Step 5: Interpretation and Reporting
Interpret the results of the spatial data analysis in the context of the
research question.
Prepare a report summarizing the findings and recommendations based
on the analysis.
Question 4
Question
A city planner is interested in analyzing the spatial distribution of air pollution
levels in a particular city. She collects air quality data from 100 monitoring
stations located throughout the city. Using spatial data analysis techniques, she
wants to create a model that predicts air pollution levels at locations without
monitoring stations based on the data collected.
Describe the steps she should take to analyze the spatial data and create a
predictive model for air pollution levels in the city.
3

Solution
To analyze the spatial data and create a predictive model for air pollution levels
in the city, the city planner should follow these steps:
Step 1: Data Exploration - Examine the distribution of air pollution
levels at monitoring stations. - Check for any spatial patterns in the data. -
Determine if there are any outliers or missing values.
Step 2: Spatial Autocorrelation Analysis - Conduct a spatial autocor-
relation analysis to determine if air pollution levels exhibit spatial dependence.
- Use tools like Moran’s I or Geary’s C to assess spatial autocorrelation.
Step 3: Spatial Interpolation - Use spatial interpolation techniques (e.g.,
kriging, inverse distance weighting) to predict air pollution levels at locations
without monitoring stations. - Validate the interpolation results using cross-
validation techniques.
Step 4: Model Building - Select appropriate predictors (e.g., land use,
traffic density) that may influence air pollution levels. - Use regression analysis
or machine learning algorithms to build a predictive model for air pollution
levels. - Evaluate the model’s performance using metrics like R-squared, Mean
Squared Error (MSE), and Root Mean Squared Error (RMSE).
Step 5: Model Validation - Validate the predictive model using tech-
niques like cross-validation to assess its accuracy and generalizability. - Make
adjustments to the model if necessary based on validation results.
Step 6: Spatial Visualization - Create spatial visualizations (e.g., maps,
heatmaps) to present the predicted air pollution levels across the city. - Identify
areas with high pollution levels for targeted interventions or policy recommen-
dations.
Question 5
Question
A city planner is analyzing traffic flow in a city and has collected spatial data
on traffic congestion at various locations. The dataset includes the geographical
coordinates of each location and the level of congestion (ranging from 1 to 10)
at each location. The planner wants to create a spatial model to predict traffic
congestion levels at new locations based on the existing data. Explain how
spatial autocorrelation and spatial regression could be used in this scenario.
Solution
Step 1: Spatial Autocorrelation Spatial autocorrelation refers to the degree
to which nearby locations in space are similar to each other regarding a certain
attribute. In this scenario, spatial autocorrelation can be used to identify if there
is a pattern in the traffic congestion levels that is related to the spatial locations.
This can help the city planner determine if there are clusters of locations with
4

similar congestion levels, which can be useful for predicting congestion at new
locations based on their proximity to existing congested areas.
Step 2: Spatial Regression Spatial regression is a statistical technique that
explicitly considers the spatial relationships between observations. In the con-
text of traffic congestion analysis, spatial regression can be employed to model
the relationship between traffic congestion levels and spatial factors such as prox-
imity to highways, population density, or commercial areas. By incorporating
spatial information into the regression model, the planner can better account for
spatial dependencies in the data and improve the accuracy of congestion level
predictions at new locations.
In summary, by using spatial autocorrelation to identify spatial patterns in
traffic congestion data and employing spatial regression to model the relation-
ship between congestion levels and spatial factors, the city planner can create
a robust spatial model for predicting traffic congestion at new locations in the
city.
Question 6
Question
Consider a dataset containing locations of 100 different trees in a forest. Each
tree is characterized by its species, height, diameter, and age. Perform a spatial
data analysis and modeling to determine if there is a spatial pattern in the
distribution of tree species in the forest.
Solution
To determine if there is a spatial pattern in the distribution of tree species in
the forest, we can perform spatial data analysis using Ripley’s K-function. The
steps to accomplish this are as follows:
Step 1: Define the Problem We want to investigate if the distribution
of tree species in the forest exhibits any spatial pattern. Specifically, we want
to determine if the spatial distribution is random, clustered, or dispersed.
Step 2: Data Preparation Prepare the dataset containing the locations
of the trees along with their respective species information. Ensure that the
data is clean and ready for spatial analysis.
Step 3: Calculate Ripley’s K-function Calculate Ripley’s K-function for
each tree species in the dataset. The Ripley’s K-function measures the spatial
clustering or dispersion of points in a given area.
Step 4: Compare Observed vs. Expected K-function Plot the ob-
served K-function against the expected K-function under a complete spatial
randomness (CSR) assumption. If the observed K-function is higher than the
expected function, it indicates clustering. If it is lower, it indicates dispersion.
Step 5: Statistical Analysis Perform a statistical test to determine the
significance of the spatial pattern observed. This can be done using Monte Carlo
5
simulation or other appropriate methods.
Step 6: Interpret Results Based on the analysis and statistical tests
conducted, make conclusions about the presence and nature of spatial patterns
in the distribution of tree species in the forest.
By following these steps, we can effectively analyze the spatial distribution
of tree species in the forest and determine if there is a significant spatial pattern
present.
Question 7
Question
Consider a dataset containing information about the elevation of different loca-
tions in a region. The dataset consists of 1000 data points, each representing a
specific location in the region with its corresponding elevation in meters. You
are tasked with analyzing and modeling the spatial variation in elevation across
the region using statistical methods.
Perform the following steps: 1. Create a spatial plot of the elevation data
points to visualize the spatial distribution. 2. Compute the sample mean and
sample standard deviation of the elevation values. 3. Perform spatial autocor-
relation analysis to determine if there is any spatial dependence in the elevation
data. 4. Fit a spatial regression model to predict elevation based on the coor-
dinates (latitude and longitude) of the locations. 5. Evaluate the goodness of
fit of the spatial regression model and interpret the results.
Solution
1. Create a spatial plot of the elevation data points to visualize the spatial
distribution.
Use a software package like R or Python with appropriate libraries to
create a scatter plot of the elevation data points on a map of the region.
Color code the data points based on their elevation values to visualize the
spatial distribution.
Ensure the axes represent latitude and longitude coordinates.
2. Compute the sample mean and sample standard deviation of the elevation
values.
Calculate the sample mean using the formula: ¯x=1
nPn
i=1 xi, where xi
represents individual elevation values.
Calculate the sample standard deviation using the formula: s=q1
n−1Pn
i=1(xi−¯x)2.
3. Perform spatial autocorrelation analysis to determine if there is any spa-
tial dependence in the elevation data.
6
Use Moran’s I statistic to measure spatial autocorrelation.
Calculate Moran’s I using the formula: I=n
Pn
i=1 Pn
j=1 wij (xi−¯x)(xj−¯x)/Pn
i=1(xi−¯x)2,
where wij is the spatial weight between locations iand j.
Interpret the Moran’s I value to determine the presence and strength of
spatial autocorrelation.
4. Fit a spatial regression model to predict elevation based on the coordinates
(latitude and longitude) of the locations.
Use spatial regression techniques like spatial lag or spatial error models.
Specify a suitable spatial weight matrix based on the spatial relationships
between locations.
Fit the spatial regression model and examine the coefficients of latitude
and longitude to assess their impact on elevation.
5. Evaluate the goodness of fit of the spatial regression model and interpret
the results.
Use metrics such as R-squared, AIC, BIC to evaluate the model fit.
Analyze the residuals to check for any patterns or spatial autocorrelation.
Interpret the coefficients of the spatial regression model and assess the
significance of predictors.
Question 8
Question
Suppose you are given a dataset containing spatial coordinates (longitude and
latitude) of 100 different locations. The dataset also includes a variable repre-
senting the elevation at each location. You are asked to build a spatial model
to predict the elevation at a new, previously unobserved location. Describe the
steps you would take to build such a model.
Solution
To build a spatial model for predicting the elevation at a new location, we can
follow these steps:
Step 1: Exploratory Data Analysis - Begin by exploring the dataset to
understand the distribution of elevation values and the spatial patterns present.
- Plot the elevation values on a map to visualize any spatial trends or patterns.
- Check for any outliers or missing data that may need to be addressed.
Step 2: Spatial Autocorrelation Analysis - Conduct a spatial autocor-
relation analysis to determine if the elevation values exhibit spatial dependence.
7

- Use spatial autocorrelation measures like Moran’s I or Geary’s C to quantify
the level of spatial autocorrelation.
Step 3: Spatial Interpolation - Choose an appropriate spatial interpo-
lation method to predict elevation values at unsampled locations. - Common
interpolation methods include Kriging, Inverse Distance Weighting, and Spline
Interpolation. - Evaluate the chosen interpolation method by cross-validation
or comparing predicted values to observed values.
Step 4: Model Building - Select a suitable statistical model to predict
elevation values based on spatial coordinates. - Consider models such as spatial
regression models or machine learning algorithms that can incorporate spatial
dependencies. - Use techniques like cross-validation to assess the model’s per-
formance and ensure it generalizes well to new locations.
Step 5: Model Validation - Validate the spatial model using independent
validation datasets or techniques like cross-validation. - Evaluate the model’s
predictive performance by comparing predicted elevation values to observed
values at new locations. - Assess the model’s accuracy, precision, and robustness
to ensure it provides reliable predictions.
By following these steps, you can build a spatial model to predict elevation
values at new, previously unobserved locations based on the available dataset
of spatial coordinates and elevation values.
Question 9
Question
Suppose you are given a dataset containing the coordinates of 100 random points
in a two-dimensional space. The dataset also includes a binary variable indi-
cating whether each point belongs to a certain region of interest or not. You
are tasked with building a model to predict whether a new point with given
coordinates belongs to the region of interest. Describe the steps you would take
to create and validate this model.
Solution
To build and validate a model for predicting whether a new point belongs to
the region of interest, we can follow the steps below:
Step 1: Data Preparation - Split the given dataset into a training set (typ-
ically 70-80- Standardize or normalize the coordinates of the points if needed. -
Review the dataset to check for any missing values or outliers and handle them
appropriately.
Step 2: Feature Selection - Identify relevant features that can help predict
whether a point belongs to the region of interest. This may include distance-
based features, clustering information, or spatial trends.
Step 3: Model Selection - Choose an appropriate spatial data model for
the prediction task. This could include models like k-Nearest Neighbors, Sup-
8

port Vector Machines, Decision Trees, Random Forest, etc. - Consider if any
specialized spatial analysis libraries are needed for the chosen model.
Step 4: Model Training - Train the selected model using the training set.
Fit the model to the training data to learn the relationships between the features
and the binary variable indicating region of interest.
Step 5: Model Evaluation - Use the testing set to evaluate the perfor-
mance of the trained model. Common evaluation metrics for classification tasks
include accuracy, precision, recall, F1 score, and confusion matrix. - Check for
overfitting by comparing the model performance on the training set and the
testing set.
Step 6: Model Tuning - If the model performance is not satisfactory,
consider tuning hyperparameters or modifying the feature set to improve the
model’s predictive power. - Use techniques like cross-validation to fine-tune the
model.
Step 7: Model Deployment - Once satisfied with the model’s performance,
deploy it to predict whether new points belong to the region of interest based
on their coordinates.
By following these steps, you can create and validate a model for predicting
whether a new point belongs to a specific region of interest based on spatial
data analysis and modeling.
Question 10
Question
Consider a dataset consisting of the elevation measurements at various locations
on a mountain. The dataset contains the elevation values (in meters) and the
corresponding x and y coordinates (in kilometers) of the measurement locations.
Given the dataset, perform the following steps: 1. Fit a spatial trend model
to the data using a second-order polynomial regression with interaction terms. 2.
Evaluate the goodness of fit of the model by calculating the R-squared value. 3.
Use the fitted model to predict the elevation at a new location with x-coordinate
2.5 km and y-coordinate 3.5 km.
(Note: Assume that the data satisfies the assumptions of the spatial trend
model.)
Solution
1. Fit a spatial trend model to the data using a second-order polynomial re-
gression with interaction terms. Let Zbe the elevation, and Xand Ybe the x
and y coordinates, respectively. The second-order polynomial regression model
with interaction terms is given by:
Z=β0+β1X+β2Y+β3X2+β4Y2+β5XY
2. Evaluate the goodness of fit of the model by calculating the R-squared
value. The R-squared value, denoted as R2, measures the proportion of the
9
variance in the dependent variable (elevation) that is predictable from the in-
dependent variables (coordinates). It is calculated as:
R2= 1 −SSresiduals
SStotal
where SSresiduals is the sum of squared residuals and SStotal is the total sum of
squares.
3. Use the fitted model to predict the elevation at a new location with x-
coordinate 2.5 km and y-coordinate 3.5 km. Substitute the values X= 2.5 km
and Y= 3.5 km into the fitted model to obtain the predicted elevation at the
new location.
This process provides a comprehensive analysis of the spatial data by fitting
a spatial trend model, evaluating its goodness of fit, and making predictions at
new locations based on the model.
Question 11
Question
A city planner is analyzing traffic patterns in a large metropolitan area. The
planner collects spatial data on traffic volume at various intersections and wants
to model the relationship between traffic volume and several predictor variables
such as population density, distance to major highways, and proximity to public
transportation hubs.
Describe how the city planner can perform spatial data analysis and model-
ing to achieve this goal.
Solution
To model the relationship between traffic volume and predictor variables in a
spatial context, the city planner can follow these steps for spatial data analysis
and modeling:
Step 1: Data Collection
Collect spatial data on traffic volume at intersections, population density,
distance to major highways, and proximity to public transportation hubs.
Ensure that the data is accurate, relevant, and covers the entire study
area.
Step 2: Data Preprocessing
Clean the collected data to remove any errors or inconsistencies.
Convert the data into a suitable format for spatial analysis (e.g., shapefiles,
geodatabases).
Step 3: Exploratory Spatial Data Analysis (ESDA)
10
Conduct exploratory spatial data analysis to identify spatial patterns and
relationships between variables.
Use tools such as Moran’s I, spatial autocorrelation, and spatial lag to
assess spatial dependencies.
Step 4: Spatial Regression Modeling
Perform spatial regression analysis to model the relationship between traf-
fic volume and predictor variables.
Choose an appropriate spatial regression model such as spatial lag model
or spatial error model.
Step 5: Model Evaluation
Evaluate the goodness of fit of the spatial regression model using metrics
like R-squared, AIC, and BIC.
Perform diagnostics to check for issues such as spatial autocorrelation,
multicollinearity, and heteroscedasticity.
Step 6: Interpretation and Visualization
Interpret the coefficients of the spatial regression model to understand the
relationship between traffic volume and predictor variables.
Visualize the results using maps, charts, and plots to communicate findings
effectively.
By following these steps, the city planner can effectively analyze traffic pat-
terns in the metropolitan area and create a spatial model that can inform future
transportation planning decisions.
Question 12
Question
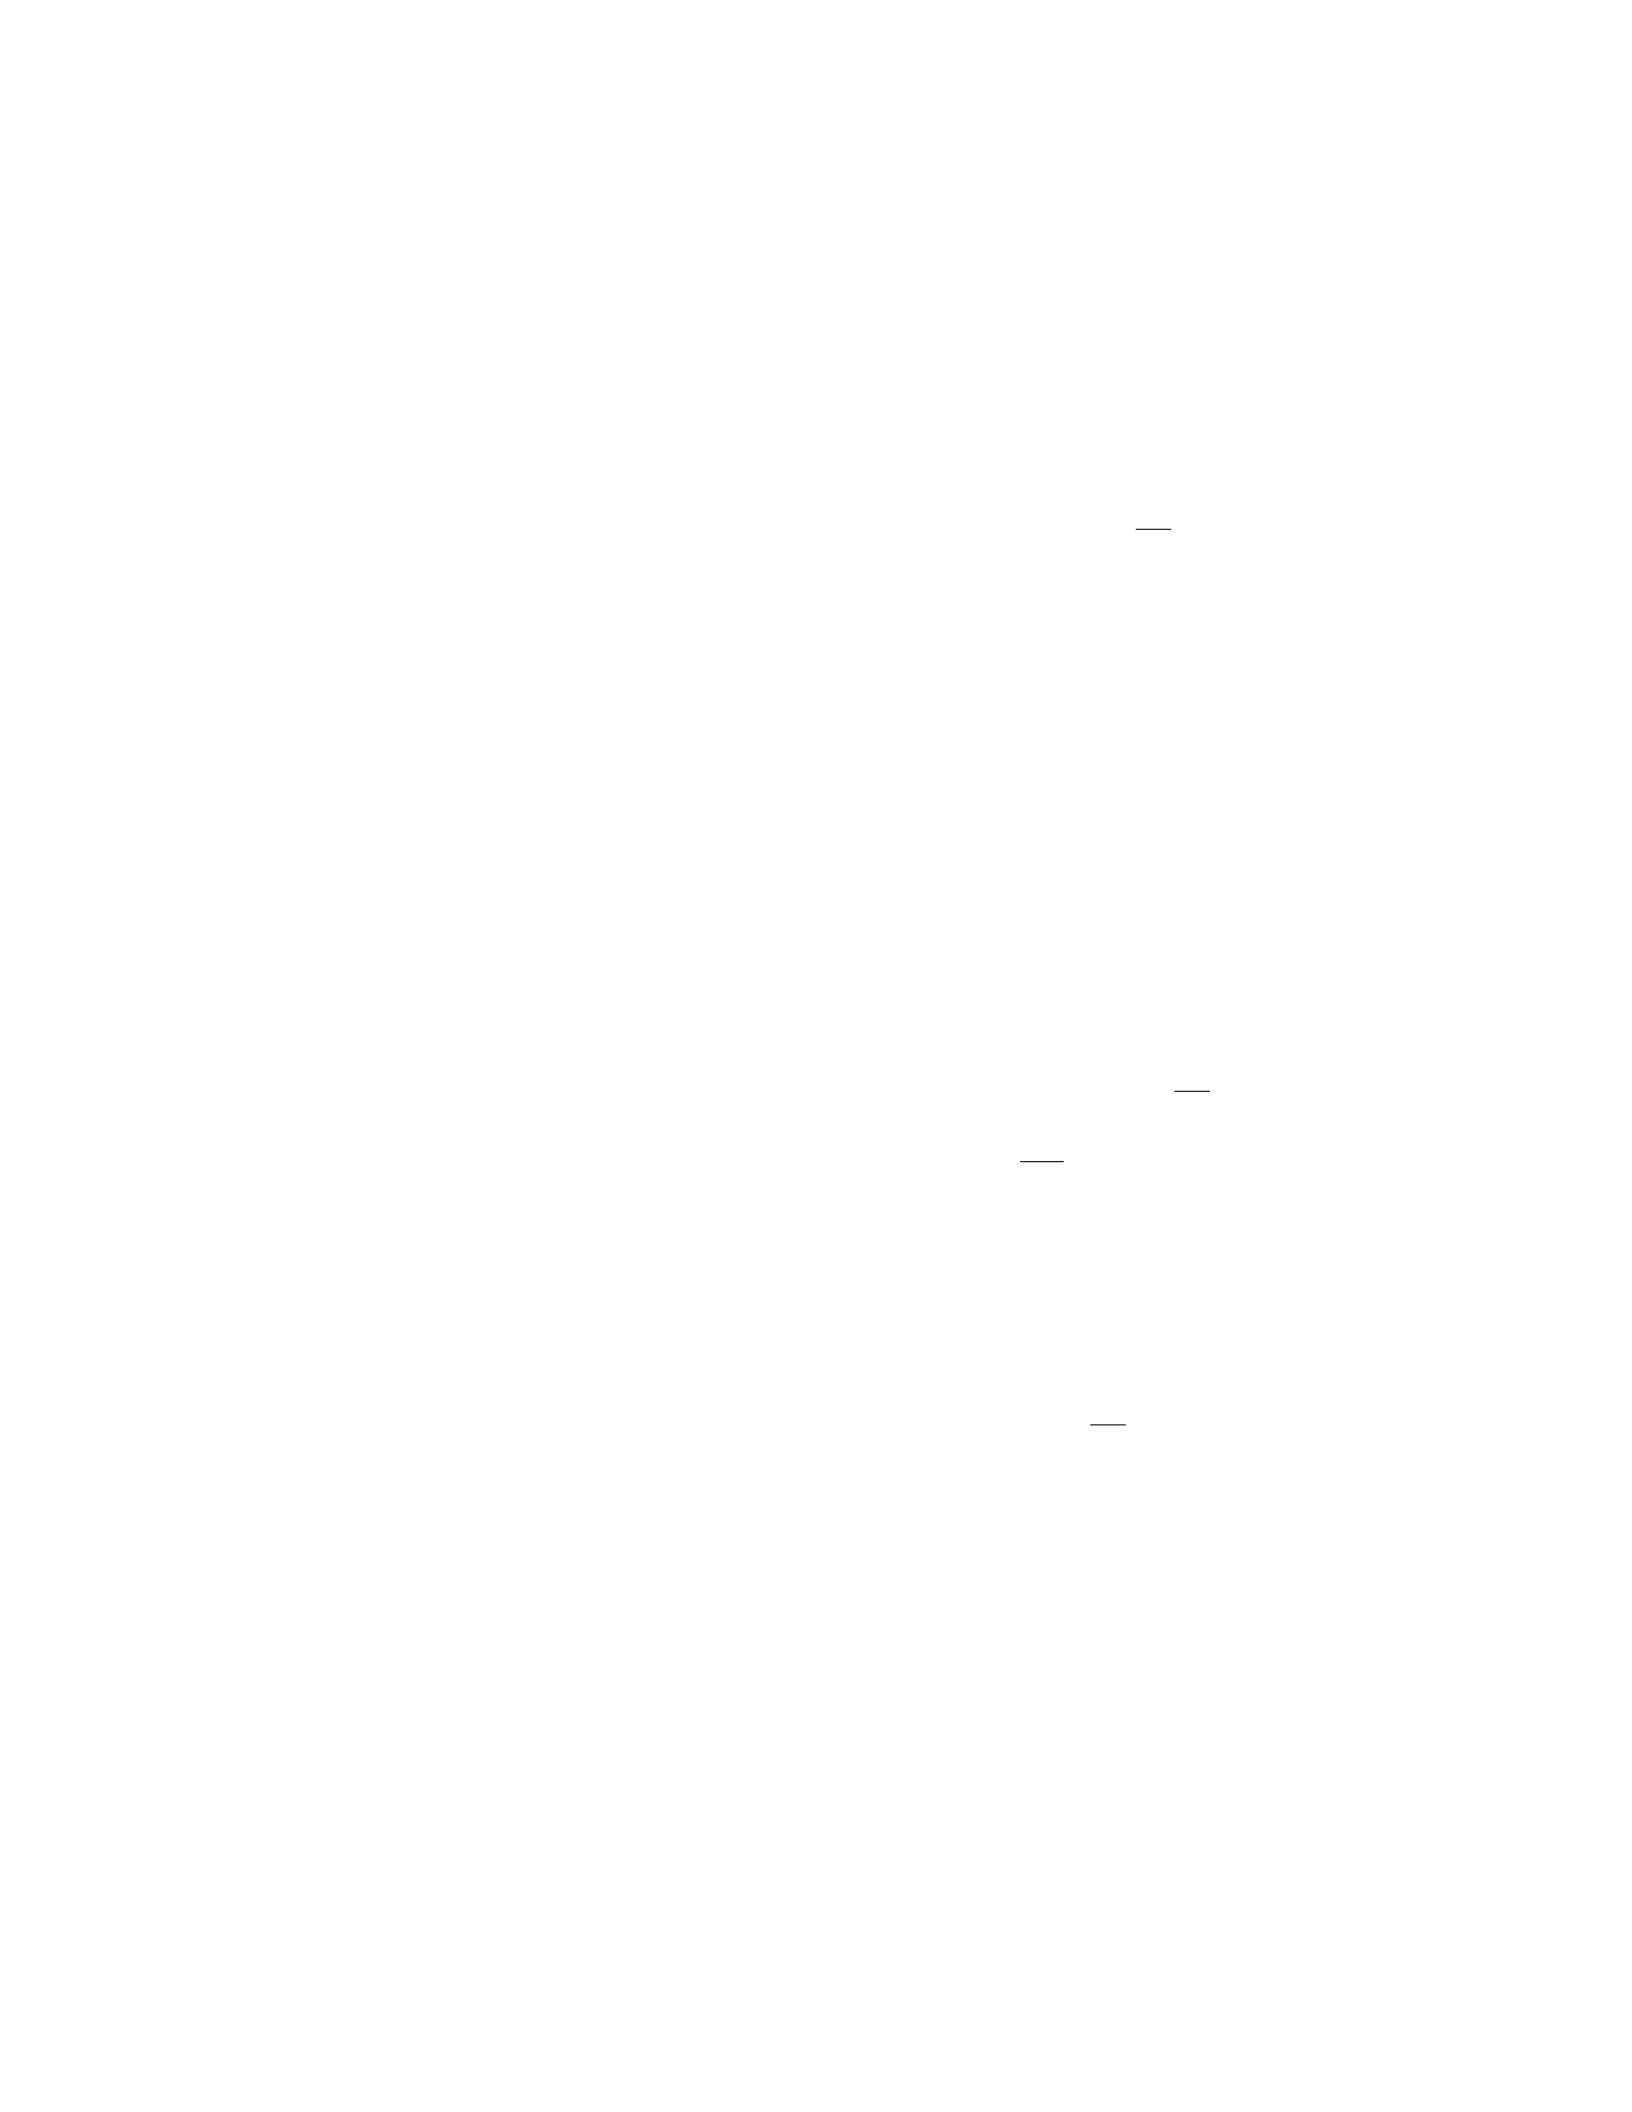
Let Xand Ybe two spatial point patterns in a region Wwith intensity functions
λX(u) and λY(u), respectively. Consider the following expression for the cross
K-function of the superposition of Xand a transformed version of Y:
KX,τ Y (r) = λX∗gτ(r) + λY∗g−τ(r)−r
|W|
where gτ(r) is the pair correlation function of Xevaluated at distance rand at
angle τ,|W|denotes the area of region W, and ∗represents spatial convolution.
Show that this expression satisfies the fundamental property of K-functions.
11
Solution
Step 1: Recall that the fundamental property of K-functions states that for any
point process Xin a region W, the expected number of points of Xat distance
rfrom a fixed point is equal to λW·KX(r), where λWis the intensity of Xin
region W, and KX(r) is the K-function of X.
Step 2: To show that KX,τ Y (r) = λX∗gτ(r) + λY∗g−τ(r)−r
|W|satisfies
the fundamental property of K-functions, we need to prove that
E[N(Br(o))] = λW·KX,τ Y (r)
for any ball Br(o)⊂W, where N(Br(o)) is the number of points of Xand the
transformed version of Yfalling inside Br(o).
Step 3: By the properties of spatial convolution, we have
E[N(Br(o))] = E[NX(Br(o))] + E[NY(Br(o))]
where NXand NYare the number of points in pattern Xand Y, respectively,
contained in Br(o).
Step 4: Recall that E[NX(Br(o))] = λX· |Br(o)|and E[NY(Br(o))] = λY·
|Br(o)|where |Br(o)|denotes the area of the ball of radius rcentered at o.
Step 5: Substituting these expressions into the equation from Step 3 gives
us
E[N(Br(o))] = λX· |Br(o)|+λY· |Br(o)|
Step 6: Now, let’s evaluate KX,τ Y (r) = λX∗gτ(r) + λY∗g−τ(r)−r
|W|at r:
KX,τ Y (r) = λX·gτ(r) + λY·g−τ(r)−r
|W|
Step 7: Since gτ(r) and g−τ(r) are pair correlation functions, they represent
the expected number of additional points in Xand the transformed version of
Yat distance rfrom a given point compared to complete spatial randomness.
Step 8: Hence, for the superposition of Xand the transformed version of
Y, the expected number of additional points at distance rfrom a fixed point is
given by KX,τ Y (r) times the intensity λW.
Step 9: Therefore, KX,τ Y (r) = λX∗gτ(r) + λY∗g−τ(r)−r
|W|satisfies the
fundamental property of K-functions and represents the expected number of
points at distance rfor the given spatial point patterns in W.
Question 13
Question
Consider a dataset containing spatial information on temperatures recorded at
different locations. You are tasked with modeling the spatial variation in tem-
peratures using Kriging interpolation. Explain the steps involved in performing
Kriging interpolation for this dataset.
12

Solution
To perform Kriging interpolation for the given dataset, follow these steps:
Step 1: Define the Problem - Clearly define the problem at hand, which
in this case is estimating the temperature at unsampled locations based on the
measured temperatures at sampled locations.
Step 2: Semivariogram Analysis - Calculate the semivariogram from
the recorded temperature data. This step involves computing the variance of
the temperature differences between pairs of locations at various distances.
Step 3: Model the Semivariogram - Fit a theoretical model (e.g., spher-
ical, exponential, Gaussian) to the empirical semivariogram obtained in the pre-
vious step. This model will help capture the spatial correlation structure of the
temperature data.
Step 4: Kriging Estimation - Using the modeled semivariogram, perform
the Kriging estimation at the unsampled locations. This involves calculating the
weights for each sampled point based on its distance and spatial correlation with
the unsampled location.
Step 5: Interpolation - Once the weights are calculated, interpolate the
temperatures at unsampled locations by combining the measured temperatures
at sampled locations using the Kriging estimation.
Step 6: Validation - Finally, validate the Kriging interpolation results
by comparing them with independent temperature measurements or through
cross-validation techniques to evaluate the accuracy of the spatial temperature
model.
By following these steps, you can effectively model the spatial variation in
temperatures using Kriging interpolation for the given dataset.
Question 14
Question
Consider a dataset of crime incidents across different neighborhoods in a city.
You are tasked with analyzing the spatial patterns of these incidents and build-
ing a predictive model to identify high-risk areas.
Given the dataset, describe the steps you would take to analyze the spatial
distribution of crime incidents and develop a spatial predictive model.
Solution
To analyze the spatial distribution of crime incidents and build a predictive
model, the following steps should be taken:
Step 1: Exploratory Data Analysis (EDA) - Conduct exploratory data
analysis to understand the distribution of crime incidents across neighborhoods.
- Use descriptive statistics and data visualization techniques such as histograms
and maps to identify any patterns or outliers.
13
Step 2: Spatial Autocorrelation Analysis - Perform a spatial autocor-
relation analysis to determine if there are spatial clusters or patterns of crime
incidents. - Use methods like Moran’s I statistic to quantify spatial autocorre-
lation.
Step 3: Spatial Hotspot Analysis - Conduct a hotspot analysis to iden-
tify statistically significant clusters of high or low crime incidents. - Utilize
techniques like Getis-Ord Gi* statistic to identify hotspots of crime.
Step 4: Spatial Regression Modeling - Build a spatial regression model
to predict crime incidents based on relevant explanatory variables. - Consider
variables such as population density, socioeconomic factors, and proximity to
amenities as predictors. - Use techniques like spatial lag or spatial error models
to account for spatial dependence in the data.
Step 5: Model Evaluation and Validation - Evaluate the spatial pre-
dictive model using metrics like R-squared, AIC, BIC, and residuals analysis. -
Validate the model by applying it to a separate dataset or using cross-validation
techniques.
Step 6: Interpretation and Visualization - Interpret the results of the
spatial predictive model and identify high-risk areas based on the model predic-
tions. - Visualize the results using maps to communicate the findings effectively
to stakeholders.
Question 15
Question
Consider a dataset containing information about the population density in dif-
ferent regions of a country. You are tasked with analyzing the spatial patterns
and trends in the data to inform urban planning decisions. Describe the steps
you would take to conduct a spatial data analysis and modeling of this dataset.
Solution
To conduct a spatial data analysis and modeling of the population density
dataset, the following steps can be taken:
Step 1: Data Collection
Collect the dataset containing information on population density in dif-
ferent regions of the country.
Ensure that the dataset includes spatial coordinates (latitude and longi-
tude) for each region.
Step 2: Data Exploration
Visualize the dataset using maps, scatter plots, and histograms to under-
stand the distribution of population density across regions.
Look for any spatial patterns or clusters in the data.
14
Step 3: Spatial Autocorrelation Analysis
Conduct spatial autocorrelation analysis to determine if there is any spa-
tial dependence in the population density values.
Use Moran’s I statistic to quantify the spatial autocorrelation.
Step 4: Spatial Interpolation
Perform spatial interpolation techniques such as Kriging or Inverse Dis-
tance Weighting to estimate population density values at unsampled lo-
cations.
Evaluate the accuracy of the interpolation results.
Step 5: Spatial Regression Modeling
Build a spatial regression model to analyze the relationship between pop-
ulation density and other factors such as land use, socio-economic indica-
tors, or infrastructure.
Incorporate spatial weights matrices to account for spatial autocorrelation
in the data.
Step 6: Model Evaluation
Validate the spatial regression model using criteria such as R-squared,
AIC, and residual analysis.
Assess the goodness of fit and predictive performance of the model.
By following these steps, a comprehensive spatial data analysis and modeling
of the population density dataset can be conducted to inform urban planning
decisions.
Question 16
Question
Let Xand Ybe random variables representing the latitudes of two earthquake
epicenters. Assume that X∼N(36.5,0.32) and Y∼N(34,0.62), and that
the correlation coefficient between Xand Yis 0.8. Find the joint probability
density function of Xand Y.
Solution
Step 1: The joint probability density function of Xand Yfor bivariate normal
distribution is given as:
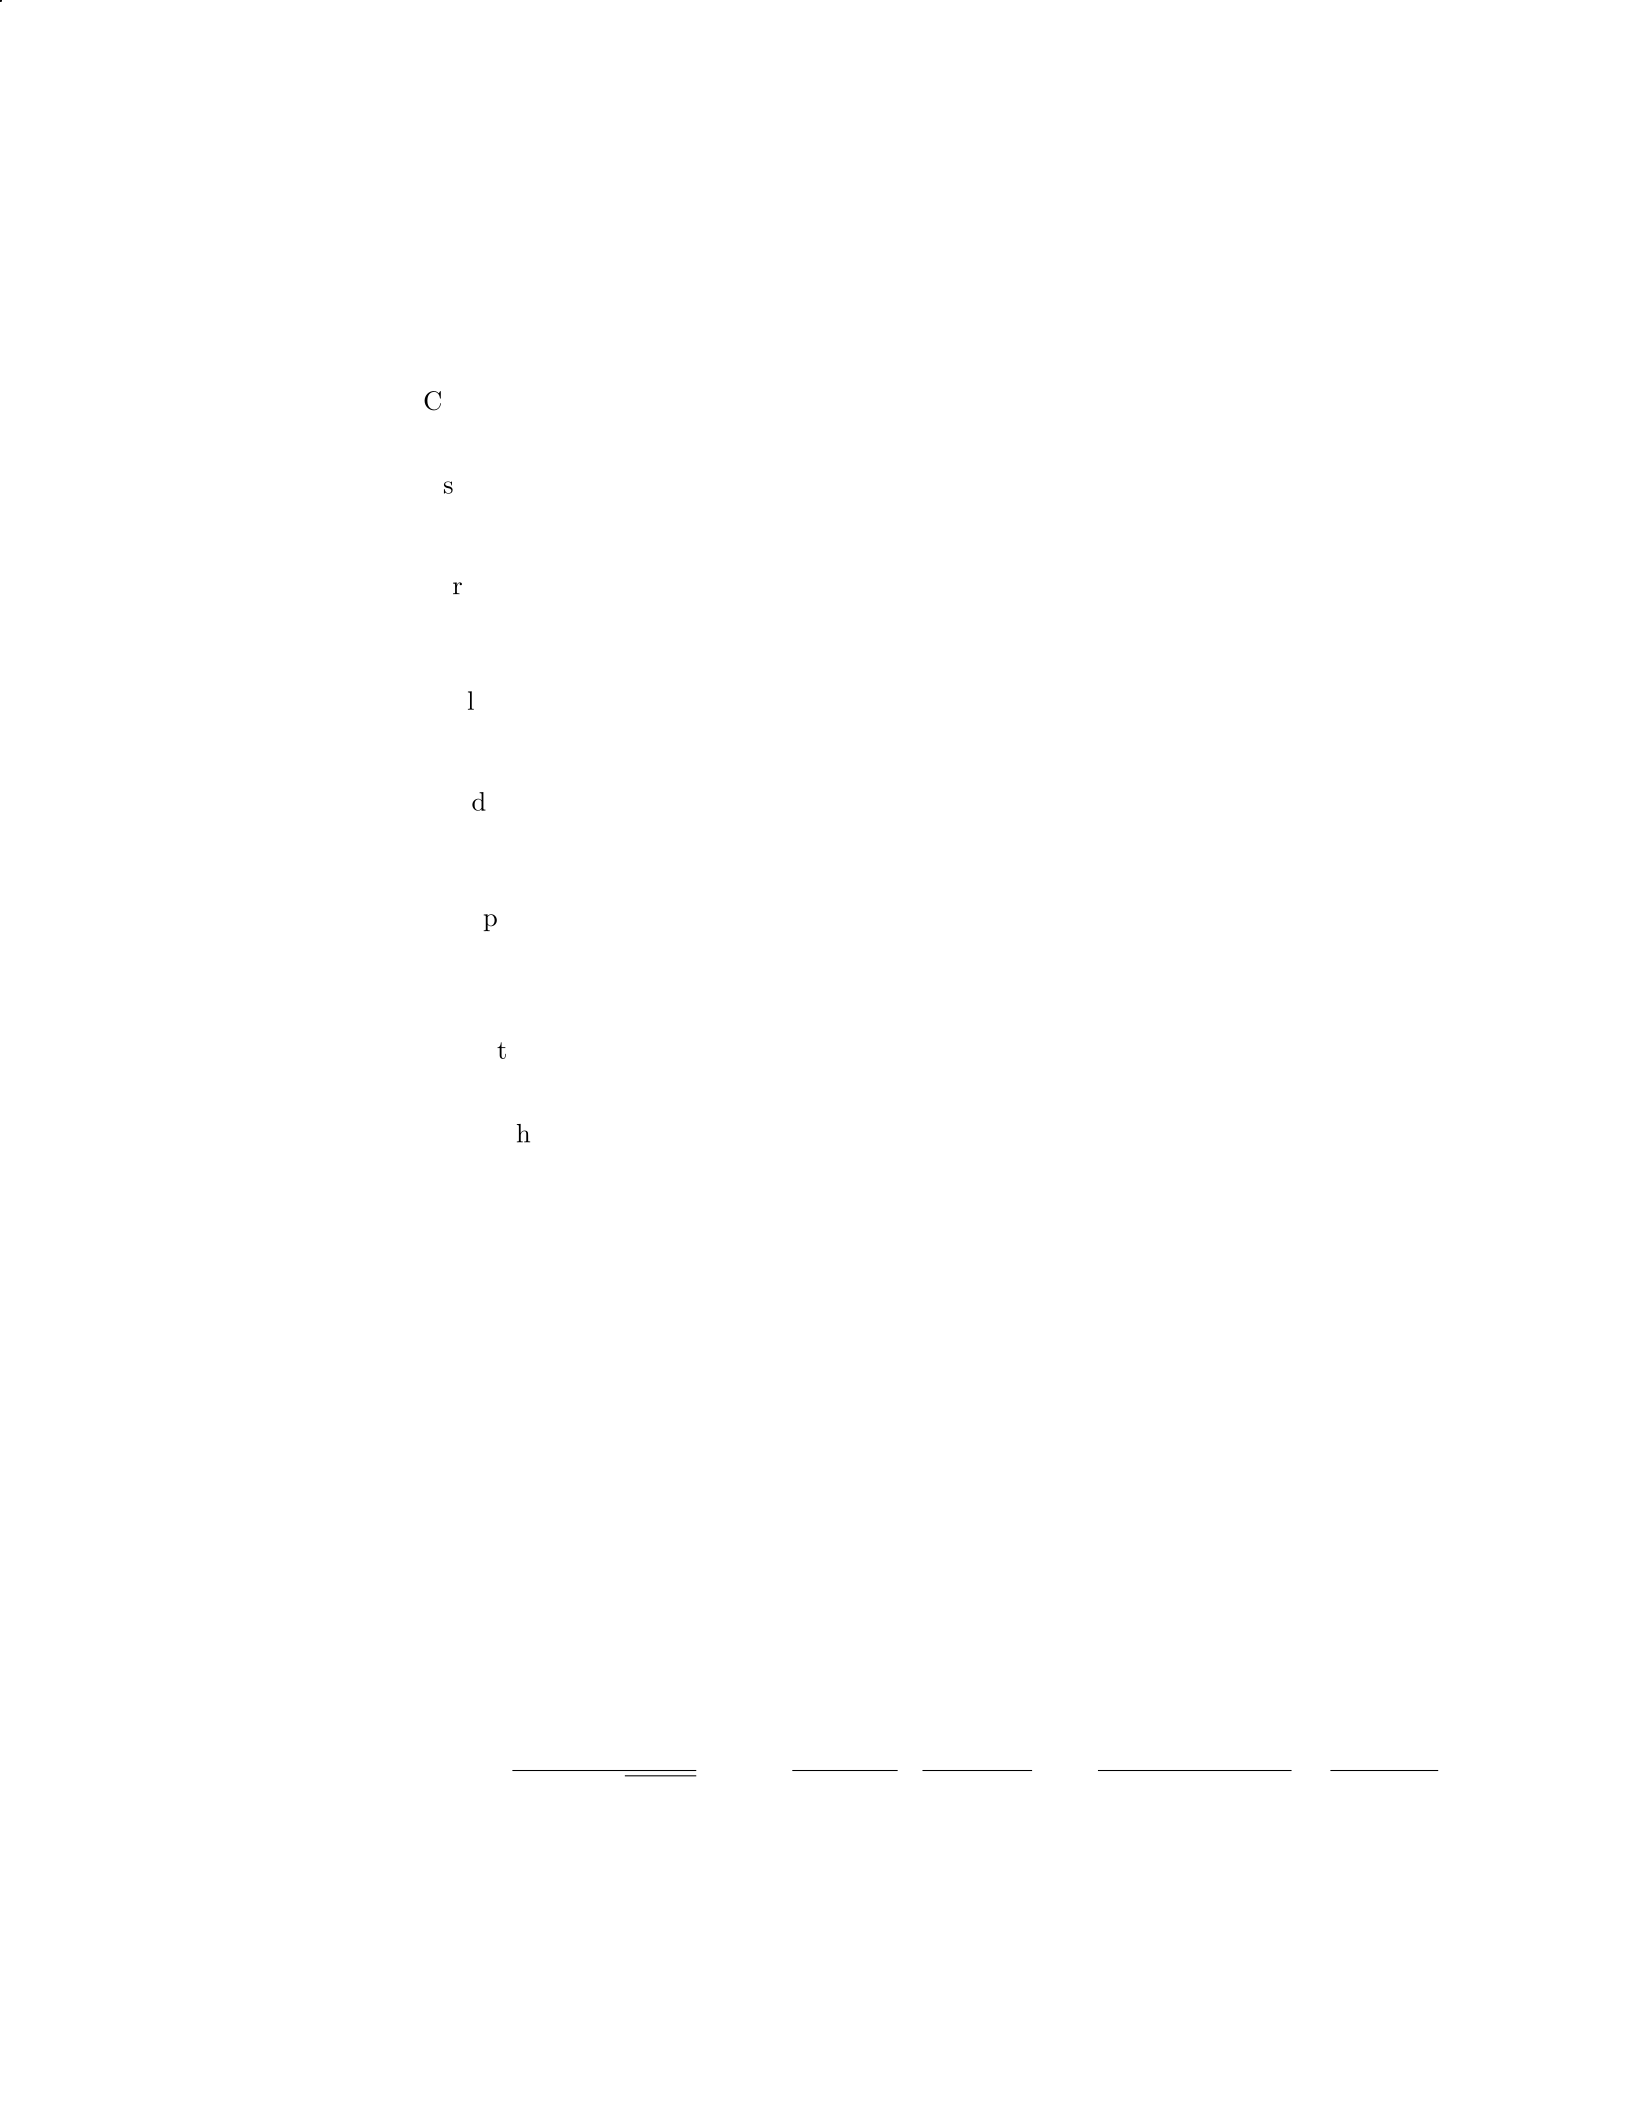
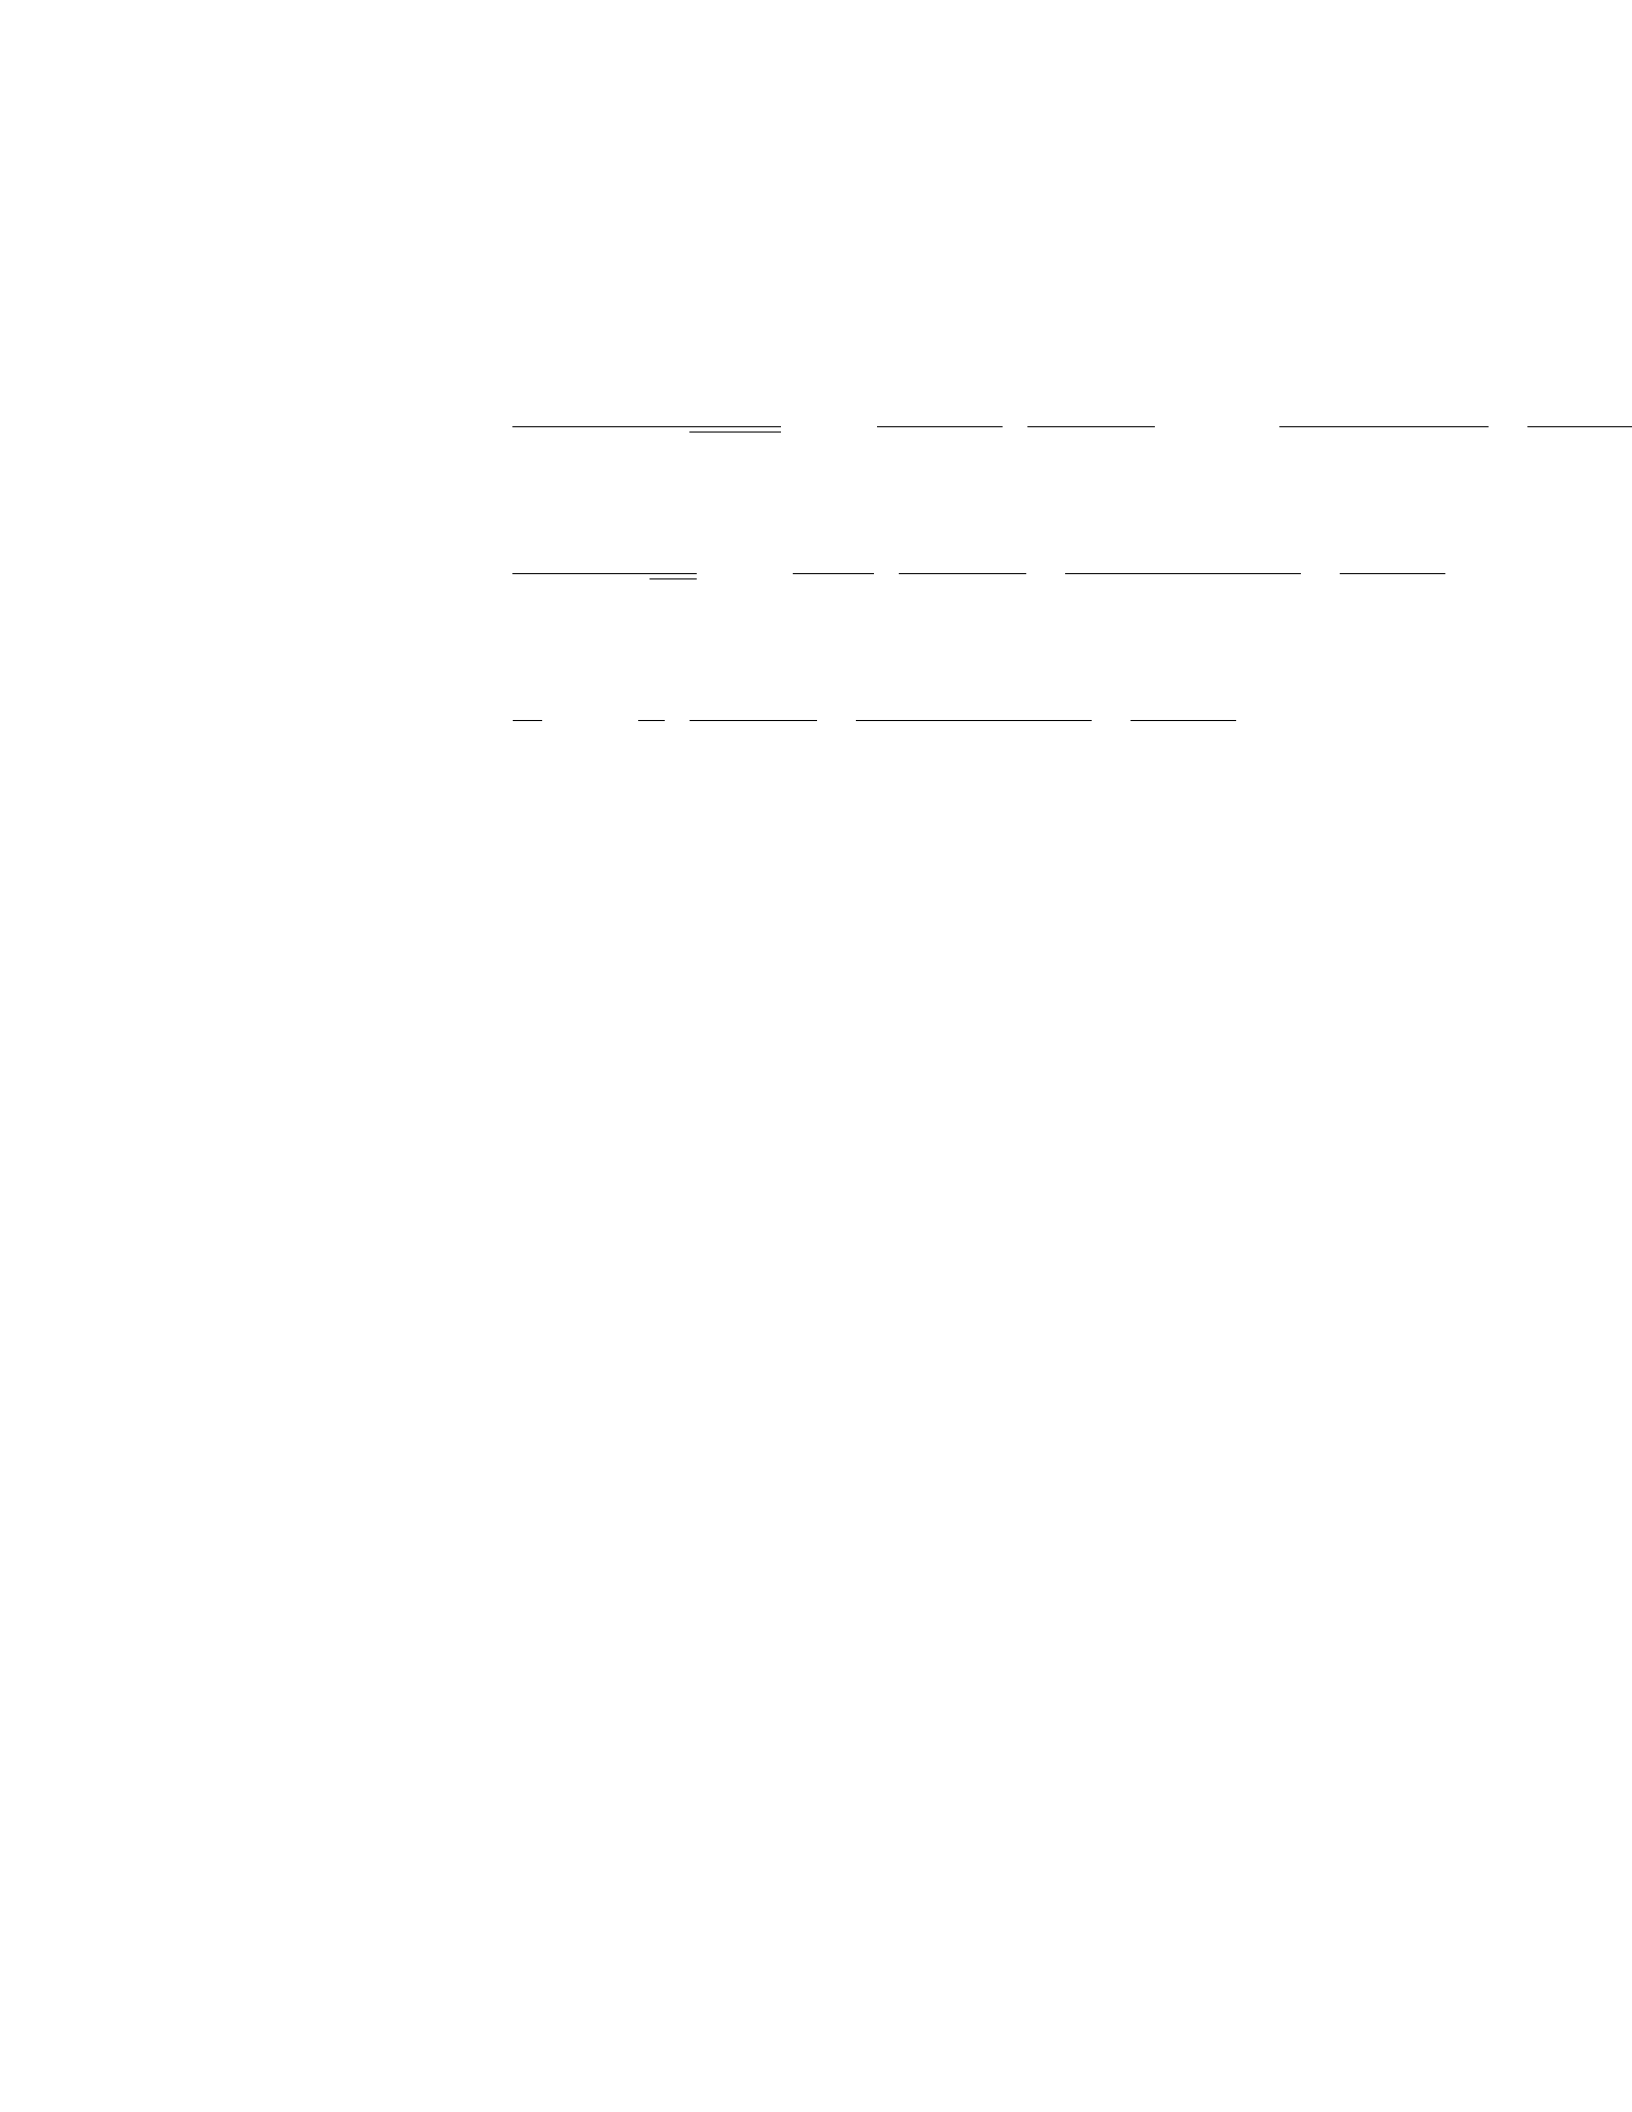
fX,Y (x, y) = 1
2πσxσyp1−ρ2exp −1
2(1 −ρ2)(x−µx)2
σ2
x−2ρ(x−µx)(y−µy)
σxσy
+(y−µy)2
σ2
y
15
Step 2: Plugging in the values of the given parameters, we get:
fX,Y (x, y) = 1
2π·0.3·0.6·√1−0.82exp −1
2(1 −0.82)(x−36.5)2
0.32−2·0.8·(x−36.5)(y−34)
0.3·0.6+(y−34)2
0.62
Step 3: Simplify the equation further:
fX,Y (x, y) = 1
2π·0.18 ·√0.36 exp −1
2(0.36) (x−36.5)2
0.09 −16(x−36.5)(y−34)
0.18 +(y−34)2
0.36
Step 4: Finally, the joint probability density function of Xand Yis:
fX,Y (x, y) = 25
3πexp −75
2(x−36.5)2
0.09 −16(x−36.5)(y−34)
0.18 +(y−34)2
0.36
Question 17
Question
Consider a dataset containing the coordinates of 100 different locations in a city.
The dataset also includes information on the average income in each location.
You are tasked with analyzing the spatial distribution of income in the city
using spatial data analysis and modeling techniques. One of the techniques you
plan to use is spatial autocorrelation analysis.
Explain what spatial autocorrelation is and how you can determine if there
is spatial autocorrelation in the income data.
Solution
Step 1: Spatial Autocorrelation
Spatial autocorrelation refers to the degree to which the values of a variable
(such as income) correlate with neighboring values in space. In other words, it
explores the spatial patterns and relationships of a variable across a geographic
area. Spatial autocorrelation can be positive, indicating that similar values tend
to cluster together, or negative, indicating dispersion or dissimilarity among
values.
Step 2: Determining Spatial Autocorrelation
To determine if there is spatial autocorrelation in the income data, we can use
a statistical test such as Moran’s I. Moran’s I statistic measures the spatial
autocorrelation in a dataset with respect to its neighboring locations. The
values of Moran’s I range from -1 (perfect dispersion) to 1 (perfect correlation),
with 0 indicating no spatial autocorrelation.
Step 3: Calculating Moran’s I
To calculate Moran’s I, we first need to define a spatial weights matrix that
specifies the spatial relationships between locations. Common types of spatial
weights matrices include binary contiguity (neighbors are defined by sharing a
border or vertex) or distance-based (weights decrease with distance) matrices.
16
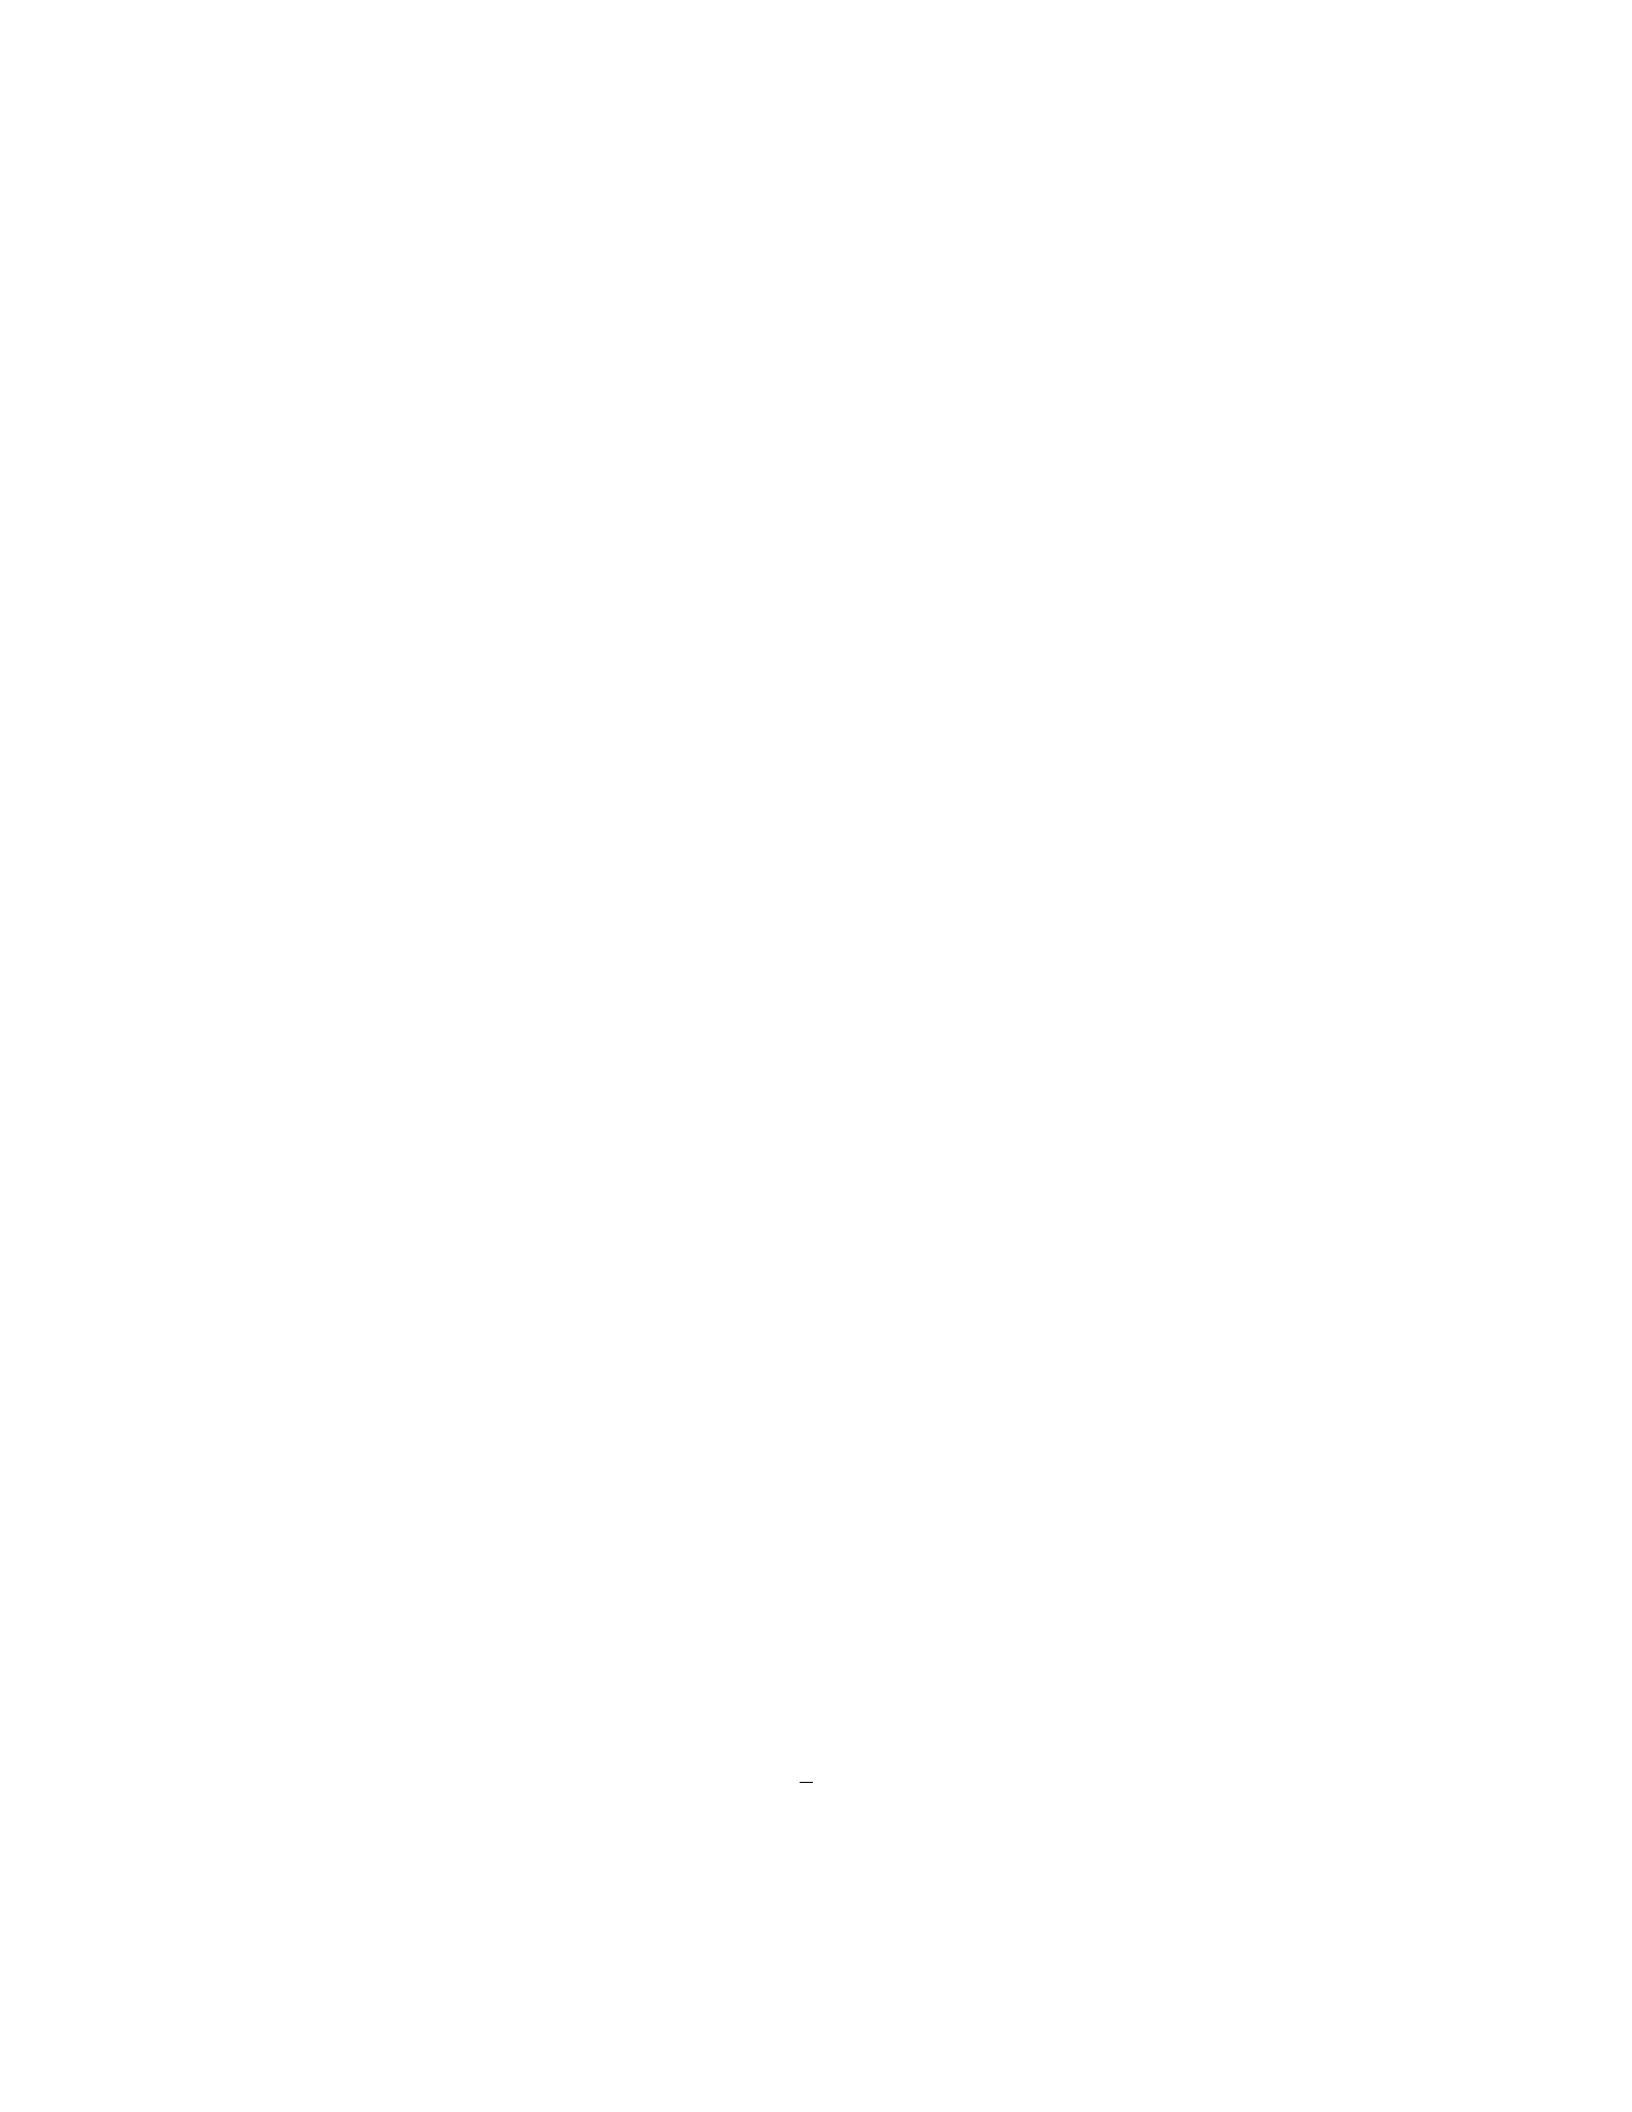
Using the spatial weights matrix, we can compute Moran’s I statistic for the
income data.
Step 4: Interpreting Moran’s I
After calculating Moran’s I, we can test its statistical significance to determine
if the observed spatial autocorrelation is statistically different from what would
be expected by random chance. If Moran’s I is significantly different from 0, we
can conclude that there is spatial autocorrelation in the income data.
Step 5: Conclusion
In this way, by conducting spatial autocorrelation analysis using techniques
such as Moran’s I, we can assess the spatial distribution of income in the city
and identify any clustering or dispersion patterns that exist. This information
can be valuable for understanding the socio-economic dynamics of the city and
informing policy decisions related to resource allocation and urban planning.
Question 18
Question
Let Xand Ybe two random variables representing the spatial coordinates (x, y)
in a two-dimensional space. Suppose the joint probability density function of X
and Yis given by f(x, y) = ce−2(x+y)for 0 <x<∞and 0 < y < ∞, where c
is a normalizing constant.
Find the marginal probability density functions of Xand Y.
Solution
Step 1: To find the marginal probability density function of X, we need to
integrate the joint probability density function f(x, y) over all possible values
of Y.
fX(x) = Z∞
0
f(x, y)dy
Step 2: Substitute the expression of f(x, y) into the integral.
fX(x) = Z∞
0
ce−2(x+y)dy
Step 3: Perform the integration.
fX(x) = cZ∞
0
e−2xe−2ydy
fX(x) = ce−2xZ∞
0
e−2ydy
Step 4: Solve the integral.
fX(x) = −c
2e−2x[e−2y]∞
0
17
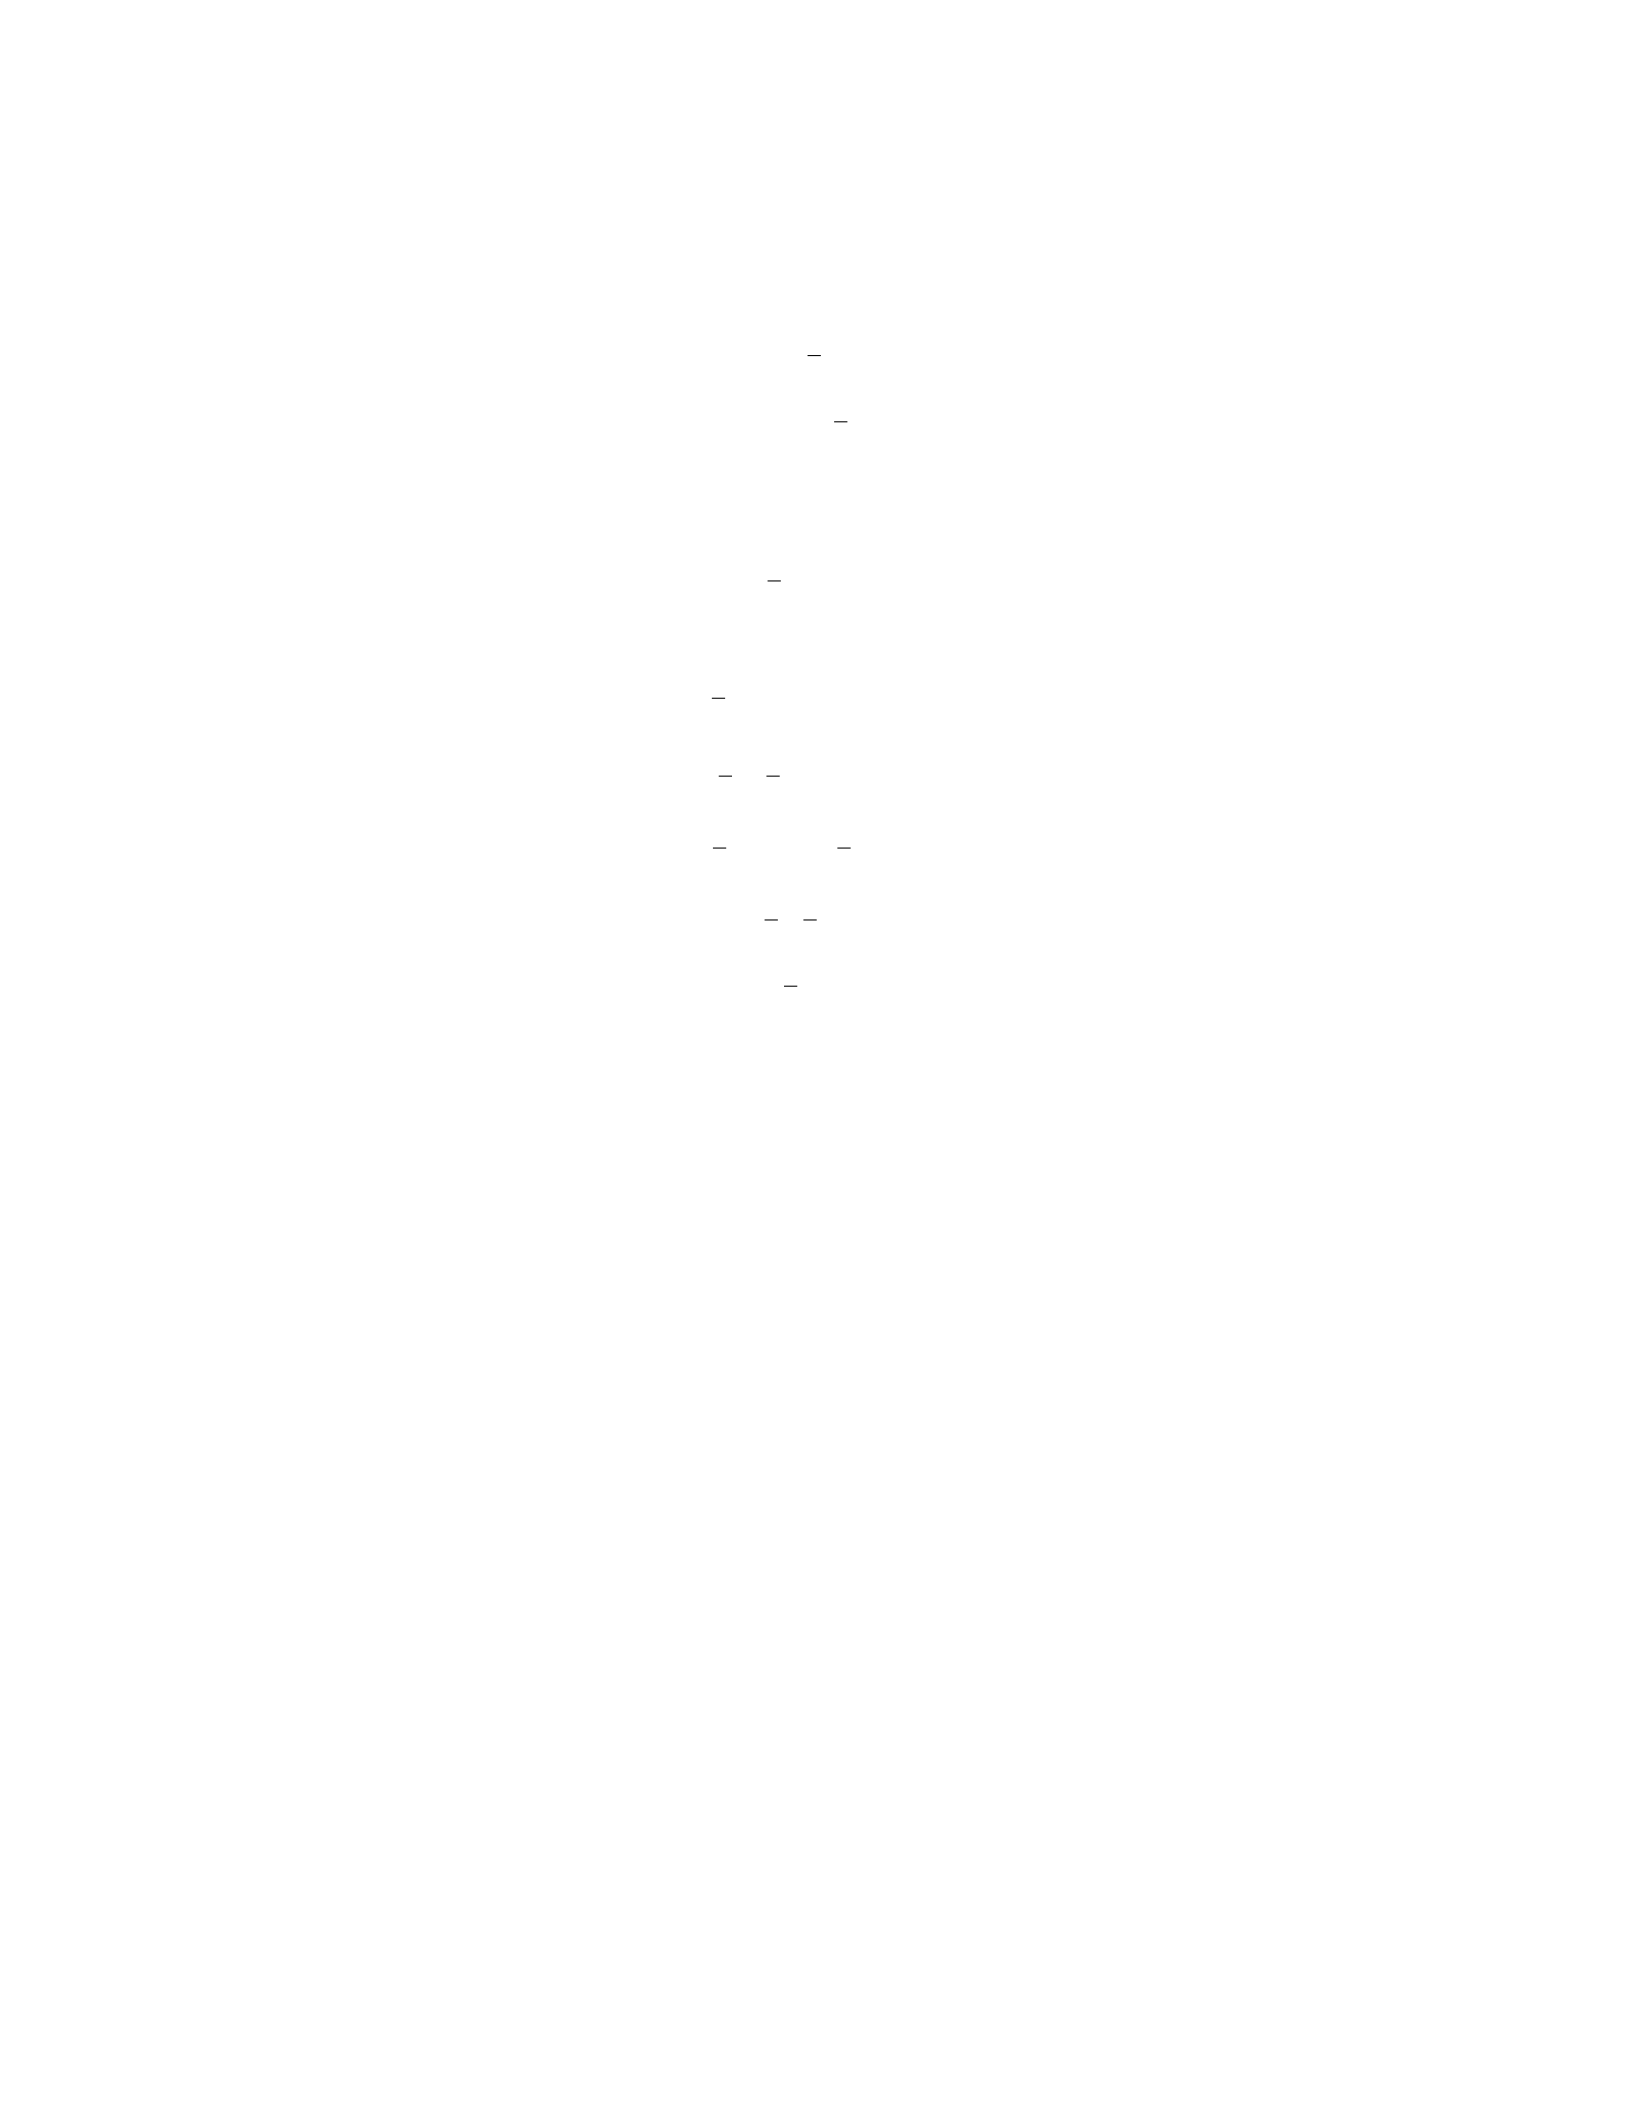
fX(x) = −c
2e−2x[0 −1]
fX(x) = c
2e−2x
Step 5: To find the value of c, we need to ensure that the marginal probability
density function of Xintegrates to 1 over all possible values of X.
Z∞
0
c
2e−2xdx = 1
Step 6: Solve for c.
c
2Z∞
0
e−2xdx = 1
c
2[−1
2e−2x]∞
0= 1
c
2[−0−(−1
2)] = 1
c
2·1
2= 1
c
4= 1
c= 4
Therefore, the marginal probability density function of Xis:
fX(x) = 2e−2x
Step 7: Similarly, repeat the steps above to find the marginal probability
density function of Y. We can interchange the roles of Xand Yin the joint
probability density function.
Step 8: The marginal probability density function of Yis given by:
fY(y)=2e−2y
Question 19
Question
Let Xand Ybe two spatial processes defined on a region D⊆R2with contin-
uous realizations and covariance functions given by:
CX(h) = σ2
Xexp(−∥h∥) and CY(h) = σ2
Yexp(−3∥h∥),
where σ2
X= 1, σ2
Y= 2, and h∈R2is the displacement vector. Determine the
process Zwhich is the difference between Xand Y, i.e., Z=X−Y. Compute
the covariance function CZ(h) of Z.
18
Solution
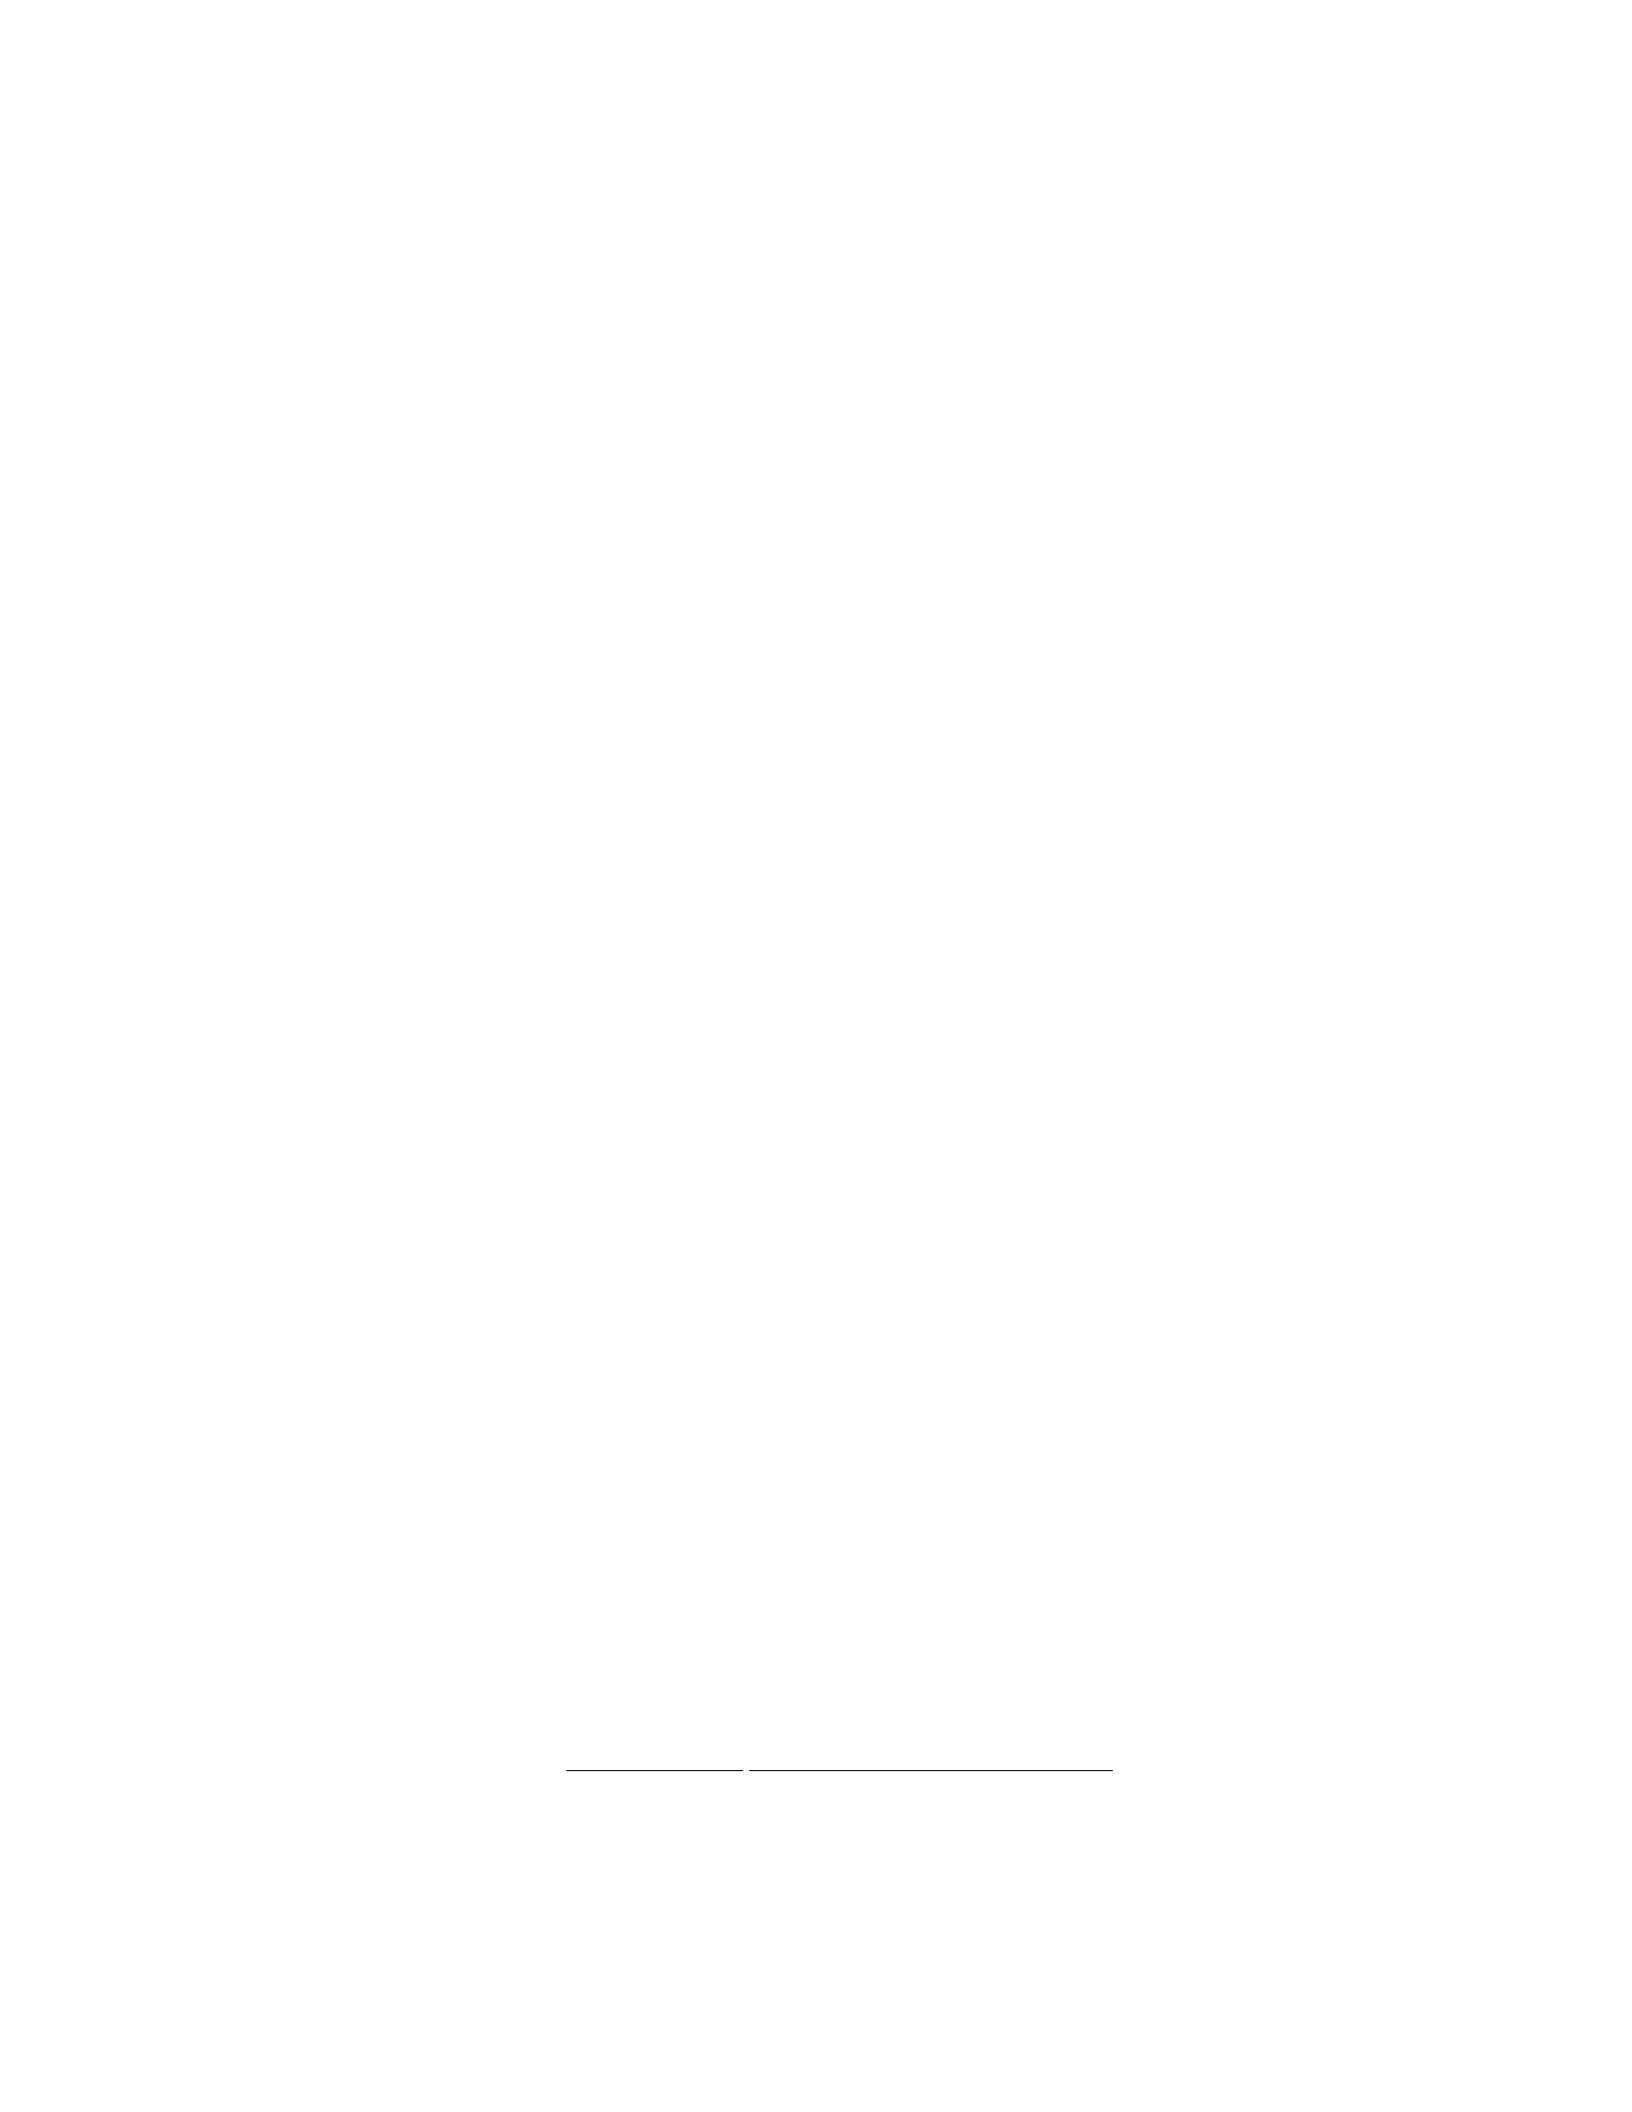
1. To determine the covariance function CZ(h) of the process Z=X−Y, we
first find the covariance function of Z:
CZ(h) = CX(h)−CY(h).
2. Substitute the given covariance functions for Xand Y:
CZ(h) = σ2
Xexp(−∥h∥)−σ2
Yexp(−3∥h∥).
3. Plug in the values of σ2
X= 1 and σ2
Y= 2 into the equation:
CZ(h) = exp(−∥h∥)−2 exp(−3∥h∥).
4. Simplify the expression by factoring out exp(−∥h∥):
CZ(h) = exp(−∥h∥)(1 −2 exp(−2∥h|)).
Therefore, the covariance function CZ(h) of the process Z=X−Yis given
by CZ(h) = exp(−∥h∥)(1 −2 exp(−2∥h|)).
Question 20
Question
Consider a dataset containing coordinates (latitude and longitude) of various
cities in a country. You are tasked with analyzing the spatial distribution of
these cities to identify any clustering patterns that may exist. Perform a spatial
data analysis and modeling to determine if the cities exhibit significant spatial
clustering or if their distribution is random.
Solution
To analyze the spatial distribution of the cities and identify clustering patterns,
we can perform a spatial autocorrelation analysis using Moran’s I statistic. This
statistic will help us determine if the distribution of cities exhibits clustering,
randomness, or dispersion.
Step 1: Define the Spatial Weights Matrix
First, we need to construct a spatial weights matrix that defines the spatial
relationships between the cities. We can use a contiguity-based weights matrix,
such as Queen’s contiguity, where cities are considered neighbors if they share
a border or a vertex.
Step 2: Calculate Moran’s I Statistic
Next, we calculate Moran’s I statistic using the following formula:
I=n
Pn
i=1 Pn
j=1 wij Pn
i=1 Pn
j=1 wij (xi−¯x)(xj−¯x)
Pn
i=1(xi−¯x)2
19

where: - nis the number of cities, - wij is the element of the spatial weights
matrix, - xiand xjare the values of the variable (coordinates) at locations i
and j, - ¯xis the mean of all values.
Step 3: Determine Significance
Finally, we can assess the significance of Moran’s I statistic by comparing
it to its expected value under the null hypothesis of spatial randomness. We
can use a permutation test to calculate a pseudo p-value and determine if the
observed spatial pattern is statistically significant.
Based on the Moran’s I statistic and its significance level, we can conclude
whether the spatial distribution of cities exhibits clustering, dispersion, or ran-
domness.
Question 21
Question
Consider a dataset containing information on the elevation (in meters) of 50
different locations within a region. You are tasked with analyzing this spatial
data to identify any patterns or trends present in the dataset. Describe how you
would approach this task by outlining the steps involved in spatial data analysis
and modeling.
Solution
To analyze the spatial data on elevation for the 50 different locations, we can
follow a series of steps in spatial data analysis and modeling:
Step 1: Data Acquisition Obtain the dataset containing the elevation
information for the 50 locations within the region. Ensure the data is accurate,
complete, and stored in a format that is suitable for analysis.
Step 2: Data Exploration and Visualization Explore the dataset by
calculating summary statistics (mean, median, standard deviation, etc.) to gain
an understanding of the central tendency and variability of elevation values.
Use visualization techniques such as histograms, box plots, and scatter plots to
identify any patterns or outliers in the data.
Step 3: Spatial Data Preprocessing Perform any necessary preprocess-
ing steps on the data, such as handling missing values, normalizing data, and
transforming the dataset if required. Ensure the data is in a format suitable for
spatial analysis.
Step 4: Spatial Autocorrelation Analysis Conduct spatial autocorre-
lation analysis to determine whether there is a spatial pattern in the elevation
data. Use techniques such as Moran’s I and Geary’s C to assess the degree of
spatial autocorrelation present in the dataset.
Step 5: Spatial Interpolation Apply spatial interpolation techniques,
such as kriging or inverse distance weighting, to estimate elevation values at
20

locations where data is missing or to generate a continuous surface of elevation
across the region.
Step 6: Spatial Regression Modeling Perform spatial regression analy-
sis to identify any relationships between elevation and other attributes or covari-
ates. Use techniques like spatial lag models or spatial error models to account
for spatial dependencies in the data.
Step 7: Model Evaluation Evaluate the accuracy and performance of
the spatial models developed using measures such as R-squared, root mean
square error (RMSE), and cross-validation techniques to assess the validity of
the models.
By following these steps in spatial data analysis and modeling, we can gain
insights into the patterns and trends present in the elevation data for the 50
locations within the region.
Question 22
Question
Consider a dataset containing information on the spatial distribution of tree
species in a forest. You are tasked with analyzing and modeling this spatial data
to understand the patterns and relationships between different tree species.
Given the dataset, describe three key spatial data analysis techniques you
would utilize and explain how each technique can help in this analysis.
Solution
To analyze and model the spatial distribution of tree species in the forest dataset,
we can use the following key spatial data analysis techniques:
Step 1: Spatial Autocorrelation - Spatial autocorrelation is a technique used
to determine if there are any spatial patterns or clusters in the data. By cal-
culating spatial autocorrelation measures such as Moran’s I or Geary’s C, we
can assess if similar tree species tend to cluster together in space. This analysis
can help us identify any significant spatial patterns of tree species distribution
in the forest.
Step 2: Kriging - Kriging is a spatial interpolation technique used to es-
timate values at unsampled locations based on the values of nearby sampled
locations. By using kriging, we can create a spatially continuous map of tree
species distribution in the forest. This can help us visualize the spatial patterns
of different tree species and make more accurate predictions about the presence
of tree species at unsampled locations.
Step 3: Spatial Regression - Spatial regression is a technique that accounts
for the spatial dependency of data when modeling relationships between vari-
ables. By using spatial regression models, we can investigate how environmental
variables such as soil type, elevation, and proximity to water sources influence
the distribution of tree species in the forest. This analysis can help us identify
21
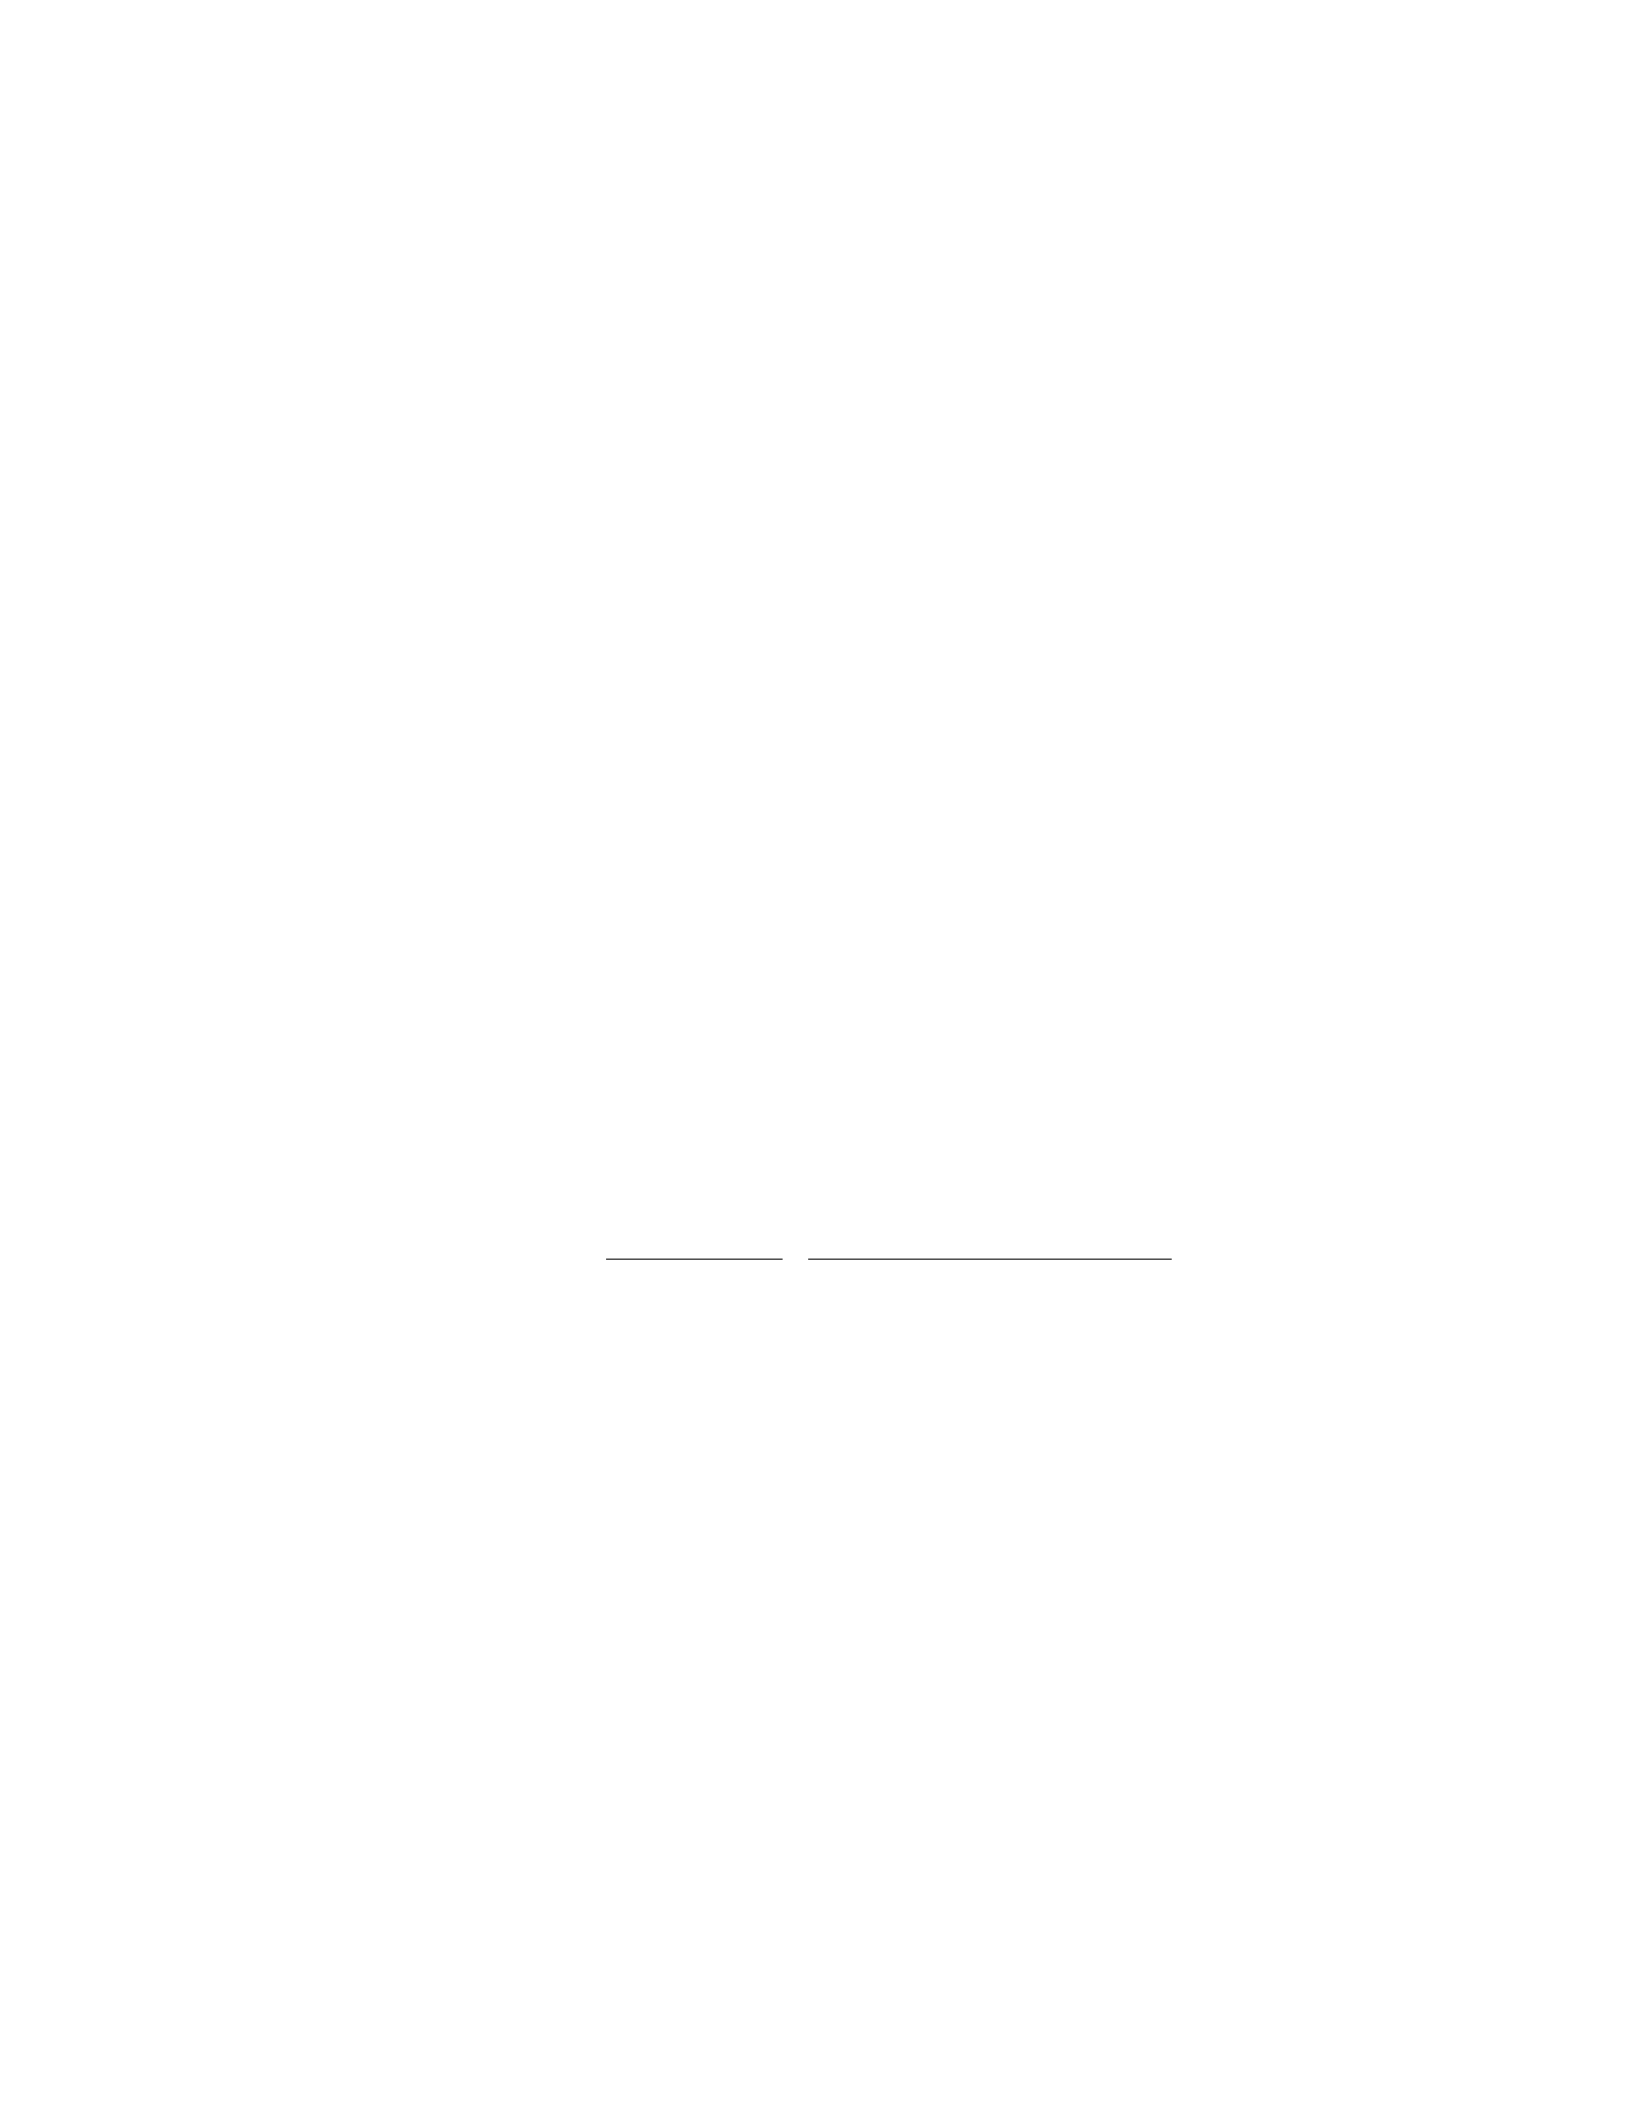
the key factors driving the spatial distribution of tree species and improve our
understanding of the ecological relationships in the forest.
Question 23
Question
Consider a dataset containing information on pollution levels and health out-
comes across different regions. You are tasked with analyzing the spatial corre-
lation between pollution levels and health outcomes using spatial data analysis
techniques.
Given a set of coordinates for different regions, pollution levels (measured
in parts per million) at each region, and health outcome scores (ranging from
1 to 10) at each region, perform the following steps: 1. Calculate the spatial
autocorrelation of pollution levels using Moran’s I statistic. 2. Determine if
there is a significant spatial pattern of pollution levels using a hypothesis test.
3. Calculate the spatial autocorrelation of health outcomes using Moran’s I
statistic. 4. Determine if there is a significant spatial pattern of health outcomes
using a hypothesis test. 5. Explore the spatial relationship between pollution
levels and health outcomes using a bivariate Moran’s I statistic. 6. Interpret
the results of the bivariate Moran’s I statistic in the context of the relationship
between pollution levels and health outcomes.
Solution
1. Calculate the spatial autocorrelation of pollution levels using Moran’s I
statistic:
Moran’s I = n
Pn
i=1 Pn
j=1 wij ·Pn
i=1 Pn
j=1 wij (xi−¯x)(xj−¯x)
Pn
i=1(xi−¯x)2
where: - nis the number of regions - xiis the pollution level at region i- ¯xis
the mean pollution level - wij is the spatial weight between regions iand j
2. Determine if there is a significant spatial pattern of pollution levels: To
test the significance of Moran’s I, we compare it to its expected value under the
null hypothesis of spatial randomness. We can calculate the z-score and p-value
to determine significance.
3. Calculate the spatial autocorrelation of health outcomes using Moran’s I
statistic: This is similar to Step 1, but with health outcome scores instead of
pollution levels.
4. Determine if there is a significant spatial pattern of health outcomes:
Repeat Step 2 with health outcome scores to determine significance.
5. Explore the spatial relationship between pollution levels and health out-
22
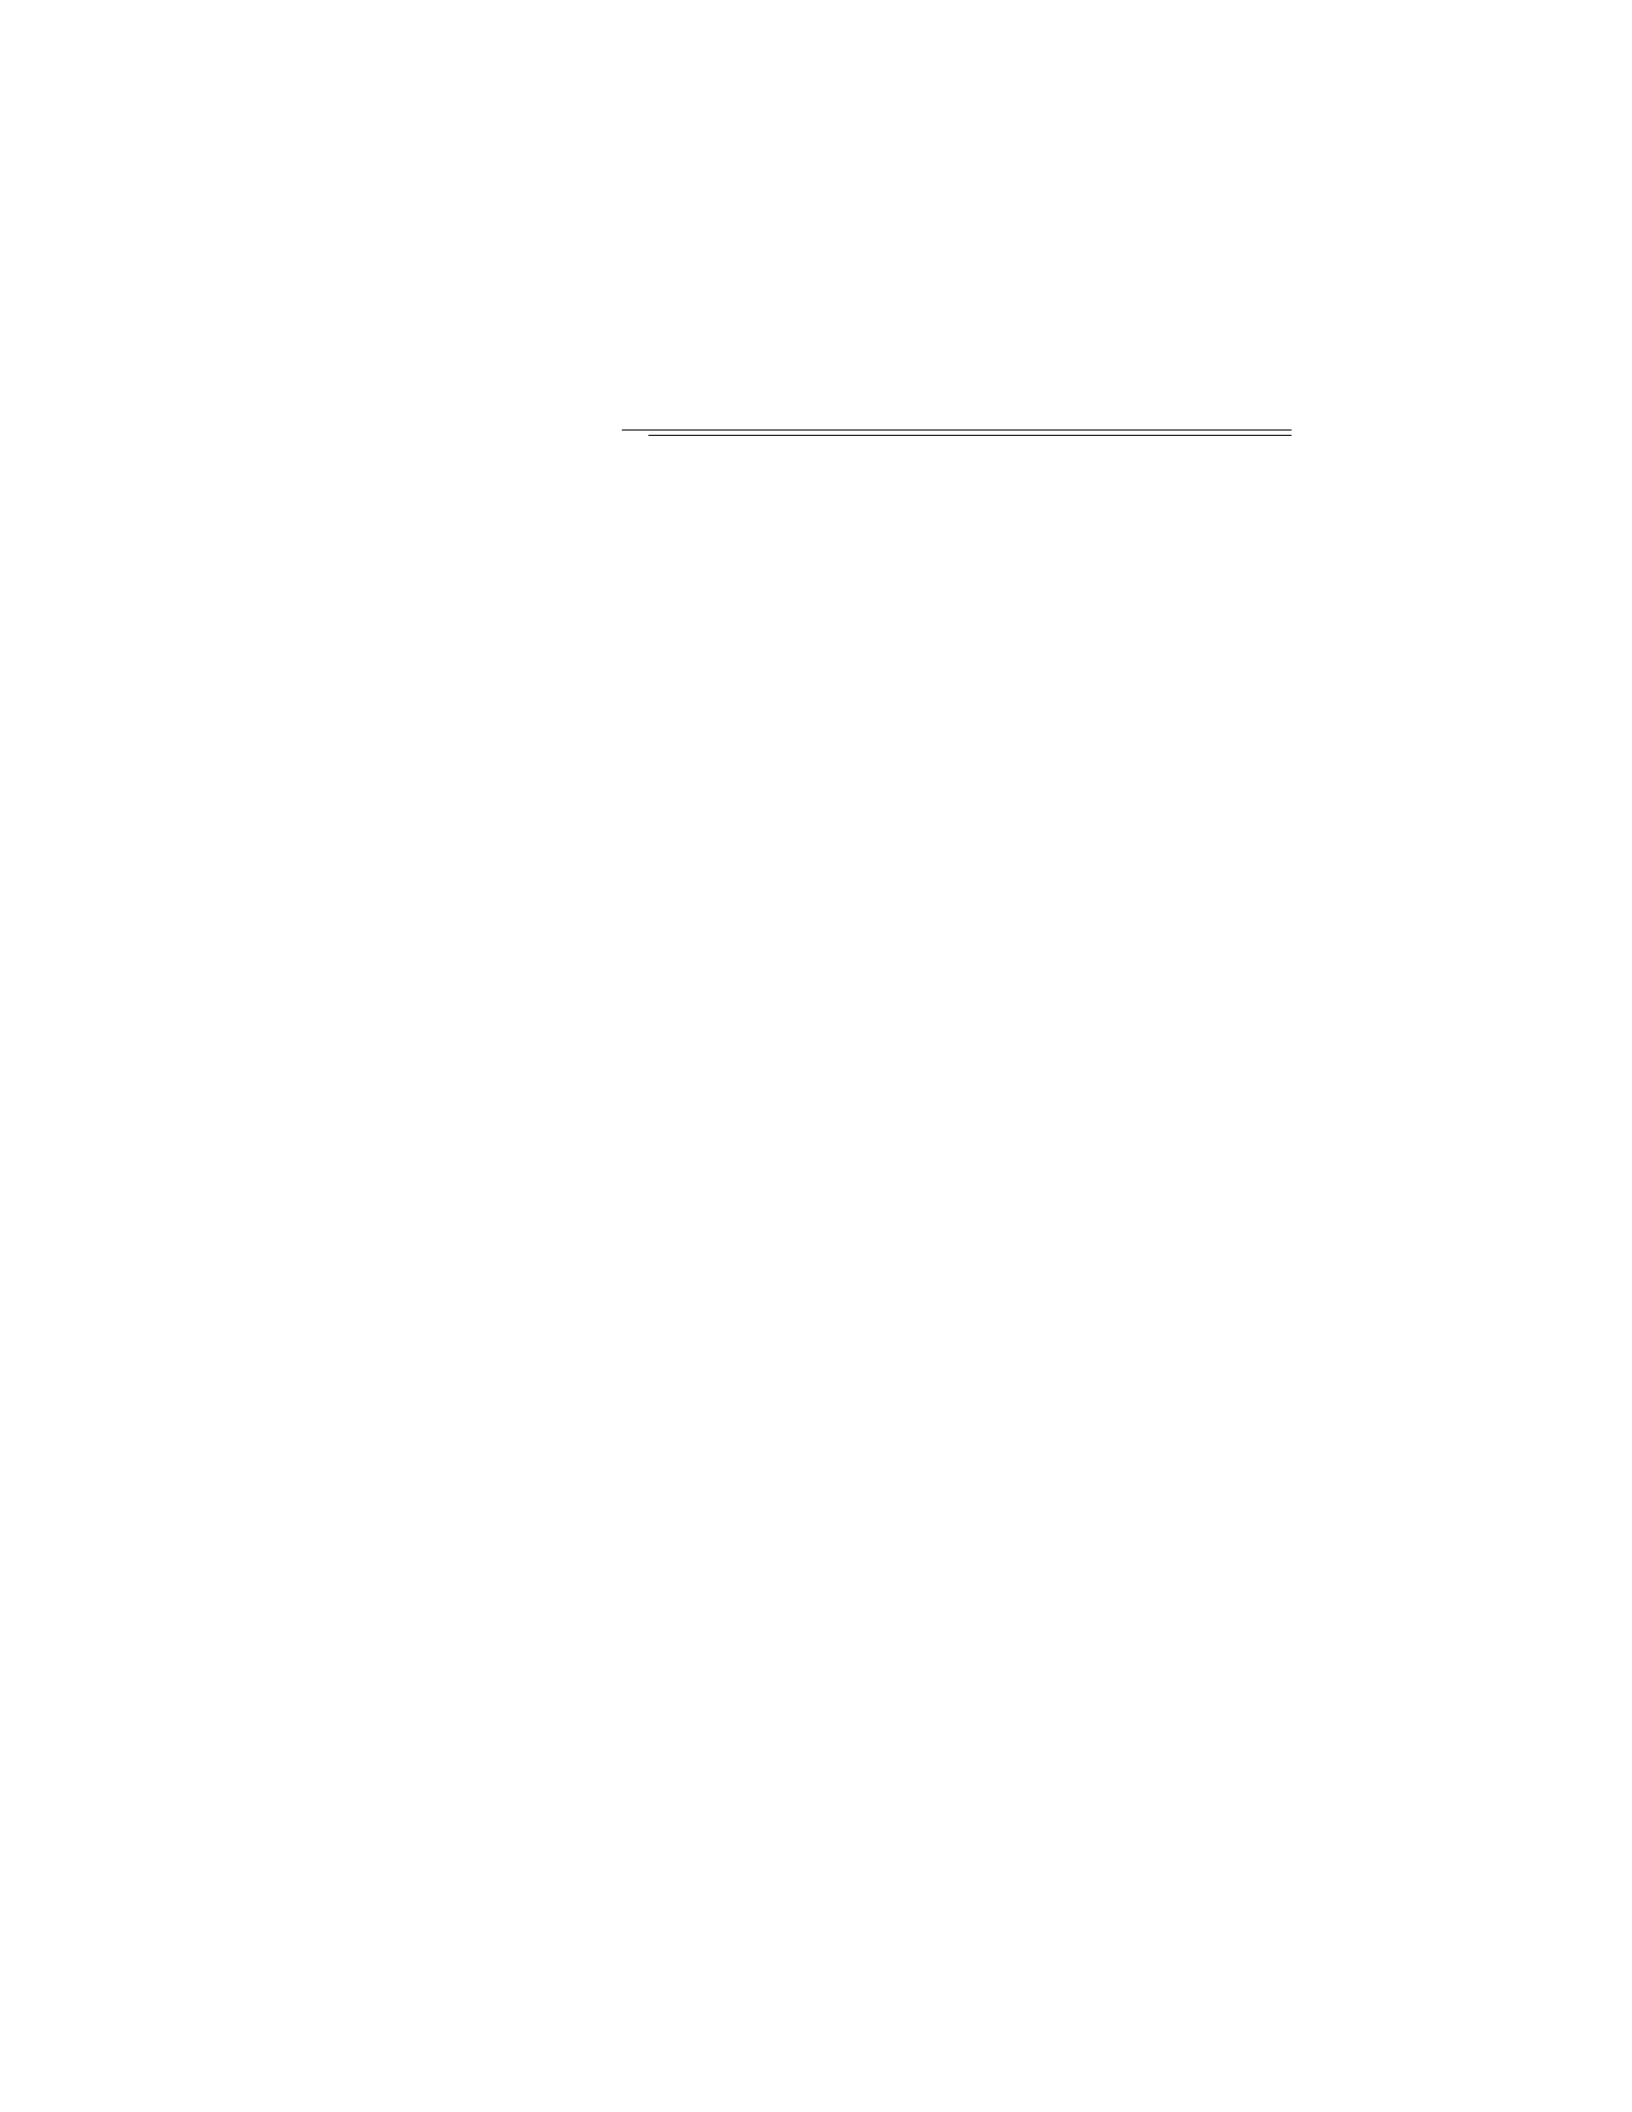
comes using a bivariate Moran’s I statistic:
Bivariate Moran’s I = Pn
i=1 Pn
j=1 wij (xi−¯x)(yj−¯y)
rPn
i=1 Pn
j=1 wij (xi−¯x)2·Pn
i=1 Pn
j=1 wij (yj−¯y)2
where: - yjis the health outcome score at region j- ¯yis the mean health
outcome score
6. Interpret the results of the bivariate Moran’s I statistic: The bivariate
Moran’s I ranges from -1 to 1. Positive values indicate positive spatial autocor-
relation (similar values close to each other), negative values indicate negative
spatial autocorrelation, and zero indicates no spatial autocorrelation.
Question 24
Question
Suppose you are given a dataset containing the coordinates (latitude and lon-
gitude) of 1000 locations in a city. You are interested in analyzing the spatial
distribution of these locations and want to fit a spatial model to predict the
location of a new point. Explain the steps you would take to conduct spatial
data analysis and modeling for this dataset.
Solution
To conduct spatial data analysis and modeling for the given dataset, follow these
steps:
Step 1: Data Exploration - Visualize the dataset by plotting the loca-
tions on a map to understand the spatial distribution. - Check for any obvious
patterns or clusters in the data.
Step 2: Spatial Autocorrelation Analysis - Evaluate the spatial auto-
correlation in the dataset using tools like Moran’s I or Geary’s C. - Determine
if there is spatial clustering, randomness, or dispersion in the data.
Step 3: Spatial Interpolation - Choose an appropriate spatial interpola-
tion method (e.g., Kriging, Inverse Distance Weighting) to predict the location
of new points. - Interpolate the data to create a continuous surface representing
the spatial distribution.
Step 4: Model Fitting - Select a spatial model that best fits the dataset
(e.g., spatial regression models, geostatistical models). - Fit the chosen model
to the data and assess its goodness of fit.
Step 5: Model Validation - Validate the spatial model using techniques
like cross-validation or comparing predicted values to actual values. - Assess
the accuracy and reliability of the model predictions.
Step 6: Prediction and Interpretation - Use the fitted spatial model to
make predictions for new locations within the study area. - Interpret the results
and make conclusions about the spatial relationships in the dataset.
23
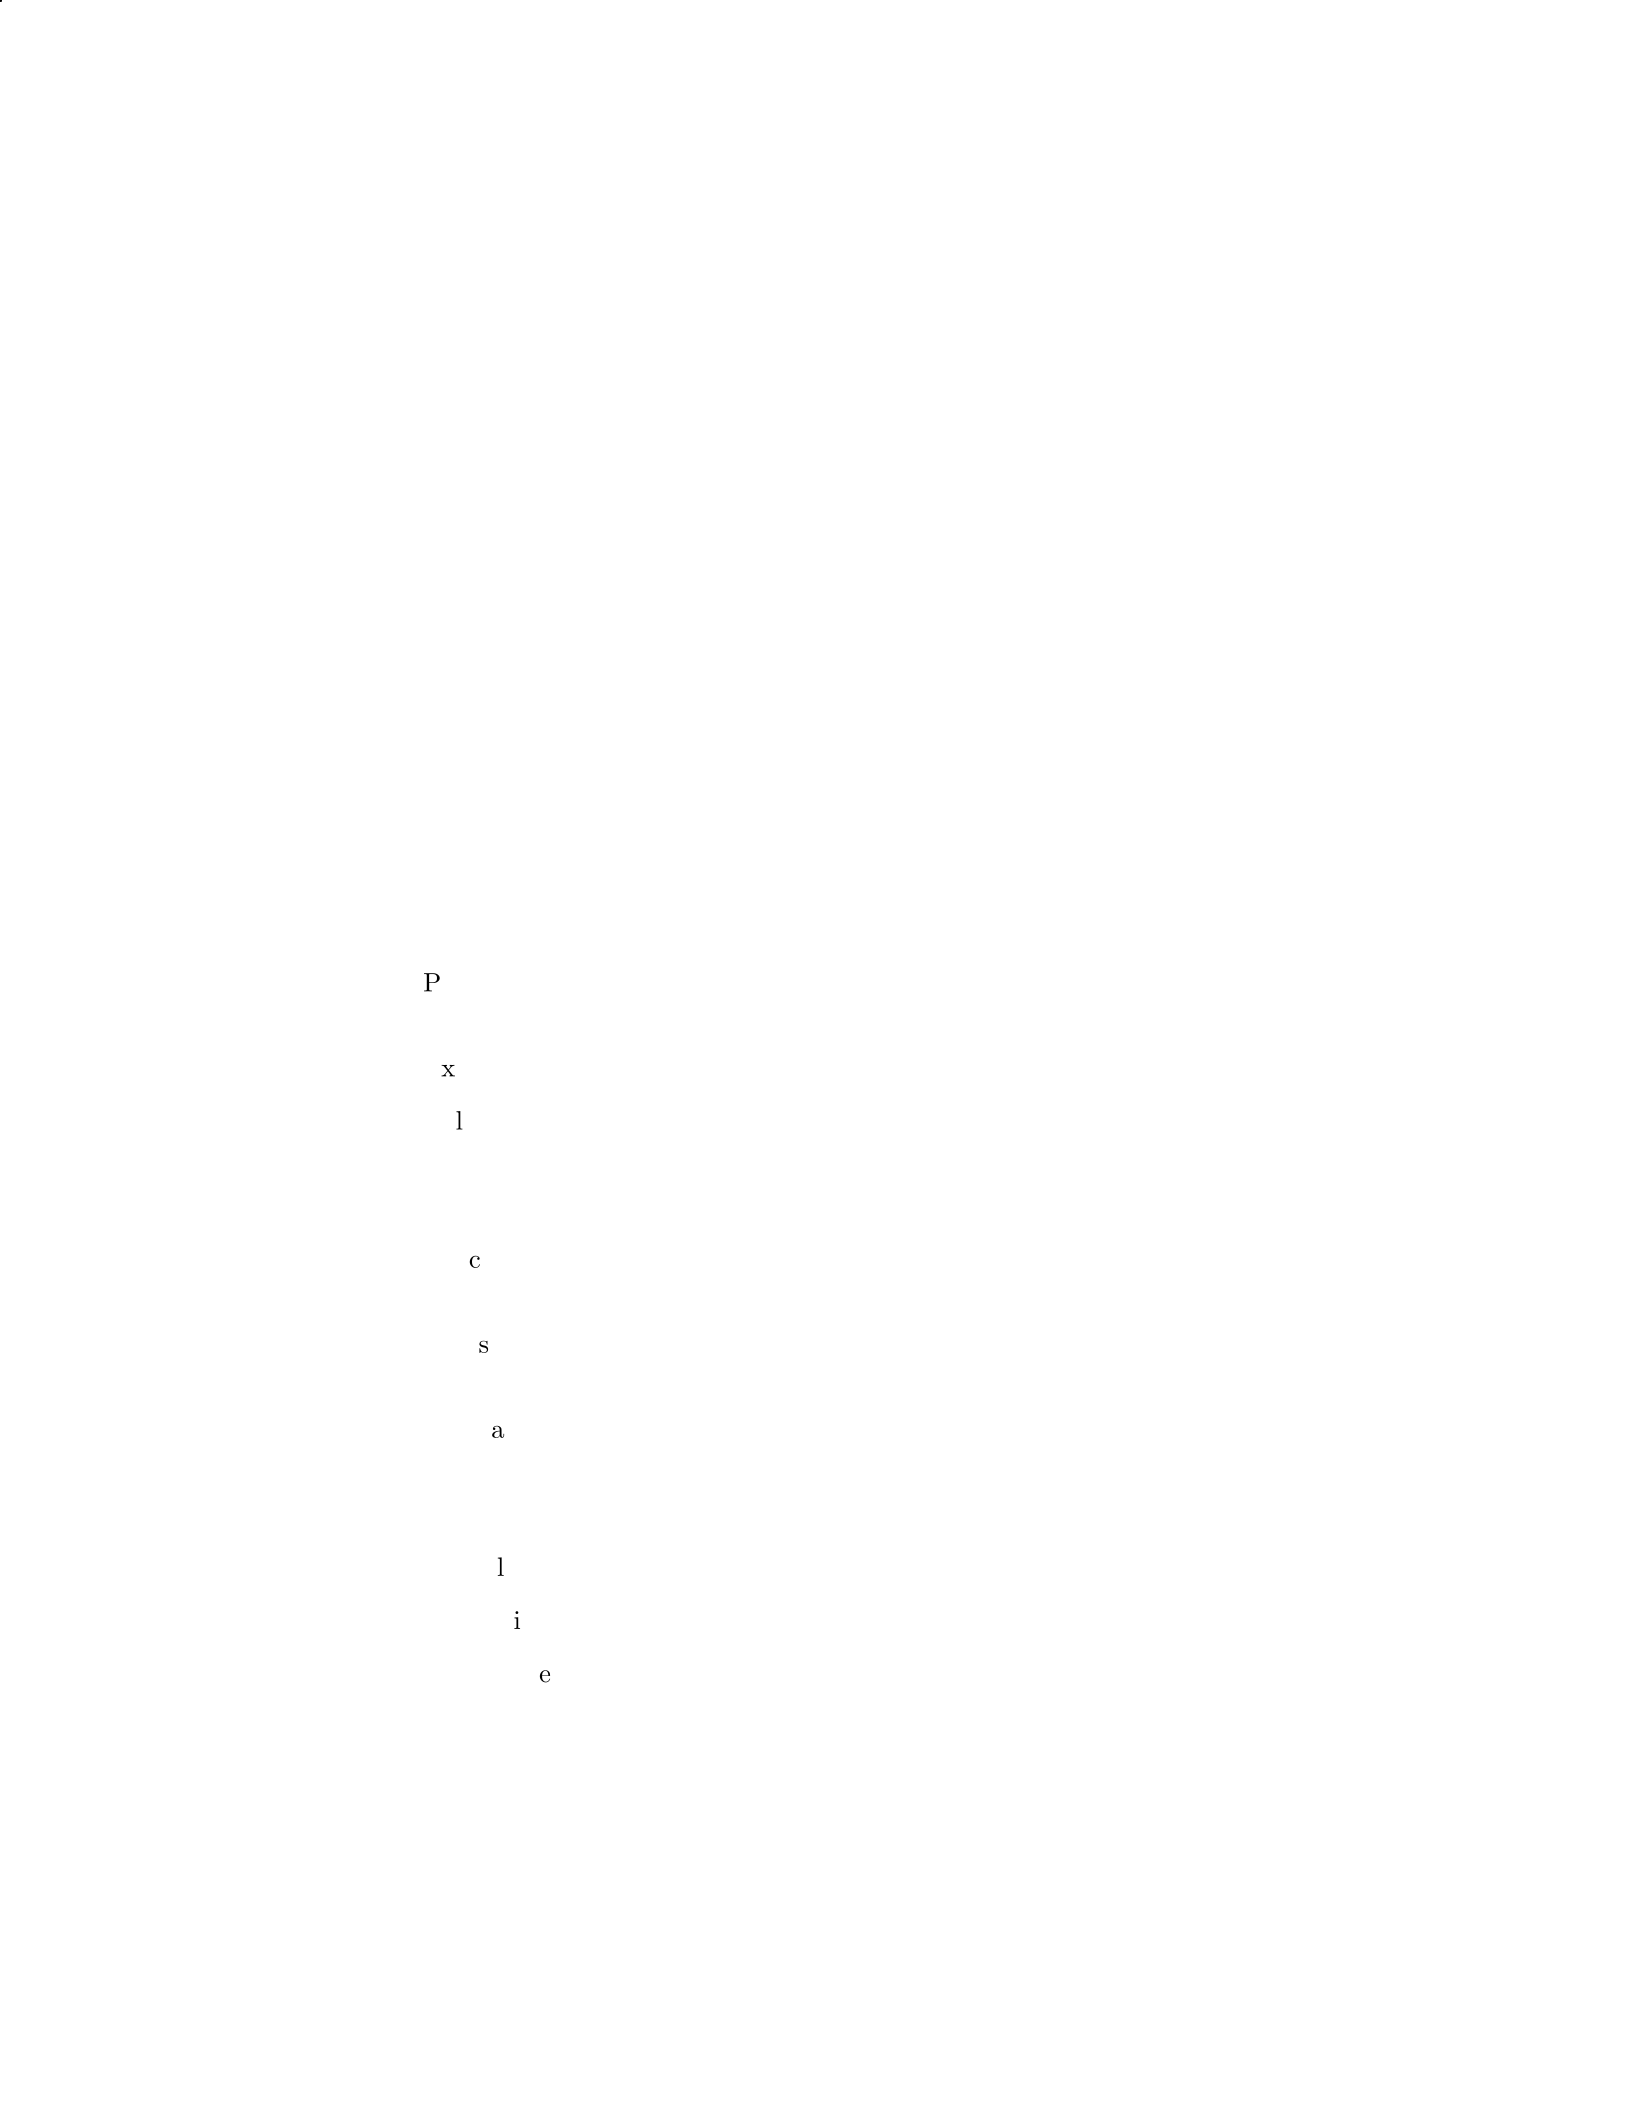
By following these steps, you can effectively conduct spatial data analysis
and modeling for the given dataset of 1000 locations in the city.
Question 25
Question
Consider a dataset consisting of the coordinates of 50 sampling points in a
forest. The goal is to build a spatial model to predict the number of trees in an
arbitrary location. Describe the step-by-step process of conducting spatial data
analysis and modeling for this scenario.
Solution
To conduct spatial data analysis and modeling for predicting the number of
trees in an arbitrary location in a forest, we can follow these steps:
Step 1: Data Collection Collect the coordinates of the 50 sampling points
and the corresponding number of trees at each location in the forest.
Step 2: Exploratory Data Analysis (EDA)
Plot the sampling points on a map to visualize the spatial distribution of
the data.
Examine the data for any outliers or missing values.
Calculate summary statistics such as mean, standard deviation, and range
for the number of trees.
Step 3: Spatial Data Preprocessing
Check for spatial autocorrelation to understand the spatial dependency of
the data.
Transform the data, if necessary, to meet modeling assumptions (e.g., log-
transform for count data).
Standardize the coordinates (e.g., using z-scores) if needed.
Step 4: Model Selection Choose an appropriate spatial model for predic-
tion. Options include:
Spatial autoregressive models (SAR)
Geostatistical models (e.g., kriging)
Machine learning models with spatial components (e.g., spatial random
forests)
Step 5: Model Fitting
24
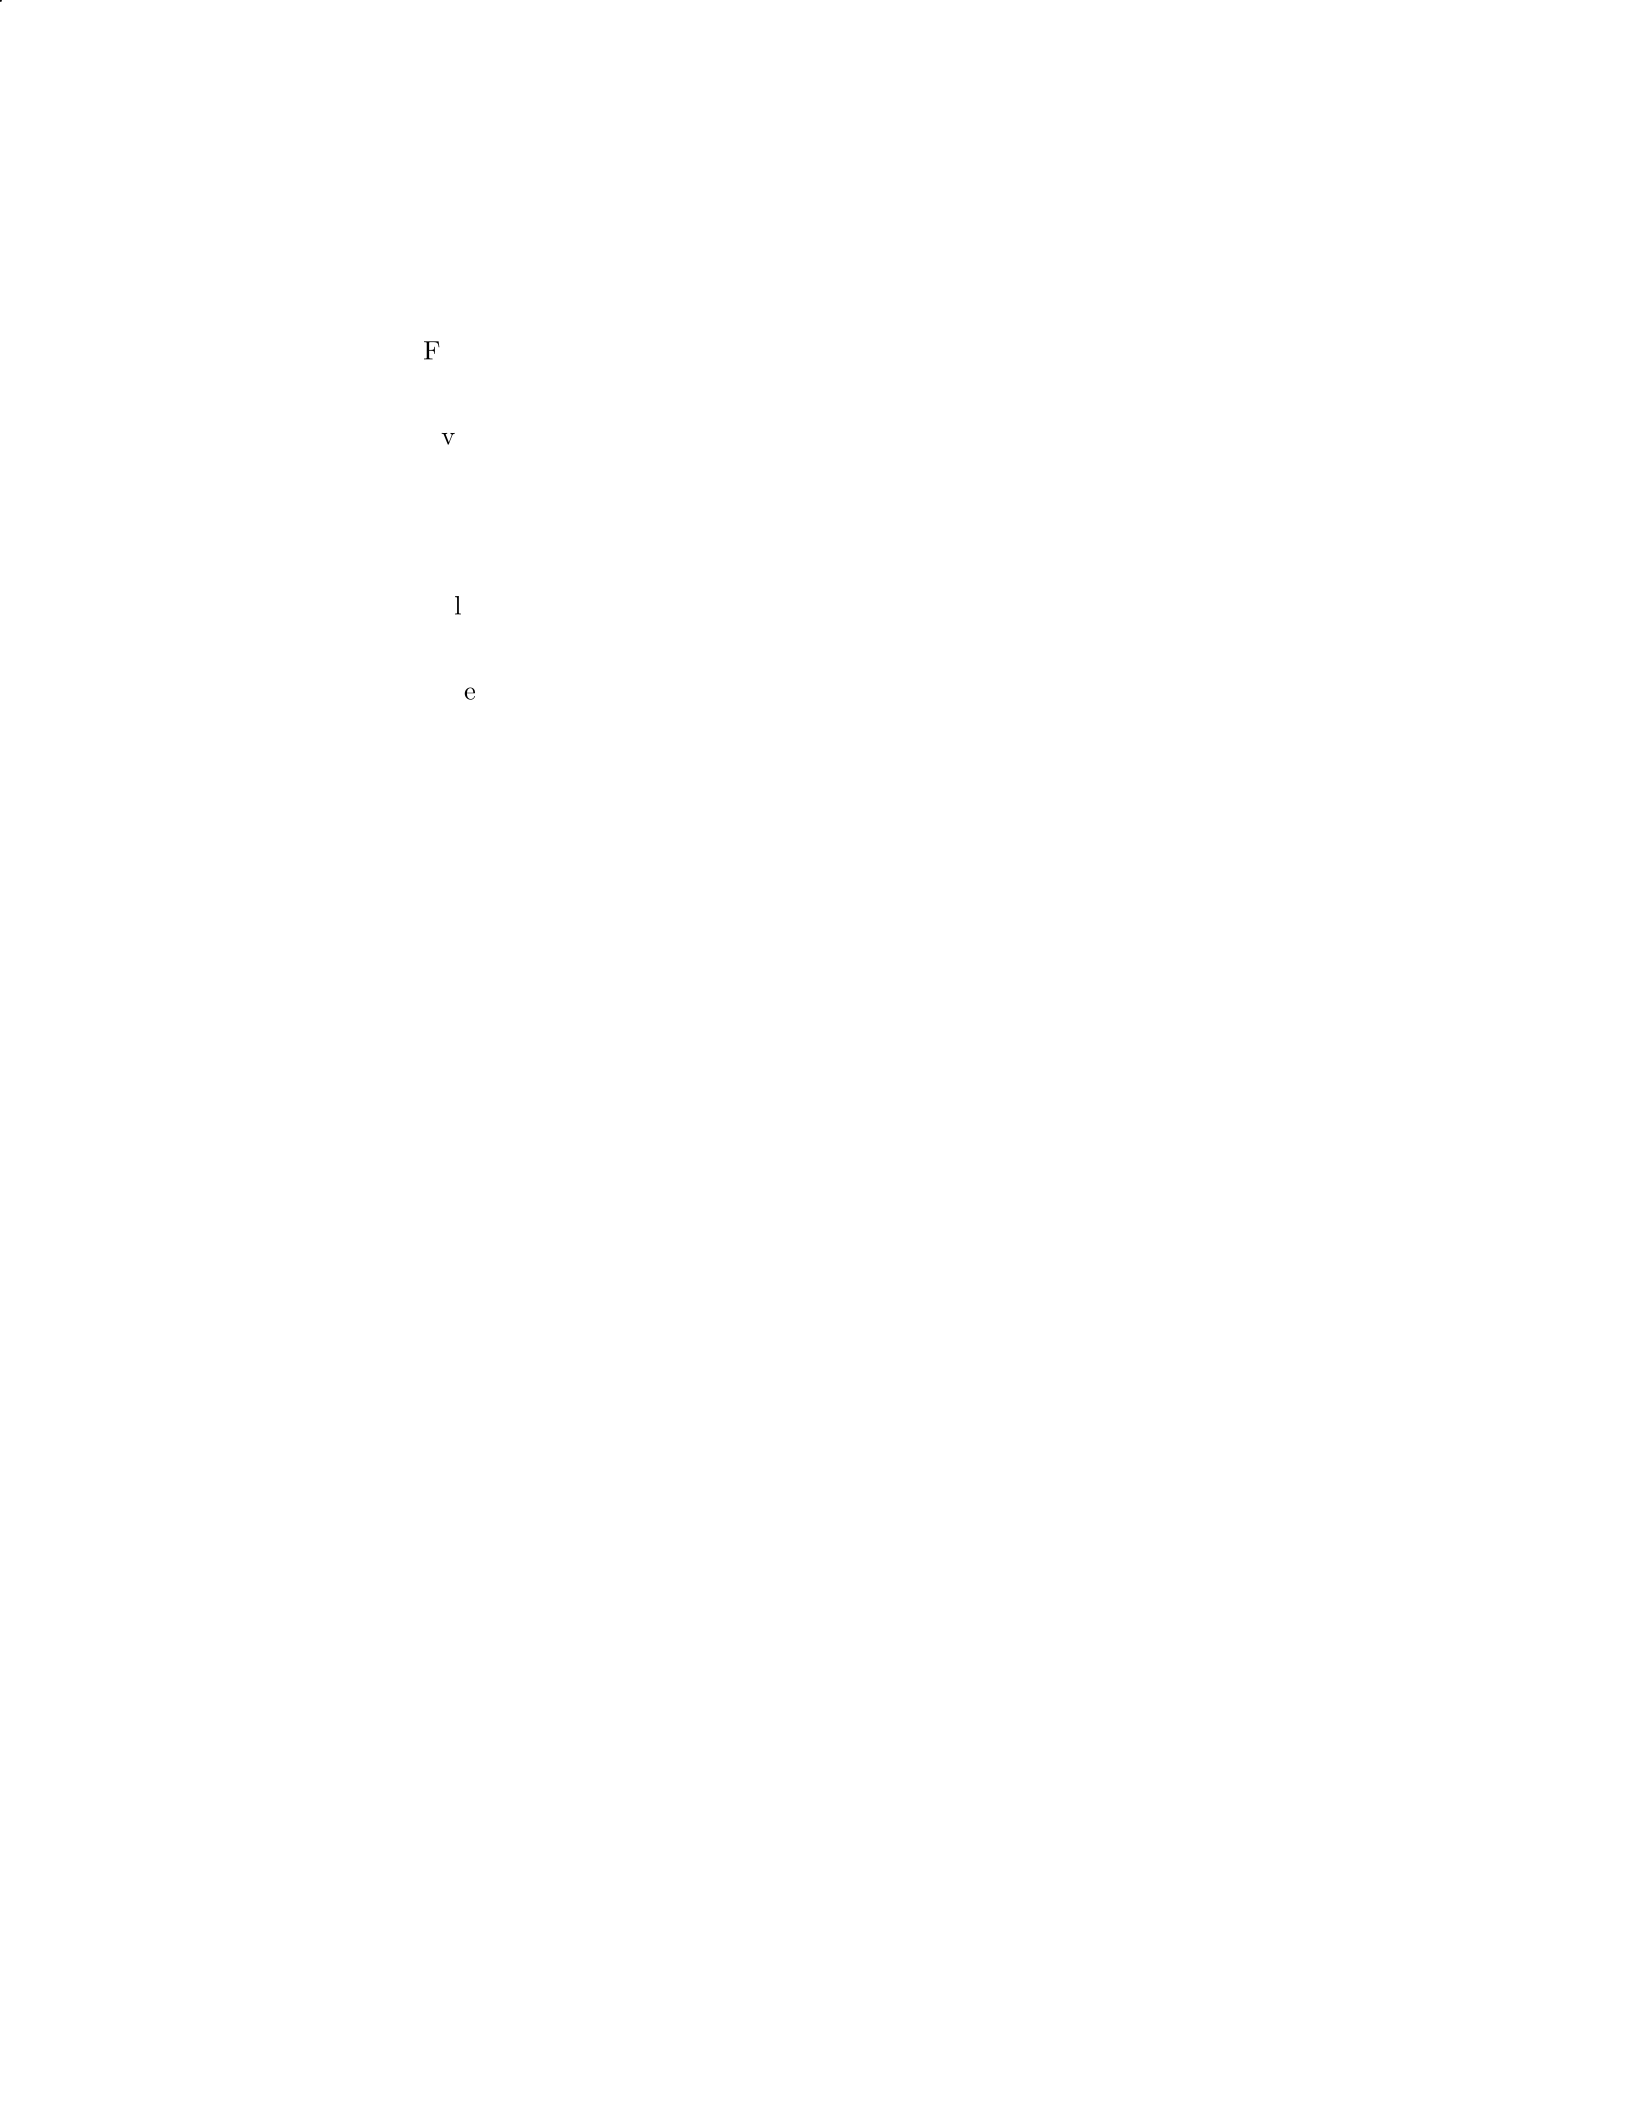
Fit the selected model to the data using appropriate software or program-
ming language.
Evaluate the model fit using diagnostic tools (e.g., residuals analysis).
Step 6: Prediction Predict the number of trees in an arbitrary location
using the fitted spatial model.
Step 7: Validation
Validate the predictive performance of the model using cross-validation or
other validation techniques.
Assess the model’s accuracy by comparing predicted values to observed
values.
Step 8: Interpretation and Application Interpret the results of the
spatial model and consider its implications for forest management or conserva-
tion efforts. Additionally, explore ways to improve the model’s accuracy and
reliability.
Question 26
Question
You are given a dataset containing the coordinates (latitude and longitude) of
100 different locations. Perform the following spatial data analysis and mod-
eling steps: 1. Create a scatter plot of the locations on a map. 2. Calculate
the distance matrix between all pairs of locations. 3. Use hierarchical cluster-
ing to group the locations based on their spatial proximity. 4. Visualize the
hierarchical clustering results using a dendrogram.
Solution
1. To create a scatter plot of the locations on a map, you need to use a mapping
tool or software that allows you to input latitude and longitude coordinates and
plot them. This can be done using Python libraries like Folium or packages in
R like ggplot2 with geompoint.
2. To calculate the distance matrix between all pairs of locations, you can use
the Haversine formula which computes the distance between two points on Earth
given their longitude and latitude. The distance matrix will be a symmetric
matrix where each element represents the distance between two locations.
3. Hierarchical clustering involves grouping data points into a hierarchy of
clusters. In this case, we will use the distance matrix to calculate the proximity
between locations and group them based on spatial similarity. The output will
be a dendrogram showing the hierarchical structure of the clusters.
4. Visualizing the hierarchical clustering results using a dendrogram will help
in understanding how locations are grouped based on their spatial proximity.
25
The dendrogram will display the clusters at different levels of similarity, showing
which locations are more closely related spatially.
Question 27
Question
Consider a dataset containing spatial information on the distribution of a rare
plant species across a region. You are tasked with analyzing this spatial data
and developing a model to predict the suitable habitats for this plant species
based on environmental variables. Describe the steps you would take to perform
spatial data analysis and modeling in this scenario.
Solution
To perform spatial data analysis and modeling for predicting suitable habitats
for a rare plant species based on environmental variables, the following steps
can be taken:
Step 1: Data Collection
Collect the spatial dataset containing information on the distribution of
the rare plant species and relevant environmental variables (e.g., temper-
ature, precipitation, soil type).
Step 2: Data Preprocessing
Clean the dataset by removing any missing or duplicate values.
Standardize or normalize the numerical variables to ensure they are on a
similar scale.
Transform the spatial data into a suitable format for analysis (e.g., spatial
polygons or points).
Step 3: Exploratory Data Analysis (EDA)
Conduct exploratory data analysis to understand the spatial distribution
of the plant species and the relationships with environmental variables.
Use visualizations such as scatter plots, maps, and spatial autocorrelation
analyses to identify patterns and correlations in the data.
Step 4: Spatial Interpolation
Use spatial interpolation techniques (e.g., kriging, inverse distance weight-
ing) to predict the distribution of the plant species across the region based
on the observed data points.
Step 5: Model Development
26
Choose an appropriate modeling technique (e.g., logistic regression, ran-
dom forest) to predict the suitable habitats for the plant species based on
the environmental variables.
Split the dataset into training and testing sets for model evaluation.
Step 6: Model Evaluation
Evaluate the performance of the model using metrics such as accuracy,
precision, recall, and area under the curve (AUC).
Make adjustments to the model if necessary based on the evaluation re-
sults.
Step 7: Model Validation
Validate the model by applying it to new data or using cross-validation
techniques to ensure its generalizability.
By following these steps, you can effectively analyze spatial data and develop
a predictive model for identifying suitable habitats for the rare plant species
based on environmental variables.
Question 28
Question
Consider a dataset consisting of the coordinates of cities in a country. The
dataset contains the following cities: City A (2,3), City B (5,7), City C (1,4),
City D (6,2), and City E (3,6). Perform spatial data analysis to determine the
city that is the farthest away from the centroid of all cities.
Solution
Step 1: Calculate the centroid of the cities.
The centroid (mean) coordinates (¯x, ¯y) of the cities can be calculated using
the formula:
¯x=xi
nand ¯y=yi
n
where (xi, yi) are the coordinates of each city and nis the total number of cities.
Calculating the centroid:
¯x=2+5+1+6+3
5= 3.4 and ¯y=3+7+4+2+6
5= 4.4
Therefore, the centroid of the cities is (3.4,4.4).
Step 2: Calculate the distance of each city from the centroid.
The Euclidean distance between two points (x1, y1) and (x2, y2) can be cal-
culated using the formula:
p(x2−x1)2+ (y2−y1)2
27
Calculating the distances of each city from the centroid: - City A: p(3.4−2)2+ (4.4−3)2=
1.14 - City B: p(3.4−5)2+ (4.4−7)2= 3.61 - City C: p(3.4−1)2+ (4.4−4)2=
2.50 - City D: p(3.4−6)2+ (4.4−2)2= 2.79 - City E: p(3.4−3)2+ (4.4−6)2=
1.41
Step 3: Identify the city farthest from the centroid.
The city farthest from the centroid is City B, with a distance of 3.61 units.
Hence, City B is the farthest away from the centroid of all cities.
Question 29
Question
In a study on spatial data analysis and modeling, a researcher collects data on
the pollution levels at various locations in a city. The researcher wants to create
a spatial model to predict pollution levels at unmeasured locations based on
the data collected. One approach is to use kriging, a geostatistical interpolation
technique. Define kriging and explain the basic steps involved in performing
kriging for spatial data analysis.
Solution
To perform kriging for spatial data analysis, the following basic steps are in-
volved:
Step 1: Data Collection and Exploration - Collect pollution level data
at various locations in the city. - Explore the spatial patterns and characteristics
of the data to understand the underlying spatial structure.
Step 2: Variogram Calculation - Calculate the semivariogram, which
measures the spatial variability or autocorrelation of the pollution levels be-
tween pairs of locations at different distances. - The semivariogram provides
information about the spatial dependence of the data and helps in determining
the appropriate model for interpolation.
Step 3: Model Fitting - Fit a variogram model to the experimental semi-
variogram obtained in Step 2. - Common variogram models include spherical,
exponential, and Gaussian models, which describe the spatial autocorrelation
structure of the data.
Step 4: Kriging Estimation - Using the variogram model fitted in Step
3, interpolate pollution levels at unmeasured locations based on the nearby
measured data points. - Kriging estimates pollution levels by optimizing a linear
combination of the measured values, giving higher weights to nearby locations
and lower weights to distant locations.
Step 5: Cross-Validation - Validate the accuracy of the kriging predic-
tions by performing cross-validation. - Compare the predicted pollution levels at
measured locations with the actual measured values to assess the performance
of the kriging model.
28

Step 6: Prediction and Visualization - Once the kriging model is vali-
dated, use it to predict pollution levels at any unsampled locations in the city.
- Visualize the predicted pollution levels on a map to identify high- and low-
pollution zones and provide insights for decision-making and policy planning.
Question 30
Question
Consider a dataset containing the location of major cities in a country, along
with their respective populations. You are tasked with analyzing the spatial
distribution of these cities to identify any underlying patterns or clusters. De-
scribe the steps you would take to conduct a spatial data analysis and modeling
of this dataset.
Solution
To conduct a spatial data analysis and modeling of the dataset containing major
cities and their populations, we can follow these steps:
Step 1: **Exploratory Data Analysis (EDA)** - Examine the dataset to
understand its structure, variables, and any missing values. - Plot the locations
of major cities on a map to visualize their spatial distribution. - Calculate basic
summary statistics for the population variable to understand its distribution.
Step 2: **Spatial Autocorrelation Analysis** - Conduct a spatial autocorre-
lation analysis to determine if there are any spatial dependencies in the dataset.
- Use methods like Moran’s I statistic to measure clustering or dispersion of
cities based on their populations.
Step 3: **Spatial Clustering Analysis** - Apply clustering algorithms such
as K-means clustering or DBSCAN to identify any spatial patterns or clusters
of cities based on their populations. - Evaluate the results to understand the
characteristics of each cluster.
Step 4: **Spatial Regression Modeling** - Perform spatial regression model-
ing to analyze the relationship between the population of cities and their spatial
attributes. - Use techniques like spatial lag or spatial error models to account
for spatial dependencies in the data.
Step 5: **Prediction and Visualization** - Use the developed spatial model
to predict the population of cities at unobserved locations. - Visualize the
predicted values on a map to understand the spatial distribution of population
more effectively.
By following these steps, we can conduct a comprehensive spatial data anal-
ysis and modeling of the dataset containing major cities and their populations,
thereby revealing any underlying patterns or clusters in their spatial distribu-
tion.
29

Question 2
Question
Consider a dataset containing the spatial coordinates (latitude and longitude)
of 100 different locations. You are tasked with analyzing this spatial data to
identify any spatial patterns or clusters. Discuss the steps you would take to
analyze this dataset using spatial data analysis and modeling techniques.
Solution
To analyze the spatial dataset containing the coordinates of 100 locations, we
can follow these steps: Step 1: Data Preparation Step 2: Exploratory Spatial
Data Analysis (ESDA) Step 3: Spatial Autocorrelation Analysis Step 4: Spatial
Clustering Analysis Step 5: Spatial Interpolation
Step 1: Data Preparation 1.1 Convert latitude and longitude coordinates
to a spatial object (e.g., points). 1.2 Check for missing or inconsistent data and
address them accordingly. 1.3 Define the spatial extent and projection of the
dataset.
Step 2: Exploratory Spatial Data Analysis (ESDA) 2.1 Calculate
the spatial weights matrix to define spatial relationships. 2.2 Calculate basic
descriptive statistics of the dataset including mean center, standard distance,
etc. 2.3 Create spatial plots (e.g., scatterplots, histograms) to visualize the
spatial distribution.
Step 3: Spatial Autocorrelation Analysis 3.1 Calculate spatial auto-
correlation measures (e.g., Moran’s I, Geary’s C) to assess spatial dependency.
3.2 Evaluate the significance of spatial autocorrelation measures.
Step 4: Spatial Clustering Analysis 4.1 Perform spatial clustering al-
gorithms (e.g., K-means, DBSCAN) to identify spatial patterns or clusters. 4.2
Evaluate the quality of spatial clusters using cluster validity indices.
Step 5: Spatial Interpolation 5.1 Apply spatial interpolation techniques
(e.g., kriging, IDW) to predict values at unsampled locations. 5.2 Validate the
accuracy of the interpolated values using cross-validation techniques.
By following these steps, we can effectively analyze the spatial dataset to
identify any spatial patterns or clusters present in the data.
Question 3
Question
Assume you have a dataset containing the locations of different tree species in
a forest. You want to analyze the spatial pattern of these tree species to better
understand their distribution. Describe the steps you would take to conduct a
spatial data analysis and modeling of this dataset.
2
Solution
To conduct a spatial data analysis and modeling of the dataset containing the
locations of different tree species in a forest, you can follow the steps outlined
below:
Step 1: Data Preprocessing
Remove any duplicate or irrelevant data points.
Check for and handle missing values in the dataset.
Step 2: Exploratory Spatial Data Analysis (ESDA)
Calculate basic statistics such as mean, median, and range of tree species
distributions.
Plot the locations of different tree species on a map to visualize spatial
patterns.
Use tools like Moran’s I and Geary’s C to assess spatial autocorrelation.
Step 3: Spatial Data Modeling
Choose an appropriate spatial data model based on the dataset charac-
teristics (e.g., point pattern analysis, spatial regression).
Implement the selected model to analyze the spatial relationships between
different tree species.
Step 4: Model Validation
Validate the spatial data model using techniques like cross-validation or
goodness-of-fit tests.
Check the residuals for any patterns or anomalies.
Step 5: Interpretation and Reporting
Interpret the results of the spatial data analysis in the context of the
research question.
Prepare a report summarizing the findings and recommendations based
on the analysis.
Question 4
Question
A city planner is interested in analyzing the spatial distribution of air pollution
levels in a particular city. She collects air quality data from 100 monitoring
stations located throughout the city. Using spatial data analysis techniques, she
wants to create a model that predicts air pollution levels at locations without
monitoring stations based on the data collected.
Describe the steps she should take to analyze the spatial data and create a
predictive model for air pollution levels in the city.
3

Solution
To analyze the spatial data and create a predictive model for air pollution levels
in the city, the city planner should follow these steps:
Step 1: Data Exploration - Examine the distribution of air pollution
levels at monitoring stations. - Check for any spatial patterns in the data. -
Determine if there are any outliers or missing values.
Step 2: Spatial Autocorrelation Analysis - Conduct a spatial autocor-
relation analysis to determine if air pollution levels exhibit spatial dependence.
- Use tools like Moran’s I or Geary’s C to assess spatial autocorrelation.
Step 3: Spatial Interpolation - Use spatial interpolation techniques (e.g.,
kriging, inverse distance weighting) to predict air pollution levels at locations
without monitoring stations. - Validate the interpolation results using cross-
validation techniques.
Step 4: Model Building - Select appropriate predictors (e.g., land use,
traffic density) that may influence air pollution levels. - Use regression analysis
or machine learning algorithms to build a predictive model for air pollution
levels. - Evaluate the model’s performance using metrics like R-squared, Mean
Squared Error (MSE), and Root Mean Squared Error (RMSE).
Step 5: Model Validation - Validate the predictive model using tech-
niques like cross-validation to assess its accuracy and generalizability. - Make
adjustments to the model if necessary based on validation results.
Step 6: Spatial Visualization - Create spatial visualizations (e.g., maps,
heatmaps) to present the predicted air pollution levels across the city. - Identify
areas with high pollution levels for targeted interventions or policy recommen-
dations.
Question 5
Question
A city planner is analyzing traffic flow in a city and has collected spatial data
on traffic congestion at various locations. The dataset includes the geographical
coordinates of each location and the level of congestion (ranging from 1 to 10)
at each location. The planner wants to create a spatial model to predict traffic
congestion levels at new locations based on the existing data. Explain how
spatial autocorrelation and spatial regression could be used in this scenario.
Solution
Step 1: Spatial Autocorrelation Spatial autocorrelation refers to the degree
to which nearby locations in space are similar to each other regarding a certain
attribute. In this scenario, spatial autocorrelation can be used to identify if there
is a pattern in the traffic congestion levels that is related to the spatial locations.
This can help the city planner determine if there are clusters of locations with
4

similar congestion levels, which can be useful for predicting congestion at new
locations based on their proximity to existing congested areas.
Step 2: Spatial Regression Spatial regression is a statistical technique that
explicitly considers the spatial relationships between observations. In the con-
text of traffic congestion analysis, spatial regression can be employed to model
the relationship between traffic congestion levels and spatial factors such as prox-
imity to highways, population density, or commercial areas. By incorporating
spatial information into the regression model, the planner can better account for
spatial dependencies in the data and improve the accuracy of congestion level
predictions at new locations.
In summary, by using spatial autocorrelation to identify spatial patterns in
traffic congestion data and employing spatial regression to model the relation-
ship between congestion levels and spatial factors, the city planner can create
a robust spatial model for predicting traffic congestion at new locations in the
city.
Question 6
Question
Consider a dataset containing locations of 100 different trees in a forest. Each
tree is characterized by its species, height, diameter, and age. Perform a spatial
data analysis and modeling to determine if there is a spatial pattern in the
distribution of tree species in the forest.
Solution
To determine if there is a spatial pattern in the distribution of tree species in
the forest, we can perform spatial data analysis using Ripley’s K-function. The
steps to accomplish this are as follows:
Step 1: Define the Problem We want to investigate if the distribution
of tree species in the forest exhibits any spatial pattern. Specifically, we want
to determine if the spatial distribution is random, clustered, or dispersed.
Step 2: Data Preparation Prepare the dataset containing the locations
of the trees along with their respective species information. Ensure that the
data is clean and ready for spatial analysis.
Step 3: Calculate Ripley’s K-function Calculate Ripley’s K-function for
each tree species in the dataset. The Ripley’s K-function measures the spatial
clustering or dispersion of points in a given area.
Step 4: Compare Observed vs. Expected K-function Plot the ob-
served K-function against the expected K-function under a complete spatial
randomness (CSR) assumption. If the observed K-function is higher than the
expected function, it indicates clustering. If it is lower, it indicates dispersion.
Step 5: Statistical Analysis Perform a statistical test to determine the
significance of the spatial pattern observed. This can be done using Monte Carlo
5
simulation or other appropriate methods.
Step 6: Interpret Results Based on the analysis and statistical tests
conducted, make conclusions about the presence and nature of spatial patterns
in the distribution of tree species in the forest.
By following these steps, we can effectively analyze the spatial distribution
of tree species in the forest and determine if there is a significant spatial pattern
present.
Question 7
Question
Consider a dataset containing information about the elevation of different loca-
tions in a region. The dataset consists of 1000 data points, each representing a
specific location in the region with its corresponding elevation in meters. You
are tasked with analyzing and modeling the spatial variation in elevation across
the region using statistical methods.
Perform the following steps: 1. Create a spatial plot of the elevation data
points to visualize the spatial distribution. 2. Compute the sample mean and
sample standard deviation of the elevation values. 3. Perform spatial autocor-
relation analysis to determine if there is any spatial dependence in the elevation
data. 4. Fit a spatial regression model to predict elevation based on the coor-
dinates (latitude and longitude) of the locations. 5. Evaluate the goodness of
fit of the spatial regression model and interpret the results.
Solution
1. Create a spatial plot of the elevation data points to visualize the spatial
distribution.
Use a software package like R or Python with appropriate libraries to
create a scatter plot of the elevation data points on a map of the region.
Color code the data points based on their elevation values to visualize the
spatial distribution.
Ensure the axes represent latitude and longitude coordinates.
2. Compute the sample mean and sample standard deviation of the elevation
values.
Calculate the sample mean using the formula: ¯x=1
nPn
i=1 xi, where xi
represents individual elevation values.
Calculate the sample standard deviation using the formula: s=q1
n−1Pn
i=1(xi−¯x)2.
3. Perform spatial autocorrelation analysis to determine if there is any spa-
tial dependence in the elevation data.
6
Use Moran’s I statistic to measure spatial autocorrelation.
Calculate Moran’s I using the formula: I=n
Pn
i=1 Pn
j=1 wij (xi−¯x)(xj−¯x)/Pn
i=1(xi−¯x)2,
where wij is the spatial weight between locations iand j.
Interpret the Moran’s I value to determine the presence and strength of
spatial autocorrelation.
4. Fit a spatial regression model to predict elevation based on the coordinates
(latitude and longitude) of the locations.
Use spatial regression techniques like spatial lag or spatial error models.
Specify a suitable spatial weight matrix based on the spatial relationships
between locations.
Fit the spatial regression model and examine the coefficients of latitude
and longitude to assess their impact on elevation.
5. Evaluate the goodness of fit of the spatial regression model and interpret
the results.
Use metrics such as R-squared, AIC, BIC to evaluate the model fit.
Analyze the residuals to check for any patterns or spatial autocorrelation.
Interpret the coefficients of the spatial regression model and assess the
significance of predictors.
Question 8
Question
Suppose you are given a dataset containing spatial coordinates (longitude and
latitude) of 100 different locations. The dataset also includes a variable repre-
senting the elevation at each location. You are asked to build a spatial model
to predict the elevation at a new, previously unobserved location. Describe the
steps you would take to build such a model.
Solution
To build a spatial model for predicting the elevation at a new location, we can
follow these steps:
Step 1: Exploratory Data Analysis - Begin by exploring the dataset to
understand the distribution of elevation values and the spatial patterns present.
- Plot the elevation values on a map to visualize any spatial trends or patterns.
- Check for any outliers or missing data that may need to be addressed.
Step 2: Spatial Autocorrelation Analysis - Conduct a spatial autocor-
relation analysis to determine if the elevation values exhibit spatial dependence.
7

- Use spatial autocorrelation measures like Moran’s I or Geary’s C to quantify
the level of spatial autocorrelation.
Step 3: Spatial Interpolation - Choose an appropriate spatial interpo-
lation method to predict elevation values at unsampled locations. - Common
interpolation methods include Kriging, Inverse Distance Weighting, and Spline
Interpolation. - Evaluate the chosen interpolation method by cross-validation
or comparing predicted values to observed values.
Step 4: Model Building - Select a suitable statistical model to predict
elevation values based on spatial coordinates. - Consider models such as spatial
regression models or machine learning algorithms that can incorporate spatial
dependencies. - Use techniques like cross-validation to assess the model’s per-
formance and ensure it generalizes well to new locations.
Step 5: Model Validation - Validate the spatial model using independent
validation datasets or techniques like cross-validation. - Evaluate the model’s
predictive performance by comparing predicted elevation values to observed
values at new locations. - Assess the model’s accuracy, precision, and robustness
to ensure it provides reliable predictions.
By following these steps, you can build a spatial model to predict elevation
values at new, previously unobserved locations based on the available dataset
of spatial coordinates and elevation values.
Question 9
Question
Suppose you are given a dataset containing the coordinates of 100 random points
in a two-dimensional space. The dataset also includes a binary variable indi-
cating whether each point belongs to a certain region of interest or not. You
are tasked with building a model to predict whether a new point with given
coordinates belongs to the region of interest. Describe the steps you would take
to create and validate this model.
Solution
To build and validate a model for predicting whether a new point belongs to
the region of interest, we can follow the steps below:
Step 1: Data Preparation - Split the given dataset into a training set (typ-
ically 70-80- Standardize or normalize the coordinates of the points if needed. -
Review the dataset to check for any missing values or outliers and handle them
appropriately.
Step 2: Feature Selection - Identify relevant features that can help predict
whether a point belongs to the region of interest. This may include distance-
based features, clustering information, or spatial trends.
Step 3: Model Selection - Choose an appropriate spatial data model for
the prediction task. This could include models like k-Nearest Neighbors, Sup-
8

port Vector Machines, Decision Trees, Random Forest, etc. - Consider if any
specialized spatial analysis libraries are needed for the chosen model.
Step 4: Model Training - Train the selected model using the training set.
Fit the model to the training data to learn the relationships between the features
and the binary variable indicating region of interest.
Step 5: Model Evaluation - Use the testing set to evaluate the perfor-
mance of the trained model. Common evaluation metrics for classification tasks
include accuracy, precision, recall, F1 score, and confusion matrix. - Check for
overfitting by comparing the model performance on the training set and the
testing set.
Step 6: Model Tuning - If the model performance is not satisfactory,
consider tuning hyperparameters or modifying the feature set to improve the
model’s predictive power. - Use techniques like cross-validation to fine-tune the
model.
Step 7: Model Deployment - Once satisfied with the model’s performance,
deploy it to predict whether new points belong to the region of interest based
on their coordinates.
By following these steps, you can create and validate a model for predicting
whether a new point belongs to a specific region of interest based on spatial
data analysis and modeling.
Question 10
Question
Consider a dataset consisting of the elevation measurements at various locations
on a mountain. The dataset contains the elevation values (in meters) and the
corresponding x and y coordinates (in kilometers) of the measurement locations.
Given the dataset, perform the following steps: 1. Fit a spatial trend model
to the data using a second-order polynomial regression with interaction terms. 2.
Evaluate the goodness of fit of the model by calculating the R-squared value. 3.
Use the fitted model to predict the elevation at a new location with x-coordinate
2.5 km and y-coordinate 3.5 km.
(Note: Assume that the data satisfies the assumptions of the spatial trend
model.)
Solution
1. Fit a spatial trend model to the data using a second-order polynomial re-
gression with interaction terms. Let Zbe the elevation, and Xand Ybe the x
and y coordinates, respectively. The second-order polynomial regression model
with interaction terms is given by:
Z=β0+β1X+β2Y+β3X2+β4Y2+β5XY
2. Evaluate the goodness of fit of the model by calculating the R-squared
value. The R-squared value, denoted as R2, measures the proportion of the
9
variance in the dependent variable (elevation) that is predictable from the in-
dependent variables (coordinates). It is calculated as:
R2= 1 −SSresiduals
SStotal
where SSresiduals is the sum of squared residuals and SStotal is the total sum of
squares.
3. Use the fitted model to predict the elevation at a new location with x-
coordinate 2.5 km and y-coordinate 3.5 km. Substitute the values X= 2.5 km
and Y= 3.5 km into the fitted model to obtain the predicted elevation at the
new location.
This process provides a comprehensive analysis of the spatial data by fitting
a spatial trend model, evaluating its goodness of fit, and making predictions at
new locations based on the model.
Question 11
Question
A city planner is analyzing traffic patterns in a large metropolitan area. The
planner collects spatial data on traffic volume at various intersections and wants
to model the relationship between traffic volume and several predictor variables
such as population density, distance to major highways, and proximity to public
transportation hubs.
Describe how the city planner can perform spatial data analysis and model-
ing to achieve this goal.
Solution
To model the relationship between traffic volume and predictor variables in a
spatial context, the city planner can follow these steps for spatial data analysis
and modeling:
Step 1: Data Collection
Collect spatial data on traffic volume at intersections, population density,
distance to major highways, and proximity to public transportation hubs.
Ensure that the data is accurate, relevant, and covers the entire study
area.
Step 2: Data Preprocessing
Clean the collected data to remove any errors or inconsistencies.
Convert the data into a suitable format for spatial analysis (e.g., shapefiles,
geodatabases).
Step 3: Exploratory Spatial Data Analysis (ESDA)
10
Conduct exploratory spatial data analysis to identify spatial patterns and
relationships between variables.
Use tools such as Moran’s I, spatial autocorrelation, and spatial lag to
assess spatial dependencies.
Step 4: Spatial Regression Modeling
Perform spatial regression analysis to model the relationship between traf-
fic volume and predictor variables.
Choose an appropriate spatial regression model such as spatial lag model
or spatial error model.
Step 5: Model Evaluation
Evaluate the goodness of fit of the spatial regression model using metrics
like R-squared, AIC, and BIC.
Perform diagnostics to check for issues such as spatial autocorrelation,
multicollinearity, and heteroscedasticity.
Step 6: Interpretation and Visualization
Interpret the coefficients of the spatial regression model to understand the
relationship between traffic volume and predictor variables.
Visualize the results using maps, charts, and plots to communicate findings
effectively.
By following these steps, the city planner can effectively analyze traffic pat-
terns in the metropolitan area and create a spatial model that can inform future
transportation planning decisions.
Question 12
Question
Let Xand Ybe two spatial point patterns in a region Wwith intensity functions
λX(u) and λY(u), respectively. Consider the following expression for the cross
K-function of the superposition of Xand a transformed version of Y:
KX,τ Y (r) = λX∗gτ(r) + λY∗g−τ(r)−r
|W|
where gτ(r) is the pair correlation function of Xevaluated at distance rand at
angle τ,|W|denotes the area of region W, and ∗represents spatial convolution.
Show that this expression satisfies the fundamental property of K-functions.
11
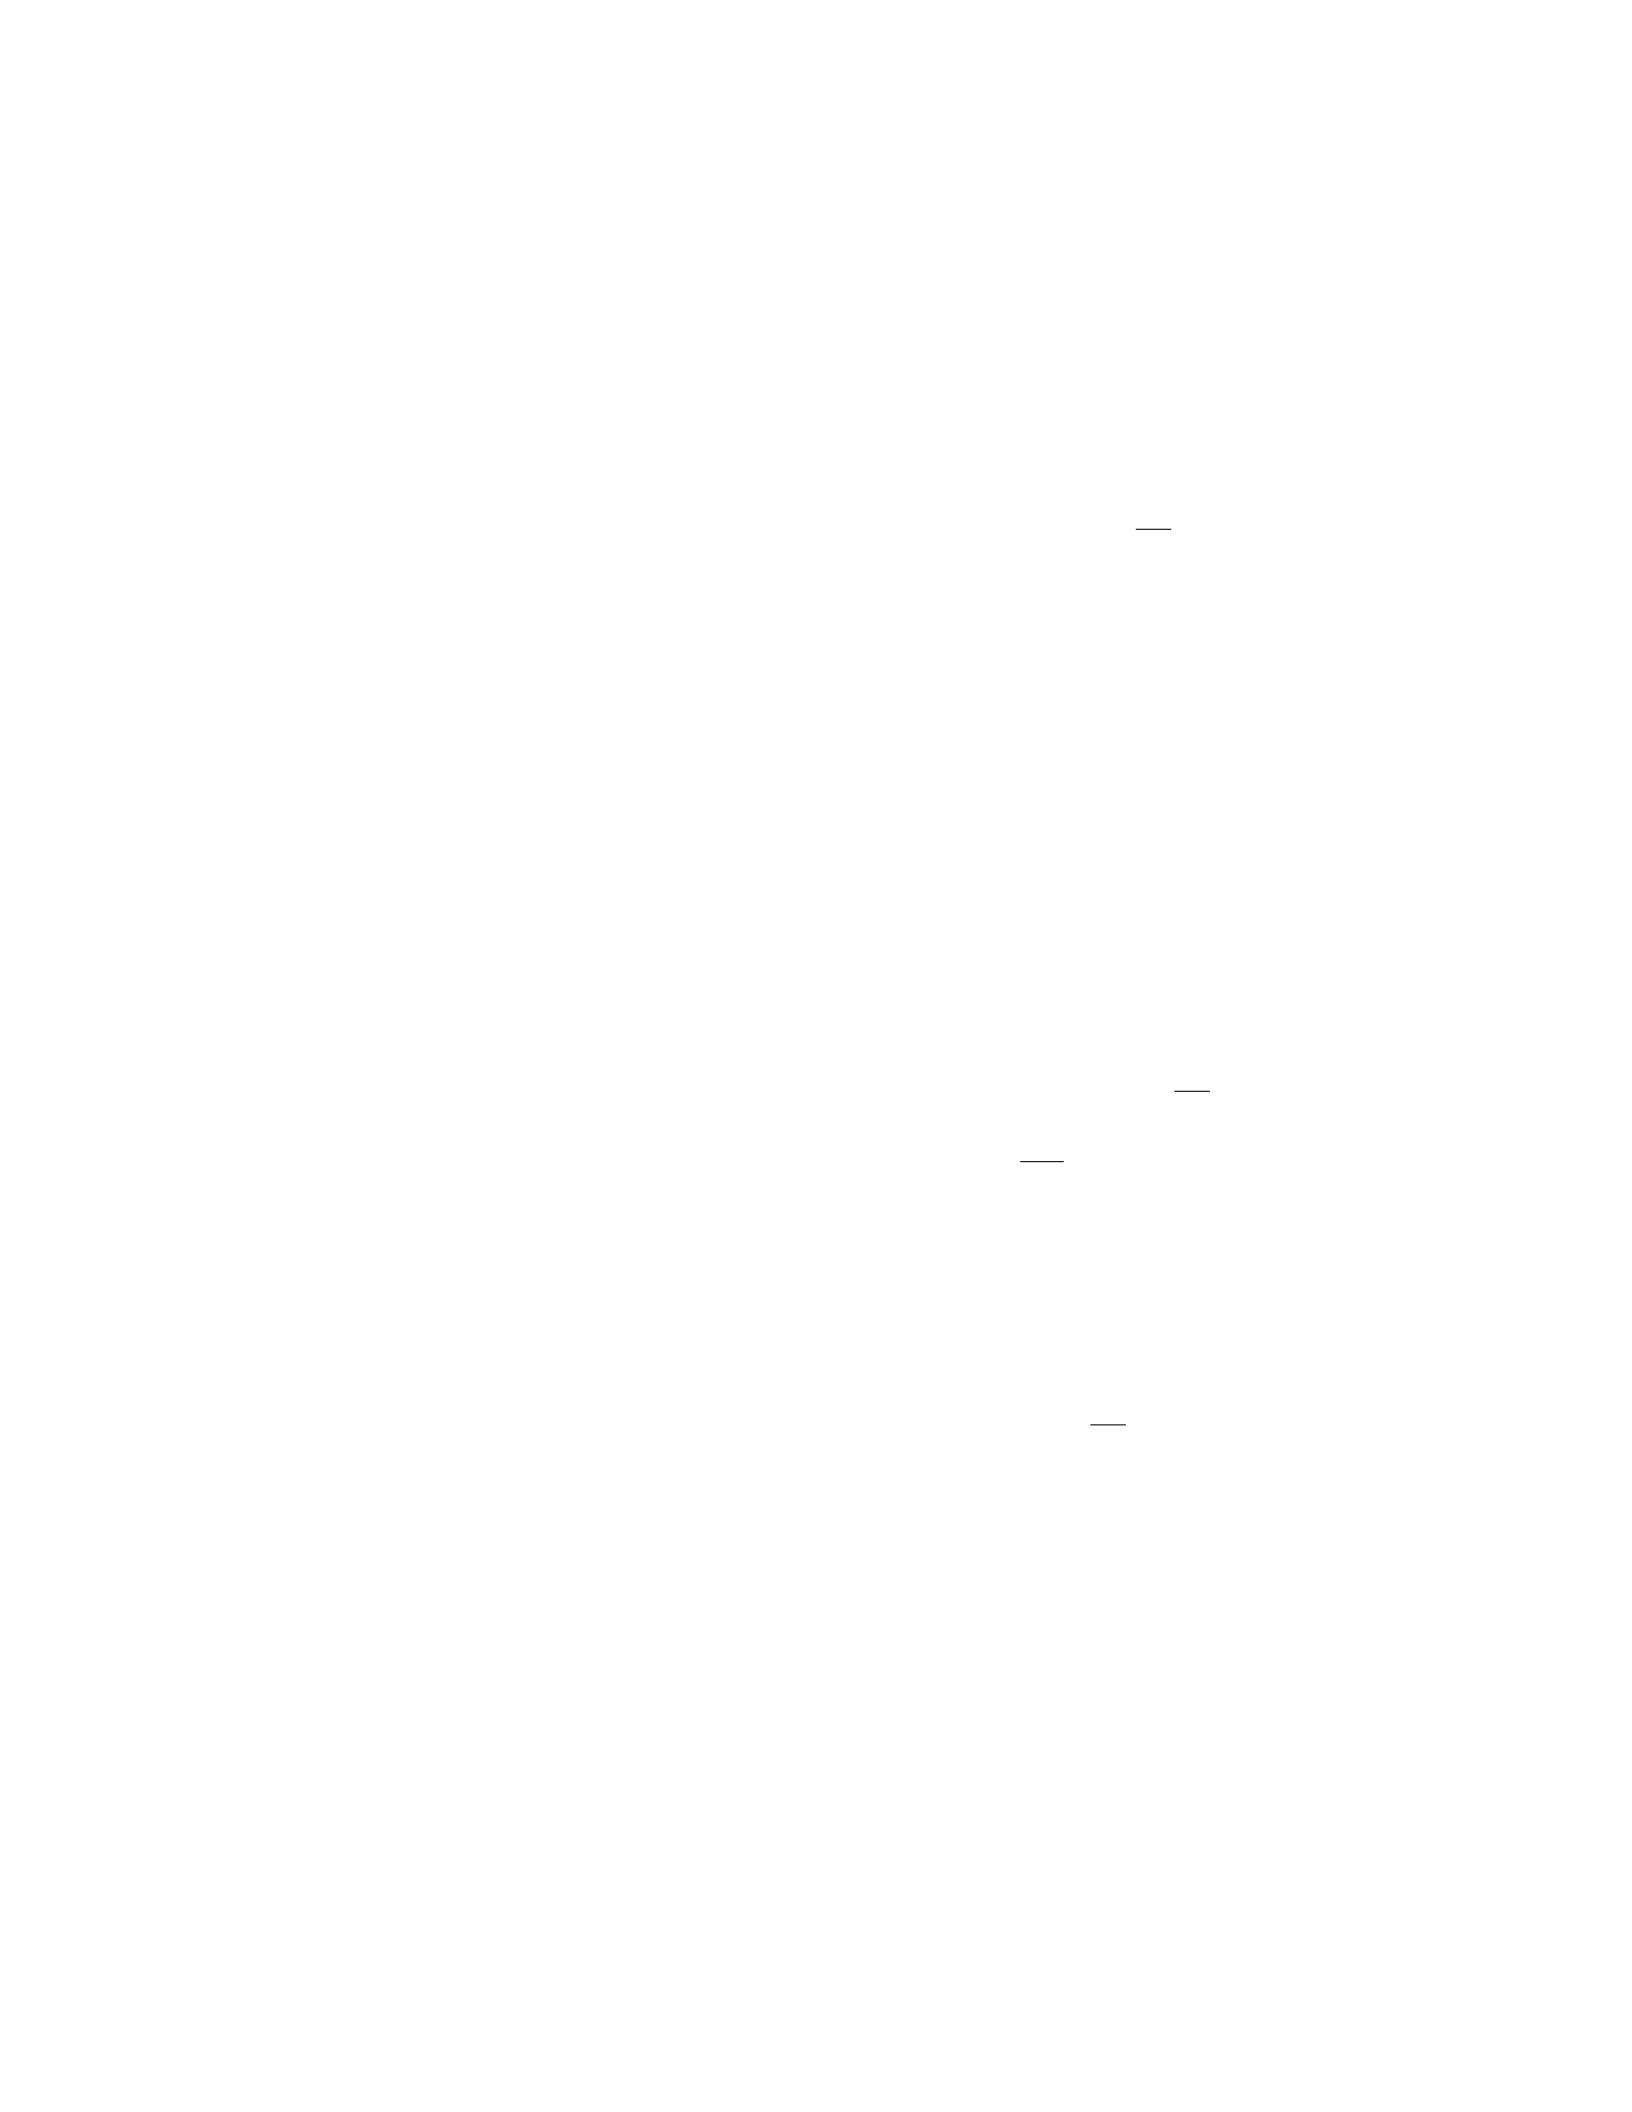
Solution
Step 1: Recall that the fundamental property of K-functions states that for any
point process Xin a region W, the expected number of points of Xat distance
rfrom a fixed point is equal to λW·KX(r), where λWis the intensity of Xin
region W, and KX(r) is the K-function of X.
Step 2: To show that KX,τ Y (r) = λX∗gτ(r) + λY∗g−τ(r)−r
|W|satisfies
the fundamental property of K-functions, we need to prove that
E[N(Br(o))] = λW·KX,τ Y (r)
for any ball Br(o)⊂W, where N(Br(o)) is the number of points of Xand the
transformed version of Yfalling inside Br(o).
Step 3: By the properties of spatial convolution, we have
E[N(Br(o))] = E[NX(Br(o))] + E[NY(Br(o))]
where NXand NYare the number of points in pattern Xand Y, respectively,
contained in Br(o).
Step 4: Recall that E[NX(Br(o))] = λX· |Br(o)|and E[NY(Br(o))] = λY·
|Br(o)|where |Br(o)|denotes the area of the ball of radius rcentered at o.
Step 5: Substituting these expressions into the equation from Step 3 gives
us
E[N(Br(o))] = λX· |Br(o)|+λY· |Br(o)|
Step 6: Now, let’s evaluate KX,τ Y (r) = λX∗gτ(r) + λY∗g−τ(r)−r
|W|at r:
KX,τ Y (r) = λX·gτ(r) + λY·g−τ(r)−r
|W|
Step 7: Since gτ(r) and g−τ(r) are pair correlation functions, they represent
the expected number of additional points in Xand the transformed version of
Yat distance rfrom a given point compared to complete spatial randomness.
Step 8: Hence, for the superposition of Xand the transformed version of
Y, the expected number of additional points at distance rfrom a fixed point is
given by KX,τ Y (r) times the intensity λW.
Step 9: Therefore, KX,τ Y (r) = λX∗gτ(r) + λY∗g−τ(r)−r
|W|satisfies the
fundamental property of K-functions and represents the expected number of
points at distance rfor the given spatial point patterns in W.
Question 13
Question
Consider a dataset containing spatial information on temperatures recorded at
different locations. You are tasked with modeling the spatial variation in tem-
peratures using Kriging interpolation. Explain the steps involved in performing
Kriging interpolation for this dataset.
12

Solution
To perform Kriging interpolation for the given dataset, follow these steps:
Step 1: Define the Problem - Clearly define the problem at hand, which
in this case is estimating the temperature at unsampled locations based on the
measured temperatures at sampled locations.
Step 2: Semivariogram Analysis - Calculate the semivariogram from
the recorded temperature data. This step involves computing the variance of
the temperature differences between pairs of locations at various distances.
Step 3: Model the Semivariogram - Fit a theoretical model (e.g., spher-
ical, exponential, Gaussian) to the empirical semivariogram obtained in the pre-
vious step. This model will help capture the spatial correlation structure of the
temperature data.
Step 4: Kriging Estimation - Using the modeled semivariogram, perform
the Kriging estimation at the unsampled locations. This involves calculating the
weights for each sampled point based on its distance and spatial correlation with
the unsampled location.
Step 5: Interpolation - Once the weights are calculated, interpolate the
temperatures at unsampled locations by combining the measured temperatures
at sampled locations using the Kriging estimation.
Step 6: Validation - Finally, validate the Kriging interpolation results
by comparing them with independent temperature measurements or through
cross-validation techniques to evaluate the accuracy of the spatial temperature
model.
By following these steps, you can effectively model the spatial variation in
temperatures using Kriging interpolation for the given dataset.
Question 14
Question
Consider a dataset of crime incidents across different neighborhoods in a city.
You are tasked with analyzing the spatial patterns of these incidents and build-
ing a predictive model to identify high-risk areas.
Given the dataset, describe the steps you would take to analyze the spatial
distribution of crime incidents and develop a spatial predictive model.
Solution
To analyze the spatial distribution of crime incidents and build a predictive
model, the following steps should be taken:
Step 1: Exploratory Data Analysis (EDA) - Conduct exploratory data
analysis to understand the distribution of crime incidents across neighborhoods.
- Use descriptive statistics and data visualization techniques such as histograms
and maps to identify any patterns or outliers.
13
Step 2: Spatial Autocorrelation Analysis - Perform a spatial autocor-
relation analysis to determine if there are spatial clusters or patterns of crime
incidents. - Use methods like Moran’s I statistic to quantify spatial autocorre-
lation.
Step 3: Spatial Hotspot Analysis - Conduct a hotspot analysis to iden-
tify statistically significant clusters of high or low crime incidents. - Utilize
techniques like Getis-Ord Gi* statistic to identify hotspots of crime.
Step 4: Spatial Regression Modeling - Build a spatial regression model
to predict crime incidents based on relevant explanatory variables. - Consider
variables such as population density, socioeconomic factors, and proximity to
amenities as predictors. - Use techniques like spatial lag or spatial error models
to account for spatial dependence in the data.
Step 5: Model Evaluation and Validation - Evaluate the spatial pre-
dictive model using metrics like R-squared, AIC, BIC, and residuals analysis. -
Validate the model by applying it to a separate dataset or using cross-validation
techniques.
Step 6: Interpretation and Visualization - Interpret the results of the
spatial predictive model and identify high-risk areas based on the model predic-
tions. - Visualize the results using maps to communicate the findings effectively
to stakeholders.
Question 15
Question
Consider a dataset containing information about the population density in dif-
ferent regions of a country. You are tasked with analyzing the spatial patterns
and trends in the data to inform urban planning decisions. Describe the steps
you would take to conduct a spatial data analysis and modeling of this dataset.
Solution
To conduct a spatial data analysis and modeling of the population density
dataset, the following steps can be taken:
Step 1: Data Collection
Collect the dataset containing information on population density in dif-
ferent regions of the country.
Ensure that the dataset includes spatial coordinates (latitude and longi-
tude) for each region.
Step 2: Data Exploration
Visualize the dataset using maps, scatter plots, and histograms to under-
stand the distribution of population density across regions.
Look for any spatial patterns or clusters in the data.
14
Step 3: Spatial Autocorrelation Analysis
Conduct spatial autocorrelation analysis to determine if there is any spa-
tial dependence in the population density values.
Use Moran’s I statistic to quantify the spatial autocorrelation.
Step 4: Spatial Interpolation
Perform spatial interpolation techniques such as Kriging or Inverse Dis-
tance Weighting to estimate population density values at unsampled lo-
cations.
Evaluate the accuracy of the interpolation results.
Step 5: Spatial Regression Modeling
Build a spatial regression model to analyze the relationship between pop-
ulation density and other factors such as land use, socio-economic indica-
tors, or infrastructure.
Incorporate spatial weights matrices to account for spatial autocorrelation
in the data.
Step 6: Model Evaluation
Validate the spatial regression model using criteria such as R-squared,
AIC, and residual analysis.
Assess the goodness of fit and predictive performance of the model.
By following these steps, a comprehensive spatial data analysis and modeling
of the population density dataset can be conducted to inform urban planning
decisions.
Question 16
Question
Let Xand Ybe random variables representing the latitudes of two earthquake
epicenters. Assume that X∼N(36.5,0.32) and Y∼N(34,0.62), and that
the correlation coefficient between Xand Yis 0.8. Find the joint probability
density function of Xand Y.
Solution
Step 1: The joint probability density function of Xand Yfor bivariate normal
distribution is given as:
fX,Y (x, y) = 1
2πσxσyp1−ρ2exp −1
2(1 −ρ2)(x−µx)2
σ2
x−2ρ(x−µx)(y−µy)
σxσy
+(y−µy)2
σ2
y
15
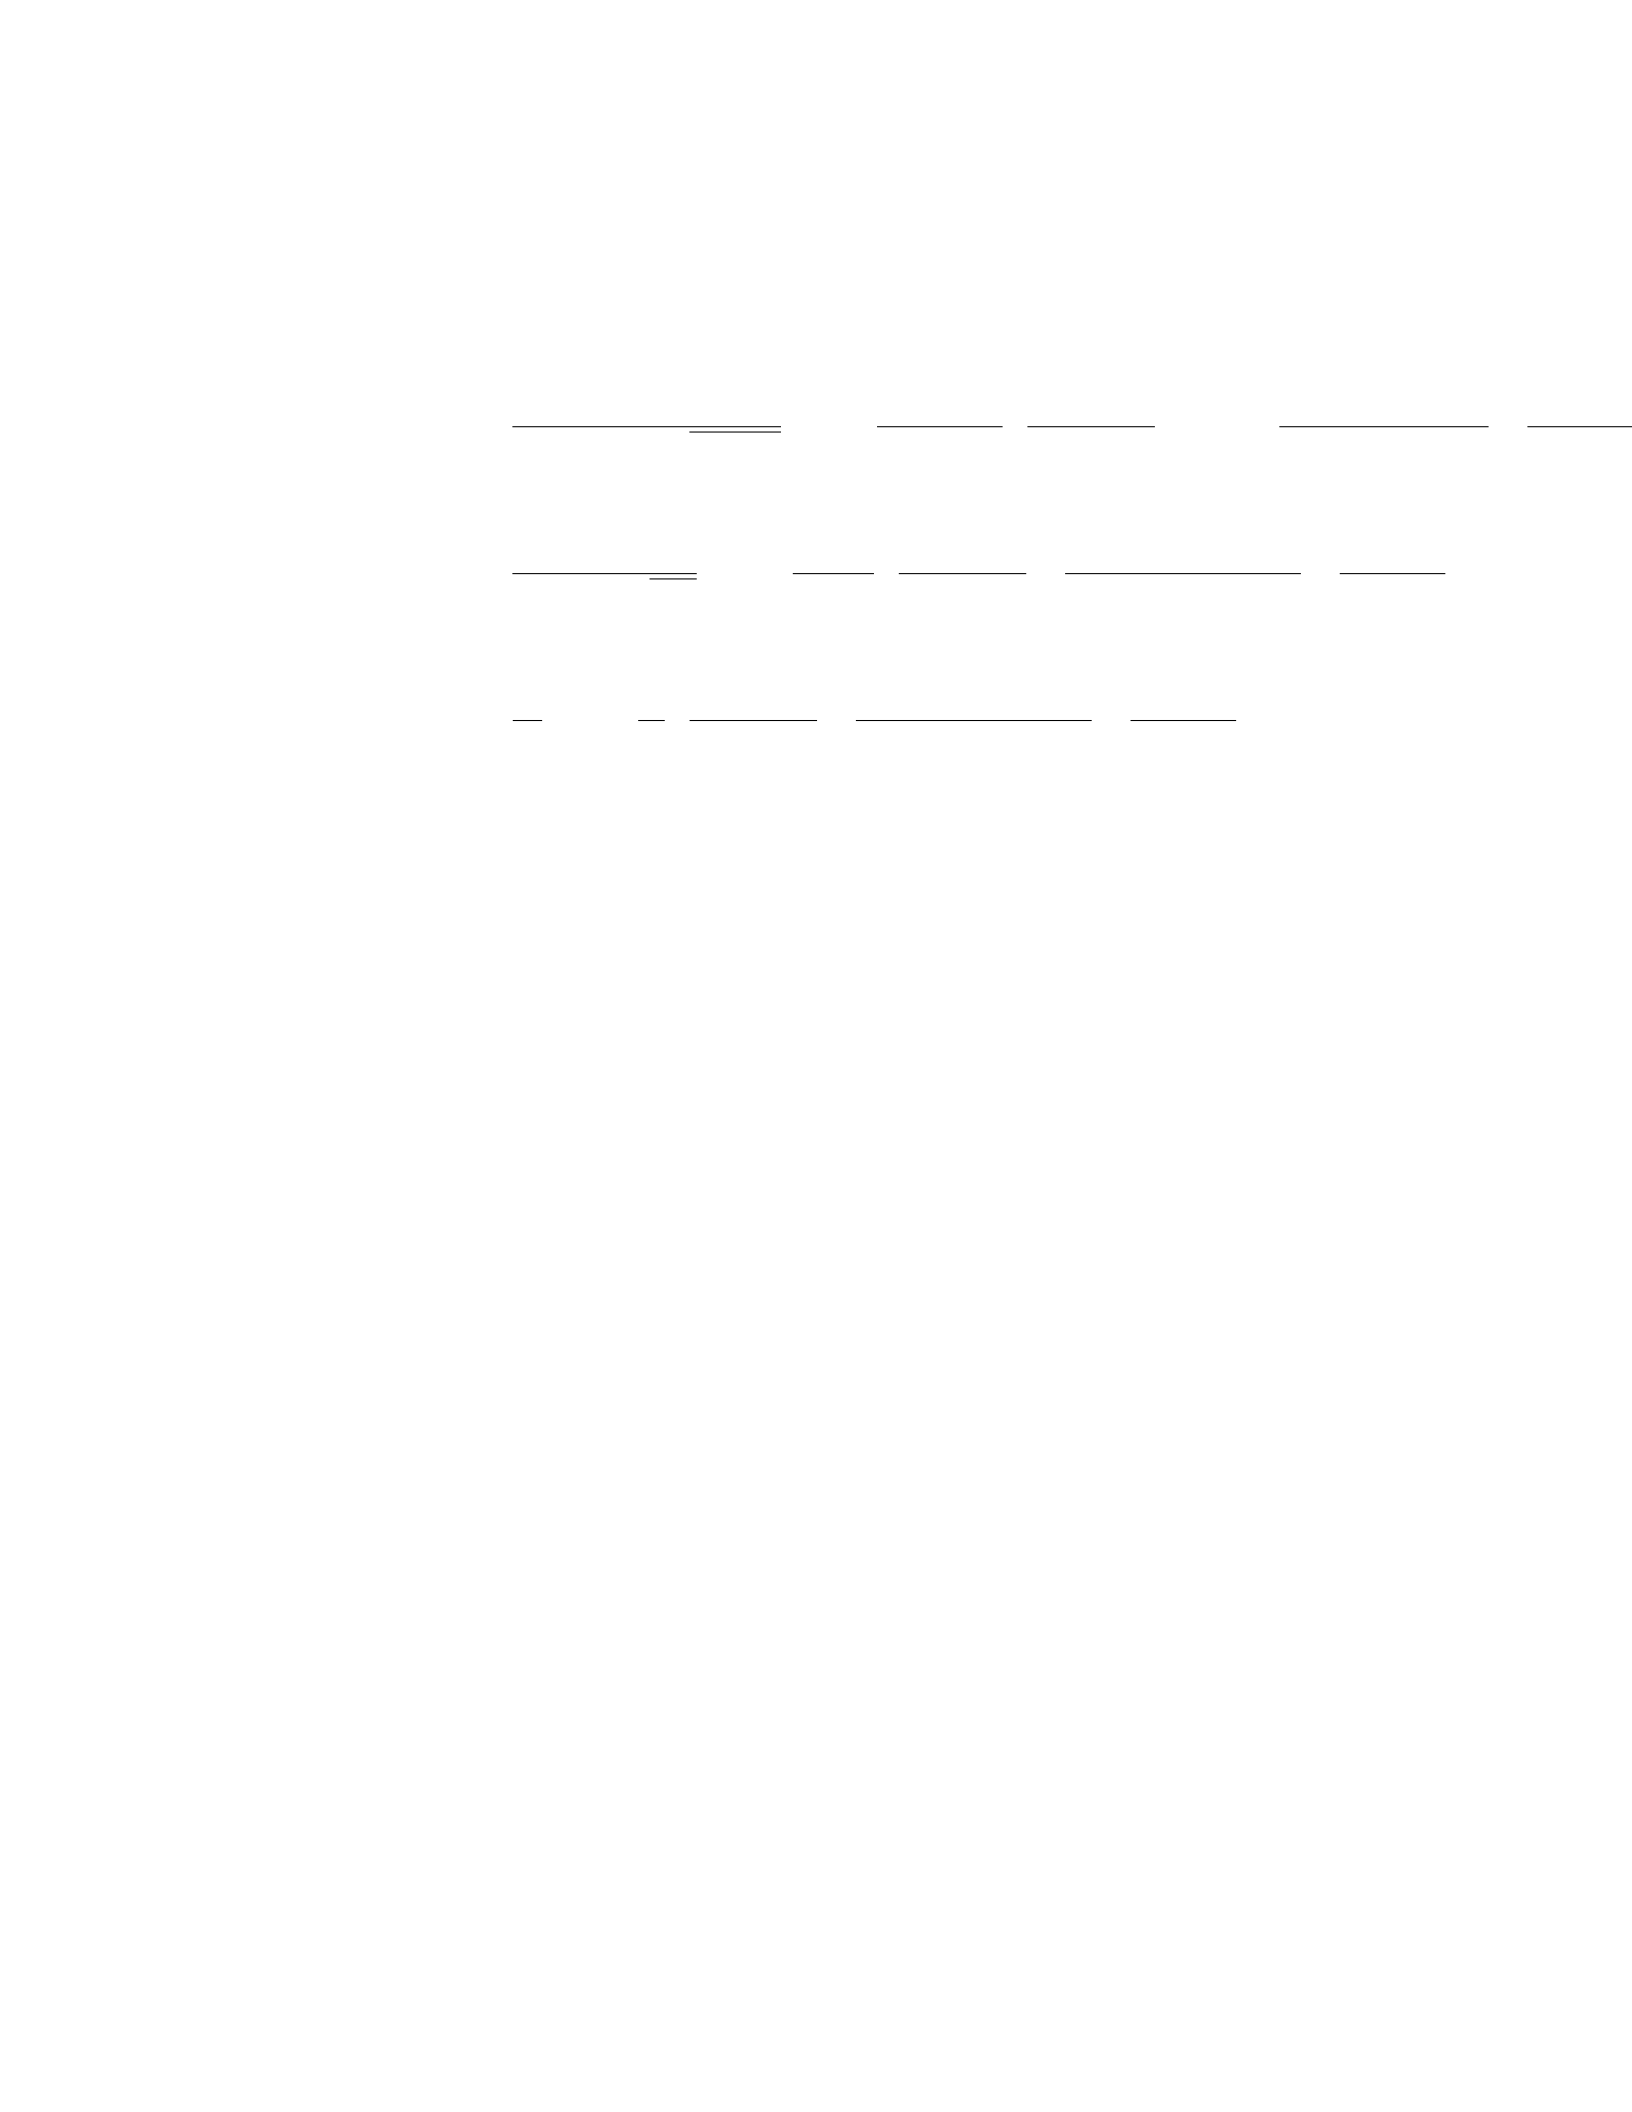
Step 2: Plugging in the values of the given parameters, we get:
fX,Y (x, y) = 1
2π·0.3·0.6·√1−0.82exp −1
2(1 −0.82)(x−36.5)2
0.32−2·0.8·(x−36.5)(y−34)
0.3·0.6+(y−34)2
0.62
Step 3: Simplify the equation further:
fX,Y (x, y) = 1
2π·0.18 ·√0.36 exp −1
2(0.36) (x−36.5)2
0.09 −16(x−36.5)(y−34)
0.18 +(y−34)2
0.36
Step 4: Finally, the joint probability density function of Xand Yis:
fX,Y (x, y) = 25
3πexp −75
2(x−36.5)2
0.09 −16(x−36.5)(y−34)
0.18 +(y−34)2
0.36
Question 17
Question
Consider a dataset containing the coordinates of 100 different locations in a city.
The dataset also includes information on the average income in each location.
You are tasked with analyzing the spatial distribution of income in the city
using spatial data analysis and modeling techniques. One of the techniques you
plan to use is spatial autocorrelation analysis.
Explain what spatial autocorrelation is and how you can determine if there
is spatial autocorrelation in the income data.
Solution
Step 1: Spatial Autocorrelation
Spatial autocorrelation refers to the degree to which the values of a variable
(such as income) correlate with neighboring values in space. In other words, it
explores the spatial patterns and relationships of a variable across a geographic
area. Spatial autocorrelation can be positive, indicating that similar values tend
to cluster together, or negative, indicating dispersion or dissimilarity among
values.
Step 2: Determining Spatial Autocorrelation
To determine if there is spatial autocorrelation in the income data, we can use
a statistical test such as Moran’s I. Moran’s I statistic measures the spatial
autocorrelation in a dataset with respect to its neighboring locations. The
values of Moran’s I range from -1 (perfect dispersion) to 1 (perfect correlation),
with 0 indicating no spatial autocorrelation.
Step 3: Calculating Moran’s I
To calculate Moran’s I, we first need to define a spatial weights matrix that
specifies the spatial relationships between locations. Common types of spatial
weights matrices include binary contiguity (neighbors are defined by sharing a
border or vertex) or distance-based (weights decrease with distance) matrices.
16
Using the spatial weights matrix, we can compute Moran’s I statistic for the
income data.
Step 4: Interpreting Moran’s I
After calculating Moran’s I, we can test its statistical significance to determine
if the observed spatial autocorrelation is statistically different from what would
be expected by random chance. If Moran’s I is significantly different from 0, we
can conclude that there is spatial autocorrelation in the income data.
Step 5: Conclusion
In this way, by conducting spatial autocorrelation analysis using techniques
such as Moran’s I, we can assess the spatial distribution of income in the city
and identify any clustering or dispersion patterns that exist. This information
can be valuable for understanding the socio-economic dynamics of the city and
informing policy decisions related to resource allocation and urban planning.
Question 18
Question
Let Xand Ybe two random variables representing the spatial coordinates (x, y)
in a two-dimensional space. Suppose the joint probability density function of X
and Yis given by f(x, y) = ce−2(x+y)for 0 <x<∞and 0 < y < ∞, where c
is a normalizing constant.
Find the marginal probability density functions of Xand Y.
Solution
Step 1: To find the marginal probability density function of X, we need to
integrate the joint probability density function f(x, y) over all possible values
of Y.
fX(x) = Z∞
0
f(x, y)dy
Step 2: Substitute the expression of f(x, y) into the integral.
fX(x) = Z∞
0
ce−2(x+y)dy
Step 3: Perform the integration.
fX(x) = cZ∞
0
e−2xe−2ydy
fX(x) = ce−2xZ∞
0
e−2ydy
Step 4: Solve the integral.
fX(x) = −c
2e−2x[e−2y]∞
0
17
fX(x) = −c
2e−2x[0 −1]
fX(x) = c
2e−2x
Step 5: To find the value of c, we need to ensure that the marginal probability
density function of Xintegrates to 1 over all possible values of X.
Z∞
0
c
2e−2xdx = 1
Step 6: Solve for c.
c
2Z∞
0
e−2xdx = 1
c
2[−1
2e−2x]∞
0= 1
c
2[−0−(−1
2)] = 1
c
2·1
2= 1
c
4= 1
c= 4
Therefore, the marginal probability density function of Xis:
fX(x) = 2e−2x
Step 7: Similarly, repeat the steps above to find the marginal probability
density function of Y. We can interchange the roles of Xand Yin the joint
probability density function.
Step 8: The marginal probability density function of Yis given by:
fY(y)=2e−2y
Question 19
Question
Let Xand Ybe two spatial processes defined on a region D⊆R2with contin-
uous realizations and covariance functions given by:
CX(h) = σ2
Xexp(−∥h∥) and CY(h) = σ2
Yexp(−3∥h∥),
where σ2
X= 1, σ2
Y= 2, and h∈R2is the displacement vector. Determine the
process Zwhich is the difference between Xand Y, i.e., Z=X−Y. Compute
the covariance function CZ(h) of Z.
18
Solution
1. To determine the covariance function CZ(h) of the process Z=X−Y, we
first find the covariance function of Z:
CZ(h) = CX(h)−CY(h).
2. Substitute the given covariance functions for Xand Y:
CZ(h) = σ2
Xexp(−∥h∥)−σ2
Yexp(−3∥h∥).
3. Plug in the values of σ2
X= 1 and σ2
Y= 2 into the equation:
CZ(h) = exp(−∥h∥)−2 exp(−3∥h∥).
4. Simplify the expression by factoring out exp(−∥h∥):
CZ(h) = exp(−∥h∥)(1 −2 exp(−2∥h|)).
Therefore, the covariance function CZ(h) of the process Z=X−Yis given
by CZ(h) = exp(−∥h∥)(1 −2 exp(−2∥h|)).
Question 20
Question
Consider a dataset containing coordinates (latitude and longitude) of various
cities in a country. You are tasked with analyzing the spatial distribution of
these cities to identify any clustering patterns that may exist. Perform a spatial
data analysis and modeling to determine if the cities exhibit significant spatial
clustering or if their distribution is random.
Solution
To analyze the spatial distribution of the cities and identify clustering patterns,
we can perform a spatial autocorrelation analysis using Moran’s I statistic. This
statistic will help us determine if the distribution of cities exhibits clustering,
randomness, or dispersion.
Step 1: Define the Spatial Weights Matrix
First, we need to construct a spatial weights matrix that defines the spatial
relationships between the cities. We can use a contiguity-based weights matrix,
such as Queen’s contiguity, where cities are considered neighbors if they share
a border or a vertex.
Step 2: Calculate Moran’s I Statistic
Next, we calculate Moran’s I statistic using the following formula:
I=n
Pn
i=1 Pn
j=1 wij Pn
i=1 Pn
j=1 wij (xi−¯x)(xj−¯x)
Pn
i=1(xi−¯x)2
19

where: - nis the number of cities, - wij is the element of the spatial weights
matrix, - xiand xjare the values of the variable (coordinates) at locations i
and j, - ¯xis the mean of all values.
Step 3: Determine Significance
Finally, we can assess the significance of Moran’s I statistic by comparing
it to its expected value under the null hypothesis of spatial randomness. We
can use a permutation test to calculate a pseudo p-value and determine if the
observed spatial pattern is statistically significant.
Based on the Moran’s I statistic and its significance level, we can conclude
whether the spatial distribution of cities exhibits clustering, dispersion, or ran-
domness.
Question 21
Question
Consider a dataset containing information on the elevation (in meters) of 50
different locations within a region. You are tasked with analyzing this spatial
data to identify any patterns or trends present in the dataset. Describe how you
would approach this task by outlining the steps involved in spatial data analysis
and modeling.
Solution
To analyze the spatial data on elevation for the 50 different locations, we can
follow a series of steps in spatial data analysis and modeling:
Step 1: Data Acquisition Obtain the dataset containing the elevation
information for the 50 locations within the region. Ensure the data is accurate,
complete, and stored in a format that is suitable for analysis.
Step 2: Data Exploration and Visualization Explore the dataset by
calculating summary statistics (mean, median, standard deviation, etc.) to gain
an understanding of the central tendency and variability of elevation values.
Use visualization techniques such as histograms, box plots, and scatter plots to
identify any patterns or outliers in the data.
Step 3: Spatial Data Preprocessing Perform any necessary preprocess-
ing steps on the data, such as handling missing values, normalizing data, and
transforming the dataset if required. Ensure the data is in a format suitable for
spatial analysis.
Step 4: Spatial Autocorrelation Analysis Conduct spatial autocorre-
lation analysis to determine whether there is a spatial pattern in the elevation
data. Use techniques such as Moran’s I and Geary’s C to assess the degree of
spatial autocorrelation present in the dataset.
Step 5: Spatial Interpolation Apply spatial interpolation techniques,
such as kriging or inverse distance weighting, to estimate elevation values at
20

locations where data is missing or to generate a continuous surface of elevation
across the region.
Step 6: Spatial Regression Modeling Perform spatial regression analy-
sis to identify any relationships between elevation and other attributes or covari-
ates. Use techniques like spatial lag models or spatial error models to account
for spatial dependencies in the data.
Step 7: Model Evaluation Evaluate the accuracy and performance of
the spatial models developed using measures such as R-squared, root mean
square error (RMSE), and cross-validation techniques to assess the validity of
the models.
By following these steps in spatial data analysis and modeling, we can gain
insights into the patterns and trends present in the elevation data for the 50
locations within the region.
Question 22
Question
Consider a dataset containing information on the spatial distribution of tree
species in a forest. You are tasked with analyzing and modeling this spatial data
to understand the patterns and relationships between different tree species.
Given the dataset, describe three key spatial data analysis techniques you
would utilize and explain how each technique can help in this analysis.
Solution
To analyze and model the spatial distribution of tree species in the forest dataset,
we can use the following key spatial data analysis techniques:
Step 1: Spatial Autocorrelation - Spatial autocorrelation is a technique used
to determine if there are any spatial patterns or clusters in the data. By cal-
culating spatial autocorrelation measures such as Moran’s I or Geary’s C, we
can assess if similar tree species tend to cluster together in space. This analysis
can help us identify any significant spatial patterns of tree species distribution
in the forest.
Step 2: Kriging - Kriging is a spatial interpolation technique used to es-
timate values at unsampled locations based on the values of nearby sampled
locations. By using kriging, we can create a spatially continuous map of tree
species distribution in the forest. This can help us visualize the spatial patterns
of different tree species and make more accurate predictions about the presence
of tree species at unsampled locations.
Step 3: Spatial Regression - Spatial regression is a technique that accounts
for the spatial dependency of data when modeling relationships between vari-
ables. By using spatial regression models, we can investigate how environmental
variables such as soil type, elevation, and proximity to water sources influence
the distribution of tree species in the forest. This analysis can help us identify
21
the key factors driving the spatial distribution of tree species and improve our
understanding of the ecological relationships in the forest.
Question 23
Question
Consider a dataset containing information on pollution levels and health out-
comes across different regions. You are tasked with analyzing the spatial corre-
lation between pollution levels and health outcomes using spatial data analysis
techniques.
Given a set of coordinates for different regions, pollution levels (measured
in parts per million) at each region, and health outcome scores (ranging from
1 to 10) at each region, perform the following steps: 1. Calculate the spatial
autocorrelation of pollution levels using Moran’s I statistic. 2. Determine if
there is a significant spatial pattern of pollution levels using a hypothesis test.
3. Calculate the spatial autocorrelation of health outcomes using Moran’s I
statistic. 4. Determine if there is a significant spatial pattern of health outcomes
using a hypothesis test. 5. Explore the spatial relationship between pollution
levels and health outcomes using a bivariate Moran’s I statistic. 6. Interpret
the results of the bivariate Moran’s I statistic in the context of the relationship
between pollution levels and health outcomes.
Solution
1. Calculate the spatial autocorrelation of pollution levels using Moran’s I
statistic:
Moran’s I = n
Pn
i=1 Pn
j=1 wij ·Pn
i=1 Pn
j=1 wij (xi−¯x)(xj−¯x)
Pn
i=1(xi−¯x)2
where: - nis the number of regions - xiis the pollution level at region i- ¯xis
the mean pollution level - wij is the spatial weight between regions iand j
2. Determine if there is a significant spatial pattern of pollution levels: To
test the significance of Moran’s I, we compare it to its expected value under the
null hypothesis of spatial randomness. We can calculate the z-score and p-value
to determine significance.
3. Calculate the spatial autocorrelation of health outcomes using Moran’s I
statistic: This is similar to Step 1, but with health outcome scores instead of
pollution levels.
4. Determine if there is a significant spatial pattern of health outcomes:
Repeat Step 2 with health outcome scores to determine significance.
5. Explore the spatial relationship between pollution levels and health out-
22
comes using a bivariate Moran’s I statistic:
Bivariate Moran’s I = Pn
i=1 Pn
j=1 wij (xi−¯x)(yj−¯y)
rPn
i=1 Pn
j=1 wij (xi−¯x)2·Pn
i=1 Pn
j=1 wij (yj−¯y)2
where: - yjis the health outcome score at region j- ¯yis the mean health
outcome score
6. Interpret the results of the bivariate Moran’s I statistic: The bivariate
Moran’s I ranges from -1 to 1. Positive values indicate positive spatial autocor-
relation (similar values close to each other), negative values indicate negative
spatial autocorrelation, and zero indicates no spatial autocorrelation.
Question 24
Question
Suppose you are given a dataset containing the coordinates (latitude and lon-
gitude) of 1000 locations in a city. You are interested in analyzing the spatial
distribution of these locations and want to fit a spatial model to predict the
location of a new point. Explain the steps you would take to conduct spatial
data analysis and modeling for this dataset.
Solution
To conduct spatial data analysis and modeling for the given dataset, follow these
steps:
Step 1: Data Exploration - Visualize the dataset by plotting the loca-
tions on a map to understand the spatial distribution. - Check for any obvious
patterns or clusters in the data.
Step 2: Spatial Autocorrelation Analysis - Evaluate the spatial auto-
correlation in the dataset using tools like Moran’s I or Geary’s C. - Determine
if there is spatial clustering, randomness, or dispersion in the data.
Step 3: Spatial Interpolation - Choose an appropriate spatial interpola-
tion method (e.g., Kriging, Inverse Distance Weighting) to predict the location
of new points. - Interpolate the data to create a continuous surface representing
the spatial distribution.
Step 4: Model Fitting - Select a spatial model that best fits the dataset
(e.g., spatial regression models, geostatistical models). - Fit the chosen model
to the data and assess its goodness of fit.
Step 5: Model Validation - Validate the spatial model using techniques
like cross-validation or comparing predicted values to actual values. - Assess
the accuracy and reliability of the model predictions.
Step 6: Prediction and Interpretation - Use the fitted spatial model to
make predictions for new locations within the study area. - Interpret the results
and make conclusions about the spatial relationships in the dataset.
23
By following these steps, you can effectively conduct spatial data analysis
and modeling for the given dataset of 1000 locations in the city.
Question 25
Question
Consider a dataset consisting of the coordinates of 50 sampling points in a
forest. The goal is to build a spatial model to predict the number of trees in an
arbitrary location. Describe the step-by-step process of conducting spatial data
analysis and modeling for this scenario.
Solution
To conduct spatial data analysis and modeling for predicting the number of
trees in an arbitrary location in a forest, we can follow these steps:
Step 1: Data Collection Collect the coordinates of the 50 sampling points
and the corresponding number of trees at each location in the forest.
Step 2: Exploratory Data Analysis (EDA)
Plot the sampling points on a map to visualize the spatial distribution of
the data.
Examine the data for any outliers or missing values.
Calculate summary statistics such as mean, standard deviation, and range
for the number of trees.
Step 3: Spatial Data Preprocessing
Check for spatial autocorrelation to understand the spatial dependency of
the data.
Transform the data, if necessary, to meet modeling assumptions (e.g., log-
transform for count data).
Standardize the coordinates (e.g., using z-scores) if needed.
Step 4: Model Selection Choose an appropriate spatial model for predic-
tion. Options include:
Spatial autoregressive models (SAR)
Geostatistical models (e.g., kriging)
Machine learning models with spatial components (e.g., spatial random
forests)
Step 5: Model Fitting
24
Fit the selected model to the data using appropriate software or program-
ming language.
Evaluate the model fit using diagnostic tools (e.g., residuals analysis).
Step 6: Prediction Predict the number of trees in an arbitrary location
using the fitted spatial model.
Step 7: Validation
Validate the predictive performance of the model using cross-validation or
other validation techniques.
Assess the model’s accuracy by comparing predicted values to observed
values.
Step 8: Interpretation and Application Interpret the results of the
spatial model and consider its implications for forest management or conserva-
tion efforts. Additionally, explore ways to improve the model’s accuracy and
reliability.
Question 26
Question
You are given a dataset containing the coordinates (latitude and longitude) of
100 different locations. Perform the following spatial data analysis and mod-
eling steps: 1. Create a scatter plot of the locations on a map. 2. Calculate
the distance matrix between all pairs of locations. 3. Use hierarchical cluster-
ing to group the locations based on their spatial proximity. 4. Visualize the
hierarchical clustering results using a dendrogram.
Solution
1. To create a scatter plot of the locations on a map, you need to use a mapping
tool or software that allows you to input latitude and longitude coordinates and
plot them. This can be done using Python libraries like Folium or packages in
R like ggplot2 with geompoint.
2. To calculate the distance matrix between all pairs of locations, you can use
the Haversine formula which computes the distance between two points on Earth
given their longitude and latitude. The distance matrix will be a symmetric
matrix where each element represents the distance between two locations.
3. Hierarchical clustering involves grouping data points into a hierarchy of
clusters. In this case, we will use the distance matrix to calculate the proximity
between locations and group them based on spatial similarity. The output will
be a dendrogram showing the hierarchical structure of the clusters.
4. Visualizing the hierarchical clustering results using a dendrogram will help
in understanding how locations are grouped based on their spatial proximity.
25
The dendrogram will display the clusters at different levels of similarity, showing
which locations are more closely related spatially.
Question 27
Question
Consider a dataset containing spatial information on the distribution of a rare
plant species across a region. You are tasked with analyzing this spatial data
and developing a model to predict the suitable habitats for this plant species
based on environmental variables. Describe the steps you would take to perform
spatial data analysis and modeling in this scenario.
Solution
To perform spatial data analysis and modeling for predicting suitable habitats
for a rare plant species based on environmental variables, the following steps
can be taken:
Step 1: Data Collection
Collect the spatial dataset containing information on the distribution of
the rare plant species and relevant environmental variables (e.g., temper-
ature, precipitation, soil type).
Step 2: Data Preprocessing
Clean the dataset by removing any missing or duplicate values.
Standardize or normalize the numerical variables to ensure they are on a
similar scale.
Transform the spatial data into a suitable format for analysis (e.g., spatial
polygons or points).
Step 3: Exploratory Data Analysis (EDA)
Conduct exploratory data analysis to understand the spatial distribution
of the plant species and the relationships with environmental variables.
Use visualizations such as scatter plots, maps, and spatial autocorrelation
analyses to identify patterns and correlations in the data.
Step 4: Spatial Interpolation
Use spatial interpolation techniques (e.g., kriging, inverse distance weight-
ing) to predict the distribution of the plant species across the region based
on the observed data points.
Step 5: Model Development
26
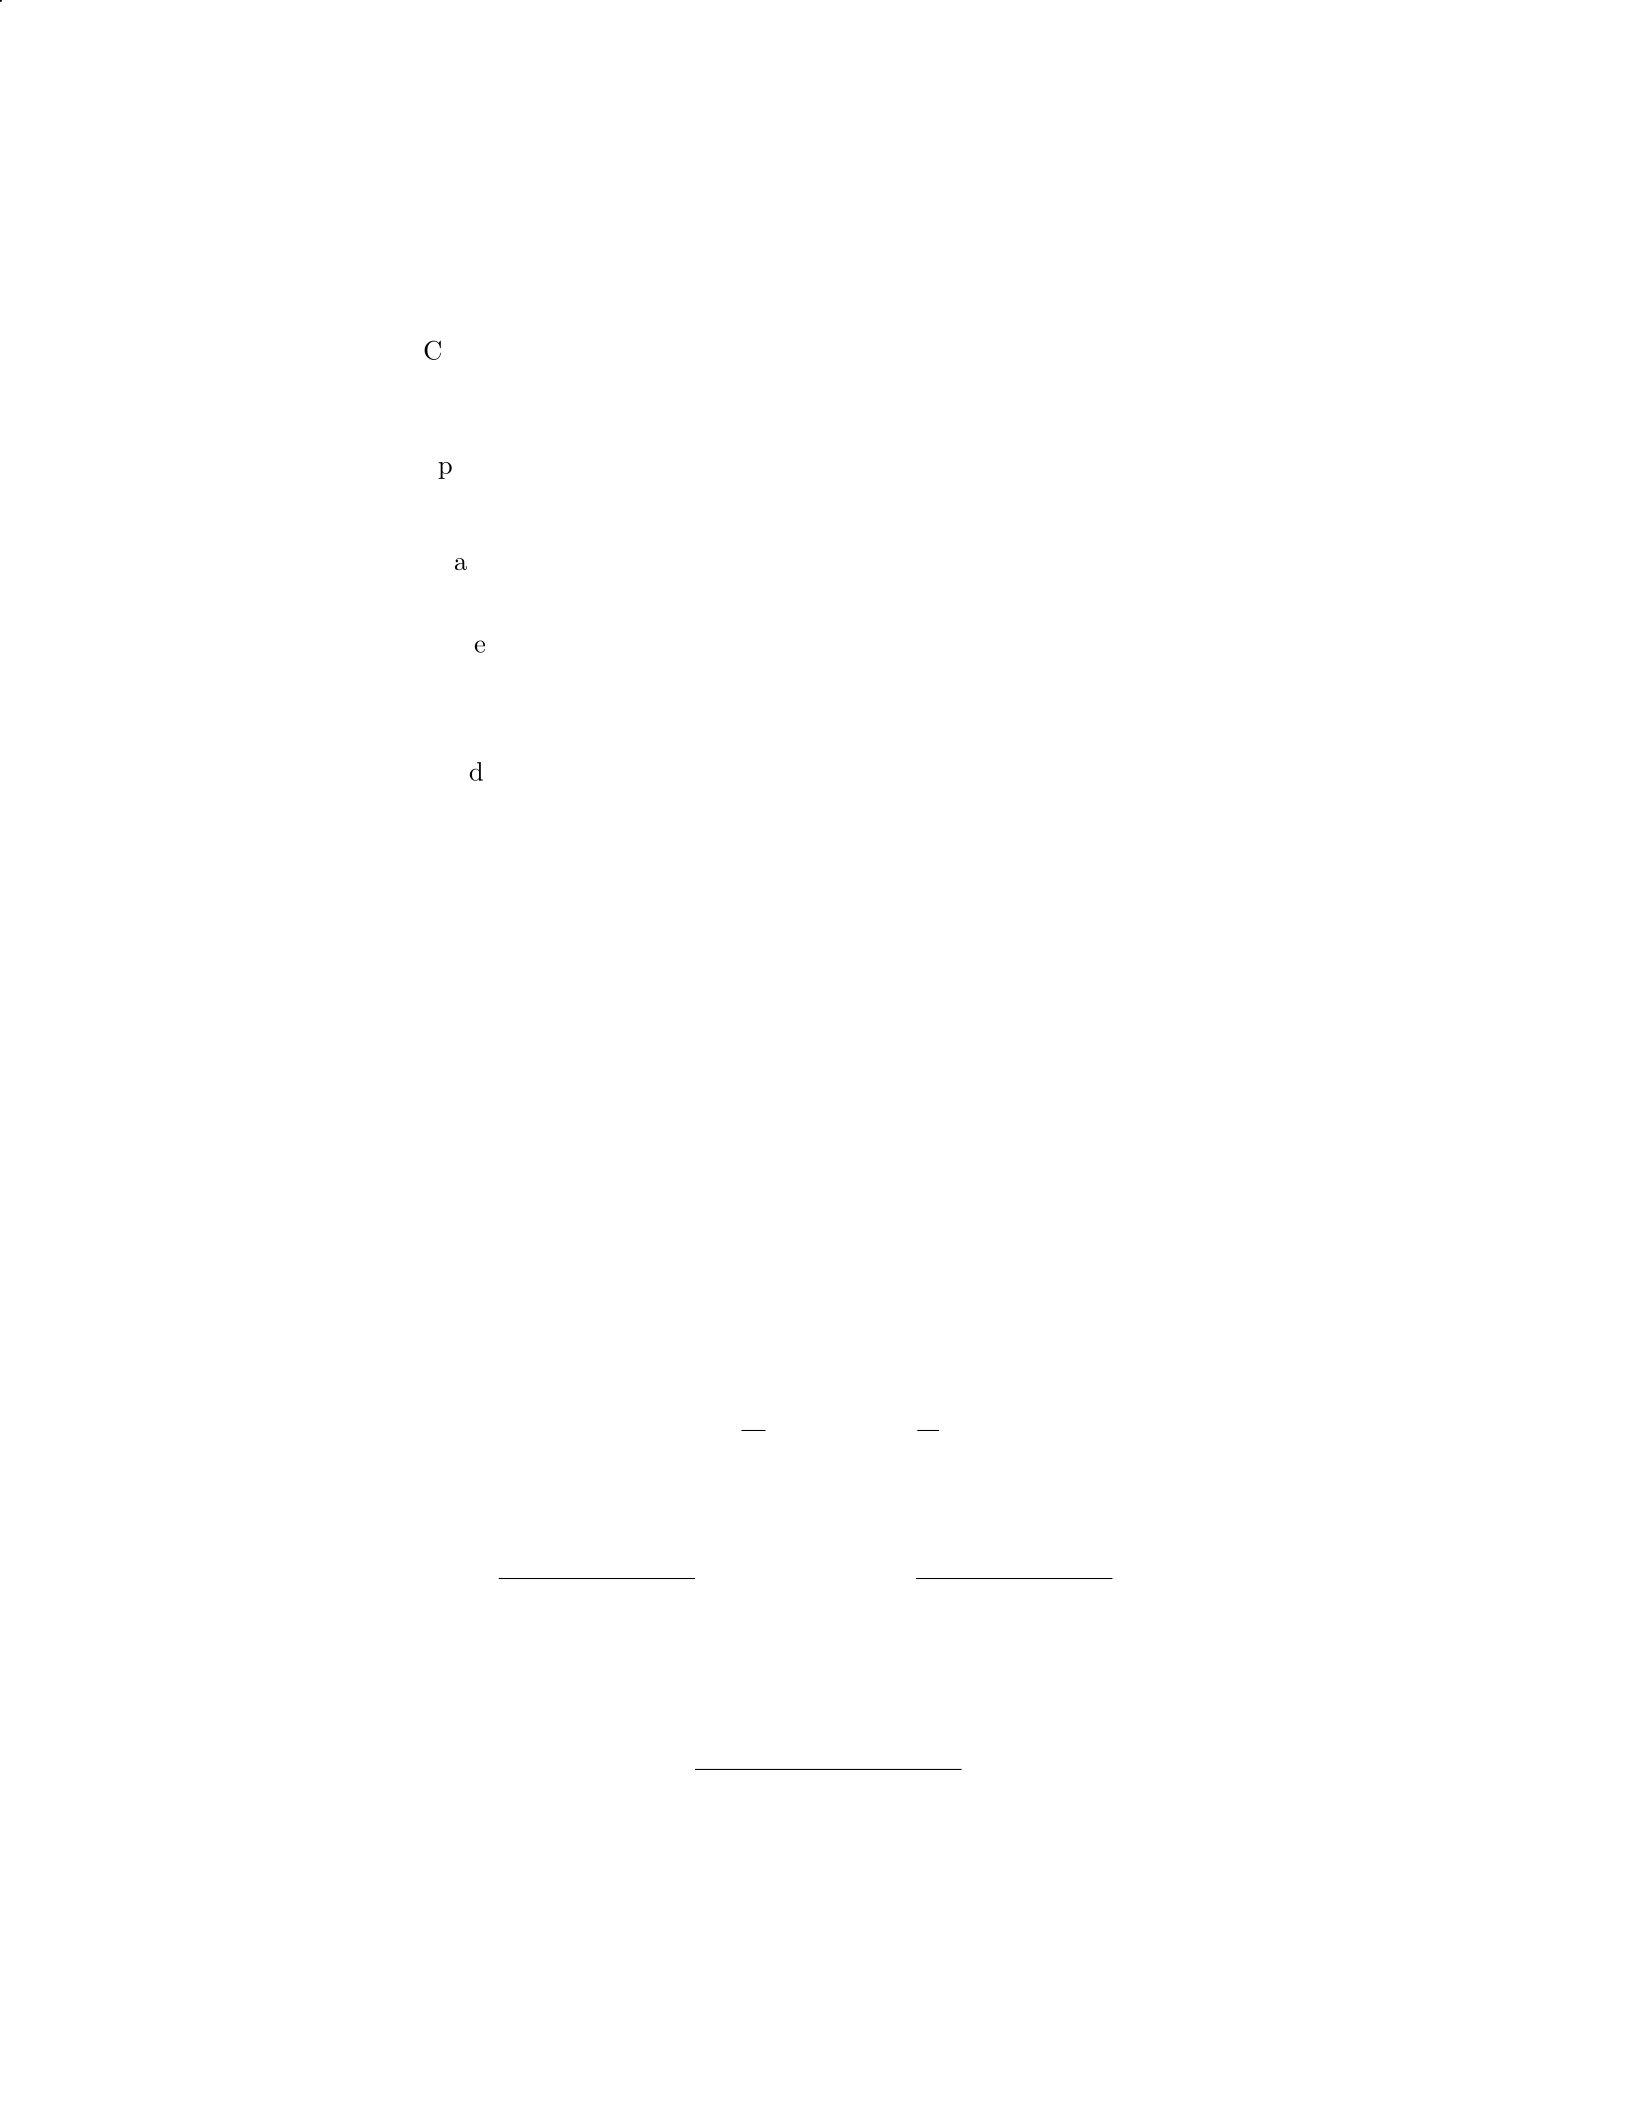
Choose an appropriate modeling technique (e.g., logistic regression, ran-
dom forest) to predict the suitable habitats for the plant species based on
the environmental variables.
Split the dataset into training and testing sets for model evaluation.
Step 6: Model Evaluation
Evaluate the performance of the model using metrics such as accuracy,
precision, recall, and area under the curve (AUC).
Make adjustments to the model if necessary based on the evaluation re-
sults.
Step 7: Model Validation
Validate the model by applying it to new data or using cross-validation
techniques to ensure its generalizability.
By following these steps, you can effectively analyze spatial data and develop
a predictive model for identifying suitable habitats for the rare plant species
based on environmental variables.
Question 28
Question
Consider a dataset consisting of the coordinates of cities in a country. The
dataset contains the following cities: City A (2,3), City B (5,7), City C (1,4),
City D (6,2), and City E (3,6). Perform spatial data analysis to determine the
city that is the farthest away from the centroid of all cities.
Solution
Step 1: Calculate the centroid of the cities.
The centroid (mean) coordinates (¯x, ¯y) of the cities can be calculated using
the formula:
¯x=xi
nand ¯y=yi
n
where (xi, yi) are the coordinates of each city and nis the total number of cities.
Calculating the centroid:
¯x=2+5+1+6+3
5= 3.4 and ¯y=3+7+4+2+6
5= 4.4
Therefore, the centroid of the cities is (3.4,4.4).
Step 2: Calculate the distance of each city from the centroid.
The Euclidean distance between two points (x1, y1) and (x2, y2) can be cal-
culated using the formula:
p(x2−x1)2+ (y2−y1)2
27
Calculating the distances of each city from the centroid: - City A: p(3.4−2)2+ (4.4−3)2=
1.14 - City B: p(3.4−5)2+ (4.4−7)2= 3.61 - City C: p(3.4−1)2+ (4.4−4)2=
2.50 - City D: p(3.4−6)2+ (4.4−2)2= 2.79 - City E: p(3.4−3)2+ (4.4−6)2=
1.41
Step 3: Identify the city farthest from the centroid.
The city farthest from the centroid is City B, with a distance of 3.61 units.
Hence, City B is the farthest away from the centroid of all cities.
Question 29
Question
In a study on spatial data analysis and modeling, a researcher collects data on
the pollution levels at various locations in a city. The researcher wants to create
a spatial model to predict pollution levels at unmeasured locations based on
the data collected. One approach is to use kriging, a geostatistical interpolation
technique. Define kriging and explain the basic steps involved in performing
kriging for spatial data analysis.
Solution
To perform kriging for spatial data analysis, the following basic steps are in-
volved:
Step 1: Data Collection and Exploration - Collect pollution level data
at various locations in the city. - Explore the spatial patterns and characteristics
of the data to understand the underlying spatial structure.
Step 2: Variogram Calculation - Calculate the semivariogram, which
measures the spatial variability or autocorrelation of the pollution levels be-
tween pairs of locations at different distances. - The semivariogram provides
information about the spatial dependence of the data and helps in determining
the appropriate model for interpolation.
Step 3: Model Fitting - Fit a variogram model to the experimental semi-
variogram obtained in Step 2. - Common variogram models include spherical,
exponential, and Gaussian models, which describe the spatial autocorrelation
structure of the data.
Step 4: Kriging Estimation - Using the variogram model fitted in Step
3, interpolate pollution levels at unmeasured locations based on the nearby
measured data points. - Kriging estimates pollution levels by optimizing a linear
combination of the measured values, giving higher weights to nearby locations
and lower weights to distant locations.
Step 5: Cross-Validation - Validate the accuracy of the kriging predic-
tions by performing cross-validation. - Compare the predicted pollution levels at
measured locations with the actual measured values to assess the performance
of the kriging model.
28

Step 6: Prediction and Visualization - Once the kriging model is vali-
dated, use it to predict pollution levels at any unsampled locations in the city.
- Visualize the predicted pollution levels on a map to identify high- and low-
pollution zones and provide insights for decision-making and policy planning.
Question 30
Question
Consider a dataset containing the location of major cities in a country, along
with their respective populations. You are tasked with analyzing the spatial
distribution of these cities to identify any underlying patterns or clusters. De-
scribe the steps you would take to conduct a spatial data analysis and modeling
of this dataset.
Solution
To conduct a spatial data analysis and modeling of the dataset containing major
cities and their populations, we can follow these steps:
Step 1: **Exploratory Data Analysis (EDA)** - Examine the dataset to
understand its structure, variables, and any missing values. - Plot the locations
of major cities on a map to visualize their spatial distribution. - Calculate basic
summary statistics for the population variable to understand its distribution.
Step 2: **Spatial Autocorrelation Analysis** - Conduct a spatial autocorre-
lation analysis to determine if there are any spatial dependencies in the dataset.
- Use methods like Moran’s I statistic to measure clustering or dispersion of
cities based on their populations.
Step 3: **Spatial Clustering Analysis** - Apply clustering algorithms such
as K-means clustering or DBSCAN to identify any spatial patterns or clusters
of cities based on their populations. - Evaluate the results to understand the
characteristics of each cluster.
Step 4: **Spatial Regression Modeling** - Perform spatial regression model-
ing to analyze the relationship between the population of cities and their spatial
attributes. - Use techniques like spatial lag or spatial error models to account
for spatial dependencies in the data.
Step 5: **Prediction and Visualization** - Use the developed spatial model
to predict the population of cities at unobserved locations. - Visualize the
predicted values on a map to understand the spatial distribution of population
more effectively.
By following these steps, we can conduct a comprehensive spatial data anal-
ysis and modeling of the dataset containing major cities and their populations,
thereby revealing any underlying patterns or clusters in their spatial distribu-
tion.
29

