Homework Notes Week 4
I. Random Variables and Probability Distributions
a. Random Variable
I. If we roll a die, the possible outcomes are the numbers
1,2,3,4,5 and 6, and each of these numbers has probability
1/6.
II. Rolling a die is a probability experiment whose outcomes are
numbers.
III. The outcome of such an experiment is called a random
variable.
1. Random Variable- a numerical outcome of a probability
experiment.
b. Discrete and Continuous Random Variables
I. Discrete random variables are random variables whose
possible values can be listed.
1. Examples:
a. The number that comes up on the roll of a die.
b. The number of siblings a randomly chosen person
has.
II. Continuous random variables are random variables that can
take on any value in an interval.
1. The height of a randomly chosen college student.
2. The amount of electricity used to light a randomly chosen
classroom.
c. Probability Distribution
I. A probability distribution for a discrete random variable
specifies the probability for each possible value of the random
variable.
1. Properties:
a. 0≤P(x)≤1 for every possible x
b. ∑P(x)=1
2. Example:
a. Four patients have made appointments to have
their blood pressure checked at a clinic. Let X be
the number of them that have high blood pressure.
The probability distribution of X is:
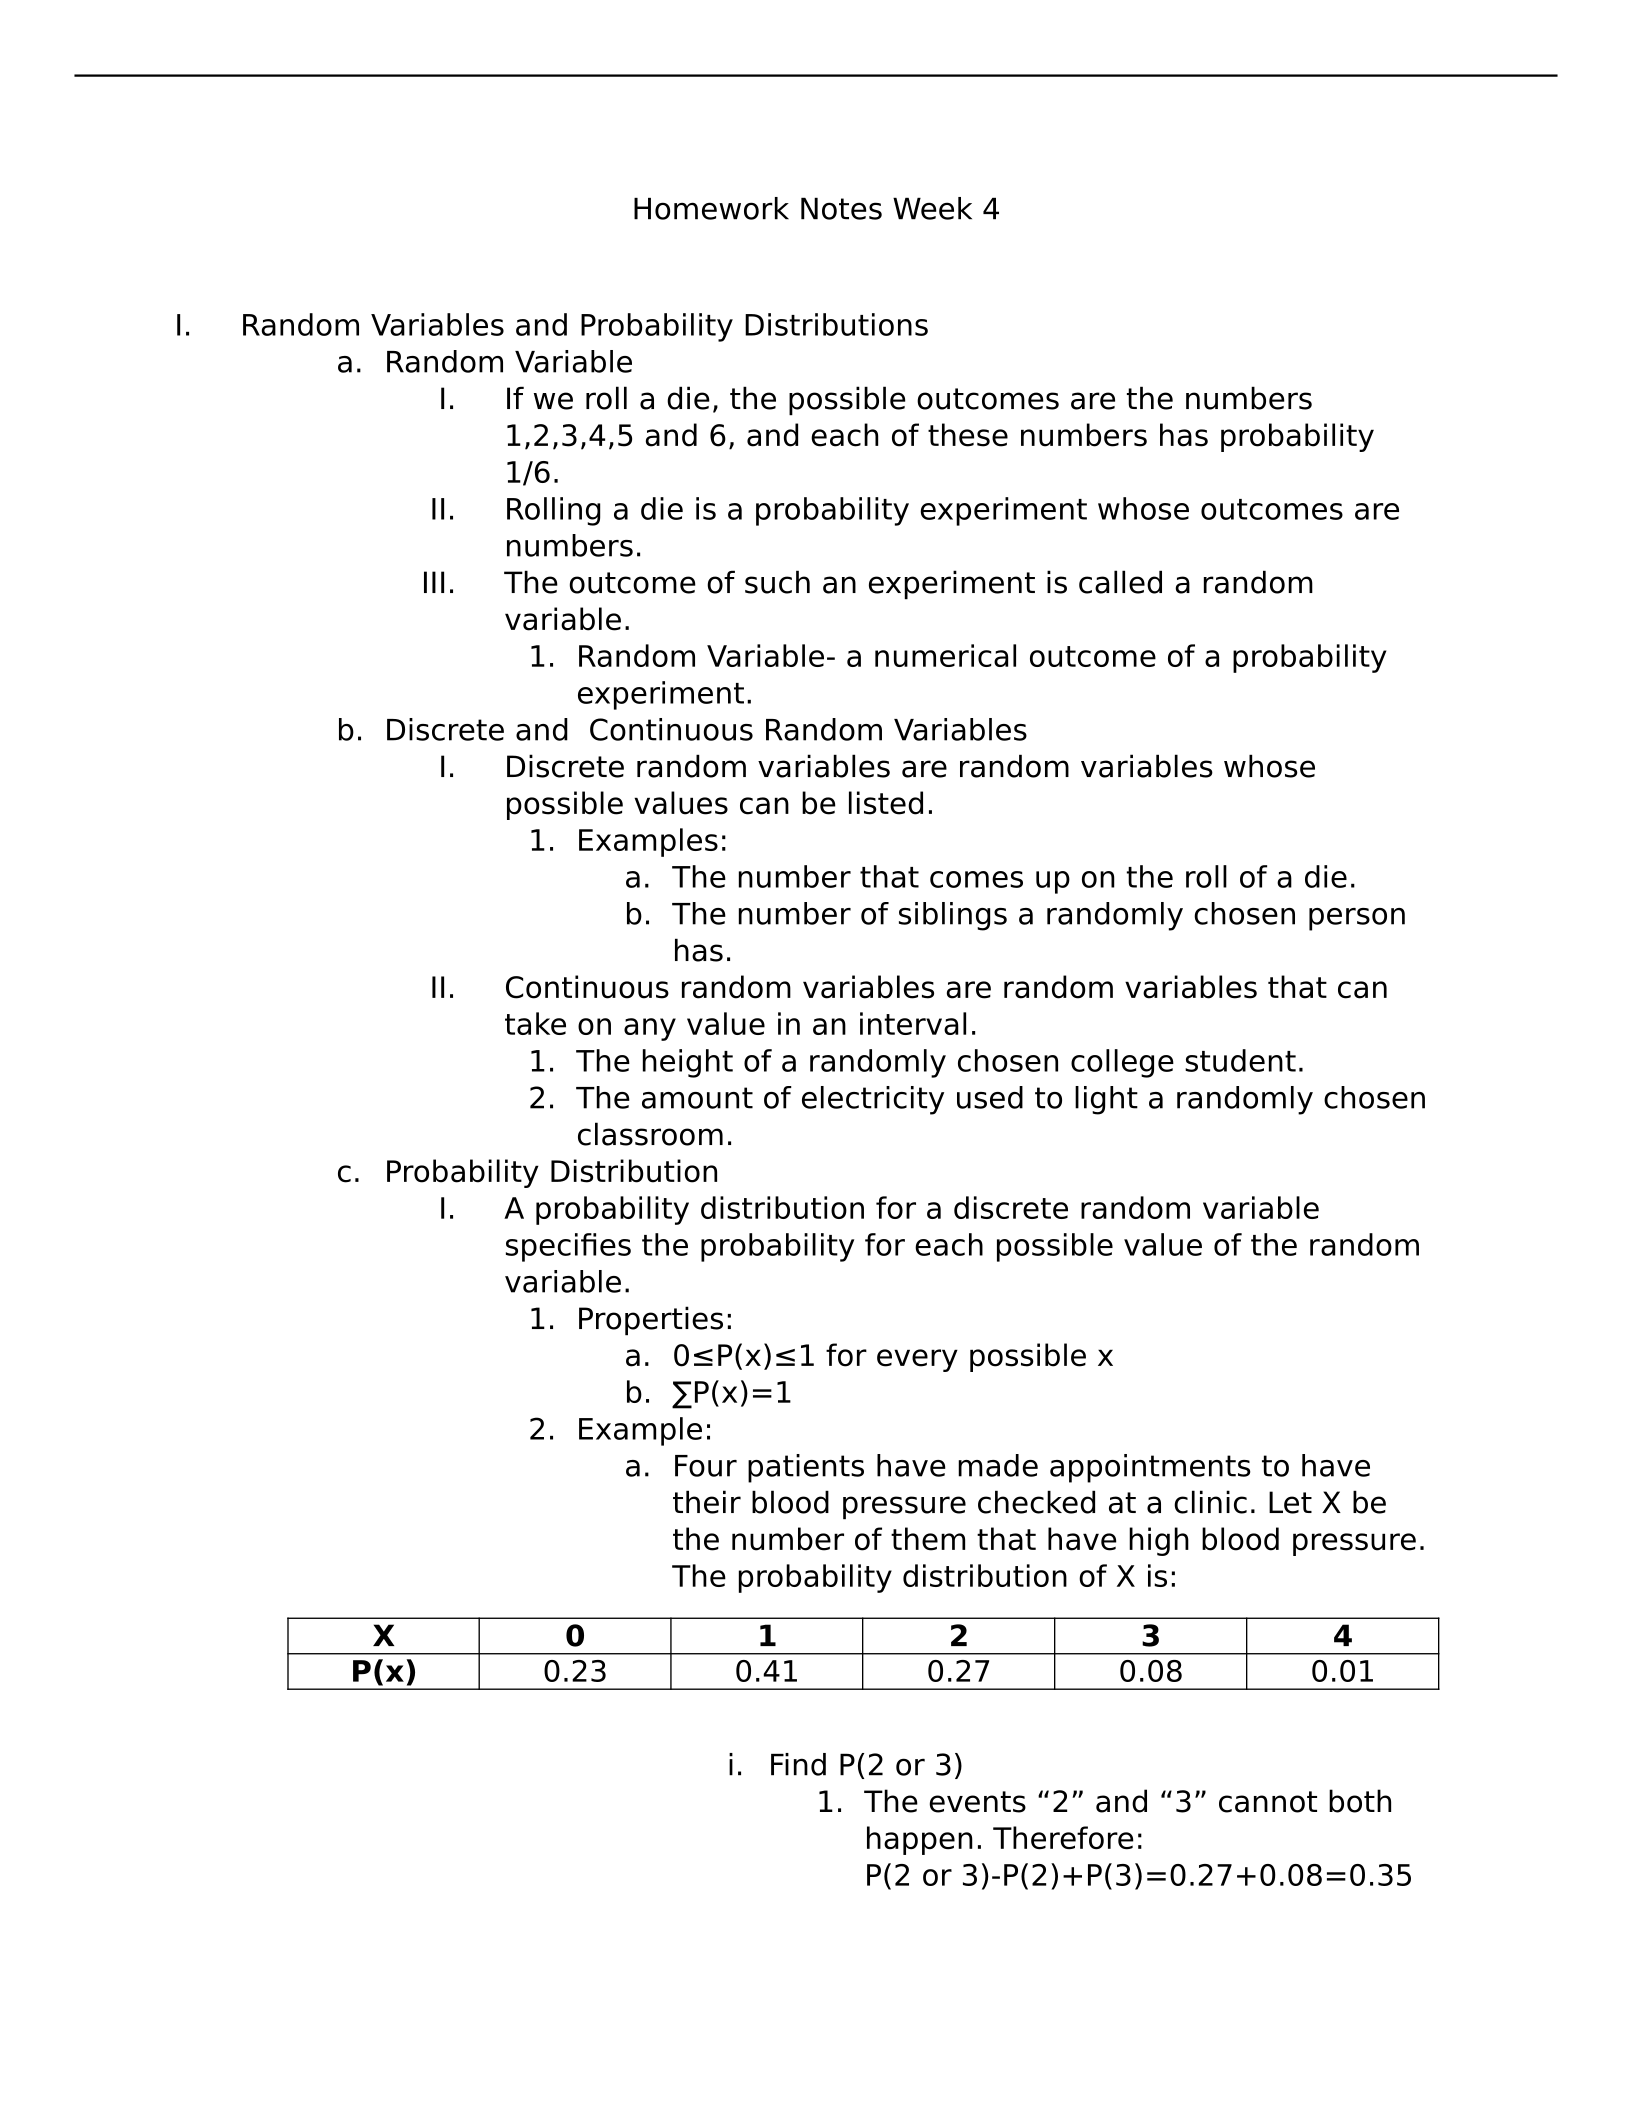
X 0 1 2 3 4
P(x) 0.23 0.41 0.27 0.08 0.01
i. Find P(2 or 3)
1. The events “2” and “3” cannot both
happen. Therefore:
P(2 or 3)-P(2)+P(3)=0.27+0.08=0.35
ii. Find P(More than 1)
1. “More than 1” means “2 or 3 or 4.” We
have:
P(More than 1)-P(2 or 3 or
4)=0.27+0.08+0.01=0.36
iii. Find P(At least 1)
1. P(At least 1)=1-P(None)=1-P(0)=1-
0.23=0.77
II. Determining a Probability Distribution
a. A probability distribution for a discrete random variable specifies the
probability for each possible value of the random variable.
I. Example:
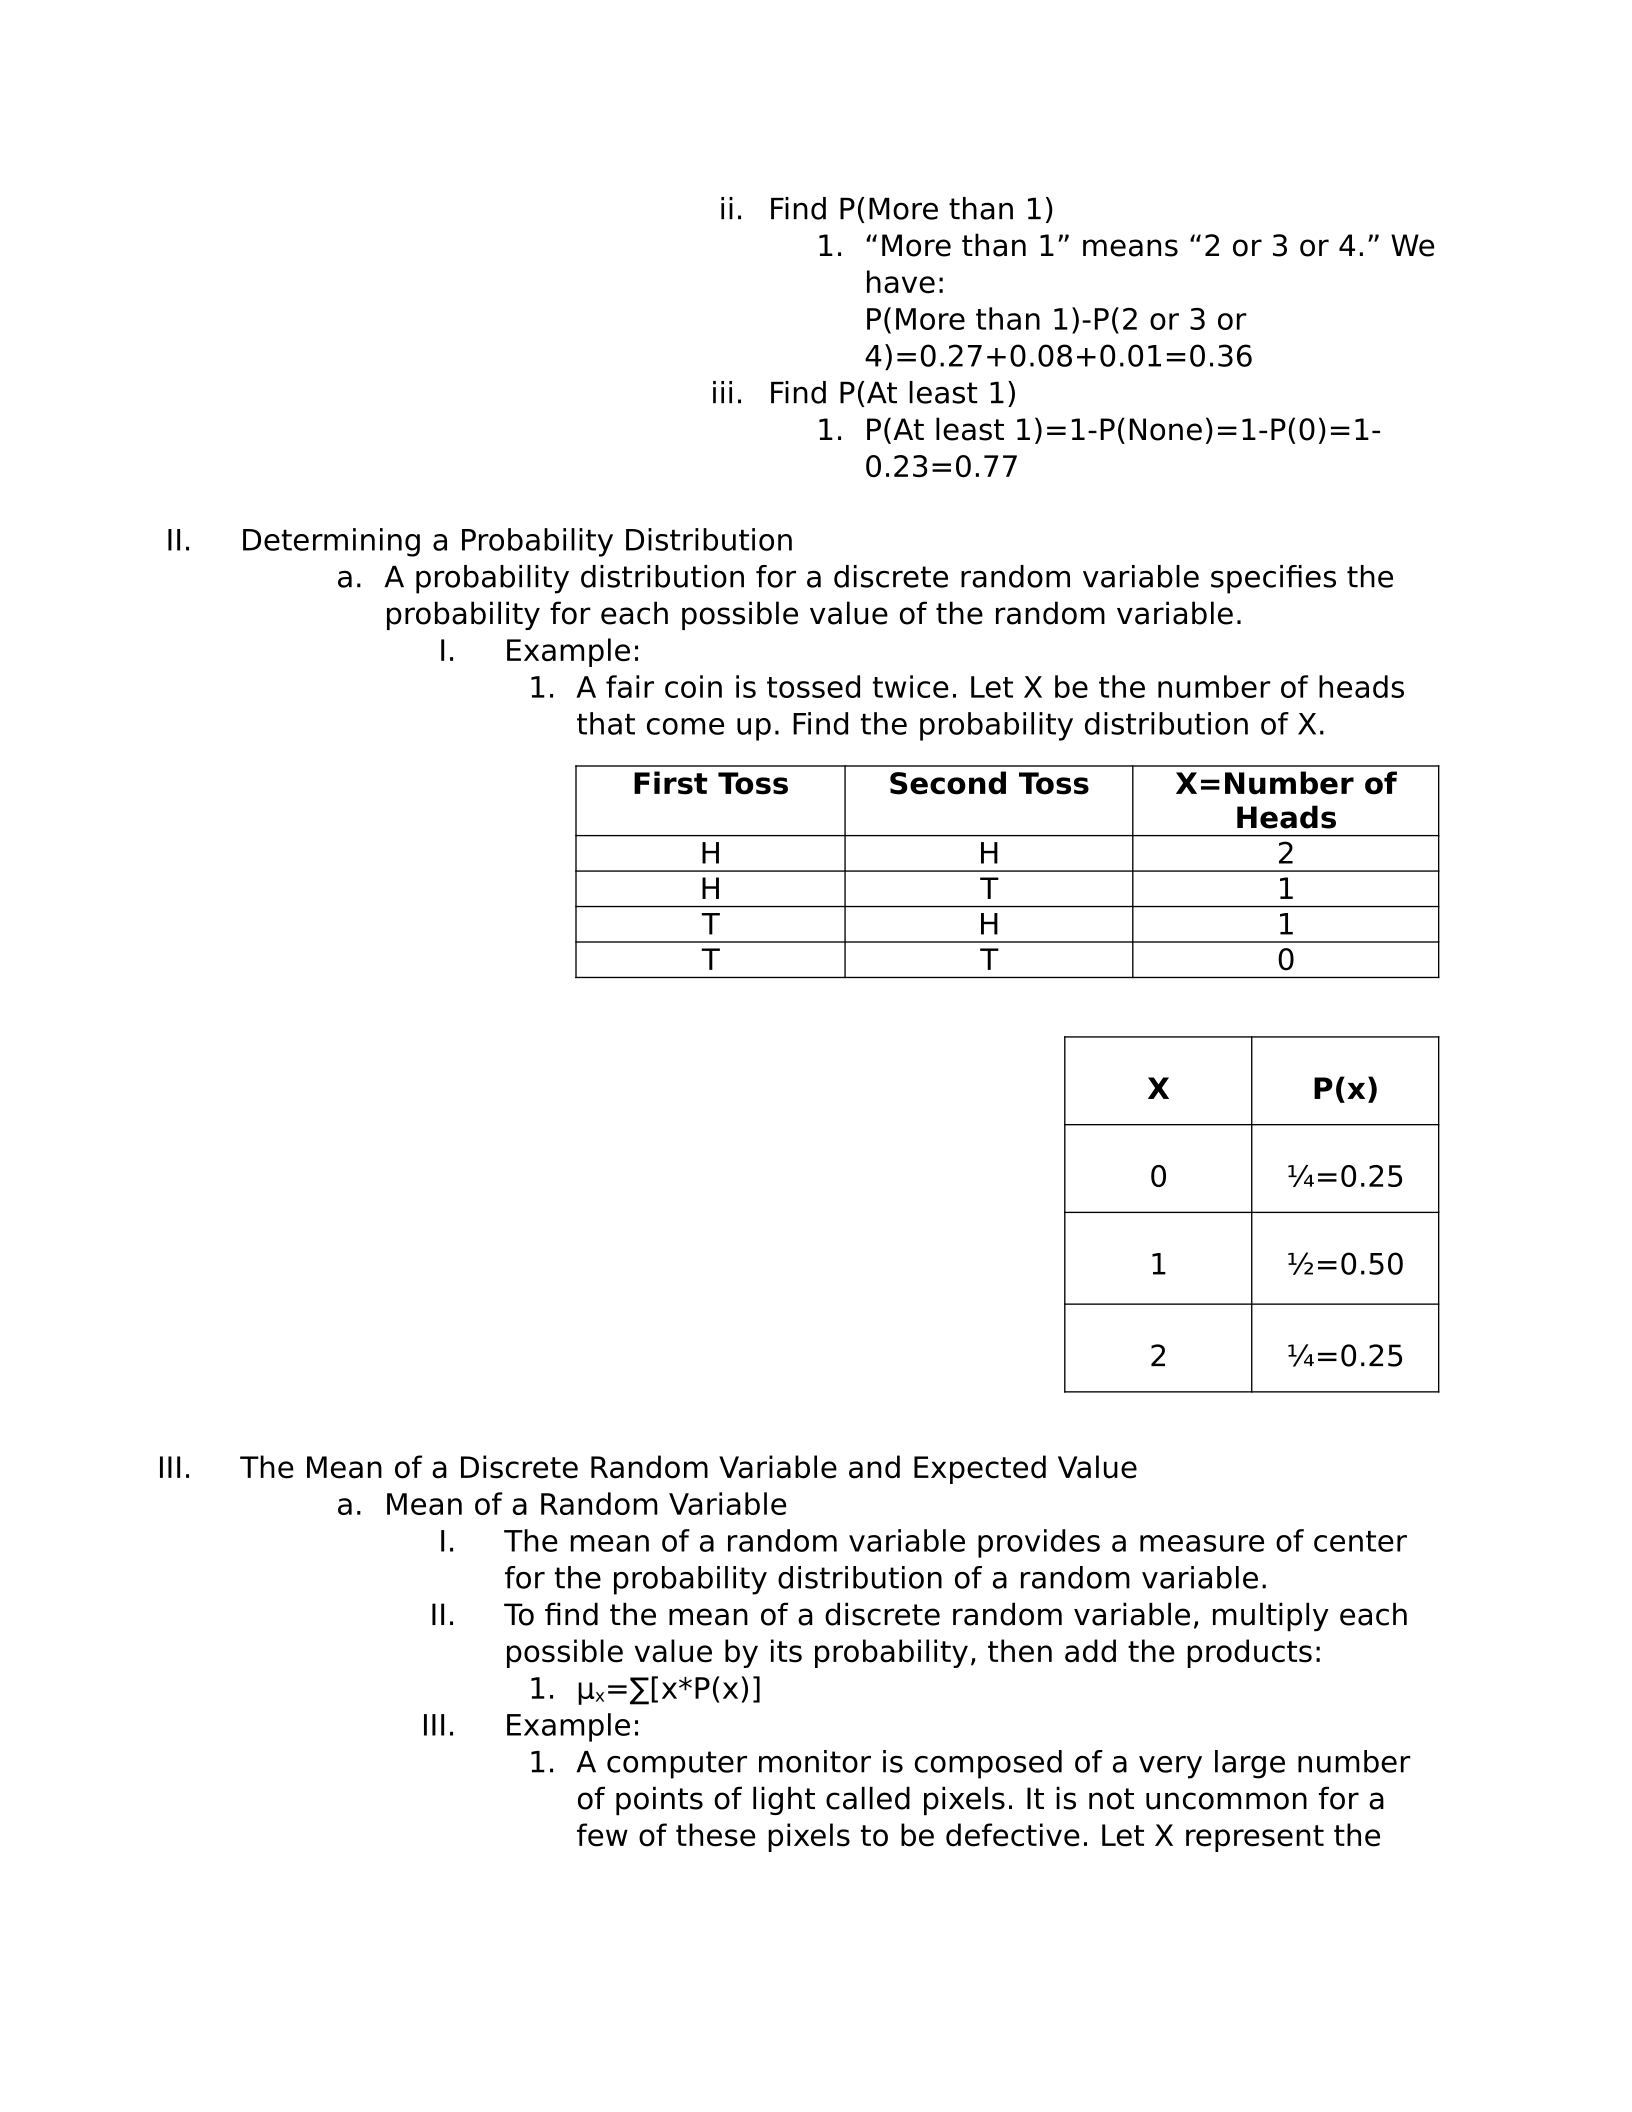
1. A fair coin is tossed twice. Let X be the number of heads
that come up. Find the probability distribution of X.
First Toss Second Toss X=Number of
Heads
H H 2
H T 1
T H 1
T T 0
X P(x)
0 ¼=0.25
1 ½=0.50
2 ¼=0.25
III. The Mean of a Discrete Random Variable and Expected Value
a. Mean of a Random Variable
I. The mean of a random variable provides a measure of center
for the probability distribution of a random variable.
II. To find the mean of a discrete random variable, multiply each
possible value by its probability, then add the products:
1. µx=∑[x*P(x)]
III. Example:
1. A computer monitor is composed of a very large number
of points of light called pixels. It is not uncommon for a
few of these pixels to be defective. Let X represent the
number of defective pixels on a randomly chosen monitor.
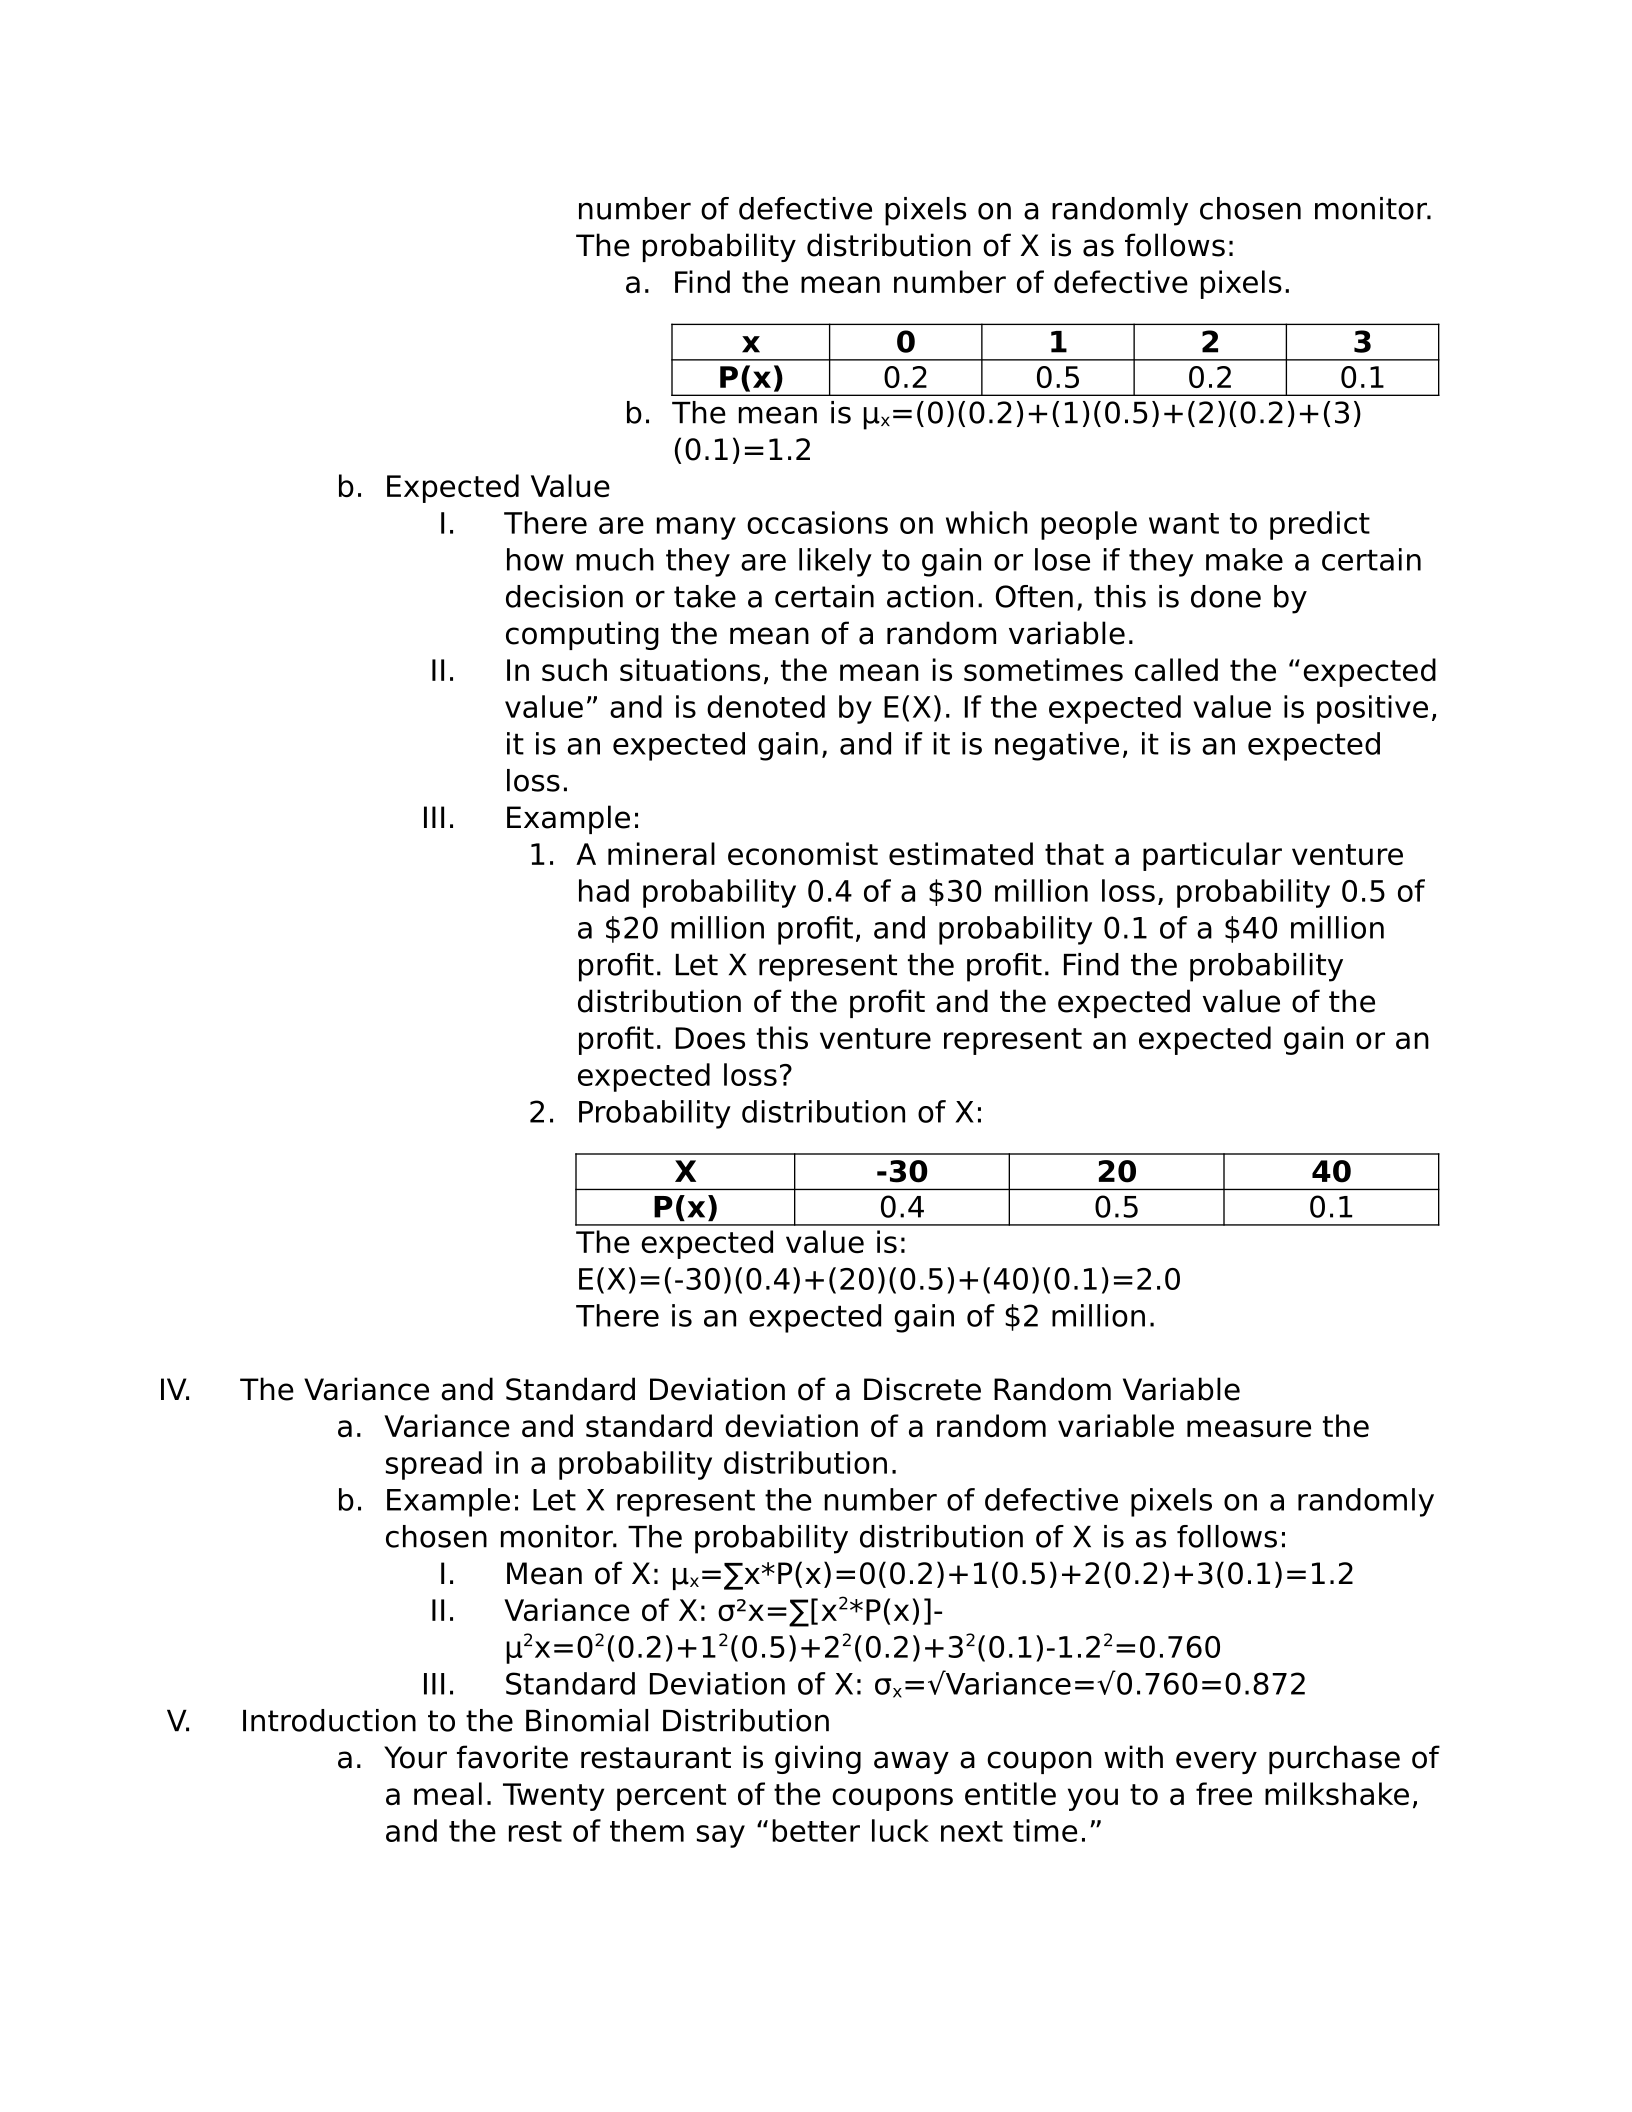
The probability distribution of X is as follows:
a. Find the mean number of defective pixels.
x0123
P(x) 0.2 0.5 0.2 0.1
b. The mean is µx=(0)(0.2)+(1)(0.5)+(2)(0.2)+(3)
(0.1)=1.2
b. Expected Value
I. There are many occasions on which people want to predict
how much they are likely to gain or lose if they make a certain
decision or take a certain action. Often, this is done by
computing the mean of a random variable.
II. In such situations, the mean is sometimes called the “expected
value” and is denoted by E(X). If the expected value is positive,
it is an expected gain, and if it is negative, it is an expected
loss.
III. Example:
1. A mineral economist estimated that a particular venture
had probability 0.4 of a $30 million loss, probability 0.5 of
a $20 million profit, and probability 0.1 of a $40 million
profit. Let X represent the profit. Find the probability
distribution of the profit and the expected value of the
profit. Does this venture represent an expected gain or an
expected loss?
2. Probability distribution of X:
X -30 20 40
P(x) 0.4 0.5 0.1
The expected value is:
E(X)=(-30)(0.4)+(20)(0.5)+(40)(0.1)=2.0
There is an expected gain of $2 million.
IV. The Variance and Standard Deviation of a Discrete Random Variable
a. Variance and standard deviation of a random variable measure the
spread in a probability distribution.
b. Example: Let X represent the number of defective pixels on a randomly
chosen monitor. The probability distribution of X is as follows:
I. Mean of X: µx=∑x*P(x)=0(0.2)+1(0.5)+2(0.2)+3(0.1)=1.2
II. Variance of X: σ²x=∑[x2*P(x)]-
µ2x=02(0.2)+12(0.5)+22(0.2)+32(0.1)-1.22=0.760
III. Standard Deviation of X: σx=√Variance=√0.760=0.872
V. Introduction to the Binomial Distribution
a. Your favorite restaurant is giving away a coupon with every purchase of
a meal. Twenty percent of the coupons entitle you to a free milkshake,
and the rest of them say “better luck next time.”
I. Suppose that ten of you order lunch at this restaurant. What is
the probability that three of you win a free milkshake?
b. Binomial Distribution Conditions
I. A fixed number of trials is conducted.
II. Two possible outcomes for each trial: “success” and “failure”.
III. Probability of success is the same on each trial.
IV. The trials are independent-the outcome of one trial does not
affect the outcomes of the other trials.
V. The random variable X represents the number of successes
that occur.
VI. Notation: n=number of trials, p=success probability
VI. Computing Binomial Probabilities (EXCEL)
a. =BINOM.DIST(x,n,p___)
I. This command takes 4 values at its arguments.
1. The first argument is the number of successes, X.
2. The second argument is the number of trials, which is N.
3. The third argument is the probability of success, P.
4. The fourth argument is a true/false value that we
determine by looking for a cumulative probability or an
exact one.
a. If we use false, then we are finding the probability
of exactly X successes.
b. If we use true, then we are finding the probability of
X or fewer successes.
VII. Mean, Variance, and Standard Deviation of a Binomial Random Variable
a. Let X be a binomial random variable with n trials and success
probability p.
I. Then the mean of X is: µx=np
II. The variance of X is: σ2x=np(1-p)
III. The standard deviation of X is: σx=√np(1-p)
b. Example:
I. The probability that a new car of a certain model will require
repairs during the warranty period is 0.15. A particular
dealership sells 25 such cars. Let X be the number that will
require repairs during the warranty period. Find the mean,
variance, and standard deviation of X.
II. There are n=25 trials, with success probability p=0.15
III. Mean: µx=np=(25)(0.15)=3.75
IV. Variance: σ2x=np(1-p)=25*0.15(1-0.15)=3.1875
V. Standard Deviation: σx=√np(1-p)=√25*0.15(1-0.15)=1.785
VIII. Exercise: The Binomial Distribution (EXCEL)
a. The Agency for Healthcare Research and Quality reported that 53% of
people who had coronary bypass surgery in a recent year were over
the age of 65. Fifteen coronary bypass patients are sampled.
b. Find the probability that exactly 9 of them are over the age of 65.
I. P(Exactly 9): =BINOM.DIST(9,15,0.53,FALSE)=0.1780
c. Find the probability that more than 10 of them are over the age of 65.
I. P(More than 10): =1-BINOM.DIST(10,15,0.53,TRUE)=0.0920
d. Find the probability that fewer than 8 of them are over the age of 65.
I. P(Fewer than 8): =BINOM.DIST(7,15,0.53,TRUE)=0.4065
IX. Introduction to the Normal Distribution
a. Probability Density Curves
I. The figure in the video presents a relative frequency histogram
for the particle emissions of a sample of 65 vehicles. If we had
information on the entire population, containing millions of
vehicles, we could make the rectangles extremely narrow.
II. The histogram would then look smooth and could be
approximated by a curve. The curve used to describe the
distribution of this variable is called the probability density
curve of the random variable.
III. The probability density curve tells what proportion of the
population falls within a given interval.
b. Area and Probability Density Curves
I. The area under probability density curve between any two
values a and b has two interpretations:
1. It represents the proportion of the population whose
values are between a and b.
2. It represents the probability that a randomly selected
value from the population will be between a and b.
c. Properties of Probability Density Curves
I. This region above a single point has no width, thus no area.
Therefore, if X is a continuous random variable, P(X=a)=0 for
any number a.
II. This means that P(a<X<b=P(a≤X≤b) for any numbers a and b.
III. That is, it doesn’t matter if we include the endpoints or not, it
doesn’t change the value of the probability.
IV. For any probability density curve, the area under the entire
curve is 1, because this area represents the entire population.
d. Normal Curves
I. Probability density curves comes in many varieties, depending
on the characteristics of the population they represent.
II. Many important statistical procedures can be carried out using
only one type of probability density curve, called a normal
curve.
III. A population that is represented by a normal curve is said to
be normally distributed, or to have a normal distribution.
e. Properties of a Normal Curve
I. The population mean determines the location of the peak.
II. The population standard deviation measures the spread of the
population.
III. Therefore, the normal curve is wide and flat when the
population standard deviation is large, and tall and narrow
when the population standard deviation is small.
IV. The mean and median of a normal distribution are equal and
they both equal to the mode.
f. Properties of Normal Distributions
I. The normal distribution follows the Empirical Rule:
1. Approximately 68% of the data are within 1 standard
deviation of the mean.
2. Approximately 95% of the data are within 2 standard
deviations of the mean.
3. Approximately 99.7% of the data are within 3 standard
deviations of the mean.
g. Standardization
I. The z-score of a data value represents the number of standard
deviations that data value is above or below the mean.
II. If x is a value from a normal distribution with mean µ and
standard deviation σ, we can convert x to a z-score by using a
method known as standardization.
III. The z-score of x is z=x-µ/σ
1. Example:
a. Consider a woman whose height is x=67 inches
from a normal population with mean µ=64 inches
and σ=3 inches.
b. Z=x-µ/ σ=67-64/3=1
h. Standard Normal Curve
I. A normal distribution can have any mean and any positive
standard deviation.
II. However, the normal distribution with a mean of 0 and
standard deviation of 1 is known as the standard normal
distribution. Z-scores that have been converted from a normal
distribution follow a standard normal distribution.
X. Area Between Two Z-Scores (EXCEL)
a. Find the area between z=-1.45 and z=0.42.
I. Sketch a normal curve, label the points z=-1.45 and z=0.42
and shade the area between them.
II. =NORM.S.DIST(z,_____)
1. Z-score for which the area is to the left, and TRUE since
cumulative probability is always true.
III. Area to the left of -1.45
1. =NORM.S.DIST(-1.45,TRUE)=0.0735
IV. Area to the left of 0.42
1. =NORM.S.DIST(0.42, TRUE)=0.6628
b. Lastly, we subtract the smaller area from the larger area to find the
area between the two z-scores.
I. 0.6628-0.0735=0.5893
XI. Find Z-scores Corresponding to Areas under the Normal Curve (EXCEL)
a. Often, we are given an area and we need the z-score that corresponds
to that area under the standard normal curve.
b. The mode, z=0, has an area of 0.5 both to its right and to its left.
c. Find the z-score that has an area of 0.26 to its left.
I. =NORM.S.INV(area)
1. Takes one value, given to the left
2. Area to the left of 0.26
a. =NORM.S.INV(0.26)=-0.6433
XII. Areas Under a Normal Curve (EXCEL)
a. In Excel, the norm-dot-dist command is used to compute the area
under a normal curve.
I. =NORM.DIST(x,µ,σ,____)
II. The command takes four arguments:
1. X=population value for which the area is to the left
2. µ=mean of the population
3. σ=standard deviation of the population
4. cumulative probability=TRUE (always use true)
XIII. Finding the Value from a Normal Distribution (EXCEL)
a. Often, we are given an area and we need the value from the population
that corresponds to that area under a normal curve.
b. The mean has an area of 0.5 both to its right and to its left.
c. =NORM.INV(area,µ,σ)
I. Area=given area to the left
II. µ=mean
III. σ=standard deviation
d. Example:
I. Scores on an IQ are normally distributed with mean=100 and
standard deviation=15.
1. What score separates the upper 2% of IQ scores from the
rest?
a. 0.02 is to its right, which means that 0.98 is to its
left
b. =NORM.INV(0.98,100,15)=130.8062
2. Which IQ scores separate the middle 90% from the rest?
a. If the middle is 0.9, then the combined tails are 0.1,
or 0.05 on each side of the middle (x1 and x2)
b. The area to the left of x1 is 0.05, and the area to the
left of x2 is 0.95.
c. Value with area 0.05 to its left
i. =NORM.INV(0.05,100,15)=75.3272
d. Value with area 0.95 to its left
i. =NORM.INV(0.95,100,15)=124.6728
XIV. Exercise: Application of Normal Value Corresponding to an Area (Tables and
Technology)
a. According to one source, the mean number of apps on a smartphone in
the United States is 90. Assume that the number of apps is normally
distributed with a standard deviation of 25.
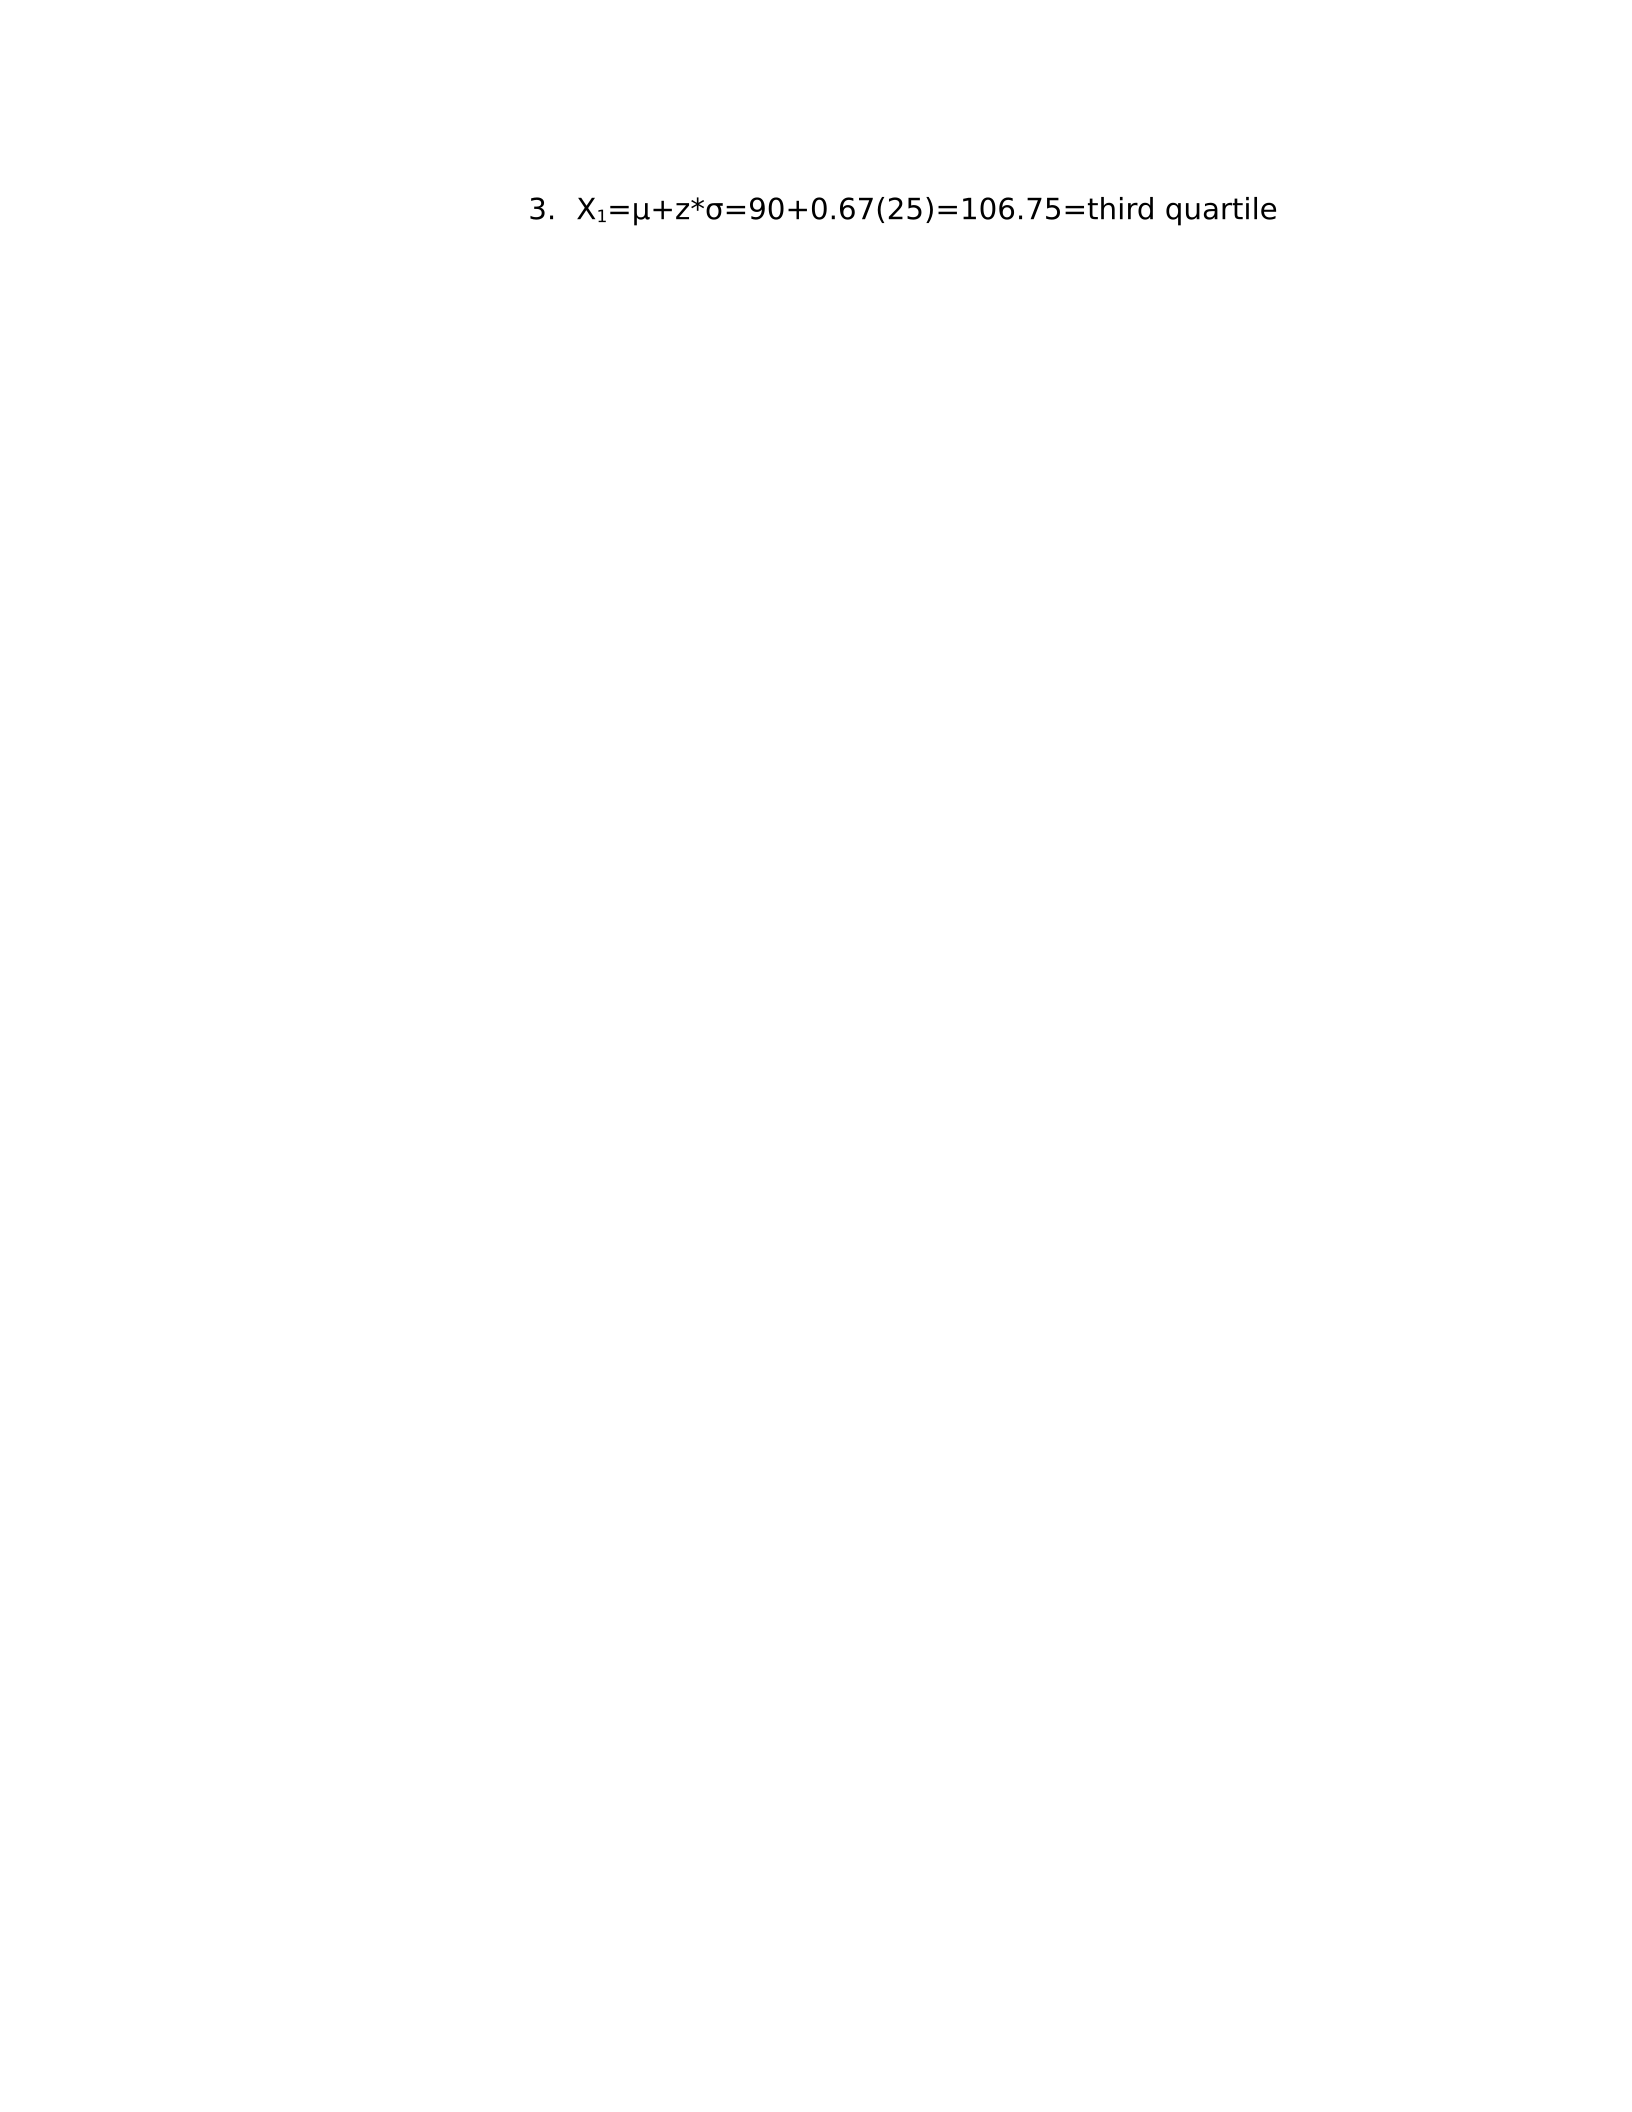
I. Find the third quartile of the number of apps.
1. 75% percentile=x1
2. =NORM.INV(0.75,90,25)=106.86224