


Blockchain Meets IoT: What Needs To Be Addressed
Chapter 1
Introduction
Internet of Things (IoT) has been emerged in both academia and industry since
early 2000s as one of the core technologies and ecosystems of the Next Generation
Network (NGN). Along with massive numbers of IoT sensors widely spread and
huge IoT data streams transmitted, researchers have put more e orts into↵
addressing the security issue due to centralized architecture. The Blockchain
technology has been showing its strong performance on decentralized security
when integrating with IoT network, i.e, Blockchain-based IoT. However, this can be
challenging. Traditional Blockchain technologies can hardly handle large-scale IoT
networks, while the inherent properties of IoT networks might also deteriorate the
performance of Blockchains. More studies on solving these challenges and
enhancing the integration are needed.
The thesis abstracts the aforementioned general challenges into the following
four problems.
• The lack of models which are capable of evaluating consensus algorithms in
large-scale networks discourages the participants who have no ability to
quantify the profits.
• The trilemma of scalability-security-decentralization in Blockchains hinders
the practical implementation of Blockchain-based IoT networks where high
scalability is desired.

• The transparency of Blockchains and the lack of access control reveal the
weak point of being implemented in the context of permissioned IoT
networks. • The compatibility of existing architecture of Blockchain-based
IoT is not good enough, e.g., the redundant IoT data reduce the throughput of
Blockchains.
The thesis addresses each of the challenges, by proposing novel models,
designs, and comprehensive comparison, as well as carrying out the corresponding
numerical and simulation.
This chapter first introduces the background of IoT and Blockchain, as well as
Blockchain-based IoT. This chapter then illustrates research topics and key
research points, followed by the overview of this thesis.
1.1 Background
1.1.1 Overview of IoT
IoT plays a core role in NGN and digitizational society [61, 127]. As the name
implies, IoT is more than just computer-to-computer or phone-to-phone
communication. It means the connection and communication among things,
indicating two important definitions. Firstly, the core and foundation of IoT is still
the Internet, but with extension and expansion based on current internet. Secondly,
clients have been extended to any physical items no matter nano and sophisticated
machines or even living things with nano-chip transplanted inside the body. As the
result, it has been successfully achieved the information exchange and
communication between “things”. IoT has been widely used in the integration of
network by means of intelligent perception, identification technology and

pervasive computing communication, etc, and therefore known as the third surge
of the global development of information posterior to computers and internet.
According to the analysis report of International Data Corporation (IDC)
updated in 2020 [87], the global spending regarding IoT technologies and services
was reached US$0.75 trillion in 2020, and would reach US$1.1 trillion by 2023. The
statistical data includes intelligent and embedded systems, connectivity services,
infrastructure, customized platforms of IoT, applications, security, analytics and IoT
professional services. It predicted that by the end of 2023, the population of IoT-
related equipment would reach approximately 13.15 billion [86]. Such a mass of
equipment is driven by, to some extent, the intelligence system, and the data
generated between clients and service providers. There still will have been a long
way to go to widen the scope of implementation of IoT, however, it is expected that
IoT will have a significant impact in many realms while IoT devices keep growing
and become seamless.
Ranged from powerful end-devices (e.g., smartphones and vehicular ad hoc
networks (VANETs)), to the cellular-based low-power wide-area networks
(LPWAN) (e.g., Narrowband IoT (NB-IoT) and Category M1 (CAT-M1)) and non-
cellularbased LPWAN (e.g., Long Range (LoRa) and Sigfox), it has been shown that
IoT is taking a great impact on the many realms in diversified ways [195, 112, 114],
including but not limited to:
•Food and Beverage: IoT can be used to track the entire process of consumer
goods, from processing, sales to quality and storage ability. Given an example,
the inspection and quarantine of outgoing beef from Australia to China
require IoT technologies to be the foundation to collect and analyze the big
data of even individual cattle from born to death.

•Healthcare: IoT technologies can be used to collect huge amount of
healthcare data in an end-to-end manner, including event monitors, clinical
research data, emergency response and home advanced care. This can
increase the size of data, the e ciency of data collection, and enhance the
treatment based on the better accuracy of prediction derived from the data,
e.g., implementing IoT technologies to defense against COVID-19 [155, 168].
•Smart Transportation and Logistics: Along with the rapid development of
VANETs, vehicles have increasingly powerful capabilities of sensing,
communicating and data processing. IoT technologies can be used to enhance
these capabilities and track the product status throughout the path.
Specifically, this information, which is shared among manufacturer,
warehouse, retailer, and customers, includes the geography and time series
tracking of location and operational status of vehicles.
•Smart Home/Grid/City: IoT technologies can be used in individual homes to
enhance the quality of life by serving environment-friendly, intelligent, and
automated facilities. Similarly, the smart grid and smart city are widely used
to replace traditional infrastructure to provide reliable and e cient energy
(e.g., electricity, gas, water) services.
Existing studies have dug deep into centralized architecture, such as a
centralized management model [203] or a centralized global IoT Platform [182],
and cloud-based architecture, such as a service-oriented hierarchical cloud
architecture for IoT [75] or an IoT-fog-cloud based architecture [60]. Software-
Defined-Network (SDN)-based IoT architecture [124] and Network-Function-
Virtualization (NFV)-based architecture [164] are also recently proposed. These
architectures aim to separate the data and control panels in a centralized manner,

in order to reduce the data loading in centralized management. With the
development of cloud, IoT cloud platform has become the mainstream architecture
[157].
However, in order to collect and analyze the data transmitted among the
exorbitant numbers of gateways and sensors in real-time context, it becomes di cult
to have the centralized infrastructure placed on cloud or private data centre, and
process the data in a collective way. There are two issues to which the existing
studies do not pay enough attention. Firstly, millions of end-devices constitute huge
amount of data that a purely centralized infrastructure will be tough to guarantee
the e ciency and scalability. Secondly, IoT security becomes an inevitable problem
including the scalability, privacy, and authentication, which results in several
vulnerability making an IoT network prone to failures and attacks, such as the
single point of failure (SPOF) and Distributed Denial of Service (DDoS) [199, 26,
190, 76]. There have been found that the following critical issues exist in live
environments:
• Amazon Cloud Service, Microsoft Azure, and Alicloud su ered from the↵
service outage from 2017 to 2019, leading to the huge losses of data service
for customers [20, 134, 204].
• The public cloud, the private cloud, and the hybrid cloud hardly tolerate the
Byzantine Failure [89]. The Byzantine Failure takes malicious nodes into
account, which is the most complicated failure mode in a distributed system
[104].
• The cloud services lack trustworthy tamper-resistance for data storage and
access control [122].

A centralized IoT architecture on cloud is not enough to ensure the IoT security.
This leads to the core objective of the thesis, implementing a reliable and
trustworthy Blockchain-based architecture for IoT networks. The architecture
considers the cloud service as an optional infrastructure, on top of which a
Blockchain system is built. The decentralized security of Blockchain has been
thought as a disruptive solution to the challenges that existing IoT networks are
facing.
1.1.2 Overview of Blockchains
1.1.2.1 Decentralization and the Byzantine Generals Problem
The typical decentralized security problem, namely the Byzantine Generals
Problem (BGP), was first proposed by Lamport, Shostak and Pease in 1982. More
specifically, this problem can be described as follows [104]:
There are three generals encircle an enemy city with one of them being the
leader among them. They can only decide whether to attack or retreat. In hope of a
plan for attacking the city being eventually finalized, each of them wishes to reach
the consensus prior to the action. However, one of them being the traitor, targets on
confusing others and disturbing the consistency of the final command. In order to
solve this issue, the following requirements must hold:
• The loyal generals must follow the leader, if the leader is loyal;
• Any two loyal generals of them must finalize the same command, if the leader
is a traitor.
In the case of the leader being likely a traitor, the general Bob cannot finalize a
command of “attack” even when he receives an “attack” from others. Thus Bob
needs to inquire of the other generals about the command they receive from the

leader. However, it turns out to be a dilemma for Bob to recognize whether the
leader or one of the generals is the traitor, if Bob receives a “attack” directly from
the leader but a “retreat” from one of the other generals. The traitor in this case is
also called a Byzantine failure, which is defined as a node either sending malicious
messages or pretending to be a normal timeout failure [104]. They also show that
there does not exist a solution for N generals, where 0 < N 3, being able to
achieve the consistency in any situation in the presence of a single traitor. Yet, the
problem is shown solvable for N 4 where any general could find the majority in a
consensus under the premise of a responsive leader in that round, i.e., weak-
synchronous; see detailed proof in [104]. Concretely, for any N that satisfies N 3f +
1, where f denotes the number of traitors, there always exists a deterministic
algorithm to reach the consensus.
1.1.2.2 Blockchain as a solution
Blockchain is one of the practical implementations. It is a decentralized
cryptographic ledger that consists of blocks in a chained form by the hash value
linking backwards, which is the kernel of Bitcoin first proposed in 2008 by Satoshi
Nakamoto [135]. It runs in a peer-to-peer (P2P) network where each piece of data
is shared among the network by data duplicately recorded on each of the nodes,
without having to rely on a central authority and previously established trust
relationship. Such a system can be trustworthy because a decentralized consensus
algorithm is implemented to solve the Byzantine Generals Problem, leading to the
tamper-resistance that prevents the double-spending attack. Specifically, di erent↵
decentralized consensus algorithms exist depending on the type of Blockchain and
on the requirements of the use cases. They are mainly categorized into two types,
Nakamoto-based and Byzantine Fault Tolerance (BFT)-based consensus
algorithms.

The game theory and incentive are applied in Nakamoto-based consensus
algorithms (e.g., Proof-of-Work (PoW)) to ensure to reach the consensus in a
probabilistic manner in a complexity of O(N), while BFT-based consensus
algorithms (e.g., Practical BFT (PBFT) [40]) ensure a deterministic result by
exchanging additional messages among the participants.
The cryptographic data structure (e.g., the attached digital signature and the
irreversible hash function) and the decentralized consensus algorithm make the
recorded data costly to be modified retroactively. This promotes Blockchain to be a
suitable role for data recording, data storage, and identity management [137].
Ranged from cryptocurrency to IoT networks, Blockchain has shown its great
potential to tackle critical security and trust challenges in various applications
[135, 140], along with several open-source platforms being widely developed, e.g.,
Ethereum [38], EOS [30], and HyperLedger-Fabric [14].
1.1.3 Blockchain-based IoT: benefits and challenges
1.1.3.1 Benefits
A conventional IoT network is likely to involve multiple business parties who
have an intent of ensuring secure and transparent data recording and sharing with
each other. It is thus normal that a central authority needs to be involved to
establish the trust relationship among all parties, which is severely prone to the
SPOF, DDoS, and potential malicious authorities. The decentralized trustworthiness
of Blockchain highly encourages the widely adoption of large-scale IoT applications
in the sense of the tamper-resistance being surely guaranteed. It is also worth
restating that the concept of Blockchain-based IoT is not opposed to the cloud-
based IoT; see Section 1.1.1. A Blockchain system itself, which is composed of a
decentralized P2P network, can be seamlessly implemented on top of any devices
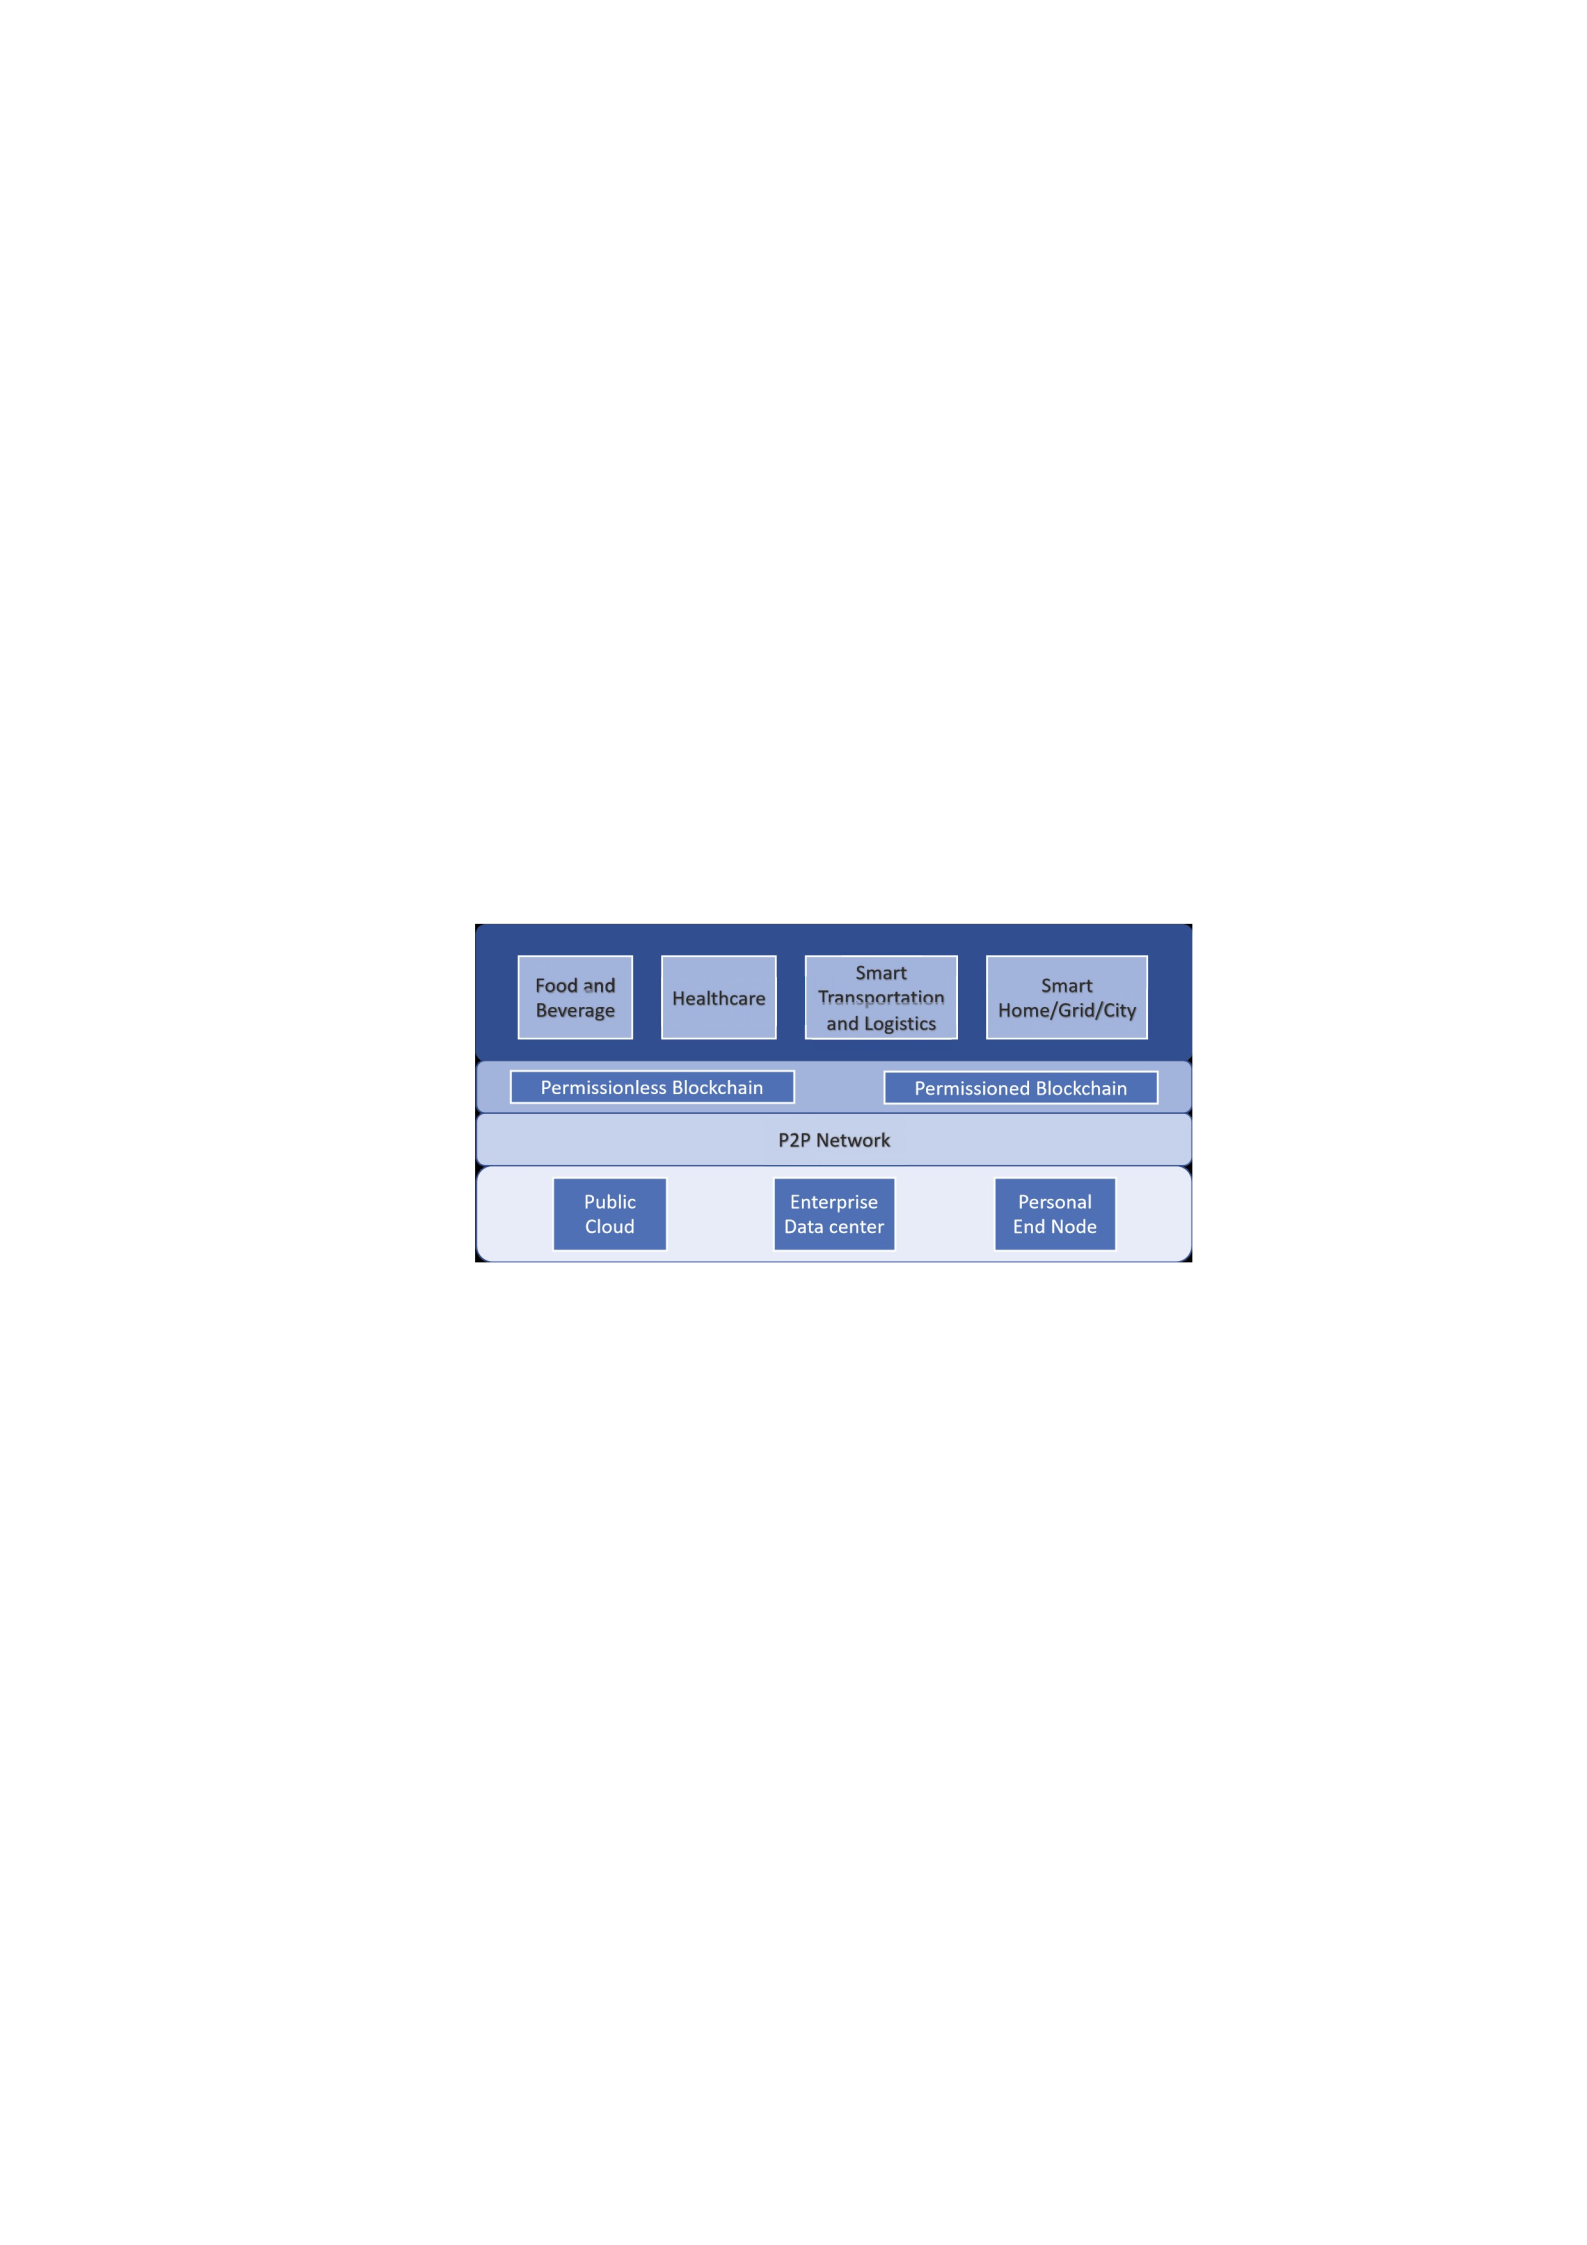
or infrastructures including the cloud-based platforms; see Figure 1.1. The
flexibility also empowers the uses of Blockchain-based IoT systems.
1.1.3.2 Challenges
The studies of Blockchain-based IoT systems have been growing at a fast pace,
however, revealing an increasing number of challenges when integrating the
Blockchain and IoT technologies.
IoT networks require high scalability in order to handle huge amount of data
stream transmitted among relatively weak performance of hardware devices. In
hopes to overcome the aforementioned critical IoT security and trust issues, a
Figure 1.1 : The system architecture shows that Blockchain-based networks can be built on top of
cloud-based platforms.
Blockchain-based IoT system also needs to delivery feasible solutions to meet
di erent requirements, such as authentication service and self-motivated↵
deployment, in a decentralized manner.
However, the trilemma of scalability-security-decentralization in Blockchain
systems exists [37], stating that the challenge to achieve high scalability while at
the same time featuring the decentralized security. This is because typical
decentralized consensus algorithms can only satisfy two out of three in this
trilemma. Typical Nakamoto-based consensus, e.g., PoW in Bitcoin, can only handle

up to approximately 10 transactions per second with its maximum block size of
1MB and average
10 minutes block period [179] in a large-scale network under decentralized
security. Typical BFT-based consensus, e.g., PBFT, can achieve a throughput of 1000
transactions per second by sacrificing the decentralization and limiting the block
generators within a small-size committee. This severely hinders the use of
Blockchains in the high-frequency data processing and trading, making Blockchains
far from practical requirements.
This thesis focuses on the following four aspects:
•Analytical models: A decentralized architecture implies the needs of novel
evaluation approaches to be established such as an analytical model. IoT
practitioners need a unified analytical model to conduct the cost-risk
assessment to maintain a Blockchain-based IoT system or even a single node
within the system.
•Scalable protocols and designs: A highly scalable Blockchain has been one
of the most crucial requirements for IoT networks in a live context. This
aspect corresponds to investigating novel protocols and designs in which the
trilemma can be balanced.
•Access control and privacy: Enterprises have been playing a important role
in IoT ecosystems. An e ective and flexible access control policy to be↵
applied in a Blockchain-based IoT system in order to protect the privacy of
customers of theirs becomes necessary. It turns out that the inherent
property of transparency in Blockchains conflicts with the requirement,
which is the focus of this aspect.
•Optimized architecture: There have been a number of studies investigating
and presenting the integration of Blockchain and IoT technologies. However,
a simple architecture without dedicated optimizations cannot take full
advantage of both technologies. On the contrary, Blockchains might incur
negative impacts from the inherent properties of IoT networks in a
straightforward
integration.
1.2 Research Objectives
The challenges of implementing Blockchain-based IoT networks exist, based on
which this thesis focuses on four categories, analytical models, scalable
protocols and designs, access control and privacy, and optimized architecture.
The research targets, key research points, and the structure of this thesis are illus-
Figure 1.2 : Research targets, key research point, and chapters.
trated in Figure 1.2.
!&!&"
! '$$#% (
!&& && !
! ! "
#+ !#&% #!!-!-
! $ $&$$$
#!!$ '&%! $
!(%!"$ %#$$$$$ %
!#%! ! %
$ !$#
! $
!"#$! $
$&$$!
%#%(%%%#&%-
$ #*"%!
%#$
#'!%!
'&% %!")%*
"!(#! $&"%!
#!' %#&$%(!#%*
'%! *&$ !
"%+ % %#%
#%%&#%!"#!'%
%#!&"&%!!
'&%! $&%!
/, %#!&%!
(0,%#%&#'
1, *%!!#
#!!-!-$$
2, -!&%! $
( %#
, %%#&%'!%! 3
!# -# $$! %#!
! - !*$%$
,!'&-! %#&%
!#! %#%-!#%!%(!#$
5,! %#&%! $
&%&#(!#

Analytical models - In regard to fulfilling the lack of a unified analytical
model of PoX consensus scheme, what model/metrics should be used to
reflect the generic properties?
Di erent from BFT-based consensus algorithms which were originally↵
dedicated to solve the BGP and have been systematically learned, unified, and
optimized (ranged from PBFT [40] to Zyzzyva [102] and Hotstu [201]), the first↵
Nakamotobased consensus algorithms was first derived from Bitcoin [135], i.e.,
PoW. PoW utilizes the game theory and incentive to simplify the network
conditions and provide a practical solution to BGP in large-scale networks. PoW has
been extended to other virtual-mining-based variations (e.g., Proof-of-Stake (PoS))
and subsequently generalized to Proof-of-X (PoX)-based consensus algorithms
[180, 186]. However, none of existing studies was able to provide a unified
analytical model for PoX schemes.
Such a model would be important to enable each practitioner to estimate its profit
against competitors based on its source. This is important for the traditional
mining industry [118] and any public IoT services based on permissionless
Blockchains in large-scale networks. Therefore, our research target for this aspect
is to provide a unified analytical model specifically for PoX consensus schemes,
which is discussed in Chapter 3. Mathematical proofs and evaluations are also
presented in the chapter to elaborate on how the proposed model helps in the cost-
risk assessment.
Scalable protocols and designs - Scale-out Blockchain technologies are
promising to break the trillema, is there a generic framework to learn them,
thus an explicit future can be pointed?
Scalability is important for IoT networks. The weak scalability of traditional
Blockchain technologies severely a ect the wide adoption due to the well-known↵

trillema of decentralization-security-scalability in Blockchains. In regards to this
issue, a number of solutions have been proposed, targeting to boost the scalability
while preserving the decentralization and security. They range from modifying the
on-chain data structure [152] and consensus algorithms [201] to adding the o -↵
chain technologies [150]. Therein, one of the most practical methods to achieve
horizontal scalability along with the increasing network size is sharding. As a scale-
out solution, sharding partitions network into multiple shards so that the overhead
of duplicating communication, storage, and computation in each full node can be
avoided, leading to a boost of the scalability of Blockchains. Chapter 4 presents a
comprehensive comparison and evaluation among existing major sharding
mechanisms, in hopes of revealing the pain points of sharding technologies and
pointing out the future
direction.
Access control and privacy - The content needs to be editable to fulfill the
changes of attributes in an ABE-based Blockchain that provides finegrained
access control, how the contradiction can be solved between this requirement
and the immutability of Blockchains?
Fine-grained access control is important in IoT networks in which the
increasing number of devices and users contribute to the massive data needed to
be accessible in a well-organized manner. Attribute-based encryption (ABE) has
been considered to achieve fine-grained access control in Blockchains. However,
members revocation which requires to modify the records conflicts with the
immutability of Blockchains. Chapter 5 proposes a novel multilayer Blockchain-IoT
data service system, which enables secure attribute updates in an ABE-based fine-
grained access control mechanism for Blockchains. Numberical results are given to
evaluate the complexity and power consumption.

Optimized architecture - How dedicated optimizations could be designed
upon a Blockchain-based IoT application such that the combination could be
natural, smooth, and e ective?↵
Researchers have been doubting with a flood of designs presenting simple and
stilted integration between Blockchain and IoT technologies. Without dedicated
optimization, a LoRa system as a typical case study, the duplicated data (which is
helpful for redundancy) becomes the cause of the throughput loss in Blockchains.
Thus, a novel Dual-Chain-based LoRa system is proposed in Chapter 6 as a feasible
case study to fill the gap. The system deliveries a trustworthy cross-
validatedsecurity in a decentralized manner, while a new incentive mechanism to
improve the Blockchain throughput. A Monte-Carlo simulation is carried out to
prove the
feasibility.
1.3 Thesis Organization
This thesis is based on the research results of 4 journal papers. The thesis is
organised as follows:
•Chapter 1: This chapter provides an overview of this research. The research
background is presented in the first place to point out the challenges,
followed by the research targets and key research points for implementing
Blockchainbased IoT networks. This chapter also illustrates the structure of
this thesis.
•Chapter 2: This chapter gives a comprehensive literature review of existing
studies regarding the challenges of Blockchain-based IoT networks from the
four highlighted aspects.

•Chapter 3: This chapter proposes a Markov model which captures explicitly
the weighted resource distribution of PoX schemes in large-scale networks
and unifies the analysis of di erent PoX schemes. The new model leads to the↵
development of three new unified metrics for the evaluation, namely,
Resource Sensitivity, System Convergence, and Resource Fairness, accounting
for security, stability, and fairness, respectively. The generality and
applicability of our model are validated by simulation results, revealing that
among typically non-Fairness-oriented PoX schemes (such as PoW and PoS),
the strongly restricted coinage-based PoS with a Pareto-distributed resource
can o er the best performance on Resource Sensitivity, while Proof-of-↵
Publication (PoP) with normal-distributed resource performs the best on
System Convergence.
Our simulations also reveal the important role of carefully designed Resource
Fairness parameter in balancing Resource Sensitivity and System
Convergence and improving the performance compared with other non-
Fairness-oriented PoX schemes.
•Chapter 4: This chapter presents a survey focusing on sharding in
Blockchains in a systematic and comprehensive way. We provide detailed
comparison and evaluation of major sharding mechanisms, along with our
insights analyzing the features and restrictions of the existing solutions. The
remaining challenges and future research directions are also reviewed.
•Chapter 5: This chapter proposes a new Blockchain-based IoT system which
is compatible with ABE technique, and fine-grained access control is
implemented with the attribute update enabled by integrating Chameleon
Hash (CH) algorithms into the Blockchains. We design and implement a new
verification scheme over a multilayer Blockchain architecture to guarantee

the tamper resistance against malicious and abusive tampering. The system
can provide an update-oriented access control, where historical on-chain
data can only be accessible to new members and inaccessible to the revoked
members. This is distinctively di erent from existing solutions, which are↵
threatened by data leakage toward the revoked members. We also provide
analysis and simulations showing that our system outperforms other
solutions in terms of overhead, searching complexity, security, and
compatibility.
•Chapter 6: This chapter proposes a novel Dual-Chain-based LoRa system
providing global cross-validated security. Behaviors, including the incentive
mechanism, and new flow control protocol, can be secured by the
tamperresistance of Blockchains. Being part of the proposed incentive
mechanism, the new self-driven flow control scales both the Dual-Chain
system and the LoRa network. We also provide analysis and simulations
showing that our system can optimize the utilization of coverage while
improving the Blockchain scalability and flexibility with the new incentive
mechanism.
•Chapter 7: The research and contributions of this thesis and are summarized
in this chapter, with the discussion of the future works ends the thesis.
Chapter 2
Literature Survey
A comprehensive literature survey is given in this chapter by summarizing recent
research breakthroughs regarding the four aspects identified in Chapter 1. They

are, respectively, analytical models for PoX consensus algorithms, scale-out
solutions, fine-grained access control, and Blockchain-based LoRa networks as a
feasible case study.
2.1 Analytical Models for PoX Consensus Algorithms
There have been several studies proposing analytical models to evaluate the
consensus engine of Nakamoto protocol, focusing on PoW from the beginning.
Garay et al. [68] proposed a model with negligible network delay and constant total
mining power for PoW. Miller and LaViola proposed an analytical model for PoW in
terms of the faulty tolerance within a reliant synchronization network [131].
Gervais and et al. [70] proposed a specific security model regarding the adversarial
strategies (selfish mining) considered in [165]. Also, in [146], a security analysis of
PoW based on a partially synchronous network was proposed in terms of both the
consistency and network partition. On top of that, Zhang and Preneel [208]
thoroughly discussed the security issue of PoW, which mainly focuses on
natural/malicious consistency problems due to the considerable block propagation
time. Apart from a few papers claiming the randomized consensus [73] and the PoX
schemes [180, 186] from which the concept of PoX-based consensus algorithms
originate, there are not as many as papers generalizing the PoW/PoS consensus
algorithms. They tend to be a model where only PoW, PoS, or any other variants are
compared [29, 56, 113].
The above models focus on attacks based on the weakness of incentive schemes
due to natural/malicious network partitions caused by the considerable block
propagation time, such as the selfish-mining-attack, eclipse-attack and
computational double-spending attack in PoW [208], and nothing-at-stake attack
and long-range attack in PoS [56]. None of them focuses on the resource
distribution, to evaluate how much di erent settings of the weighted system↵

resource distribution will impact the long-term steady-state, and provides an
analytical model to each individual miner for a long-term risk assessment, i.e., the
amount of profits can be earned if being a miner to pay the system resource.
It is worth noting that, authors of [208] proposed the pitfalls in existing security
models that the unrealistic parameters range may prevent the vulnerabilities from
being discovered in the first place and mislead researches into only focusing on a
single attack strategy and incentive. This is indeed acceptable, nevertheless, the
resource distribution can be analyzed separately from all the other parameters
caused by the network delay and non-zero block propagation time; refer to Algo. 4
in [68]. In our model proposed in Chapter 3, we simplify our scenario and focus on
the security only impacted by the resource distribution without taking the network
delay ([68] considers the same assumption) and any corresponding attack
strategies and incentives caused by the delay into account.
2.2 Scale-out Solutions
The scalability issue, which is derived from the discussed Blockchain trilemma,
has been considered to consist of two major factors, i.e., throughput and latency.
Before digging into the depth, the following introduces how exactly the scalability
issue impacts on the Blockchains, and how the scale-out solutions are used to solve
the scalability issue by improving the throughput of a large-scale Blockchain
system.
The throughput of a Blockchain system, defined as the number of processed
transactions per second of the Blockchain, is far from practical requirements and
has become a crucial limitation stopping Blockchain from being widely adopted
[183]. For example, Bitcoin can only handle up to approximately 10 transactions per
second with its maximum block size of 1MB and average 10 minutes block period

[179], which severely hinders the use of Blockchains in the high-frequency trading.
To handle a great number of transactions, Blockchain has been considered as a
secure base-layer (or a settlement center for cryptocurrencies) where transactions
are processed o -chain and then settled in the Blockchain. For example, Lightning↵
network and Raiden network (referring to the state-channel technology) support
o -chain payments and broadcast a summary of a batch of o -chain payments to↵ ↵
the Blockchain [151, 1]. Plasma (referring to the sidechain technology) builds
various applications on the top of Ethereum [150]. These methods, known as the
Layer-2 scaling, minimize the interaction with the Blockchain to reduce the latency
from the users’ perspective but do not improve the throughput of Blockchains [90].
In contrast, the Layer-1 scaling is designed for improving the throughput of
Blockchains from the systematic perspective. A Blockchain system can be
optimized in the following ways to handle a growing amount of work.
• reducing the communication and computation overhead;
• adding resources to a single node, i.e., vertical scaling;
• adding more nodes to the Blockchain, i.e., horizontal scaling [41].
Reducing overhead: New Blockchain consensus protocols have been
developed for high Blockchain throughput by reducing the overhead. For example,
every PoW winner (i.e., a miner) is eligible for several blocks rather than a single
block in Bitcoin-NG [62] and its variations [25, 94]. The traditional PBFT consensus
protocol has been developed and optimized to reduce the communication overhead
and achieve high throughput in large-scale networks [132, 202, 101, 71]. However,
O(n) (n is the number of participating miners) is the lower bound that this type of
technologies can reduce the overhead at most, as every participating miners have

to exchange and store messages during every consensus round regardless of the
route of transactions.
Vertical scaling: Bitcoin tried to improve throughput by vertical scaling methods.
For example, increasing the number of allowed transactions in a single block and/or
reducing the block period can improve the throughput of Bitcoin but consume more
resources, e.g., storage, computation, and bandwidth, of Bitcoin nodes [50, 69, 192,
119]. Beyond this, The Greedy Heaviest Observed Subtree (GHOST) [171] is
implemented by Ethereum to organize blocks in a tree instead of a chain of blocks
and obtain a higher throughput [188]. The GHOST is subsequently extended to the
directed acyclic graph (DAG). The DAG is adopted to organize transactions where
every transaction contains hash values pointing to existing transactions [152, 48, 23,
170, 172, 109]. The DAG structure allows transactions to be confirmed in parallel
and thus improves the network utilization ratio given the resources of a node, which
improves the throughput of the entire distributed system. However, the vertical
scaling methods cannot infinitely improve the throughput, as a Blockchain system is
designed to run in a decentralized and homogeneous network where the security is
closely dependent on the consensus across the entire network. The larger-scale the
network is, the more bandwidth is needed to achieve the network synchronization,
while the bandwidth is the resource that cannot be indefinitely added [50]. This
leads to the vertical scaling being compromised to the throughput of resources-
limited nodes.
Horizontal scaling: Sharding technology, dividing a whole Blockchain into
multiple shards and allowing participating nodes to process and store transactions
of a few shards (i.e., only parts of the Blockchain), holds the key to horizontal
scaling, also known as the scale-out technology. By taking advantage of the sharding
technology that allows partial transactions processing and storage on a single node,

the whole Blockchain can achieve a linearly increasing throughput with the
growing number of nodes. This is important for the adoption of Blockchains
providing high quantity and quality of services to the public in large-scale networks
with infinite growth, which has attracted the interest of researches regarding the
improvement of the Blockchain scalability.
A number of studies have proposed new sharding mechanisms. Surveys of
Blockchain scalability which used to only focus on Reducing overhead and
Vertical scaling have been gradually taking the sharding technology into account.
However, none of them was able to focus on sharding and systematically introduce
the challenges of sharding, features and restrictions of the existing solutions, and
the future trends.
2.3 Fine-grained Access Control
Recently, several access control mechanisms have been proposed for IoT
networks based on cloud services [15, 200, 46]. Therein the ABE technology has
attracted much attention in cloud computing to provide fine-grained access control
[161, 64, 110]. For example, authors of [161] applied ABE over multiple cloud
servers; and authors of [64] provided a distributed and scalable structure for an
ABE-based IoT network. The ABE allows users to asynchronously decrypt a
ciphertext when the users’ attributes match the prespecified access rules of the
ciphertext with no need for IoT devices staying online all the time [27]. ABE
schemes can be divided into Key-Policy Attribute-Based Encryption (KP-ABE)
[103] and Ciphertext-Policy Attribute-Based Encryption (CP-ABE). In KP-ABE
schemes, a ciphertext is associated with a set of attributes, and users’ secret keys
are based on an access policy.

CP-ABE schemes use access policies to encrypt data, and users’ secret keys are
generated over a set of attributes. However, only relying on cloud services may lead
to a loss of reliability and traceability of data [20, 134, 204]. Thus Blockchain-based
access control becomes increasingly attractive.
In [143, 122], it is shown that Blockchains allow the manager or gateway of
each domain network to be part of the consensus process in a Blockchain-based
Key Management Cloud. This can ensure the service of key management and
distribution for users in a transparent manner. Nevertheless, such access control
mechanisms are incapable of providing fine-grained access control in the presence
of a device, or even system breakdown, caused by a burst of encryption request
messages at the IoT devices. To address this issue, there have been studies on
Blockchain-based ABE schemes [185, 156, 154]. For example, in [156], an ABE
scheme is employed in a Blockchain-based IoT system to encrypt sensory data into
transactions. However, as revealed in [185], few existing Blockchain-based ABE
schemes can support a practical mechanism for attribute update and thus can
hardly be adopted in dynamic IoT applications. One of those providing a vague
discussion about attribute update is [154] (the technological detail is not given),
where the smart contract is used to support attribute updates in a Blockchain-
based ABE system. The scheme in [154] can potentially allow the data to be directly
exposed to members with revoked attributes. This is because the history of smart
contract is recorded along with the past blocks, and the revoked members can
directly access outdated versions of the ciphertext associated with their outdated
ABE private keys. A potential remedy to this issue is to introduce a redactable
Blockchain by using CH algorithms [17, 81, 84]. Our system proposed in Chapter 5
achieves a better performance than that of [154] in terms of overhead, searching
complexity, and security.

2.4 Blockchain-based LoRa networks: A case study
We take Blockchain-based LoRa networks as a case study in this thesis because
of the following two factors.
• LoRa networks allows the data sent from an end-device to be received by
multiple LoRa Gateways, i.e., the duplicated data, which is helpful for data
redundancy in the context of LPWAN wherein the reliable connection is
normally being pruned due to the limited resource. However, the duplicated
data uploaded to the Blockchains, on the other hand, compromises the
Blockchain throughput.
• Self-motivated deployment is the key strategy of the rollout of LoRa
technology. Proper incentive can play an important role in encouraging the
private deployment of LoRa and increase coverage. A global validation which
can secure the incentive process in a decentralized manner becomes crucial.
Recent studies have investigated the integration between the Blockchain and
LoRa technologies [145, 54, 139, 115]. They integrate an existing traditional
Blockchain platform (e.g., Ethereum) with a LoRa network, aiming to take advantage
of smart contracts for data storage. Ozyilmaz and Yurdakul [145] introduced an
Ethereum Blockchain for data storage and access, where either end-devices or
gateways are in charge of the block generator. Danish and et al. [54] realized the end-
devices incur large overhead with the design in [145], thus introducing a separate
Ethereum Blockchain in which multiple agent nodes can provide data storage and
access services for either gateways and controllers. Authors of [139, 115] involved an
Ethereum Blockchain as a decentralized database providing data storage and access
services for all nodes in the network. However, an Ethereum Blockchain or other
traditional

Blockchain technologies have been revealed that the vulnerable scalability in the
context of Low-Power Wide-Area Network (LPWAN) [163], and the one-device-
tomany-gateway property of LoRa networks with ALOHA access even compromises
the scalability. Again, an incentive mechanism needed to motivate the LoRa
network deployment still lacks a reliable Blockchain-based solution. None of the
existing technologies take advantage of both technologies, and are able to deliver a
Blockchain-based solution to LoRa Networks where the Blockchain and LoRa
technologies can complement each other to address the above issues. By using our
new Dual-Chain-based LoRa network, the scalability issue (throughput loss and
huge storage) of Blockchains can be relieved without modifying the original LoRa
transmission protocol, and the self-motivation to deploy the LoRa networks can be
fairly incentivized and secured by Blockchains.
2.5 Chapter Conclusion
A comprehensive literature related to this thesis was reviewed in this chapter,
laying a solid foundation for the following chapters. To be specific, this chapter
summarized and compared the latest research progress about, 1) the analytical
models for PoX consensus algorithms; 2) varieties of solutions to improve the
scalability issue and how the scale-out solutions outperform others in terms of
throughput; 3) ABE as a solution to provide feasible fine-grained access control in
Blockchains; and 4) the integration between Blockchains and LoRa networks. This
chapter also identified the gap between existing studies and our research targets,
leading to the key research points of this thesis.
Chapter 3

A Unified analytical model for Proof-of-X schemes
As a solution to reach the consensus in the context of a large-scale IoT network,
PoX schemes have been considered appropriate and have been learned from
various perspectives, including presenting many variations, e.g., Proof-of-Activity
(PoA) [24] and Proof-of-Publication (PoP) [180], and the corresponding analytical
models. However, there has been to date in lack of a unified analytical model for
each participant to evaluate its steady-state profit against the competitors. The
selection of mathematical model and metrics which could properly reflect the
phenomenon requires more attraction. Under this background, this chapter
proposes a Markov model which captures explicitly the weighted resource
distribution of PoX schemes in large-scale networks and unifies the analysis of
di erent PoX schemes.↵
3.1 Introduction
Nakamoto protocol in Bitcoin [135] was proposed to address the Byzantine
Generals Problem [104] other than the traditional BFT protocol. The consensus
engine of the Nakamoto protocol was first proposed as PoW, and has been
extended to other virtual-mining-based variations (e.g., PoS) and subsequently
generalized to PoX-based consensus algorithms [180, 186]. PoX schemes take
advantage of probabilistic consensus algorithms, and introduce a publicly
Verifiable Random Function
(p-VRF) with only communication overhead of O(N) (N is the number of miners).
Along with the PoX schemes have been widely adopted in a variety of applications
(such as Proof-of-Collaboration (PoC) [193] and Proof-of-Distribution (PoD) [106]
in IoT systems), as well as the comparison between BFT schemes and PoX schemes

becoming attractive [183, 209, 188], the studies on PoX schemes become
increasingly interesting for large-scale networks.
In PoX schemes, the computation resource used in PoW can be replaced using
any other publicly-verifiable system resources with customized parameters (e.g.,
account balance/coinage in PoS and task progress in PoC), as long as the p-VRF can
hold. Several recent studies analyzed the PoW, PoS and their variations [131, 146,
73, 208], but none of them was able to evaluate the long-term steady state of the
system and the impact of the distribution of system resource on the state. There
also lacks a general analytical model for PoX schemes. Such a model would be
important to enable each miner to estimate its profit against competitors based on
its source. This is important for the traditional mining industry [118] and any
public services based on permissionless Blockchains.
In this chapter, we propose a new unified analytical model which is able to
quantify the profit of individual miners in any of the popular permissionless
PoXbased Blockchains. By applying the model, miners can estimate their profit
against their resources under di erent PoX schemes. The new model captures↵
proposed changes in the system resource distribution of PoX schemes by designing
an infinitedimensional Markov chain. A set of expressions is established to e ciently
evaluate the mining probability of a miner, given the amount of system resource
owned by the miner. The type and distribution of system resources can be
customized in line with system requirements. We develop a new general
presentation to unify a variety of system resource distributions in PoX schemes,
such as PoW, PoS, and Proof-ofPublication (PoP). Specifically, we characterize
probabilistically the system resource owned by a miner. The instantaneous
probability with which the miner can mine a block at any instant is generalized to
be captured by two new configurable functions respectively accounting for the

specific fairness measures of a PoX scheme and the dependence of mining success
on the resource distributions in the scheme.
We also design three new performance metrics, namely, Resource Sensitivity,
System Convergence, and Resource Fairness, to evaluate the di erent PoX-based↵
consensus algorithms systematically and consistently. The metrics are quantifiable
based on the average mining probabilities that the proposed infinite-dimensional
Markov model is able to derive under the new unified measure of system resource
distributions.
As revealed by our analysis, in PoX-based consensus algorithms where the
monopoly of block generation is prevented and diversity is maintained, miners can
maximize the profits with strong double-spending-resistance and controllable cost-
risk assessment, thereby contributing to a healthy and sustainable mining ecosystem.
Specifically, the system resource has the weakest impact on the average mining
probability for each participating miner when a configurable function delivering
positive correlation takes e ects, which leads to the best ↵Resource Sensitivity. Better
System Convergence can be achieved in PoX schemes with normal-distributed system
resource than that with a Pareto-distributed system resource, unless the schemes are
designed to restrict the monopoly of block generation. Good fairness or balanced
resources play important roles in fast convergence. The proposed fairness function
can be implemented in a distributed manner, to improve the fairness between miners
and speed up the convergence.
The rest of this chapter is organized as follows. Section 3.2 discusses the
preliminary knowledge. In Section 3.3, a Markov analytical model is presented. The
considered network setting is also discussed in Section 3.4, followed by the
simulation and analysis on di erent existing PoX-based consensus algorithms in↵
terms of three proposed metrics in Section 3.5. In Section 3.6, conclusions are
drawn.
3.2 Preliminary
In this section, the security model considered in Bitcoin is discussed to
illustrate the relationship between Bitcoin’s security model and our proposed
metric, Resource Sensitivity, as will be shown in Section 3.3.4.1. The PoX scheme is
also recapped as the basis to our proposed model.
3.2.1 Bitcoin’s Security Model
In Bitcoin’s model [135], security is measured by the probability with which an
attacker can catch up with the loyal miners to dominate the block generation. is
considered to be subject to the Poisson Distribution, as given by
,
where p denotes the probability of a loyal node being the current block generator
and q denotes the probability of a malicious node being the current block
generator. p > q, = z pq, and k z, where z denotes how much the malicious node
falls
behind the loyal miners in terms of block height.
3.2.2 PoX-based Consensus Algorithms
PoW is generalized to the PoX scheme. The PoX scheme describes a system
where a unique miner is elected to generate a new block based on a publicly
verifiable system resource ratio. The PoX scheme proposed in [180, 186] can be
described as
follows,
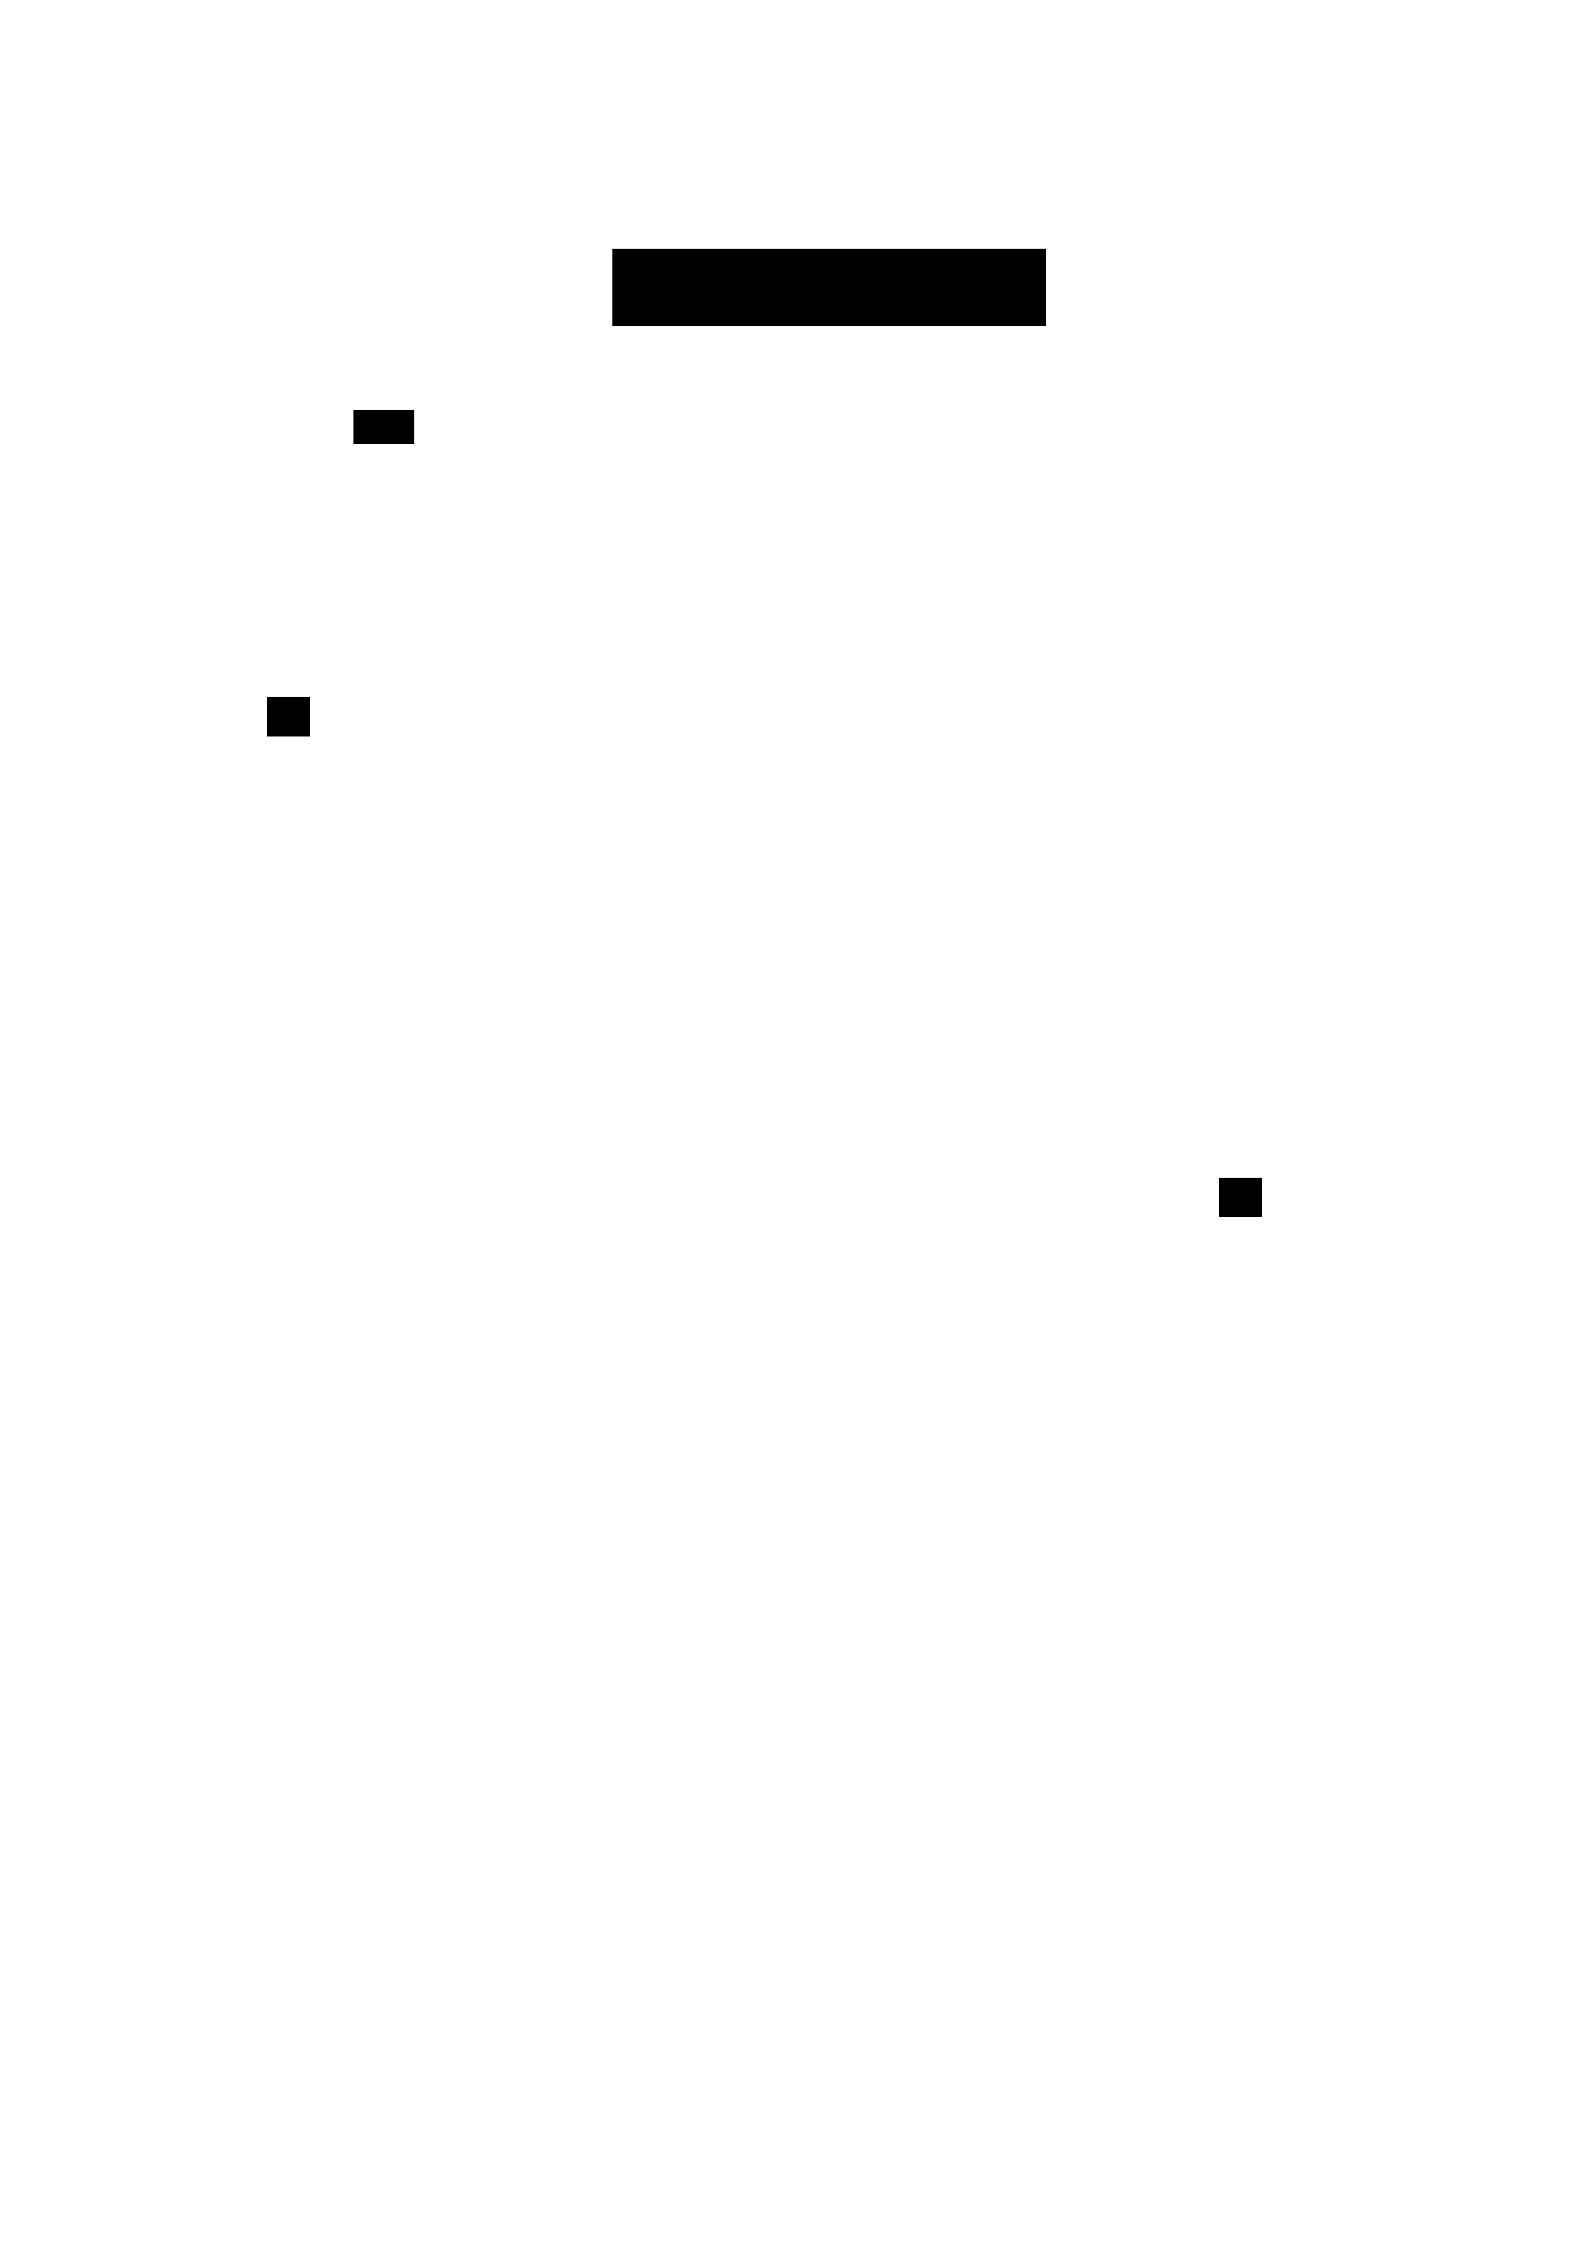
,(3.1)
where is the probability of Node-i being elected as the generator of the block,
and !i is the amount of system resource owned by Node-i. P! is the total amount of
system resources across the network, e.g., computation power, token balance, etc.
! denotes the ratio of system resource owned by Node-i over the total amount of
resource in the network.
On the other hand, i and F(·) can be customized to meet di erent requirements.↵
i is used to adjust how much impact is !i having on Piwin (denoted as i !!i). For example,
a hybrid of PoW and PoP [106] defines to be the number of packets that a
particular miner has distributed and forwarded, which can accordingly decrease
the di culty to win the puzzle-solving race, i.e., increasing the value of !. Function
F(·) denotes a p-VRF applied during the consensus process to randomly select the
block generator, subject to the distribution of P!, as given in (3.1).
In order to select the block generator in a large-scale network with an unknown
network size in practice, a PoX-based algorithm can be any consensus algorithm
subject to the Longest Chain Rule [186] that leverages a p-VRF based on any
verifiable system resource. We consider two di erent types of system resources.↵
They are 1) system resources which are independent to its transmission bandwidth
(typically, this type implies that the the considered system resource ratio in (3.1)
does not take the transmission bandwidth into account, and this type of resource
can be considered independently without network connection); and 2) network
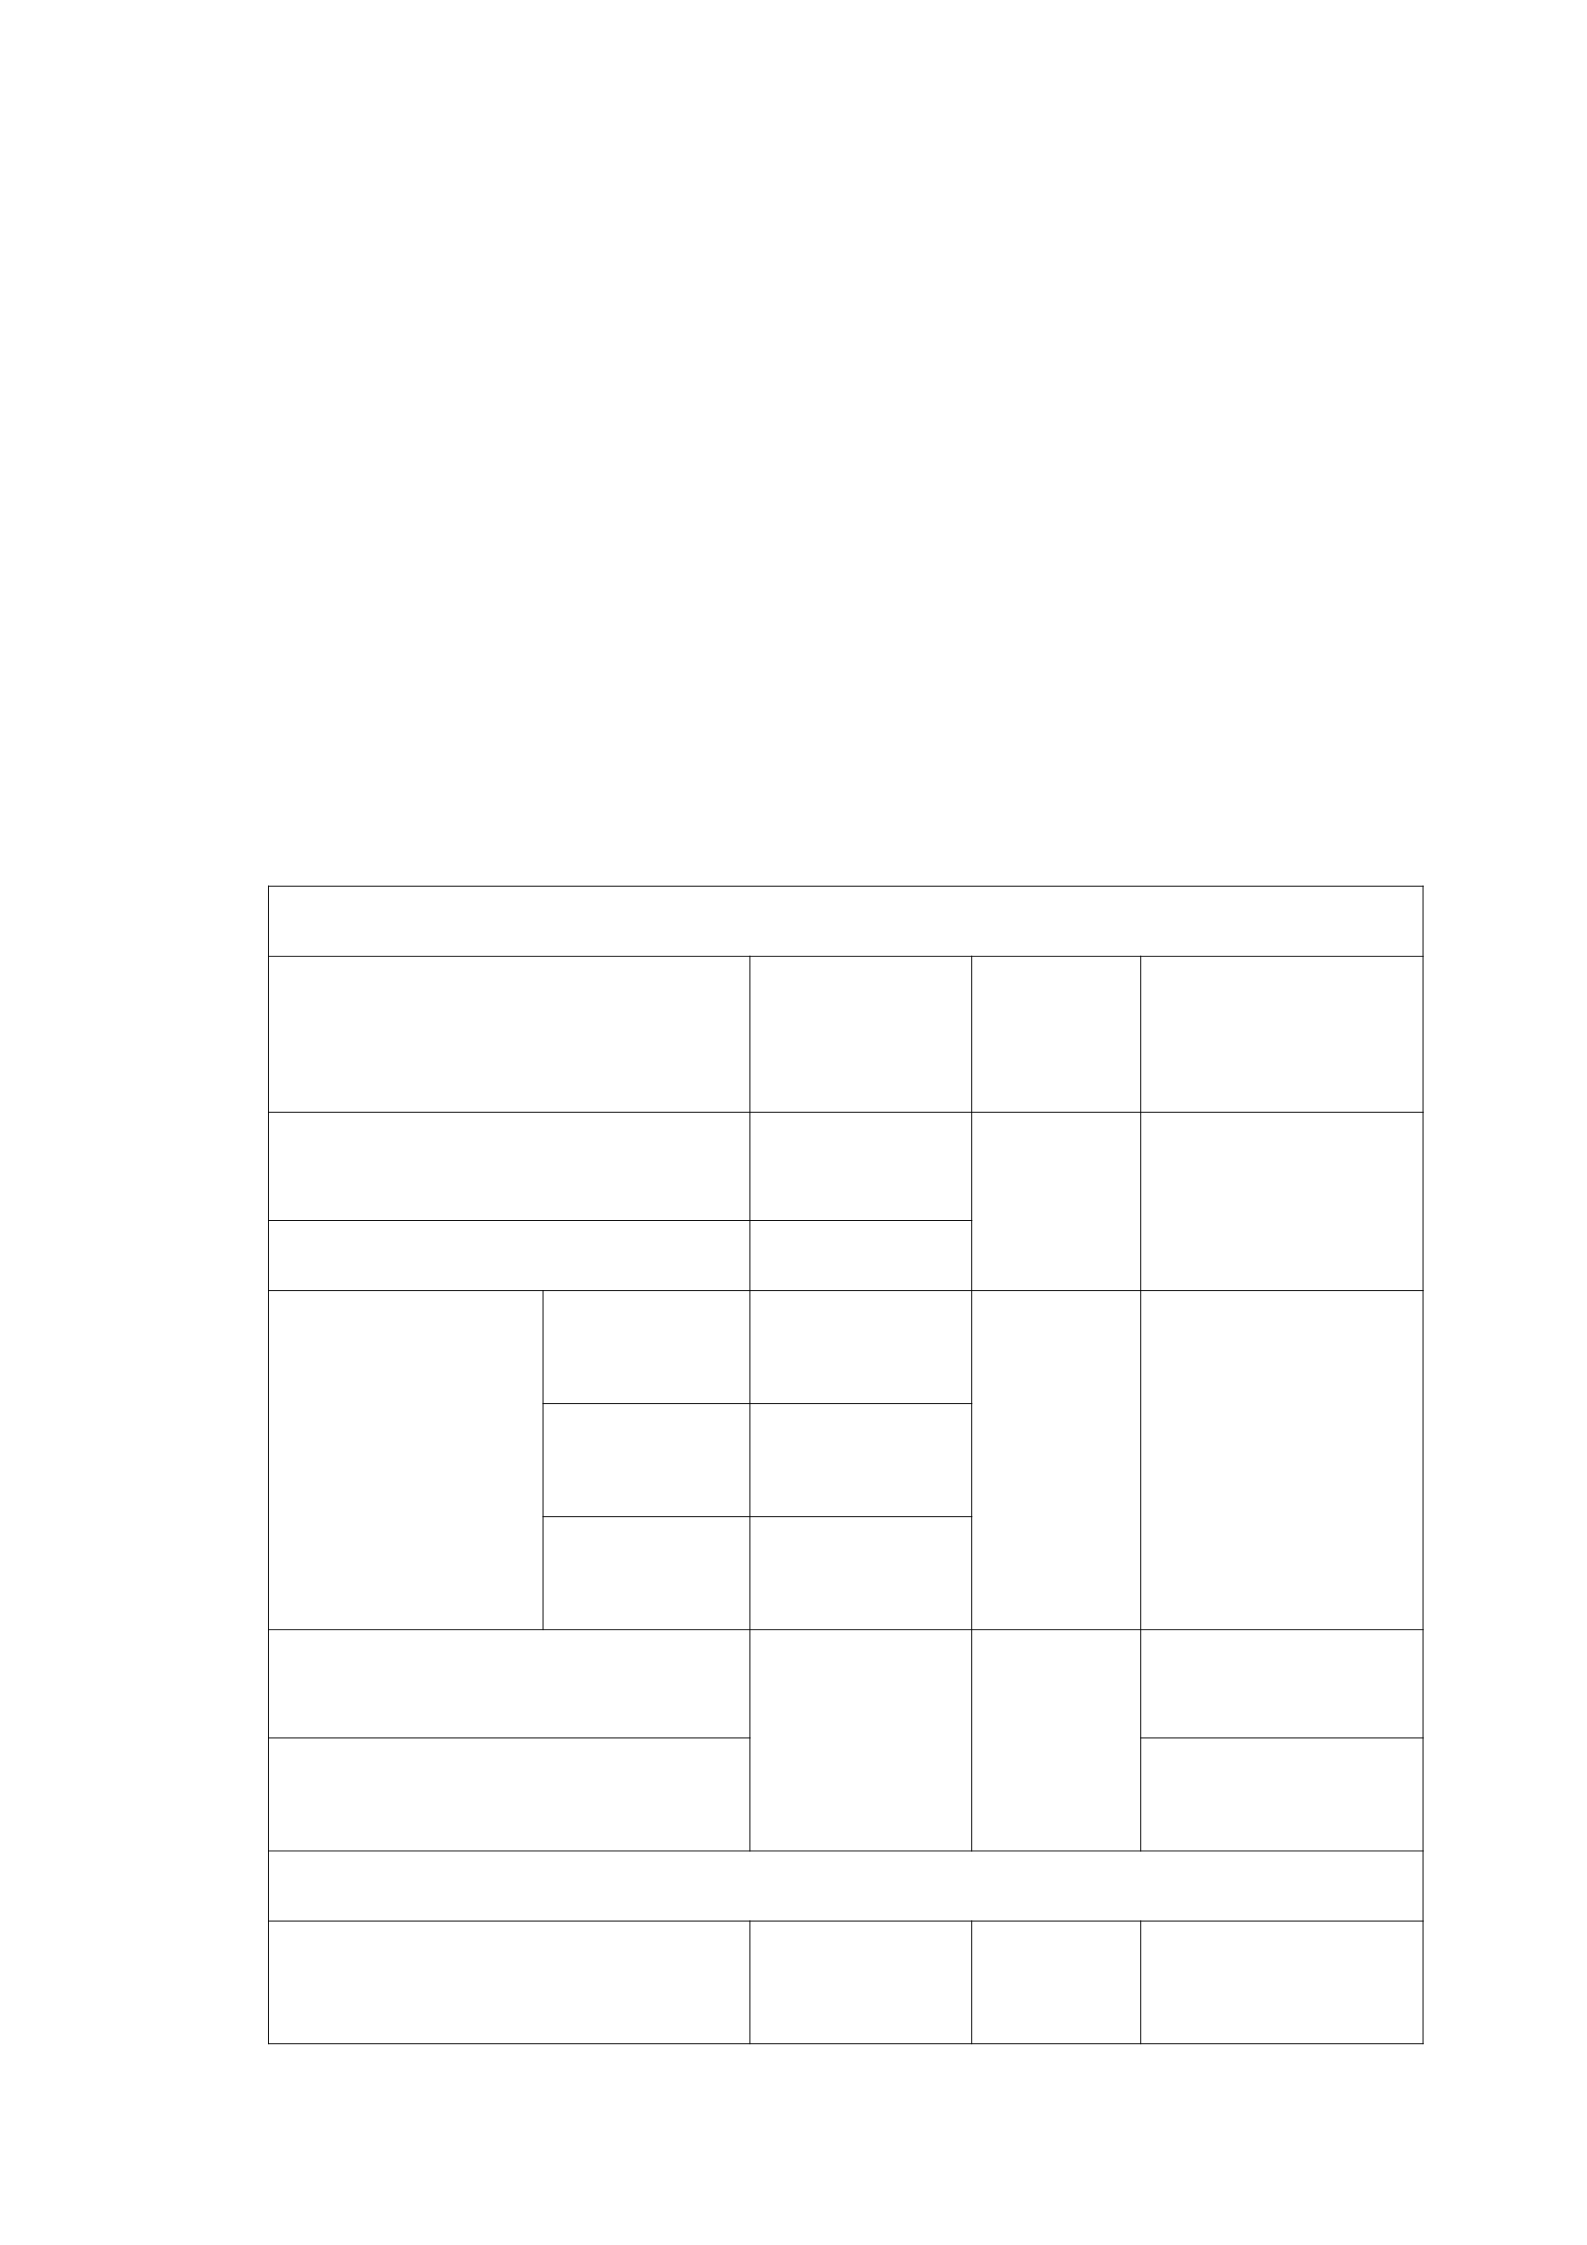
resource (typically, the transmission bandwidth corresponds to the network
performance). Such algorithm includes, but is not limited to, the consensus
algorithms listed in Table 3.1. For example, authors of [106] considered !i as the
total amount of system resource that a specific miner i owns, part of which is i in
the form of the number of distributed packets. F(·) can be a height-oriented factor
in Proof-of-Stake-Velocity (PoS-Velocity) [3], e.g., a function with variables !i and i ! h
(indicating Piwin is height-oriented with positive correlation). In other words, the
longer it has been since the last time a miner was elected as the block generator,
the more likely the miner is elected as the block generator in the current round.
Table 3.1 : Expressions of (non-)Fairness-oriented PoX schemes
Non-Fairness-oriented, let (⌥!i) = !i
The PoX schemes Types of the
System
Resource
Distribution
of !i†
fi,h
Proof-of-Work [135]
Computation power
PD?!↵i
Proof-of-Activity (PoA) [24] Online duration
Proof-ofPublication
(PoP) [180]
Proof-of-
Memory [82]
Memory ND‡!↵i
Proof-of-
Storage [100]
Disk Storage
Proof-of-
Distribution [106] Packets Forwarding
Proof-of-Stake (Coinage, Strong
restriction) [96, 193]
Account Coinage PD !↵imin{h1,H}
Proof-of-Stake (Coinage, Weak
restriction)
!↵imin{h,H}
Fairness-oriented, let (⌥!i) = ⇣(!i), where ⇣(!i) can be defined to be partitioned
The PoX schemes Types of the
System
Distribution of
!i†
fi,h
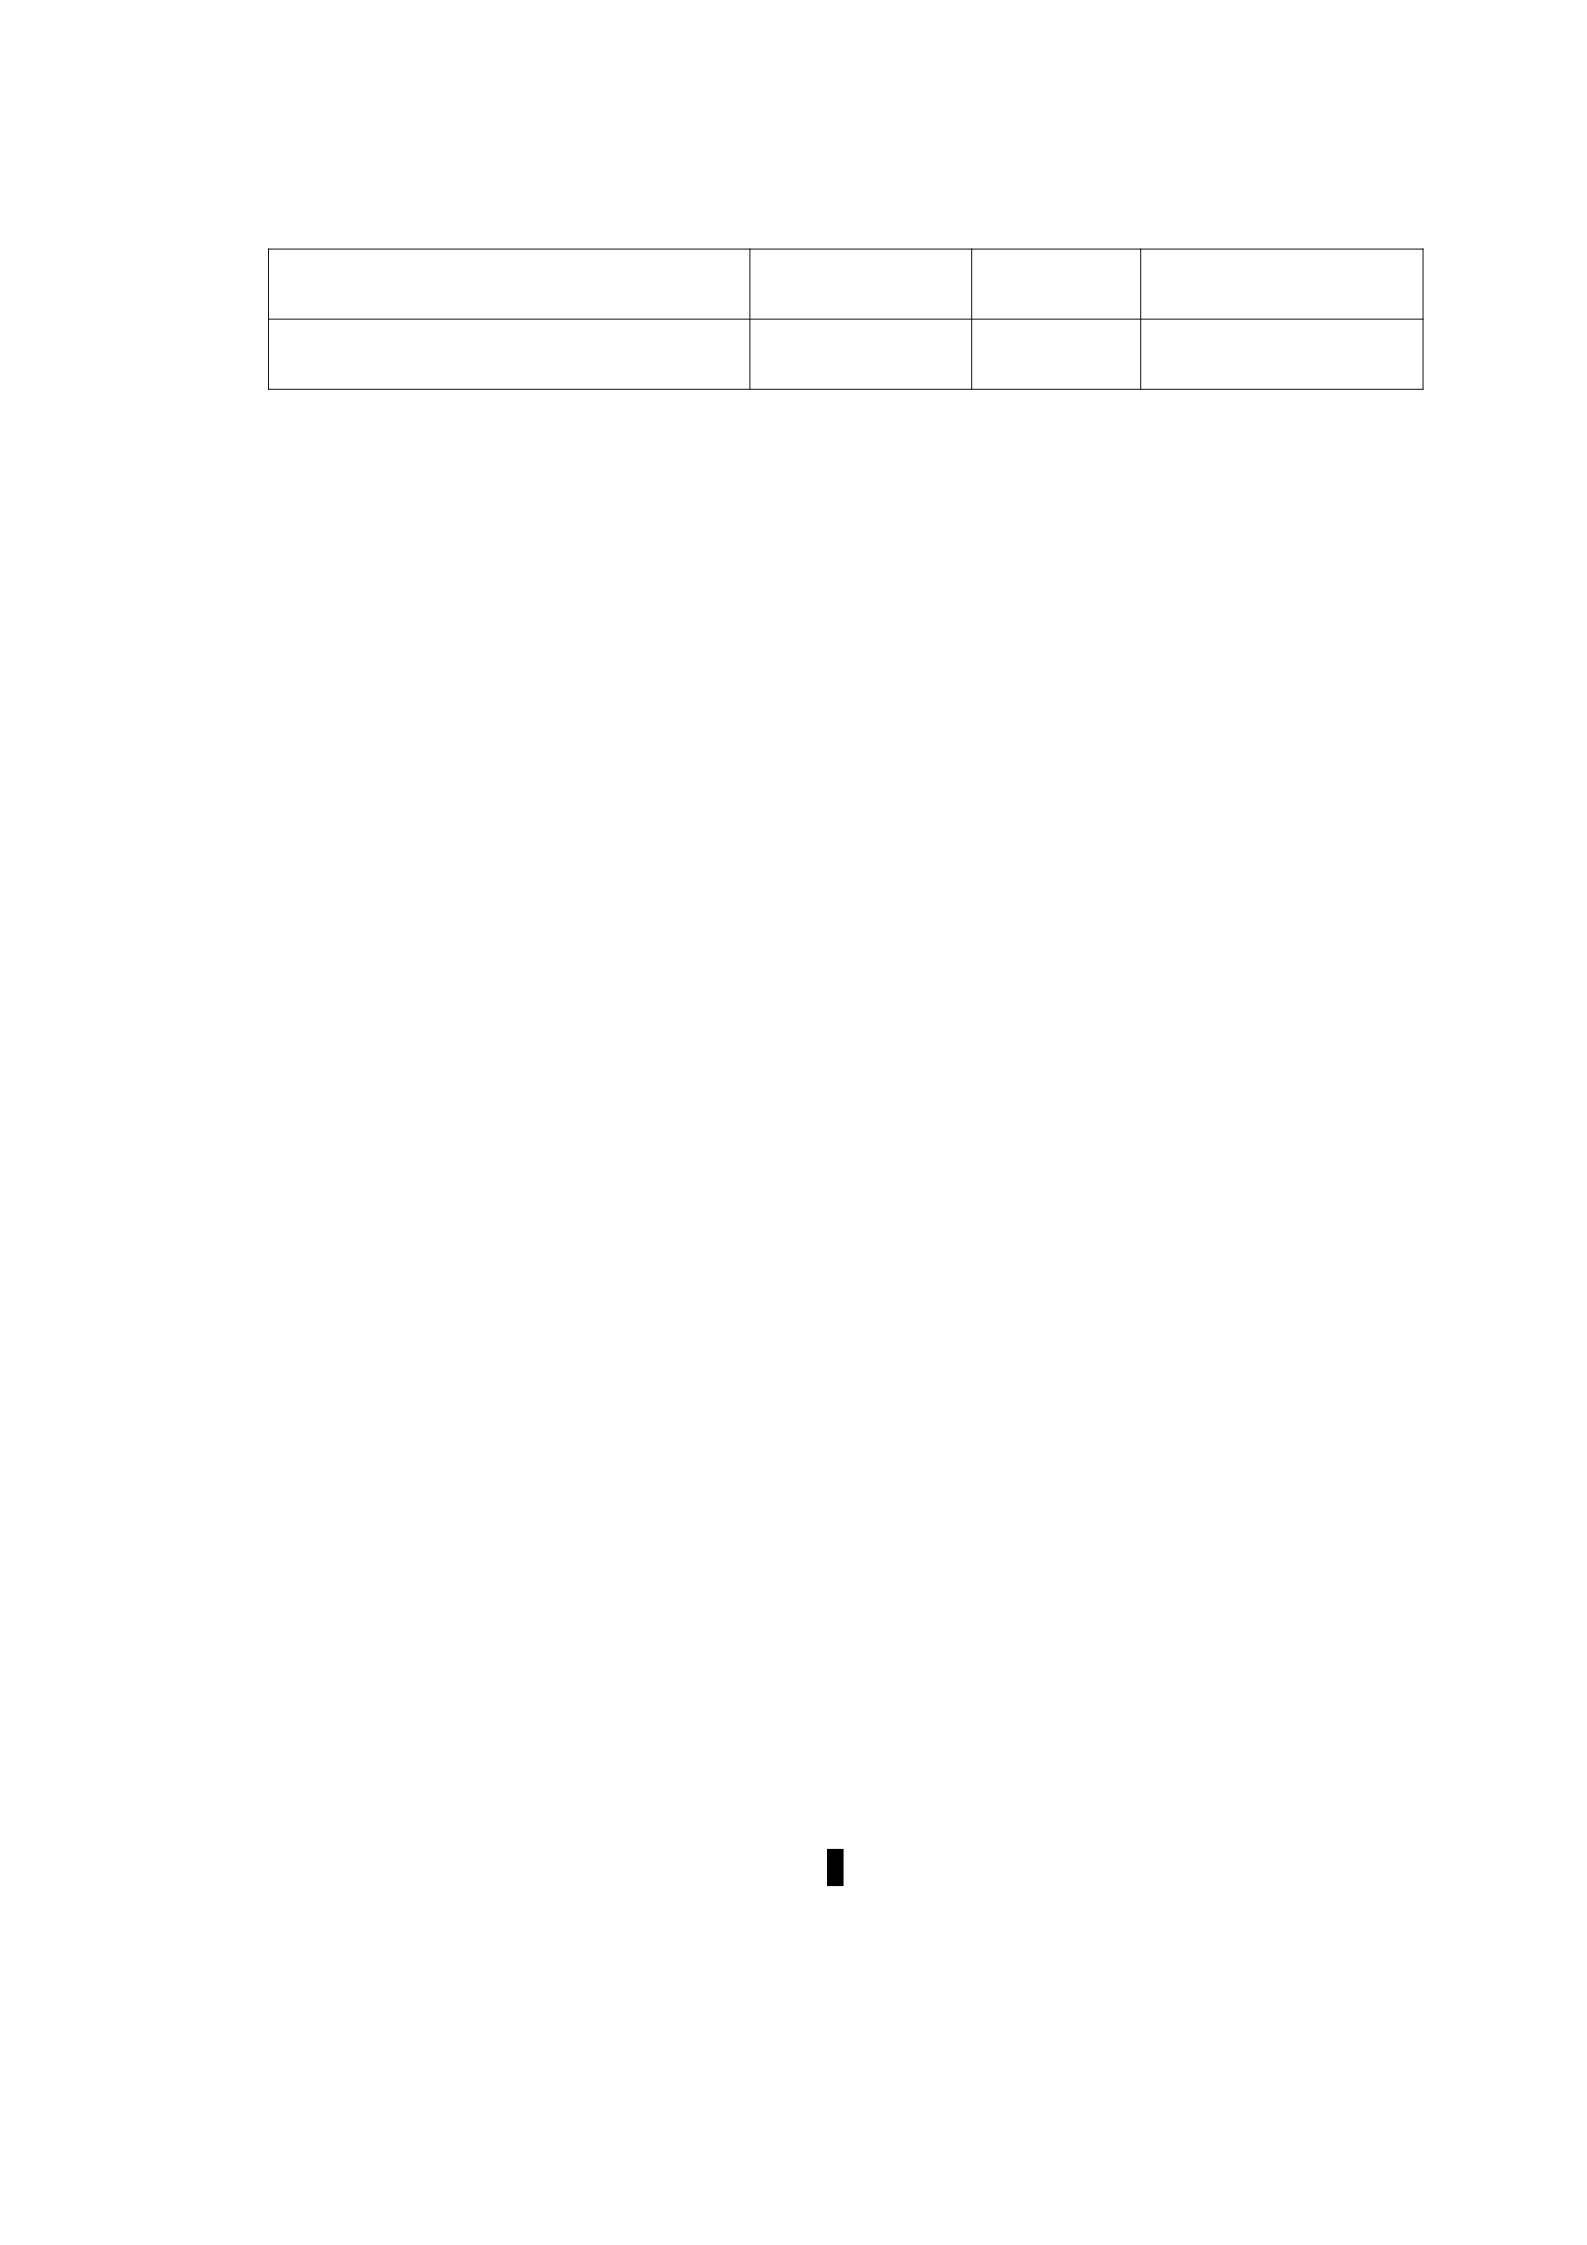
Resource
Proof-of-Stake-Velocity [3] Account Coinage PD ↵⇣i(!i)µ(min{h,H})
†The type of distribution a set of system resource expected to follow is dependent to the considered PoX scheme shown in
the first column (see the detail in Section 3.5.1).
? Pareto distribution. It describes an 80/20-rule-based wealth inequality (see the detail in Section 3.5.1).
‡Normal distribution.
!i denotes the amount of system resource owned by Node-i fi,h denotes the per-slot mining
probability of Node-i; see more details in Section 3.3.3.2
The following model is proposed to generalize (3.1) based on an infinite-
dimensional Markov chain. Under the premise of the above-mentioned existing
studies failing to evaluate PoX schemes in terms of steady states, the propose model,
as far as we know, is the first one that can be used to describe the PoX-based
consensus algorithms in a long-term stable system, in order to evaluate the
distribution of the mining winners, and predict the cost-benefit ratio.
3.3 New Infinite-Dimensional Markov Chain Model for PoX
Schemes
In this section, we first provide an overview of the proposed model along with
its network settings followed by the detail of the model. The proposed metrics,
Resource Sensitivity, System Convergence, and Resource Fairness will be elaborated.
3.3.1 Overview
For illustration convenience, we consider large-scale synchronous Blockchain
networks with reference to the settings of [68] (that at most one miner can
successfully mine a block within a time slot). We further consider a sparse
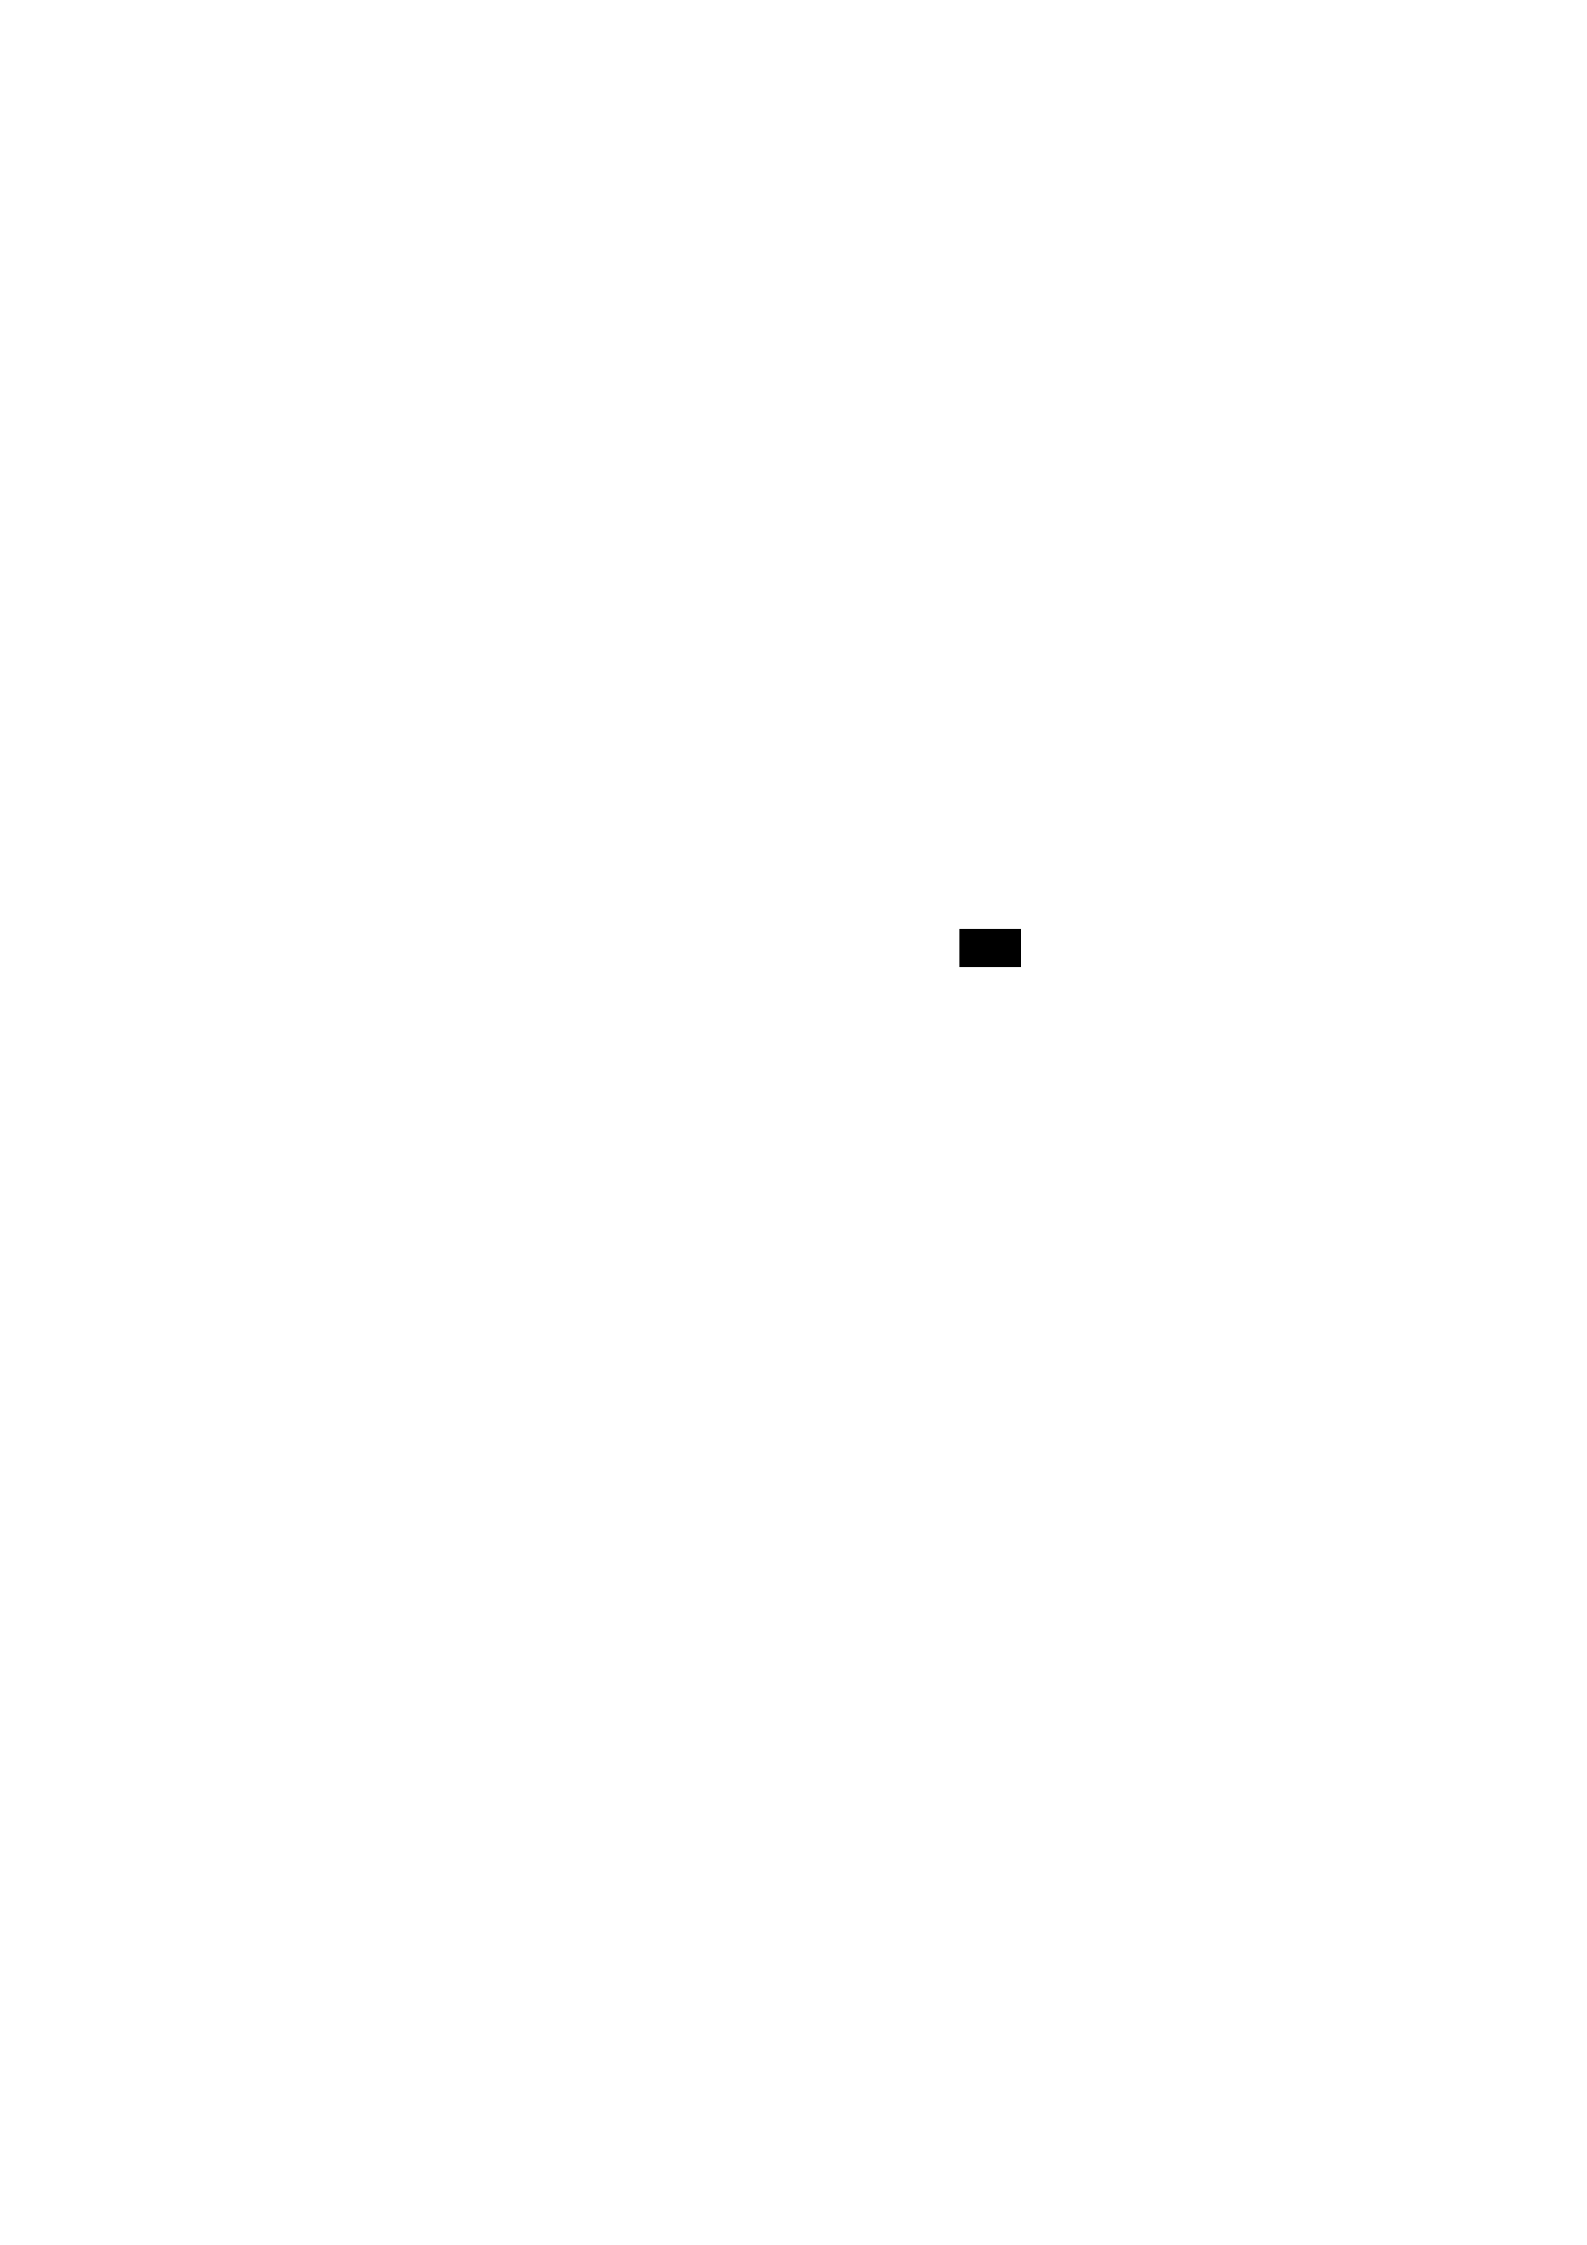
Blockchain system in which the value of is su ciently small and negligible with t
denoting the block propagation delay and T denoting the block period. Also, we
consider attack strategies which are resource-oriented, where attackers mainly
leverage the double spending attacks and selfish mining to maliciously rollback the
history based on their current dominated system resource ratio.
The analytical model is designed for analyzing the long-term steady-state (i.e.,
the probability of each state can be predicted as the system becomes stable) of PoX-
based consensus algorithms. This is achieved by considering the resource
distribution that is weighed by a Degree function and a Fairness function (which
will be defined in Section 3.3.3.2). The analytical model features an infinite-
dimensional Markov chain to investigate the long-term steady state. We also
propose three metrics, namely, Resource Sensitivity, System Convergence, and
Resource Fairness (which will be defined in Section 3.3.4), for evaluation and
simulation. To be specific, a generalized form of (the probability of Node-i
elected to be the block generator in a particular round) can be obtained, i.e., Pi. By
using Pi, we can evaluate the PoX-based consensus algorithms in terms of the
proposed metrics - Resource Sensitivity, System Convergence, and Resource Fairness.
3.3.2 System Model - Small-slotted mechanism
In this section, we describe the system model. The notations used are listed in
Table 3.2.
Our proposed analytical model starts with a small-slotted system, where the
period of any miner mining a block is denoted as a “round”, while a “miner” denotes
any node participating in the race to win for the block generator of each round.
Each round refers to a block height number and is divided into many small time
slots. The number of time slots contained in a round depends on the expected block
period, i.e., T. Each of the slots lasts a constant short time. The gap between two
consecutive slots can be reduced to satisfy the assumption referred to [68]. This
assumption is reasonable as we can make the slots arbitrarily small; see Fig. 3.1.
Each miner can potentially generate a new block on block height n, based on the
amount of its system resources, as can be done by evaluating (3.1). In some PoX
schemes, such as coinage-based PoS and PoS-Velocity, (3.1) can be a ected by the↵
awaiting gap h of each miner, with an upper bound H. The awaiting gap is the gap
between the considered miner being the elected generator from the last round to
present. There exist the following three possible scenarios for a miner within a
slot.
Table 3.2 : Parameters of the analytical model
Symbols Description
hAwaiting gap that is miner-specific, the gap since the last round a designated miner
being the winner until it wins again?.
(·) A Degree function measuring the impact of h on fi,h
(·)⌥A Fairness function defining whether the monopoly of system resource can be
avoided
!iThe amount of system resource owned by Node-i
NThe number of miners among the entire network
HThe upper bound of h
↵A constant network parameter, normalizing the mining probability fi,h in terms of
the size of a time slot
Pr(x|y) The transition probability from awaiting gap y to awaiting gap x
RThe mining probability of the entire network per slot
fi,h The mining probability of Node-i per slot at awaiting gap-h
⇡(h) The steady probability of a miner at awaiting gap-h in an arbitrary slot
TiThe average number of awaiting gap for Node-i being the winner since its last
winning
PiA generalized form of Pi,win in (3.1) based on the proposed model
tThe block propagation time
TThe expected value of block period (round)
? This can be any level of grain. For example, it can be block-height-oriented (in terms of the block
height), as shown in Section 3.5 or time-oriented [193]. Alternatively, it can be a customized level
of grain can replace the block height or time to meet specific requirements.
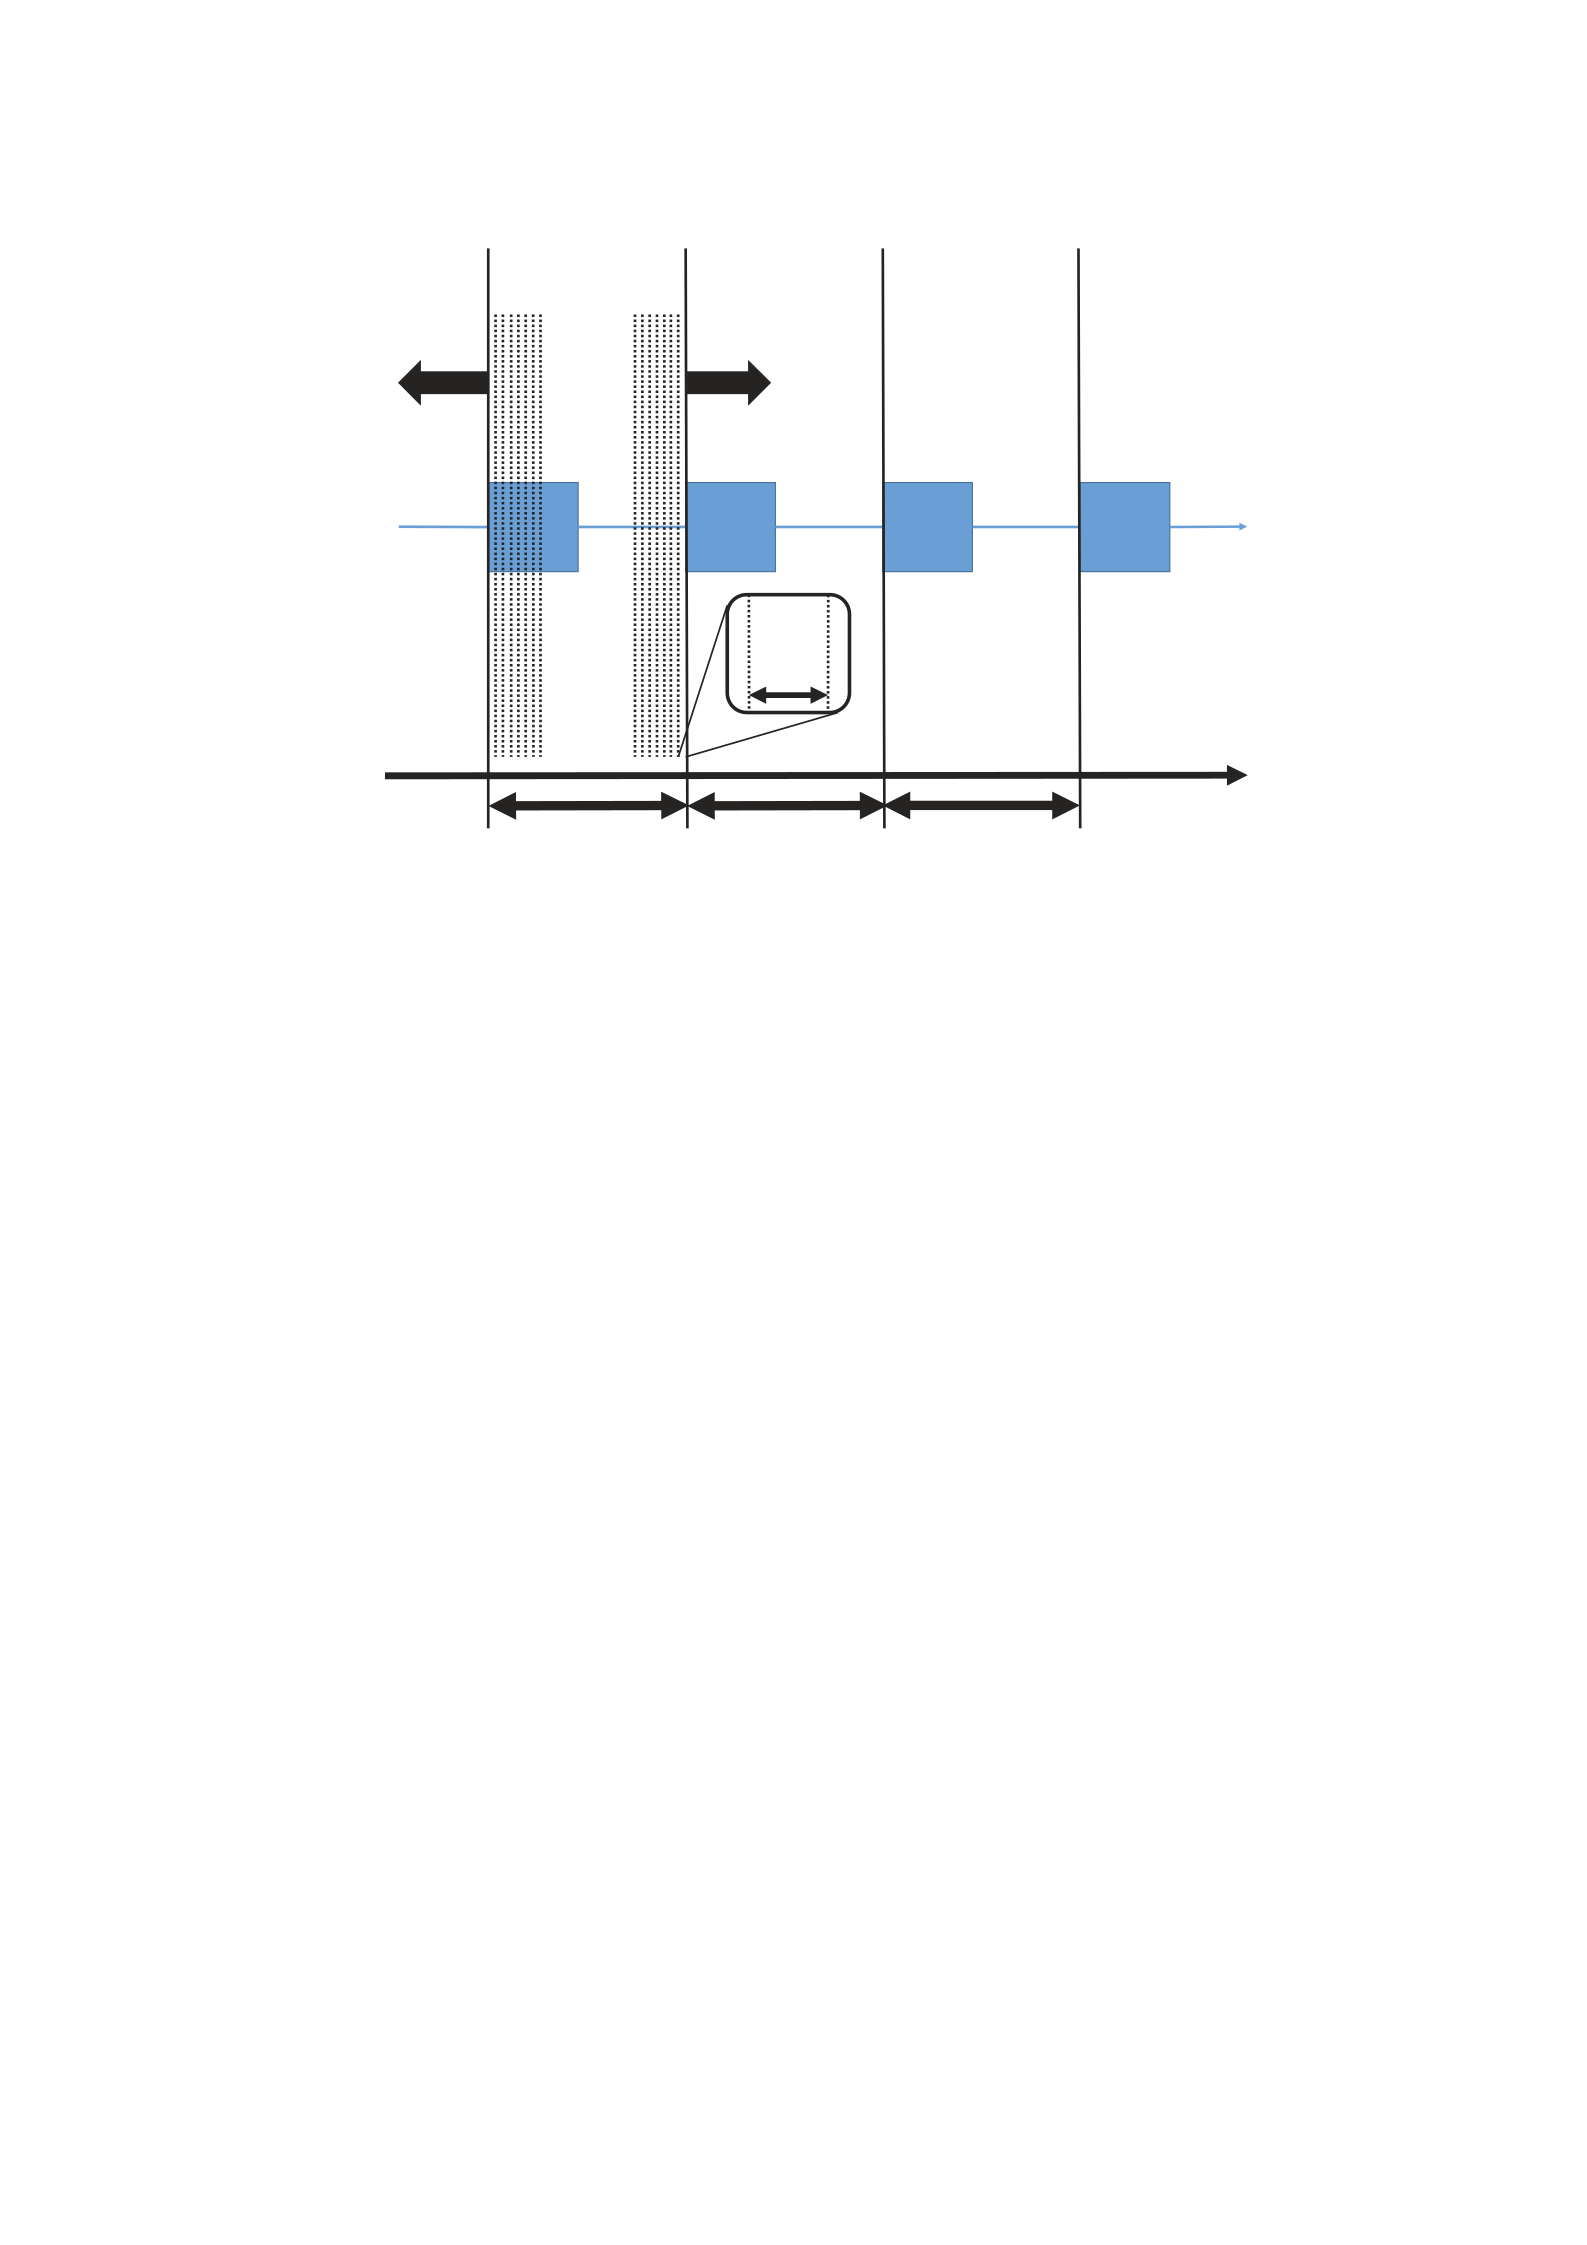
Figure 3.1 : The small-slotted mechanism divides a round into multiple slots. The number of slots
contained in a round is subject to the expected value of the block period T.
1. Scenario 1: None of the miners mines a valid block in the network.
2. Scenario 2: This miner does not mine its own block but accepts a block mined
by another miner;
3. Scenario 3: This miner mines a block, and the block is immediately accepted
by other miners at the beginning of next slot, prior to the mining for the next
round;
3.3.3 The Proposed Analytical Model
To clarify Scenarios 1-3 in Section 3.3.2, we present an infinite-dimensional
Markov chain. For simplicity, Pr(·) denotes the simple form of Pr(i,·) for Nodei; ⇡(·)
denotes the simple form of ⇡i(·) for Node-i.
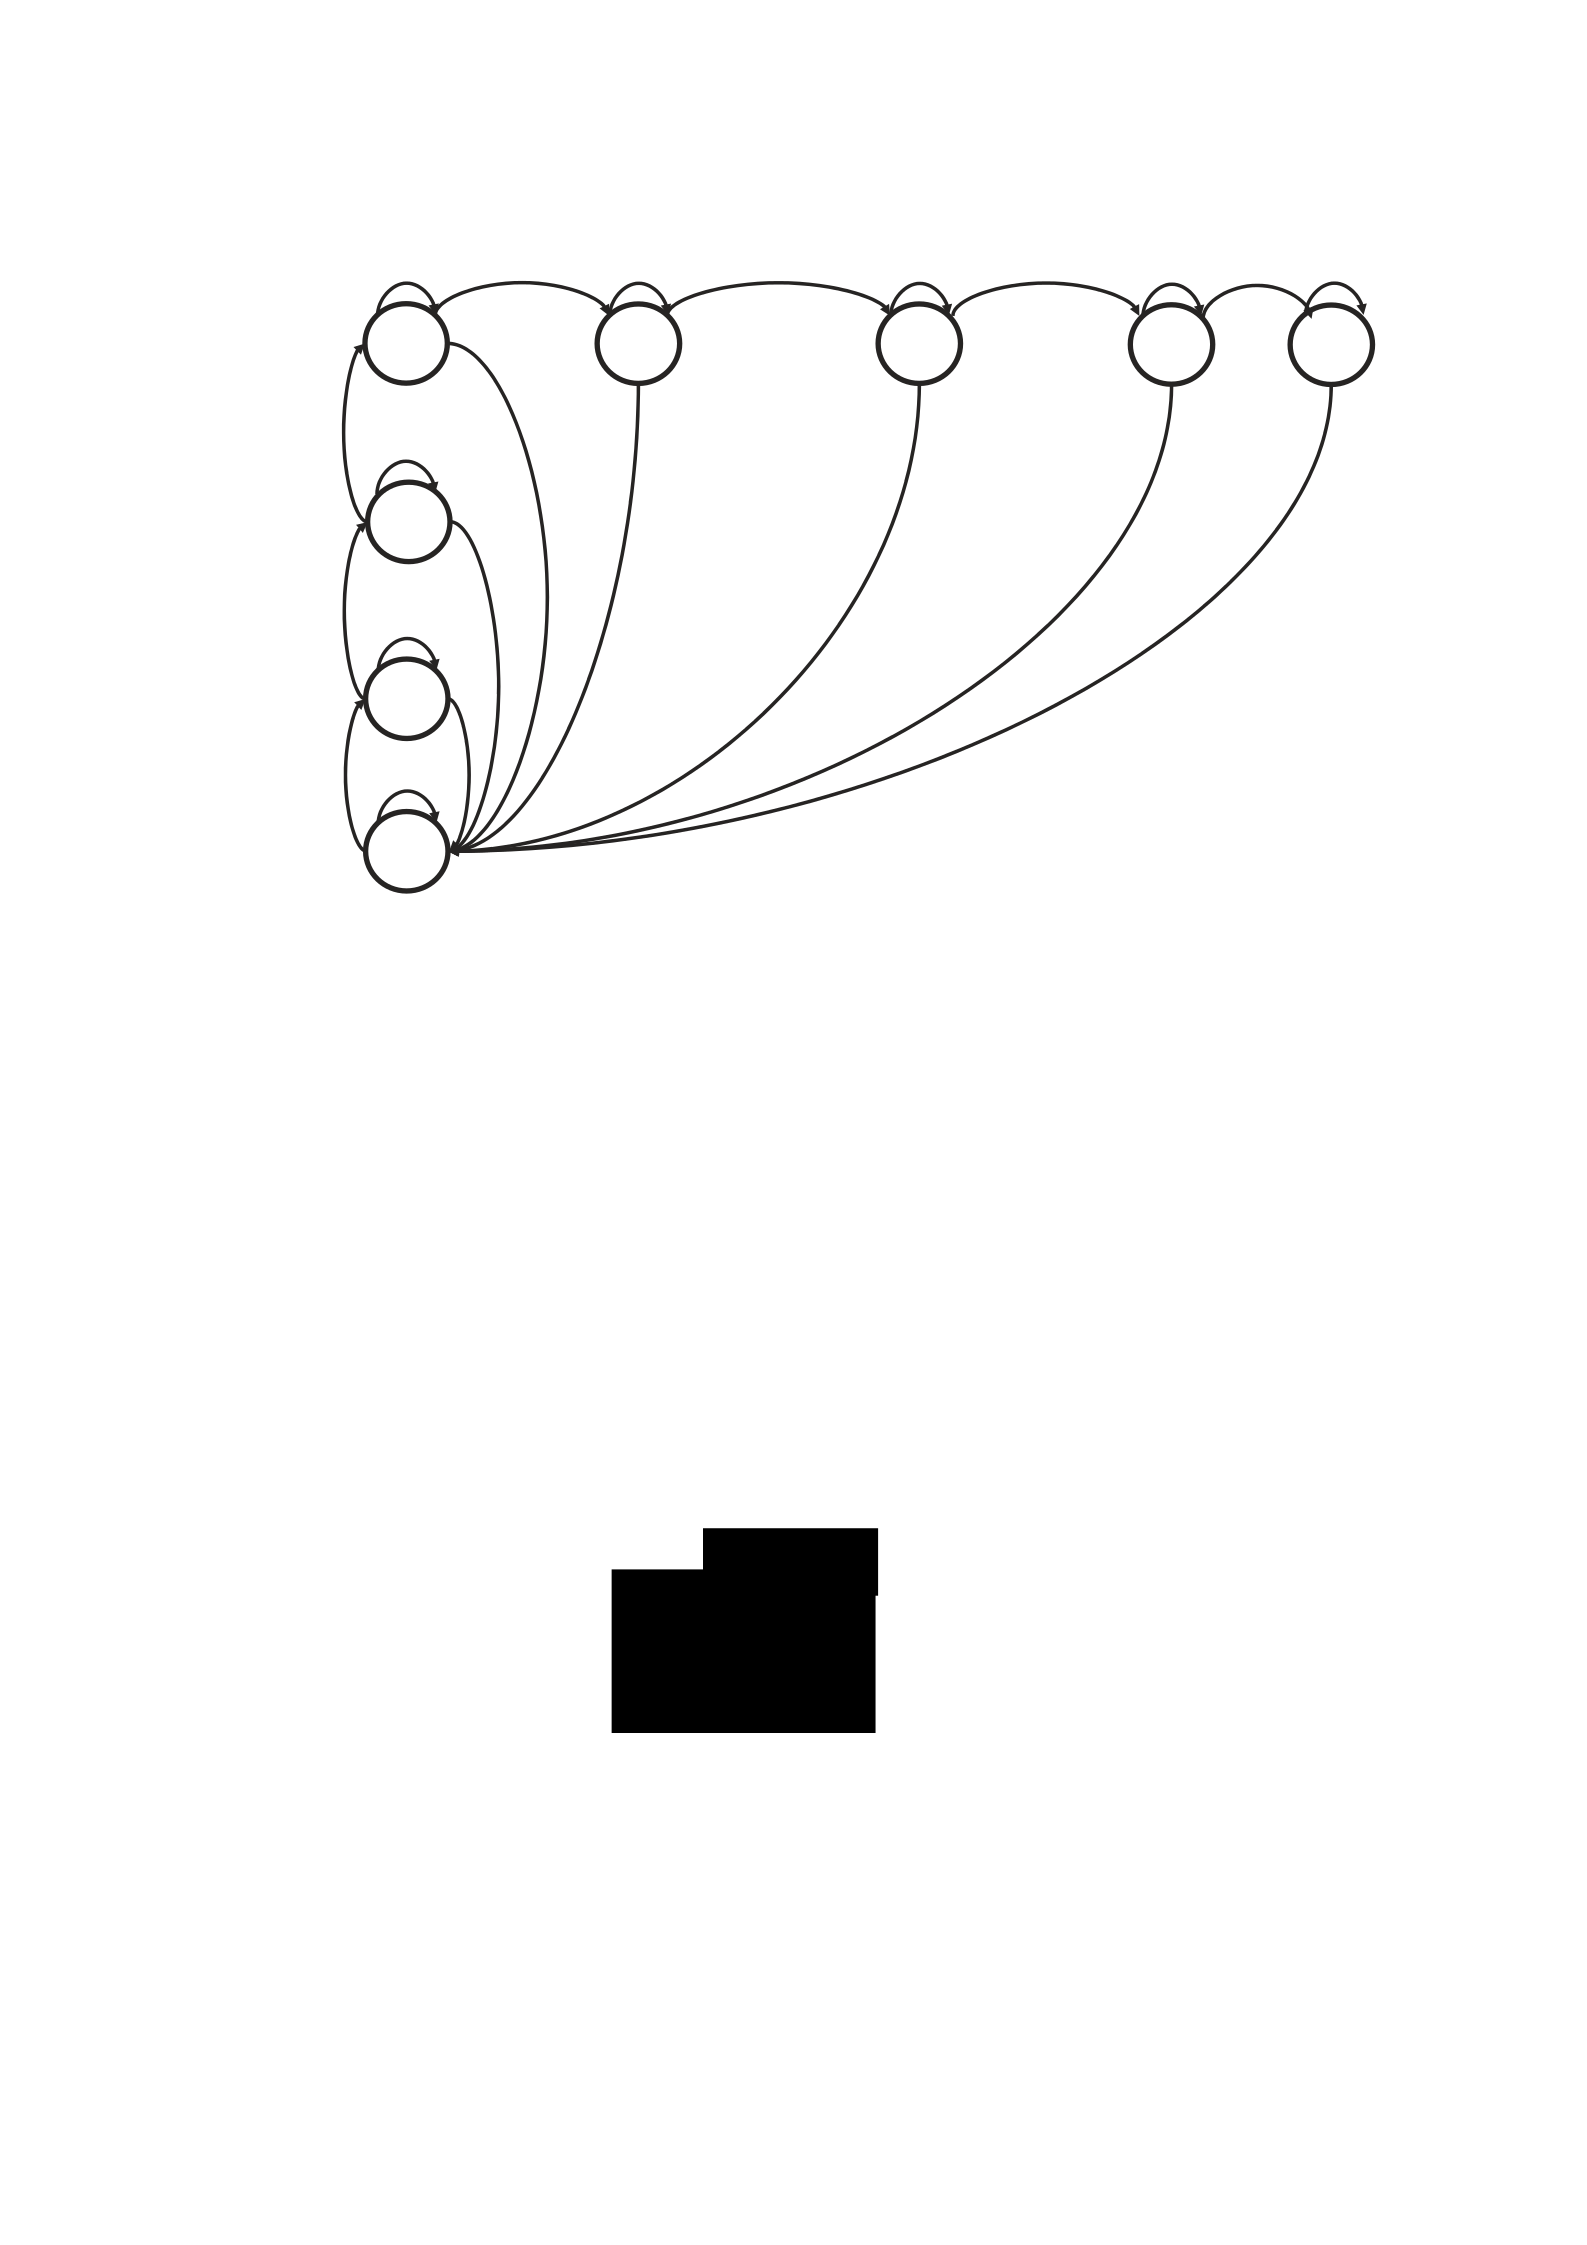
Figure 3.2 : The state transition of the proposed infinite-dimensional Markov chain at Node-i. fi,h is
denoted as fh for simplicity.
3.3.3.1 The infinite-dimensional Markov chain
Let Pr(x|y) denote the transition probability of an individual node/miner from
awaiting gap y to the awaiting gap x at two consecutive slots. The transition
probability at Node-i can be given by
Pr(h|h) = 1 R; (3.2a)
Pr(h + 1|h) = RPr(1|h); (3.2b)
,if 1 < h H;
Pr(1 >> i,H (3.2c) f
,if h > H;
,if h = 1;
>>>: 0,otherwise.
In (3.2), R denotes the mining probability of the whole network at a slot. We
consider R is consistent over time, as it must take some k slots for miners to
generate a new block for a specific round, while k depending on a constant T can
>
also be considered to be constant in the long term. Recall that h is miner-specific
(and is the simple form of hi). h is not the actual height of the chain, but the
awaiting gap which can be block-height-oriented (see Table 3.2), between the
previous round where a miner being the block generator and the current round
where the same miner being selected again.
In (3.2), a miner running at an awaiting gap h within the considered slot
behaves either in the following way.
• Eq. (3.2a) refers to Scenario 1. It provides the transition probability that no
new block is mined in the network during this time slot. Thus, the miner is
still at the awaiting gap h in the next slot.
• Eq. (3.2b) refers to Scenario 2. It provides the transition probability that this
miner does not generate a new block, and a new block generated by another
miner is finalized. Thus its awaiting gap h increases by 1, with a probability of
R Pr(1|h).
• Eq. (3.2c) refers to Scenario 3. It provides the transition probability that the
miner is elected as the block generator to finalize a new block. Thus, its
awaiting gap h returns to 1, with a probability of fi,h if 1 < h H. Otherwise, fi,H
remains unchanged if h > H with an upper bound H set.
It is apparent that the process above is stateless, in the sense that the
probability distribution of any state-(h + 1) would only be determined by the
current state-h. Moreover, a state can transit forward to H1 along with the decreased
zero-lowerbounded steady probability as h ! H. It is thus reasonable to use an
1 H H, denoting the gap between the chain tip and state-1, could theoretically be infinity.
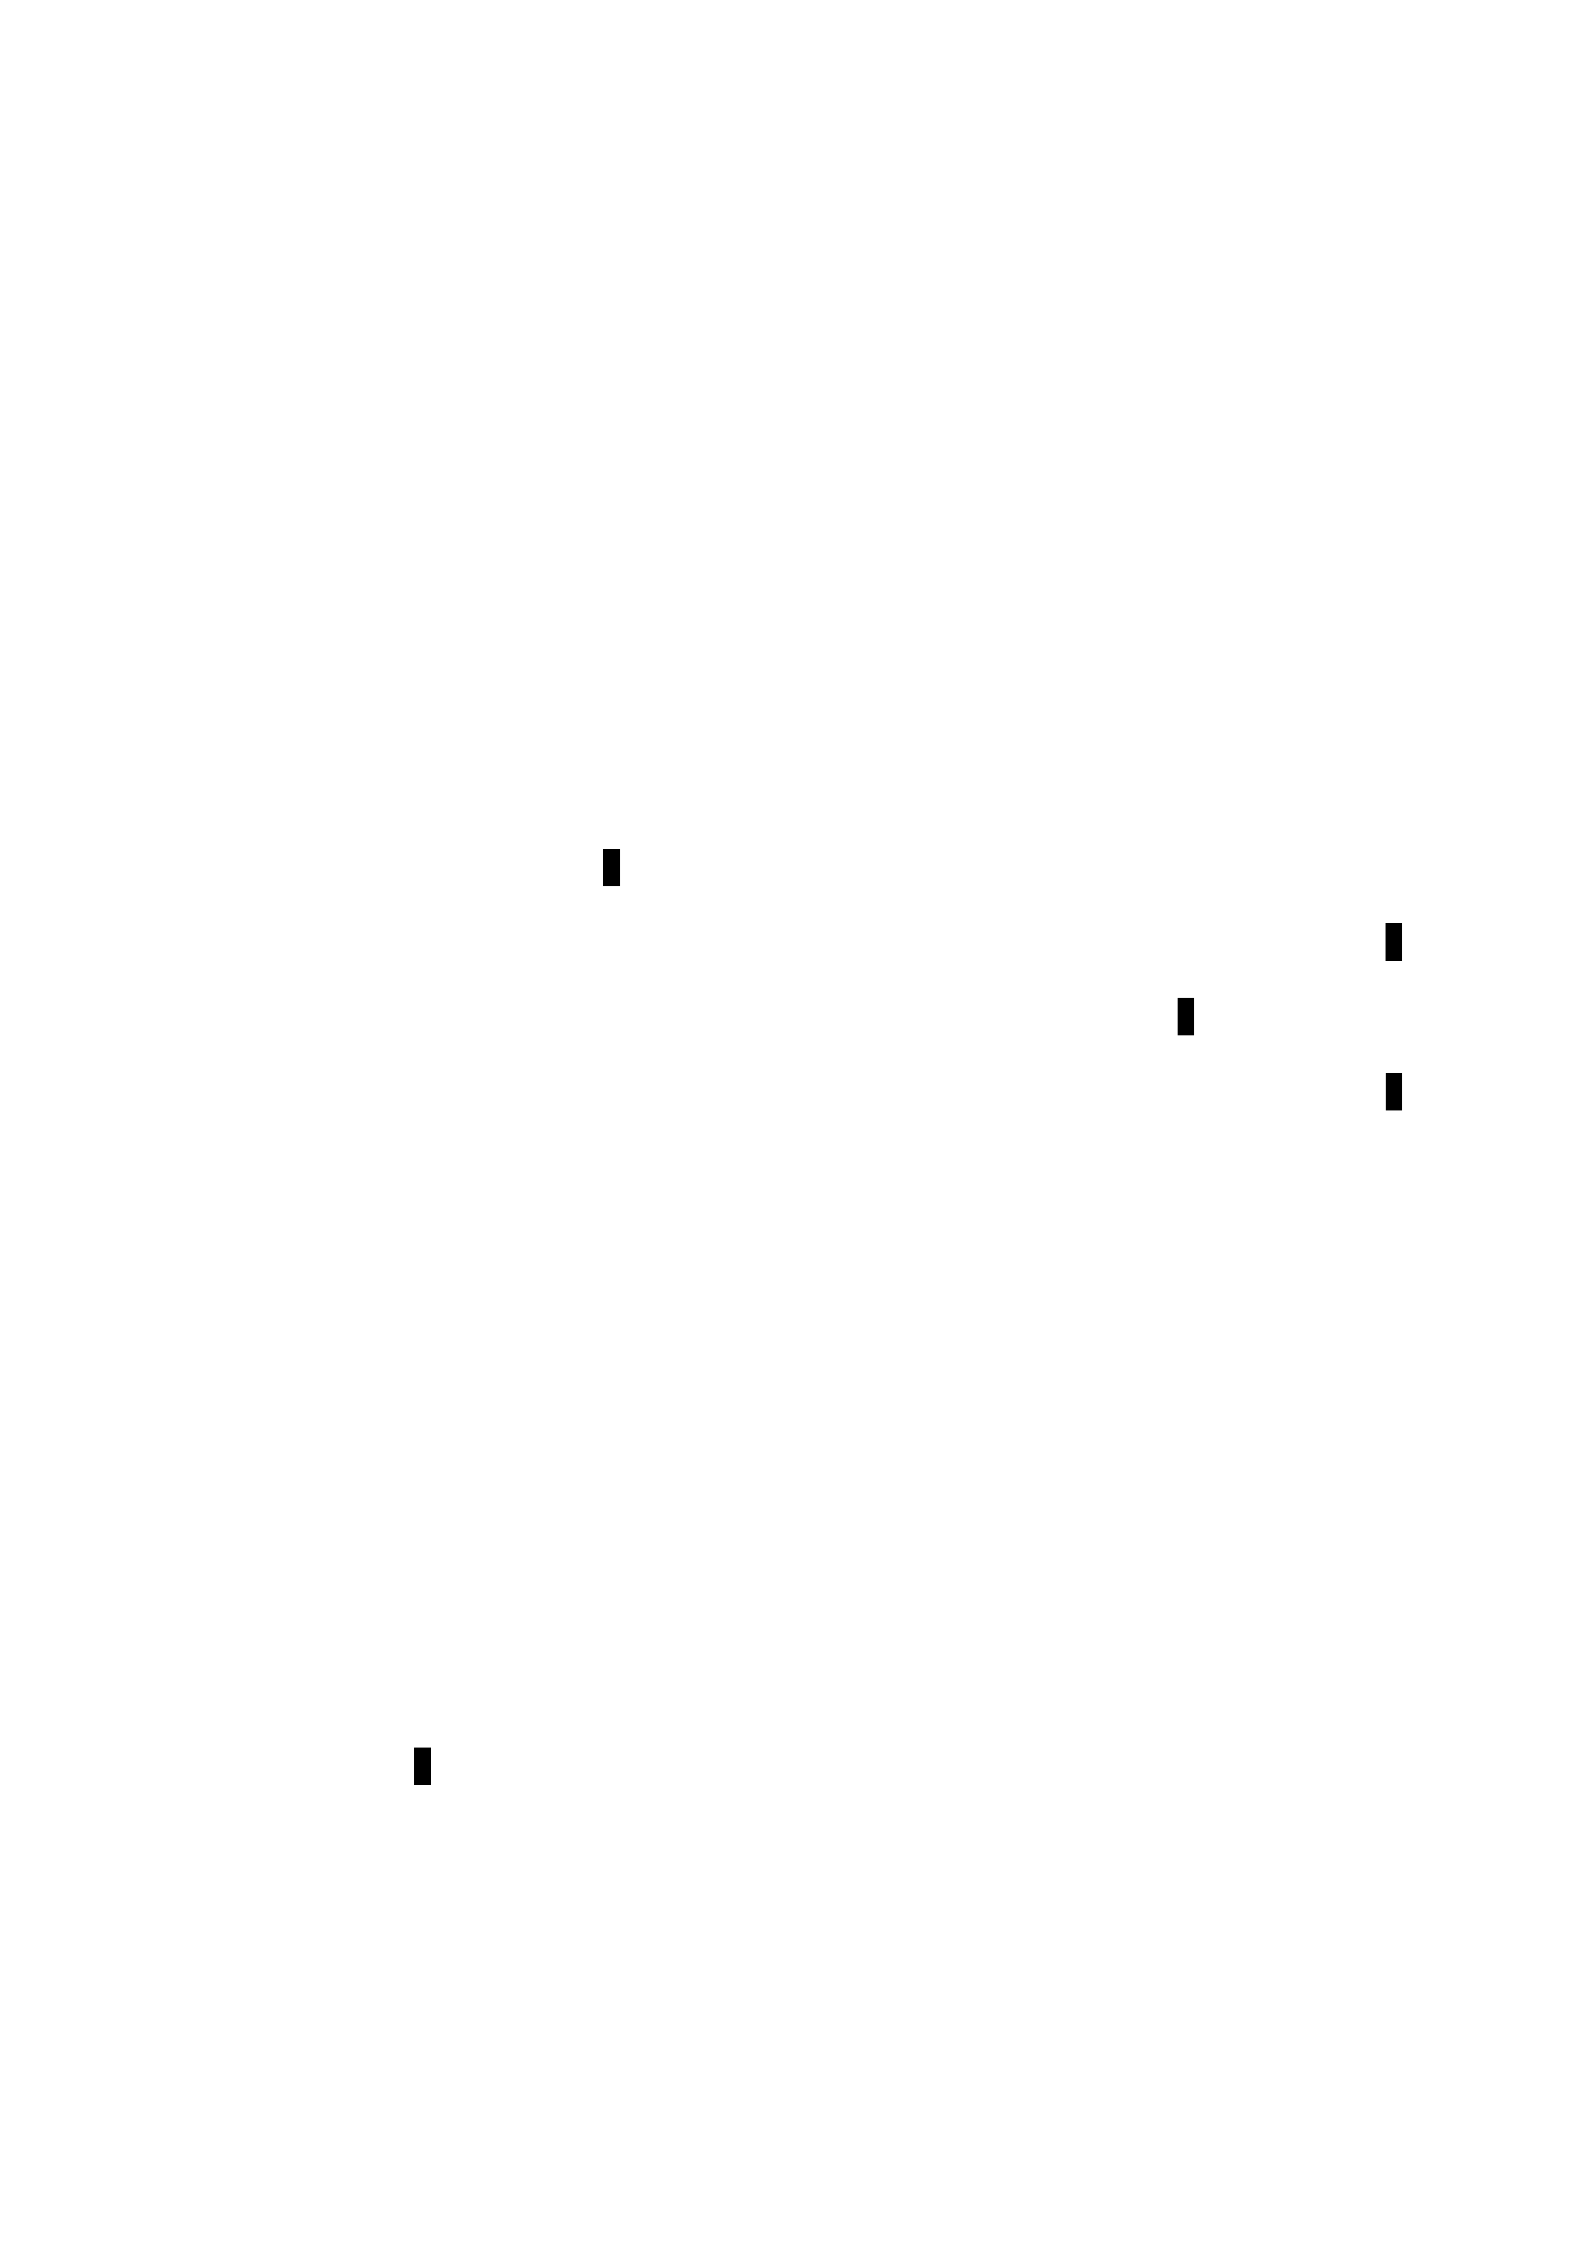
infinite dimensional Markov Chain to capture changes of the awaiting gap in our
system.
With an increasingly comparable network latency t, the probability of finalizing
a valid block per unit time (the slot time) decreases. This leads to a larger average
number of slots contained in a round due to the increasing likelihood of forks per
slot time, which results in a slower block period; see (3.2). The deviation
(decreased probability of the generation of a valid block per slot time) implicitly
captures the impact of network delay in practical asynchronous networks on the
overall mining process and block miming at block-n. Intuitively, the deviation
depends on the value of . The probability of finalizing a valid block per slot time
incur deviation away from the estimated one derived from our model as
increases. In such way, the deviation can correspond to the value of .
To simplify and satisfy the small-slotted mechanism, we consider a small
where t denotes the propagation delay and T denotes the expected block period
(more details in Section 3.4.1). Thus, the miners avoid needing to consider forking
(i.e., multiple blocks with identical height being found), and have su cient time to
mine a potential unique block at the same block height-n among all received blocks
at height-(n-1). With the help of a game-theoretic incentive scheme [135], the
miners are willing to be consistent with each other about the finalized block for the
current round (the block is broadcast and accepted by all miners), e.g., based on the
di culty defined in Bitcoin [135] or Ethereum [38]. In other words, this situation
can be interpreted to a small-slotted mechanism with su ciently small and
negligible , i.e., the first generated block can be finalized and accepted by all
miners immediately to reach the consensus, and consistency can be satisfied by the
end of this round. Thus, the infinite-dimensional Markov Chain satisfies our
proposed small-slotted mechanism, hence Scenarios 1-3 as defined above can hold.
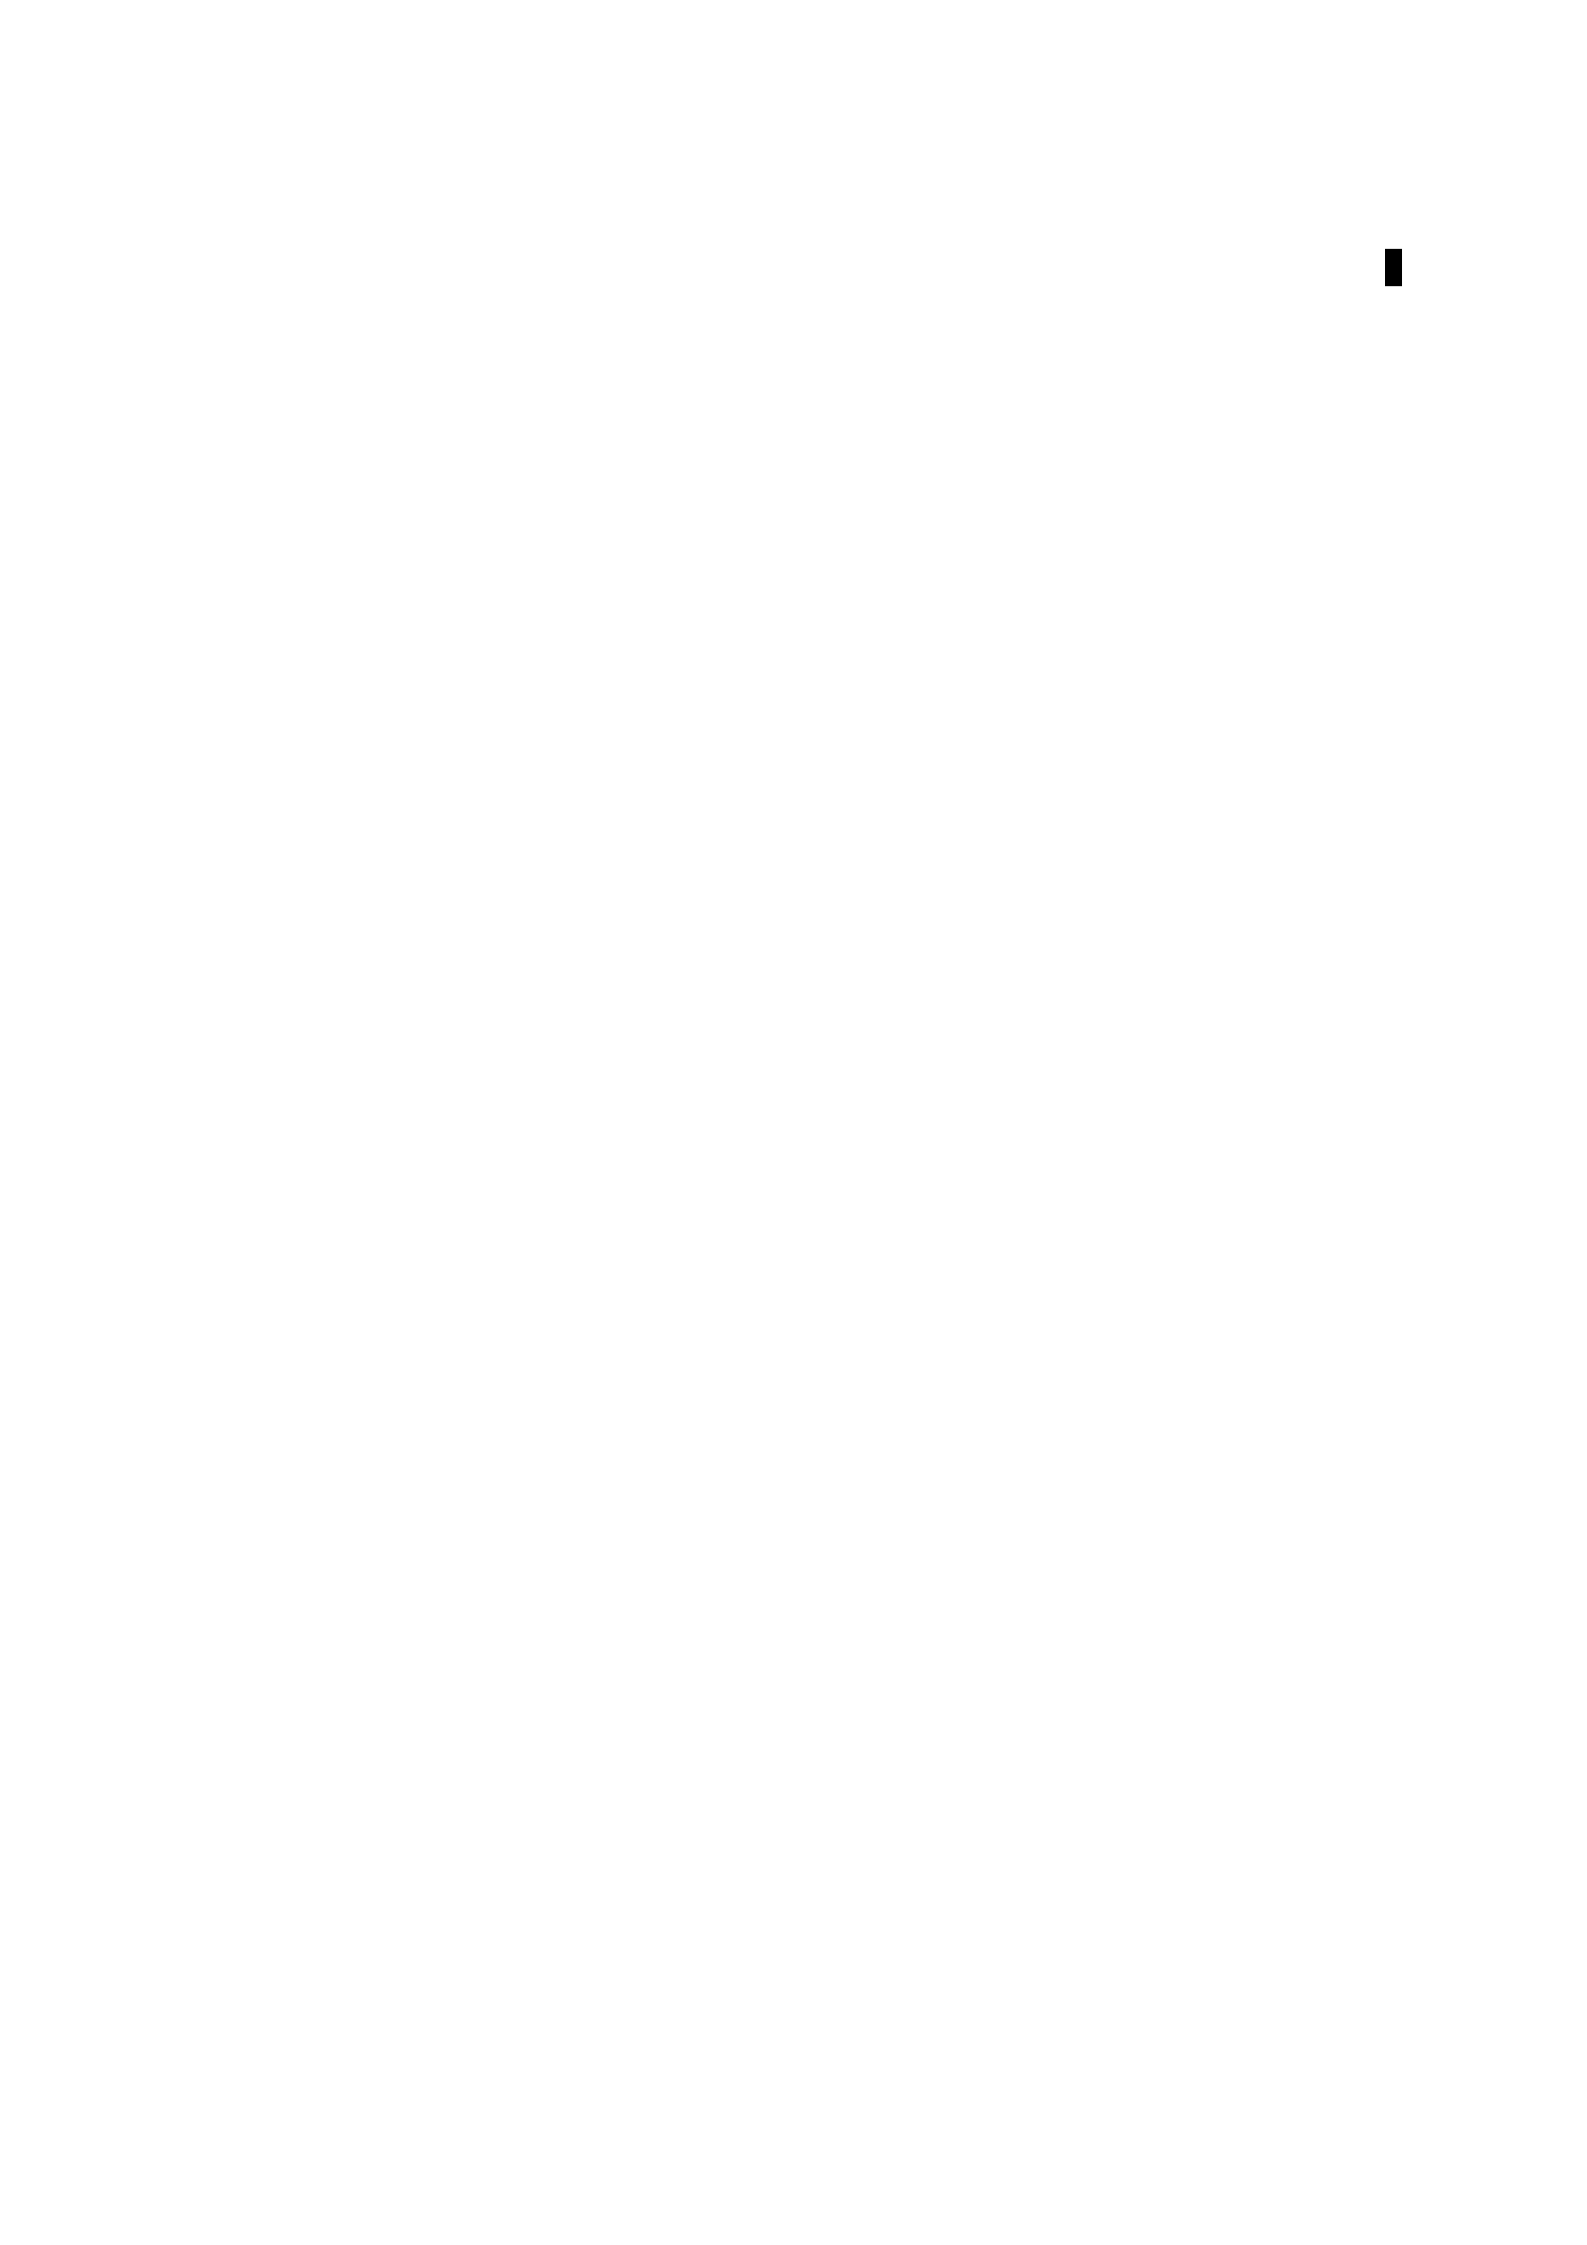
As a consequence for the results of our calculation and simulation, a small
minimizes the impact of propagation latency.
3.3.3.2 The per-miner-per-slot mining probability fi,h
According to (3.2c), fi,h provides the per-slot mining probability of Node-i at
awaiting gap-h. fi,h depends on other nodes. It reflects the system resource
distribution of a specific node, Node-i, at the state with the awaiting gap h. We
propose the following expression for fi,h to unify it for a range of popular PoX
schemes:
fi,h = ↵(⌥!i) (h,H) R. (3.3)
Here, (·) and⌥(·) are defined as the Fairness function and Degree function, re-
spectively.
•Fairness function indicates whether the weighted resource distribution is
Fairnessoriented, and how Resource Fairness a ects the weighted resource↵
distribution if any.
•Degree function can be customized in terms of the awaiting gap h, along with
an upper bound H. It measures how much the awaiting gap impacts on the
resource distributed to each miner, in turn, the probability that a miner is
elected to be the block generator.
For example, (⌥!i) = !i indicates an inactive Fairness function, while (·) can be a⌥
partition function if fi,h is Fairness-oriented (so that the impact from a high !i to fi,h

can be restrictive). ↵is a network-level parameter normalizing the probability and
accounting for the size of a time slot. (·) can be either equal to 1 (an inactive Degree
function), or customized depending on the awaiting gap h and an upper bound H.
For example, (·) = min{h,H} (a positive Degree function that delivers a positive
correlation of fi,h and h), outputting the minimum value between the current h and
H, is used in the existing PoS consensus algorithm [96]. The expressions for fi,h
under currently popular PoX schemes are shown in Table 3.1.
3.3.3.3 Steady-state probability
In this section, the steady-state probability of a miner at awaiting gap-h at an
arbitrary slot is evaluated. The steady-state probability, denoted by ⇡(h), can be
calculated in three cases, i.e., h = 1, 1 < h H and h > H, subject to the rule of
“steady state”, ⇡(h) = Pi Pr(h0|h)⇡(h),8h : P⇡(h) = 1. We consider that any fi,h with
awaiting gap 8h > H, equals to fi,H. ⇡(h) can be derived based on (3.2) as
follows.
In the case of 1 < h H:
The steady-state probability ⇡(h) can be given by
(3.4)
= (R fi,h 1)⇡(h1) + (1 R)⇡(h),1 < h H,
⇡(h) = Pr(h|h1)⇡(h1) + Pr(h|h)⇡(h)
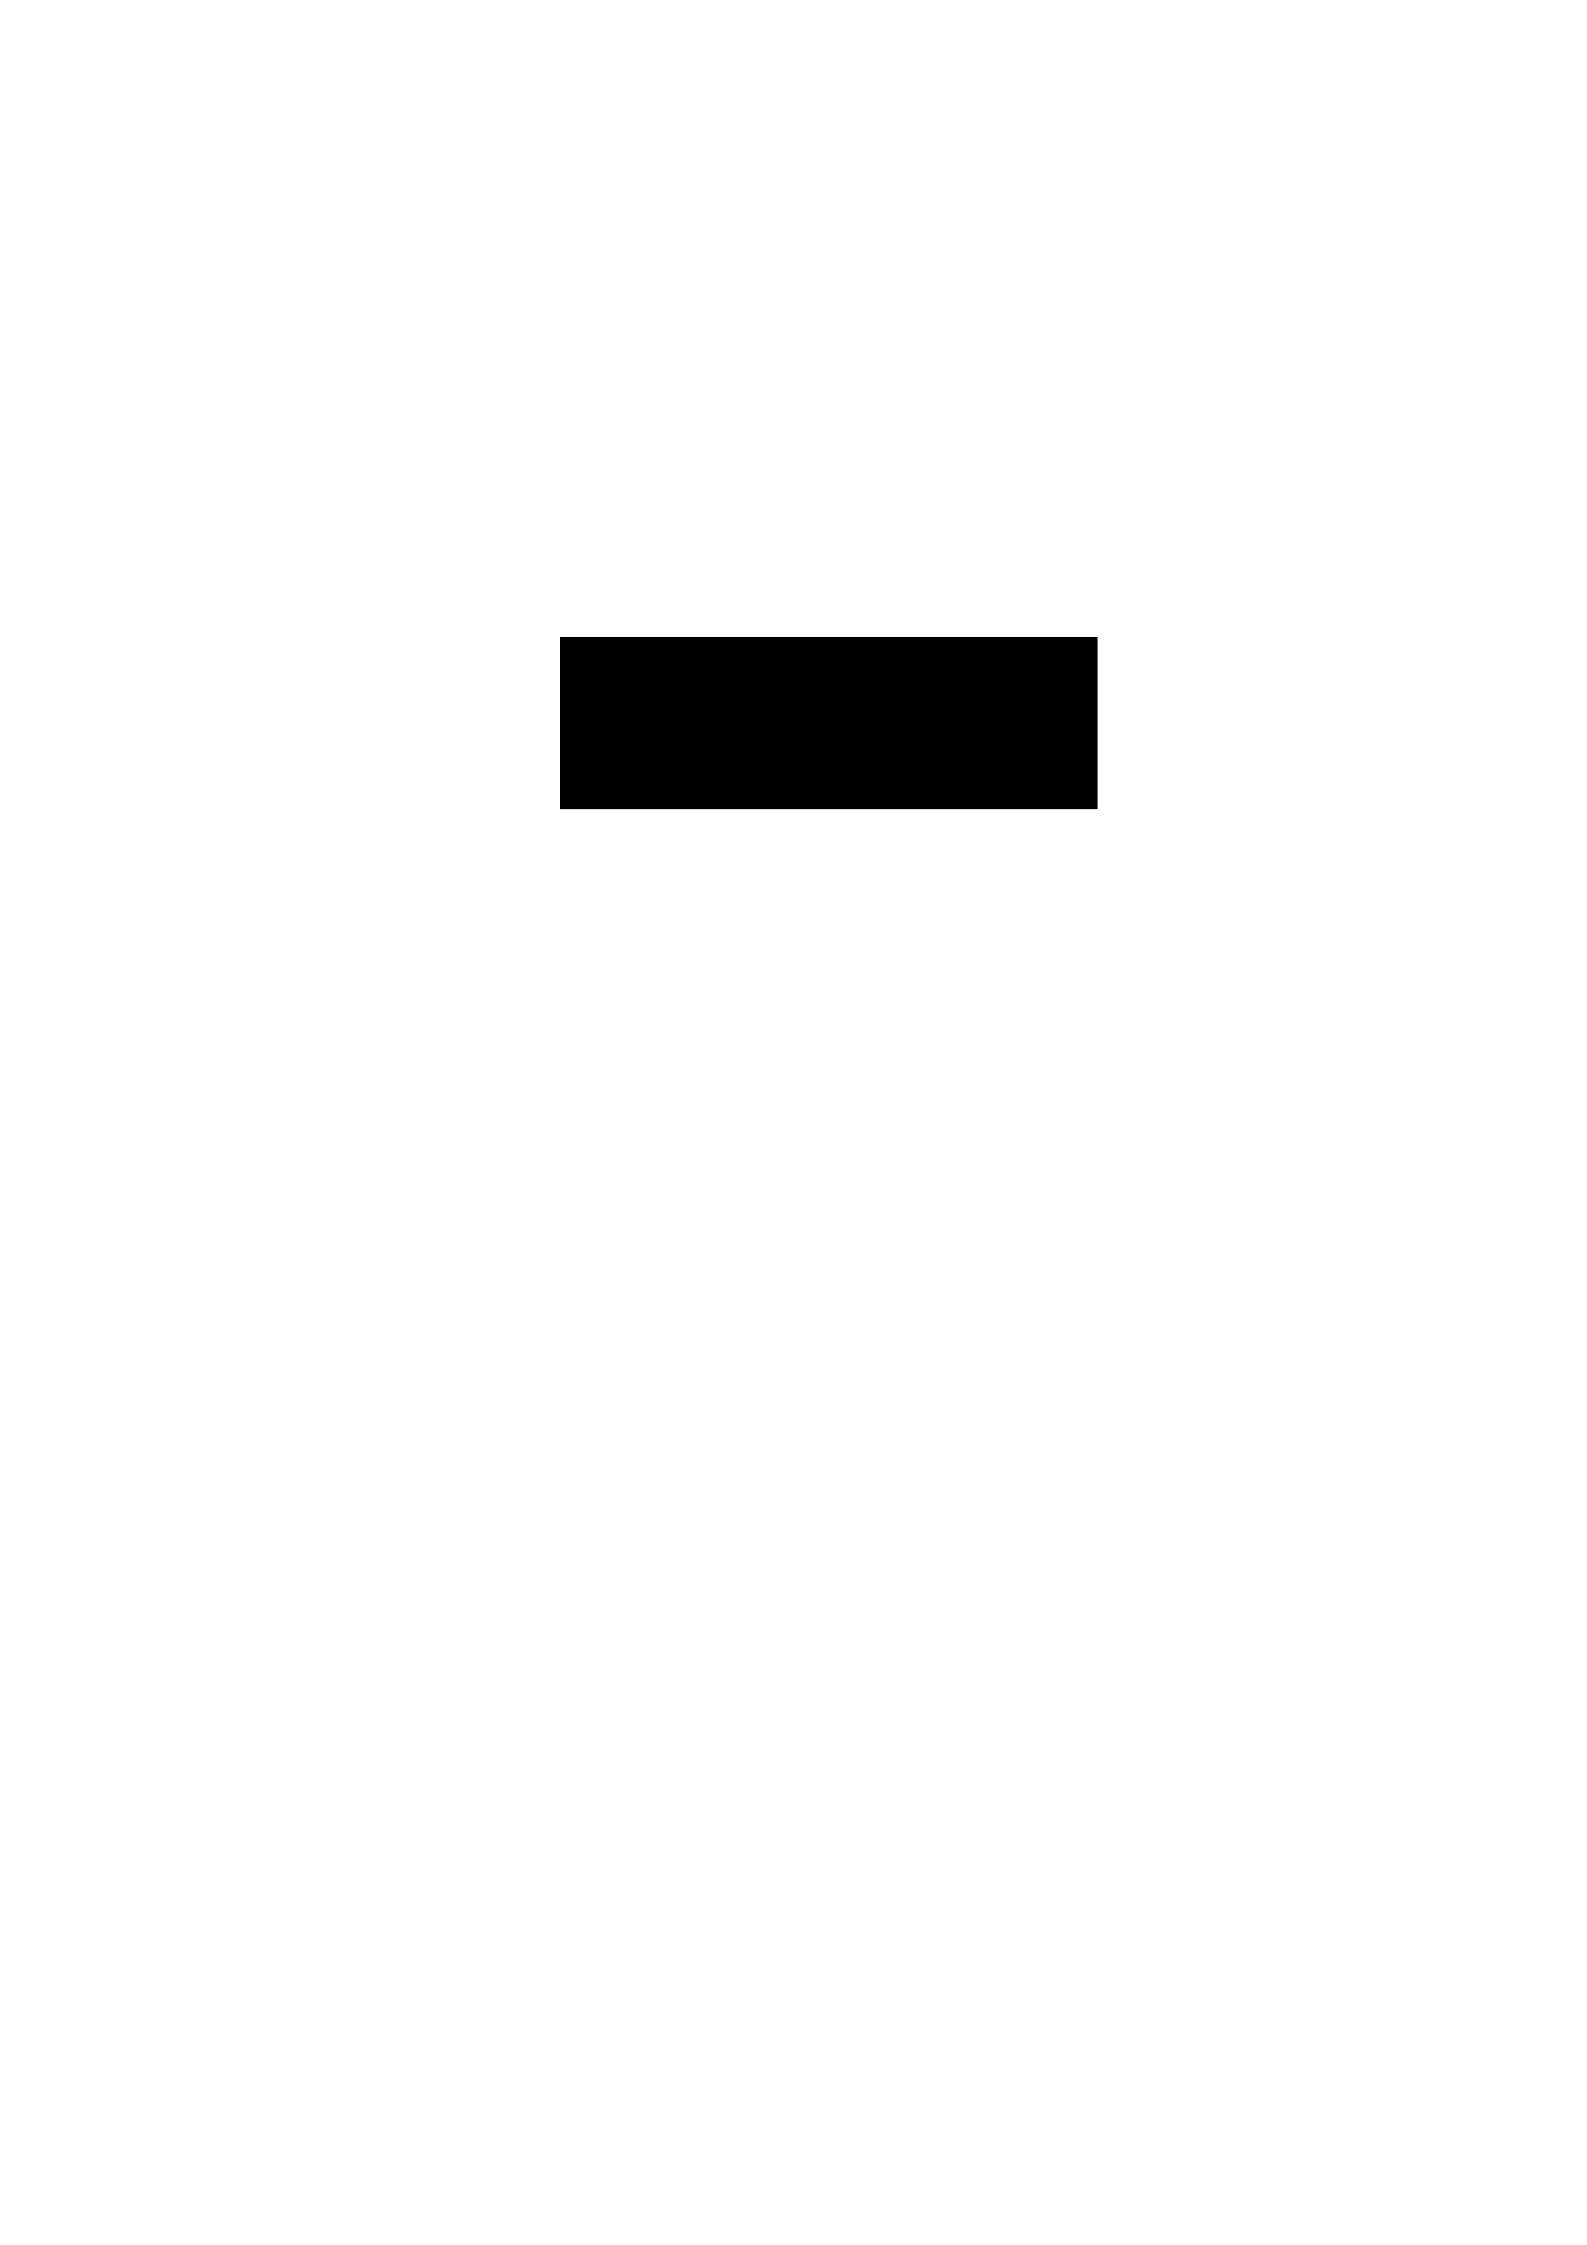
which is derived from (3.2). In particular, ⇡(h) is equal to the sum of the
probabilities, 1) that Scenario 2 happens given that the considered node is on the
awaiting gap h1, i.e., Pr(h|h1)⇡(h1); and that 2) Scenario 1 happens given
that the considered node is on the awaiting gap h, i.e., Pr(h|h)⇡(h).
By rearranging (3.4), ⇡(h) can be rewritten as
(3.5a)
(3.5b)
where (3.5b) is obtained by recursively substituting ⇡(h 1) with ⇡(h 1), ⇡(h 2), · ·
·, ⇡(2) into the right-hand side of (3.5a).
In the case of h > H:
The steady-state probability ⇡(h) can be given by
⇡(h) = Pr(H + 1|H)⇡(h1) + Pr(h|h)⇡(h)
= (R fi,h)⇡(h1) + (1 R)⇡(h), h > H, (3.6)
which is also derived from (3.2). In particular, ⇡(h) is equal to the sum of the
probabilities that, 1) Scenario 1 happens given that the considered node is on the
awaiting gap h, i.e., Pr(h|h)⇡(h); and that 2) Scenario 2 happens given that the
considered node is on the awaiting gap h 1, i.e., Pr(H + 1|H)⇡(h 1).
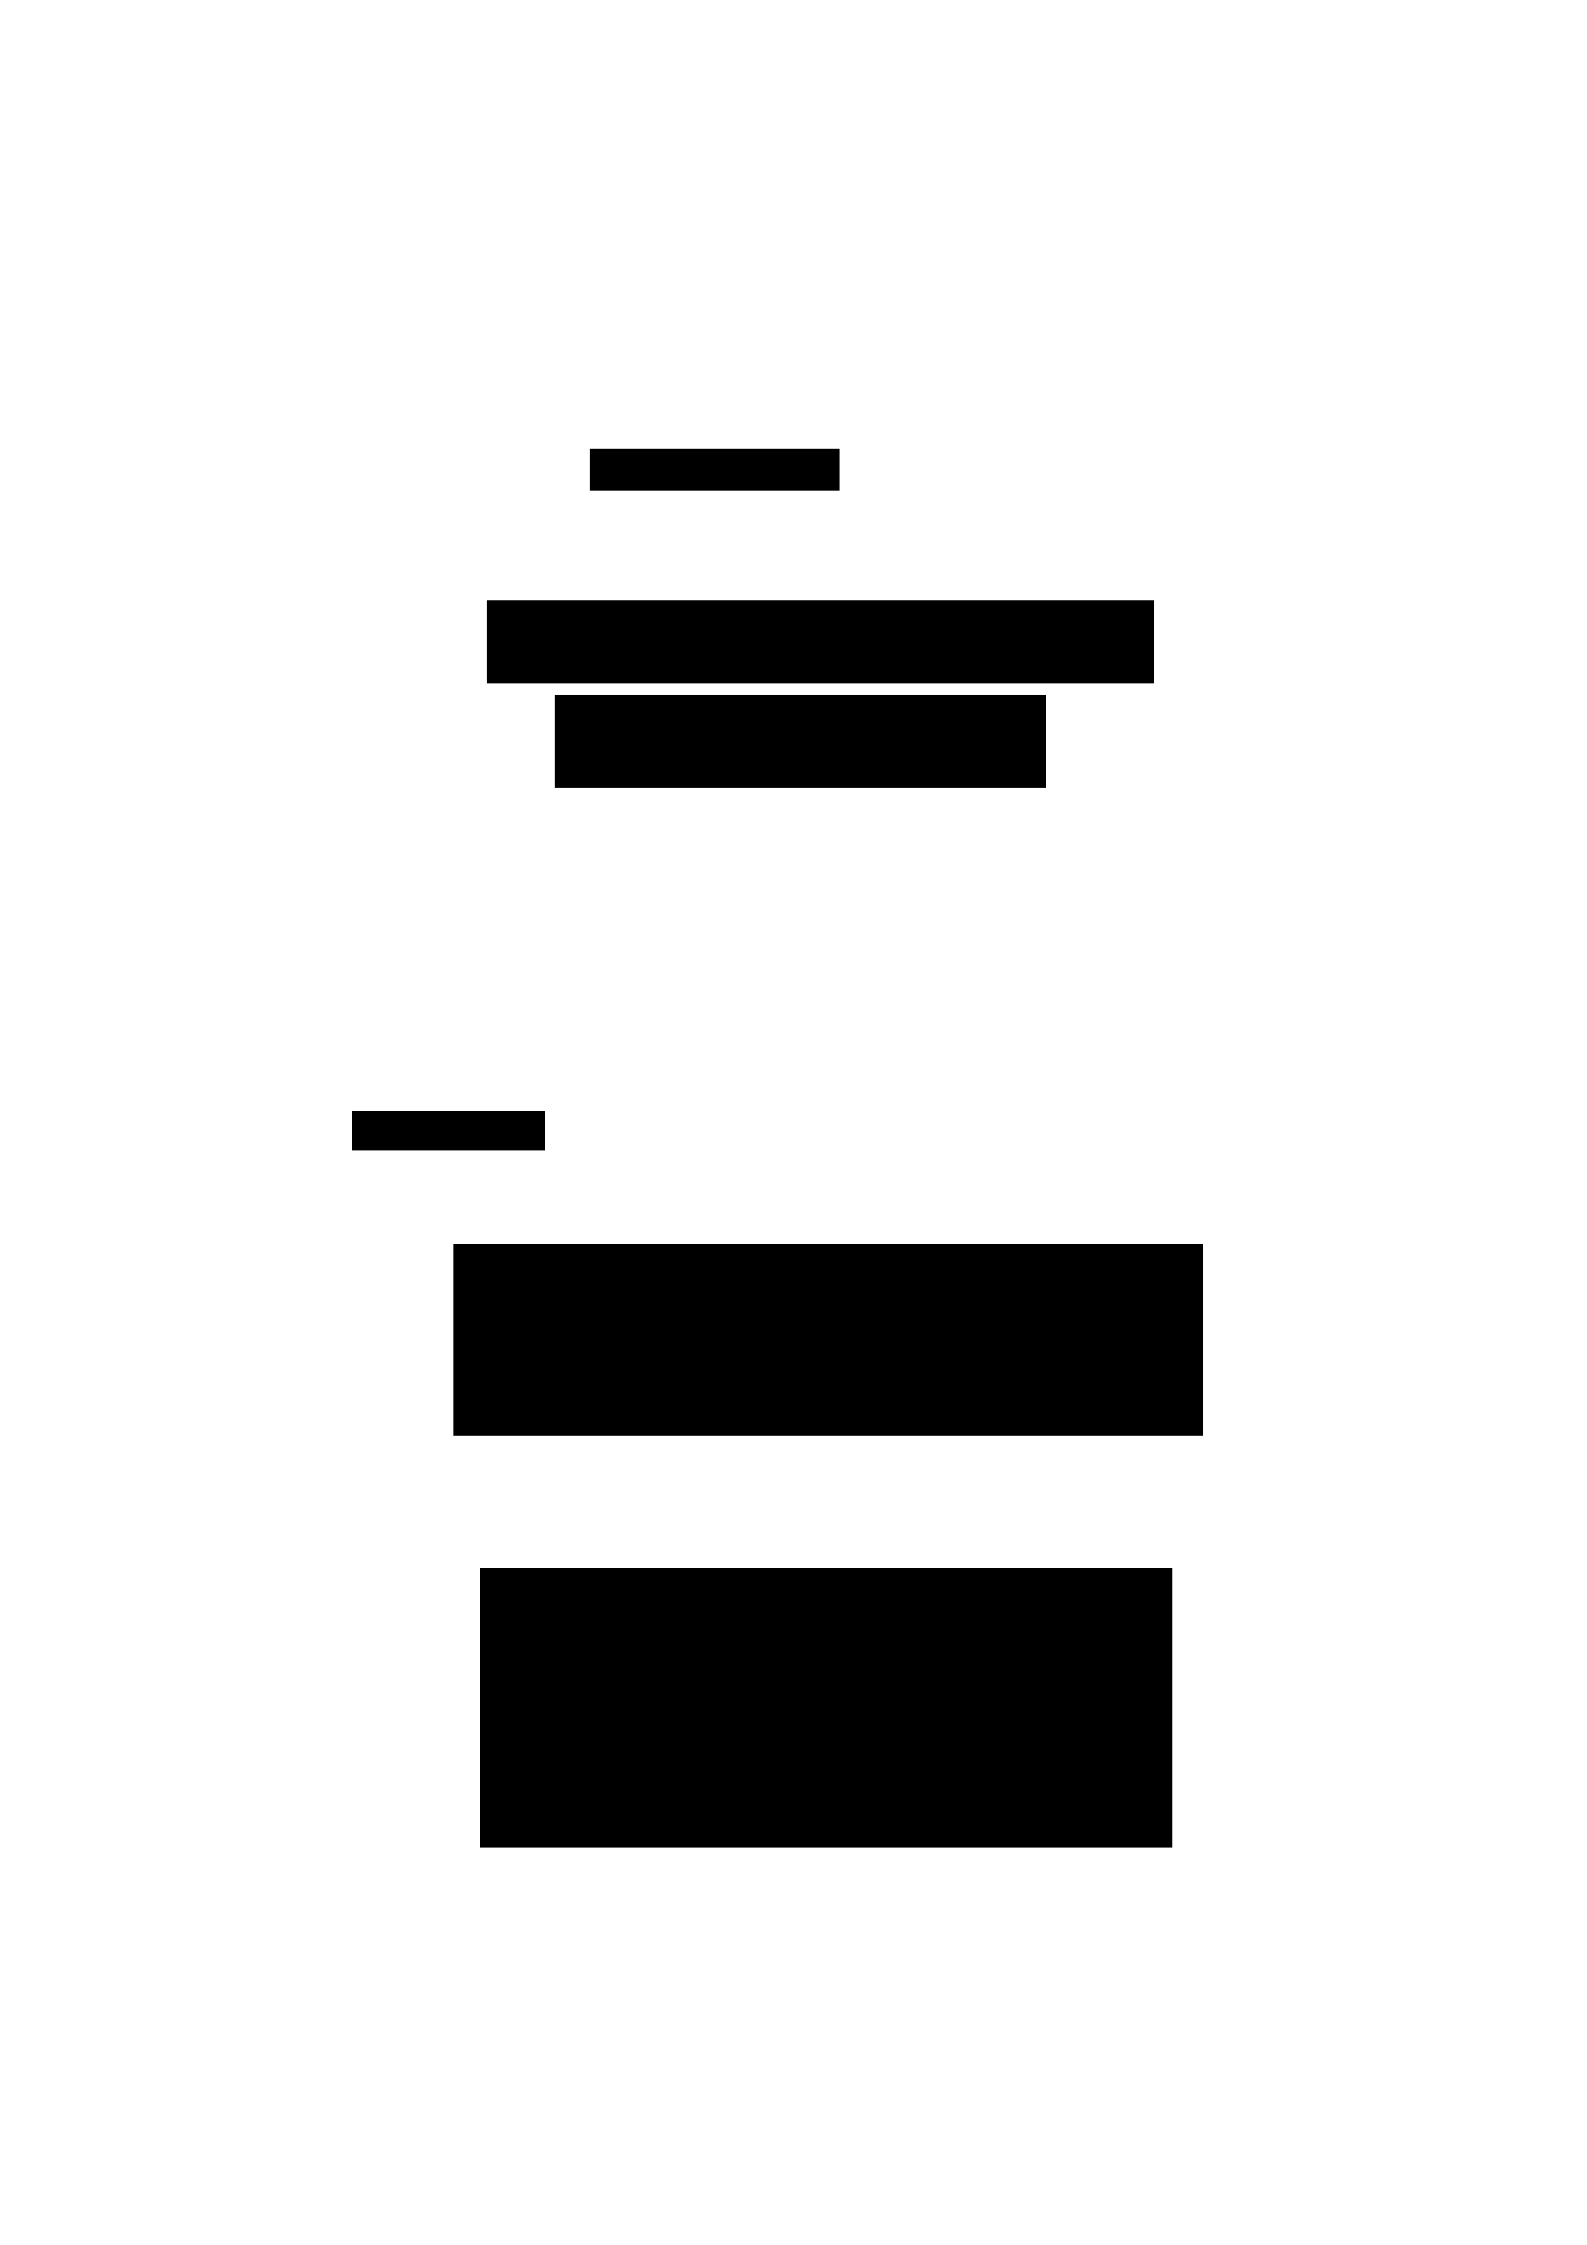
Note that in our proposed model, there exist the states with h > H in which the
probability of Scenario 2 is unchanged (i.e., Pr(H + 1|H)). The probability that the
miner of interest has an awaiting gap H can be interpreted as an accumulation of all
⇡(h) with h > H, i.e., lim
By rearranging (3.6), ⇡(h) can be rewritten as
(3.7a)
, h > H, (3.7b)
where (3.7a) can be converted ⇡(h) to multiple of ⇡(H), and (3.7b) is obtained by
substituting ⇡(H) into (3.5b).
In the case of h = 1:
As lim ) = 1, we can add up ⇡(h) in all the three cases, i.e., h = 1, 1 < h
H, and h > H, as given by
, (3.8)
wherein,
which is derived from (3.7a). Also from (3.8), the steady probability ⇡(1) can be
obtained as
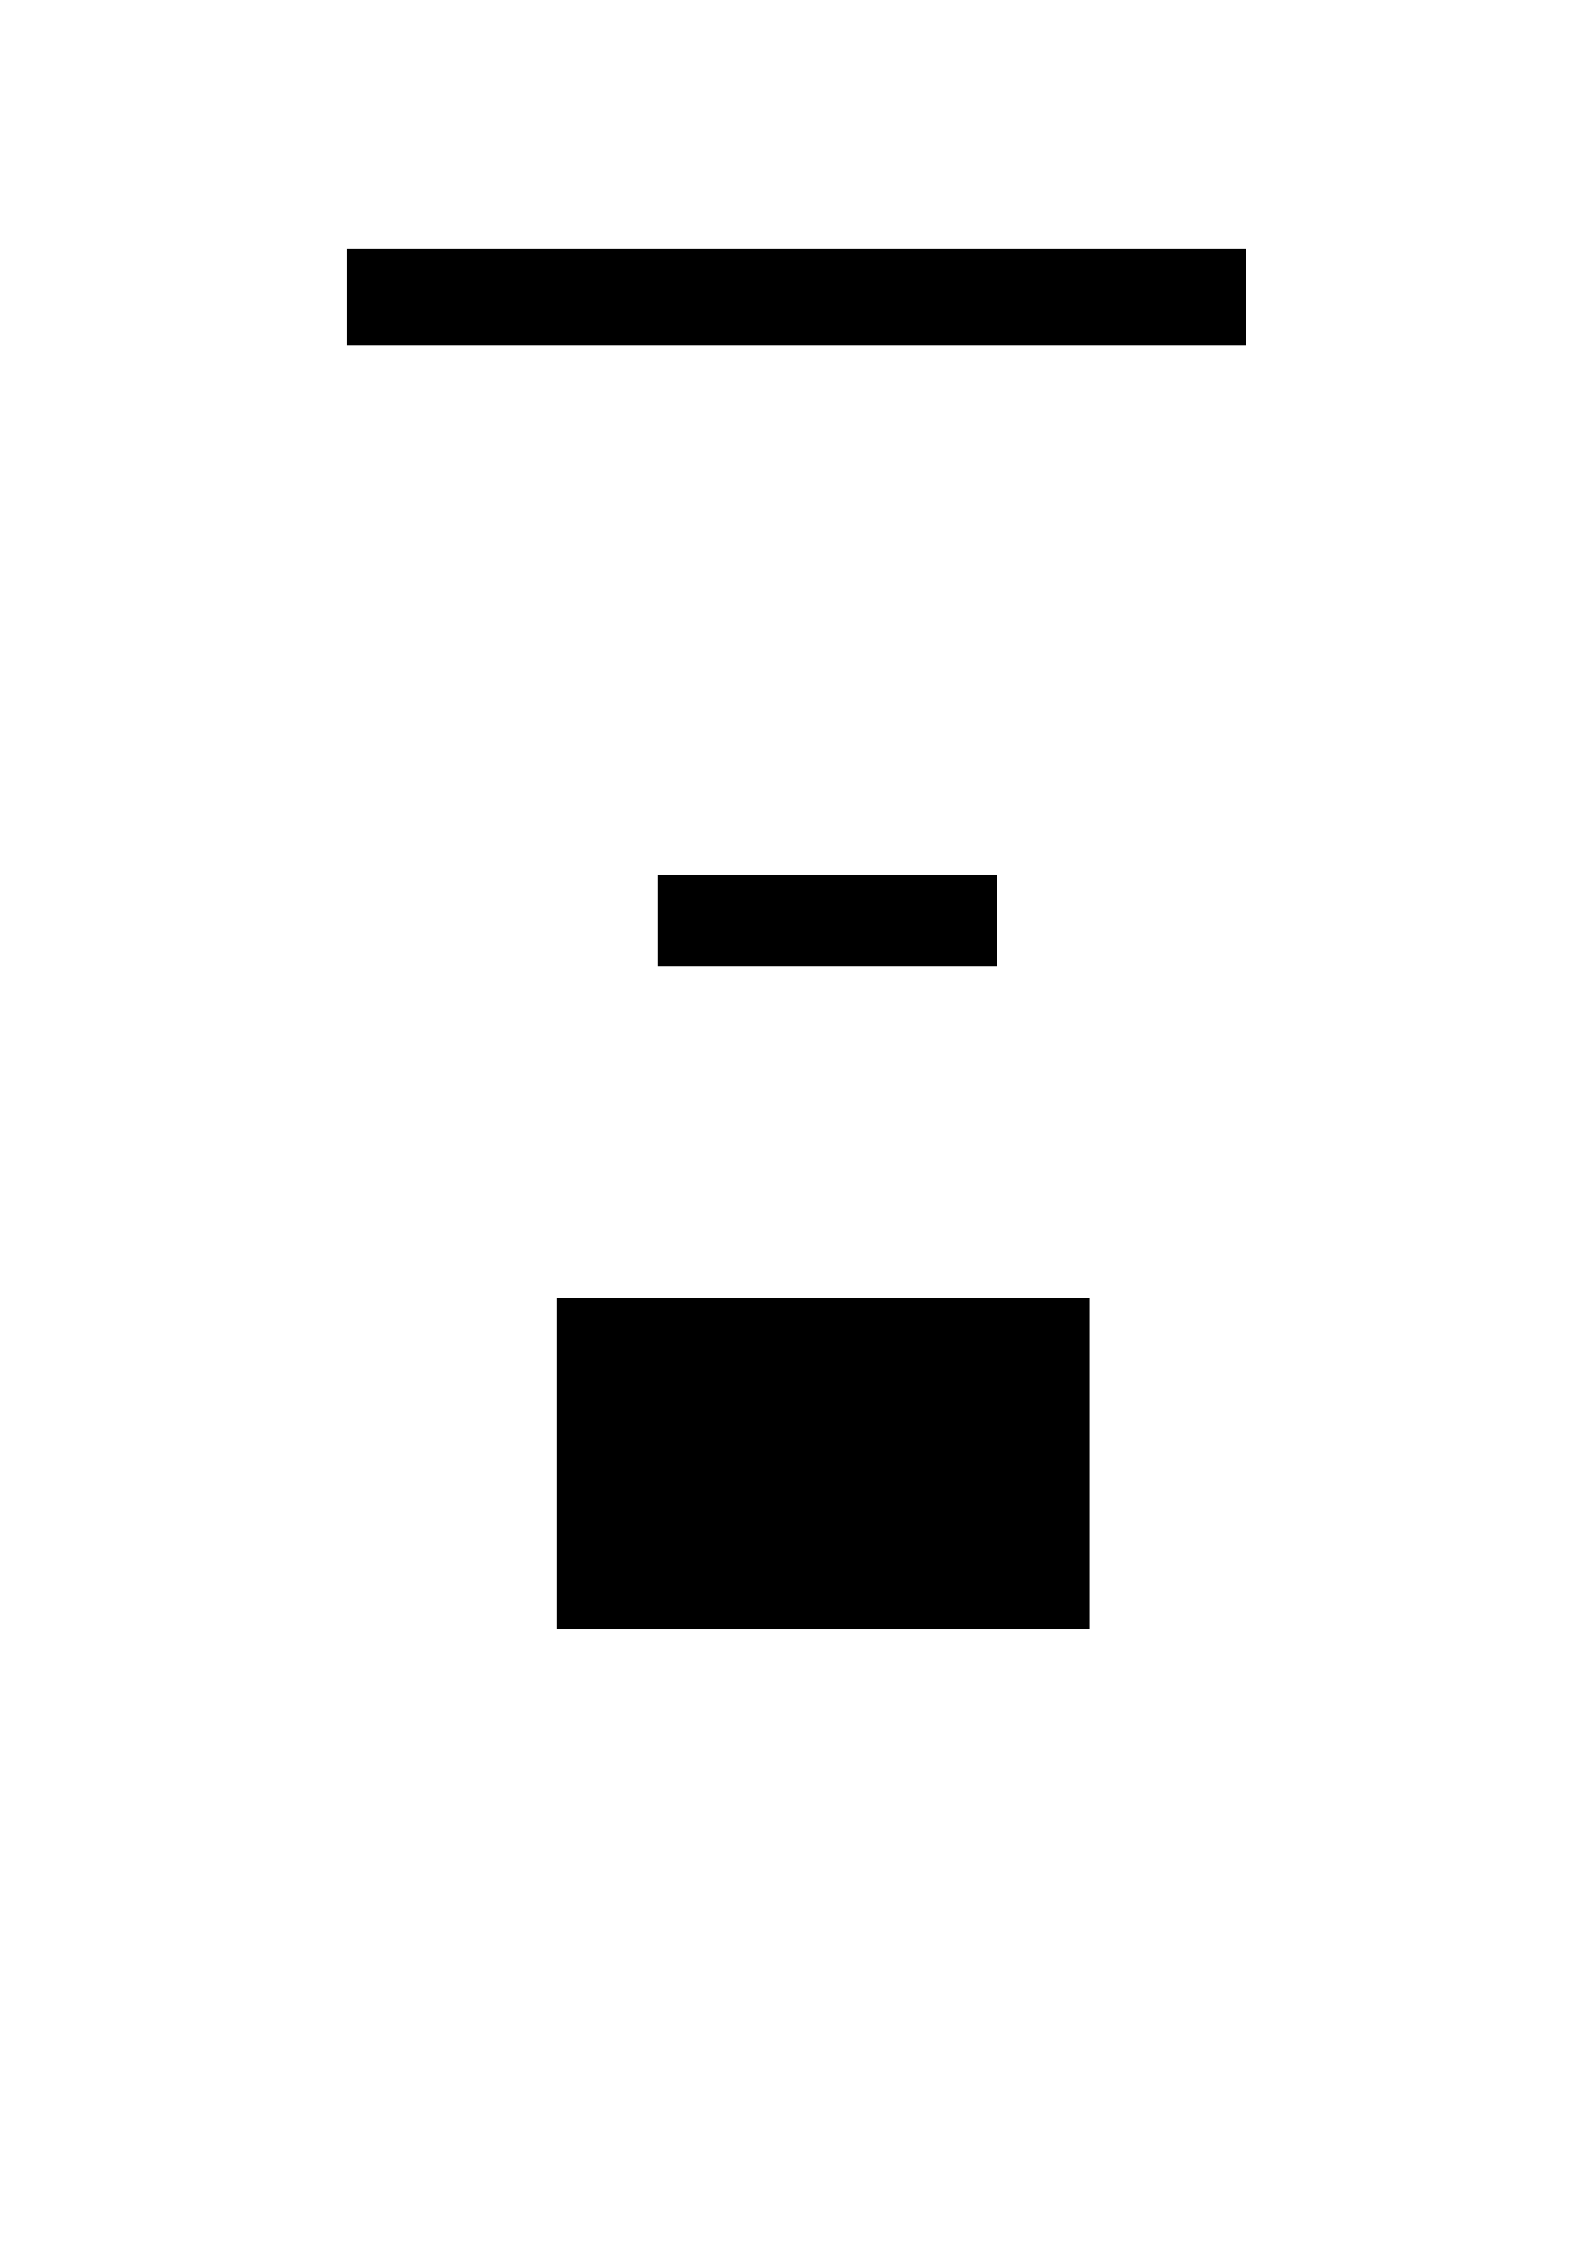
.(3.9)
Consequently, ⇡(h) can be derived with (3.5), (3.7) and (3.9) for any awaiting
gap h in the cases with 1 < h H, h > H, and h = 1.
3.3.3.4 Relation between the total per-slot mining probability R and the per-slot mining
probability of an individual node fi,h
Recall the mining probability of the entire network per slot, R, as given in (3.2). It
can be interpreted as the steady mining rate of the whole network. R is given by
,(3.10)
where ⇡i(x) denotes the steady-state probability of Node-i with the awaiting gap x,
and ⇡i(x) can be obtained by substituting (3.3) into (3.5) and (3.7).
By using (3.5) and (3.7), the total per-slot mining probability R can be expanded
to the following form:
(3.11a)
(3.11b)
.(3.11c)
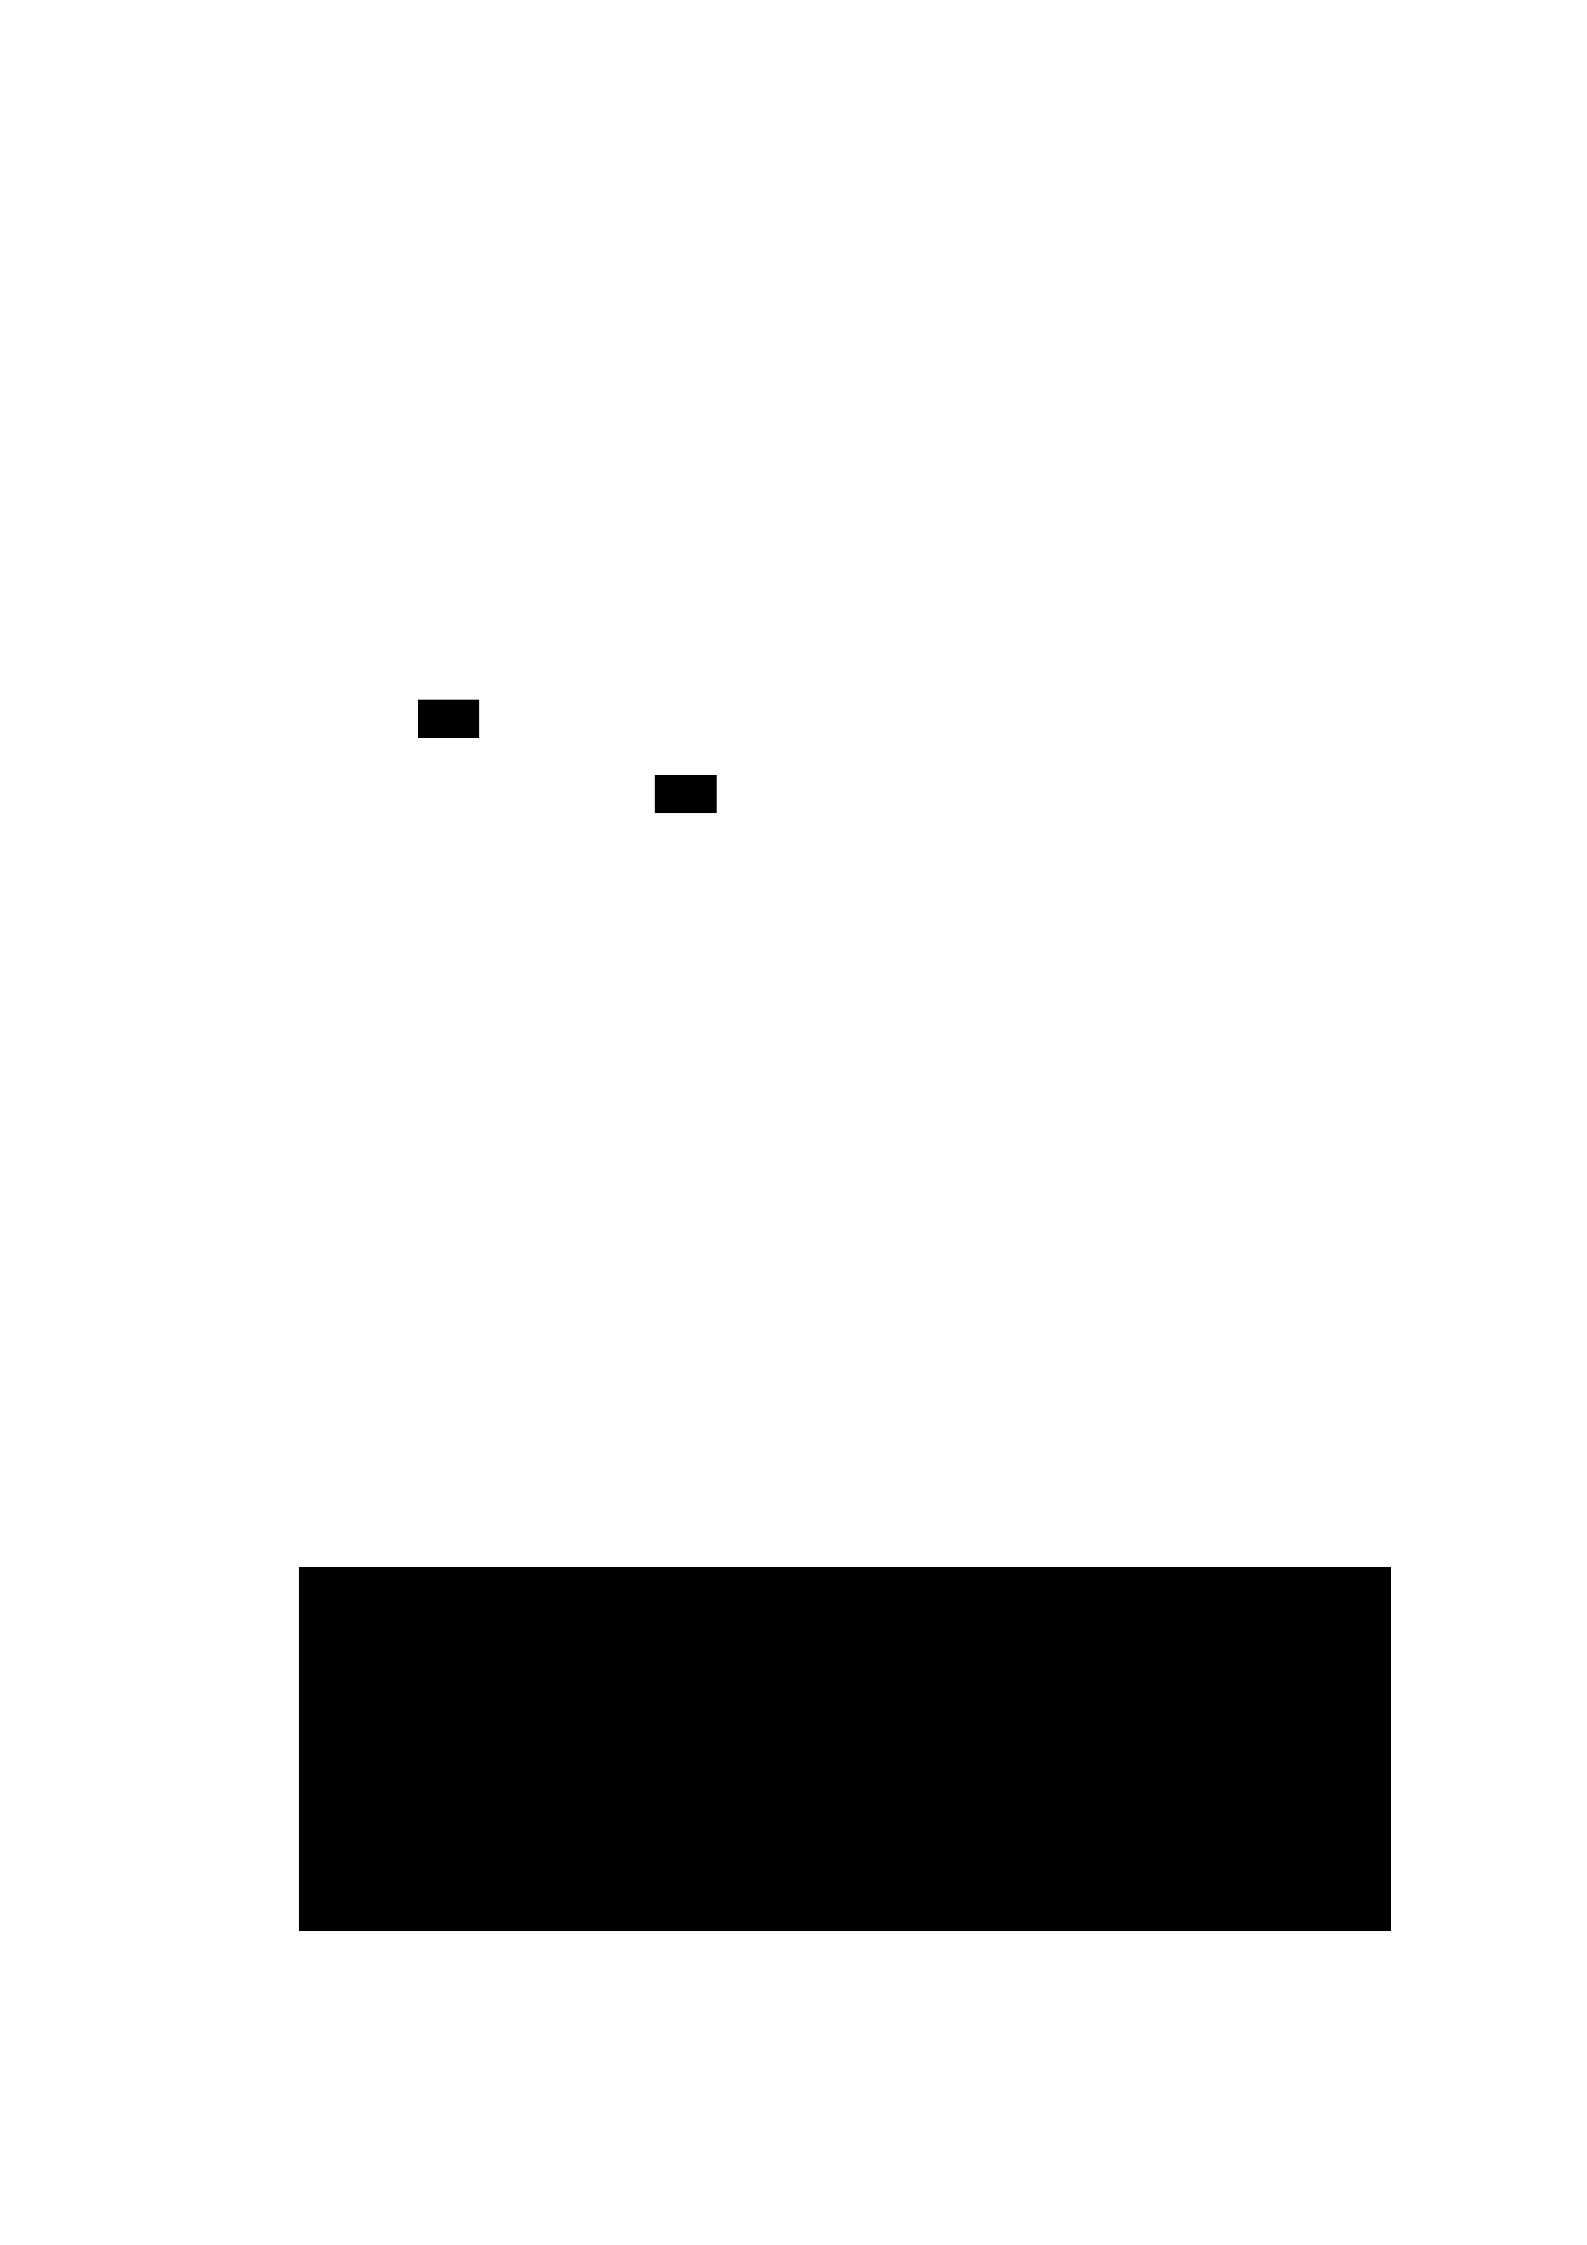
Therefore, R can be calculated with (3.11) by summing up the steady mining rate
for any awaiting gap h 2 [1,1] among all nodes i 2 [1,N]. Note that ⇡i(1) is the
corresponding steady-state for Node-i with awaiting gap-1; therefore, ⇡i(1) = ⇡(1).
⇡(1) is given in (3.9).
3.3.3.5 Generalization of Pi,win
Recall that is the probability of Node-i being elected as the block generator. We
derive Pi which generalizes in terms of fi,h for PoX schemes. By using such
generalized form, is abstracted into the configurable functions (Fairness function
and/or Degree function) of fi,h for any Node-i. As such, any miners can obtain the
probability being elected as the block generator by calculating fi,h. We define Ti as
the block generation rate of Node-i. It is measured by the average number of
awaiting gaps required for the miner to be elected again. For simplicity of notation,
we let fi,h = ↵(⌥!i) (h,H) = ↵i (h,H), where ↵i = ↵(⌥!i) and ↵is a network
parameter normalizing the probability. This operation is reasonable as the Degree
function (·) can equal to 1 and be ignored for some PoX schemes (e.g., PoW), while
we can realize ↵i is (non-)Fairness-oriented by observing whether (⌥!i) = !i holds.
Then, Ti can be given by
As a result, Pi can be given by
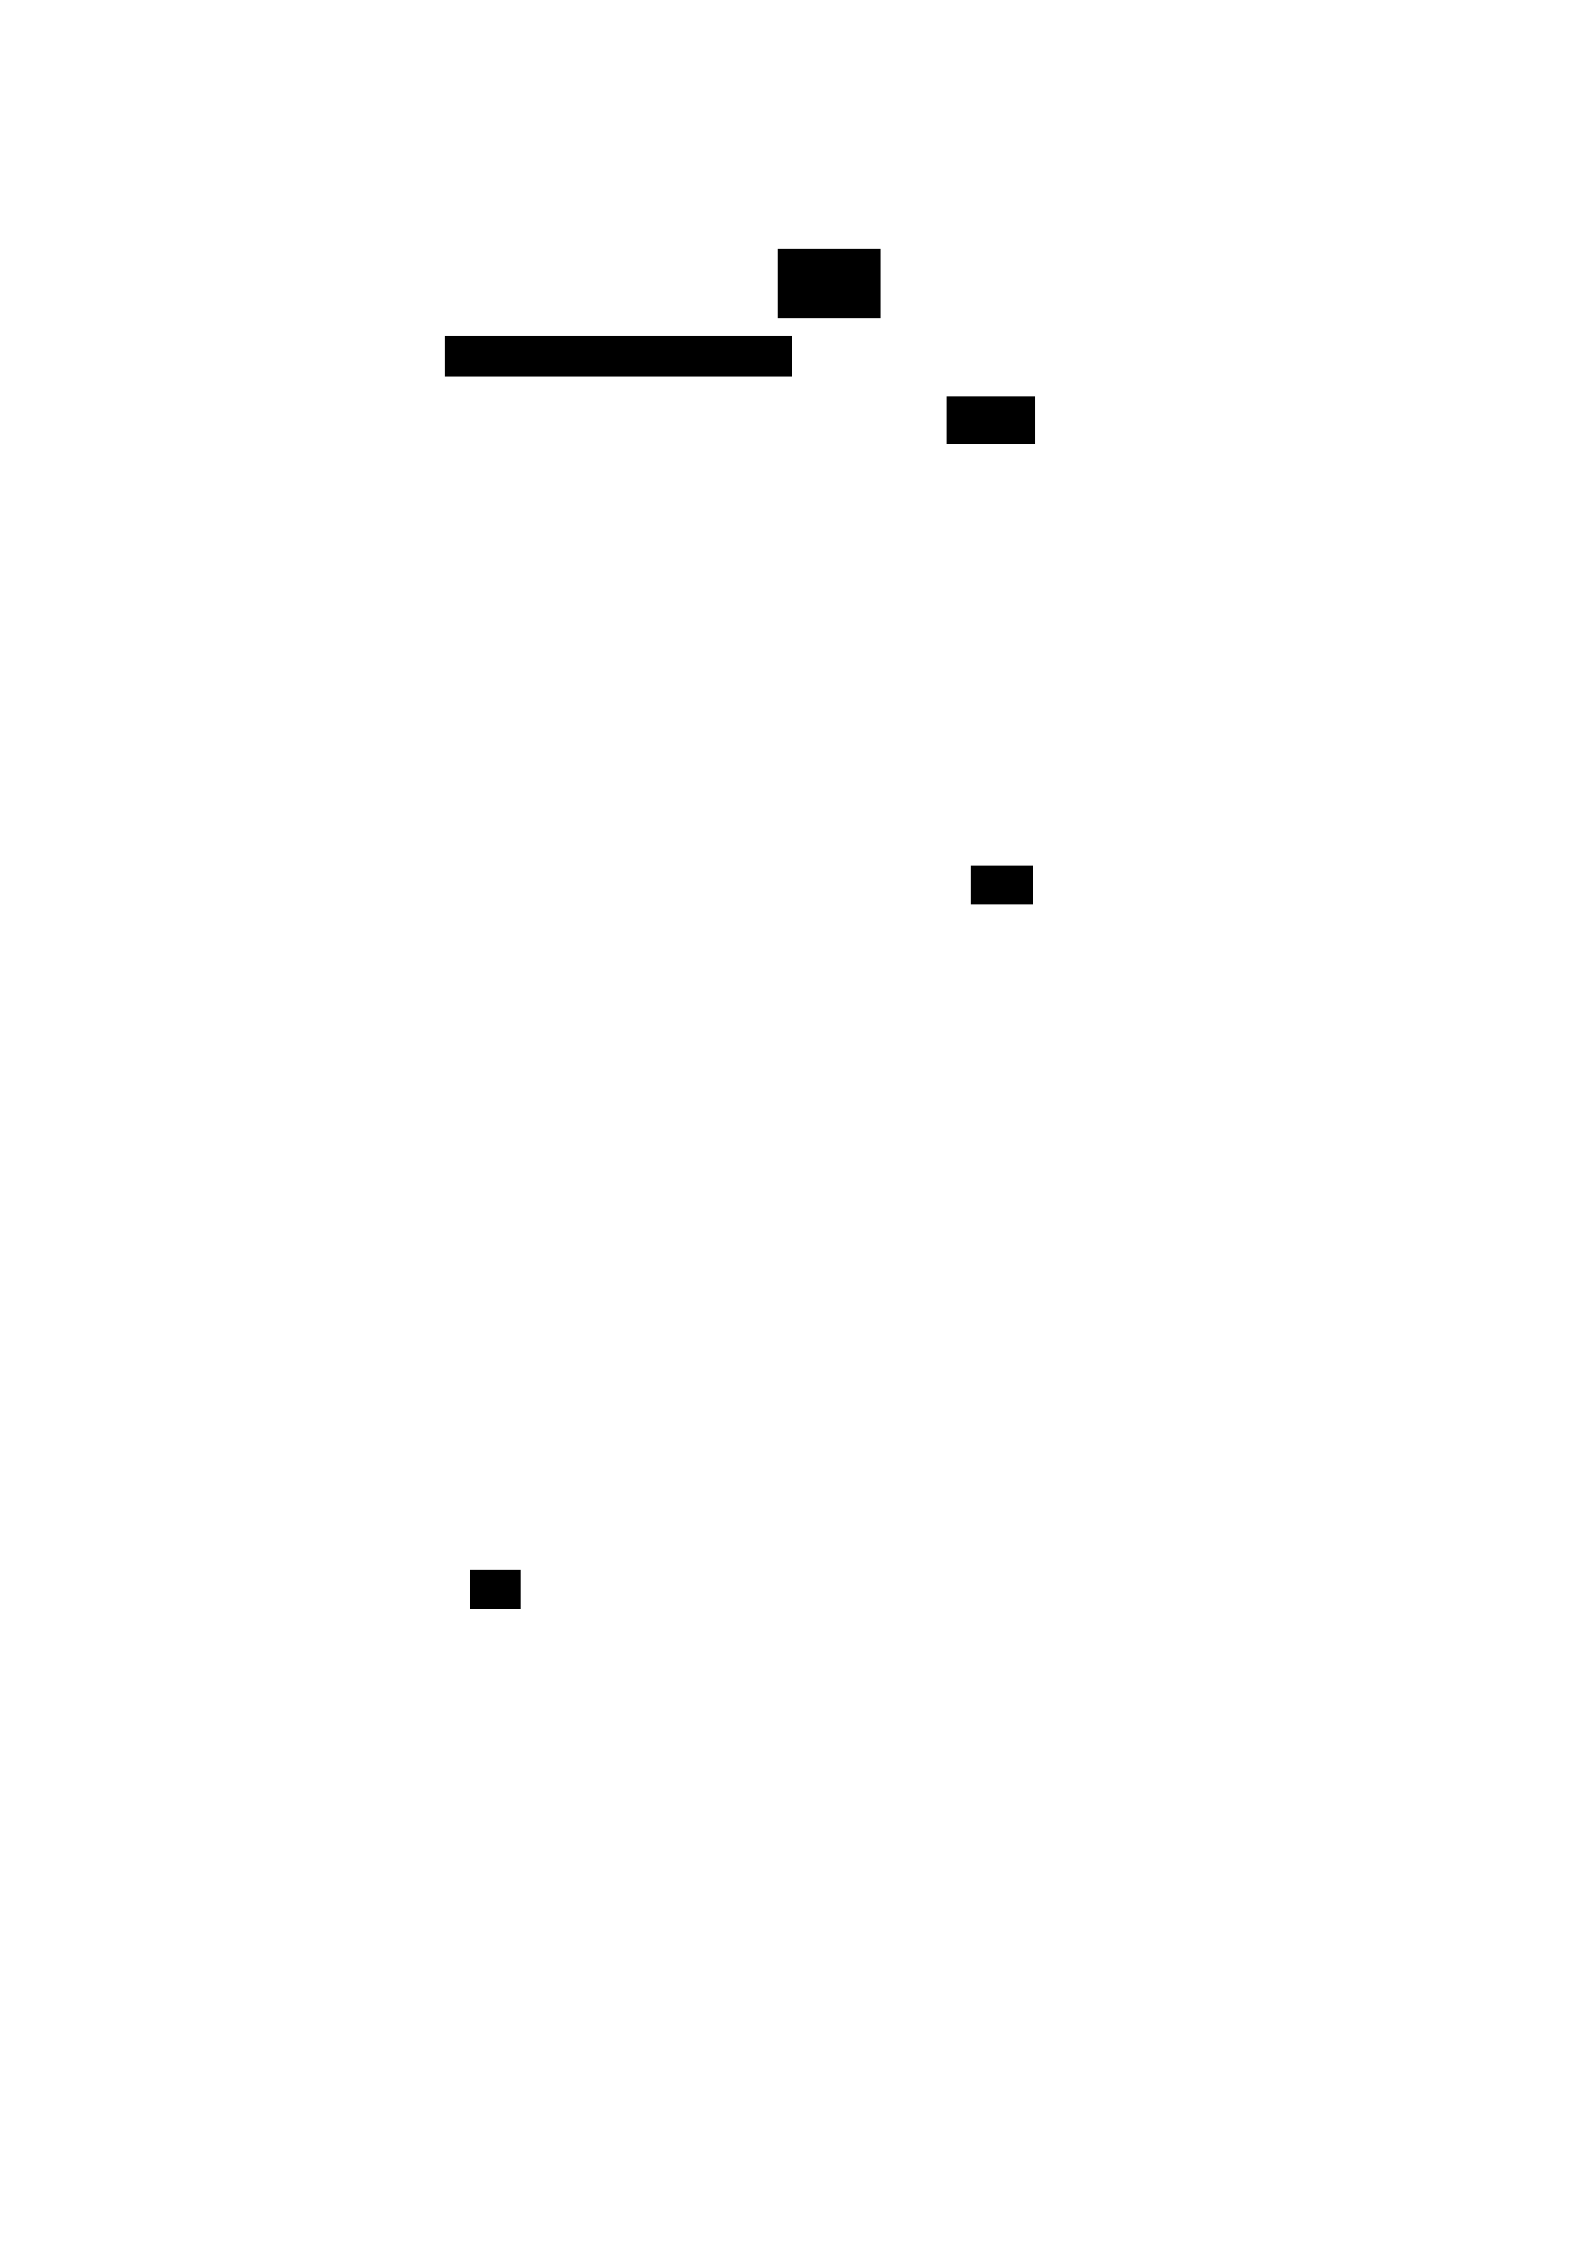
.(3.13)
Note that lim , and it indicates that no new block has been
finalized in the last k slots of the current round. is the probability that the
awaiting gap of Node-i starts at the height of x. Here, ⇡(x) is divided by ⇡(1) to
eliminate the e ect of the initial state (i.e., ↵h = 1).
As a result, Ti can be calculated based on (3.5) to (3.11), and the given {↵i, (·),⌥
(·)}. Since Ti is the generation rate of Node-i (i.e., how many awaiting gaps on
average a miner needs to wait until it can be elected as the block generator since
the last time it was elected), the generalized form of in (3.1), Pi = 1/Ti.
3.3.4 Proposed Evaluation Metrics
Based on the proposed analytical model and the resulting Pi in (3.12) and
(3.13), we propose three important metrics to evaluate PoX schemes, i.e., Resource
Sensitivity, System Convergence, and Resource Fairness. Currently popular PoX-
based consensus algorithms, as summarized in Table 3.1, can all be evaluated by
using the proposed metrics.
3.3.4.1 Resource sensitivity
The proposed Resource Sensitivity evaluates the correlation between the system
resource ratio , and the average probability of Node-i being the elected as the
block generator, Pi.
For any PoX scheme, we have Pi = f(z), where z = !i/P!i. The gradient g of any point
and the corresponding area E(g) bounded by f(z) can be defined as
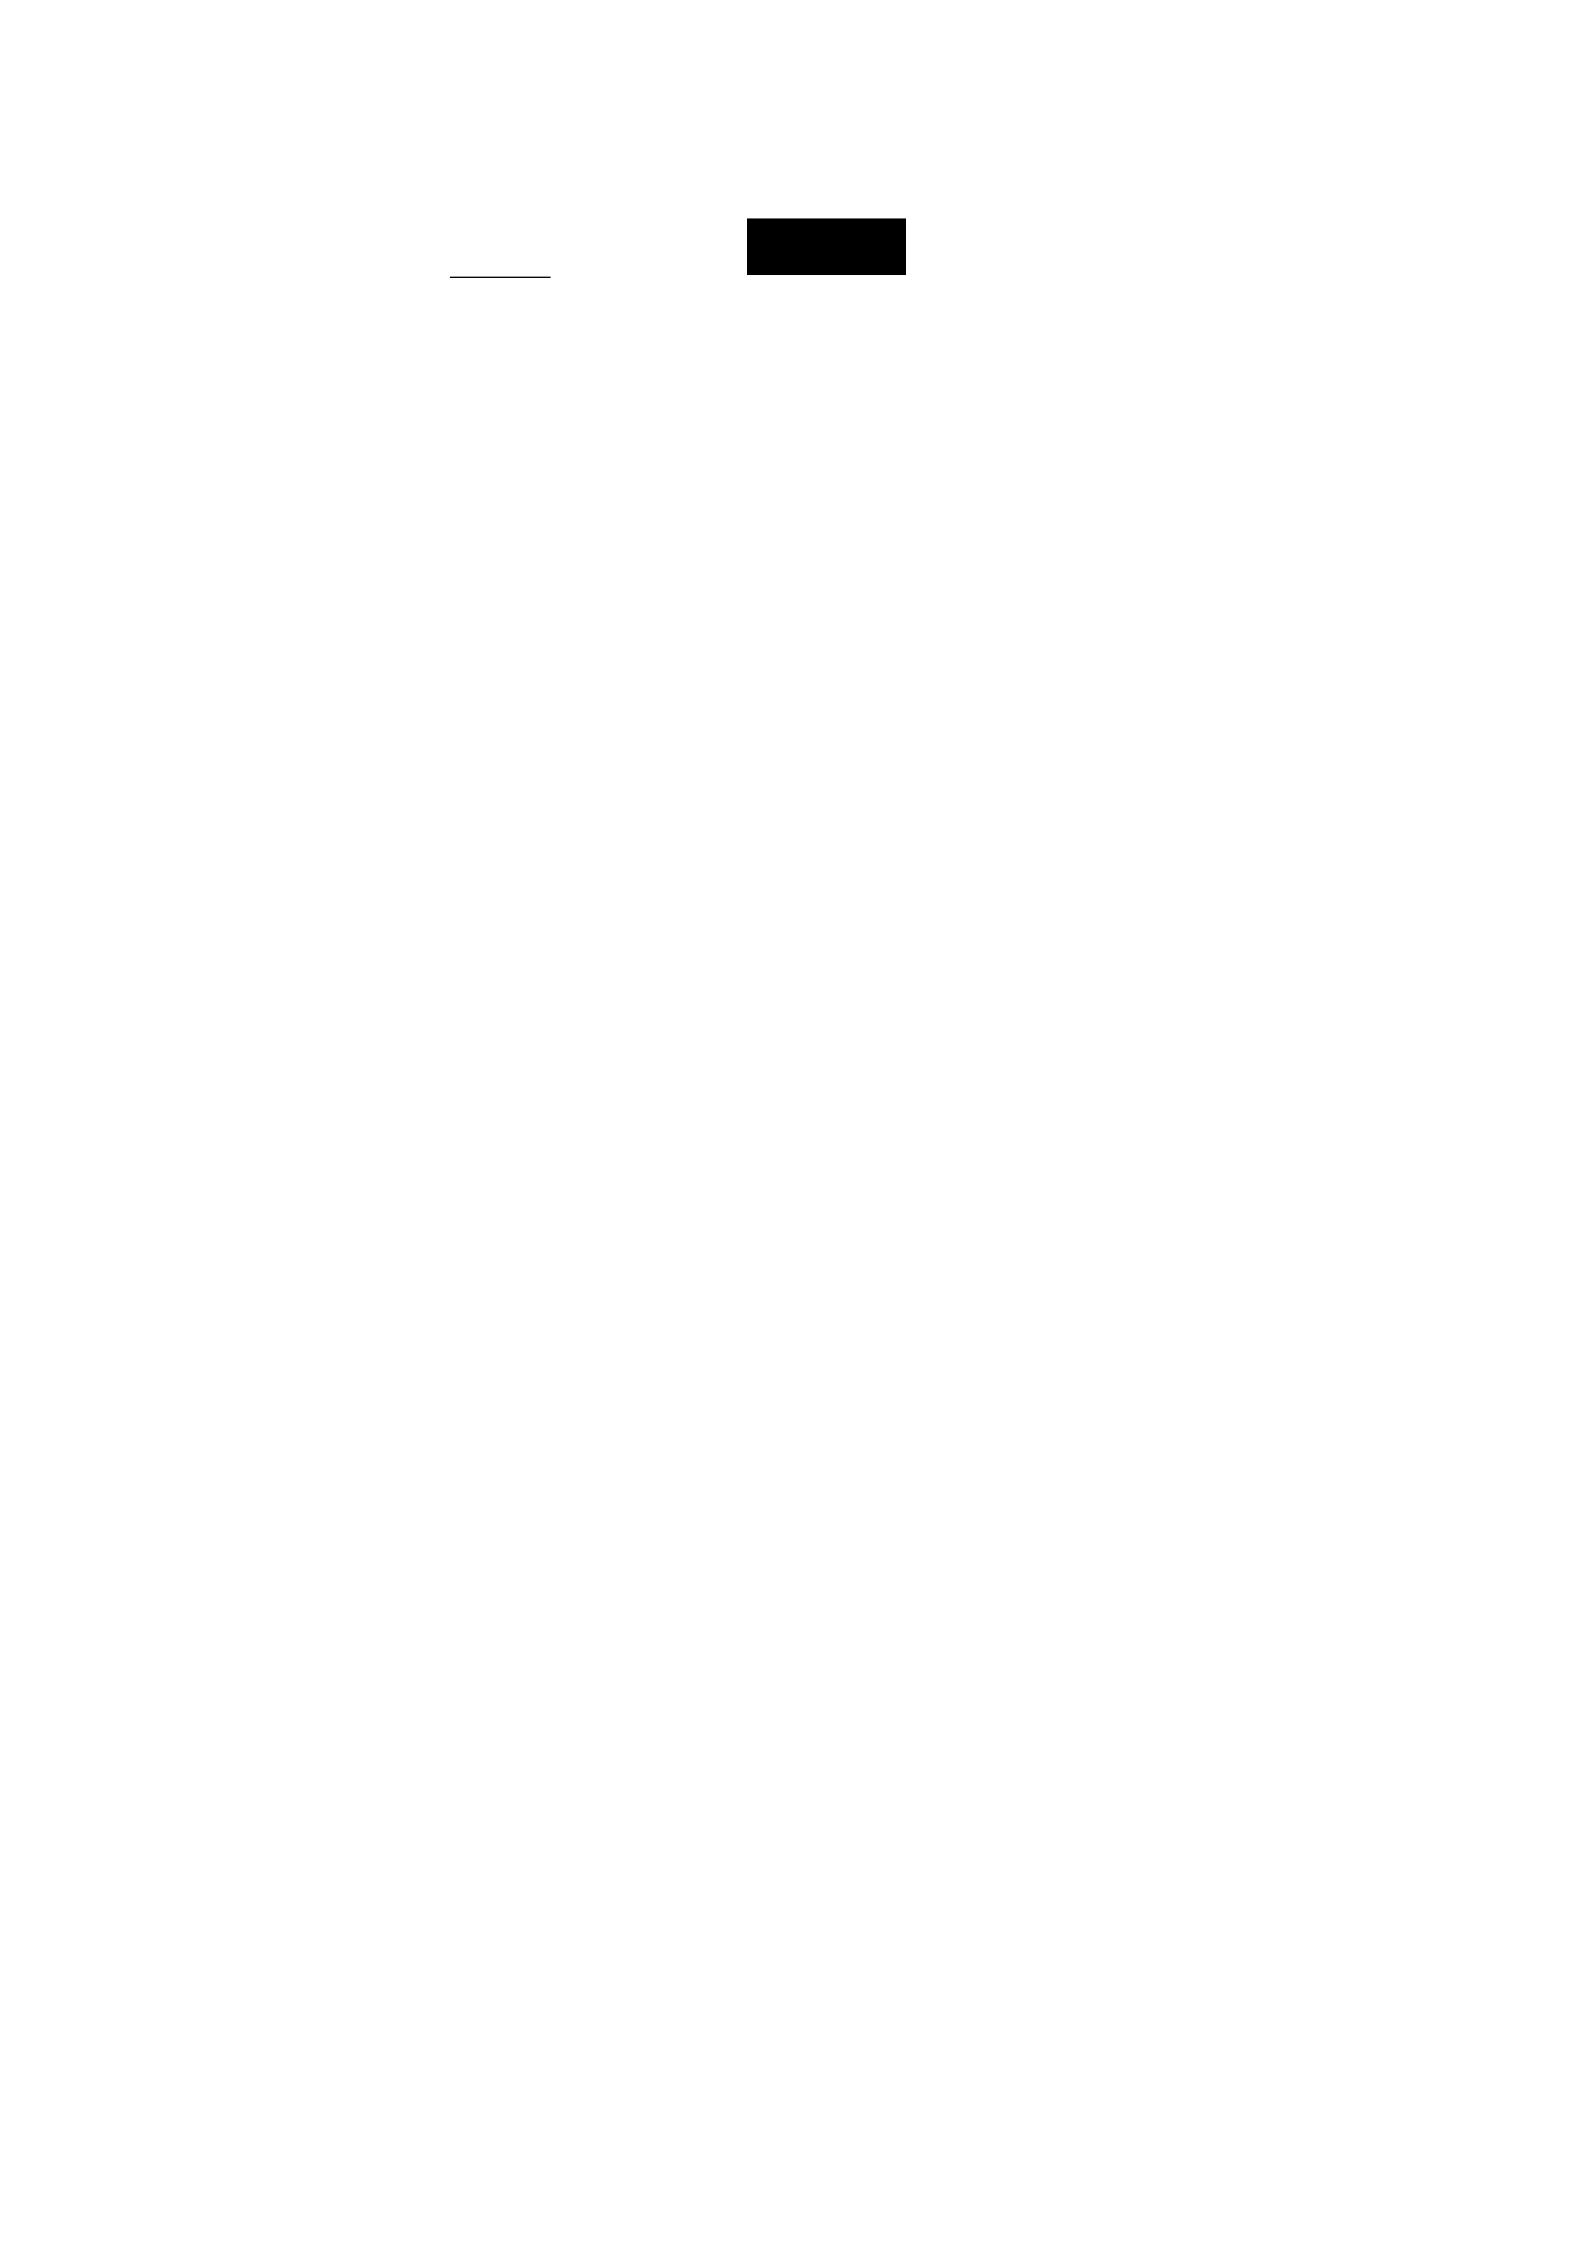
;
50%
E(z) =f(z)dz, 8g0.
0
We define Zero-Resource-Sensitivity if g = 1; Positive-Resource-Sensitivity if g > 1;
and Negative-Resource-Sensitivity if 0 g < 1. Zero-Resource-Sensitivity indicates the
mining probability Pi is proportional to the resource ratio in a 1:1 ratio. The 50% is
the resource ratio with which this node can launch the double-spending attack in a
Zero-Resource-sensitive context (1:1 ratio). A positive sensitivity leads to a larger
impact to Pi by the resource ratio, while a negative one leads to a smaller impact to
Pi. We also assert the relationship between Resource Sensitivity and the security of a
PoX scheme, i.e., the smaller E(z) is, the less Resource-sensitive it can achieve, thus
a more secure PoX scheme that has better performance on Resource
sensitivity.
By referring to the security model proposed in Bitcoin’s whitepaper [135],
security is specified to be the probability that an attacker could catch up with loyal
miners in some consecutive rounds. It is closely dependent on the probability that
an attacker potentially wins the puzzle race and generates a malicious block, as
captured by our proposed Pi. For example, Pi of traditional PoX schemes, e.g., PoW
and PoS, leads to a Zero-Resource-Sensitivity with fi,h = !↵i, (⌥!i) = !i, and
(·) = 1 (which is the identity line illustrated as the dark blue solid line in Fig. 3.6).
This consequently indicates that Pi increases along with the system resource in a
1:1 ratio, i.e., E(z) = 1 (i.e., an isosceles right triangle. Here “1” represents a
normalized area.), hence more Resource-sensitive and less secure than those with
E(z) < 1.
Z

Resource Sensitivity is complementary to the Bitcoin’s security model, in terms
of the correlation between the system resource ratio and the average probability of
any node being the block generator. Such definition of Resource Sensitivity based on
the resource distribution is reasonable, as influential attack strategies (e.g., selfish
mining and double-spending attack) depend on the resource distribution.
3.3.4.2 System convergence
The entire system takes rounds to reach the steady-state, while the steady-state is
satisfied if both (3.4) and (3.6) hold. Thus, System Convergence is evaluated by the
number of rounds needed to reach steady-state.
Here, the gap between the theoretical value of Tn (driven by (3.12)), and the
simulation one (obtained by the Monte Carlo-based simulation) is upper bounded
by a chosen tolerance (the steady-state is reached if the tolerance is satisfied). The
tolerance is chosen as 3% (see Fig. 3.4). This is because the PoX schemes⇠
considered in Table 3.1 have a margin of error of 3% (the y-axis of Fig. 3.4) while
the ratio of system resource owned by an arbitrary node fi,h ' 50% (the x-axis of Fig.
3.4). This satisfies the requirement of the fault tolerance (FT) of PoX-based
consensus algorithms, N > 2f+1 (N denotes the total number of participating
miners; f denotes the number of malicious miners).
A stable Pi can be useful for each individual miner to estimate the profits more
accurately, while an unstable consensus algorithm does not provide such benefits
in the absence of a steady-state. As a result, System Convergence can be an
important metric for rational users who tend to run more controllable PoX
schemes. They will be able to observe how much longer they need to wait until the
entire system becomes stable and predictable with high precision, so that a more
controllable cost-risk assessment can be conducted. Here, a more controllable cost-
risk assessment implies that, the faster a system becomes stable, the earlier users
obtain an accurate profit estimation, thus the users can be more thoroughly
prepared for all possible financial challenges. Moreover, we prove the model
realistic with System Convergence in a real-world system based on the simulation in
Section 3.5.2.1. The simulation reveals that our model can provide reasonably
accurate estimation of the number of rounds in the real world, especially in a well-
connected network with low latency.
3.3.4.3 Resource fairness
Resource Fairness [123] is defined as an indicator that indicates (in the case of E(z) <
1) whether there exists a threshold with respect to the resource ratio, to the right-⌘
hand-side of which g ! 0 based on the corresponding Fairness function
(·)⌥.
The asymptotically zero gradient (g ! 0) provides Resource Fairness against a
wealthy, resourceful node (i.e., Fairness-orientation). Here, a wealthy node has at
least 50% resource ratio, with which this node can launch the double-spending
attack in a Zero-Resource-sensitive context (1:1 ratio).
Resource Fairness is a specific requirement of a PoX-based consensus algorithm.
It prevents monopolization of wealthy miners, and incentivizes all miners to
participate in the mining process. The miners are expected to voluntarily apply
Fairness function because of the similar reason how miners remain decentralized
among centralized mining pools [55]2. Resource Fairness has an impact on Resource
Sensitivity by narrowing down the gap between the lowest and highest Pn with an
2 The loss caused by a double-spending attack launched by a centralized mining pool will make
the participated miners migrated out. Similarly, miners are expected to voluntarily prevent the
monopoly by restricting the wealthy when they are rich enough.
unchanged value of H. Resource Fairness also a ects ↵System Convergence by
introducing a many-to-one function with respect to h, e.g., a partition function ⇣(·)
in Section 3.5. As such, the Fairness function (·) = ⌥⇣(·) can significantly decrease
the number of rounds to reach the steady-state; see Fig. 3.7 for further details.
As of the time of writing, the proposed model is the first, among existing
studies, to determine the Fairness function and Degree function, thus considering
the e ects on the correlation between the system resource ratio and the individual↵
mining probability in di erent settings of these two functions, i.e., ↵Resource
Sensitivity and Resource Fairness. The model is also the first to be able to evaluate
the longterm stability by considering the convergence of Markov steady state, i.e.,
System Convergence, which provides a reliable cost-risk assessment.
3.4 Consideration on Network Setting
3.4.1 Sparse Blockchain Networks
Our model, using the similar assumption of [68], i.e., a well-connected network
with a small , and P!!iforked is also negligible with a constant P!. A small also
contributes to a negligible orphan rate, giving attackers no opportunities to exploit
any attack strategies on the orphans; refer to [8, Section IX-A].
Forking is purposely prevented when every miner mines on a new block with
the same block height, and the assumption of a zero propagation time t is subject to
the following reasons.
For the PoW schemes, the de facto probability that a forked block is mined and
inserted is also (apart from Pi,win) directly proportional to,
1. the ratio between t and T, i.e., ;
2. the ratio of computation resource forked working on a block that would be
ωforked an orphan one, to the total
resource ω; i.e., (the chain quality proposed
in [ 68 , 208 ]).
The upper bound of time consumption to finalize a new block, , becomes
unpredictable as 1. This means the synchronization becomes looser so that
the performance and security of PoW deteriorates. Thus, as we consider
1. approaches zero (the throughput is not considered here);
2. rational miners are incentivized to wait until the finalized block of the
current round is consistently accepted across the whole network before
mining the next block, 3
P!
iforked
!can be negligible in our model.
For the PoS and other PoX schemes without the computation resource,
punishment mechanisms (such as the Slashers in Ethereum 2.0 [37] or the
Verifiable Delay Function (VDF) [32]) are applied to miners who mine multiple
blocks on the same height to prevent Nothing-at-stake and long-range attacks. In
the case that approaches zero, P!!iforked is also negligible.
3.4.2 Large-scale Blockchain Networks
The proposed model is designed for a large-scale Blockchain network with N
potential miners competing for the role of block generator. We define a finite scale
3 In this paper, we consider that the attackers do not behave maliciously at the time when the honor
miners are waiting for the consistency while T becomes large. When , the
partially synchronous network can be thought to be completely synchronous, in turn, satisfies the
proposed small-slotted mechanism.
of an upper bound of the awaiting gap h, i.e., N > H. This is reasonable and usually
implemented in PoS-Velocity [3]. Similar designs have also been implemented to
prevent coins hoarding. This is a critical issue of traditional coinage-based PoS.
Attackers hoard the coins on multiple accounts with infinite H to boost the success
probability [180]. On the other hand, it is practical to implement an upper bound so
that the physical operation can be more a ordable due to the worst-case searching↵
complexity of O(NH) for traversing the awaiting gaps of all N miners in the entire
network.
3.5 Simulation and Evaluation
In this section, we present the simulation and evaluation, based on Resource
Sensitivity, System Convergence, Resource Fairness of our proposed analytical model
of the considered PoX schemes listed in Table 3.1.
3.5.1 Framework
The simulation setting is presented in the following.
Hardware setting: A 2017 iMac with 10.13.3 macOS High Sierra, a processor of
2.3GHz Intel Core i5 and 16 GB 2133 MHz DDR4 memory are used.
Software setting: We carry out a Monte Carlo simulation using Python-2.7 to
conduct the mining process given N, H, and ↵= 2H P1 !i , to obtain the simulated value
of Pi for Node-i. The calculated value of Pi for Node-i based on (13) is obtained by
using Matlab-2017. Here, the values of N, H, and ↵are set based on the hardware
performance.
Samples setting: The parameter fi,h for each of the PoX-based consensus
algorithms is described in Table 3.1, given the distribution of {↵i}. Here, a coinage-
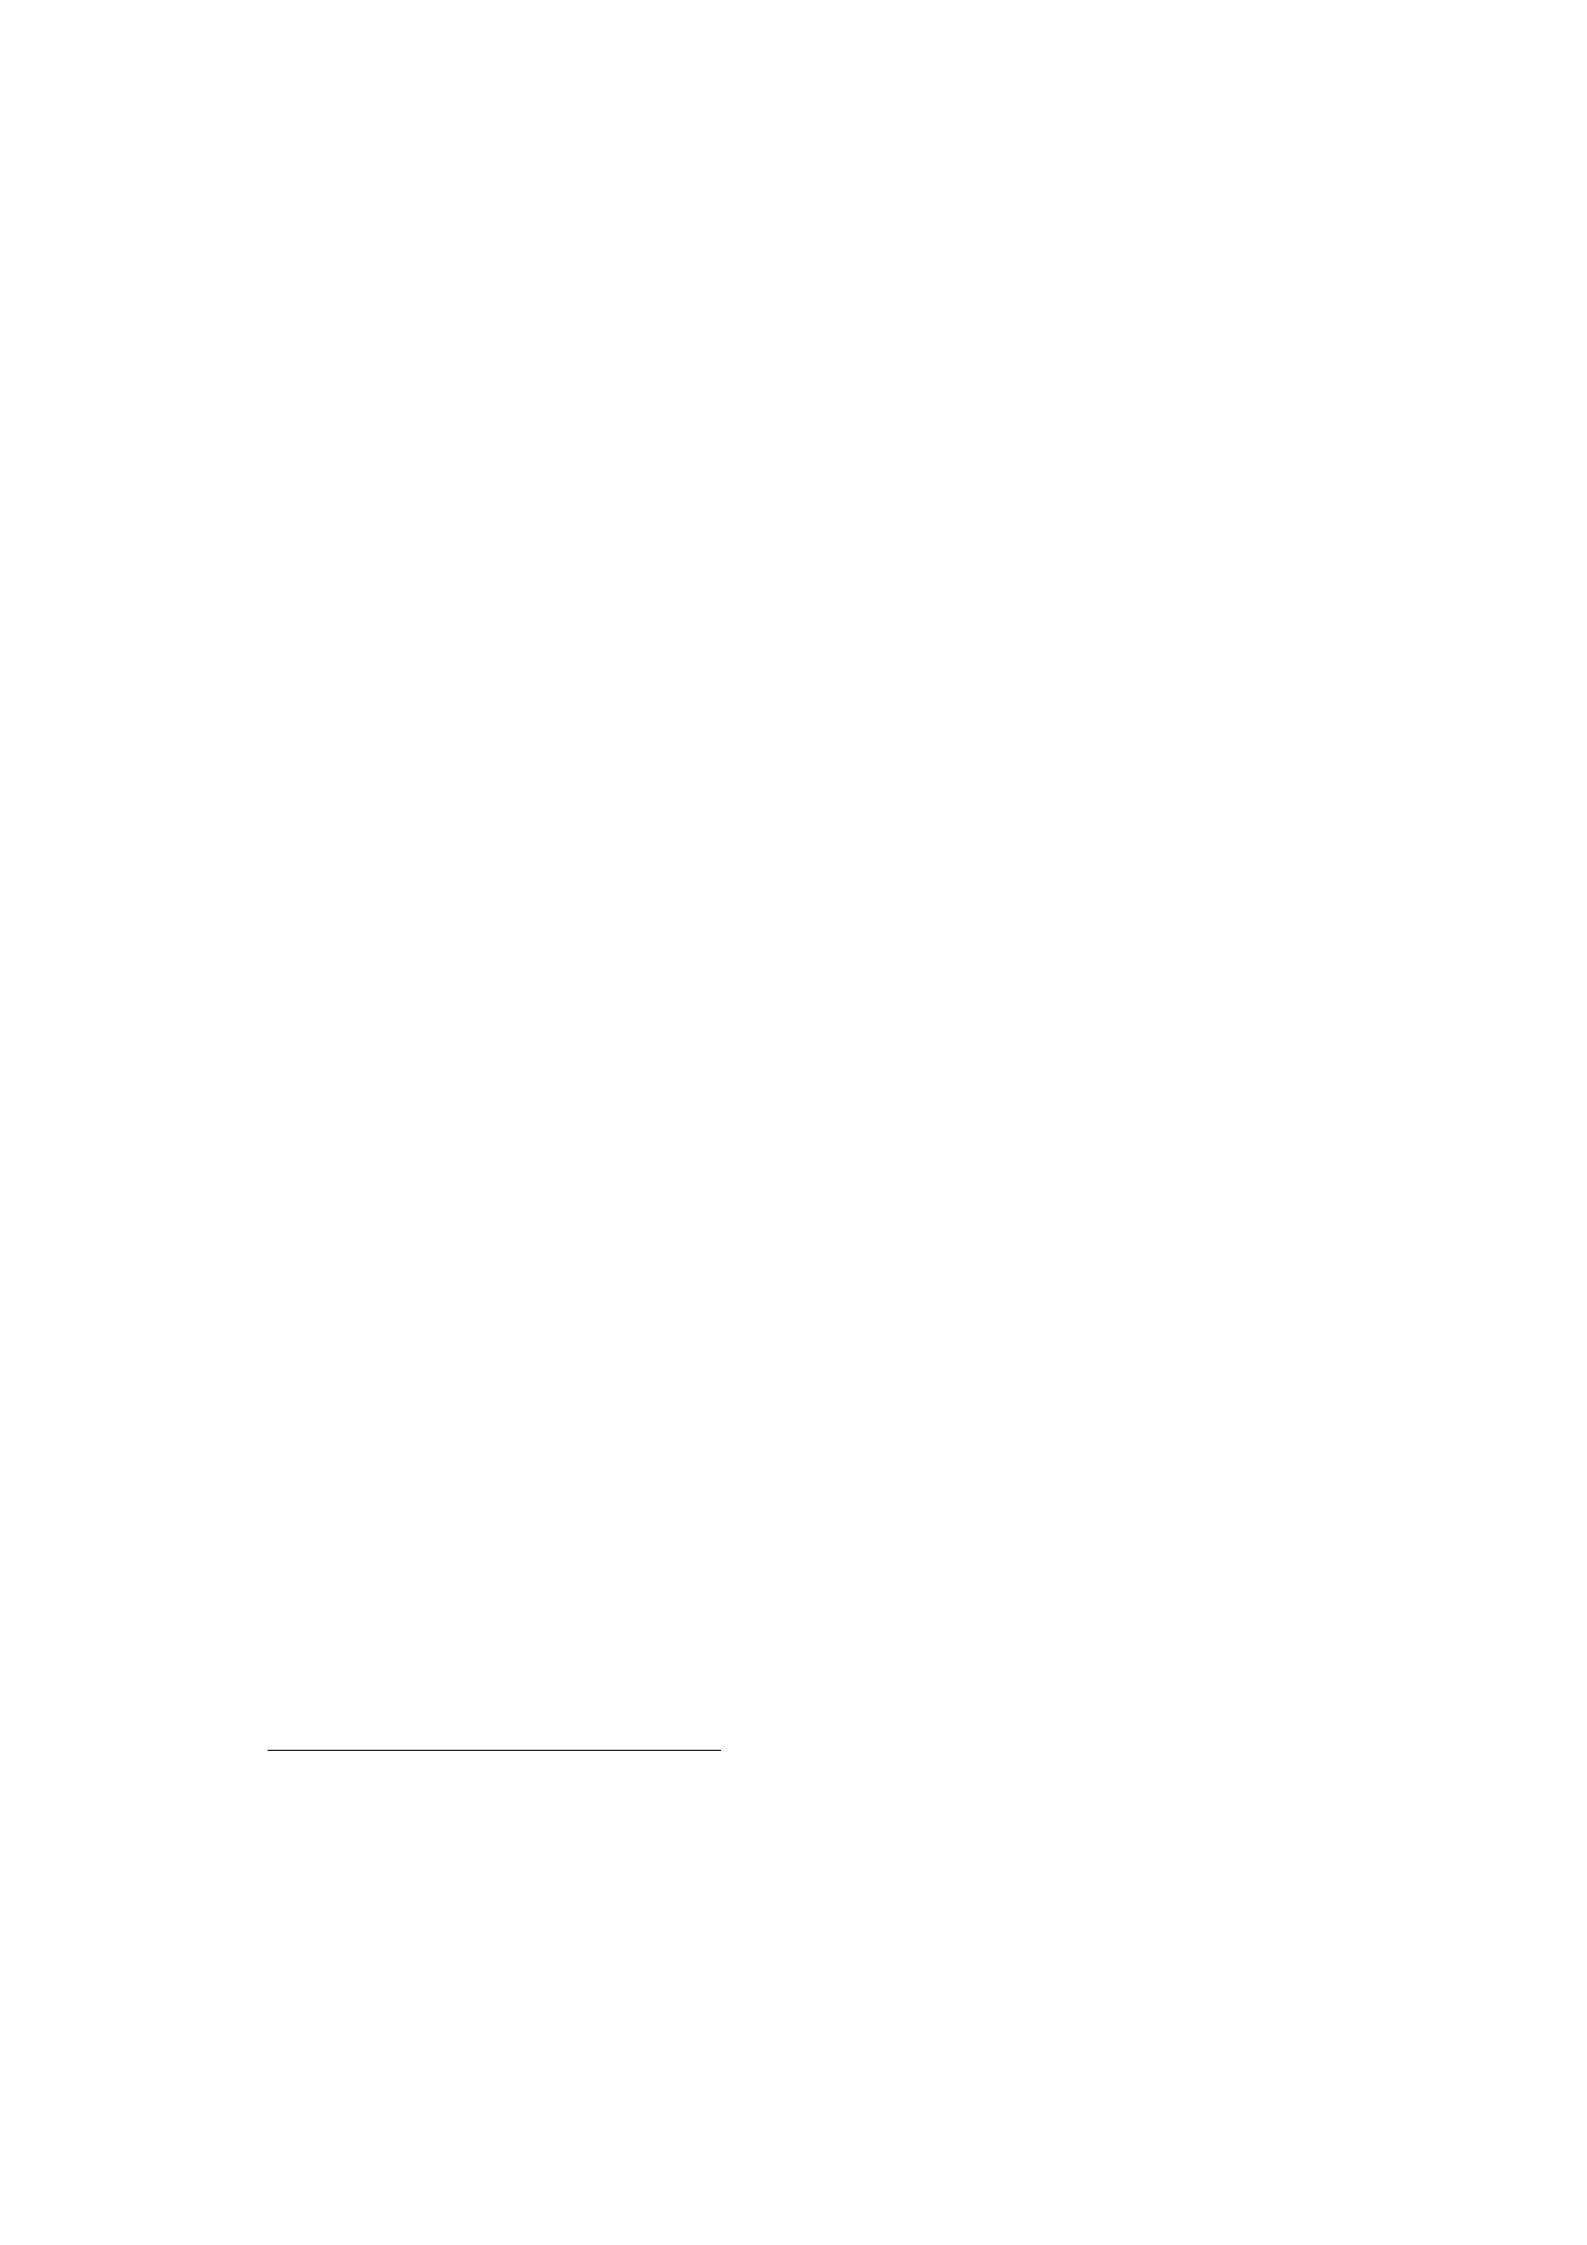
based PoS with a strong restriction implies that the awaiting gap of an elected
generator starts from 0 (zero probability of being elected consecutively), while a
weak restriction starts from non-zero.
In this simulation, we use a normal distribution and a Pareto distribution for
the resource distribution among the miners. The reason is that these two
distributions feature normal-distributed wealth inequality (non-monopoly) and
80/20-rule-based wealth inequality (monopoly), respectively, covering most well-
known PoX schemes listed in Table 3.1. Any PoX scheme where miners need to put
great e orts, e.g., computational power and token values, in winning the race↵
results in a Pareto Distribution [181], while it is normal-distributed if the system
resource becomes less costly to the system resource among the miners, e.g., PoP. As
such, we assume that {↵i} of PoW, PoS, and PoA follow the Pareto distribution; PoP
follows the normal distribution. To be specific, we implement Proof-of-
Collaboration (PoC) [193]4, for the simulation of both strongly restricted and
weakly restricted coinage-based PoS consensuses.
We implement a typical type of Fairness-oriented PoS-Velocity with a Pareto
distribution in the simulation, where the Fairness function (⌥!i) = ⇣(!i) and the
Degree function (·) = µ(min{·}) are used5. Here, we use the definition in [180] of
PoS-Velocity. That is the linear (·) is substituted by other forms of Degree functions,
e.g., a non-linear function µ(·); the Fairness function is set to the form of a partition
function, e.g., ⇣(·).
4This consensus defines two new parameters, CC and PPoC. The winner of each round of
generating the new block will earn CC, while PPoC is defined as the time since the last CC changes.

On the other hand, PPoC 2 [L,R], where L can be constant during a long-term period and R = 3L. Also,
PPoC of the winner is set to 0 for the next single round (so that PPoC starts from 0). Therefore, the PoC
consensus can be regarded as a variant of strongly restricted coinage-based
PoS and fn,h = ↵n min{h1,H}, where 1 h H, h = PPoC, h = 1 = L, h1 = 0, H = R. In
addition, the PoC consensus can be with a weak restriction if we set PPoC to L instead of 0.
5An example is that, ⇣(·) can be a partition function where the lower and upper bound are pre-
defined to avoid the monopoly and starvation; µ(·) can be a non-linear function where the gradient g
remains flat from the beginning up to a threshold, followed by a sharp increase after the threshold
(so that the poor miners can be more likely to win).
3.5.2 Simulation Result
First, the scope of our proposed model in terms of the margin of error is
discussed. After that, the proposed metrics, Resource Sensitivity, System
Convergence, and Resource Fairness are simulated among the (non-)Fairness-
oriented PoX schemes listed in Table 3.1. Finally, we deliver the implicit findings for
miners to evaluate PoX schemes in di erent scenarios based on the proposed↵
model.
3.5.2.1 Accuracy of the proposed model - margin of error
To investigate the accuracy of the estimation derived from our model and possible
factors impacting on such accuracy, we consider two types of margin of errors in
this
section.
•Standard Error (S). It is also known as the standard error of the estimate,
representing the average distance between the estimated values and observed
values. Smaller S implies a better fitted model.
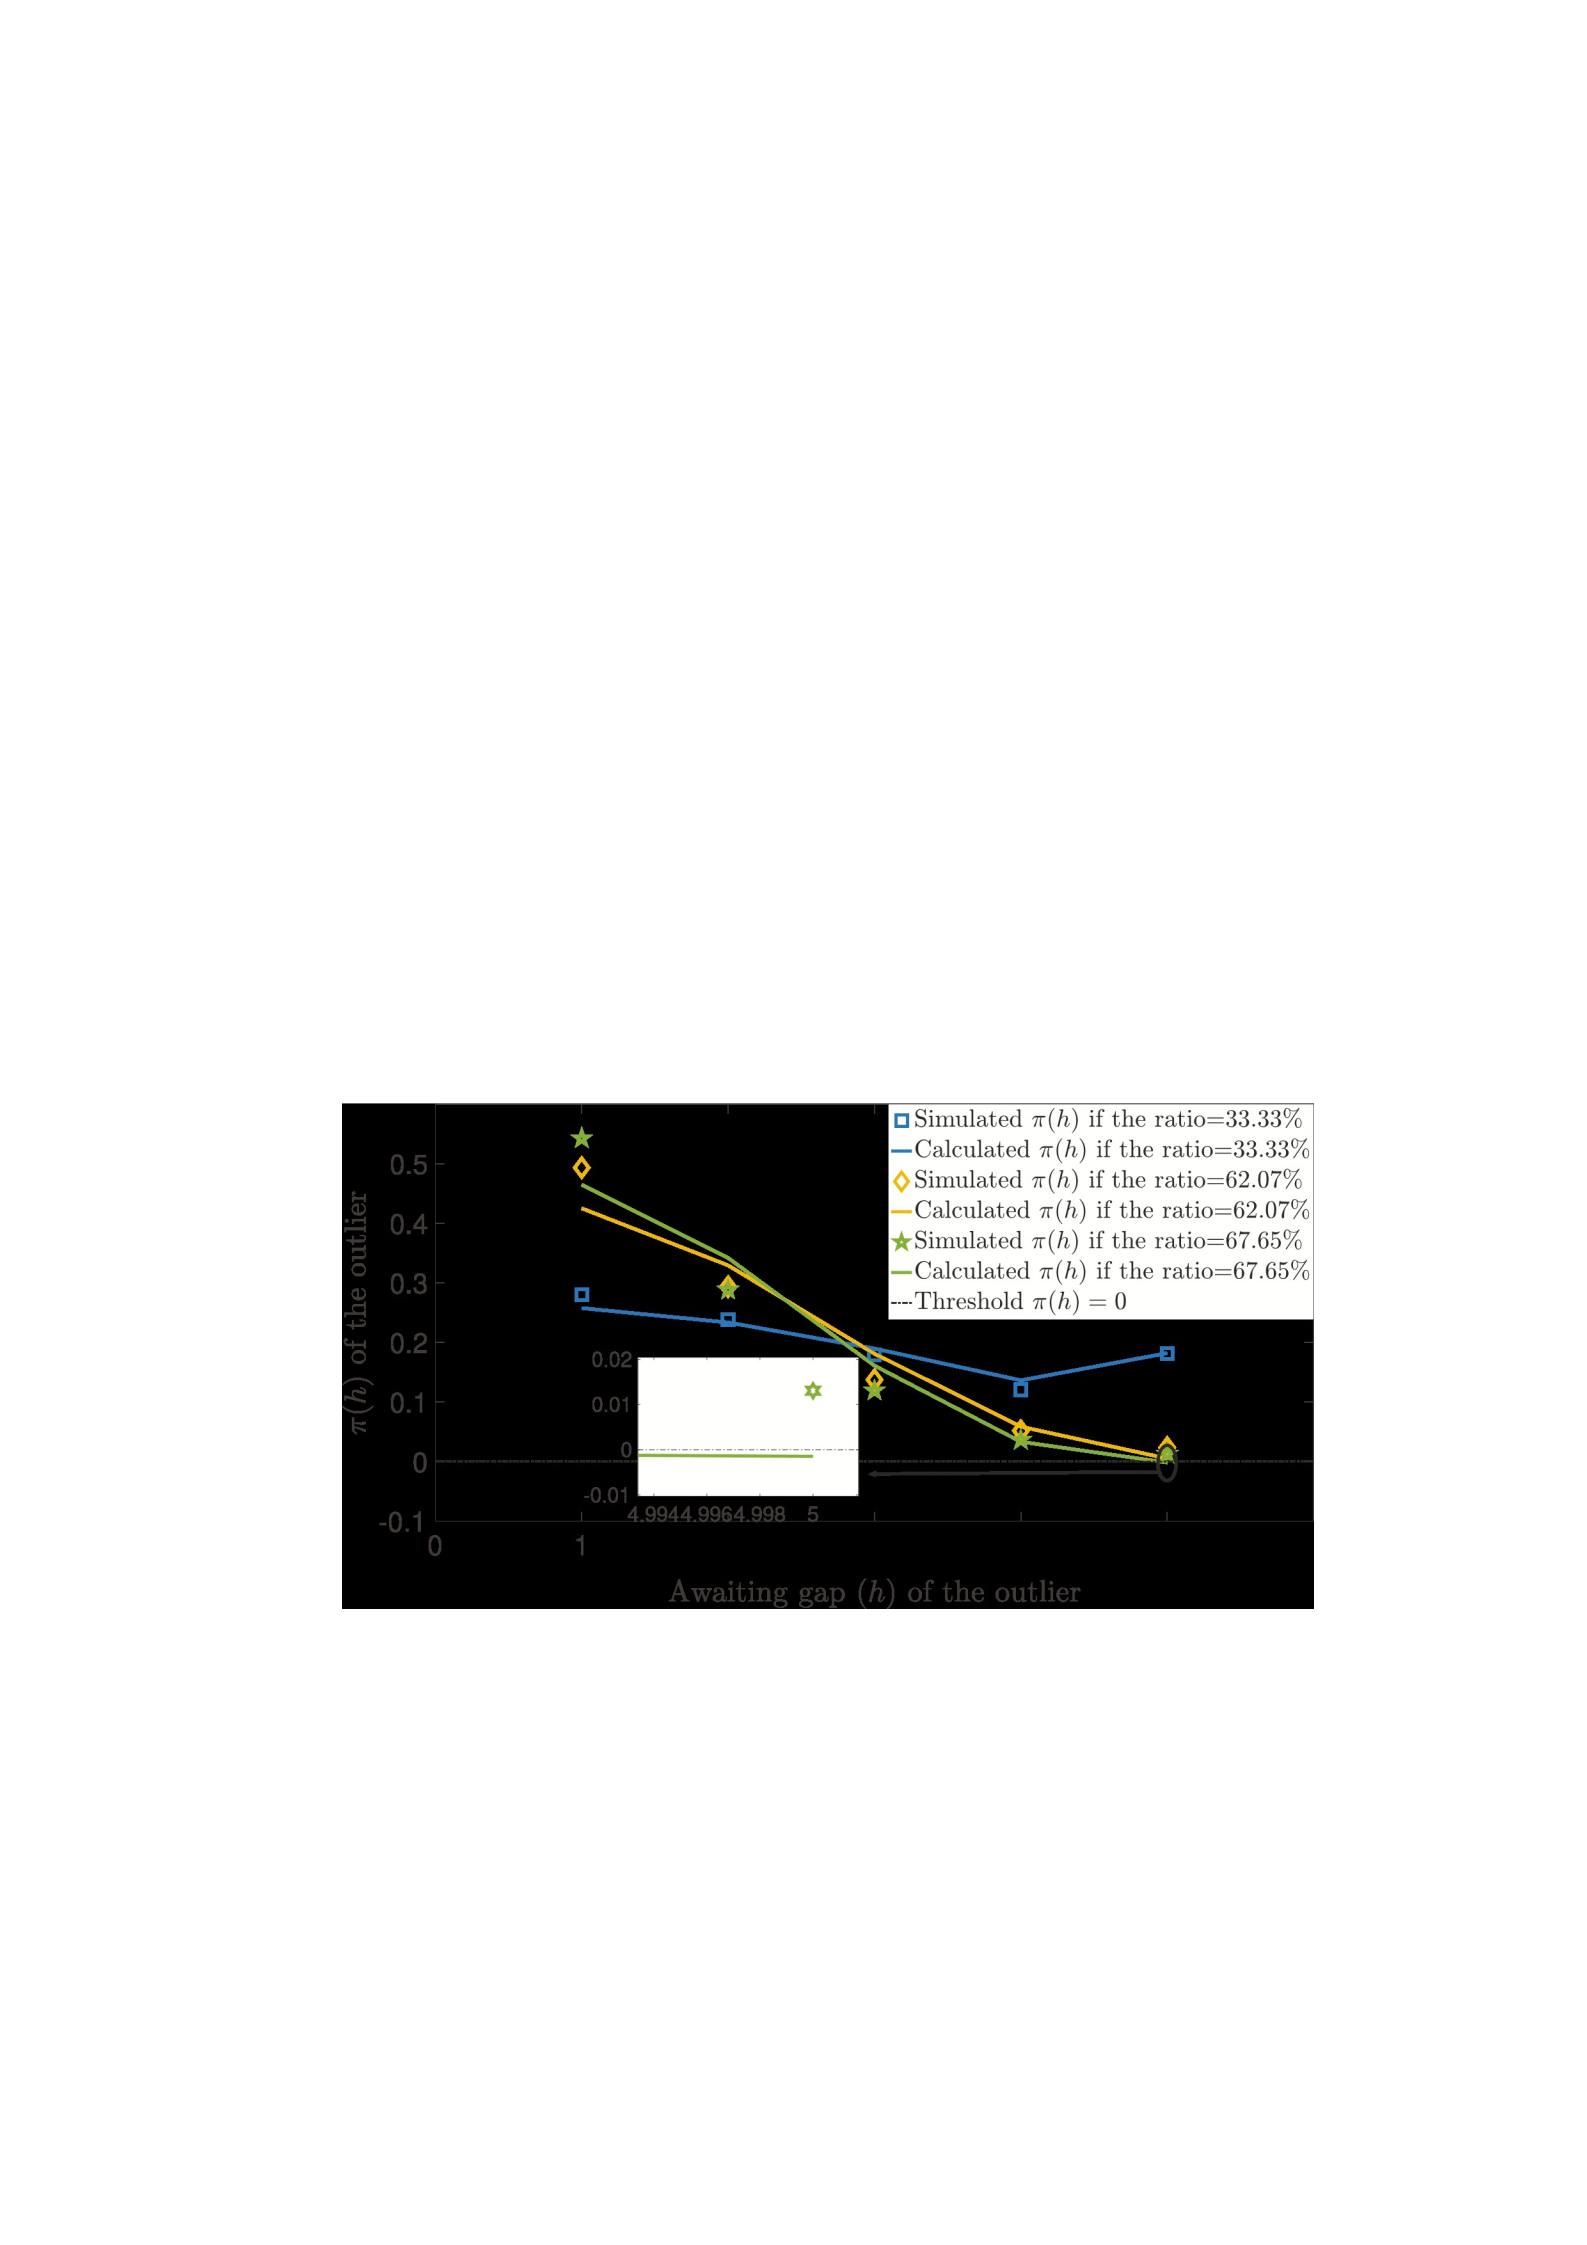
•Adjusted R-squared (ARSQ) [130]. ARSQ is known as the adjusted co-
e cient of determination in statistics, representing the ratio of the variance in
the dependent variable that is predictable from the independent variable(s)
with considering the number of independent variable(s). It is often used to
assess how good the estimated model fit the observed values, the closer to 1
the better. Note that, in our simulation ARSQ is a complemented metrics to S
as a non-linear model may imply an inaccuracy due to the unexpected over-
fitting. A high-ARSQ indicates a good fitting only if S is within the acceptable
range. In contrast, we can still reliably approximate the trend with a high-
ARSQ when S is slightly higher than the range.
Our analytical model is applicable to Pareto distributions (that is the worst
case), where the outlier owns up to 50% of the system resource that is equal to the
(a) fi,h = αmin{h,H}
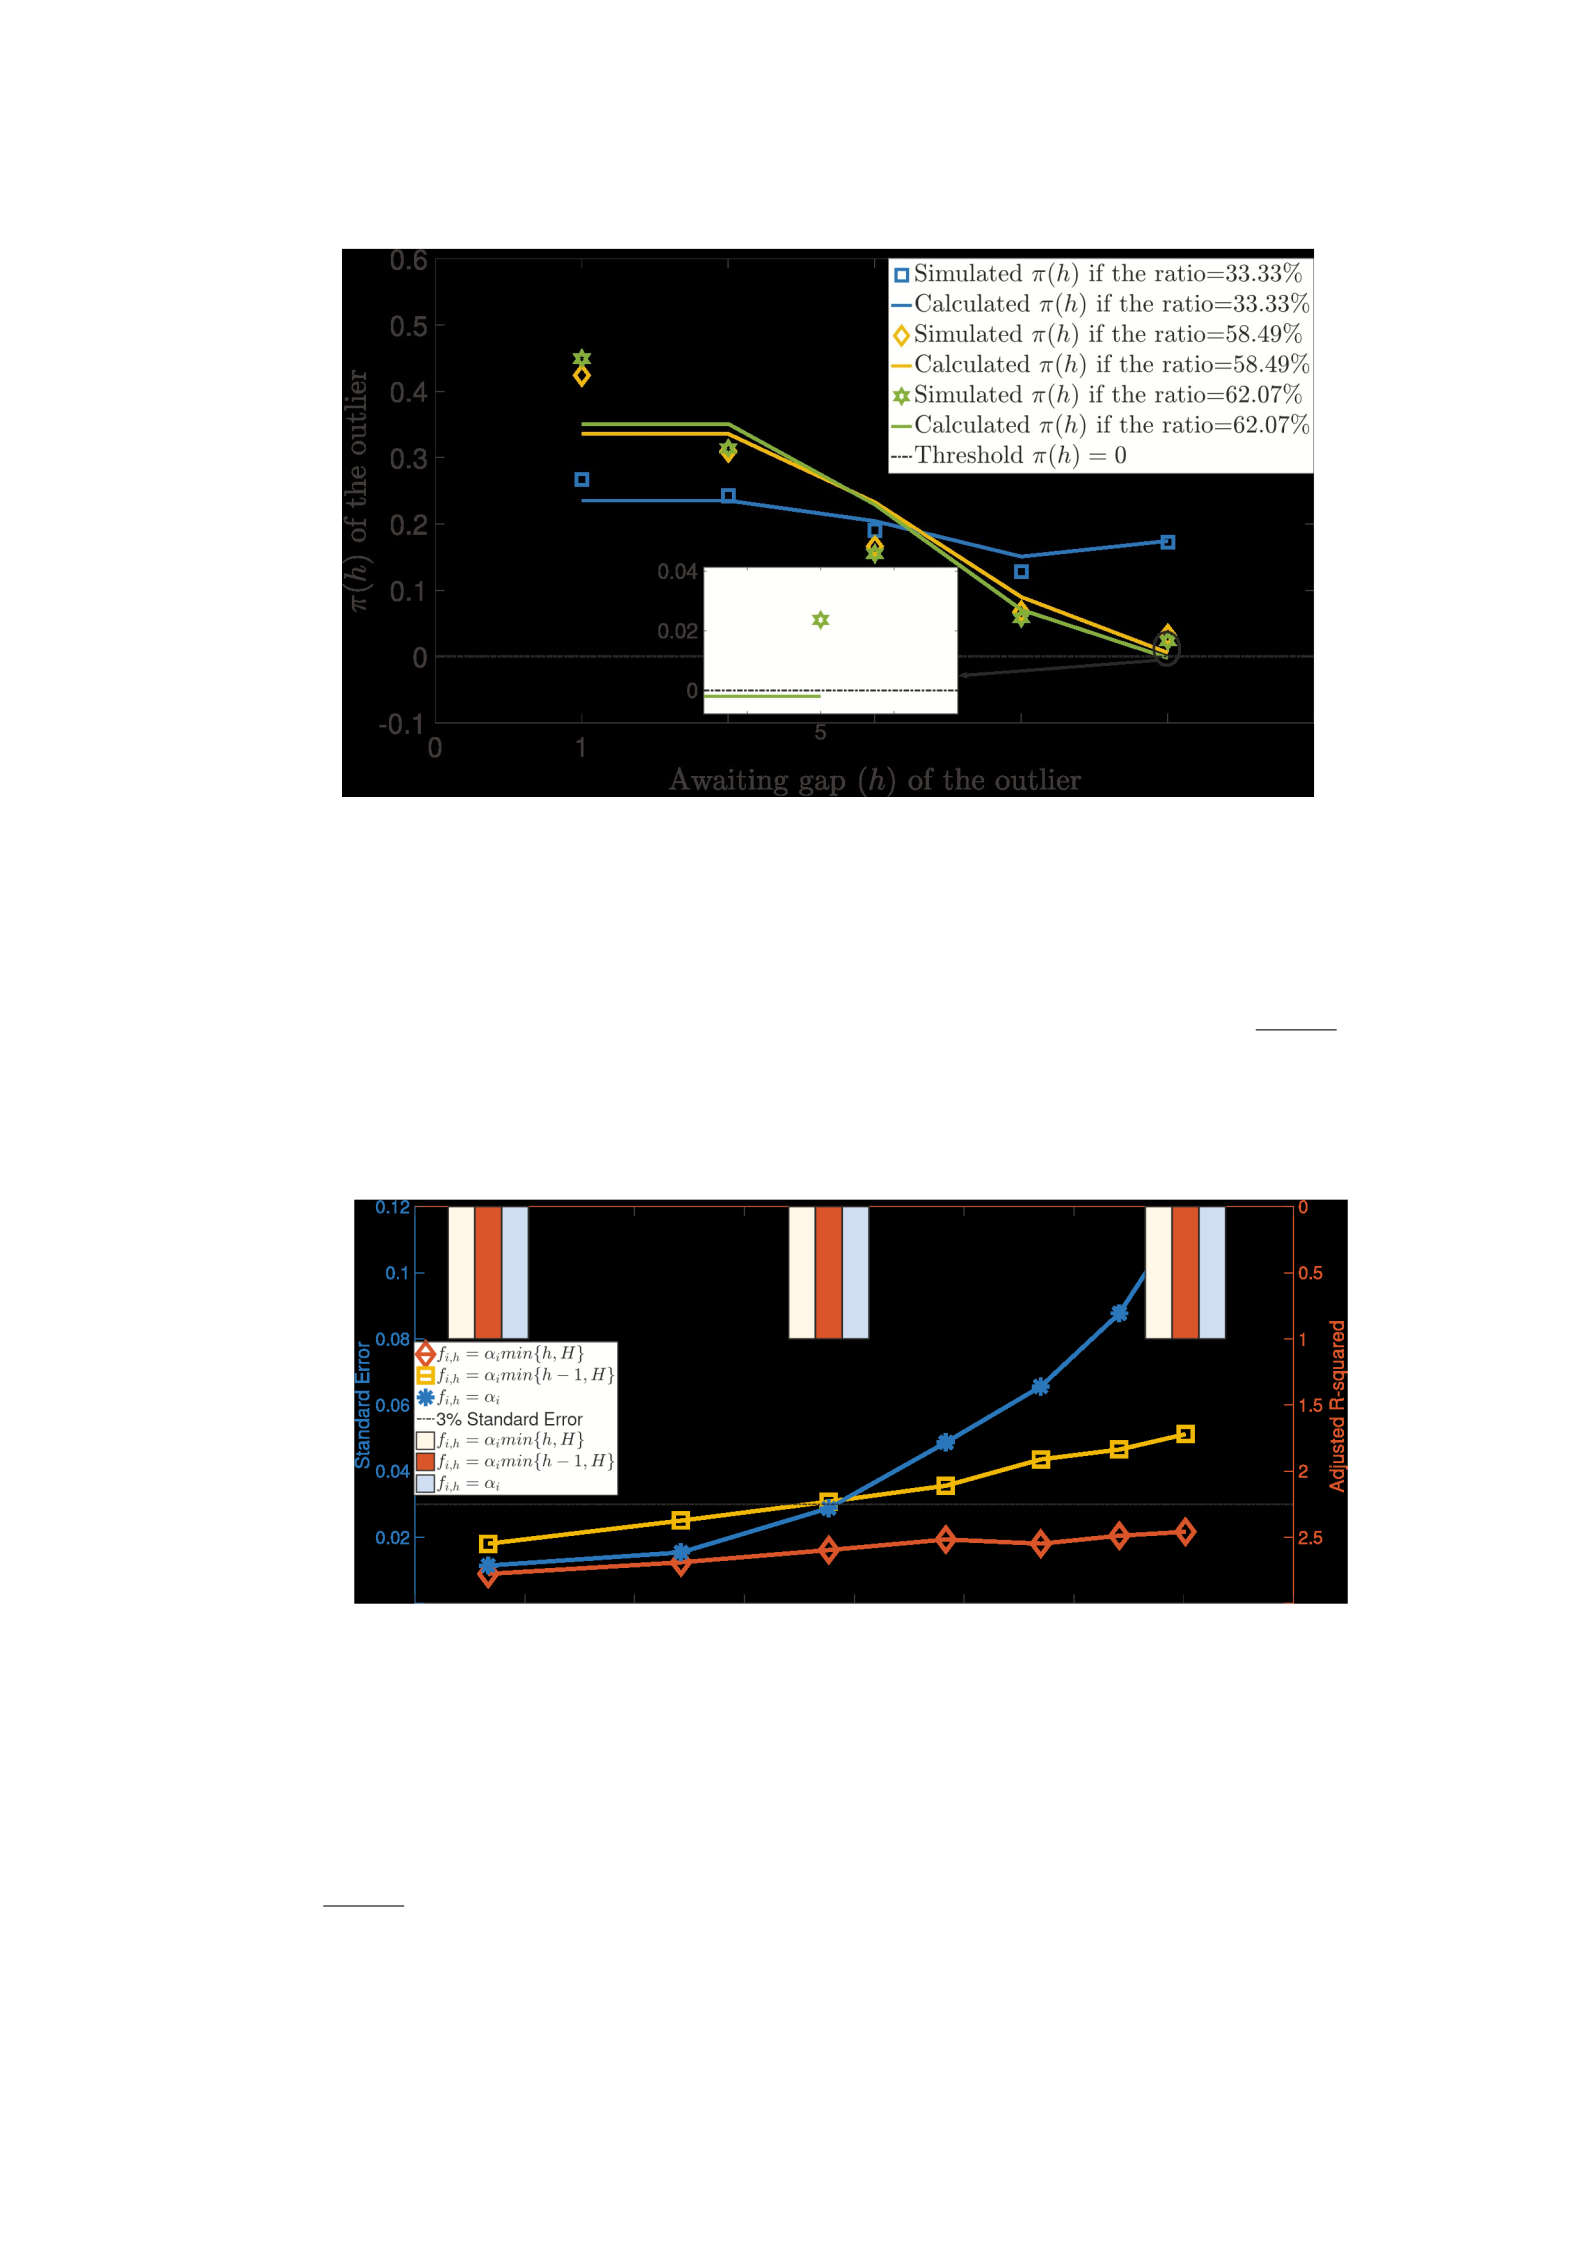
(b) fi,h = αmin{h − 1,H}
Figure 3.3 : ⇡(h) of the outlier with a Pareto distributed system resource for coinage-based PoS and
Non-Fairness-oriented PoS-Velocity respectively, where N = 10, H = 5, ↵= 2H P1 !i . An invalid ⇡(H) that
is negative appears when h = H.
03
0.3 0.35 0.4 0.45 0.5 0.55 0.6 0.65 0.7
Ratio of the amount of system resource
Figure 3.4 : The line plots are with respect to the blue axis on the left-hand side, while the bar plots
are with respect to the upside-down red axis on the right-hand side. The margin of error with the
growth of the resource ratio owned by an arbitrary miner that is the outlier, where N = 10, H = 5, ↵
=
2H P1 !i , in terms of both S and ARSQ. Here, the system resource is Pareto distributed. Note that the
ratio is the system resource ratio that a specific outlier miner owns.
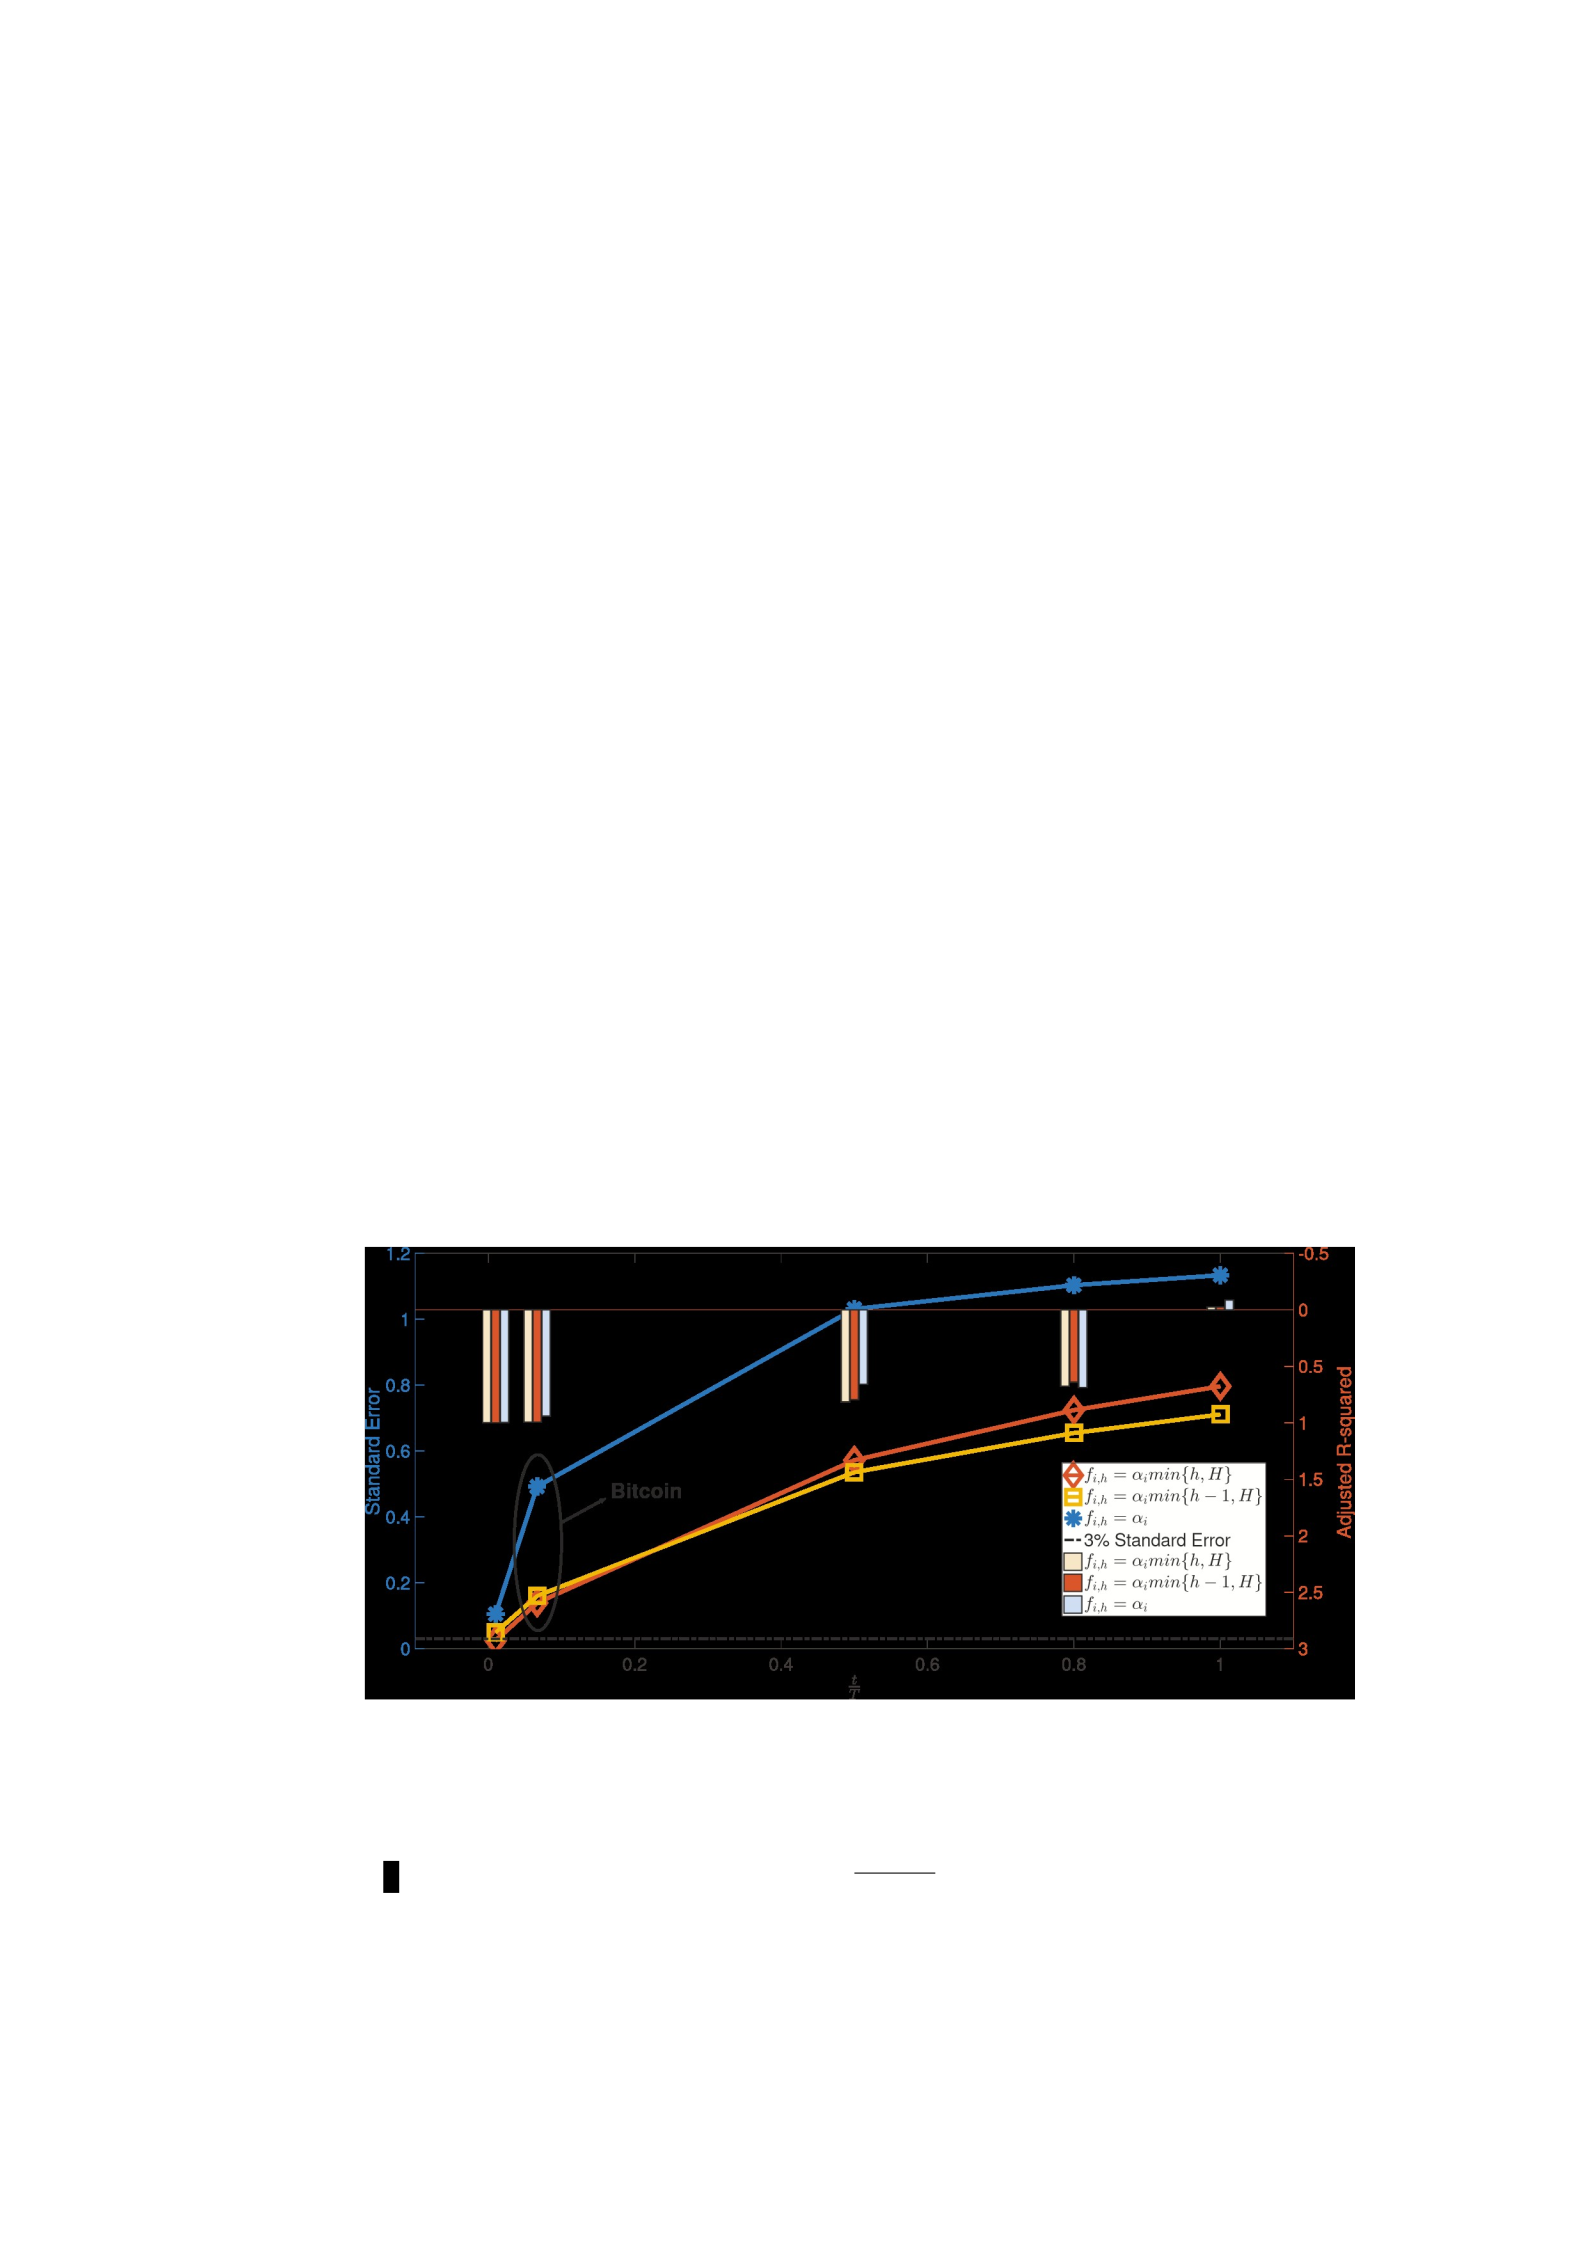
FT of all PoX schemes. An outlier denotes Node-i that owns the majority of the
Pareto-distributed system resource. For example, in the following list if N = 10,
! = [0.01,0.02,0.03,0.04,0.05,0.06,0.07,0.08,0.09,0.55],
where the n-th element in the list is the ratio of the amount of system resource of
Node-i. The node with ! = 0.55 is defined as the outlier.
According to Fig. 3.3, when fi,h = ↵imin{h,H} (see Fig. 3.3(a)) and ↵imin{h 1,H}
(see Fig. 3.3(b)), the invalid negative ⇡(i,H) appears at h = H, as the ratio of system
resource owned by Node-i increases.
Fig. 3.4 shows the correlation of the resource ratio owned by the outlier, with
the two types of margin of error between the estimated and simulated values. It
shows that ARSQ of all considered fi,h remains closed to 1, which results in a good
fitting if S is within the acceptable range. S remains low when the ratio of the
amount of system resource is less than 50% for all considered fi,h. Also, S increases
Figure 3.5 : The line plots are with respect to the blue axis on the left-hand side, while the bar plots
are with respect to the upside-down red axis on the right-hand side. The margin of error with the
growth of , where N = 10,H = 5, ↵= 2H P1 !i , in terms of both S and ARSQ. Here,
the system resource is Pareto distributed with the ratio of the amount of system resource owned by
a specific outlier miner is 33%.
exponentially as the ratio increases for fi,h = ↵i (the blue line). Thus, it can be
concluded that, the proposed model suits in the Pareto distribution with an outlier
owning up to 50% resource, but does not suit an accurate prediction for a⇠
Paretodistributed system with an outlier that is too fart apart (greater than ⇠
50%), except for algorithms satisfying Resource Fairness (referring to the example
of PoSVelocity shown in Table 3.1). In spite of this, the proposed model can still be
reliable on approximating the trend. Note that the smallest outlier has satisfied the
required FT (N 2f + 1), where f is the number of faulty miners. This consequently
leads to an acceptable range of S for the accuracy of the proposed model, i.e., 3%.
Fig. 3.5 shows the correlation of with the two types of margin of error
between the estimated and simulated values. By investigating what range of the
margin of error can be acceptable, we can subsequently determine the upper
bound of which can tolerate the possible deviation in (3.2). It shows that the
values of ARSQ of all considered fi,h remain closed to 1 when (Bitcoin point,
95% confident interval) [135, 57], decrease smoothly when Tt 0.8, and incur a
sharp decrease onwards. S of fi,h = ↵i min{h,H} and fi,h = ↵i min{h 1,H} remain closed
to the 3% range when falls around the Bitcoin point, which still results in a
reliable trend-approximation. However, S of fi,h = ↵i (the blue line) supports the
reliable trend-approximation only if stands around the Bitcoin point, and incurs a
sharp increase onwards. The same circumstance happens for fi,h = ↵i min{h,H} and
is greater than the Bitcoin point. Thus, it can be
concluded that, the proposed model supports a reliable trend-approximation for
that is smaller than the Bitcoin point.
Validated by Figs. 3.3 to 3.5, it can be further concluded that
• the model is accurate if the FT of PoX schemes is satisfied with either
Paretodistributed or normal-distributed resource;
• the model can provide a reliable trend-approximation when is su ciently
small (the network latency is comparatively negligible to the block period),
which corresponds to the circumstance of a well-connected network with low
latency in the real world.
3.5.2.2 Resource sensitivity
We simulate the process ranging from PoW to PoP, and both of the coinage-based
PoS with strong and weak restrictions, as shown in Table 3.1. Also, the
corresponding calculated values are obtained by calculating (13) under di erent↵
settings of fi,h.
Finding 1: The coinage-based PoS (Strong restriction) [96, 193] has the best
performance on Resource Sensitivity among our considered non-Fairness-oriented
PoX schemes.
This finding is revealed in Fig. 3.6, where P is subject to the ratio of the amount
of system resource. An identity line regardless of the distribution type is obtained
for fi,h = ↵i (the dark blue line), i.e., zero-Resource-sensitive. Note that Pi is
collectively generalized as P among the miners. The light blue curve of fi,h = ↵imin{h
1,H} appears to have a better performance on Resource Sensitivity than that of fi,h =
↵imin{h,H} (the purple line) due to the setting of strong restriction rather than
weak restriction. Referring to Section 3.2.1, it can be concluded that the cost for

attackers to catch up with the honest miners can be higher with fi,h = ↵imin{h 1,H}
or fi,h = ↵imin{h,H} than only fi,h = ↵i.
Finding 2: The poor (i.e., the less resourceful miners) can gain more profit with a
positive Degree function (that increases the mining probability by multiplying the
resource ratio and the awaiting gap) [3, 96, 193]. In contrast, the obtained profit
becomes lower for the rich with the increased ratio of resource owned.
Based on Fig. 3.6, it is conceivable that poor miners can obtain a greater
gradient g than wealthy miners (positive-Resource-sensitivity), in the case of fi,h =
↵imin{h 1,H} (the light blue line) and ↵imin{h,H} (the purple line) with a Pareto-
distributed resource. There exists a threshold intercepting the identity line, to the
left of which the gradient m is greater so that poor miners can obtain a larger P
than they used to deserve with only fi,h = ↵i (the dark blue line). Likewise, wealthy
miners, i.e., the outliers, can only obtain a smaller g than that of fi,h = ↵i. This
implies a mechanism that taking from the wealthy to help the poor to balance the
profits among the whole participated miners.
3.5.2.3 System convergence
We proceed to evaluate System Convergence of the considered PoX schemes, where
each of them runs for 1,000 tries. In each of the schemes, the system starts from
the
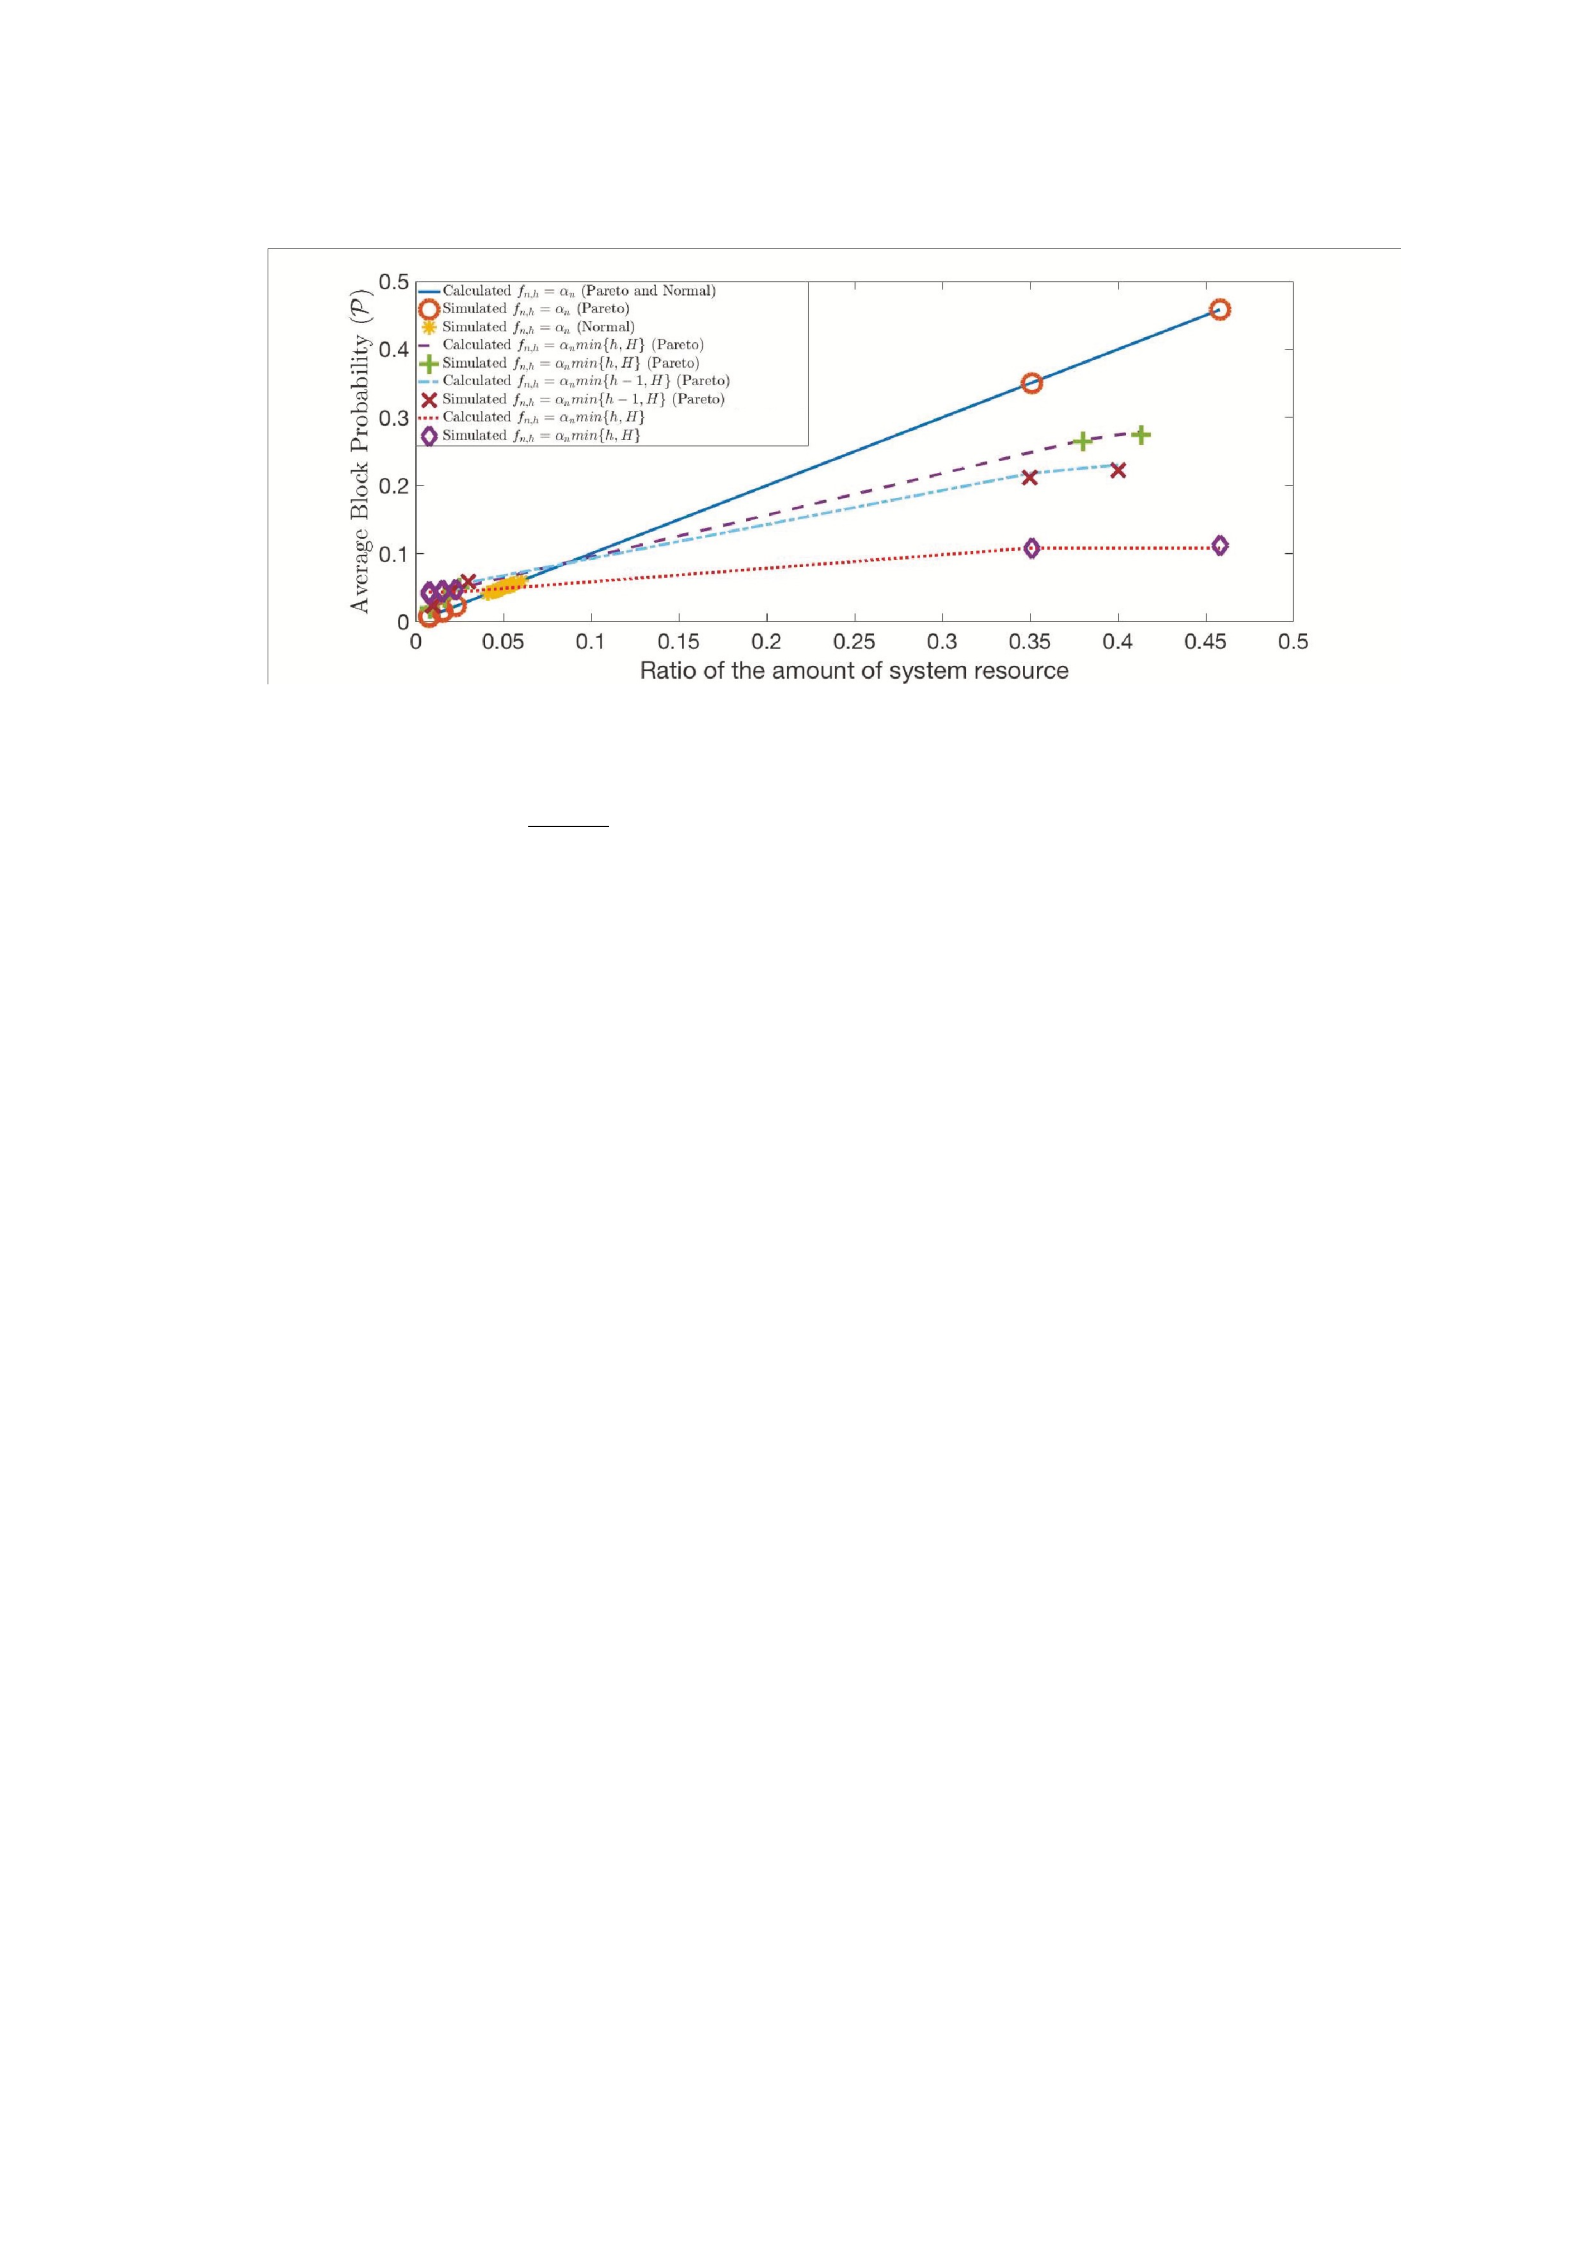
Figure 3.6 : The correlation between the resource ratio and the average block probability P, where
N = 20, H = 10, ↵= 2H P1 !i .
same initial state. We name the number of rounds required to reach the steady-
state system convergence period. During this simulation, we set that the steady-state
is reached once the gap between the calculated and the simulation value of Ti
decreases down to 3% (the explanation of 3% refers to the definition of System
Convergence in Section 3.3.4).
Finding 3: For PoX schemes disabling the Fairness function, 80/20-rule-based wealth
inequality deteriorates System Convergence, compared to normal-distributed wealth
inequality.
This finding is shown in Fig. 3.7, where a Pareto distribution applying to fi,h = ↵i
(the brown box) takes the longest time to reach the steady-state, while it converges
the most quickly with a normal-distributed resource (the purple box). Thus, PoP
resulting in a normal-distributed resource has the lowest number of rounds to
reach the steady-state, compared with those with a Pareto-distributed resource.
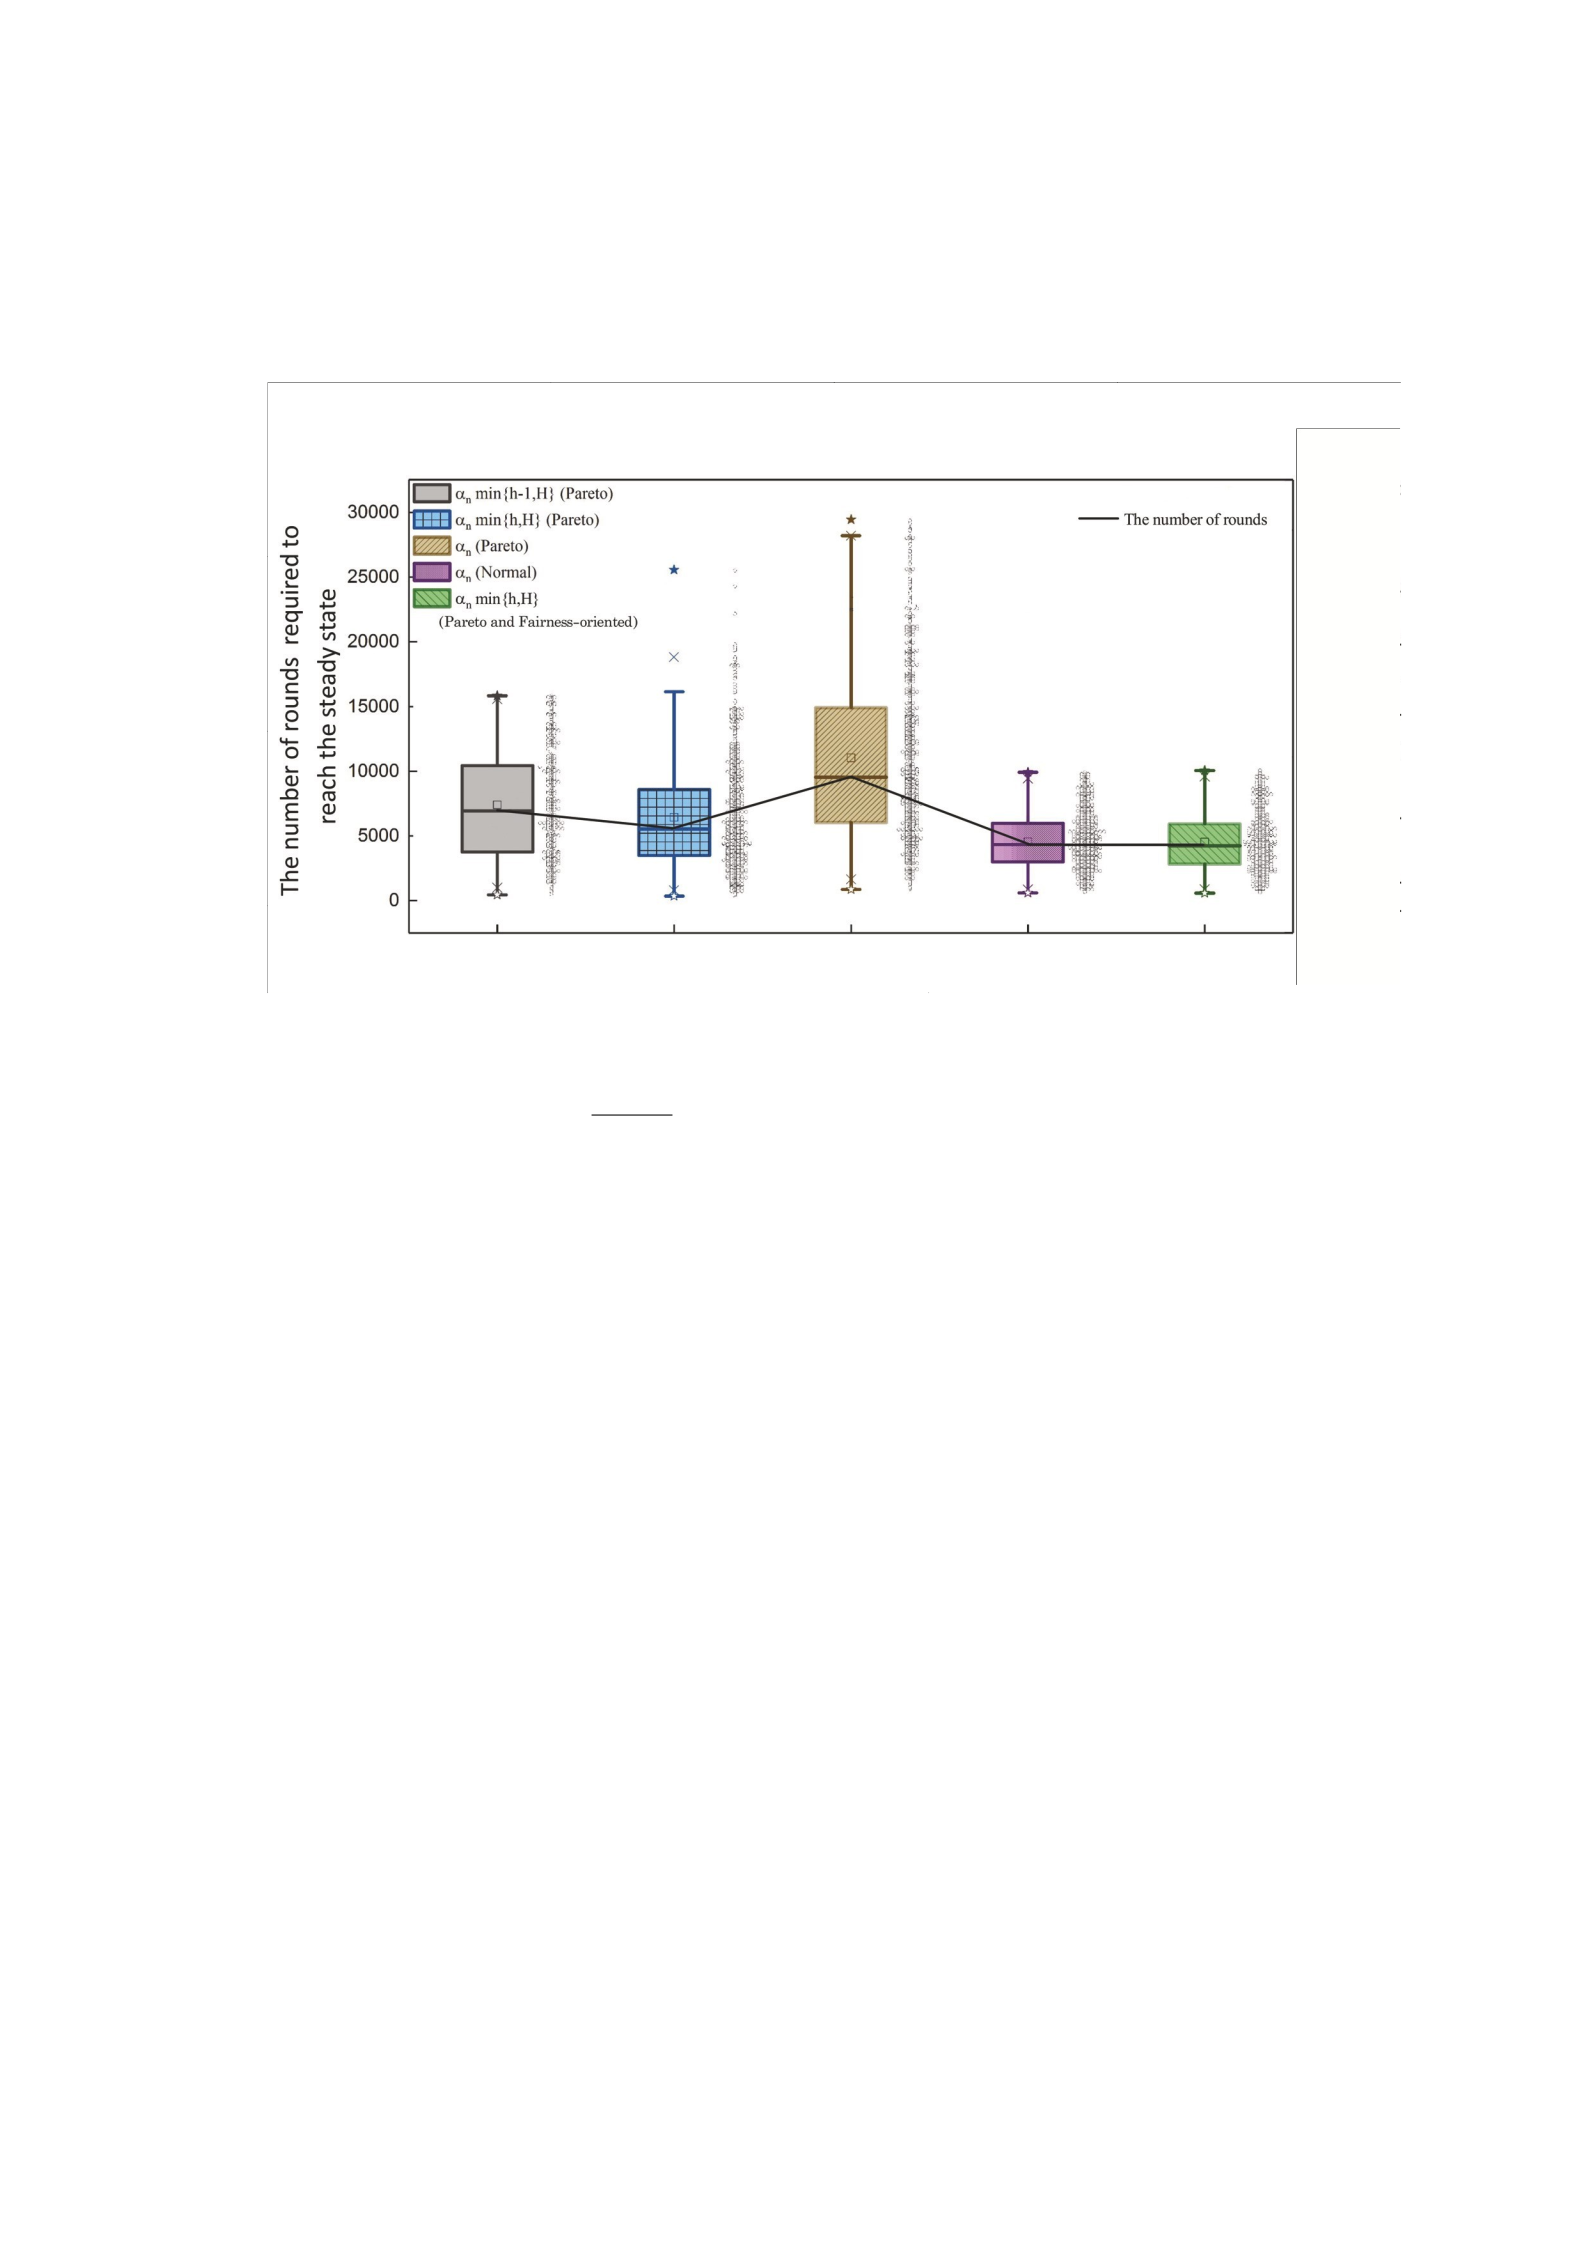
This is because of the outlier of Pareto-distributed resource overwhelmingly
dominates the mining process.
Figure 3.7 : The comparison among the four di erent PoX schemes in terms of ↵System Convergence,
where N = 10, H = 5, ↵= 2H P1 !i .
Finding 4: The system convergence period can be reduced by enabling Resource
Fairness and applying a positive Degree function (that increases the mining
probability by multiplying the resource ratio and the awaiting gap).
According to Fig. 3.7, it can be found that fi,h = ↵i min{h,H} (the green box) with
an active Fairness function needs fewer rounds to reach the stead-state than that of
fi,h = ↵i min{h,H} (the blue box) with an inactive Fairness function. On the other
hand, fi,h = ↵i (the brown box) with Degree function (·) = 1 has longer system
convergence period than the blue box with a positive Degree function. This is
because the active Fairness function and positive Degree function apply a stronger
restriction to the Monte Carlo variables, compared to those without an inactive

Fairness function.
3.5.2.4 Resource fairness
Fig. 3.6 shows that none of the considered PoX schemes (except the red dot line) is
upper bounded and Fairness-oriented, as the Pi of wealth miners remain a linear
increasing based on the resource ratio owned by each miner. In other words,
Resource Fairness is inactive for these PoX schemes, while Resource Fairness holds
in some circumstances (i.e., (⌥!i) =6 !i, to meet di erent requirements) for the↵
Fairnessoriented PoS-Velocity listed in Table 3.1, referring to the red dot line in Fig.
3.6 and green box in Fig. 3.7. In this section, we show how Resource Fairness
“encourages” such kind of PoX schemes to achieve better performance of Resource
Sensitivity and System Convergence.
Recall that we implement a typical type of PoS-Velocity (see Section 3.5.1) as an
example of a Fairness-oriented PoX scheme. It is revealed in Fig. 3.6, where the
considered PoS-Velocity has the best performance on Resource Sensitive (i.e., the
smallest E(g)) among all of the considered PoX schemes. In addition to the better
performance of Resource Sensitivity, P remains constant when the upper bound is
met with a partition function ⇣(!). In other words, Resource Fairness can be
satisfied with a simple linear (⌥!i) being substituted by the design of a partitioned
(⌥!i) = ⇣(!). Thus, the considered PoS-Velocity prevents wealthy miners from
monopolizing the entire network and incentivizes all miners to participate in the
mining process and getting rewards.
Furthermore, the 80/20-rule-based wealth inequality can be addressed by the
considered PoS-Velocity. Fig. 3.7 shows that System Convergence of the considered
PoS-Velocity with a Pareto distribution (the green box) performs as good as that of
PoP, i.e., fi,h = ↵i with a normal-distributed resource (the purple box).

It turns out that by enabling Resource Fairness with the designed (·) and (·),⌥
the considered PoS-Velocity achieves,
•best Resource Sensitivity: the best performance on Resource Sensitivity among
any other non-Fairness-oriented PoX schemes listed in Table 3.1, based on
the red dot line in Fig. 3.6;
•improved System Convergence: a performance on System Convergence that is
as good as that of PoP with a normal-distributed resource, based on the
comparison between the purple and green boxes shown in Fig. 3.7.
3.5.2.5 Summary
To sum up, apart from the considered PoS-Velocity scheme (defined in Section
3.5.1), other Fairness-oriented PoS-Velocity schemes can also reveal their
optimized Resource Sensitivity and System Convergence by using our model. This
can be achieved as long as the proper (·) and (·) are set (e.g., partition (·) and⌥ ⌥
non-linear (·)). By using the proposed model, we reveal that carefully designed
Resource Fairness is particularly important to balance Resource Sensitivity, and
System Convergence of PoX-based consensus algorithms in the long-term steady-
state. Such steady-state analysis and findings have not been possible without our
model.
3.6 Conclusions
Remark that participators hardly succeed to evaluate the profits by observing
the generic property of any PoX schemes due to the lack of a unified analytical
model.

This question was resolved in this chapter by developing a new infinite-
dimensional Markov model to unify the steady-state analysis for weighted resource
distribution of di erent PoX-based Blockchains in large-scale networks. The↵
probability of an arbitrary node being elected as the block generator was derived.
Based on the analytical model, we evaluated PoW, balance-based and coinage-
based PoS, PoA and PoP, in terms of Resource Sensitivity, System Convergence, and
Resource Fairness. We also assessed a typical PoS-Velocity scheme with a weight
consisting of the proper set Fairness function and Degree function, and showed the
balanced performance of the scheme in regards to all the three metrics. Extensive
simulation results also prove that the applicability and generality of the model.
This can significantly encourage the adoption of Blockchains in large-scale
networks that provide public services to the communities.

Chapter 4
Scaling-out Blockchains with Sharding
The decentralized security relies on the consensus regarding the duplicated
communication, storage, and computation among each full node in a large-scale
network. However, the duplicated overhead is inevitable, leading to the scalability
issue, i.e., an upper limit of Blockchain throughput, due to the limited
communication, storage, and computation resource in a live context. Having an
ability to increase the throughput along with the increasing network size becomes
crucial. One of the most practical methods to overcome this issue is sharding, by
partitioning network into multiple shards so that the overhead of duplicated
resources among full nodes can be downgraded while maintaining the
decentralized security. There has been existing studies presenting various sharding
mechanisms, but none of them provides a comprehensive comparison. Industry
and academia are desperate for a generic and systematic framework to learn
various sharding mechanisms. Under this background, this chapter refers to [205],
presents a detailed comparison and evaluation of major sharding mechanisms,
along with our insights analyzing the features and restrictions of the existing
solutions. The remaining challenges and future research directions are also
reviewed.
4.1 Introduction
Sharding is first proposed by [49] and commonly used in distributed databases
and cloud infrastructure. Based on the pioneering proposals [53, 120] integrating
sharding with permissioned and permissionless Blockchain, respectively, the

sharding technology is thought to be able to partition the network into di erent↵
groups
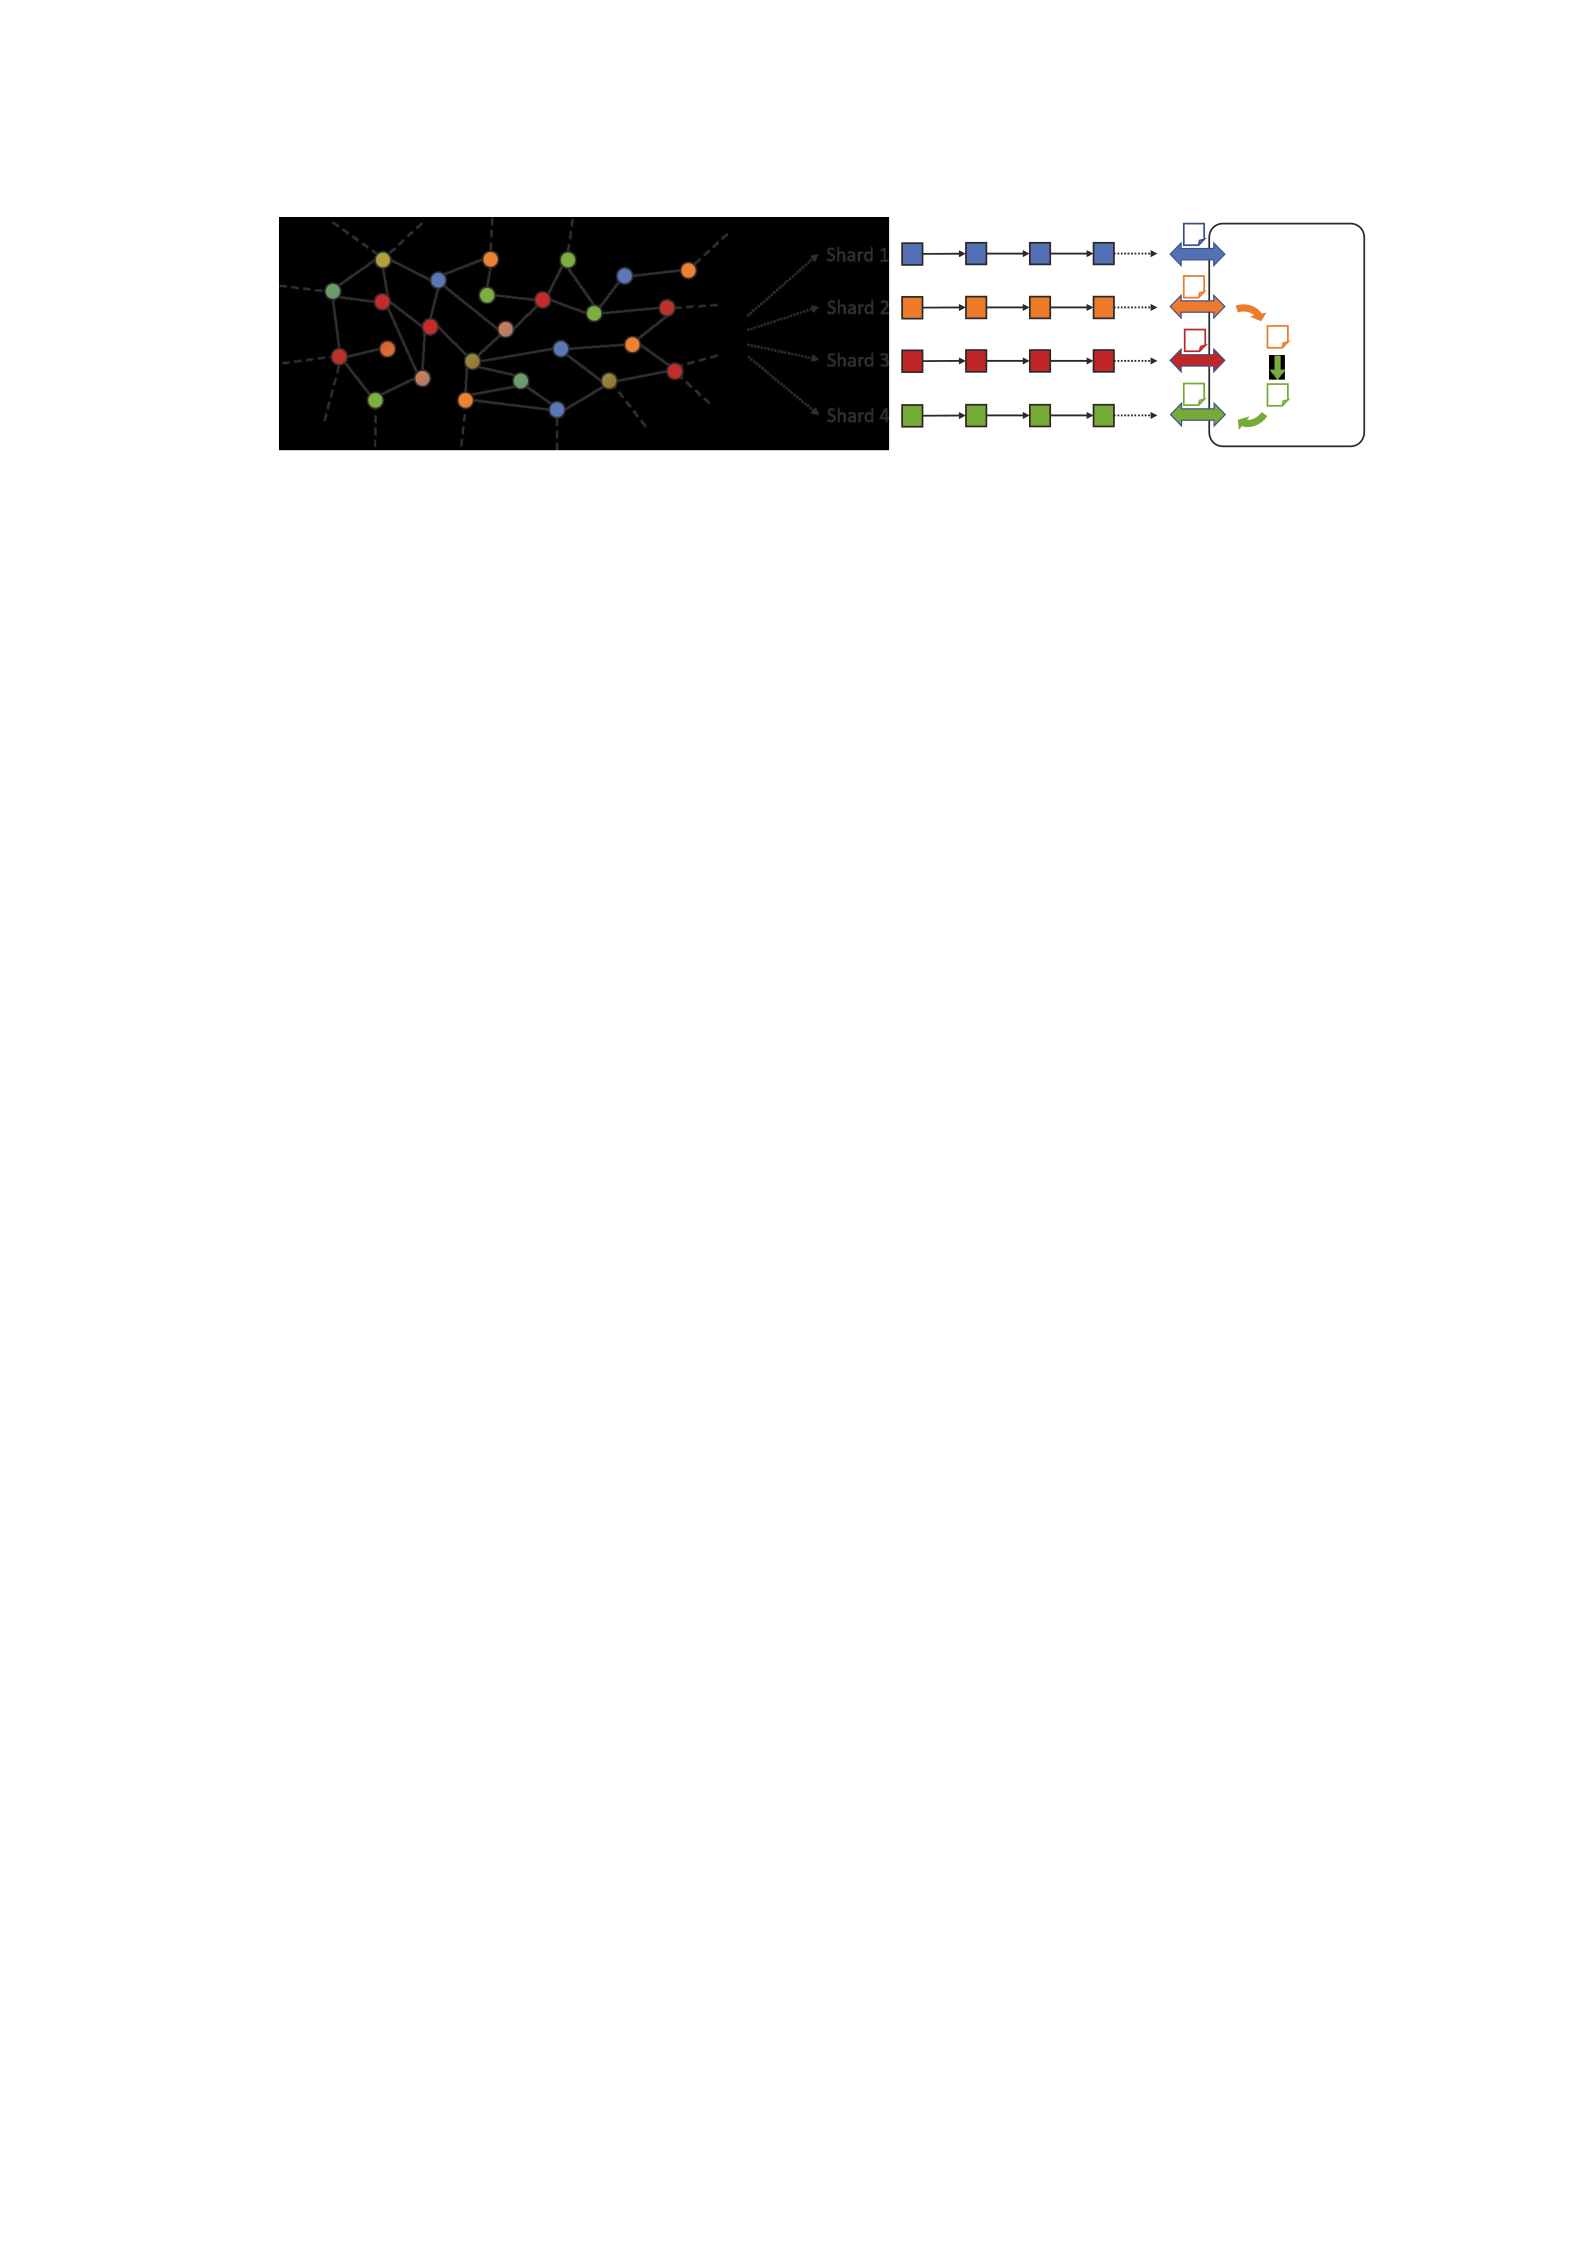
66
Figure 4.1 : The sharding technology partitions the network into different groups, while each of the
groups maintains its own ledger and processes and stores a disjoint set of transactions. By
implementing a secure cross-shard communication protocol, such disjoint transaction sets that
could not have been interacted become securely verifiable and interactively executable in parallel.
Note that, nodes in some sharding mechanisms (e.g., Monoxide) can choose to participate in the
processing of multiple shards and maintain their ledgers, as illustrated by the multicolored circles,
while the unicolored circles denote the nodes only participating in a single shard to which they are
assigned in terms of the color.
(shards), so that the compulsory duplication of three resources (i.e., the
communication, data storage, and computation overhead) can be avoided for each
participating node, while these overheads must be incurred by all full nodes in
traditional nonsharded-Blockchains. This partition is essential because the
restriction incurred by the three resources owned by a single node may make the
system unable to take full advantage of a scalable consensus algorithm. Sharding is
so far one of the most practical solutions to achieve a scale-out system where the
processing, storage, and computing can be conducted in parallel, as illustrated in
Fig. 4.1. As such, the capacity and throughput being linearly proportional to the
number of participating nodes or the number of shards become possible, while
preserving decentralization and security. However, sharding poses new challenges
to Blockchains, i.e., the intraconsensus-safety, cross-shard-atomicity, and the general
improvements:

67
•intra-consensus-safety: how to secure the consensus algorithm inside a
shard away from both the Nakamoto-based and BFT-based 1% attack
[37] in a scalable way, while the latter can also be corresponding to a
secure randomness

68
generation process, as discussed in Section 4.2; note that 1% attack is an
attack strategy in sharded networks where attackers can dominate a single
shard more easily than dominating the whole network;
•cross-shard-atomicity: how to support the cross-verification, and guarantee
the Atomicity [74, 77] of cross-shard transactions for both unconditional
transactions (simple payment) and conditional contract-oriented
transactions in an e cient way (ine cient if the latency and overhead for
achieving atomic-safe cross-shard transactions are higher than O(n); n
denotes the number of shards being partitioned or the number of
participating nodes), as discussed in Section 4.3;
•general improvements: based on the intra-consensus-safety and cross-
shardatomicity, we focus on the improving factor N regarding the multiple of
optimized global throughput for each considered sharding mechanism, while
N is subject to the linear order O(n). On the other hand, the additional latency
and overhead originated from the proposed solutions also reveal the new
problems that sharding brings to us. In regard to this, some general
improvements are discussed in Section 4.4.
There have been a few studies working on these challenges regarding the
sharding in permissionless Blockchains [120, 99, 206, 5, 37, 184], prior to which
[53] proposes a sharded permissioned Blockchain that will not be discussed in this
chapter due to its forfeit of permissionless decentralization. Rather, the sharding in
permissionless Blockchains is focused (as permissioned Blockchains do not take
full advantage of the sharding technology due to the smaller network size and its
forfeit of permissionless decentralization). Also this chapter is based on the

69
published research papers and other research references of Monoxide [184],
Elastico [120], OmniLedger [99],
Rapidchain [206], Chainspace [5], and Ethereum 2.0 [37]. Our contribution can be
characterized as follows.
1. Our work, for the first time, provides an introduction of state-of-the-art
sharding mechanisms ranged from BFT-based to Nakamoto-based sharding
mechanisms, while the latter has never been systematized in any of the
existing surveys at the time of writing.
2. We gain our own insights analyzing the features and restrictions into the
existing solutions to the intra-consensus-safety, atomicity of cross-shard
transactions, and general challenges and improvements proposed by the
considered sharding mechanisms. Based on the insights of the features and
restrictions of each existing sharding solution, a comprehensive comparison
is proposed.
3. Finally, we point out the current remaining challenges of sharding
mechanisms, followed by suggestions for the future trend of designing
reliable sharding mechanisms.
4.2 Intra-Consensus Protocol
Sharding significantly increases the throughput in O(n), but sacrificing security
in intra-consensus protocols, i.e., the per-zone security or 1% attack [184, 37].
Concretely, it is categorized into the Nakamoto-based 1% attack and BFT-based 1%
attack.
The total amount of mining power among the network, i.e., P, guarantees the
low probability for a single entity to dominate over 50% mining power. By

70
purposely dividing the network into n partitions (shards), we can greatly increase
the throughput in O(n), where rational miners tend to ideally distribute their
mining power in multiple shards (at most n shards) in order for the maximum
rewards. However, this also decreases the security of PoW in each shard in O(1/n).
Such a system can be more prone to double-spend attack by a malicious miner that
only needs to own the mining power P > P/n 50% due to the smaller shard size⇥
compared to the entire network size. This issue deteriorates as n increases in order
for a larger throughput, which becomes the most serious barrier to PoW being
implemented for the intra-consensus protocol of a sharding mechanism.
On the other hand, BFT-based consensus algorithms are considered instead of
PoW in order to solve the security challenge, as discussed above. However, such
designs introduce another kind of vulnerabilities other than that of the PoW-based
one, as discussed in the following.
• It is of importance to carefully design a scheme to generate an unpredictable
and unbiasable randomness without any third-parties in permissionless
Blockchains. The randomness can be used to 1) allocate validators (an alias for
nodes participating in the intra-consensus process in the context of BFT-based
systems) into di erent shards at the beginning phase and every↵
reconfiguration phase; 2) select the leader of each shard; and 3) decide which
shards a cross-shard transaction should broadcast to, etc. Without such a
strictly-chosen randomness, malicious validators may be able to bias the
allocation and control the elections at will, such as collusion within a shard
(with a small number of validators due to the weak scalability of traditional
BFT-based consensus algorithms [59], e.g., PBFT [40]).
• Then it ends up encountering the dilemma of BFT-based 1% attack that the
weak scalability of BFT-based consensus algorithm restricts the shard size, i.e.,
71
the number of members in a shard, while too small a size can potentially
decrease the security of the intra-consensus with a strict fault-tolerance (FT), as
described by the following cumulative binomial distribution,
cm
s(c,m,p) = P[X c] = Xk=0 ✓k ◆pk(1 p)m k,
f(c,m,p) = 1 s(c,m,p),(4.1)
where X is the random variable that represents the number of times a
malicious miner is picked [98, 120, 99, 62]; m denotes the shard size; c
denotes the number of malicious members within a shard; and p denotes the
total FT among the entire network. It is strongly suggested that s(c,m,p)
should be greater than 99% [98], while only m & 144 can satisfy, of which the
traditional BFT-based consensus algorithm cannot be capable4. In order to
resolve this, highly scalable BFT-based consensus algorithms with large
shard size require more attractions.
In this section, we compare and discuss the intra-consensus protocols of the
considered sharding mechanisms, i.e., Monoxide, Elastico, Chainspace, OmniLedger,
RapidChain, and Ethereum 2.0. Note that the Shasper used in Ethereum 2.0
features its novel and engineering-oriented design that combines the two major
issues (intra-consensus-safety and cross-shard-atomicity) and kills two birds with
one store. Elastico and Chainspace directly use PBFT for intra-consensus that are
not discussed in detail in this section. This is because, as the first practical BFT-
4 A few sharding mechanisms are incurring a total 25% FT based on the 33% FT in each shard,
e.g., Elastico, OmniLedger, and Chainspace. This can be a BFT-based 1% attack, by dispersing
validators into as many shards as possible to maximize the possibility to control some shards.
Elastico and Chainspace su er from this security issue, while OmniLedger implements a scalable↵
BFT-based consensus algorithm to address this issue.

72
based consensus algorithm, PBFT has been the baseline of any other more
advanced BFTbased consensus algorithms. The randomness generator of
Chainspace is also not discussed as the detail is not provided in [5].
Also note that, a threat model where the attackers can refuse to participate or
collude others (behave arbitrarily) takes e ect in all discussed sharding↵
mechanisms in this chapter. Also, Elastico [120], OmniLedger [99], and RapidChain
[206] assume the slowly adaptive attackers (who can only succeed to attack in a
long time), while Monoxide [184], Ethereum 2.0 [37], and Chainspace [5] assume a
model of uncoordinated majority where all participators are game-theoretically
rational, i.e., egoism (with an upper-bounded fraction that can coordinate the
majority). Therein Chainspace [5] also introduces an audit scheme to prevent
attacks from dishonest shards.
4.2.1 Nakamoto-based - Monoxide - Chu-ko-nu mining
Monoxide is the first sharding mechanism that eliminates the need for
generating randomness, and implements Nakamoto consensus algorithm for its
intra-consensus. It introduces a one-o bootstrapping in the beginning, to allocate↵
each node (including miners and non-miners) into di erent shards based on their↵
identity addresses. By using the proposed Chu-ko-nu mining, Monoxide can achieve
a large-scale network with a huge number of shards and a flexible shard size. It
involves a Merkle Patricia Tree (MPT) [191] root consisting of all proposed blocks
among multiple shards, thus the P/n can be multiplied by a factor k (k denotes the
number of shards a particular miner manage to mine on). Consequently, dispersing
mining power can be re-aggregated to solve the 1% attack, i.e., Pk/n 'P as k ! n.
In order to meet the requirement of Pk/n 'P, Monoxide needs most of miners to
conduct Chu-ko-nu mining across as many shards as possible, i.e., k = n in the best

73
case. However, this implies the fact that if miners only mine on k out of n shards,
i.e., Pk/n, where k ⌧n, the factor expected to amplify the e ective mining power↵
will be too small to secure the mining process, hence reducing the attack cost. On
the other hand, rational miners tend to mine on all n shards to reap the maximum
profit, which may also result in the power centralization due to the huge cost of
bandwidth, disk storage, and computing processors that only the professional
mining facilities can a ord.↵
Insight 1. The amplification to the e ective mining power relies on an incentive↵
scheme that should encourage miners to mine across k ! n shards in Chu-ko-nu
mining. This also poses the issue of power centralization and additional overhead to
Monoxide.
4.2.2 BFT-based - Elastico
Using BFT-based algorithms for the intra-consensus is an alternative to bypass
the vulnerability of Nakamoto-based algorithm (Insight 1). Thus, including but not
limited to Elastico, OmniLedger, RapidChain, Chainspace, and Ethereum 2.0 choose
to implement BFT-based algorithm. Therein, Elastico uniformly (re)allocates
potential validators in terms of the di erent least-significant bits of the↵
unpredictable PoW solutions at the beginning of each epoch, followed by running
PBFT for the intra-consensus. The randomness used during the mining is
generated by a proposed distributed commit-and-xor scheme.
Consensus Algorithm - PBFT’s restrictions in sharding
Due to the weak scalaibilty of PBFT, Elastico incurs an unacceptable failure
probability of 8% with f(c,m,p) = f(6,16,0.25) based on the result of [59], while it
still incurs 2.76% with f(c,m,p) = f(34,100,0.25) even extending to a larger-scale
network of m = 100 (which can be the bottleneck [99]) by running powerful

74
servers in cloud. This security issue has been hindering Elastico to be practically
used, which are greatly resolved and improved by OmniLedger and RapidChain.
Insight 2. The traditional non-scalable PBFT incurs unacceptably high failure
probability with total FT of only 25%, unless increasing the size of the consensus
group, which leads to a chicken-and-egg problem due to huge communication
overhead.
Generating Randomness - Distributed commit-and-xor scheme
The distributed commit-and-xor scheme is implemented for the randomness
generation in Elastico. It can be categorized into the commit-and-then-reveal scheme
[136], with an exception that the final result (randomness) varies depending on the
di erent combinations of seeds ↵i every validator chooses. Also, the randomness
generation is conducted by a global subset, i.e., the final committee.
This design, however, is not perfectly unbiased. It is exponential biased and
bounded by the size of i, i.e., | i|, and m (m denotes the size of the final committee).
In order to prevent the attacks from biasing the randomness by deliberately
choosing a specific set of m/2 + 1 values of i in his favor, | i| should be large enough
as m also increases. This incurs large communication overhead, in addition to the
overhead of the extra verification during PoW process. In the case of only
2m/3 values of ( i,Hash( i)) being received, the lack of Verifiable Secret Sharing
(VSS) [65, 147, 175] forces all senders of these 2m/3 values to be online all the
time with no network outage or delay.
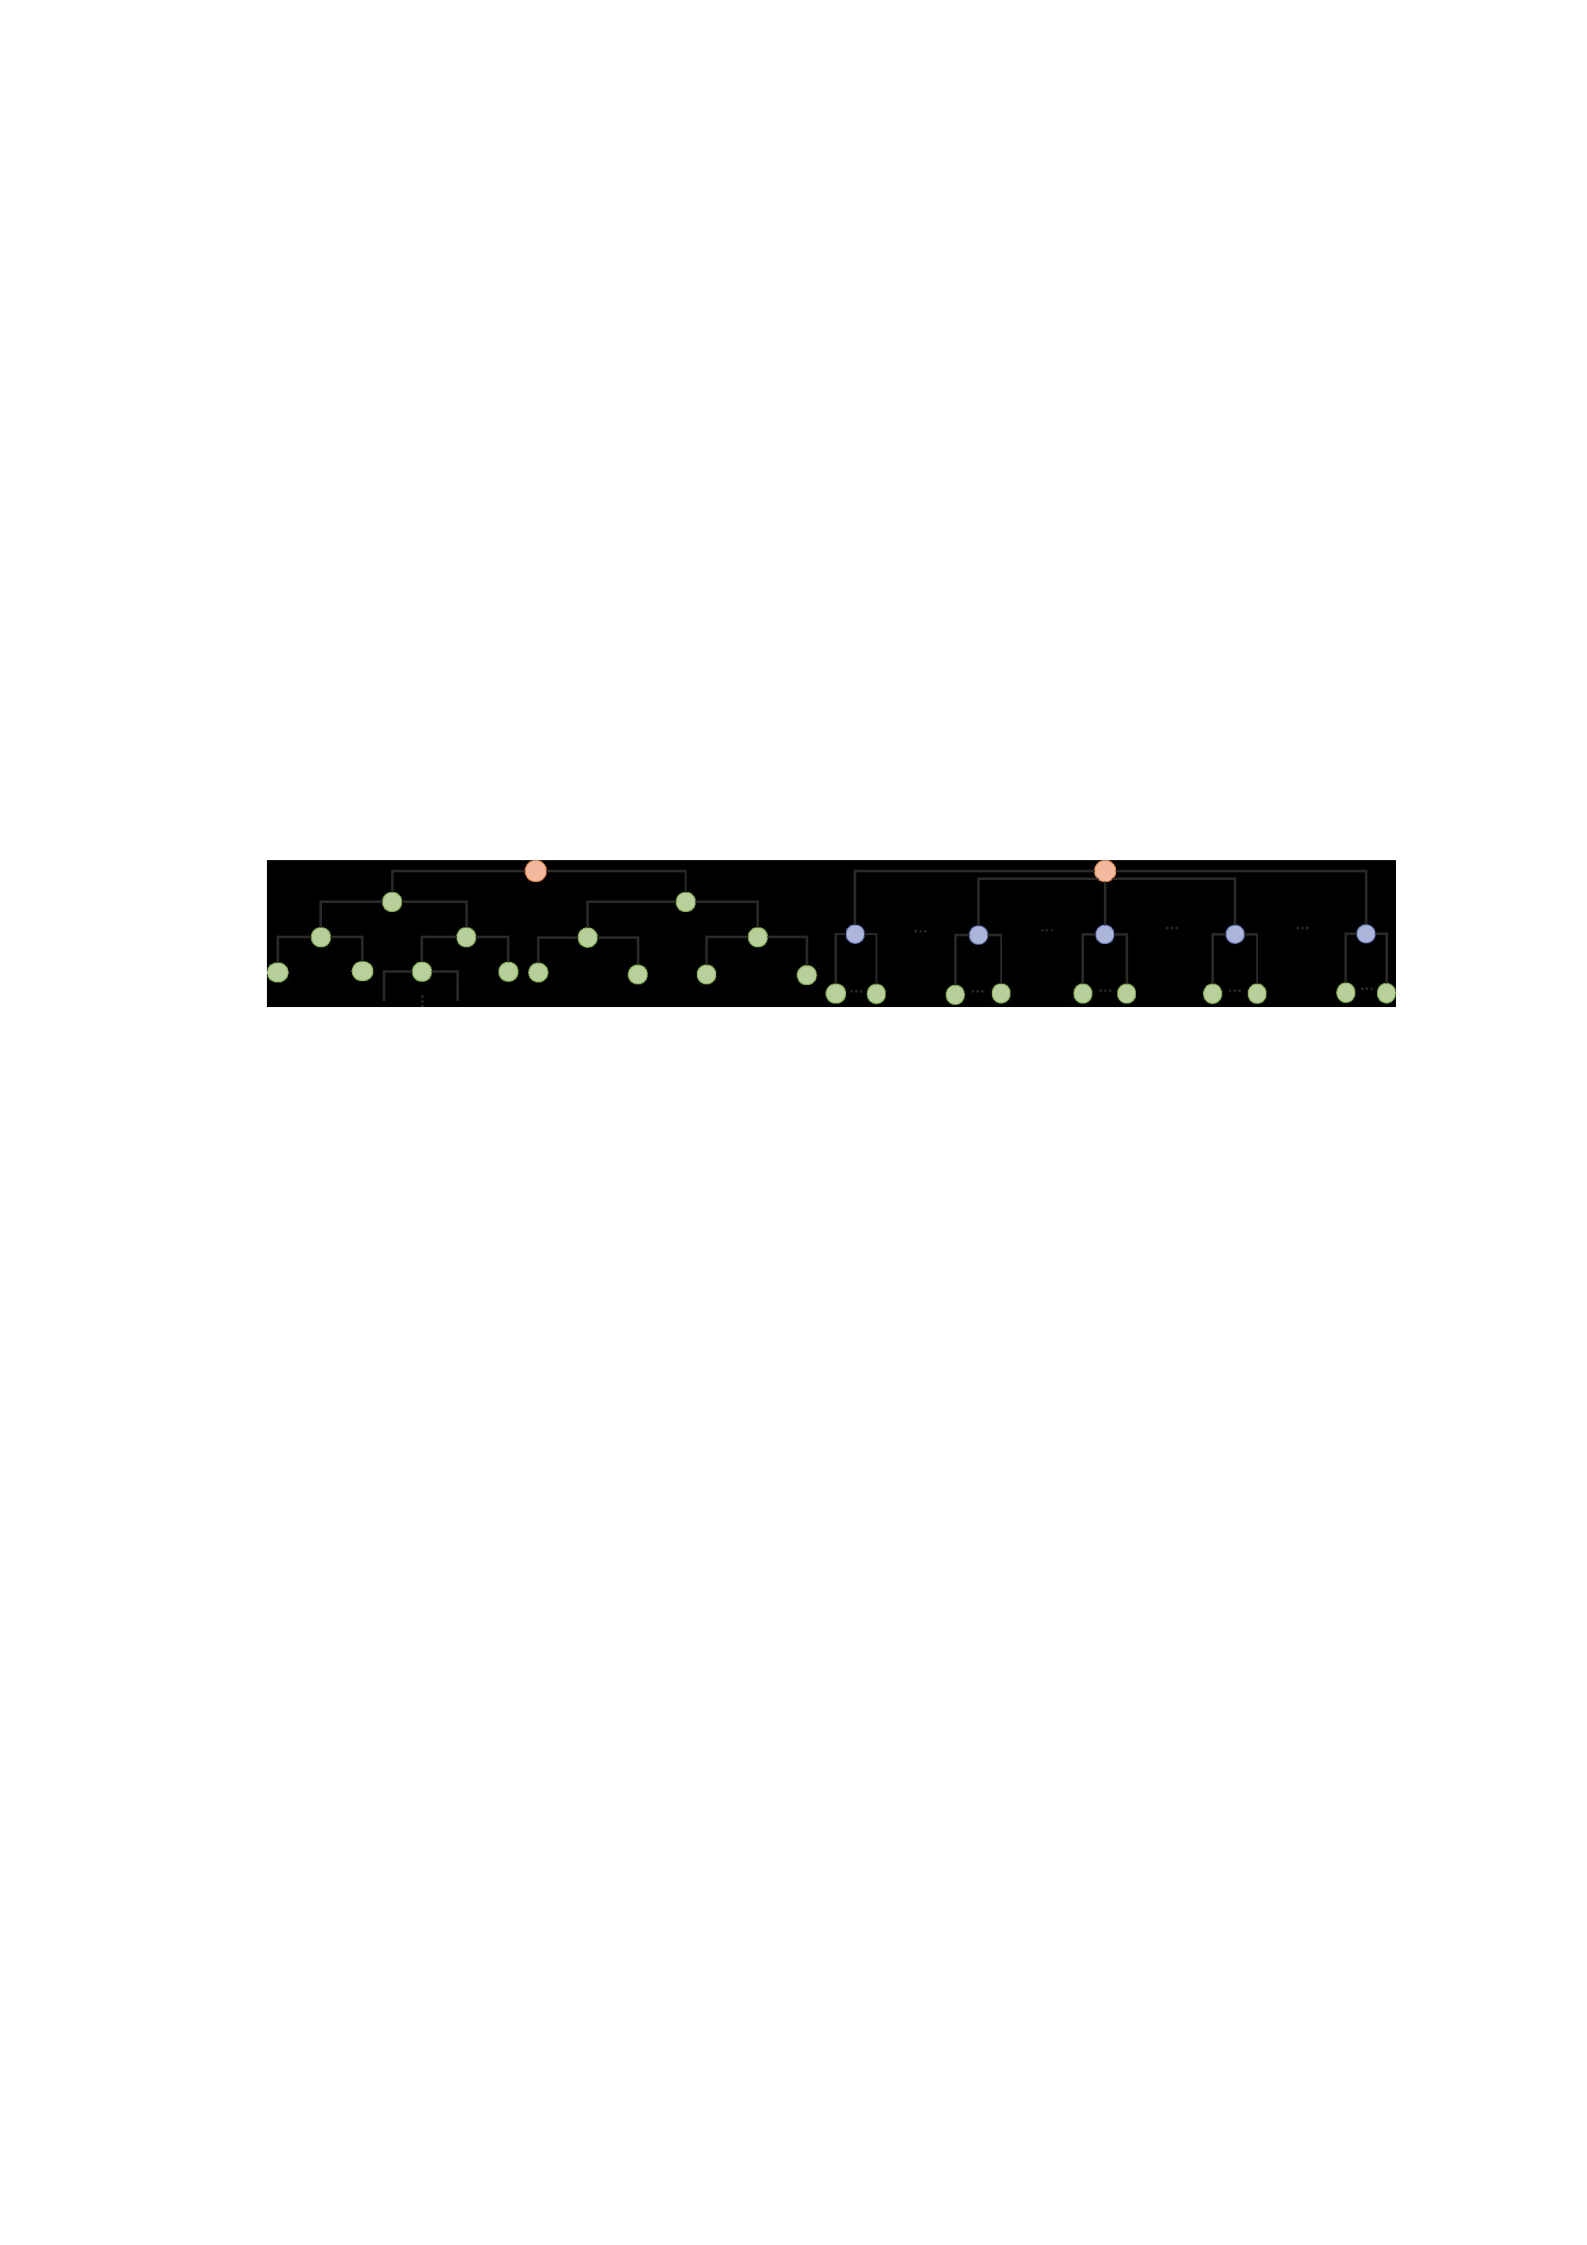
75
Insight 3. The distributed commit-and-xor scheme of Elastico has weak availability
and robustness, and it is not a perfectly unbiased randomness generator unless
paying more for the communication overhead.
4.2.3 BFT-based - Chainspace
Chainspace uses an optimal implementation of PBFT, Mod-SMaRt [174], which
accounts for the intra-part of the S-BAC protocol proposed by Chainspace. However,
Mod-SMaRt does not scale PBFT to address the issue of 1% attack. It decouples the
communication and consensus primitives, while it only reduces the
Figure 4.2 : (Left) ByzCoin implements a tree with a fixed branching factor and an increasing depth.
(Right) ByzCoinX implements a shadow tree with a fixed depth and an increasing branching factor.
overhead of the latter with an unchanged overhead of O(n2) by replacing the
process with the Validated and Provable Consensus (VP-Consensus). In addition,
the high failure probability of the intra-consensus in Elastico also takes e ects in↵
Chainspace, which restricts the use of Chainspace in a large-scale network. Note
that, the stages of Propose and View change take as input the elected leader, while
the detail of randomness generator is not provided in [5].
4.2.4 BFT-based - OmniLedger
OmniLedger combines RandHound [177] and Algorand-based Verifiable
Random Function (VRF) [71] to produce an unpredictable and unbiasable
randomness under a 25% FT for re-allocation and leader-election of each shard

76
and sub-group. Also, a new scalable BFT-based consensus algorithm, ByzCoinX, is
proposed by optimizing ByzCoin [98], which resolves the dilemma of BFT-based
1% attack in sharding, by increasing the shard size to hundreds and up to a
thousand.
Consensus Algorithm - ByzCoinX
Initially, ByzCoin [98] was the first scalable consensus protocol that combines
PoW and BFT algorithms in a tree-based structure, by means of scalable collective
signing (CoSi) [33, 178]. ByzCoinX optimizes ByzCoin in terms of the better latency
and more robust FT for a shard with hundreds of validators. Concretely, ByzCoinX
implements a shallow tree with a fixed depth-3 and an increasing branching factor.
Based on the shard size, each group leader is responsible for a group forming a sub-
tree with a fixed number of group members.
By using such a new tree-based structure, ByzCoinX can outperform ByzCoin by
a better latency for a shard with hundreds of validators due to the shorter path
from leaves to the root with a fixed depth, and a robust fault-tolerance due to the
increasing branching factor. When the number of validators goes above a threshold,
the latency of ByzCoin outperforms that of ByzCoinX due to the increasing
branching factor. On the other hand, ByzCoinX can achieve a failure probability
around 1.5% with f(c,m,p) = f(48,144,0.25), and even 1% with f(342,1024,0.3) at
the cost of latency, as shown in Fig. 10 of [99].
Insight 4. ByzCoinX improves the scalability with a lower failure probability for the
intra-consensus of OmniLedger, by sacrificing the transaction latency in large-scale
networks.

77
Generating Randomness - Combination of RandHound and VRF
In order to address the issue of Insight 3, OmniLedger implements a scalable
bias-resistant distributed randomness generator, RandHound [177], combined
with a VRF-based leader election algorithm proposed by Algorand [71].
Insight 5. The combination of RandHound and VRF su ers from the reliance on a↵
third-party initial randomness pre-defined in the genesis block. A falling-back to an
ine cient scheme occurs in the context of asynchronous networks, which limits the
salability that RandHound could have guaranteed.
4.2.5 BFT-based - RapidChain
RapidChain [206] implements a VSS-based [65] distributed random generation
(DRG) protocol to agree on an unbiased randomness. On top of the DRG protocol,
RapidChain addresses Insight 5 by introducing a deterministic random graph
where a certain fraction (50% with high probability [206]) of the number of
malicious validators can be guaranteed in the initial set (the reference committee,
similar to the final committee in Elastico). Inspired by [159], in addition,
RapidChain resolves the dilemma of BFT-based consensus algorithm in sharding,
by increasing the FT of the intra-consensus protocol up to 50%.
Consensus Algorithm - 50% BFT
RapidChain aims for higher FT (50% BFT) of the intra-consensus protocol to
address the dilemma of BFT-based 1% attack for sharding mechanisms with a
small shard size. To be specific, RapidChain runs an autonomous pre-scheduled
scheme within a shard to agree on a timeout , based on which the consensus speed
can be adjusted by the system to prevent the asynchronization. This ensures a
synchronous network in the long-term, in which a non-responsive synchronous
78
(with constant rounds) BFT-based consensus protocol with FT of 50% can be used.
Referring to (4.1), the design of 50% BFT achieves a failure probability around
1.5% with f(c,m,p) = f(17,32,0.33), and even 1% with f(51,100,0.39) at a cost of
communication overhead.
Insight 6. Di ering from ByzCoinX in OmniLedger, the ↵50% BFT of RapidChain
solves the BFT-based 1% attack by increasing the FT of intra-consensus protocol,
nevertheless, this can only suit small-sized shards (not scalable with communication
overhead of O(n2)). In addition, the pre-scheduled scheme defining the timeout is not
conceivably proved synchronous enough to run the pipelining 50% BFT.
Generating Randomness - VSS-based DRG protocol
The proposed DRG protocol by RapidChain, in fact, only implements a basic
VSS-shares scheme, where all participating validators can reconstruct the final
randomness r by the share of r (the share equals to calculated by other
validators except validator-j) received from other validators. Note that, ⇢2 Fp
denoting a finite field of prime order p, and m denotes the size of the reference
committee. As a result, the DRG protocol encounters a similar issue to that of any
other typical VSS scheme, i.e., non-scalable (even though it suits with the 50% BFT
in small-sized shards).
4.2.6 BFT-based PoS - Ethereum 2.0
Ethereum has been running publicly as the first decentralized Blockchain
platform (Blockchain 2.0 that implements a Turing-complete programming
language to develop smart contracts for the first time since 2014 [191]. With the
gradually rising demands of high throughput, Casper-FFG with sharding (Shasper)
is proposed [37] to allow the current Ethereum mainnet (a PoW-based single

79
chain, also referred to Ethereum 1.0) to migrate to the new architecture stably and
securely.
Consensus Algorithm - Solving the intra-consensus in a global way
Shasper chooses the BFT-based consensus algorithm to solve the 1% attack
issue of intra-consensus. Concretely, the Casper-FFG of Shasper can be regarded as a
variation of BFT-based PoS consensus algorithms [71, 95] with careful designs for
generating randomness, as opposed to the virtual-mining PoS consensus
algorithms [97, 194]. Note that, we assume a scalable BFT algorithm similar to
ByzCoin [98] and ByzCoinX of OmniLedger is used in Shasper.
Shasper decouples the member allocation and consensus process, which leads to
the fact that the intra-consensus within a shard also involves those validators from
other shards being the attesters. The members of attesters group associated with a
specific shard can be updated every slot. This implies that an eligible validator in
Shasper should at least store all block headers (headers is called collations in
Shasper) of all shards regardless of which shard this validator is allocated at the
beginning of every epoch. The group of attesters can be re-allocated for each
proposed collation in a times slot, which provides the strongest security but incurs
huge overhead when, 1) each shard conducts the consensus among continuously
updated validators; 2) validators need to store data of more shards; and 3) the 1-
slot-period re-allocation has to be executed.
Insight 7. The security level of Ethereum 2.0 - Shasper provides more flexible
allocation for intra-consensus than that of any other considered sharding
mechanisms, nevertheless, by incurring larger overhead.

80
Generating Randomness - Combination of RANDAO and VDF
RANDAO [2] is implemented based on the commit-and-then-reveal scheme
[136] written in a pre-defined smart contract running on the beacon chain. A
Verfiable Delay Function (VDF) as a “hash onion” [32] is implemented on each seed
to ensure the unbiased randomness, as only the serial computing can be run
regardless of the computation power owned by a validator. The design is thought
as a feasible solution to prevent malicious manipulation such as deciding not to
reveal the commitment. However, the design still su ers from three flaws:↵
• A VDF consisting of n times Hash(·) incurs a computation overhead of O(n),
which is ine cient. There have been a few advanced VDF schemes proposed
by the recent researches [189, 148, 66].
• This design is prone to the censorship attack [35]. Malicious validators can
send irrelevant transactions with a high gas fee to fill up a block. Thus, the
commitment may have to be interrupted as the gas limit of the block is run
out.
• This design is also prone to the grinding attack [47] if the seed is based on
the hash of the parent block, because validators can send arbitrary
transactions, and try to find out the most biased seed by collecting di erent↵
sets of
transactions.
Insight 8. Current design of randomness generator in Ethereum 2.0 incurs high
computation overhead, and is overwhelmingly dependent on the incentive scheme

81
(punishment). It is prone to censorship attack and grinding attack, if the attack cost is
acceptable.
4.3 Atomicity of Cross-Shard
It is of importance that a sharding mechanism can support the cross-
shardverification and cross-shard transactions for validators allocated in di erent↵
shards, according to the result shown in [99, 206] (showing that the probability of
cross-shard transactions approaches to 100% as the total number of shards
increases). Maintaining an individual global root chain may be one of the solutions
to verification, but it does not natively support cross-shard transactions without
any additional mechanism, e.g., lock/unlock operation in synchronous networks or
lock-free operation in asynchronous networks. The demand for a secure protocol of
cross-shard transactions gradually outweighs a naive mechanism lacking the
support of cross-shard transactions (even it can achieve a high improving factor N).
Di ering from the traditional database system, the support of cross-shard↵
transactions proposes a challenge to guarantee the Atomicity of the data that was
first defined in [74, 77] across multiple shards. Not only a simple payment
transaction involving withdraw and deposit operations needs to be atomically
protected, but also the demand for the complicated conditional statements attracts
more attention to the contract-oriented Atomicity.
In this section, we compare and discuss the protocols to achieve cross-
shardatomicity in the considered sharding mechanisms. We focus on the design of
crossshard transaction, including Monoxide that supports asynchronous lock-free
simple payment transactions; OmniLedger, RapidChain, and Ethereum 2.0 that
supports simple payment transactions with lock/unlock scheme; and Chainspace
82
that supports cross-shard operations for smart contracts (Elastico is vaguely
discussed as it does not support atomic-safe cross-shard transactions.
4.3.1 Monoxide - Relay Transactions
In order to bypass the overhead of lock/unlock operation that greatly
constrains the throughput and performance in regards to cross-shard transactions,
Monoxide proposes Eventual Atomicity where a single cross-shard transaction is
decoupled into an originated transaction (tl) in the local shard, and a relay
transaction (tr) being put into the outbound transactions set (and hence becoming
an inbound transaction when it is received by the destination shard). Rather than
the immediate atomicity, Eventual Atomicity features its lock-free design and takes
advantage of Chu-ko-nu mining across parallel shards in an asynchronous network,
in order to maximize the global throughput via simple message exchange. As a
result, a cross-shard transaction in Monoxide achieves an improving factor of
as it is split into the locally-executed transactions and relay transactions
expected to be outbound.
However, di ering from the cross-shard transactions that can be proactively↵
rejected by an acknowledgement from an entity (this is in charge by clients in
OmniLedger, as discussed later), the chain forking in Monoxide can cause a reversion
of the history and orphanize the block containing the tl that has been executed within
a shard. Without any existing of acknowledgement reminding the originated shard
the status of tr in the destination shard, the forking not only invalidates tr in the
destination shard (if tr has been sent out before the forking occurs), but also
invalidates all the subsequent cross-shard transactions relayed to any other shards.
This implies the following drawbacks.

83
Incompatibility to Smart Contracts. There does not exist an upper-bound of
timeout indicating if Eventual Atomicity of a cross-shard transaction has been
finalized, leading to the incompatibility of conditional transactions, e.g.,
complicated operations in smart contracts.
Additional Latency. There must be confirmation blocks delaying the execution of
the inbound transaction, i.e., tr, in order to ensure the corresponding tl in the
originated shard is finalized and unlikely reverted. Also, the absence of
acknowledgement and strict upper-bound of timeout deteriorates the latency and
throughput due to the inevitable message loss, which incurs additional latency.
Unexpected Replay. To invalidate the inbound transactions tr and all the
subsequent trs due to the failure and reversion of tl in the originated shard, and
prevent the history of all destination shards from being reverted, the history needs
to be rebuilt from the genesis block of each shard. This incurs unexpected overhead
even if a checkpoint scheme is introduced, e.g., the shard pruning in OmniLedger
[99].
Insight 9. In order to maximize the global throughput, Eventual Atomicity achieves
the lock-free asynchronous cross-shard transactions at the cost of incurring
Incompatibility to Smart Contracts, Additional Latency, and Unexpected Replay.
4.3.2 Elastico - No cross-shard Transactions
The elected leader of the traditional PBFT consensus algorithm in each shard
finalizes and sends an agreement in regards to local transactions to a global subset,
i.e., the final committee, as discussed in Section 4.2.2. A final global block is stored
in the global ledger and broadcast to all validators among the network, so that
validators can verify the transactions from other shards. However, Elastico does
not provide a secure protocol to ensure the atomicity across shards via this global
84
ledger. There will be a fund loss as an unexpected dead-lock occurs if the cross-
shard transaction sent to the destination shard gets rejected.
4.3.3 OmniLedger - Atomix Protocol
To simplify the cross-shard-atomicity, OmniLedger proposes a client-driven
Atomix protocol that is UTXO-based, where the communication overhead is shifted
outside the shards. This indicates that the clients act as a gateway exchanging
messages across multiple shards, by paying an extra cost of overhead themselves.
Consequently, a cross-shard transaction containing inputs from one single input
shards (IS) and output shards (OS) can achieve an improving factor of , as
this transaction is only stored in two shards, i.e., this IS and OS. On the other hand,
inputs and outputs of multiple ISs and OSs result in the transaction being stored
among the involved shards, i.e., an improving factor of N = 1 in the worst case that
the entire network is involved.
Insight 10. Atomix Protocol is, in fact, a band-aid at best. It sacrifices the support of
light-weighted clients, but requires powerful performance for a client-driven
exchange of messages.
Insight 11. Atomix Protocol has poorer support for UTXO-based cross-shard trans-
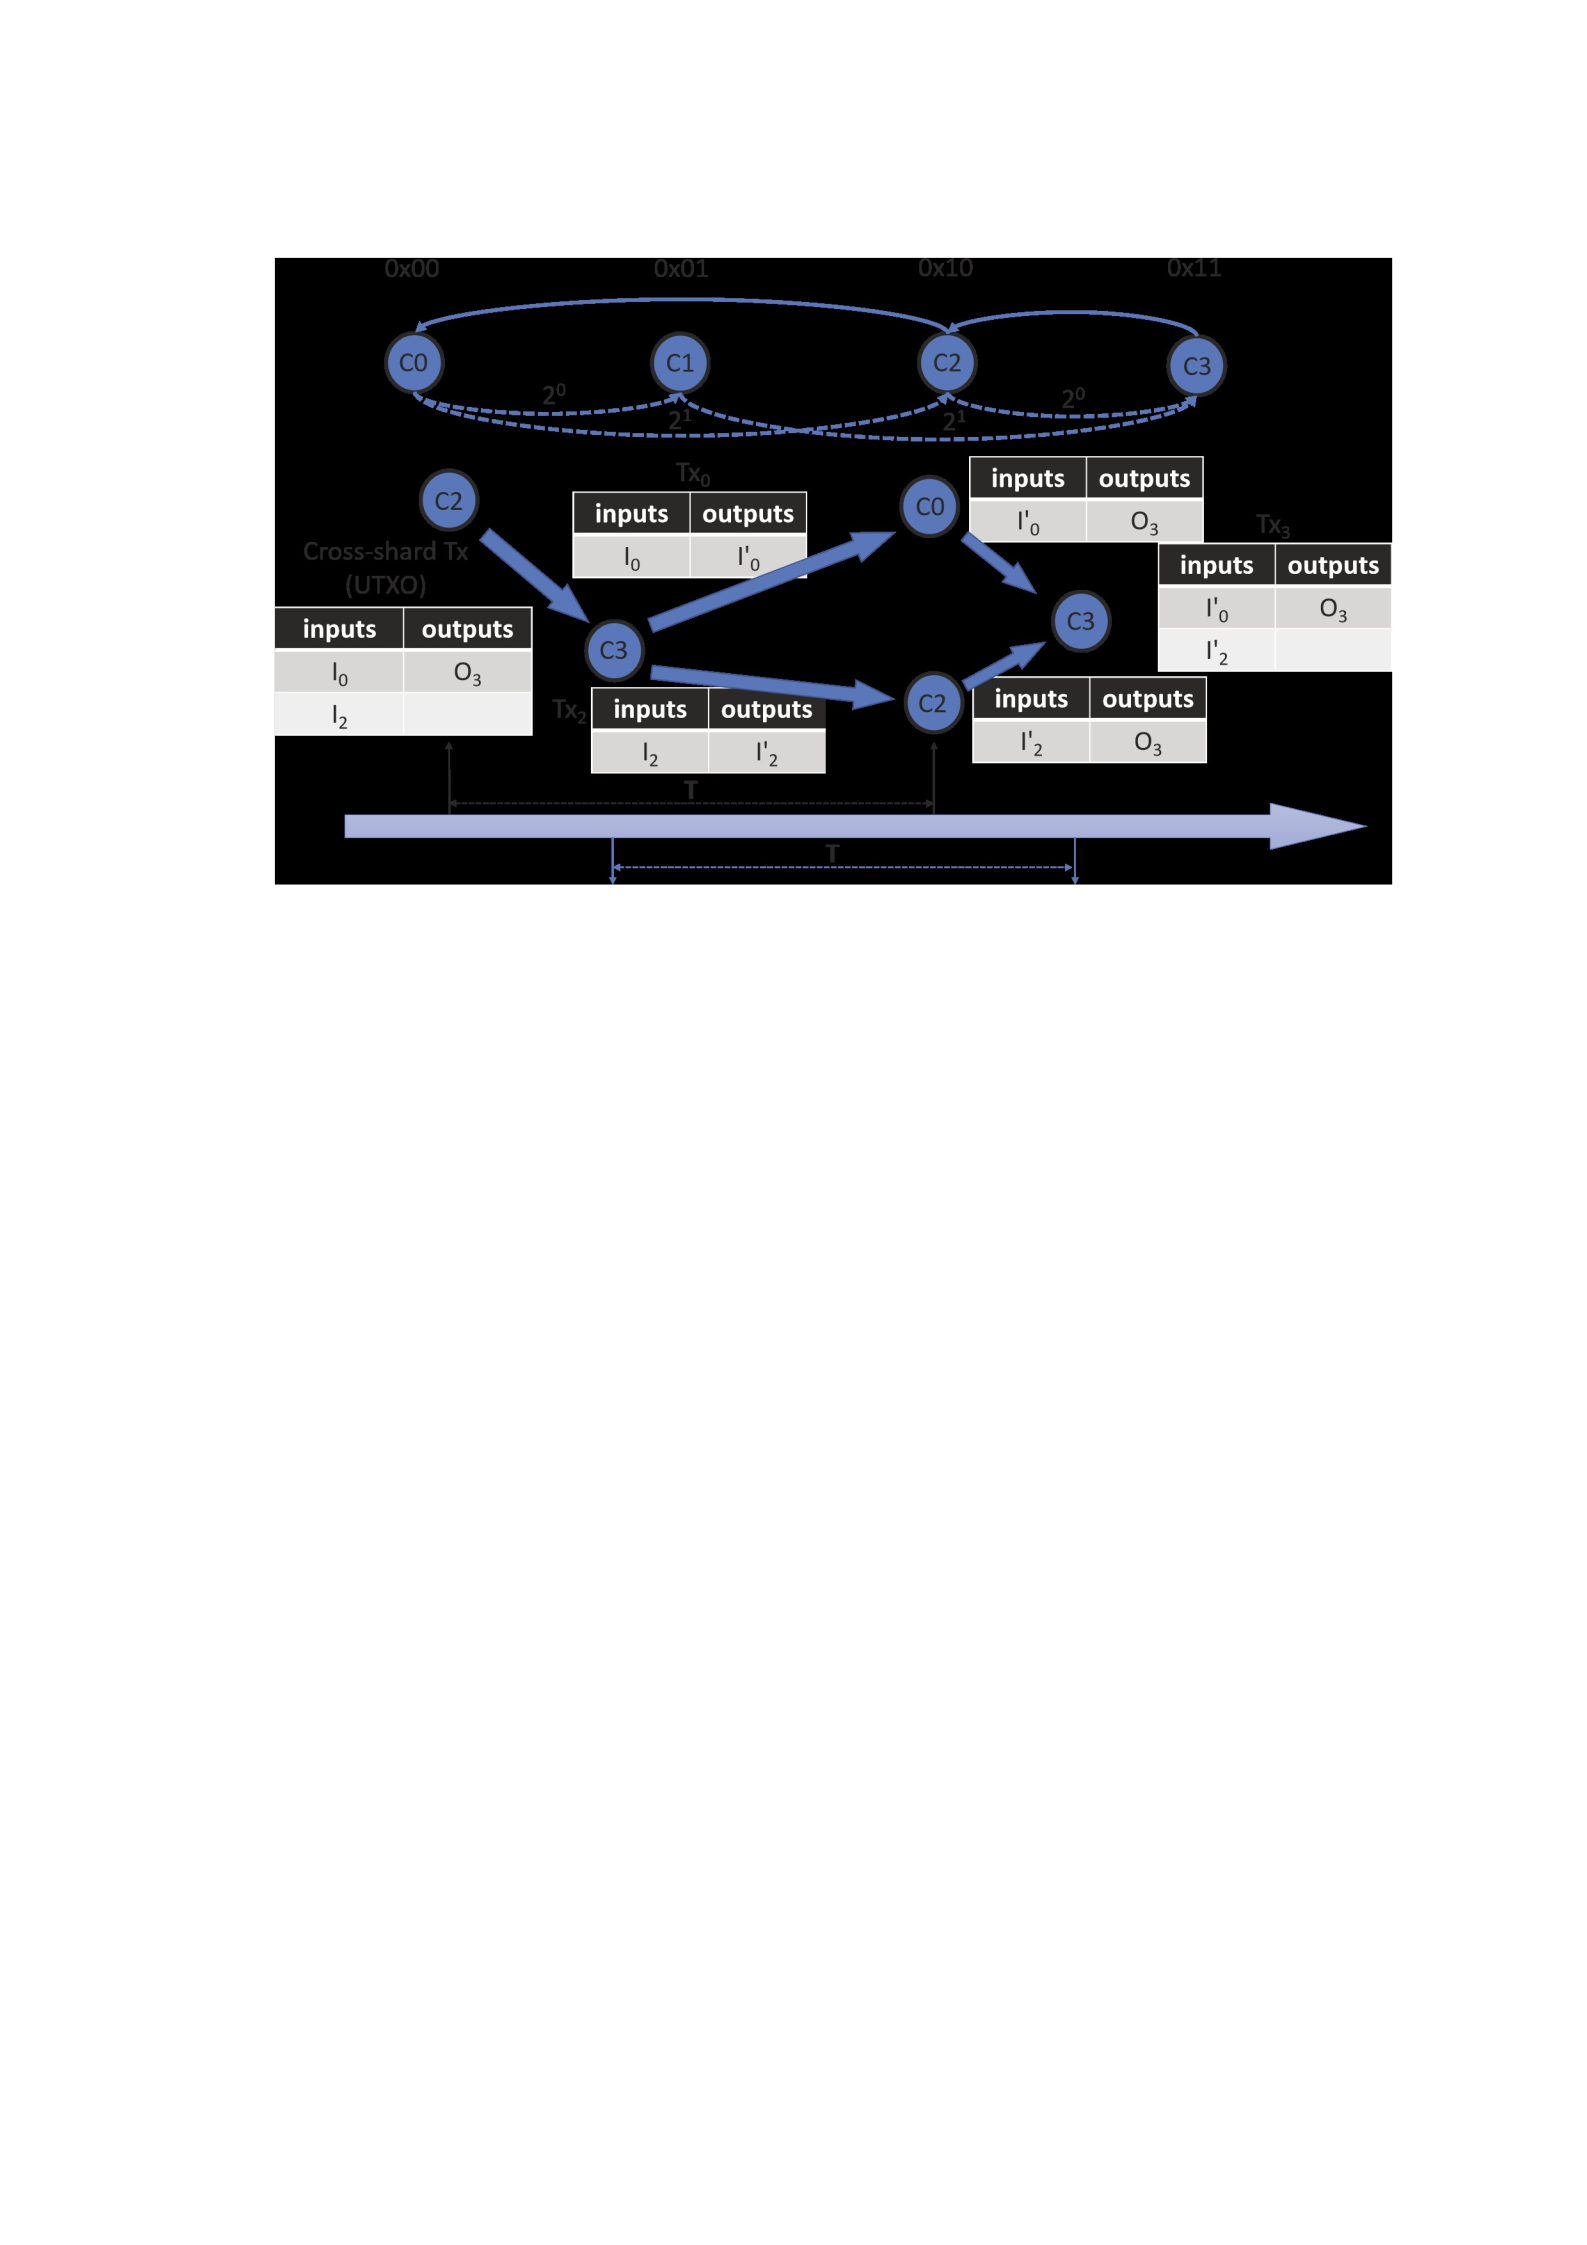
85
Figure 4.3 : (Top) Each committee (shard) maintains a routing table containing log2 n other
committees. The routing table improves the e cient communication among multiple shards, as
described in Section 4.4.2. Committee C0 can locate C3 (via C2) responsible for transactions with
prefix 0x11. (Bottom) To cross-validate a UTXO-based cross-shard transaction requires this
transaction to be spilt in three-way confirmation.
actions as the number of participating shards increases, which is unable to take full
advantage of the UTXO format.
4.3.4 RapidChain - Three-way Confirmation
To verify a UTXO-based cross-shard transaction, there proposes a three-way
confirmation in RapidChain to optimize the Atomix Protocol in OmniLedger, as
shown in the bottom part of Fig. 4.3. Concretely, k 1 sub-transactions (Tx0 and Tx2)
destined for each committee that stores its own Ii of the cross-shard transaction,
with Ii as the inputs and Ii0 as the outputs, respectively, and k is the number of
inputs of this cross-shard transaction, are created by the output committee, i.e., C3
as the Cout. After passing the verification on each input committees, i.e., C2 and
86
C0 as the two Cin(s) of the original cross-shard transaction, Tx0 and Tx2 are stored in
their own local ledger, respectively. Finally, all Cin(s) send the corresponding
transactions back to C3, and end up aggregating Tx3 to be finally stored in the local
ledger of C3.
In order to determine the improving factor N, we assume that a single
committee can only be either a sender committee or a receiver committee
(practically a shard can be both a sender or a receiver) at the same time for
simplicity. In the worst case where a full-sized cross-shard transaction contains
only the input from a single committee, Cin has to send this full-sized transaction
twice (each corresponds to invoking the inter-communication once), i.e, 1-st and 3-
rd handshaking. On the other hand, the period from Cin sending Cout the cross-shard
transaction to it finishing verifying the sub-transactions received, equals to the
period from Cout finishing verifying the original cross-shard transaction to it
finishing verifying the confirmations sent by Cin, i.e., one block period. It is because
the original cross-shard transaction is spilt into,
• the sub-transactions that are supposed to be stored in the local ledger of each
Cin (a full-sized of the original cross-shard transaction with inputs from a
single committee or inputs involving all committees);
• the final transaction that is supposed to be stored in the local ledger of Cout
(another full-sized of the original cross-shard transaction) at the end of the
protocol.
Consequently, either of these two kinds of transactions accounts for the
intrathroughput of a committee, hence one block period, as shown by the T at the
bottom of Fig. 4.3. Therefore, an improving factor of can be achieved.
87
Insight 12. The routing table and three-way confirmation resolve the issue of
OmniLedger, by significantly reducing the overhead of communication, even with a
large number of participating shards in a single UTXO-based cross-shard transaction.
However, by polluting specific routing tables, the eclipse attack [80] becomes a
concern.
4.3.5 Ethereum 2.0 - Using Receipts
Having known the beacon chain, validators can not only address the issue of
intraconsensus, but also address the issue of cross-shard-atomicity, i.e., cross-
verifying the normal transactions in each shard the validators care about, and
enabling the cross-shard transactions. Note that, Shasper so far can only support a
simple account-based (as opposed to the UTXO-based) payment transaction, while
the design contract-oriented cross-shard transaction has not been finalized and
presented.
The cross-shard transactions in Shasper rely on the receipts. Receipts
correspond to accepted cross-shard transactions that are used to verify and log the
validity of the transactions’ operations. Also, the result of these operations can be
obtained by the involved validators conducting cross-validation in the destination
shards. By means of receipts whose identities are contained in Txgroup root field
(Receipt root), the cross-shard transactions are split into multiple sub-transactions
being executed in the originated and destination shards, respectively (the original
transaction, a proof-of-receipt, and a proof-of-response). This can be regarded as a
variation of the synchronous lock/unlock scheme implemented in OmniLedger and
RapidChain, while the receipts take the actual role of the lock. Thusm, a cross-shard
transaction that is account-based in Ethereum 2.0 - Shasper can achieve an
improving factor of due to the preliminary transaction, proof-of-receipt, and
proof-of-response.

88
Insight 13. Ethereum 2.0 - Shasper introduces account-based cross-shard
transactions by implementing the global (stored by all validators) beacon chain to
exchange the essential message, i.e., the receipts and proofs. However, Shasper cannot
be more than a transitional version due to the disadvantage of possible overhead.
4.3.6 Chainspace - The inter-part of S-BAC
S-BAC refers to Sharded Byzantine Atomic Commit, whose intra-part makes use
of an optimal PBFT, Mod-SMaRt, to handle the intra-consensus process; see Section
4.2.3. Upon the intra-consensus being finalized within a shard (Chainspace
allocates nodes in di erent shards based on the objects management, as described↵
in Section 4.4.6), the elected leader of the shard, the BFT-Initiator, takes
responsibility for the atomicity of cross-shard transactions. It is worth noting that
Chainspace makes use of the concept of BFT to ensure such atomicity, which
constitutes the inter-part of S-BAC. It resembles the Atomix Protocol in
OmniLedger, with a crucial optimization where BFT consensus process must be
conducted instead of a naive client-driven model. However, similar to the problem
the Atomix Protocol of OmniLedger has encountered, i.e., Insight 11, the improving
factor upon a crossshard transaction can be ranged from N = n to N = 1 with T
containing only one input object and no object being output, and T involving all
objects around the
entire network, respectively.
4.4 General Improvements
In this section, some general key challenges and improvements particularly
proposed by the considered sharding mechanisms are listed. Such improvements
can be generally implemented to address the new issues the considered sharding
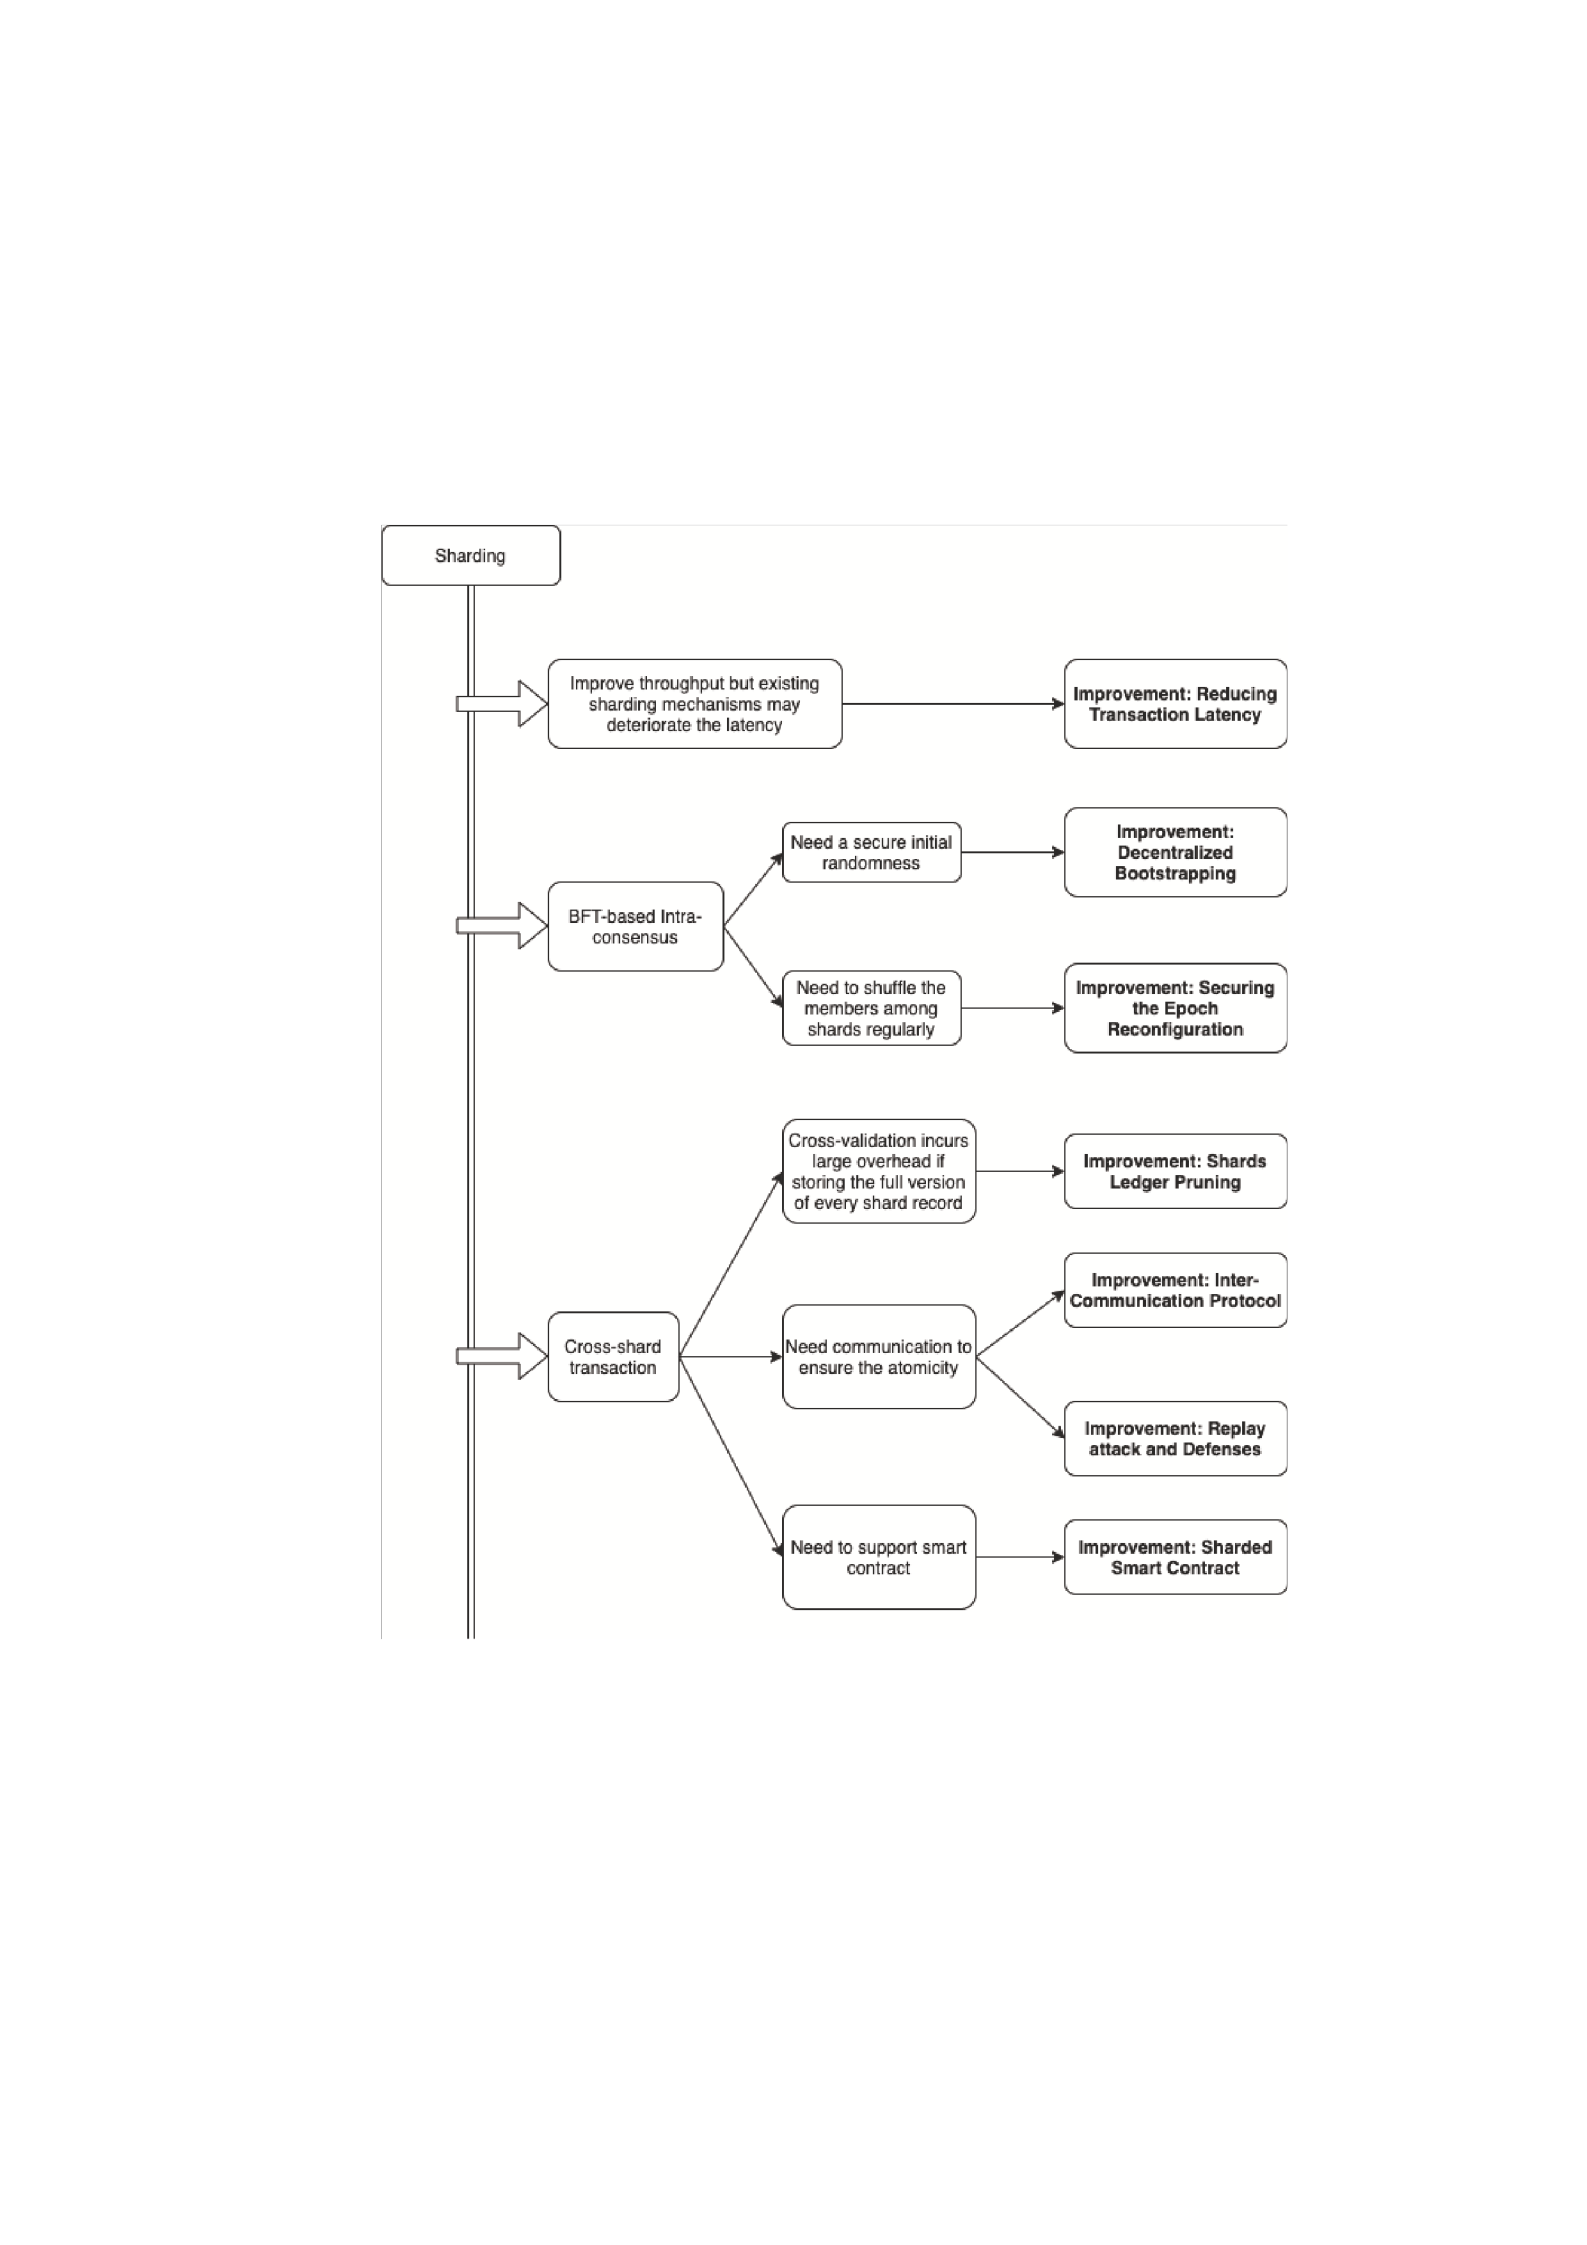
89
solutions pose to the entire system, as shown in Figure 4.4. They include
transaction latency, inter-communication protocol, shards ledger pruning,
decentralized bootstrapping, securing the epoch reconfiguration, sharded smart
contract, and replay attacks and defenses against cross-shard transactions.
Figure 4.4 : The pain points that each of the proposed improvements are expected to solve
4.4.1 Reducing Transaction Latency
Apart from the throughput, the transaction latency, referring to how long a
transaction is deterministically confirmed and finalized, is most likely more
sensitive to individual users. It has been shown that the BFT-based 1% attack
(refers to Section 4.2) can be either resolved by implementing a scalable BFT

90
consensus, e.g., OmniLedger and Ethereum 2.0, or increasing the FT within a single
shard, e.g., RapidChain. However, it remains the issue of transaction latency, as
described below.
•The transaction latency deteriorates as a scalable BFT consensus features a
large scale shard size to address the 1% attack, according to the evaluation
shown in [98, 99]. Thus, Omniledger introduces the trust-but-verify
transaction validation scheme running within each shard to provide the real-
time transaction confirmation time, which can also be implemented in any
compatible sharding scheme, such as Ethereum 2.0. Concretely, an optimistic
validation and a core validation are conducted. Those users who are care
more about the latency than security can choose to accept transactions after
the optimistic validation is passed.
Insight 14. The real-time transaction latency is achieved by sacrificing the security,
as the further 1% attack can still happen in optimistic groups. Similar to IoTA [152],
this real-time transaction latency can only be used in specific scenarios with lower
security requirements.
•The transaction latency deteriorates as a non-scalable 50% BFT consensus
incurs larger communication overhead. Thus, upon the 50% consensus only
agreeing on a digest of the block. RapidChain implements the information
dispersal algorithm (IDA)-based gossip protocol [9, 10] to transmit large
payload more e ciently. Concretely, the sender divides the original message
into some n-equal-sized chunks, followed by applying an (m,n) erasure code
scheme to encode the n chunks to m chunks. As a result, each node can
reconstruct the original message by receiving valid n chunks from its

91
neighbors with the help of some proofs, e.g, the MPT proofs, hence
significantly reduces the latency.
4.4.2 Inter-Communication Protocol
Di ering from the protocol to achieve the ↵atomicity-cross-shard, the inter-
communication protocol focuses on the overhead of data transmission among
shards. The related schemes discussed in this chaoter include the following two
major types. • A global root chain acting as a message distributor is implemented,
while each validator (or miner in the context of Monoxide) needs to store this
chain. Sharding mechanisms using this kind include Ethereum 2.0, Monoxide with
identical PoW targets, and Elastico.
Insight 15. The bottleneck is shifted to the global root chain due to its single-chained
structure, as opposed to sharded structure. This can only be a transitional version but
not a real solution.
• The most straightforward way is used by OmniLedger and Chainspace, i.e.,
full-mesh connection. This requirement tends to hold in those latency-
sensitive systems, which incurs an considerable overhead.
In order to bypass the full-mesh connection, RapidChain proposes a novel
intercommunication protocol based on a routing table stored by each validator; see
the top side of Fig. 4.3. It is inspired by Kademlia-based [126] routing protocol,
where each validator in a shard maintains a routing table containing all members
of its shard as well as log2 log2 n validators of other log2 n shards which are distance
2i for 0 i log2 n 1 away. The inter-communication is conducted by having all

92
validators in the sender shard send messages to all validators on the receiver side.
By taking advantage of P2P network, the communication overhead can be
significantly reduced.
4.4.3 Shards Ledger Pruning
The reason most of the existing Blockchain system with a single-chained
structure tends to store the full version of its chain is that they intend to improve
the communication and computation overhead of censorship and audition. Storing
a full version of ledger of every shard incurs an unacceptable overhead of disk
storage to validators, as validators need to track the history of each shard in order
to support the cross-shard transactions, as well as the re-allocation
(bootstrapping) during each epoch. To solve this, OmniLedger proposes the design
of state blocks (SB).
SBs of a shard summarizes the state as well as all transactions of its shard
associated with each epoch. The design of SBs is similar to stable checkpoints in
PBFT [40], fast-sync mode in Ethereum [38], and stable checkpoints of Node
HashChains in Chainspace [5]. According to the evaluation in [5], such kind of
pruning incurs an overhead of O(m + logT) for a partial audit and O(T) for a full
audit, where m denotes the shard size, and T denotes the number of transactions.
The partial audit allows any users to obtain a proof to verify the existence of any
transactions in any shards; the full audit allows a full verification by replaying the
entire history of a shard. However, the design of SB raises two issues, 1) the
overhead of transaction proofs might become the bottleneck, but it can still be
relieved by introducing the Simple Payment Verification (SPV) [135, 38], several
multi-hop backpointers [138, 21, 158], or Proofs of Proof of Work (PoPoW) [93,
92]; and 2)
93
Insight 16,
Insight 16. The design of State blocks faces the same problem as that of the Atomix
Protocol in OmniLedger and light-client protocol in Ethereum 1.0 (if used in
Ethereum 2.0), i.e., shirking the most important duty to the client side.
4.4.4 Decentralized Bootstrapping
For sharding mechanisms involving a randomness generator that is responsible
for a PoW-based entry ticket in the BFT-based intra-consensus protocol, it is
important to select the initial set with an honest majority, e.g., the final committee
in Elastico, and the reference committee in RapidChain5.
Thus, RapidChain proposes a decentralized bootstrapping in the form of
samplergraph election network [206], with only a hardcoded seed and some
network settings. In such an election network, participating validators are
uniformly distributed into a few groups, within each of which a PoW-based result is
computed by each member based on the randomness generated by the VSS-based
DRG protocol (Section 4.2.5) and its identification ID. Based on the result, a
subgroup can be obtained for each group. Finally, a unique root group (it randomly
selects the members of the reference committee) can be obtained with 50% honest
majority (high probability), when this process is iterated. Consequently, the
communication overhead can be improved from (⌦n2) to O(npn) with n denoting
the total number of participating
validators.
5 OmniLedger eliminates the necessity of an initial global set that responsible for verifying the
PoW result, by using RandHound and VRF. However, an initial global randomness is still needed to
derive VRF. Ethereum 2.0 builds the design on top of PoW-based mainnet, where the PoS-based
Casper is used instead of PoW.

94
4.4.5 Securing the Epoch Reconfiguration
For sharding mechanisms running a BFT-based intra-consensus protocol, (new)
validators have to be swapped-out and re-allocated in other shards every epoch in
order to prevent attacks from slowly adaptive adversaries, i.e., attacker can corrupt
or Distributed Denial of Service (DDoS)-attack validators, but it takes a bounded time
for such attacks to take e ect. This indicates that the epoch length should be↵
carefully designed to be lower than the bounded time.
Recall that Elastico and Chainspace do not provide such a solution, while
Ethereum 2.0 solves the intra-consensus with a global validator pool by frequently
updating the member participating in the intra-consensus protocol for each shard.
Both of them require validators to track the status of each shard to speed up the
reconfiguration phase. OmniLedger implements a random permutation scheme to
swap-out the validators, ensuring the number of validators being swapped is
bounded by k = logn/m at a given time, where n denotes the total number of
participating validators; m denotes the number of shards. Here, new validators that
require to register their ID on a global identity Blockchain are also assigned to
random shards. As such, the number of remaining honest validators can be su cient
to reach consensus while some are swapped-out, thus the idle phase can last shorter
to improve the throughput. However, this scheme incurs a significant delay and
scales moderately, which cause 1-day-long epoch that does not suit highly adaptive
adversaries (when the bounded time becomes smaller).
In contrast, RapidChain proposes a light-weighted reconfiguration protocol
based on the Cuckoo rule [19, 166], where only a constant number of validators are
allowed to move between committees in each epoch. To be specific, the reference
committee
(Cr) announces a PoW puzzle based on the randomness generated in epoch i1

95
(Ri) by the DRG protocol, thus validators that wish to participate in epoch i + 1
(including those that have participated in epoch i 1 and i) can solve the puzzle and
inform Cr by the end of epoch i. During epoch i + 1, Cr defines the active and inactive
lists of validators of epoch i + 1, and swap-out a constant number of validators
from one to another committee based on Ri+1 generated in epoch
i. Finally, Cr agrees on a reference block stored in the local ledger of Cr, and
broadcasts it to the entire network. This design, compared to that of OmniLedger,
incurs less overhead and allows a more frequent epoch reconfiguration to suit
more highly adaptive adversaries.
4.4.6 Sharded Smart Contract
None of the considered sharding mechanism has achieved the smart-
contractoriented sharded so far except Chainspace introducing such functionality
for the first time, by using a new transaction structure based on new atoms Objects
denoted as o. Objects defines a series of new parameters including input objects x,
output objects y, reference objects r, contracts c as special objects, procedures
proc, and checkers v. By following a serious of operations, the atomicity of smart
contracts can be ensured in Chainspace.
Insight 17. By modifying the transaction structure and involving the concept of the
new atoms and objects, it can safely shard a smart contract with strong atomicity, but
at the cost of considerable overhead and hence low throughput.
4.4.7 Replay Attacks and Defenses against Cross-shard Protocols
As raised by [173] for the first time, the replay attacks and defenses against
BFT-based cross-shard protocols have attracted increasing attention (i.e.,
Monoxide is Nakamoto-based and has a lock-free cross-shard protocol, thus
96
immune to this kind of replay attacks). By utilizing the property of unanimous
voting, the replay attacks strategy has the ability to compromise the cross-shard
atomicity, and launch the double-spending attack with a low cost. Specifically, each
shard participated in a cross-shard transaction needs to transmit its own decision
(i.e., accepting/aborting the transaction) to the other participants, in order to
lock/unlock the internal objects and thus guaranteeing the cross-shard atomicity.
However, an e ective replay attack can be easily launched by conducting the↵
following strategy. Here, we consider an attacker and a honest client who is about
to sending a cross-shard transaction T(x1,x2
) ! (y1,y2,y3) where xi represents the input
objects managed by shard-i, and yi represents the output objects managed by
shard-i.
1. Eliciting and invalidating the decision-message sent from shard-1: The attacker
races the client by sending a T0(x2,···) to shard-2 so that the involved objects
will be locked in shard-26. The attacker quickly follows up by submitting T to
shard-1 and shard-2. As soon as T reached shard-1, an accept(T) is sent out
and can be pre-recorded by the attacker. In contrast, T will be invalidated in
shard-2. An abort(T) will be sent out and pre-recorded by the attacker due to
the locked objects of shard-2.
2. Compromising the consistency: At any time shard-1 is about to sending the
decisions, the attacker can race shard-1 by broadcasting and replaying the
pre-recorded message which always opposes to shard-1. As a result, the input
objects of shard-1 is still active, while new output objects have been created
in shard-2 and shard-3, i.e., the consistency of the system is compromised.
6 The destination of T or T0 is replaced by a self-driven client in OmniLedger as such a client is
considered to be the handler to achieve the cross-shard atomicity.

97
Authors of [173] also pointed out the reasons making the replay attacks possible.
First ( 1 ), there lacks a way for the input shards to know the correspondence
between a protocol message received (i.e., accept(T) or abort(T)) and a specific
transaction T. Second ( 2 ), there also lacks a way for the output shards to know the
context of a specific transaction as they are, in fact, excluded from the intermediate
processing.
To address the limitations, a modified version of Chainspace, Byzcuit [173], is
proposed along with two new features. In regards to 1 , a sequence number scheme is
applied to each transaction to ensure the correspondence, while a dummy object of
each output shard is added to the input field of a transaction (i.e., forcing the output
shards to participate in the intermediate processing) in order to address 2 .
Insight 18. The proposed replay attacks and defenses against BFT-based crossshard
protocols is significant and worth more attraction. However, the sequence number
scheme still has a synchronization issue, and the dummy object remains poor at the
scalability, both of which strive for optimization.
4.5 Challenges and Future Trend
We have elaborated on the designs and protocols of each considered sharding
mechanisms, i.e., Monoxide, Elastico, OmniLedger, Rapidchain, Ethereum 2.0, and
Chainspace, in terms of the intra-consensus, cross-shard atomicity, and general
improvements, based on which a comprehensive comparison is presented in Tables
4.1 and 4.2.
We conclude that RapidChain and Ethereum 2.0 implement optimizations that
reduce restrictions of Elastico and OmniLedger, which leads to RapidChain and
Ethereum 2.0 being the most advanced BFT-based sharding mechanisms in terms

98
of throughput and cost. On the other hand, Monoxide pushes the upper-bound of
throughput to Mega level, and opens up a new direction of the Nakamoto-based
sharding mechanisms. Chainspace has plenty of room for performance
improvement for sharded-smart contract.
Furthermore, we point out the challenges remaining unsolved practically, as well
as the future trend being discussed.
99
Chainspace
Partial-sync
Attackersbehave
arbitrarily,
Uncoordinated
majority
33
%
25
%
Mod-SMaRt
implementationof
PBFT
Unknown
Unknown
One-offallocation
basedonobjects
N/A
No
Object-driven,
contract-sharded
Yes
Sync,Lock/Unlock
O(m2+n)
O(|C|+|Cnh |)
Insights2,11,17,
18
Ethereum2.0
Partial-sync
Attackersbehave
arbitrarily,
Uncoordinated
majority
33
%
33
%
BFT-basedPoS
Yes.Each Ris
generatedbyusing
RANDAO+VDF
onthebeacon
chain
1
.Selectthepro
-
poser/
attesters;
2
.Selectthe
validatorsfo
r
checkpointingfro
m
theglobalpool.
Allocationbased
on R
Yes
Yes,themainnet
andbeaconchain
Account
Yes
Sync,Lock/Unlock
O(m2+n)
⌦
(|C|+n|H|+|Cg|)
⇠
O(n|C|+|Cg|)
Insights7,8,13,
15
,18
RapidChain
Sync
Partial-
sync
Attackersbehave
arbitrarily,slowly
adaptive
50
%
33
%
50 %BFT
Yes. Ri+1 is
generatedbythe
reference
committeeatthe
endofepochi
1
.Theseedof
PoWpuzzlefor
thenextepoch;
2
.Selectthe
intra-leader;
3
.Bootstrapping;
4
.Epoch
reconfiguration
Allocationbased
ontheresultof
PoWpuzzles
Yes,swapping-out
aconstantnumber
ofnode
Yes,reference
Blockchain
UTXO
Yes
Sync,Lock/Unlock
O(m2+mlog 2n)
O(|C|+|Cr|)
Insights6,12,18
Intra
Total
OmniLedger
Partial-sync
Attackersbehave
arbitrarily,slowly
adaptive
33
%
25
%
ByzCoinX
Yes. Ri+1 is
generatedbyusing
RandHound+
VRFinthe
beginningofepoch
i+1
1
.Selectthe
intra-leaderand
thesub-group;
2
.Epoch
reconfiguration;
3
.trust-but-verify
validation
Allocationbased
on R
Yes,swapping-out
boundedby2/3at
agiventime
Yes,identity
Blockchain
UTXO
Yes
Sync,Lock/Unlock
Olog
(2m+n)
Insights4,5,10,
11
18
,14,16,
Elastico
Partial-sync
Attackersbehave
arbitrarily,slowly
adaptive
33
%
25
%
PBFT
Yes. Ri+1 is
generatedbythe
finalcommitteeat
theendofepochi
1
.Theseedof
PoWpuzzlefor
thenextepoch;
2
.Selectthe
intra-leader
Allocationbased
onthe
least-significant
bitsoftheresult
ofPoWpuzzles
Unsafe
Yes,aglobal
ledger
UTXO
No
N/A
O(m2+n)
O(n|C|)
Insights2,3,15
Monoxide
Partial-sync
Attackersbehave
arbitrarily,
Uncoordinated
majority
50
%
50
%
PoW-based
Chu-ko-numining
No
N/A
One-offallocation
basedonthe
identity(address)
ofnodes
N/A
Mixedtargets:No;
Identicaltargets:
Yes
Account
Yes
Async,Lock-free
MixedPoW
targets:
O(m+nlog 2n)
IdenticalPoW
targets: O(m+n)
⌦
(|C|)
⇠
O(|C|+n|Ch|)
Insights1,9,15
Networkmodel
Threat
model
Security
model
Intra
Total
Intra-ConsensusProtocol
Existence
Randomness
(R)
Use
Allocation
Members
SafeEpoch
reconfiguration
AdditionalglobalBlockchain
Transactionstructure
Support
Method
Communi-
cation
Storage
FeaturesandRestrictions
FT
Cross-shardTx
Complexity
Table4.1:Acomparisonregardingtheprotocols(rangedfromthesettingsofintra-consensustothedesignofcross-shardatomicity,aswellasthe
correspondingoverhead)amongthediscussedshardingmechanismsinthischapteriselaborated.
100
Table4.2:Acomparisonamongthediscussedshardingmechanismsinthischapteriselaborated.Theresultsofthroughputandcostareshownin[205].
Thelatencyisalsoobtainedandshown(N/A:NotAvailable).
Chainspace
<10 2
<10 2
Exists,details
notprovided
2
s
Unknown
1⇠n/2
<
400
tps
N/A
Ethereum
2.0
<29
<10 2
oneweek
Unknown
n/3
ktps
134
0.4⇠0.45
USD/hour
RapidChain
<28
(2 2-1) ⇠28
one
day
70
s
n/2
ktps
128
0.2⇠0.3
USD/hour
OmniLedger
<26
22⇠210
oneday
⇠
100
s
1000
s
1⇠n/2
28.8
ktps
0.2⇠0.3
USD/hour
Elastico
<10 2
<10 2
⇠min
10
<900
s
N/A
n
48ktps
30⇠35
USD/hour
Monoxide
210 ⇠218
10 2⇠10 4
N/A
23
s
N/A
n/2
1.23⇠
2.56
Mtps
30⇠80
USD/hour
Shards’settings
Numberof
shards (
)
n
Shardsize (
)
m
Epochlength
Transaction
confirmation
Epoch
reconfiguration
Improvingfactor
Throughput
Cost
Latency
Upper-bound

101
4.5.0.1 Future Trend for Reducing the Overhead
Three common pitfalls in existing sharding mechanisms prevent the system
from being horizontally scaled to the theoretical upper bound due to the
communication and storage overhead.
•An existing global chain that is needed to be stored by all participating
miners/validators. Such a global chain tends to be responsible for all global
operations, such as generating randomness, cross-validating transactions in
di erent shards, reshu ing operation. However, this simply poses the↵✏
bottleneck threat (not only the performance bottleneck but also the security
bottleneck) back to a single global chain, which is the root issue sharding
technologies would have tried to solve. Insight 15 and other (most recently
proposed) sharding mechanisms hit this pitfall, e.g., SSChain [43] and
Thinkey [45]. SSChain simply utilizes a two-layer architecture where a global
chain is set to deal with all data migration and reshu ing operations.✏
Thinkey also implements a root chain to achieve the cross-shard transactions
and reshu ing operations. ✏Trend 1: Restricting the use of a global chain
in any operations, and the bottleneck requiring to be solved if used.
•Requiring miners/validators to store ledgers from other shards. This is
necessary in some of the existing sharding mechanisms in order to cross-
validating transactions and reshu ing operation. However, it leads to✏
miners/validators incurring high communication and storage overhead in
O(n) (n is the number of shards). Insights 1, 7, 9, 10, 11, 13 hit this pitfall.
Trend 2: Balancing the storage and communication overhead for
miners/validators in sending cross-shard transactions and reshu ing,✏
so that the order can be lower than O(n). One of the potential solutions
102
might be the fraud proof that enables light nodes to be as secure as full nodes
without needing to store the whole ledger [6], yet it has not been mature at
the time of writing. • Allocating participating nodes to shards based on their
business requirements in order to bypass the overhead of cross-shard
communication. Business-driven members allocation for shards has been
proposed and discussed in some designs, e.g., Ethereum 2.0 [117]7 and
VAPOR [160]8, in order to reduce, 1) the frequency that a participating node
gets swapped out; and 2) the ratio of non-cross-shard transactions, for the
ease of management and lower overhead. However, this results in a very long
epoch reconfiguration for participating nodes and unevenly shard size, which
ultimately poses a risk of crowed transactions to a single shard as time
passes and the size and throughput increases, thus hitting the bottleneck of
intra-consensus. Trend 3: Avoiding simple business-driven members
allocation that risks shards su ering from crowed transactions.↵
4.5.0.2 Future Trend for Strengthening the Security and Atomicity
This trend corresponds to the intra-consensus and atomicity of cross-shard
transactions, respectively. We point out the potential direction on more secure
intraconsensus and more e cient cross-shard transactions, as shown in the
following.
Intra-consensus:
7 A possible design proposed by Ethereum 2.0 is to merge shards that interact more frequently than
others.
8 Another design proposed by VAPOR is to define a shard as a subset of nodes who care about
some transactions. Transactions in VAPOR feature the ownership and record the nodes who have
ever held the ownership.

103
•Trend 4: Scaling the unbiased and unpredictable randomness generator
in large-scale networks with as few third-party hardcoded settings as
possible. The unbiased and unpredictable randomness plays an important
role in BFT-based intra-consensus design. Improving this kind of algorithms
can significantly prevent the validators from being under DDoS attacks.
Insights 3, 5, and 8 belong to this aspect.
•Trend 5: Improving the PoW-based intra consensus, and generalizing it
into other types of Nakamoto-based consensus algorithms. Chu-ko-nu
mining of Monoxide takes advantage of PoW to bypass the vortex of
randomness, nevertheless, the security of which is dependent on the storage.
As such, the future direction can be potentially decoupling the security and
storage, and generalize the concept to other Nakamoto-based consensus
algorithms, e.g., PoS.
•Trend 6: Balancing the uses of stochastic and biased members
allocation for shards. All discussed sharding mechanisms (except
Chainspace) use a stochastic allocation. A stochastic allocation is helpful to
protect the shards from malicious biased allocations. On the other hand, new
notions have been proposed to improve the scalability by taking advantage of
a biased allocation. For example, [196] proposes a biased allocation to force
the number of members an attacker can own within a single shard to be
upper-bounded, in order to achieve a total FT of 50%. However, a
vulnerability of this mechanism has been revealed that attackers can simply
save the redundant resources from a specific shard, and has more su cient
resources to control more shards.

104
Thus, a balance of this use still strives for a solution.
E cient atomicity:
• Trend 7: Enabling e cient conditional cross-shard transactions that enable
contract-orient operations. Only Chainspace and the future phase
of Ethereum 2.0 claim to support such conditional cross-shard transactions
so far, but at the cost of unacceptable overhead and latency, which requires
more focus in the future trend.
• Trend 8: Combining sharding technologies with DAG being the data
structure of any shards. DAG provides more flexibility specifically in some
IoT contexts, such as the micro-payment. However, the implications of the
cross-shard transactions with DAG still require more focuses.
4.6 Conclusions
Remark that the lack of a generic and systematic framework to learn various
sharding mechanisms occurs along with the sharding technology has taken centre
stage of scaling Blockchains. This was resolved in this chapter by highlighting the
importance of sharding for the design of scale-out Blockchains and systematizing
the state-of-the-art sharding mechanisms in regards to the intra-consensus security,
atomicity of cross-shard transactions, and general challenges and improvements. We
also proposed our insights analyzing the features and restrictions, based on which
a comprehensive comparison among the considered sharding mechanisms was ob-
tained.
A list of the key observations and conclusions are as follows:

105
• For the first time Monoxide proposes a Nakamoto-based sharding
mechanism, but at the cost of storing headers of all shards to guarantee the
maximum
intra-consensus-safety.
• The traditional PBFT used in Elastico and Chainspace does not guarantee the
intra-consensus-safety due to its weak scalability, while the BFT-based
sharding mechanisms, i.e., OmniLedger, Rapidchain, and Ethereum 2.0,
improve the intra-consensus-safety by scaling the traditional PBFT or
increasing the fault tolerance of the traditional PBFT.
• The randomness generators of all considered sharding mechanisms in this
chapter need strict network settings, otherwise the unpredictiability and
unbiasability in scaled networks will be compromised.
• Monoxide, OmniLedger, Rapidchain, and Ethereum 2.0 all propose their own
solution to the issue of cross-shard transactions, none of which can support
cross-shard smart contracts. Only Chainspace proposes a smart-
contractoriented sharding mechanism, but at the cost of low throughput. • All
considered sharding mechanisms introduce the optimizations to address the
new challenges their proposed sharding mechanisms pose to the system, e.g.,
latenc, storage, fair randomness generator, and replay-attack defense, but
further improvements are necessary.
Chapter 5

106
Enabling Attribute Revocation for Fine-grained Access
Control in Blockchain-IoT Systems
Regardless of the network size, Blockchain-based IoT networks become
increasingly reliant on fine-grained access control due to the growing size of IoT
data stream and the growing requirement of flexible data management. ABE has
been considered appropriate to provide fine-grained access control in Blockchains
that inherently lack such features. However, the adoption of ABE in Blockchains has
been severely hindered by the incompatibility between the immutability of typical
Blockchains and the attribute updates/revocations of ABE, which requires more
attentions. Under this background, this chapter proposes a new Blockchain-based
IoT system which is compatible with ABE technique, and fine-grained access
control is implemented with the attribute update enabled by integrating CH
algorithms into the Blockchains.
5.1 Introduction
The Blockchain technology, originating from cryptocurrency, has been recently
employed in the IoT as the root of trust for authorization management [144], policy
management [141], and data security [111]. In a Blockchain, all participants can
verify and certify data by following a common consensus protocol to provide
decentralized, reliable, and tamper-resistant services [188]. There have been a
number of attempts to implement data access control on the traditional
Blockchains where data are publicly stored, e.g., Bitcoin and Ethereum [135, 191].
Cryptographic technologies, e.g., homomorphic encryption and zero-knowledge-
proof [116, 129], have been adopted. However, these technologies can su er from↵
prohibitive overhead for IoT devices [197]. This prevents fine-grained access
control in Blockchain-based IoT systems. Meanwhile, Hyperledger Fabric [85]

107
implements a traditional access control by using transaction encryption and key
management. However, the size of encrypted conversation keys grows linearly with
the number of users. The overhead would still be very high in Blockchain for fine-
grained access control.
The Attribute-based Encryption (ABE) technologies have the potential to
achieve fine-grained access control where a ciphertext can only be decrypted when
the attributes of a user match a predefined set of rules [185, 156]. In [156], the
conversation keys of encrypted transaction data are protected with ABE by the
transaction senders (i.e., data owners). Any outdated ciphertext needs to be
updated and overwritten with an updated version when the attributes are revoked.
However, the immutability of Blockchain prevents the update of attributes and the
dynamic group membership of ABE. The existing solution tends to store the
updated ciphertext of ABE by smart contracts [154]. A risk of a direct data leakage
to revoked members arises. Adequate designs of ABE-based Blockchain access
control have yet to be properly addressed.
In this chapter, we propose a novel multi-layer Blockchain-IoT data service
system which enables secure attribute updates in an ABE-based fine-grained
access control mechanism for Blockchains. We develop a redactable key chain
along with a standard data chain to secure and control the access to the data chain.
Empowered by redactable hash functions, the redactable key chain allows the
access policies of ABE to be updated by key chain miners. The data chain can be
any existing Blockchain with any scalable structure and preserves the immutability
of the IoT data. Collectively, these crytographic primitives address the inherent
incompatibility between the immutability of Blockchains and the indispensable
need of updating attributes to manage the access to Blockchains. To the best of our
knowledge, the proposed Blockchain-IoT data service system is the first of its kind

108
to enable the attribute updates and provide e ective access control in the presence↵
of the updates. The system is compatible with the major types of cryptographic
primitives and consensus algorithms in Blockchains.
The key contributions of this chapter are shown as follows.
1. We identify the incompatibility between the immutability of Blockchain and
the update of attributes in ABE, and the resultant potential risk of direct data
leakage to revoked members. The incompatibility hinders the adoptions of
ABE in Blockchain-based IoT systems.
2. We design a new multi-layer Blockchain structure consisting of a data chain
and key chains, in order to decouple data storage and access control
management. ABE is used for fine-grained access control in the proposed key
chains.
3. We propose to integrate the CH algorithm in the Blockchain structure along
with a new verification scheme to support the tamper-resistant attribute
update of ABE in the proposed key chains. As a result, the system allows
trusted policy update in ABE, while still preserving the tamper-resistance of
Blockchains.
The analysis and simulation results show that our proposed mechanism is able to
outperform existing solutions in terms of overhead, searching complexity, and
security. Our mechanism also provides excellent compatibility with major types of
consensus protocols, cross-chain protocols, and crypto algorithms (ABE and CH).
The rest of this chapter is organized as follows. Section 5.2 presents the
proposed Blockchain system. Section 5.3 presents the multi-layer Blockchain
design, as well as the design of redactable key chain with a new verification
109
scheme. In Section 5.4, we conduct comprehensive system analysis and simulation.
Section 5.5 concludes the chapter.
Table 5.1 : Notation Definition
Notation Definition
DP Data Publisher
DU Data User
PT Plaintext of a message
CT Ciphertext of a message
PT Plaintext of a conversation key
CT Ciphertext of a conversation key
EEncrypting function to an encrypted message
DDecrypting function to a decrypted message
{A}Access policy that defines the access to conversation keys
SKA,P/PKA,P Conversation keys that used to an encrypt/decrypt message P, with access
policy assigned as {A}
ABEAAttribute-based encryption algorithm to encrypt/decrypt conversation
keys, with access policy assigned as {A}
ABE ,SK,i↵/ABE ,PK↵Private/Public key of the given ABE, where the private key is identitybased
for each member i in attribute ↵
ABE ,SK↵An abbreviation of ABE ,SK,i ↵for simplicity
110
↵ ✏AAn attribute ↵satisfies an access policy {A}
CHSK,P/CHPK,P Private/Public key of the CH algorithm with respect to a message P
ti,j j-th transaction on Block-i, i.e., the block with height i
n
mA LOOP process starting from index m to index n
F
5.2 Preliminary
5.2.1 Attribute-based Encryption
ABE provides access control to data based on a set of rules associated with data
and attributes of a data user. In general, an ABE scheme consists of the following
five algorithms. Tab. 5.1 summarizes the notations used in the rest of the paper.
ABE Setup (1k) ! (MK): This algorithm sets up ABE. It takes as input a security
parameter 1k, and outputs a master key MK.
ABE KeyGen (MK,r) ! (ABESK,i,ABEPK): This algorithm generates attributebased keys. It
takes as input the master key MK and a random number r, and outputs a pair of ABE keys.
Each pair of ABE key includes a private parameter set, ABESK,i, and a public parameter
set, ABEPK. Note that ABESK,i is identitybased, which indicates that each member i
assigned with the same attribute has its own unique ABESK,i.
ABE Encrypt (PT,A,ABE ,PK↵) ! (CT): This algorithm encrypts data according to the
assigned access policy. It takes as input a message to encrypt PT, an access policy A
and a set of public parameters ABE ,PK ↵of attribute , and outputs ↵CT which is the
ciphertext of PT.
111
ABE Decrypt (CT,A,ABE ,SK↵) ! (PT): This algorithm decrypts data if the attribute-
related parameters satisfy the access policy. It takes as input a message to decrypt CT,
an access policy A and a set of private parameters ABE ,SK ↵by each member in
attribute , and outputs ↵PT which is the plaintext of CT.
ABE Update This algorithm
updates the CT and the corresponding ABE ,SK ↵to a new version, i.e., CT0 and
, respectively, to meet the update of attribute members. It takes as input the
master key MK, an attribute , the outdated ↵CT, the outdated ABE ,SK↵, and a new
random number r0, and outputs the updated CT0 and ABE↵0 ,SK.
5.2.2 Chameleon Hash (CH) Algorithm
A generic CH algorithm involves a trapdoor (private key) to allow one to quickly
identify an arbitrary hash collision within the domain of this algorithm. It consists
of the following three algorithms.
CH KeyGen ( ,ParaCH) ! (SKCH,PKCH): This algorithm generates CH keys, given
security parameters. It takes as input a security parameter and a system parameter
ParaCH; and outputs a private (trapdoor) key SKCH and a public
(hash) key PKCH.
CH Hash (M,PKCH,r) ! (CH): This algorithm generates CH value for a message. It
takes as input a message to hash M, a private key PKCH and a random number r; and
outputs a CH value CH.
CH Update (M,M0,r,SKCH) ! (r0): This algorithm updates CH-related parameters to
guarantee that the original CH value remains valid after the message update. It takes
as input a message before the update M, the message after the update M0, the CH
random number r before the update and the corresponding private key SKCH; and
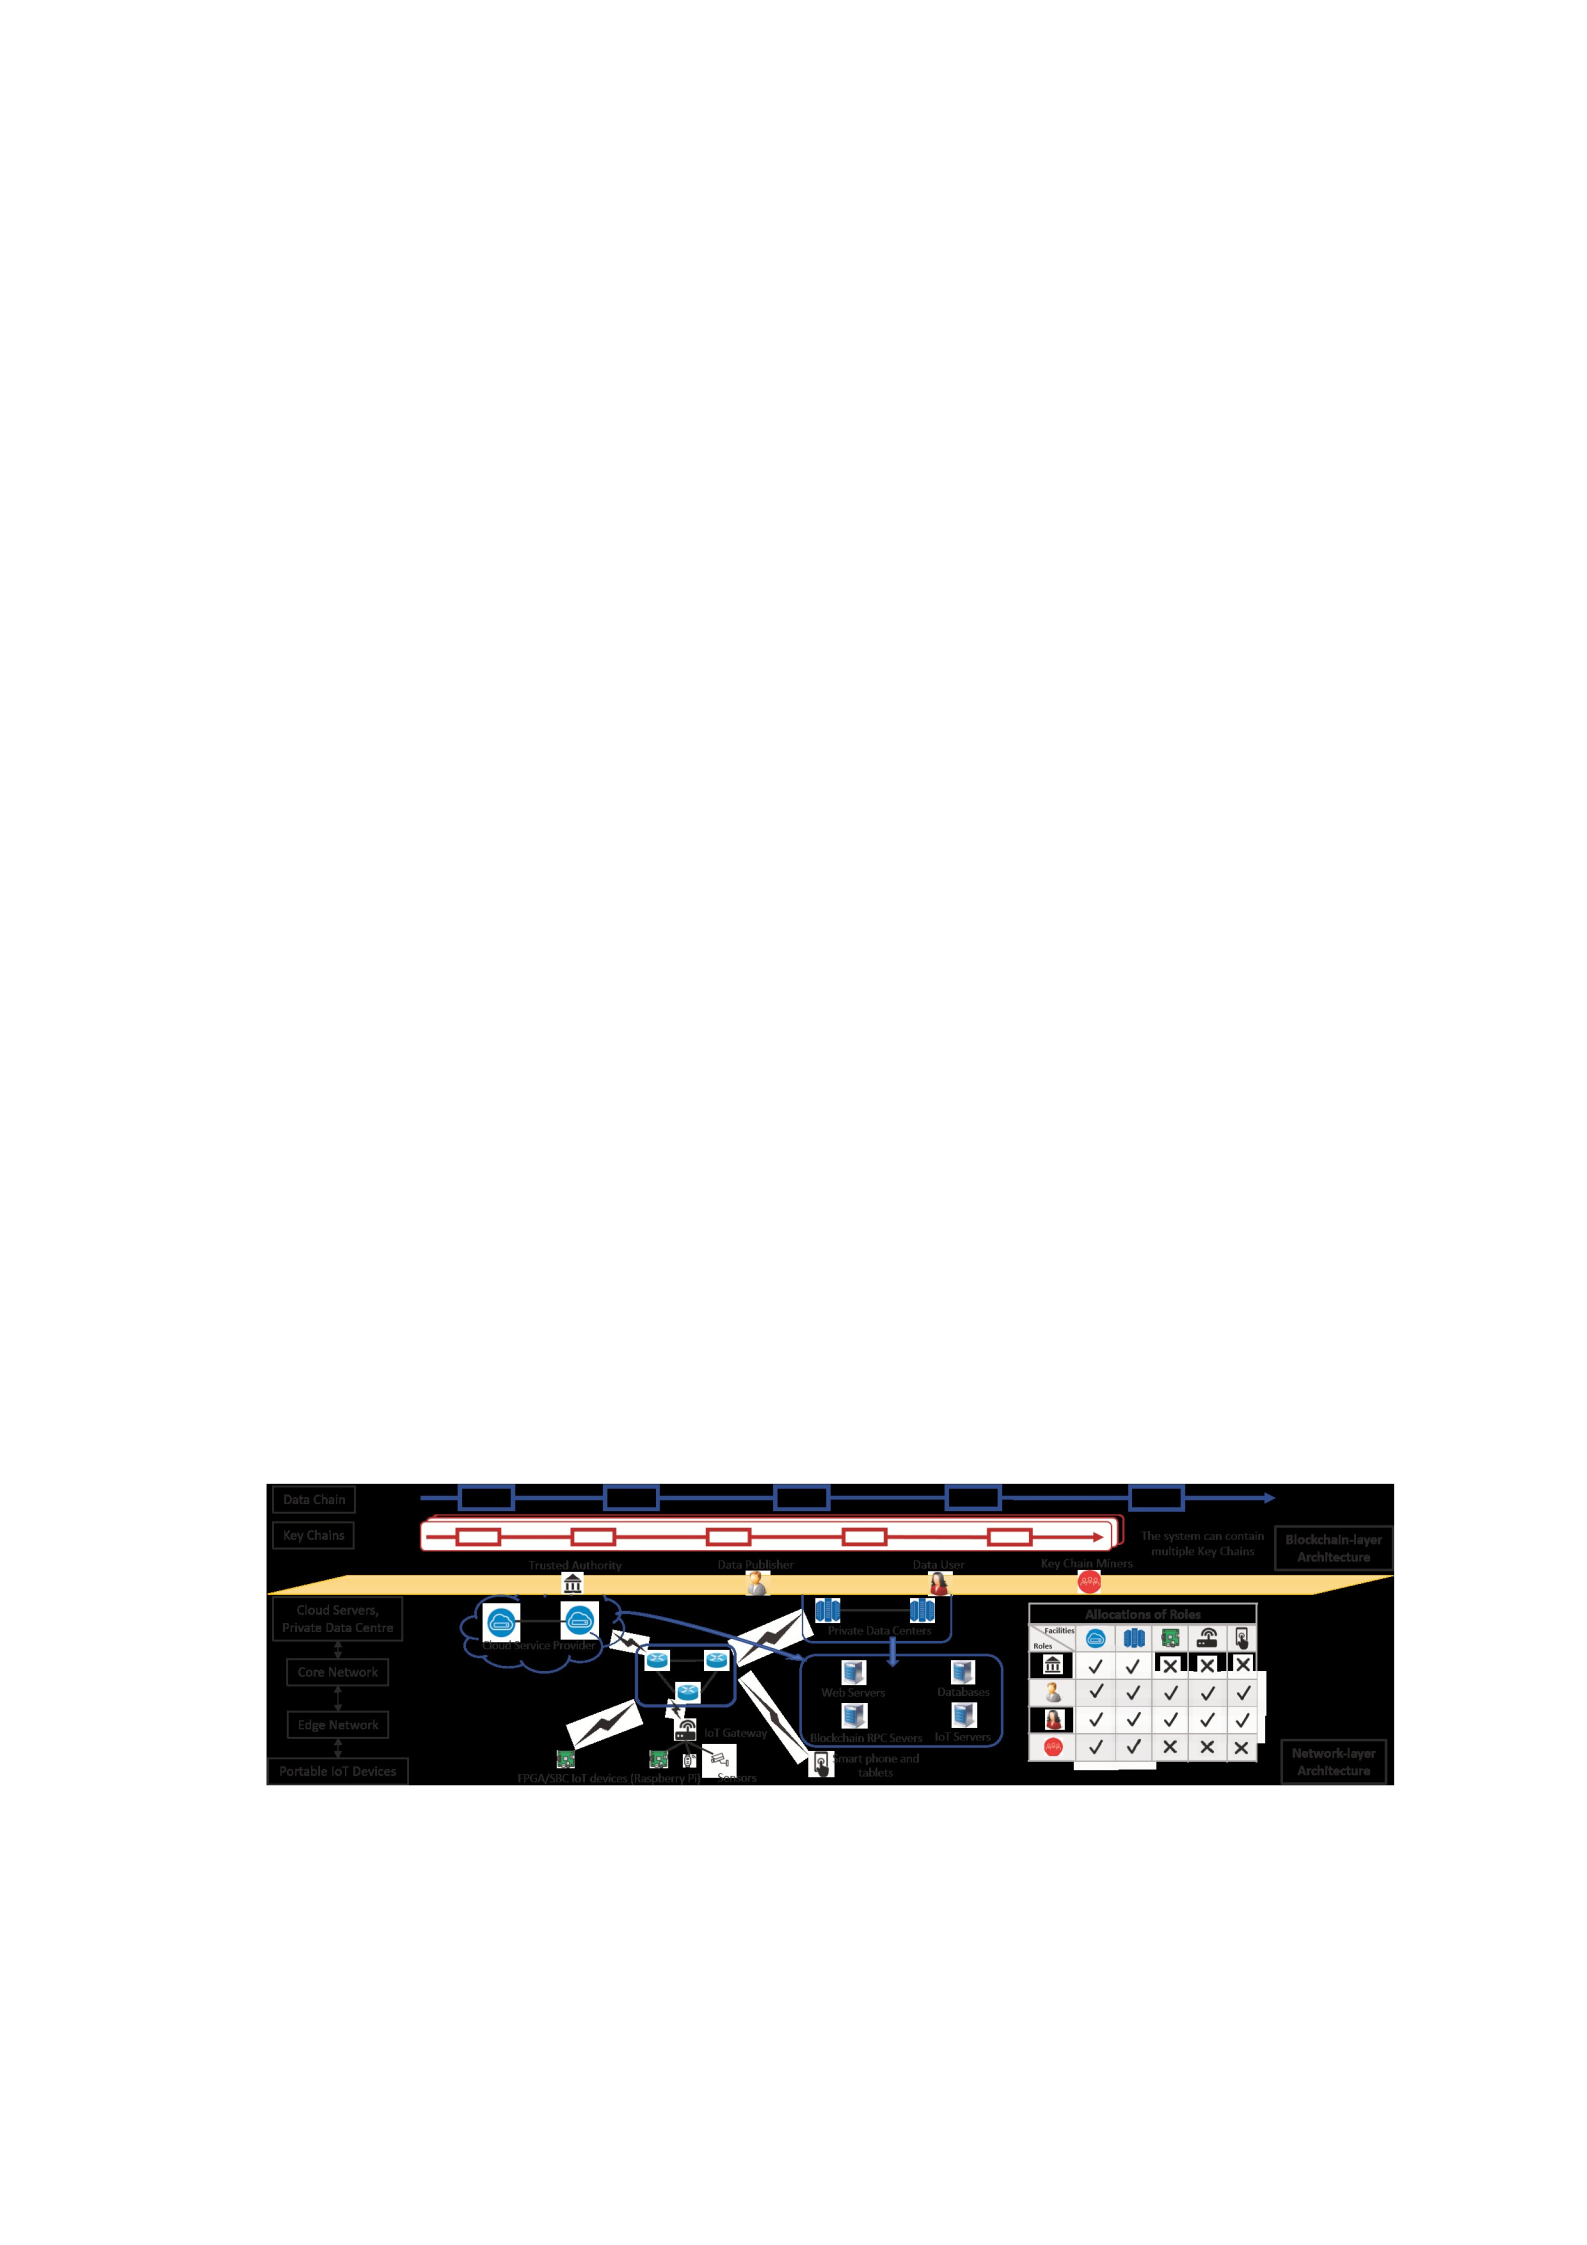
112
outputs an updated CH random number r0. The CH associated with the updated CH
random number and the updated message is identical to the original CH value
before an update, i.e., CH Hash (M0,PKCH,r0) = CH Hash (M,PKCH,r).
5.3 Multi-layer Blockchain-IoT System with Redacatble Key Chain
This paper proposes a novel multi-layer Blockchain-IoT data service system
where secure attribute updates are enabled in an ABE-based fine-grained access
control mechanism for Blockchains. We develop a redactable key chain to provide
secure access to another standard data chain. The redactable key chain enables the
tamper-resistant attribute updates of ABE via a new verification scheme conducted
by the key chain miners. As a result, a secure fine-grained access control
mechanism for Blockchain-IoT systems can be achieved.
5.3.1 System Overview
The proposed system uses Blockchain to provide IoT data storage and data
sharing services where a CP-ABE scheme is integrated to enable fine-grained
access control. The proposed system consists of the following four roles:
Trusted Authority (TA): The TA assigns and manages attributes for the entities
Figure 5.1 : This figure illustrates an overview of the proposed system. The bottom-half-side shows
the architecture of the network-layer where the hierarchical topology of facilities is specifically
described, upon which Blockchains being run among these facilities charged with di erent roles↵

113
are described in the top-half-side. The table regarding the allocation of roles describes the
relationship between the considered facilities and roles.
in the system. The accessibility of an entity to a particular piece of data depends on
the attributes of the entity, as well as the access control policy of the data. The TA
can be a standalone entity or a multi-authority group of which each member
manages a set of attributes for robustness and scalability. In this paper, we
consider the TA as a single entity.
Data Publisher (DP): The DPs, such as IoT devices, produce, packetize, and
upload data to Blockchain in the form of transactions. The DPs also specify the
access policy for each new published message, so that only the data users with
attributes satisfying the access policy can access the message. Data User (DU): The
DUs access the Blockchain to retrieve data. Their attributes may change over time,
and only the TA can update DUs’ attributes and attribute-related private
information.
Miners: A Miner is responsible for mining data into the Blockchain and
providing tamper-resistance, as typically done in any existing Blockchain systems.
A new responsibility of the Miners is to conduct a new verification scheme to avoid
abusing the CH updating function during the consensus process, as will be
described in Section 4.3.1. In the rest of this paper, Miners refer to those running,
managing, and storing the key chains. They are powerful servers typically located
in either the cloud or private data centers.
Fig. 5.1 shows the network construction of a hierarchical IoT system, where
these roles can be decoupled from the physical devices and one device may take
multiple roles. For example, servers providing di erent services (e.g., Web servers,↵
IoT servers, and Blockchain RPC servers) can take the role of DP or DU. The table at

114
the right-bottom corner of Fig. 5.1 provides the mapping between network
elements in the network architecture and the roles in the (key) Blockchains. As a
result, every network element assigned with one or multiple roles, is connected via
the network. Each of the roles can participate in the data exchange of Blockchains,
i.e., uploading or fetching data from the Data Chain or Key Chains.
An IoT device serves as a DP/DU (primarily DP) in the proposed protocol. It
only uses its own conversation key SKP /PKP associated with message P, ABE public
key ABEPK and private key ABESK associated with each of its attributes, to encrypt its
data before uploading the data to the Blockchains (or to decrypt its data after
downloading the data from the Blockchains). Based on FPGA and System-onChip
(SoC) boards such as AVNET’s Zedboards or single-board computers (SBCs) such as
Raspberry Pi, many current IoT devices are reasonably powerful to carry out
encryption operations. These are the IoT devices considered in this paper. On the
other hand, ABEPK and ABESK are generated by the TA and maintained/stored in one
of the key chains. The IoT devices only retrieve the keys from the key chain, and are
not involved in running, managing, or storing any of the Blockchains (including the
key chains and the data chain) due to limited memory and communication
resources of the devices.
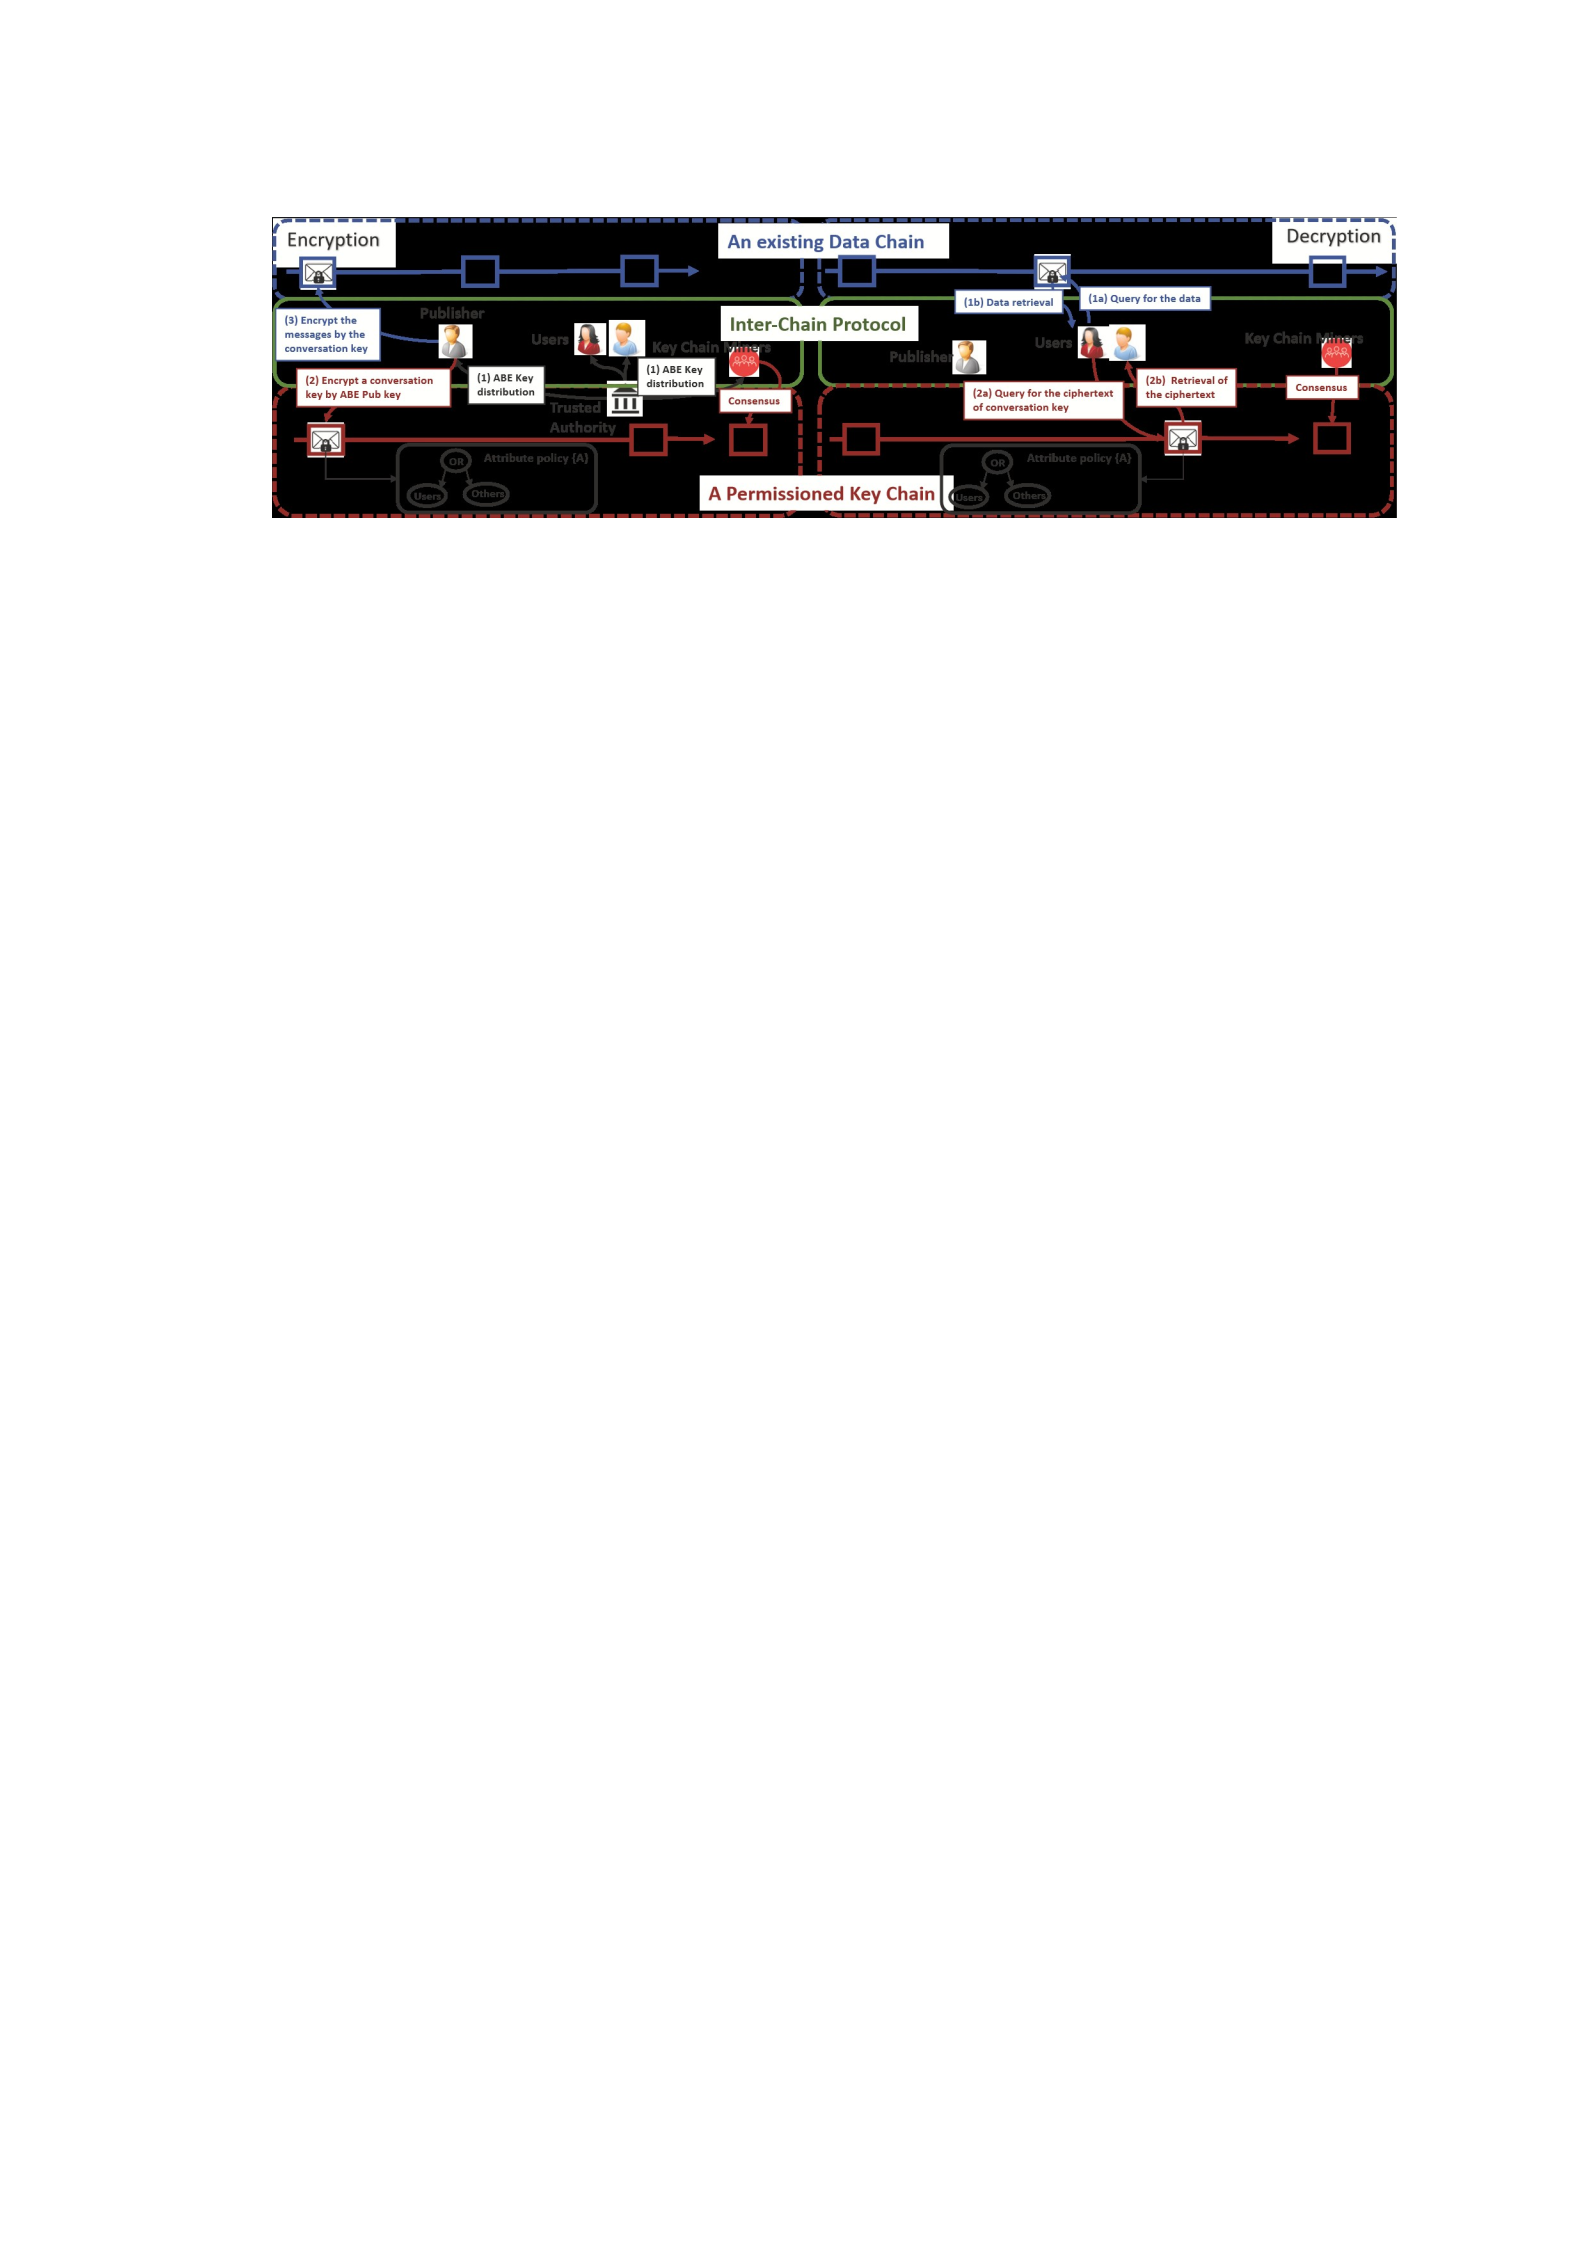
115
Figure 5.2 : The process of encrypting and publishing a new message is shown on the left-hand side.
The right-hand side shows the process of decrypting and retrieving a new published message. A
Data Publisher (DP) and Data Users (DUs) implement the Inter-chain Protocol to deal with the data
encryption/decryption between the Data Chain and Key Chain.
5.3.2 The Proposed Multi-layer Blockchain System
We propose a multi-layer Blockchain-based data ledger service system
consisting of two types of Blockchains, Data Chain for immutable confidential data
service, and Key Chain for key management, as shown in Fig. 5.2.
Data Chain - A Data Chain can be any existing permissionless or permissioned
Blockchains used for recording data, e.g., Ethereum [191], with the following
scalability-enhancing techniques:
• existing scalable consensus algorithms or data structures, e.g., ByzCoin [98]
and Directed-acyclic-Graph [152], that can help reduce the communication
overhead of the proposed system to at most O(n), where n is the network
size;
• existing scale-out techniques that can partition a network (including the
proposed network) into shards from the perspective of data storage,
communication bandwidth, and computation, to achieve horizontal

116
scalability (sharding) to accommodate huge amounts of data, e.g.,
OmniLedger [99].
By using these techniques, the total capacity and throughput of a scalable Data
Chain can be expected to support the huge data of IoT systems. A DP encrypts
117
its data with conversation keys before publishing encrypted data in the form of
transactions in the Data Chain.
Key Chain - A Key Chain stores the ciphertext of the conversation keys, i.e., CT,
for key management. The Key Chain is permissioned and has a unique TA to
manage the key generation and distribution of the ABE scheme. Here, the
conversation keys, used to encrypt data in the Data Chain, are encrypted by the
ABE algorithm by the DP, before the DP publishes the encrypted data in the Data
Chain. Every Key Chain is redactable along with a new verification scheme
conducted by the Miners on the Key Chain to guarantee the tamper-resistance.
Thus, the attribute updates of ABE can be enabled.
Inter-Chain Protocol - This protocol is implemented for data exchange among
a Data Chain and Key Chains9. Any participants acting as clients on both Data Chain
and Key Chains operate the new the Inter-Chain Protocol. The protocol includes
the following subprotocols.
Encryption and publishing a new message P: A DP encrypts PKA,P to CT =
ABEA(PKA,P ), by using ABE ,PK ↵where an attribute ↵satisfies an attribute policy {A}.
This CT is uploaded to a Key Chain as a transaction, ti,j (j-th transaction of the block
with height i). After that, the DP encrypts the message P into CT by using the
corresponding SKA,P . As such, the indexes to ti,j, i.e., i and j, are uploaded along with
CT on a Data Chain for the cross-reference in the Decryption subprotocol. The
details are provided in Section 5.3.4.1.
Decryption and retrieving a new message P: A DU assigned with the attribute
9 A major type of cross-chain protocol [36] can be rather implemented to bridge the
communication among Data Chain and Key Chain instead of making DPs send the transactions to
each Blockchain by themselves. Remark that our system is a generic one and independent of the
crosschain protocols.

118
↵satisfying {A} intends to retrieve the message P, and the DU identifies the block
containing the related CT and the indexes, i and j on the Data Chain. The DU then
searches for the corresponding ti,j on the Key Chain. Next, the DU can retrieve the
PKA,P by decrypting the CT with its own ABE ,SK↵. As such, the DU can decrypt CT on
the Data Chain with PKA,P . The details are provided in Section 5.3.4.2.
Attribute updates by updating blocks on a Key Chain: The non-revoked (this
means the DUs that are reserved after the corresponding attribute changes) and
new DUs assigned with the attribute ↵satisfying {A} update the outdated ABE ,SK↵.
Meanwhile, the miners of the Key Chain update the outdated CT. The revoked DUs
cannot directly retrieve PKA,P from the Key Chain, whilst the non-revoked and new
DUs can access any CT assigned with the attribute policy {A}. The details are
provided in Section 5.3.4.3.
The proposed system can have a Data Chain and multiple Key Chains to support
di erent and independent access policies to the ↵Data Chain, as shown in Fig. 5.1.
The Data Chain ensures the data integrity and transparency among multiple
communities, and all communities can contribute to maintaining the Data Chain.
The multiple Key Chains allow each community to manage their own private keys
independently, using their own Key Chain to meet di erent requirements.↵
Attributes are managed independently from other Key Chains. This is useful
because two Key Chains, for example, may be managed by two communities that
have similar business requirements. This implies that these two communities may
use identical attributes expected to be mutually privacy-reserved on their own Key
Chain, thus leading to the design of a cluster of Key Chains for flexible management
of IoT.
The Data Chain and Key Chains collaborate to provide the following properties.

119
Fine-grained access control: An ABE scheme integrated with the proposed
multi-layer Blockchain system guarantees the secured, fine-grained access control.
Take the access control of a message M as an example. M is encrypted by a
conversation key before stored in the Data Chain. The conversation key is a
prerequisite to access M. Only the DUs satisfying the access policy of the
conversation key can retrieve the key which is stored in the Key Chains and
encrypted by the ABE
algorithm.
Revocable attribute of ABE: The editability of a Key Chain enables the support
of attribute revocability of ABE in the Key Chain. All related conversation keys
remain unchanged, while the corresponding ciphertext stored in the Key Chain is
updated if an attribute of a member is revoked. Only DUs with attributes satisfying
the attribute policy are able to decrypt the conversation keys and, in turn, the data.
As a result, the Data Chain is una ected by the attributes update, while the ↵Key
Chains adopt CH to run as redactable Blockchains to embrace the addition and
revocation of attributes. The design of the redactable Key Chains and the details of
attribute updates will be given in Sections 5.3.3 and 5.3.4.3, respectively.
Anti-tampering: The tamper-resistance of both the Data Chain and Key Chains
is inherited from the Blockchain. In the case with the member update supported,
the Data Chain is una ected, as discussed earlier. The ↵Key Chain can also guarantee
the tamper-resistance by conducting a new verification scheme with the editability
of the CH algorithm, as will be given in Section 5.3.3.1. Thus, the secure update of
attributes of ABE can be ensured on the Key Chain.

120
5.3.3 New Design of Redactable Key Chain
As mentioned in Section 5.3.2, the key to achieving the revocable attributes of
ABE and anti-tampering is the key management in the design of Key Chains. In this
section, the design of a single redactable Key Chain is presented for illustration
conveniences, such as the block structure, and the new verification scheme to
ensure the tamper-resistance of the Key Chain.
5.3.3.1 Block Structure
Di erent from the existing Blockchain such as Bitcoin, our ↵Key Chain is
designed to be a redactable Blockchain to address the conflict between the
immunity of Blockchains and attribute updates of an ABE scheme. We propose to
use a CH
algorithm, instead of traditional collision-free hash algorithms, to hash the data
field of the blocks. The CH allows one to easily find an arbitrary hash collision
regarding a specific hash value with a trapdoor, i.e., CHSK [39], and has been used for
removing sensitive information from Blockchains [16]. The CH can preserve the
editability of the Key Chain, while allowing the Key Chain to be updated in response
to additions and revocations of members and attributes. Here, (CHSK,CHPK) is short
for (CHSK,P ,CHPK,P ).
Each pre-defined Miner is assigned with a CHSK, as given by,
PKMiner,P = ABE Decrypt(CT,Miner,ABEMiner,SK),(5.1a)
CHSK = DPKMiner,P (ESKMiner,P (CHSK)),(5.1b)
where CT = ABEMiner(PKMiner,P ) on the Key Chain. Each block has a data field
containing the CT and a random number in the block body. Any Miner which holds
CHSK is able to edit the data field of the blocks, while the CH value of the transaction
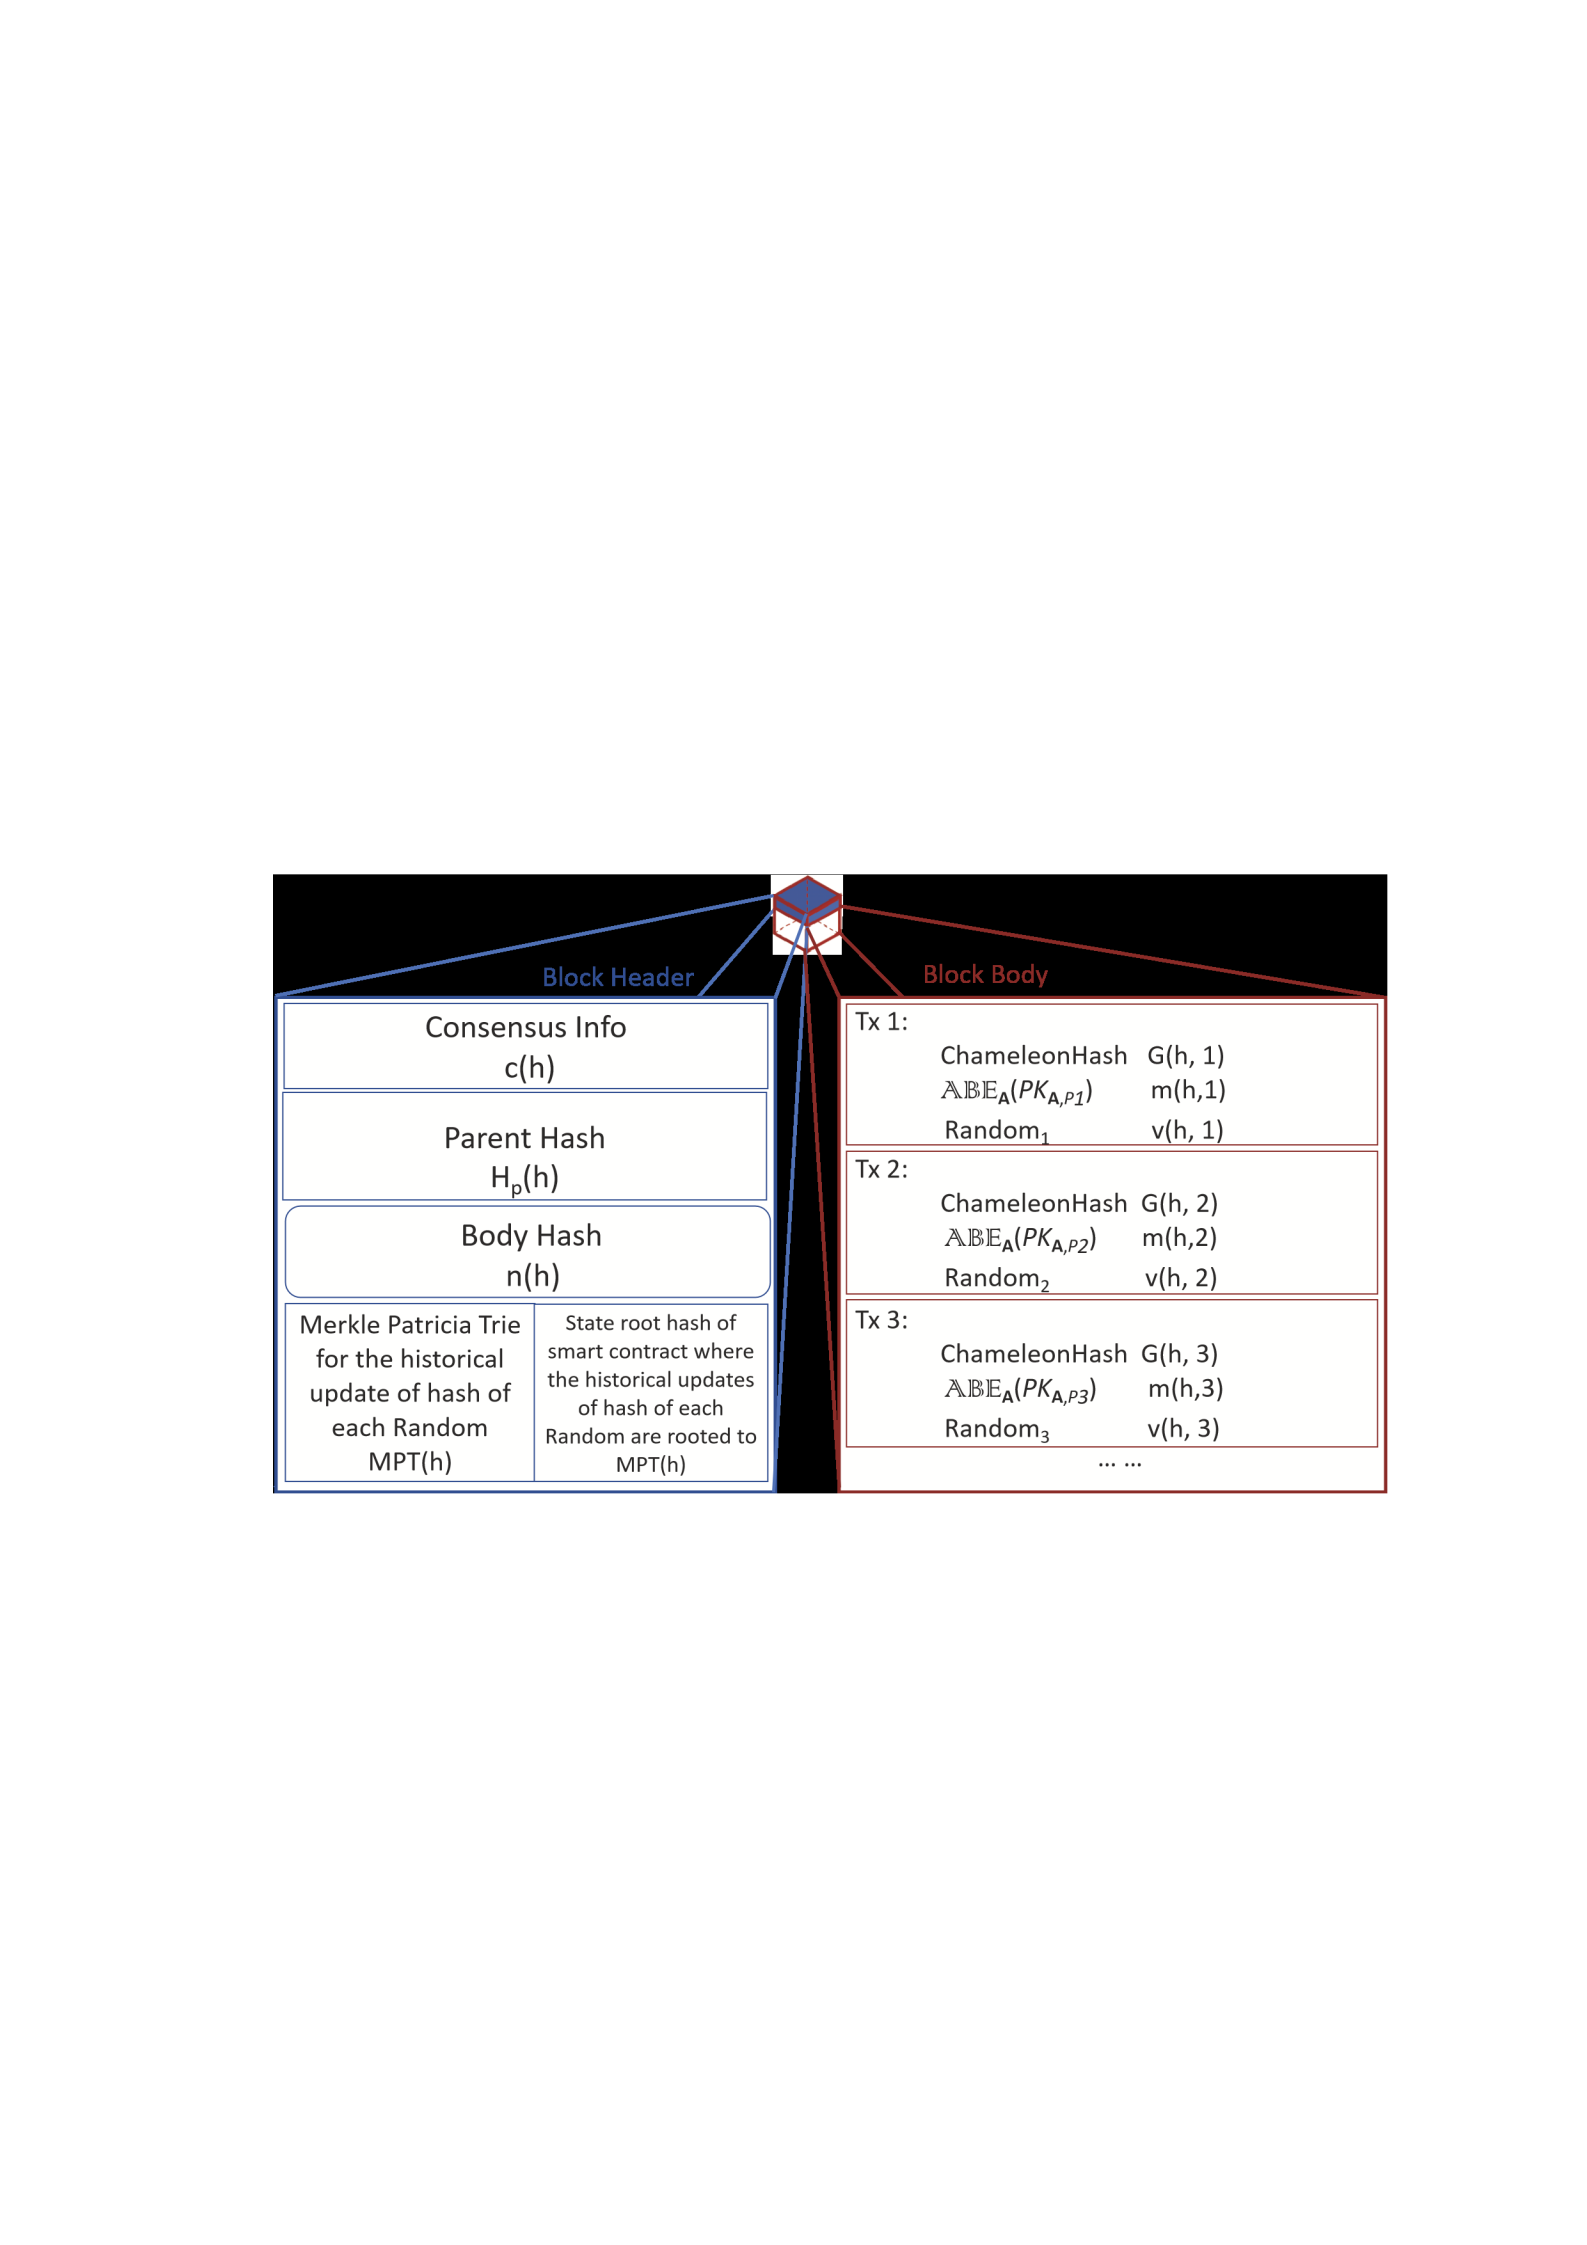
121
remains unchanged. In this way, the chained structure of the Key Chain is
maintained. Only a node of the Key Chain possessing CHSK can edit blocks.
As shown on Fig. 5.3, each block of a Key Chain has a block header and a block
body. Take Block-h, i.e., the block at height-h, for an example. The block header
contains the following four key fields. The first two fields, c(h), i.e, the Consensus
Info of the consensus algorithm, and Hp(h), i.e., Parent Hash accounting for the
linked structure, are inherited from the traditional Blockchain structure. n(h) and
MPT(h) are new in the Key Chain for security consideration to monitor and prevent
any unauthorized Blockchain updates.
Figure 5.3 : The block structure of a block in a Key Chain that stores redactable messages
Body Hash n(h): This field can be regarded as the hash value of the block body,
i.e., the right-hand side of Fig. 5.3, except for the message itself and the
corresponding random number. That is,
n(h) = Hash(G(h,1),G(h,2),G(h,3),...),(5.2)
122
where n(h) remains unchanged given that G(·) is unchanged, even in the presence
of an update of the data field and the related random number. G(·) is the CH value
of the transaction. An optional field containing all other information related to the
transactions, such as event logs or receipts defined in Ethereum-like Blockchain,
can also be included in the Body Hash [191].
Updating Log MPT(h): It denotes the state of the hash of every single random
number in each transaction of the block body, i.e., v(i,j), all through the LOOP
process defined in Table. 5.1, i.e., ) on Block-h (the latest state). This
describes a process that,
1. any j-th transaction starting from the first to the last of a Block-i is traversed;
2. on top of 1), any Block-i starting from the first to Block-h is traversed.
The immutability of MPT(h) is a clear indicator of the e ectiveness of the↵
proposed verification scheme in terms of overhead and search complexity, as
shown in Section 5.3.3.2 and the simulation result in Section 5.4.1. MPT(h) can
prevent a malicious Miner from conducting a false update, which can be an
outdated content intentionally preserved without breaking the linked structure
because of the property of the CH algorithm (the users cannot distinguish any
change of ciphertext by just looking at the unchanged G(·)). Otherwise, the revoked
DUs from an attribute ↵can directly access the outdated CT with their outdated
ABE ,SK ↵and retrieve the conversation key PK.
There is no restriction on the data structure of MPT(h), nevertheless, it contains
the following rule formulated in (5.3):
mapping[i][j] =) Hash(v(i,j)),(5.3)
123
which indicates that a hash value of a specific v(i,j) should be traceable given the
unique block height i and the transaction index j of Block-i, when the verification
scheme of MPT(h) is conducted, as shown in Fig. 5.4. Here, storing the state of
Hash(v(i,j)) prevents the outdated v(i,j) from being directly exposed to revoked
members on the Key Chain.
The following structures are provided as possible options for MPT(h): • A
variable stored in a smart contract through which the state root of the world
state, in the format of a Merkle Patricia Tree (MPT) used in Ethereum, can
notify the world state of the hash of every single random number [191];
• A new dedicated MPT in addition to the world state MPT;
• An engraved transaction in the block body that is immutable and engraved
inside Block-h and all blocks beyond.
In the case where the world state MPT or the new dedicated MPT is used, the
values stored in the leaves of the tree constitute the values of their parents and
ancestors, i.e., up to the value of the state root. The proposed verification scheme
can be achieved due to the fact that any updates at an individual leaf, i.e., the value
of Hash(v(i,j)), would change the value of the state root stored in the block header;
see more details of the MPT in [191].
As shown on the right-hand side of Fig. 5.3, the block body contains several
redactable transactions which store encrypted conversation keys10. A redactable
10 In the case that the data structure of the engraved transaction is chosen for MPT(h), the
immutable engraved transactions used for recording the update history are contained in the block
body.

124
transaction has the following fields. Here a transaction ti,j, i.e., the j-th transaction in
the body of Block-i, is taken for an example.
• ABE Encrypted Key m(i,j): This field stores the latest encrypted conversation
key ABEA(PK). Each transaction only records one encrypted conversation key.
This field is not required when calculating n(i) of the block header.
• Random Number v(i,j): This field stores the latest random number used for
calculating the CH value based on m(i,j). This field is also not used when
calculating n(i) in the block header.
• The CH Value G(i,j): It is the CH value of the transaction. This field remains
unchanged as it is involved in the calculation of n(i) in the block header.
Here, m(i,j) and v(i,j) can be jointly edited without changing their CH value G(i,j), by
following the algorithm CH Update defined in Section 5.2.2. For example, we
assume m(i,j) in the transaction m(i,j),v(i,j),G(i,j) changes to m0(i,j), CH Update
outputs v0(i,j) which satisfies:
CH Hash m0(i,j),v0(i,j)
=CH Hash m(i,j),v(i,j)
=G(i,j).(5.4)
The design in (5.4) contributes to the e cient and secure editability of the Key
Chain. On the one hand, the design saves computation overhead by keeping only a
single edited block valid in the presence of a change of m(i,j) and v(i,j). This is
because G(i,j) is the only field in the block body that is taken to validate the Key
Chain. This allows G(i,j) not to be changed even with the update of m(i,j) and v(i,j),
leading to an unchanged n(h) in the block header. In other words, a valid block with
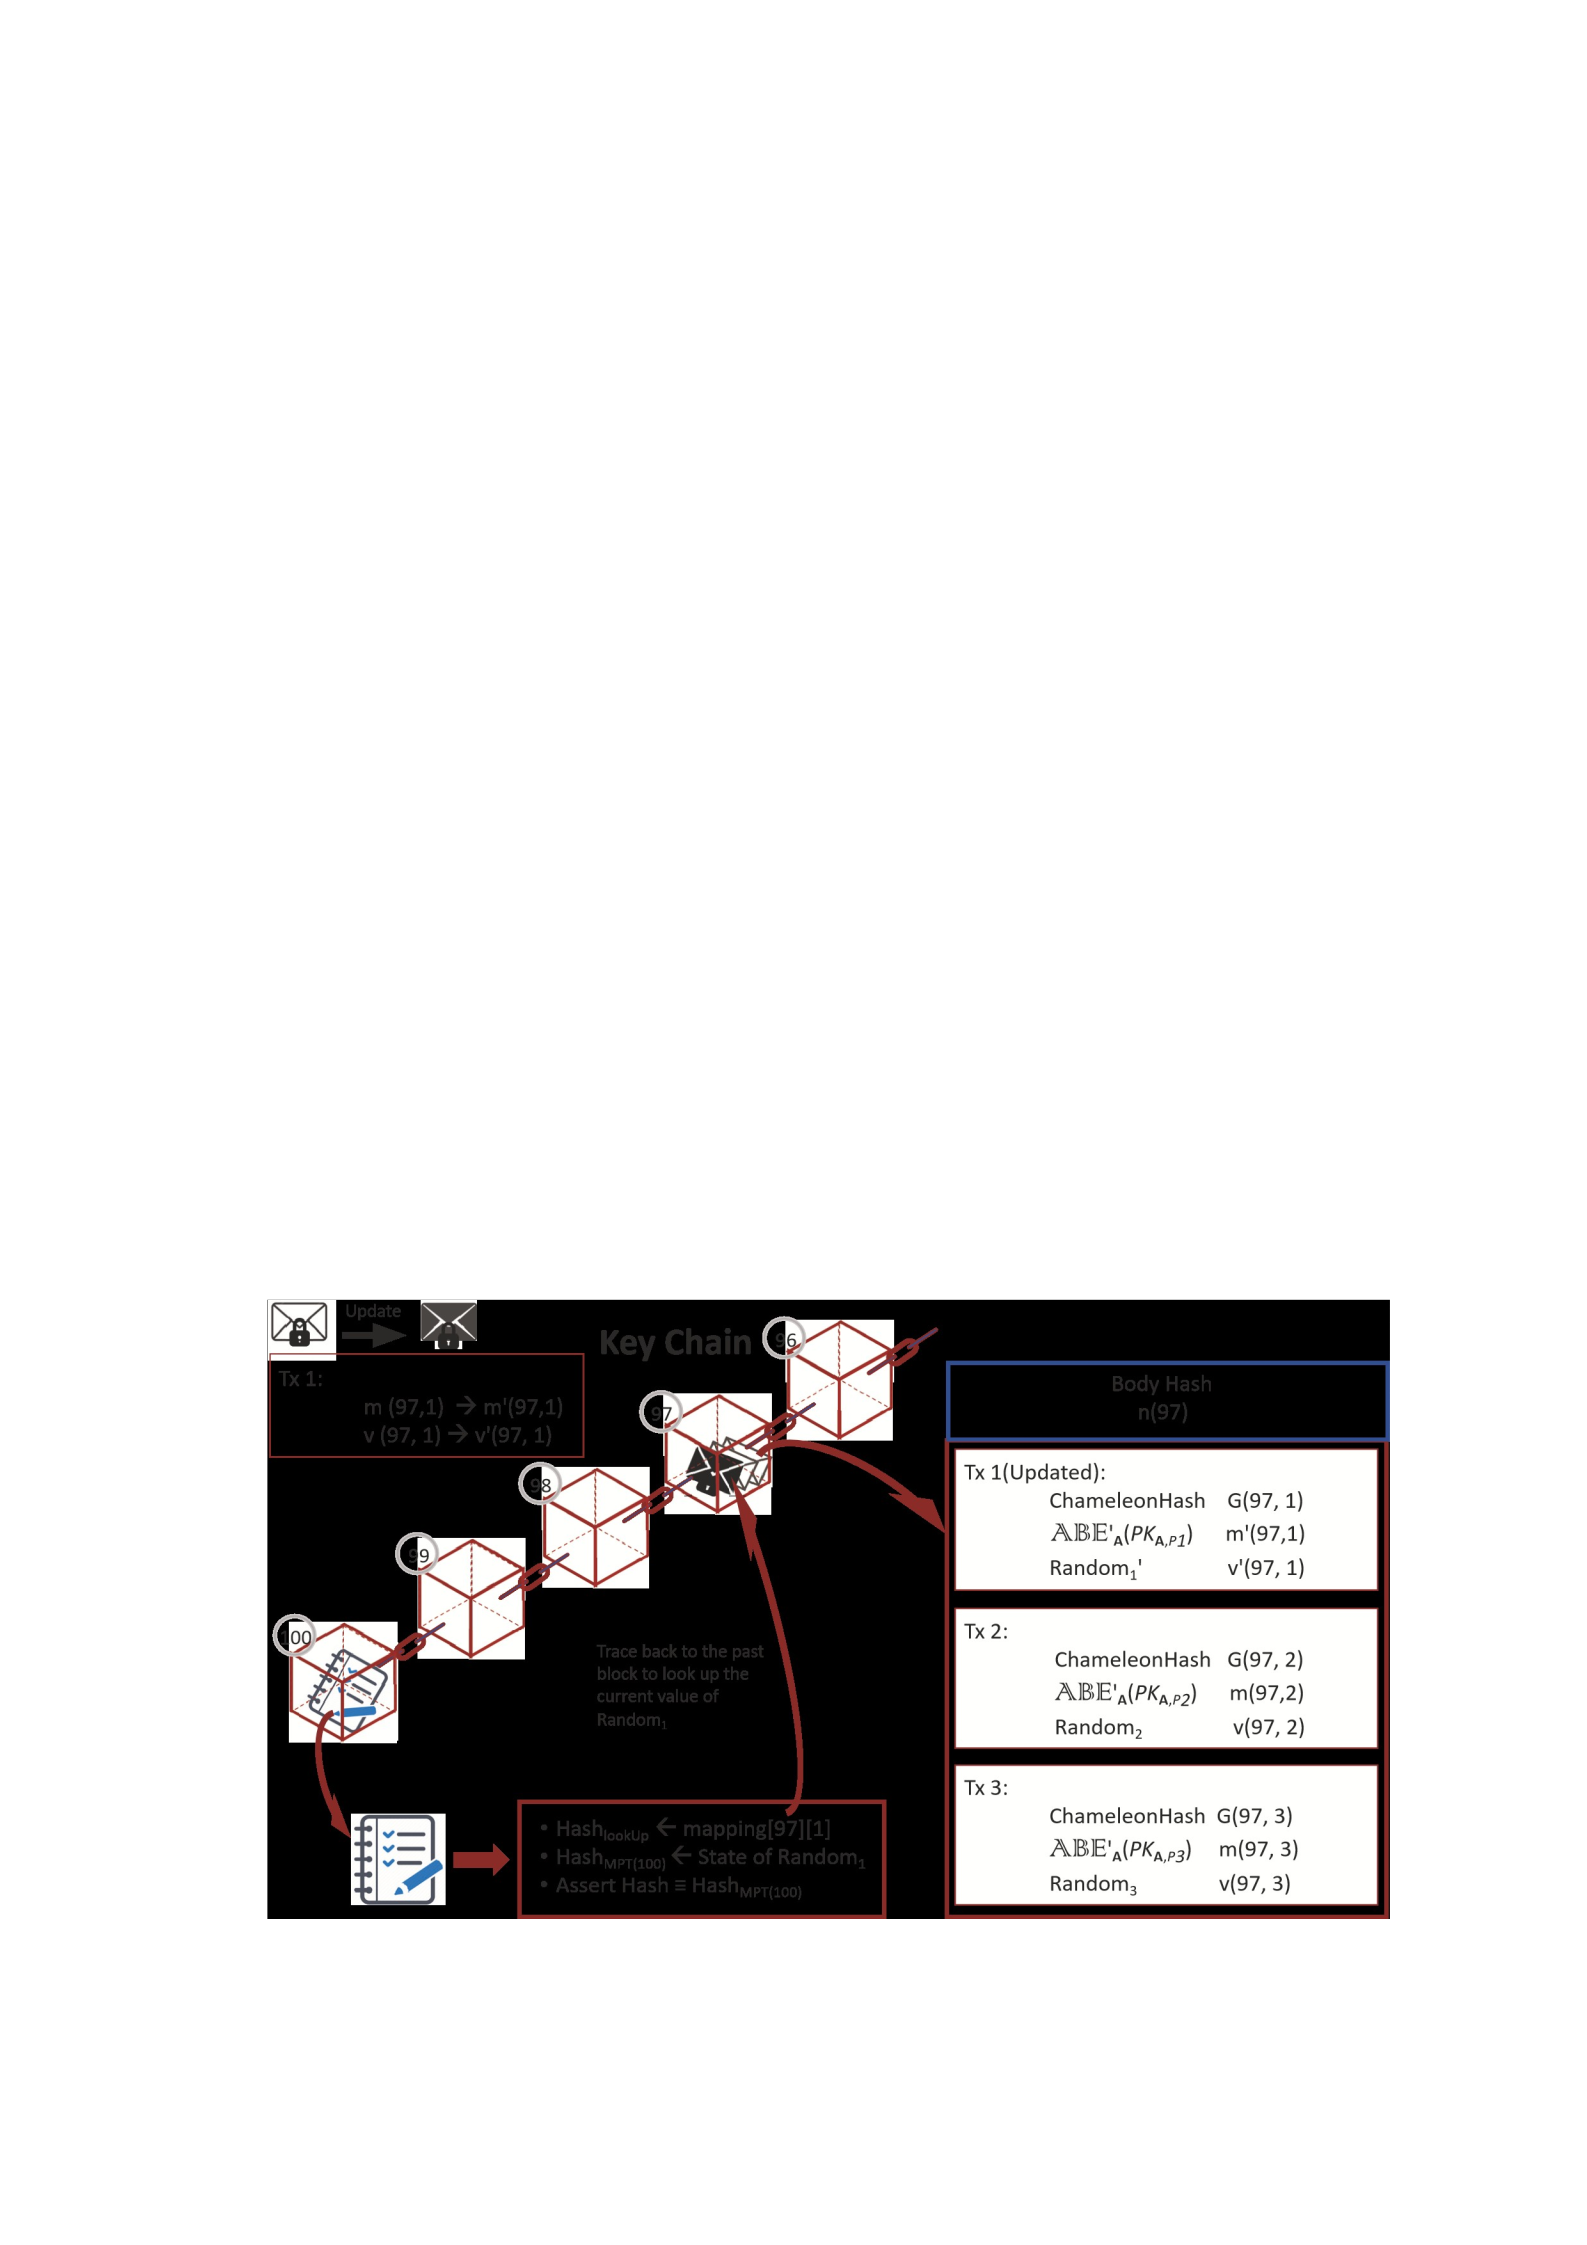
125
an immutable block header can still be validated, as long as m(i,j) and v(i,j) are
edited based on the algorithm CH Update to satisfy the property of G(i,j), as shown
in (5.4). On the other hand, such editability does not breach the tamper-resistance
of the Key Chain. One reason is that the editability of the block body is secured by
CHSK (trapdoors) which are an indispensable input to CH Update. Another reason is
that all fields in the block header of the Key Chain are immutable to provide high
tamper-resistance. Specifically, c(h) and Hp(h) jointly guarantee that the Blockchain
is robust to block tampering. MPT(h) protects the historical path of redactable
transaction updating, and prevents malicious Miners from exposing the outdated
version of ABEA(PK) by an intentional false update.
5.3.3.2 Block Generation and Verification
With the transaction and block form defined above, the DPs of the permissioned
Key Chain generate and broadcast transactions in the Key Chain. In contrast, the
Miners reach consensus on generating blocks based on a collection of pending
transactions.

126
Figure 5.4 : The scheme of MPT(h) delivers reliable verification for every editing conducted at block
height-h, by maintaining an additional MPT dedicated for the logs.
Block verification is required when mining blocks and retrieving blocks from
the Miners. Block-h in a Key Chain is valid if and only if the following three
conditions
are all satisfied:
Verify MPT(h), ti,j : This function implements a verification mechanism where
an additional pointer links to the past block headers in addition to Hp(h). Here,
Hp(h) denotes the hash of the parent block header, which provides a pointer linking
to the past generation. In contrast, MPT(h) provides a pointer linking to an
arbitrary ancestor block headers. Based on MPT(h), the latest state of Hash(v(i,j)),
provided in (5.3), is matched with the hash value of the random number contained
in ti,j, as stated at the bottom in Fig. 5.4. As long as CT = ABEA(PK), the Key Chain is
updated and edited (the first redactable transaction turning to black color and
getting updated from the outdated version, m(97,1) to the latest version, m0(97,1),
as shown in the top left corner of Fig. 5.4), its related random number v(97,1) is
also updated to the latest version, v0(97,1).
While G(97,1), denoting the CH value of the first redactable transaction in Block97,
remains unchanged as described in (5.4). This also contributes to an unchanged
n(97,1), as shown in the block header on the right-hand side of Fig. 5.4.
Verify hp(h) and Verify c(h) : These function verify the linked structure via
hp(h) and the consensus requirement via c(h), respectively. They are standard to
existing Blockchain systems [135, 191].
In general, the Miners owning the CHSK on a Key Chain can update the
transaction ti,j containing m(i,j) and v(i,j), and append a new Block-h where

127
Hash(v(i,j)) can be traceable via MPT(h). This can ensure the update of CT =
ABEA(PK) without corrupting the linked structure. Note that m(i,j), i.e., the data
field of ti,j, denotes ABEAm{PKAm,Pn} where Am denotes the m-th access policy and Pn
denotes the n-th message. MPT(h) records the state of the hash of v(i,j) on Block-h
associated with each individual update of (ABEAM {PKAM,PN })AAm0,P,P
0n, i.e., all ABEAM
{PKAM,PN } from A0 to Am with messages from P0 to Pn.
5.3.4 New Design of Inter-Chain Protocol
This section elaborates on the design of our proposed Inter-Chain Protocol.
Three subprotocols are discussed separately in Sections 5.3.4.1 to 5.3.4.3. Algo. 1
presents the whole process of data sharing in our system regarding the encryption
and publishing a new message conducted by a DP, and the decryption and
retrieving the new message conducted by entitled DUs. Therein, Algo. 2 describes
the process of the encryption and decryption used in Algos. 1 and 3. Algo. 3
presents the complete process of updating an attribute (both adding and revoking)
by updating blocks on a Key Chain.
5.3.4.1 Protocol of Message Encryption and Publication
We start with the Encryption subprotocol of the Inter-Chain Protocol, with
details in the following (referring to Lines 4-5 of Algo. 1 and Steps (1)-(3) of Fig. 5.2
on the left-hand side, denoted as Fig. 5.2-L),
Step 1: Initialization by TA. The unique TA of a Key Chain takes responsibility for
initializing the system, as shown in Line 1 of Algo. 1 and Step (1) of Fig. 5.2-L.
1. User Register and Attribute Initialization: Entities register at the TA, after
which the TA allocates attributes for each entity as a DU.

128
2. ABE Initialization: The TA generates ABE parameters for each attribute ↵
with the Algorithm ABE KeyGen, as defined in Section 5.2.1.
3. CH Function Initialization: The TA generates the parameters of a chosen CH
algorithm according to CH KeyGen, as defined in Section 5.2.2.
4. Key Distribution: The TA distributes the private ABE parameters ABE ,SK ↵in a
secure channel to the corresponding DUs. Recall that ABE ,SK ↵is identitybased,
i.e., each member of ↵has its own unique ABE ,SK↵. In the meantime, the TA
broadcasts the public ABE parameters ABE ,PK↵,8 ↵to the network, as shown
in Line 2 of Algo. 1.
Step 2: Publish Data by DP. ESKMiner,P (CHSK) assigned to the DUs owning an attribute
Miner ✏{Miner} (attribute Miner satisfies the access policy {Miner}) is published
on the Data Chain by the DP, prior to publishing a new message. Thus, only the
Miners of the Key Chain are entitled to the update process. Every new message is
assigned with such a pair of CH key pair (CHSK,CHPK) regarding a chosen CH
algorithm, where ESKMiner,P (CHSK) is stored in the Data Chain and CHPK is publicly
broadcast, and ABEMiner(PKMiner,P ) is stored in the Key Chain.
Then a DP publishing a new message PT is subject to the following procedures to
generate two transactions, one in the Data Chain and the other in the Key Chain;
see Steps (2) and (3) of Fig. 5.2-L.
1. Define Access Policy: The DP defines the access policy, {A}, to its data PT, i.e.,
PT is only accessible to the DUs whose attributes satisfy the access policy {A}.
129
2. Generate Conversation Key: The DP generates11 a pair of conversation keys
(SKA,P ,PKA,P )12 for the access policy {A} DP also generates a pair of
conversation key (SKMiner,P ,PKMiner,P ) to publish the CH private key CHSK based
on the {Miner}; see Line 3 of Algo. 1. Here, (SK,PK) is short for (SKA,P ,PKA,P ) in
the rest of the paper for simplicity.
3. Encrypt Conversation Key: The DP uses the ABE algorithm ABE Encrypt to
encrypt the conversation (public) key PK to CT = ABEA(PK). Here,
ABEA(PK) denotes the ABE ciphertext of PK with its access policy {A}. The
corresponding attribute scheme is shown on the bottom-left of Fig. 5.2-L,
where an attribute User ⇢↵, User ✏A exists.
4. Generate Transaction for Conversation Key: The DP generates and uploads a
transaction to the Key Chain; see Line 1 of Algo. 2. Here, the transaction
contains CT = ABEA(PK), and the corresponding CH value and random
number. This transaction is denoted as ti,j after the successful mining of the
transaction on the Key Chain.
5. Encrypt Data: The DP encrypts PT to the ciphertext CT by using the
conversation (private) key SK, and then CT = ESK(PT). Here, E denotes the
encryption operation of the chosen encryption algorithm.
11 The key generation depends on the data encryption algorithm, which is chosen according to
specific applications and beyond the scope of this paper.
12 In fact, the conversation keys, (SKA,P,PKA,P), can be a symmetric or an asymmetric key pair,
depending on the chosen encryption algorithm. To simplify the illustration, we only discuss the case
of asymmetric encryption algorithm and conversation keys in the rest of this paper. In the case of
symmetric keys, the encryption key SKA,P and the decryption key PKA,P are identical,
i.e., SKA,P = PKA,P.

130
6. Generate Transaction for Data: The DP generates a transaction based on the
encrypted message CT and uploads to the Data Chain. This transaction, tP ,
contains the indexes i and j of ti,j to its encrypted conversation key ABEA{PK},
i.e., the j-th transaction of Block-i on the Key Chain where
ABEA{PK} is stored, in order to identify the location of CT in the Key Chain. As
such, a private message can be successfully published after mining in the
Data Chain.
5.3.4.2 Protocol of Message Decryption and Retrieval
We proceed with the Decryption subprotocol of the Inter-Chain Protocol.
This subprotocol only contains one step, Access to Data by DUs. In the case that
a DU/Miner is to obtain the message PT in the transaction tP , two procedures take
place to retrieve the decryption key PK by decrypting the CT in a Key Chain; also see
Lines 6-7 of Algo. 1 and Steps (1)-(3) of the right-hand side of Fig. 5.2, denoted as
Fig. 5.2-R.
1. Retrieve Conversation Key from Key Chain: As mentioned in Steps 2-(2) to 2-
(6) in Section 5.3.4.1, tP of the Data Chain stores the index to its encrypted
conversation key in the Key Chain. The DU first retrieves the indexes i and j
from transaction tP , and then obtains the latest ABEA{PK} in ti,j from the Key
Chain. If the attributes of the DUs satisfy the access policy {A}, e.g., Users in
Fig. 5.2-R, the DUs can retrieve the conversation key PK by decrypting
ABEA{PK} with the corresponding private key ABEUser,SK. Here the decryption
algorithm refers to ABE Decrypt; also see Line 9 of Algo. 2.

131
2. Retrieve Data from Data Chain: By using the conversation key PK and the
encrypted message CT in transaction tP , the DU can decrypt CT to PT =
DPK(CT), referring Line 10 of Algo. 2. Herein, D is the decrypt algorithm,
corresponding to the encrypting algorithm E.
Algorithm 1: The whole process of data sharing
. Define
Receiver ( Sender.Send(Message); // This transmission is secured by any private and
encrypted channels, e.g. TLS.
. Initialization Phase
1(ABEm,SKn,SK ,ABEm,PKn,PK )TA.Initialize(); // TA initializes the system and generates ABE key
pairs from attribute m to n.
2Public Network ( TA.Send(ABEm,PKn,PK ) and Nodesnm ( TA.Send(ABEm,SKn,SK ); // Nodesnm indicates nodes that
have attribute m to n, respectively.
3(SKMiner,P,PKMiner,P), (CHSK,P,CHPK,P), (SKUser,P,PKUser,P) DP.Initialize(); // A DP planning to publish a
message P generates three key pairs, i.e., (SKMiner,P,PKMiner,P) (CHSK,P,CHPK,P) and
(SKUser,P,PKUser,P), where {Miner} and {User} are the corresponding attribute policies.
Meanwhile, CHPK,P is broadcast to the network.
. Encryption Phase
4DP.Encryption(SKMiner,P,CHSK,P,ABEMiner,PK, PKMiner,P) // Miner is an attribute belonging to
attributes set ranging from m to n.
5DP.Encryption(SKUser,P,PT,ABEUser,PK,PKUser,P); // User is an attribute belonging to attributes
set ranging from m to n.
. Decryption Phase
6PT Decryption(ABEUser,SK, ti,j); // A DU satisfying {User} retrieves the indexes i and j stored in
a block in the Data Chain. After that, the DU retrieves PT with ti,j, where ti,j denotes
the j-th transaction of Block-i in the Key Chain.
7CHSK,P Decryption(ABEMiner,SK, ti,j); // A Miner of the Key Chain satisfying {Miner}
retrieves the indexes i and j stored in a block in the Data Chain. After that, the
Miner retrieves CHSK,P with ti,j.

132
. Notice
8Encryption() and Decryption() are shown in Algo. 2.
9ABEm,SKn,SK during this process is identity-based, which indicates that each member has a particular attribute m has
its own ABEm,SK.
Algorithm 2: The encryption process Encryption() and the decryption
process Decryption() . Encryption()
Input: SK, PT of the message, ABEPK, PK
Output: A new block appended to the Data Chain and the Key Chain, respectively
1BlockKey,Pending SendChameleonTx(ABEPK.Encrypt(PK), CHPK); // The DP encrypts
PK by using the ABEPK, i.e., CT, and Chameleon-hashes the ciphertext by using the
CHPK prior to inserting it into a new pending block of the Key Chain.
2while Consensus do
3Miner.Verify(BlockKey,Pending);
4i f BlockKey,Pending is invalid then
5alarm and exit
6Key Chain, i, jBlockKey,Pending; // Append the new block to the Key Chain, obtain the index j
of the transaction in Block-i.
7Data Chain BlockData,Pending SendNormalTx(SK.Encrypt(PT), i, j); // The DP encrypts PT by using the
SK, and hashes the ciphertext prior to inserting into a new pending block of
Data Chain, along with the corresponding i and j.
. Decryption()
Input: CT, ABESK, ti,j
Output: PT of message
8CT Find(ti,j); // The DU retrieves CT with given ti,j in the Key Chain.
9PK ABESK.Decrypt(CT);
10 PT PK.Decrypt(CT);
. Notice
11 ABE PK.Encrypt(PK) refers to ABE Encrypt shown in Section 5.2.1, where PT = PK, the attribute policy assigned to
PK = {A};
13 ABE SK.Decrypt(CT) refers to ABE Decrypt shown in Section 5.2.1, where the attribute policy assigned to CT = {A}.
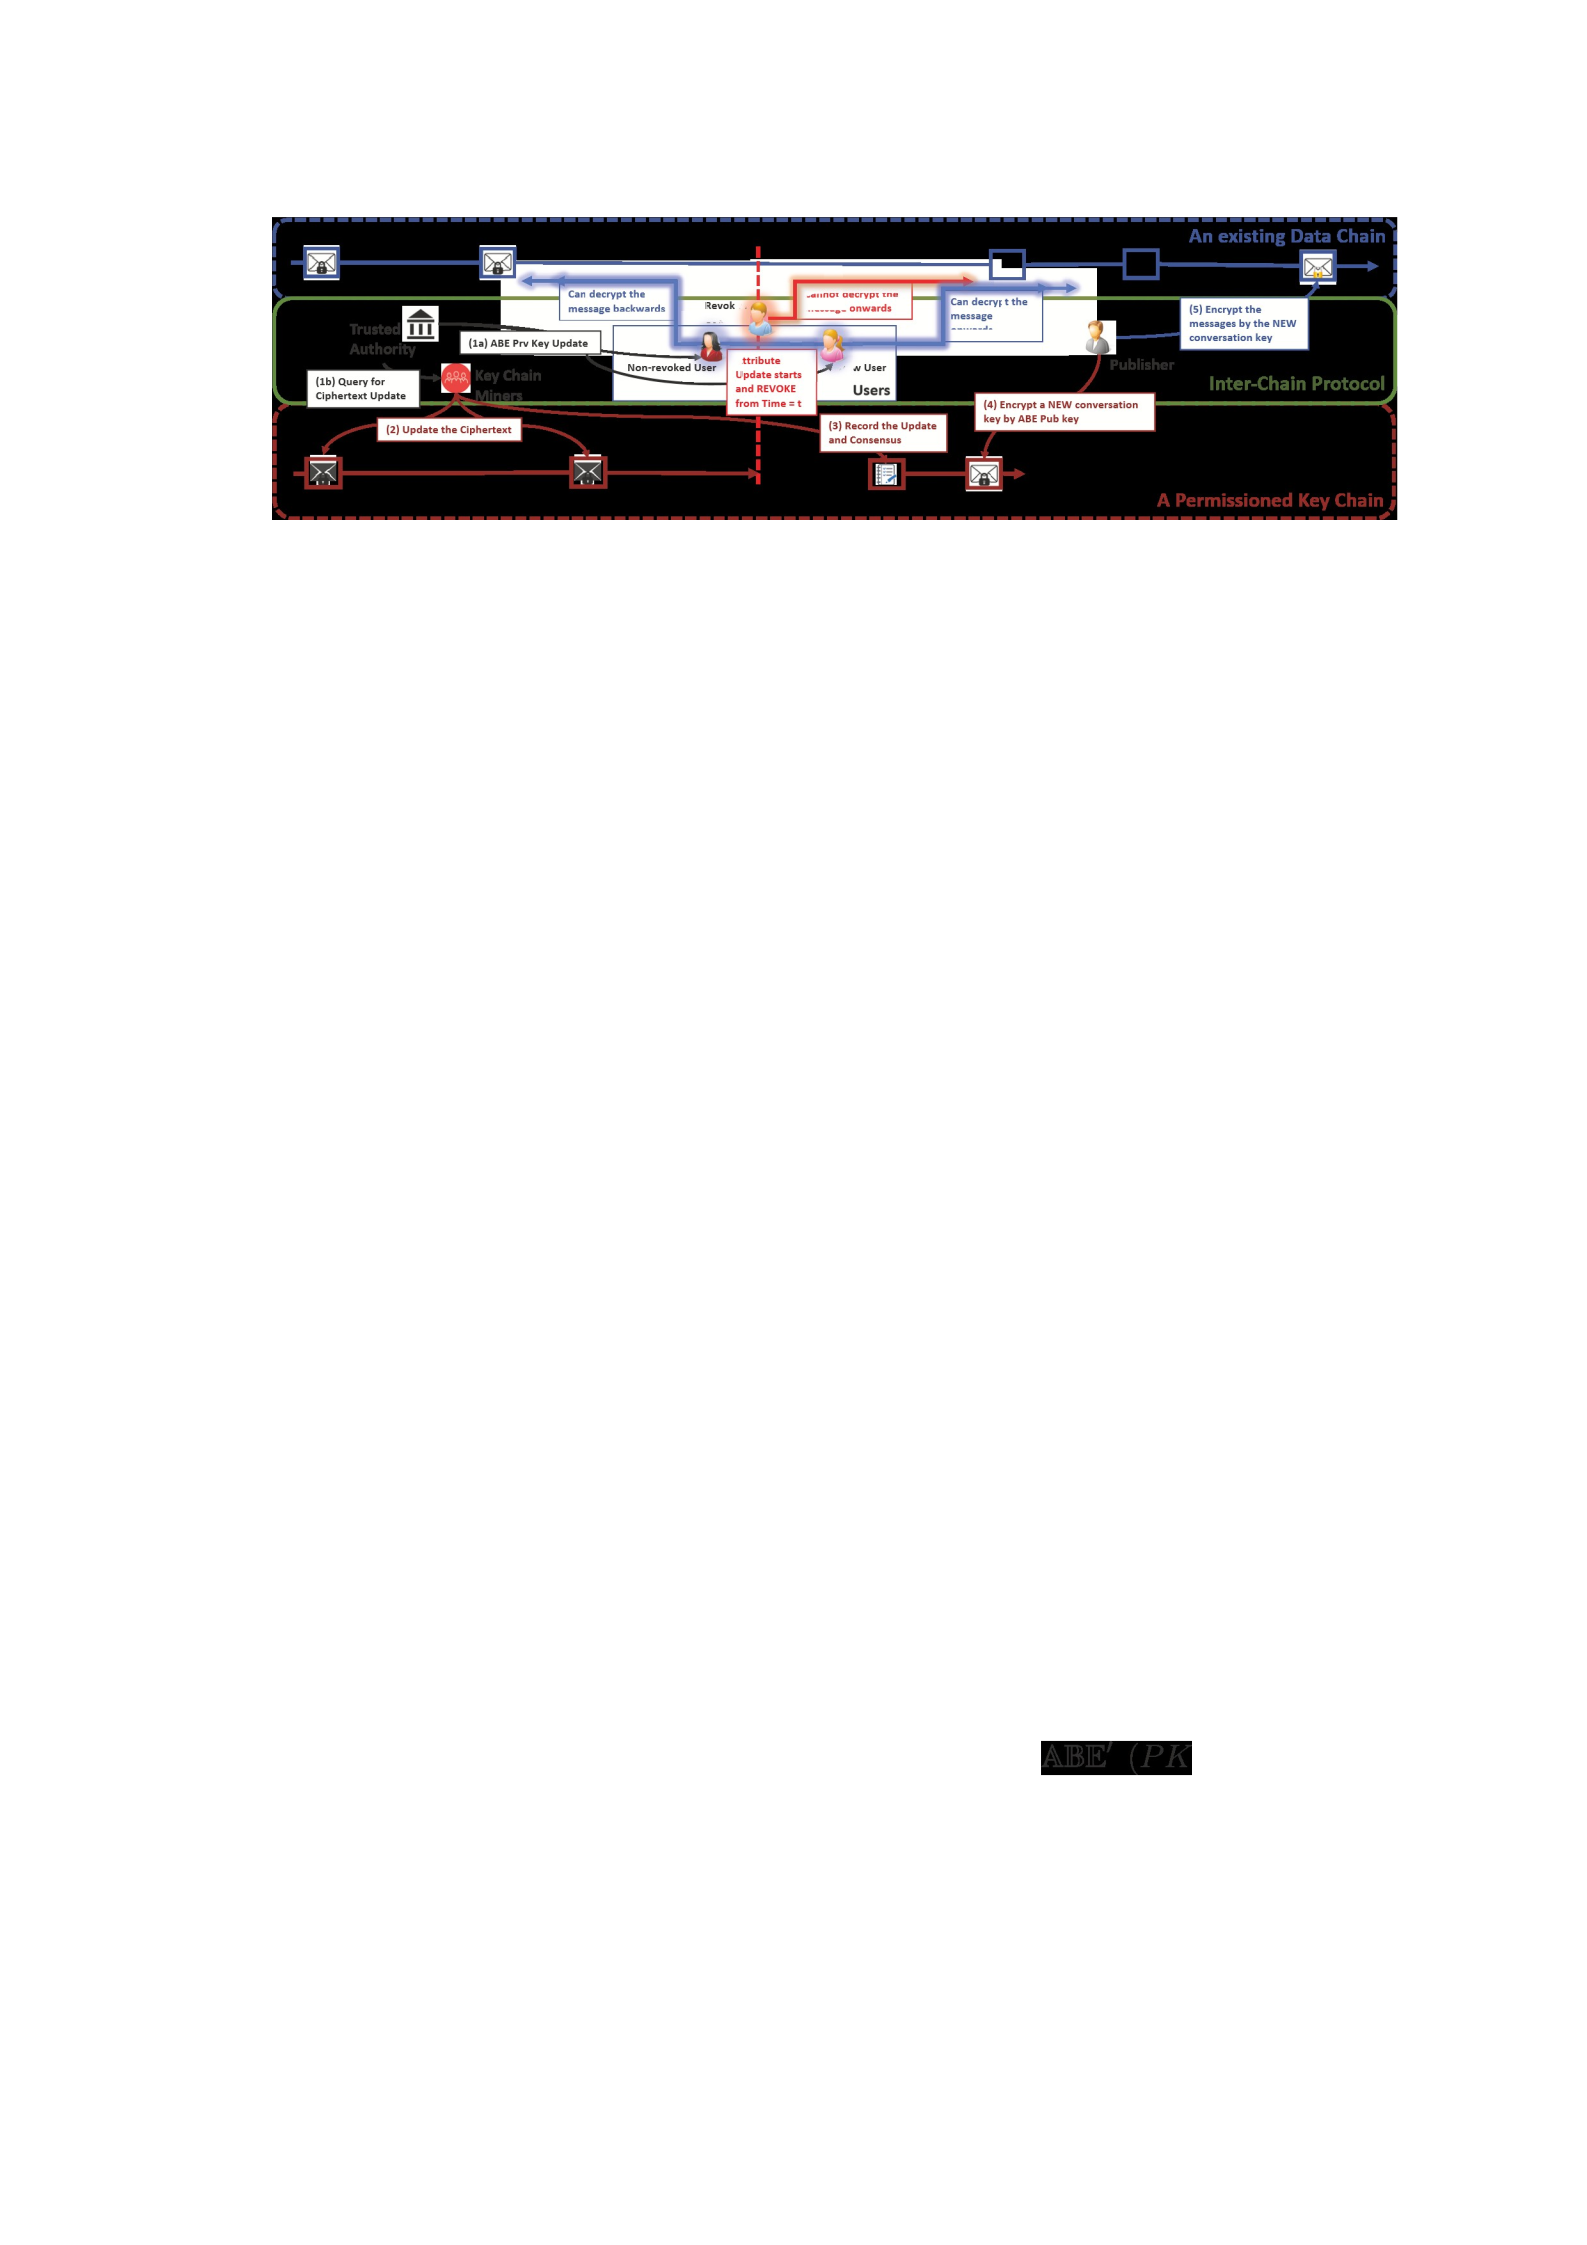
133
Figure 5.5 : The process of an attribute update is shown. Only the non-revoked DU and new DUs
obtain the updated ABE private key, so that they can access to all related data across the Data Chain.
In contrast, the revoked DU can only access to the history with the outdated ABE private key and
updated ciphertext edited by the miners.
5.3.4.3 Protocol of Attribute Updates on a Key Chain
This section describes the Attribute Updates in the Inter-Chain Protocol. In
the case that new members are to be registered in attribute α, or current members
are to be revoked from α, the Data Chain remains stable while the Key Chain
updates those blocks which store encrypted conversation keys assigned with
access policy {A} satisfied by α, i.e., ABEA(PK), α A. The detail of updating in a Key
Chain is shown as follows.
Step 1: Update the Ciphertext in the Key Chain. The TA runs ABE Update and
sends entities the corresponding updated attribute parameters in any secure and
encrypted channel; see Define of Algo. 1, Lines 1-2 of Algo. 3 and Steps (1a) and
(1b) of Fig. 5.5. After that, each Miner calculates the updated CT for any of its
conversation keys PK whose access policy {A} can be satisfied by α. Here the CTs
before and after the update are denoted as ABEA(PK) and A ),
respectively.

134
Step 2: Update Transactions in the Key Chain. In Lines 5-6 of Algo. 3, with the aid
of the CHSK, each Miner overwrites CT via the given indexes i and j with the updated
CTUpdate; also see Step (2) of Fig. 5.5. Then by including the updated

Algorithm 3: The update process of members with specific attributes
. Define
All functions inherited from Algo. 1
Input: An attribute ↵
. TA Computation phase
1(UFSK, UFCT)TA.ComputeUpdate(↵); // TA computes the updating factor (UF) associated
with an attribute ↵.
2Nodes ↵( TA.Send(UFSK) and Miner ( TA.Send(UFCT); // TA sends the updating factor of SK to the
non-revoked nodes and the updating factor of CT to nodes assigned with
{Miner}.
. Ciphertext updating phase
3CT Find(ti,j); // Miners retrieve CT with given ti,j in the Key Chain.
4CTUpdated Miner.UpdateCT(CT, UFCT)
5Miner.Overwrite(CTUpdated, ti,j, CHSK); // Miners overwrite the outdated CT with
CTUpdated in ti,j by using CHSK obtained from Line 7 of Algo. 1.
6BlockKey,Pending Miner.UpdateMPT(Hash(CTUpdated.Random)); // The Miners update the latest
state of Hash(CTUpdated.Random) in a new pending block of the Key Chain.
7while Consensus do
8Miner.Verify(BlockKey,Pending);
9i f BlockKey,Pending is invalid then
10 alarm and exit
11 Key Chain, i, jBlockKey,Pending; // Append the new block to the Key Chain, obtain the index j of
the transaction in Block-i.
. Private key updating phase
12 ABE↵0 ,SK Nodes↵.UpdateABE SK(ABE ,SK↵, UFSK); // ABE↵0 ,SK is unique for each member of ↵, i.e.,
identity-based.
13 PT Nodes↵.Decryption(ABE↵0 ,SK, ti,j); // The non-revoked nodes can then decrypt
CTUpdated in ti,j by ABE
↵0 ,SK.
14 Nodenew, ↵( TA.Send(ABE↵0 ,SK) and PT Nodenew,↵.Decryption(ABE↵0 ,SK, ti,j); // A new member of attribute
↵can also conduct the decryption.
. Notice
15 ComputeUpdate, UpdateCT and UpdateABE SK constitute ABE Update shown in
Section 5.2.1.
MPT(h) in each of the new pending Block-h, with the latest state of the hash of the
updated random number related to CTUpdate, a consensus process runs to complete
appending Block-h to the Key Chain; see Lines 7-11 of Algo. 3 and Step (3) of Fig.
5.5. Note that a Practical Byzantine Fault Tolerance (PBFT) (or a PBFT-like)
consensus algorithm [40] with a lower-bounded number of faulty nodes N 3f + 1 is
usually considered in a permissioned Blockchain, where N denotes the number of
Miners and f denotes the number of faulty Miners. The proposed verification
scheme is applied during this process to ensure the consistency among the Miners
to prevent a malicious Miner from conducting a false update to expose an outdated
version of the message.
When a DP publishes a new message with a new PK assigned to attribute ↵
after the revocation; refer to Steps (4)-(5) of Fig. 5.5, it can be found in Lines 1114
of Algo. 3 that only the non-revoked DUs with attribute ↵and the new DUs can
conduct the decryption process to any messages on the Data Chain assigned
to attribute ↵by their own updated . Recall that is identity-
based. On the other hand, the revoked members fail to conduct the following after
this update event (update-oriented):
• retrieve the new PK, e.g., PKA,P2 in the absence of its corresponding new
ABE ,SK↵
• directly retrieve the past PK before the revocation from an updated
via its own outdated ABE ,SK↵.
This is because the revoked members of attribute ↵do not have the updated
ABE ,SK ↵regarding the CTUpdate after an update happens. Meanwhile, the revoked
members cannot directly access the outdated CT from the past blocks of the Key

Chain as CT has been overwritten without breaking the linked structure by using
the CH algorithm. In contrast, the non-revoked DUs and new DUs of ↵have the
latest updated ABE↵0 ,SK. This indicates that they can decrypt any CTUpdates in the
past and any future new CTs, where their attribute ↵ ✏{A}.
5.4 Analysis and Evaluation
In this section, we present the system analysis and simulation in terms of
energy, scalability, compatibility, and security.
5.4.1 System Analysis
5.4.1.1 Energy Overhead
We consider the IoT devices are typically FPGA (e.g., AVNET’s Zedboards) or
SBCs (e.g., Raspberry Pi) which can be the DU or DP in the analysis regarding the
energy overhead. Such IoT devices are considered to be able to handle the
following behaviours, as illustrated in Fig. 1, including
• conducting the cryptographic operations for conversation keys and ABE
cryptographic operations (encryption/decryption);
• signing transactions by themselves when publishing new messages; and
• exchanging network packets with the higher layer devices (e.g., the edge
network or the core network).
Any other devices that are incapable of delivering and handling the above
behaviours are considered to be the data collectors (e.g., sending sensor data to

SBCs). It is pointed out that the proposed system is suitable for typical IoT systems
with such IoT devices for the following two reasons.
Firstly, it is not the responsibility for IoT devices to maintain the chains, as
illustrated in the table on the right-hand side of Fig. 5.1. Rather, it is the su ciently
powerful machines (cloud servers or local data centres) that are in charge. The
CHoriented overhead of the update process is conducted by the miners of Key
Chains, while the miners also tend to be located in cloud or local data centres. As
such, IoT devices only deal with the overhead of running the cryptographic
operations and transmitting the ciphertext.
Secondly, a cluster of Key Chains is designed to provide di erentiated access↵
control of the data chain for di erent organizations and communities, so that the↵
overlapped attributes in di erent contexts (di erent ↵ ↵ Key Chains) can be properly
managed. This enables IoT devices to be usually involved in only a single Key Chain
and the Data Chain, so that the total communication and computation overhead on
IoT devices can be regarded as the overhead between the Data Chain and a single
Key Chain.
Upon the considered communication and computation overhead that excludes
the Blockchain maintenance for IoT devices running across the Data Chain and the
related Key Chain, we present the following energy analysis.
Computation overhead and performance:
Our proposed system can be suited to IoT systems in terms of the computation
overhead and performance. We take Raspberry Pi for an example, because of its
popularity as an SBC. To be specific, the computation overhead mainly includes 1)
the en/decryption of the (a)symmetric encryption algorithm; and 2) the
en/decryption of the ABE algorithm. A DP publishing a message needs to conduct
the encryption process, while the decryption process accounts for the computation
overhead that a DU needs to incur. We utilize the metrics proposed in [11],
Execution Time (denoted as t, and measured in second). We also define the
number of the complete process flows under the given condition (T ) to
evaluate the energy e ciency/consumption, as given by
,
where C denotes the battery capacity measured in mAh; V denotes the working
voltage of the tested Raspberry Pi measured in Volt; and ⌘refers to the proposed
metrics in [11], i.e., the Energy Consumption for a single execution measured in J.
It can be concluded from Table 5.2 that, even the most energy-consuming type
of Raspberry Pi, i.e., 1B, can execute the encryption operation around 18,800 times
and the decryption operation 30,000 times with a 10,000mAh battery, in the
context of an 80-bit security level. The most energy-e cient type, Zero, and the most
powerful 4B can both execute the encryption operation around 60,000 70,000⇠
times and the decryption operation around 90,000 100,000 times with the same⇠
battery life. In contrast, the optimized CPU performance of 4B can potentially
improve tABE,en to around 10s and tABE,de to around 9s with a security level of 128
bits under 30 attributes, respectively. In such context with a stronger security level,
Raspberry Pi 4B can still execute the encryption operation around 6,000 times and
the decryption operation around 6,700 times. As a result, 4B can even be used in
scenarios with a fixed power supply, e.g., CCTV cameras or solar-based devices, so
that higher computation performance (compared to 1B and Zero) can guarantee a
stronger security level, at the cost of a slightly higher energy consumption.
Communication overhead and performance:
Our system is also suited for IoT systems in terms of communication overhead
and performance (with Wi-Fi, or even more energy-saving protocols where
messages can be chunked into pieces, e.g., LoRa, NBIoT, and Zigbee). As a DP, an IoT
device uploads the ciphertext of messages and ciphertext of the conversation key
(i.e., CT and CT, respectively) to the Data Chain and Key Chain. The DP (playing the
role
Table 5.2 : It shows the computation overhead and performance comparison between di erent↵
types of Raspberry Pi with a security level of 80 bits under 30 attributes (the last column shows the
performance of 4B with a 128-bit security level under 30 attributes); C = 10,000mAh, V = 3.3V and
5V. We focus on the cryptographic operations. The typical AES scheme proposed in [51] with
pipelining is used to encrypt (and protect the confidentiality of) conversation keys. We consider the
widely accepted CP-ABE scheme [27] which is part of AndrABEn, an open source ABE library
particularly optimized for Android/smartphone/IoT operating systems. The ABE library has been
adopted in many existing studies, e.g., [11, 12].
Raspberry Pi 1B Zero 2B 3B+ 4B 4B (120-bit)
Encryption ( AES*+ABE**)
ten (tAES,en + tABE,en)†5.30s 5.30s 3.40s 1.87s 1.06s 10.30s
⌘3.3V 6.31J 1.75J 2.58J 2.47J 2.01J 19.57J
5V 9.54J 2.65J 3.91J 3.74J 3.05J 29.67J
T
3.3V 18,836 67,925 45,975 48,128 58,987 6,071
5V 18,868 67,925 46,036 48,128 58,962 6,068
Decryption ( AES*+ABE**)
tde (tAES,de + tABE,de)†3.30s 3.30s 2.11s 1.19s 0.66s 9.30s
⌘3.3V 3.93J 1.09J 1.60J 1.57J 1.25J 17.67J
5V 5.94J 1.65J 2.43J 2.38J 1.90J 26.78J
T
3.3V 30,252 109,091 74,083 75,630 94,737 6,723
5V 30,303 109,091 74,181 75,630 94,697 6,720
* The data is sourced from [167] based on the pipelining scheme [176].
** The data is sourced from [211, 7].
† ten and tde denote the execution time for encyption and decryption, respectively. tAES,en and tAES,de are
considered to be equal. tAES,keygen can be negligible because of the
pipelining [176]. tAES,keygen can also be negligible as it is the TA’s responsibility.
of DU) also downloads the CT and CT from the Data Chain and related Key Chain,
respectively.
Transmitting CT: As block ciphers, the size of CT is nearly equal to that of PT. A
1MB message is considered in the computation analysis, which has been proved
acceptable based on the result [44, Tables III - VIII].
Transmitting CT: According to [187], the communication overhead of
transmitting CT is 50kB, 96kB, and 140kB, for 80-bit, 112-bits, and 128-bit security
level, respectively. The overhead consists of, 1) transmitting CT; and 2) receiving
the up-
dating factor of in some ABE algorithms) from the TA whenever
an attribute is updated. The latter happens infrequently in practice so that we can
focus on the former, which are 25kB, 48kB, and 70kB, as the two aspects of the
overhead share the overhead on a fifty-fifty basis [47, Fig. 5]. Thus, Wi-Fi satisfies
such overhead based on the normal LAN throughput of Raspberry Pi [211]. It is
noteworthy that the energy consumption of Wi-Fi is about 10% more than the case
where all communication modules are turned o [125].↵
5.4.1.2 Scalability and Compatibility
Because of the editability of our proposed system, this analysis focuses on the
scalability of a Key Chain with the redactable data structure, as well as the
compatibility of our system integrated with a cloud-based system. We develop a
Pythonbased testbed which is based on a popular (4.7k stars) Python-based open
source platform13 and the Charm Crypto native libraries6. The testbed allows us to
run multiple entities on a single machine. We can simulate multiple nodes with
di erent roles (i.e., the TA and miners typically located in clouds/data centers, and↵
13 https://github.com/dvf/blockchain
6https://github.com/JHUISI/charm
the DPs/DUs typically running on IoT devices) on a single 2017 iMac with 10.13.3
macOS High Sierra, a processor of 2.3 GHz Intel Core i5 and 16 GB 2133 MHz DDR4
memory.
Scalability: We conduct a comparison among our three proposed data
structures of MPT(h) (see description below (5.3)), and the state-of-the-art design
developed in [154] regarding the overhead and searching complexity of H, K and R,
where the notations are described as follows.
•H, (blocks): the Block Height, starting from a block where a given CT being
inserted or updated to the latest block.
•K, (inserts/blocks): the Insert Rate, the average rate for DUs to insert CTs in a
Key Chain.
•R, (updates/blocks): the Update Rate, the average rate of attribute updates
being applied in a Key Chain.
Recall that the data structures discussed in this paper correspond to the world
state and smart contract used in Ethereum [191]. In the segment figures, the blue
curves denote the structure of engraving transaction; the red curves denote that of
storing Hash(v(i,j)) in a smart contract as a pure variable in the existing world state
MPT; the green curves denote that of storing Hash(v(i,j)) as a new dedicated MPT
in addition to the MPT world state; the gray curves denote that of storing CT in a
smart contract as a pure variable in the existing world state MPT, vaguely discussed
in [154]14. For the red and gray curves, there exist the unrelated addresses of
14 We can assume that CT is directly stored as a variable in smart contracts rather than storing
Hash(v(i,j)), as the overwriting or purge of the on-chain-stored outdated CT by the latest updated
version is not discussed in [154]. This implies that [154] has no new verification scheme for the
normal accounts and smart contracts in the same Key Chain, the number of which is
denoted as C. C has an apparent impact on the searching complexity.
Figure 5.6 : The comparison among our three proposed structures and the structure proposed in
[154] regarding the storage overhead with respect to H, where R = K = 1000. Note that the y-axis
denotes the storage complexity.
Overhead: It is shown in Fig. 5.6 that in the case of K ' R with the growth of H,
the green, red, and gray curves have a linear growth rate. The green grows more
slowly than the red and gray, with an increasing gap between the green and red
curves. The blue curve grows the most quickly with an intersection point to the
gray curve at around H = 60, which is at quite an early stage. In the case where a
large value of H is expected to appear in a Key Chain, the blue curve has a superior
growth rate, while the growth rate of the green curve is the lowest.
In Figs. 5.7 and 5.8, we conduct a controlled-experiment that the values of K and
R are set to be the independent variables respectively with a certain H = 10000, in
order to investigate the correlations between K and the growth rate, and between R
update process.
90 100100 20 30 40 50 60 70 80
0
0.5
1
1.5
2
2.5
Storage
108
Engraving Transaction
Smart Contract with Hash of Random
MPT of Hash of Random
Smart Contract with CT Storage of Engraving
Transaction increases
the most quickly
The gap increases as H
gets increased

and the growth rate. We also choose two di erent values of ↵R in Fig. 5.7 and K in
Fig. 5.8 to evaluate the side e ect of one to another.↵
It is shown in Fig. 5.7(a) that the blue curve, which starts with the largest storage
space, has the smallest growth rate as K increases from 0 to 3000 inserts/block
with R = 1 updates/block. This can be found at the intersections where K ' 2500, as
shown in the sub-figure in the bottom right corner of Fig. 5.7(a). The red curve has
the largest growth rate as K increases. For a large value of R = 1000 within the
range of K from 0 to 300000 in Fig. 5.7(b), the blue curve has a superior growth
rate. The gray curve intersects the red curve right after K ' 2000 and increasingly
approaches the green curve as K increases. The growth rate of the green curve
remains the lowest throughout the range. It can be concluded that K has a strong
impact on the red curve, and a negligible impact on the blue curve among all these
structures. Nevertheless, the blue curve is strongly impacted by a large R, while the
green curve performs the best among all these structures throughout the range of K
regardless of the value of R.
It is shown in Fig. 5.8(a) that the blue curve has a superior growth rate among
these structures, the gray curve performs the second to the worst, and the green
curve has the lowest growth rate. As shown in Fig. 5.7, K has a much stronger
e ect on the gray, red and, green curves than the blue curve. As such, for a small↵
value of K = 1 where R 2 [0,200], it can be concluded that the blue curve is
incapable of the storage for a Key Chain. If a large K is set, e.g., K = 100000, shown
in Fig. 5.8(b), the blue curve performs the best when R 40. As R increases, the
blue curve grows sharply, while the green curve increases slowly with the lowest
growth rate. It can be concluded that R has the strongest e ect on the blue curve,↵
and the weakest e ect on the green curve.↵
The green curve is the most appropriate data structure implemented in the
scheme of an attribute update, if the settings of the Key Chain that might happen in
a realistic environment are taken into account, as shown in the following,
•K is much likely greater than R;
(a) K [0∈,3000], R = 1 (b) K [0∈,300000], R = 1000
Figure 5.7 : The comparison among our three proposed structures and that of [154] regarding the
overhead with respect to a constant H = 10000 and an upper bound of K in two di erent values of↵
R. Note that the y-axis denotes the storage complexity.
• both values of K and R are likely within the range of (0,10000) due to the
throughput restriction15 of the commonly used consensus algorithm in a Key
Chain, i.e., PBFT.
Therefore, it is unrealistic to set a su ciently large value of K to support better
performance of the blue curve among all these structures. On the other hand, the
green curve has the most stable and smallest growth rate with respect to both R
and K. It is expected to be the most appropriate structure to update the attribute in
a Key Chain.
15 The throughput (transactions per second) is limited in the case where the Byzantine tolerance
needs to be satisfied [133].
Searching Complexity: As Engraving Transaction has a searching complexity of
at least O(HR), which is significantly greater than the other three which are only in
a logarithmic order, we only compare Smart Contract with Hash of Random (the
red curve in Figs. 5.6-5.8), Smart Contract with CT (the gray curve in Figs. 5.6-5.8)
and MPT of Hash of Random (the green curve in Figs. 5.6-5.8). Also because an
inner MPT used in a smart contract is implemented in both Smart Contract with
(a) R [0∈,200], K = 1 (b) R [0∈,200], K = 100000
Figure 5.8 : The comparison among our three proposed structures and that of [154] regarding the
overhead with respect to a constant H = 10000 and an upper bound of R in two di erent values of↵
K. Note that the y-axis denotes the storage complexity.
Hash of Random and Smart Contract with CT, which doubles the depth of the MPT,
Smart Contract with Hash of Random and Smart Contract with CT have the same
searching complexity, i.e., O(log(HK +C)), as shown by the blue curve in Fig. 5.9. On
the other hand, MPT of Hash of Random has a searching complexity of O(log(HK)),
as shown by the red curve in Fig. 5.9. It can be concluded that the red curve has a
smaller growth rate than the blue curve, according to Fig. 5.9. As the value of C
increases and asymptotically stabilizes, the performance of the blue curve
converges to that of the red curve.
Therefore, it is the most appropriate to introduce a new dedicated MPT for
storing Hash(v(i,j)) in a practical implementation of the Key Chain based on both
the overhead and searching complexity (MPT of Hash of Random, the green curve
in Figs. 5.6-5.8 and the red curve in Fig. 5.9). In contrast, if the unchanged structure
of block headers is preferable, e.g., Ethereum, for backward compatibility with the
existing Blockchain, Hash(v(i,j)) can be stored in the existing the world state MPT
as a pure variable (Smart Contract with Hash of Random, the red curve in Figs. 5.6-
5.8 and the blue curve in Fig. 5.9). Also, Engraving Transaction (the blue curve in
Figs. 5.6-5.8) can be used in a testing environment where the complexity is not the
Figure 5.9 : The comparison among our proposed structures and that of [154] regarding the
searching complexity with respect to H, where R = K = 1000, C = 1000000. Note that the y-axis
denotes the searching complexity.
focus because of its simple implementation.
Compatibility: It is worth noting that our proposed system is a general
decentralized framework and is generic to all the consensus protocols, cross-chain
protocols, and cryptographic algorithms. Although we do not encourage completely
relying on cloud services due to risks on the reliability, traceability, and
transparency, the proposed structure and protocols complement to cloud services,
1000080006000400020000
6
8
10
12
14
16
18
Searching Complexity
Stored in Smart Contract
MPT of Hash of Random

rather than a competitor. In our scenario, Blockchain is considered to be a
decentralized data structure, while part of the nodes storing a copy of data running
on the cloud servers can be a better option. As such, either faulty cloud servers or
attacks on cloud servers cannot have strong impacts on our proposed Blockchain
system.
5.4.2 Security Analysis
This analysis focuses on the security of our entire multi-layer Blockchain
system. The TA is supposed to have the highest security level and the immunity to
cyber and physical attacks, as is typically assumed in ABE systems (this assumption
still holds for multi-authorities as the trust is only alleviated for a single authority
while the wholeness must be still trusted [42]).
Attack model: External and internal adversaries target to break the
confidentiality and integrity of the data recorded in Blockchains. Here, the external
adversaries are nodes which can only obtain the public information, such as the
ciphertext of a message CT in the Data Chain and/or the public key of an attribute
↵, i.e., ABE ,PK↵. The internal adversaries can be categorized into two types, • the
nodes which used to be legitimate and now are revoked in regards to a specific
attribute, and have not had their ABESK updated;
• the nodes which have been assigned with a specific attribute Miner (Key
Chain).
In an update process, the internal adversaries can conduct a false update to
compromise the integrity (or in other words, tamper-resistance) of the redactable
Key Chains with legal identities and valid keys, i.e., ABESK. The proposed
architecture is expected to be secure against the two types of adversaries in terms
of the confidentiality of the published messages in the Data Chain and the integrity
of the updated ciphertext CTUpdate in the Key Chains.
Confidentiality: We consider that an external or internal adversary targets to
obtain the encrypted message CT stored in the Data Chain which must not be
accessible to the adversary, i.e., the adversary does not own any attribute ↵
satisfying the access policy {A} of CT. In the proposed system, the original message
P is encrypted to CT and stored in the Data Chain, while the decryption key PKA,P is
encrypted by an ABE algorithm to be CT = ABEA(PKA,P ), as described in Section
4.2.
For an external adversary whose attribute ↵has never satisfied the access
policy {A} before, the adversary cannot decrypt CT = ABEA(PKA,P ) to obtain PKA,P , as
can be guaranteed by the security of the ABE algorithm. Therefore, the external
adversary does not have the decryption key PKA,P and cannot extract the message P,
as guaranteed by the security of the (a)symmetric encryption algorithm.
For an internal adversary whose attribute has once satisfied the access policy
{A}, the attribute and the encrypted conversation key CT are updated. As a result,
the revoked adversary without the correspondingly updated version of ABE ,SK
cannot decrypt CT to obtain the decryption key PKA,P ; see the revocation design in
Section 4.4.3. As a result, the internal adversary cannot directly access the message
P, as it is unaware of the decrypted key PKA,P . 16
Integrity/Anti-Tampering: The integrity can be guaranteed as long as the
lower bounds of faulty tolerance of consensus protocols (e.g., 33% for PBFT [40] or
50% for PoW [135]) are all satisfied among the Data Chain and Key Chains. The
history of updates is immutable and verified during the consensus. Because of the
16 A direct access indicates an on-chain access, i.e., data being looked up directly from the Key
Chain, but not replicating a copy locally.

synchronization among the miners [40] in a permissioned Blockchain where a
PBFT (or PBFT-like) consensus is implemented, an internal adversary with an
attribute Miner conducting a false update (it is possible due to identical CH values)
and providing an outdated version of blocks to any DUs would fail to synchronize
with other honest Miners and would be detected by the system, as discussed in
Section 4.3.2. Therefore, by means of punishment for the internal adversaries
found conducting a false-update attack, the integrity and tamper-resistance of
Blockchains can still be ensured in our proposed system. In addition, the updated
ciphertext, CTUpdate, is attached with the signature of the leader of the current
consensus round. As a result, there is no need for the DPs to remain online, and the
man-in-the-middleattack can be prevented.
5.5 Conclusions
Remark that the content needs to be editable to fulfill the changes of attributes
in an ABE-based Blockchain that provides fine-grained access control, how the
contradiction can be solved between this requirement and the immutability of
Blockchains has been resolved in this chapter. We proposed a new Blockchain
system with finegrained access control for IoT applications, where the membership
and attributes of individuals, i.e., data owner, user, and miner, can be updated
securely in anti-tamper
Blockchains by integrating CH algorithms in a new multi-layer chain architecture.
The system addresses direct data leakage caused by revoked members, and
maintains good compatibility with major consensus protocols, cross-chain
protocols, and encryption algorithms. The system can be further optimized by
having multiple

TAs in a decentralized manner to guarantee the superior security level of the TA.
Our system analysis and simulation show that the proposed system can
outperform existing solutions in terms of overhead and complexity.
By utilizing the proposed system, a secure, manageable and decentralized data
access control which enables large-scale and high-precision data management can
be readily deployed in an IoT network. The access control can, for the first time,
stop revoked users or miners from accessing not only the future data but the past
data in a Blockchain, thereby substantially improving the manageability without
compromising the tamper-resistance of the Blockchain. This allows flexible and
secure
Blockchain-based IoT services and management to be adopted by regional/global
IoT leagues. Our analysis provides managerial guidelines for risk assessment, cost
evaluation, and energy and storage requirements, so that appropriate technical
solutions can be designed to meet specific business requirements.

Chapter 6
A Novel Dual-Blockchained Structure for Contract-
Theoretic LoRa Networks
Many existing studies present simple and stilted integration between Blockchain
and IoT technologies without dedicated optimization. However, such integration
cannot take full advantage of both technologies. On the contrary, Blockchains might
incur negative impacts from the inherent properties of IoT networks, while the
inherent properties need to be secured by the global validation of Blockchains.
How dedicated optimizations could be designed upon a Blockchain-based IoT
application such that the combination could be natural, smooth, and e ective↵
becomes gradually substantial. Under this background, this chapter, taking
Blockchain-based LoRa networks as a case study, proposes a novel Dual-Chain-
based LoRa system that provides global cross-validated security. The optimized
architecture can scale both the Dual-Chain system and the LoRa network.
6.1 Introduction
LoRa (Long Range), one of the most popular low-power wide-area network (LP-
WAN) technologies, has been reported to outperform cellular-based LPWAN (e.g.,
Narrow-Band IoT) in corporate or private realms, due to its self-driven public
participation and comprehensive open-source community [169, 149]. Operating in
an unlicensed band, several open-source protocols are presented (e.g., LoRaWAN
[8]), where a star-of-stars network is established between end-devices and a LoRa
Gateway, and between LoRa Gateways and a LoRa Controller (i.e., LoRa network
server).

It is reported that LoRa has held the highest market share in some countries and
accounted for the highest annual unit shipments along with an increasing
projection of the entire LPWAN market [28, 128, 13].
The use of unlicensed bands and open-source platforms compel LoRa to stay on
top of improving the scalability and flexibility among self-deployed gateways (e.g.,
relieving tra c congestion resulting from the channel limit) [58, 142], while
incentivizing more private owners to increase coverage. To achieve a secure,
e ective, and fair incentive mechanisms, the contract-theoretic incentive↵
mechanism [83, 31] is proposed to incentivize the private deployment of LoRa
[198], densify technology adoption and improving coverage and spectrum
utilization.
However, existing contract-theoretic designs neither consider a malicious LoRa
Controller which censors the LoRa Gateways by paying less reward, nor apply a
reliable mechanism to prove the validity of the incentive processing. Blockchain is
considered to be suitable to address the issues of centralization by taking
advantage of the decentralized architecture and tamper-resistant validation [140,
52]. However, traditional Blockchain technologies fail to handle massive data
streams, incurring significant latency and low throughput [163, 188]. In addition,
the one-device-tomany-gateway property (which is helpful for redundancy) of the
most popular protocol, LoRaWAN, may compromise the scalability of Blockchain
and the scalability of LoRa networks.
The above issues remain and a holistic solution is in demand. Specifically, the
remaining challenges are: 1) how the contract-theoretic incentive mechanism can
be integrated into the system, in which a new self-driven flow control protocol can
relieve the tra c congestion and throughput loss resulting from duplicated data
uploaded to the Blockchain; and 2) how the Blockchain can be integrated into the

proposed contract-theoretic LoRa network to provide secure and scalable data
storage services.
In this chapter, we develop a new Dual-Chain-based LoRa system by taking
advantage of the Directed Acyclic Graph (DAG) structure. Such DAG is set along
with a typical chain-based structure that provides identity registration and
protocol monitoring in smart contracts. By interacting with both the DAG and
identity chain and leveraging decentralized global cross-validation, a new contract-
theoretic incentive mechanism can be secured. The contract-theoretic incentive
mechanism consists of a new self-driven flow control protocol which scales the
LoRa network by relieving tra c congestion, and improves the throughput of the
Blockchain, scaling the Dual-Chain system. As a result, the system enables: 1)
strong compatibility with typical LoRaWAN protocols; 2) the Proof-of-Task-
Overhead (PoTO), a new spam protection dedicated for LoRa networks to reduce
resource waste; 3) e cient and flexible data storage services at any time with high
throughput; and 4) the transparency and fairness of incentives and data storage
services because of the tamper-resistance property of the decentralized cross-
validation protocol.
As revealed by our analysis and simulation results, the proposed Dual-
Chainbased LoRa system can significantly improve the throughput of the
Blockchain, while maintaining a high area utilization.
The rest of this chapter is organized as follows. In Section 6.2, we present the
proposed system model about the new Dual-Chain-based structure and the new
flow control protocol. The numerical simulation is shown in Section 6.3. Section 6.4
concludes the chapter.
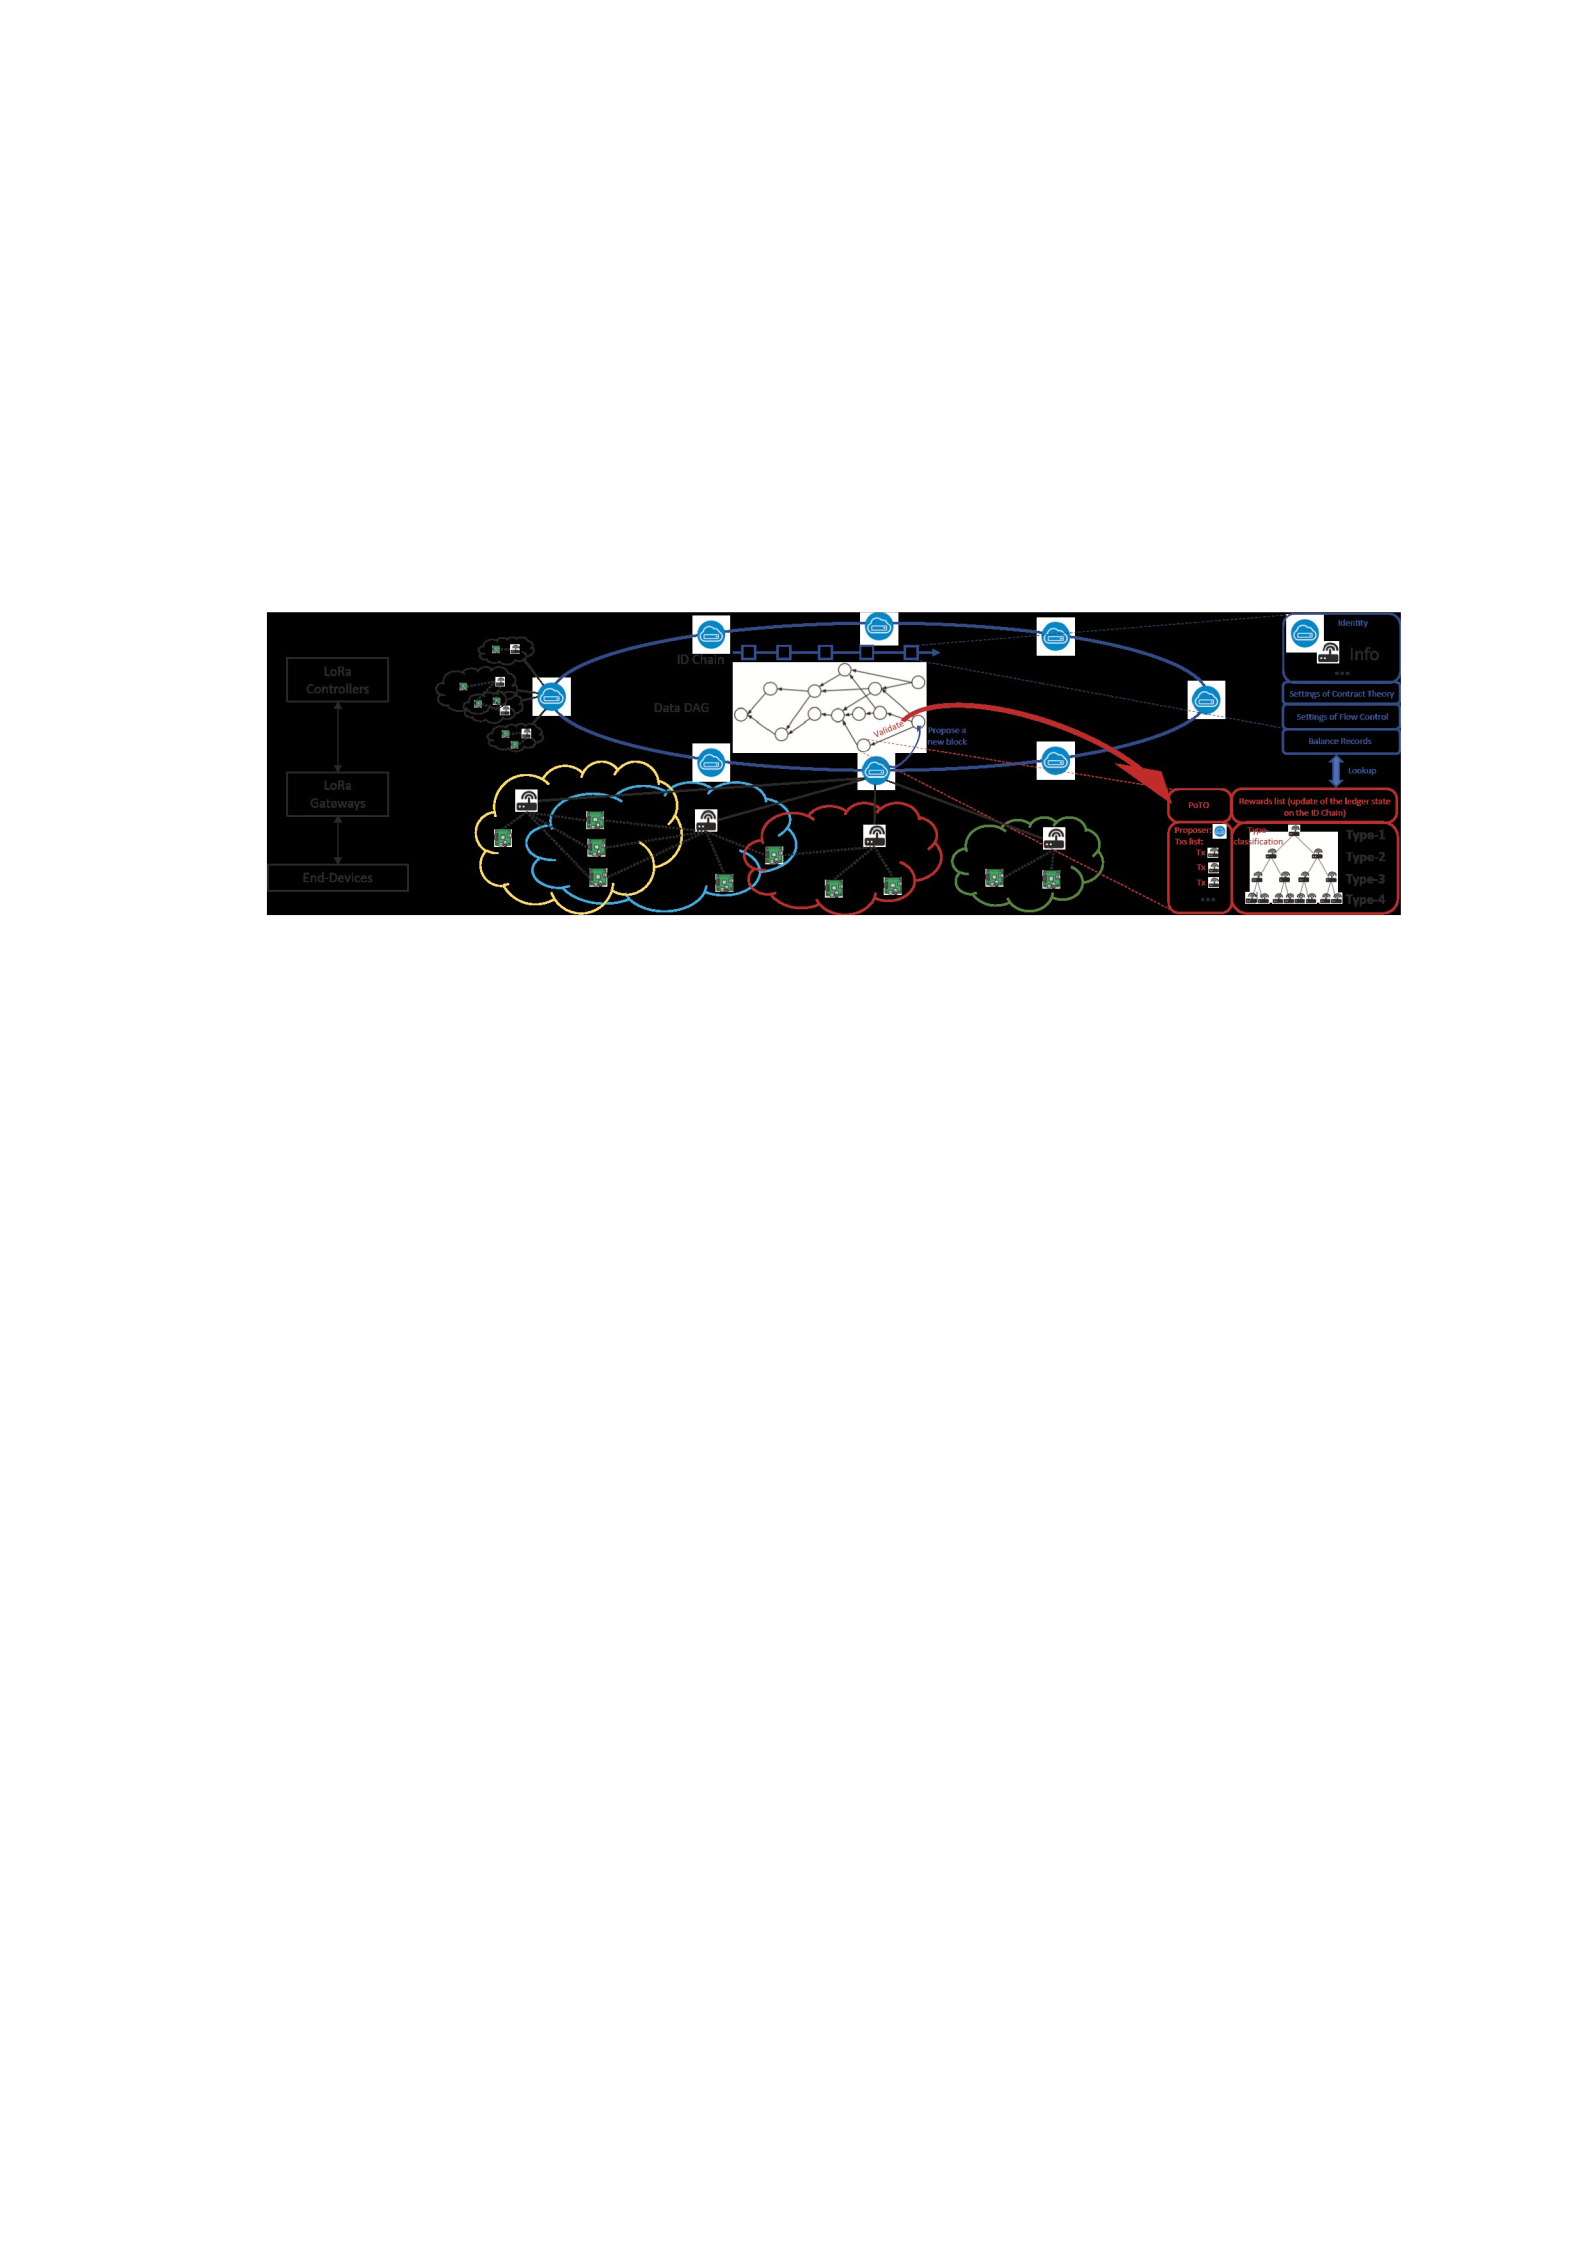
6.2 System Model
As shown in Fig. 6.1, a number of LoRa Controllers are distributed, each of
which runs a regional LoRa network supported by several LoRa Gateways. Many
end-devices are distributed in each of the regions. Each region is covered by a
LoRa Gateway which forwards data between the end-devices and the
corresponding
Figure 6.1 : The system architecture of the proposed Blockchain-based LoRa system with
contracttheoretic incentive mechanism. A star-of-stars network is established between end-devices
and a LoRa Gateway, and LoRa Gateways and a LoRa Controller. A group of controllers constitute a
committee and maintain a Dual-Chain structure, i.e., the ID Chain providing registration and
monitoring service, and Data DAG providing data storage service. Each controller as a task publisher
collects data from its corresponding gateways and pays incentives. Such behaviors are included in a
DAG block to be injected to the Data DAG, and cross-validated by other controllers.
LoRa Controller. There could be overlapping coverage areas among the gateways.
Data sent from the end-devices situated in the overlapped area (the yellow, blue,
and red regions in Fig. 6.1) is likely to be received by multiple gateways that have
overlapping coverage.
To prevent these gateways from being congested or transmitting excessive
duplicated data to their corresponding controller, a self-driven flow control
protocol is applied to the gateways that have a large overlapping coverage area, i.e.,
the yellow and blue regions. Here, the term “self-driven” indicates that the flow
control is not aimed to control tra c by cutting o the transmission. Instead, it is to↵
incentivize the gateways to maximize their profit by complying with any
preconcerted rules. A single epoch comprises several time-frames assigned to each
gateway. Each authorized gateway is assigned to transmit within its own short
time-frame based on the flow control protocol running on the controller.
A controller publishes a contract-theoretic task with a random timeout (i.e., the
controller decides the timeout point which is identical to a single epoch of the flow
control) to all of its corresponding gateways. Based on the uploading data size from
the gateways to their controller, the gateways are classified into di erent types in a↵
tree structure managed by the controller, as shown in the type-classification in the
red box at the bottom-right corner of Fig. 6.1. The discounted uploading data size as
the penalty is applied to the unauthorized gateways transmitting beyond its time-
frame. The larger data size a gateway contributes within the epoch, the higher
likelihood the gateway is classified into a type that is closer to the root of the tree,
and the more incentive can be granted for this task.
Each controller is powerful and robust, and responsible for multiple gateways
in a geographical region, and the controllers cooperate and interact with each
other17. Specifically, all controllers maintain a Dual-Chain-based structure, i.e., an ID
Chain and a Data DAG, based on which the data can be secured by conducting a
tamperresistant cross-validation among the controllers. Critical information is
17 The LoRa Controllers are typically owned and maintained by the service providers [63]. We
consider a decentralized league of hundred-scale controllers in di erent controller platforms or↵
di erent geographical regions, while each controller can be much powerful than a single end-↵
device or gateway machine, such as enterprise data centres (e.g., The Things Network, TTN) and
smallersized organizations using open-source platform [72, 34]/Software-as-a-service
(SAAS)/Platform-asa-service (PAAS) implemented at the cloud-based distributed cluster. The LoRa
data originating from densely distributed gateways in the same region ends up at a single controller
platform that manages this region. The physically damaged individual controller would be
destructive to the regional LoRa service, but would not a ect the data retrieval service thanks to↵
the faulty tolerance of the dual-chain structure.

uploaded to the ID Chain as smart contracts by controllers during the registration
phase, and updated periodically for the cross-validation, as shown in the blue box
at the top-right corner of Fig. 6.1. Such information includes the settings and status
of published contract-theoretic tasks, the flow control processing, and each
gateway’s serial number and public key (from which the Blockchain address can be
derived).
The ID Chain is a regular Blockchain only maintained by the controllers, while a
DAG-based structure is used for data storage, i.e., the Data DAG managed by both
the controllers and gateways. In a DAG-based structure inspired by [152], blocks
can be proposed in parallel. Each proposed block needs to validate other pending
blocks as a part of contribution to be proved. Such pending blocks are usually those
previously proposed by other controllers and yet not validated by sufficient
subsequent blocks. To introduce a DAG-based structure instead of a classical chain-
based one for data storage is due to its high scalability by supporting parallel
blocks/transactions. With its IOTA-like DAG-based solution, the Data DAG is
particularly suitable for storing large amounts of data in parallel. A LoRa Controller
does not need to wait until its previous block has been accepted or others have
finalized their blocks, it can publish tasks anytime with any timeout based on its
requirements. However, a single Data DAG is not as powerful as a chain-based
solution in terms of the support for smart contracts [210, 121]. Thus, we propose a
separate ID Chain which is superior in terms of handling this issue. The ID Chain, in
spite of its relatively weak support for parallel blocks compared to a Data DAG, can
be as scalable as a Data DAG in terms of transactions per second by implementing
the advanced technologies, such as the HotStu consensus algorithm [201] that↵
enables a high transaction rate among large communities, and the sharding
technology (as suggested in Chapter 4) that enables horizontal scalability.

By combining these two primitives, we are able to deliver a controllable and
flexible dual-chain system. In particular, di erent functionalities are split between↵
a Data DAG and ID Chain. The Data DAG enables the parallel data storage
service, where LoRa Controllers can initiate contract-theoretic tasks and collect the
LoRa data with no need of compliance with the sequence of the consensus process.
The Data DAG also provides a flexible validation process for businesses that
requires lower security levels and latency. The ID Chain is adopted to conduct
devices registration/monitoring and contract in initialization/status records. It is
also responsible for the incentive payment and balance records of the whole
system. Therefore, splitting the data storage and balance records between the Data
DAG and ID Chain, respectively, enables the independence among controllers. Each
controller is only responsible for the validity of on-chain LoRa data stored on the
Data DAG, and not for the validity of the metadata, i.e., the physical meaning of the
data stored on the Data DAG. This allows for improved controllability and
flexibility.
By looking up the information of each gateway in the ID Chain and validating
each transaction size, hash value, and timestamp in the tree, the other controllers
can confirm a contribution of a particular gateway is valid. With the same method,
the type-classification conducted by a controller and the transfer of the incentive
can also be validated on the ID Chain by the other controllers, as shown in the red
box at the bottom-right corner of Fig. 6.1. Thus, the cross-validation can be
conducted among the LoRa Controllers to prevent malicious behaviors in the Data
DAG, such as an invalid process of the PoTO protocol, invalid published
contracttheoretic task, invalid rewards transfer, and invalid source data from some
unknown controllers or gateways.

The proposed system focuses on the uplink transmission, because 1) the uplink
transmission is strongly favored in LoRa networks [4]; 2) the downlink
transmission can only happen after a successful uplink transmission [105]; and 3)
the duty cycle of uplink transmission is regulated by several governments agencies
and departments due to the default ALOHA access and limited channel resource,
thus limiting the usage of LoRa networks [162].
6.2.1 Dual-Chain Structure and Cross-Validation
The proposed Dual-Chain structure consists of two types of Blockchains, ID
Chain for gateways registration, contract initialization, and status updating, and
Data DAG for e cient data storage service, as shown in Fig. 6.1. The Dual-Chain
structure is the foundation of the cross-validation conducted among all
participating LoRa Controllers, for instance, validating the behaviors of controllers.
Registration and Initialization on ID Chain - The ID Chain with a typical
chain-based structure is maintained by all participating controllers to conduct the
registration of the gateways, contract initialization services, and subsequent status
updating. Specifically, the ID Chain consists of two operations (see Lines 1 and 2 of
Algo. 4):
•Devices Registration: Each gateway needs to register its identity to its
corresponding controller, including its unique serial number and public key
(from which the Blockchain address can be derived). Thus, the controller
collects a list of gateways it is responsible for, and can subsequently upload
the list to a smart contract on the ID Chain. Note that we consider a controller
that owns the su cient performance to maintain multiple Blockchains and
manipulate a large amount of data among the gateways and the other
controllers.

•Contract Initialization: Besides the gateways registration, the smart contract
also records the rule of flow control and type-classification for each
registered controller based on their own requirements; see Section 6.2.3. The
rule includes but not limited to 1) the number of types; 2) the number of
gateways in each type; and 3) the amount of incentive paid to each type.
By interacting with such an ID Chain, each controller fetches and updates the
information of the gateways and types secured by the tamper-resistance property,
and thus a reliable reference can be provided to the controllers during the
crossvalidation phase.
Data Uploading to Data DAG - A typical chain-based structure incurs poor
scalability and flexibility for LoRa networks due to its sequential generation of
blocks one after another. Di erent from the typical chain-based ↵ID Chain, a Data
DAG features a DAG-based structure enabling parallel blocks/transactions to
replace the traditional single block. In this chapter, the Data DAG features a general
DAGbased structure where a block can be injected into the network at any time
with an upper-bounded frequency and PoTO certified. Such a block is designed to
verify a certain number of pending blocks (e.g., two blocks in IOTA [152]), and will
be accepted by the network with a high likelihood if the block has been verified by
a su cient number of forthcoming blocks. Note that the Data DAG is compatible with
the common tools used in typical DAG-based structures (e.g., the trunk/branch
transaction process for bundling in IOTA). It is generic and not limited to any
specific tools, protocols, or algorithms. A weighting factor is applied to encourage
blocks to verify the most recent pending blocks (i.e., the tits of the DAG), and verify
pending blocks proposed by the other controllers (i.e., the cross-validation).
Consequently, the system can achieve:
• high throughput of the Data DAG (transactions/second) as processing
parallel blocks/transactions are now allowed simultaneously;
• instead of a single block generator per slot, a controller does not have to wait
until its own previous blocks has been accepted or the other controllers have
finalized their own blocks.
Based on the above, high throughput can be achieved in the network in which the
controllers can publish a contract-theoretic incentive task for their gateways, and
upload the result at any time with an upper-bounded frequency18, as well as a
timeout parameter on demand. This significantly contributes to an e ective↵
mechanism for LoRa networks in which high scalability and flexibility are
important.
Data uploading is conducted for the controllers to upload the transactions sent
from the corresponding gateways to the Data DAG. It consists of the following
steps; see Lines 3-11 of Algo. 4).
Data collection at LoRa Controllers: At anytime a controller decides, it publishes
a task inquiring LoRa Data forwarded from its corresponding gateways in the form
of transactions. The task is subject to a pre-defined timeout and the allocation of
the flow control if enabled. The controller marks full contribution only for
transactions received from assigned gateways during a time-frame based on the
allocation of the flow control (i.e., a discount is applied as a penalty for those
18 Strictly, there should be a lock-phase between each task, i.e., an upper-bounded frequency.
The upper-bounded frequency ensures that the previous blocks have been accepted by the Data
DAG with high likelihood. This prevents the out-of-order of transactions [152], and unexpected
rollbacks or forks by leveraging a block-ordering in the case where the data uploading is conducted
in a very high rate. In this chapter, the flexibility of publishing tasks without having to limited by a
certain period is our focus.

breaching the rule; see Section 6.2.2). Note that collecting data from end-devices on
the gateways’ sides is independent of the flow control. A gateway can suspend the
data forwarding while continuing to bu er the received LoRa data, if the gateway↵
is unauthorized. The transaction sent from a gateway is secured by using its private
key associated with the public key stored on the ID Chain, and also specifically
contains the data size and data hash. Any received transactions which 1) belong to
unregistered gateways,
2) present unmatched data size or data hash, or 3) display incorrect data format
(e.g., not comply with the pre-defined upper-bounded size of uploading data; see
Section 6.2.3), are considered to be invalid and discarded by the controller.
Algorithm 4: Decentralized data uploading mechanism
. Define
Controlleri and Gatewayi,j; // The i-th LoRa Controller and its corresponding j-th LoRa
Gateway.
Receiver Sender.Send(Message); // A sender sends msgs to a receiver.
Blockchain ( Sender.Upload(Message); // A sender uploads msgs to the chain.
Gatewayi,j Controlleri.Incentive(datai,j,k); // The i-th LoRa Controller pays incentive to
j-th LoRa Gateway on the ID Chain upon the data uploaded in taskk.
incentive to j-th LoRa Gateway on the ID Chain upon the data uploaded in
taskk.
FlowControl // Enabling the flow control
. Registration
1ControlleriGatewayi,j.Send(info);// where info contains the information of Gatewayi,j
(e.g., Blockchain address).
2BlockchainID ( Controlleri.Upload(info);
. Uploading data
3Controlleri publishes Taski,k with Timeouti,k, records TimeStampstart.
4if FlowControl is enabled then
5I nvoke Algo. 3.Defining Congestion
6while Timeouti,k not yet reached do

7Controlleri Gatewayi,j.Send(LoRa data); // data size and data hash are included in LoRa data
apart from the data itself. LoRa data is secured by the asymmetric encryption.
8if the sending data from Gatewayi,j is invalid then
9alarm and drop
10else
11Controlleri records TimeStampj,t, i.e., the actual time that Gatewayi,j sends LoRa data.
// The controller ranks and pays Gatewayi,j with different types in Treei,k based on
the inbounddata size |datai,j,k| for Taski,k.
12 if FlowControl is enabled then
13I nvoke Algo. 3.Incentive Allocation
14 else
15 Gatewayi,j,k Controlleri.Incentive(|datai,j,k|)
// Invoke Algo. 2 where i0 =6 i, to validate a pending block proposed byanother
controller.
16 blocki,k Controlleri.Validate(blocki0,k).Result;
17 Data DAG ( Controlleri.Upload(blocki,k);// where Treei,k is containedin the blocki,k.
18 The uploading succeeds only if Algo. 2 returns TRUE during the cross-validation of other forthcoming blocks.
Algorithm 5: Decentralized cross-validation mechanism
Output: TRUE or FALSE
. Define
Result Validator.Validate(Message); // A validator validates some messages and return a
bool result.
. Cross-Validation
1Result Controlleri.Validate(blocki0,k.Tree), i0 =6 i. {
2if blocki0,k self-validating or lazy-validating then
3return FALSE
4for each LoRa datai0,j,k in blocki0,k.Tree do
5Result Controlleri.Validate(LoRa datai0,j,k) {
// Asymmetric-decrypting LoRa datai0,j,k
6if Gatewayi0,j info 2/ BlockchainID then
7return FALSE
// Validate the PoTO protocol

8if |datai,j,k| < lower-bound OR |datai,j,k| =6 data sizei0,j,k then
9return FALSE
10i f Hash(datai,j,k) =6 data hashi0,j,k then
11r eturn FALSE
}
12 end for each
// Validate the type-classification
13 if FlowControl is enabled then
14I nvoke Algo. 4.Cross-Validation for Flow Control
15
16i f Line 16 of Algo. 1 is NOT properly executed then
17r eturn FALSE
18 otherwise return TRUE
}
Data uploading from LoRa Controllers to Data DAG: A controller first classifies
the gateways which have completed the task into di erent types based on the data↵
size that gateways have forwarded. The types are designed to fit in a tree structure,
implying that type-1 contains the smallest number of gateways, and the number of
gateways increases with the type index. The larger amount of data is received by
the controller, the higher probability the gateway is classified in a type that is closer
to the root of the tree. With a closer position to the root of the tree, the gateways
are o ered a higher incentive by the controller. The incentive is subsequently↵
applied in a block which the controller has generated and broadcast. The block
verifies a certain number of pending blocks in the Data DAG by pointing to their
block hash values. The typical PoW is replaced by a more e cient protocol, PoTO;
see
cross-validation in the following.
Cross-Validation - The data uploading succeeds only if the pending block
passes the cross-validation by all the participating controllers (or more specifically,
validated by su cient numbers of forthcoming blocks proposed by other
else

controllers); see Algo. 5. By introducing a weighting factor to encourage blocks to
cross-validate the tits of the DAG, the risk of a malicious controller conducting self-
validation (i.e., validating its own previous blocks) and lazy-validation (i.e.,
validating any ancient blocks) can be reduced. Also, a minimum size of payloads is
compulsory to prevent distributed denial-of-service (DDoS) attacks and Sybil
attacks. Each transaction of the tree in a pending block can be associated with the
LoRa data forwarded from each gateway to a specific controller for a published
task. In regards to each transaction, other controllers can retrieve information,
including the data size, data hash, and data payload after identifying the
transaction, if the information of the gateway has been recorded on the ID Chain.
Thus, the cross-validation can be conducted associated with the following aspects.
Identity (Lines 6-7 in Algo. 5): The information of each gateway and controller
is secured by the tamper-resistance of the ID Chain. The missing information of a
gateway on the ID Chain leads to a possibility of the controller colluding with an
unregistered gateway by packetizing its transaction into a pending block.
Proof-of-Task-Overhead (PoTO) (Lines 8-11 in Algo. 5): The PoW used in typical
IOTA is a simple computational operation dedicated for spam protection and the
defense to DDoS attacks [22]. Our proposed PoTO protocol, featuring the
integration of Blockchain-LoRa, can delivery the same protection without need of
additional computational operations required by the PoW used in IOTA. In
particular, the computational operations can be omitted, as the limited data source
transmitted in a physical channel, the limited data size, and the limited number of
gateways inherently extend a period of time for every task. Even the malicious
controllers would have to comply with the system restriction, thus leading to a
controllable growth rate of the Data DAG. Based on this property, the amount of
data received by the controllers (the data refers to the size of data payload of each

transaction in a pending block on the Data DAG) are enough to be the amount of
“work” done during the data collection and validation process. As a result, the
PoTO protocol compromises the motivation to launch attacks. This is because
controllers are not responsible for the validity of the metadata based on our Dual-
Chain-based structure. Malicious controllers spending time and consuming
communication (downloading/uploading) and computation (verifying/smart
contract operations) resources to upload local corrupted LoRa data do not a ect↵
the interests of others and reap no profits for itself (See Section 6.3.1.3 for more
details on the security analysis).
Type-classification (Lines 13-17 in Algo. 5): Recall that the rule of type-
classification for each registered controller is recorded in the smart contract on the ID
Chain. Global cross-validation regarding the type-classification can also be conducted
to avoid any cheating, for example accepting bribes from a gateway and assigning it
with a higher type than it deserves. Based on the data size from the last validation
item, the other controllers can verify whether a specific controller has complied with
the type-classification rule stored on the ID Chain. Thus, the incentive o ered to each↵
type of the gateways can subsequently be cross-validated by checking the balance of
the gateways claimed by the pending block.
6.2.2 Flow Control Protocol in a self-driven way
In a typical LoRaWAN network, end-devices are connected to multiple LoRa
Gateways, and hence the end-devices transmit data to multiple connected gateways
[18]. The gateways transmit transactions to the corresponding controller, resulting
in duplicated data at the controller. The duplicated data needs to be handled
specifically because: 1) the Data DAG incurs a throughput loss and a data storage
waste; and 2) the duplicated data still accounts for the uploading data size of the
gateway during the type-classification, which can result in unfair competition.
Thus, a discount applied to the duplicated data as the penalty is introduced to
reduce unfair competition.
We propose a new flow control protocol which is designed to e ectively↵
allocate a fair and proper amount of incentive to each contributing gateway based
on its uploading data size. Being part of the contract-theoretic incentive
mechanism (see Section 6.2.3) to reduce the unfairness, the flow control is not
aimed to control the transmission in a compulsory way (e.g., cutting o the↵
transmission). Instead, it is a management tool to incentivize the gateways and
make them comply with any preconcerted rules in a self-driven way, thus achieving
the scalability as expected. Exceptions (e.g., sending urgent messages) are allowed.
In other words, a gateway can still upload data anytime without caring about the
flow control if the gateway has a strong wish to do so. The controller maintains an
internal clock which determines a time-frame for every single gateway, while the
controller can still receive the transmission from all the gateways. This motivates
the gateway to transmit as much as possible in their own time-frames, in order to
reduce the ratio of duplicated data and maintain the participation of an adequate
number of gateways in a specific
region.
Algorithm 6: Flow Control: Congested LoRa Gateways and Incentive
Allocation
. Defining Congestion
1Controlleri uploads randomness for Taski,k+1 to the ID Chain using Blockchain-based randomness
generator.
2while [Gatewayi,j, ... ,Gatewayi,n] do
// i denotes the overlapped proportion
3i f Overlap(Gatewayi,j,Gatewayi,j+1)> i then
4Controlleri records Gatewayi,j.DAGAddr, count the number of congested gateways n.
5for each j of Gatewayi,j do
6TimeStampj = TimeStampstart + Timeouti,k ⇥nj
7Scheduleri,k Controlleri.Scheduler(Gatewayi,j.DAGAddr, TimeStampj)
. Incentive Allocation
6.2.2.1 Congested LoRa Gateways
(Lines 1-7 of Algo. 6) Each gateway has a specific coverage area to serve
enddevices. Multiple gateways in a region may have some overlapping coverage.
Within the overlapping coverage, the end-devices connect to multiple gateways and
are most likely to transmit duplicated data. Thus, we define the congested gateways
as the gateways which have a specific common overlapping coverage area. A
gateway registered on the ID Chain leads to the essential information, including the
geographical location, device model, coverage area stored in a smart contract. The
overlapped proportion is also defined in the smart contract, defined as the
overlapped area divided by the total coverage area of a single gateway.
Through the overlapped proportion and the coverage area of each gateway
recorded on the ID Chain, the corresponding controller is able to determine the
congested gateways as a list [Gatewayi,j, Gatewayi,j+1, ... ,Gatewayi,n] where i indicates
the i-th controller; j indicates the j-th gateway; and n indicates the number of
congested gateways within a specific overlapping coverage). Also, a scheduler is
defined in a smart contract and secured by the ID Chain. The scheduling for Taski,k is
based on the pre-defined randomness announced on the ID Chain by using the
Blockchainbased randomness generator such as RANDAO [2]. The scheduler records
the identity and the assigned time-frame of each congested gateway. The controller
refers to the scheduler determining whether a gateway transmits data within its own
timeframe hence marked as a full contribution.
The contract-theoretic task-k published by the controller-i includes a timeout
Timeouti,k which is a single epoch of the flow control. At the same time of publishing
a task, a local timer is triggered on the controller and the initial timestamp
TimeStampstart is recorded. Meanwhile, the controller checks the congested
gateways based on the information (e.g., the overlapped proportion) of the
gateways in the smart contract. The period of an epoch, Timeouti,k, is divided into n
timeframes which equals to the number of congested gateways. Therein, each
boundary point is defined as the unique timestamp for each gateway-j TimeStampj
(Line 6 of Algo. 6)19. Finally, the controller updates every single timestamp
TimeStampj to the scheduler based on the identity of the congested gateway
Gatewayi,j.DAGAddr. Note that using a single randomness for multiple tasks (i.e.,
multiple epochs) is permitted to prevent updating smart contracts for every task,
and reduce the transaction load on the ID Chain which is typically poor at
scalability.
6.2.2.2 Incentive allocation
(Lines 8-10 of Algo. 6) Recall that the incentive allocated to each gateway is
based on the uploading data size as the contribution. The flow control is an internal
management tool for controllers to adjust the contribution of each gateway during
a task, in order to allocate a proper incentive to the gateways and provide a fair
type-based classification. The gateway can either check the Data DAG before
transmitting transactions to reduce the ratio of duplicated data, or transmit
without checking due to reasons such as saving query resources, enhance the data
redundancy, or the willingness for sharing the coverage. Thus, transmitting data
19 Generally, multiple gateways as a group can be allocated in one time-frame based on the live
requirements. For simplicity, this chapter considers a one-gateway-one-timeframe scheme.

within its own time-frame is strongly encouraged with a high incentive, thus
motivating gateways to reduce the ratio of duplicated data. In other words, if the
transaction is uploaded by a gateway within its own time-frame, a full incentive is
o ered to the gateway based on its uploading data size. While if the transaction is↵
uploaded by a gateway out of its corresponding time-frame, a partial incentive is
o ered based on the data size as the penalty. Here, the partial incentive is↵
calculated by the original size of the uploading data divided by the number of
congested gateways, n.
Algorithm 7: Flow control: decentralized cross-validation mechanism
Output: TRUE or FALSE
. Cross-Validation for Flow Control
1Result Controlleri.Validate(Scheduleri0,k), i0 6= i.
{if Gatewayi,j.DAGAddr /2 Scheduleri,k then
2return FALSE
3i f the pre-defined randomness is NOT matched with Scheduleri,k then
4return FALSE
5i f Algo. 3.Incentive Allocation is NOT properly executed then
6return FALSE
7otherwise return TRUE
}
6.2.2.3 Cross-validation of Flow Control
The above incentive allocation will not be conducted until passing the global
cross-validation of flow control among other controllers. Recall that finalizing a
pending block needs to validate a su cient number of other pending blocks. By
specifying the transactions in an arbitrary pending block uploaded to the Data DAG,
all the other controllers can validate the transactions via their own proposed
pending blocks, through the following aspects:

•Identity of gateway (Lines 2-3 of Algo. 7): The controllers validate whether
the identity (e.g. Blockchain Address) belongs to one of the congested
gateways based on the scheduler.
•Scheduler (Lines 4-5 of Algo. 7): The controllers validate whether the
presented scheduler for a task is matched with the publicly pre-defined
random-
ness.
•Timestamp and Incentive (Lines 6-7 of Algo. 7): The controllers compare the
timestamp of the transaction with the time-frame of the gateway that is
recorded in the scheduler. After that, the controllers calculate the amount of
incentive and compare it with the intended amount.
6.2.3 Practical Implementation of the Incentive Mechanism
In regard to motivating more to participate in the deployment of LoRa Gateways
to expand the coverage, we aim to design an incentive mechanism where the
corresponding LoRa Controller will o er the token reward based on the amount of↵
each gateway has contributed. However, a controller does not have any prior
knowledge about the performance of gateways (e.g., the hardware performance)
and the amount of LoRa data each gateway is willing to forward as a contribution.
The information asymmetry between the controller and gateways needs to be
tackled to reduce the cost of the incentive while maximizing the utility of both
controllers and gateways. In this chapter, we adopt contract theory [31] in the
incentive mechanism design that can be integrated in a Blockchain-based LoRa
system. In other words, the reward can be matched with how much each gateway
should deserve in terms of the contribution without any bias, which guarantees e
ciency and fairness. The whole process of the adoption of the contract theory is
conducted during the contract initialization in the smart contract of ID Chain
(referred to Section 6.2.1), and is discussed in the following.
During packetizing the block with task index k by a controller i chosen by the
consensus process, a monopoly market [31] is considered. Therein, the market
consists of a controller acting as the task publisher and a set of gateways N =
{N1,...,Nj,...,NN},1 j N. For a gateway Nj, the total amount of
receiving data forwarded from the end-devices to the controller is denoted as Qi,kj
for task-k published by controller-i. Any Q is resource-intensive in terms of the
bandwidth, the performance of receiver, the number of supported bands, etc. To be
specific, Q can be abstracted into R and t, denoting the single channel bandwidth
(bps) and the usage (second) of this channel on this bandwidth during the
maximum task period of task-k, respectively. Note that, (6.1) represents the vector
of the logic channel characterized by a pair BW and SF (denoting the bandwidth in
Hertz and the spreading factor), while CR denotes the code rate defining the level of
tolerance to signal interference [18].
(6.1)
Thus, we define F types based on the heterogeneous willingness in terms of the
total uploading data size B. We assume that the gateways are sorted in an
ascending order of the contributed data: ✓1 < ··· < ✓f < ··· < ✓F . The greater ✓f,f 2
{1,...,F} implies the more LoRa data that this type of gateways have forwarded from
the enddevices to the controller [91, 207]. Thus, each task Qi,kj is denoted by a two-
tuple
(Ri,kj ,ti,kj ).

Each controller needs to encounter the information asymmetry while they aim
to minimize the economic loss. For all F types ✓f customized by a controller in a pre-
defined contract by a controller, the contract is a series of uplink-data-reward
bundles denoted by (Tf(Bf),Bf). Bf denotes the total uploading data size B of the type-
✓f gateways and Tf(Bf) is the incentive o ered to the gateways. Also note that, the↵
gateways which forward more data from the end-devices to the corresponding
controller under a valid threshold upper-bounding the uploading data size B (i.e.,
Bmax) can be rewarded more.
6.2.3.1 Uploading data size in LoRa Gateways
We define the uploading data size B as the significant data size. Here, the term
“significant” indicates that the received LoRa data is de-duplicated (i.e., repeated
data being discounted as the penalty) after decoded at the controller side. This is
due to the fact that multiple gateways may receive and forward identical messages
sent from a single end-device either with the same or di erent logic channels [18].↵
In addition, we define Bf taking the following factors into consideration:
• the number of end-devices served by the type-✓f gateways;
• the latency for the type-✓f gateways to complete the task (receiving data and
forwarding out) associated with both inbound and outbound bandwidth; •
the coverage area and the overlapping coverage area subject to the proposed
flow control protocol (see Section 6.2.2);
• the amount of duplicated data.
We consider a specific region. For the j-th gateway completing the task-k, the
significant data size Bf(Rkj ,tkj ) for data forwarding task Qkj can be given by
,(6.2)
where Rkj and tkj denote the vector of logic channels and the time of transmission on
each discrete logical channel out of total l channels during the task Qkj , respectively.
Bf denotes the size of uploading data from the end-devices to the gateways and
should be upper-bounded by Bmax = PRkj|Tmax, where| Tmax is the task period (i.e., an
epoch period). Bf is equivalent to datai,j,k used in Algo. 6 for a specific significant data
size sent from j-th gateway to its matched i-th controller during task-k. In (6.2),
and Bf Bmax. Note that the actual significant data size Bf > Bmax may
happen due to maliciously forwarding accumulated data to the controller, which is
detectable at the controller side by comparing Bmax with the actual inbound
uploading data size from gateways. This is because the link between gateways and
controllers can be a fixed, wired, or backbone network. Thus, the total size of the
accumulated data can be much bigger than Bmax.
6.2.3.2 Utility of LoRa Controllers
Based on the signed contract (Tf,Bf) between a controller and the type-✓f
gateways, the utility of the controller earned through the task Qk from the type-✓f
gateways is given by
Uc(✓f) = µ(Bf) !Tf,(6.3)
where
if Bmax Bf,
(6.4)
0 otherwise.
There is a penalty applied to the gateways uploading excessive data to the
controller
(i.e., Tf(Bmax < Bf) = 0). Note that > 0 is a pre-defined parameter and (6.4) implies
Bf (closer to Bmax) can attain a larger µ(Bf). Thus, the goal of the controller is to
maximize its total utility all through the F types of gateways, as given by
F
maxf
Uc = XpfN(µ(Bf) !Tf),8f 2 {1,...,F},(6.5)
(T ,B ) f=1
where N is the total number of gateways that the controller is in charge of; ! is a
pre-defined parameter; and pf is the prior probability of the type-✓f gateways with
= 1. Note that the controller can attain the distribution based on the
historical statistics, and we assume a uniform distribution among the F types
gateways which the controller is aware of [91, 207, 83]. The controller is also
aware of the value of N, as a pre-registration on the ID Chain is needed to activate
gateways in the coverage.
6.2.3.3 Utility of LoRa Gateways
For the type-✓f gateways completing the task-k based on the signed contract
(Tf,Bf), the utility function is given by
Uf = ✓f⌫(Tf)Bf,8f 2 {1,...,F},(6.6)
where is the unit resource cost of data forwarding; ⌫(Tf) is the evaluation function
of the type-✓f gateways in terms of the incentive Tf. The evaluation function ⌫(Tf)
monotonically increases with the following properties [31]:
0, monotonically increasing;
0, concavity;
0, positive correlation of data contribution; and
• ⌫(0) = 0, scheme for non-incentive.
The goal of all F types of gateways is to maximize the utility earned by data
forwarding, as given by
.(6.7)
Based on (6.5) and (6.7), our objective is to maximize the utility of the controllers
and the utility of the gateways at the same time, while they are, in fact,
contradictory. To solve the conflicting problem, the contract theory is used to
design a series of optimal type specific contract (Tf⇤,Bf⇤); see more details on our
published
article [67].
6.2.3.4 Interaction between Dual-Chain to secure incentive
The following steps are conducted for the practical implementation of the
contracttheoretic incentive mechanism, as shown in Fig. 6.2. A LoRa Controller,
acting as the task publisher, obtains the values of any relevant information based on
the historical data. Such information includes the LoRa settings i.e., (SF, BW, and CR),
the number of LoRa Gateways under the management, and the expected value of
significant uploading data size. Thus, the controller can calculate the optimal
contract along with the types, and subsequently broadcasts this term to the
gateways via the internet. By evaluating the utility based on the contract received
from the controller, each of the gateways decides whether to participate in the task,
and chooses one option in the contract, i.e., (Tf,Bf), by sending back feedback to claim
its willingness for signing the contract with the controller. The above is recorded
and updated with the status of smart contract in the ID Chain. Finally, after the
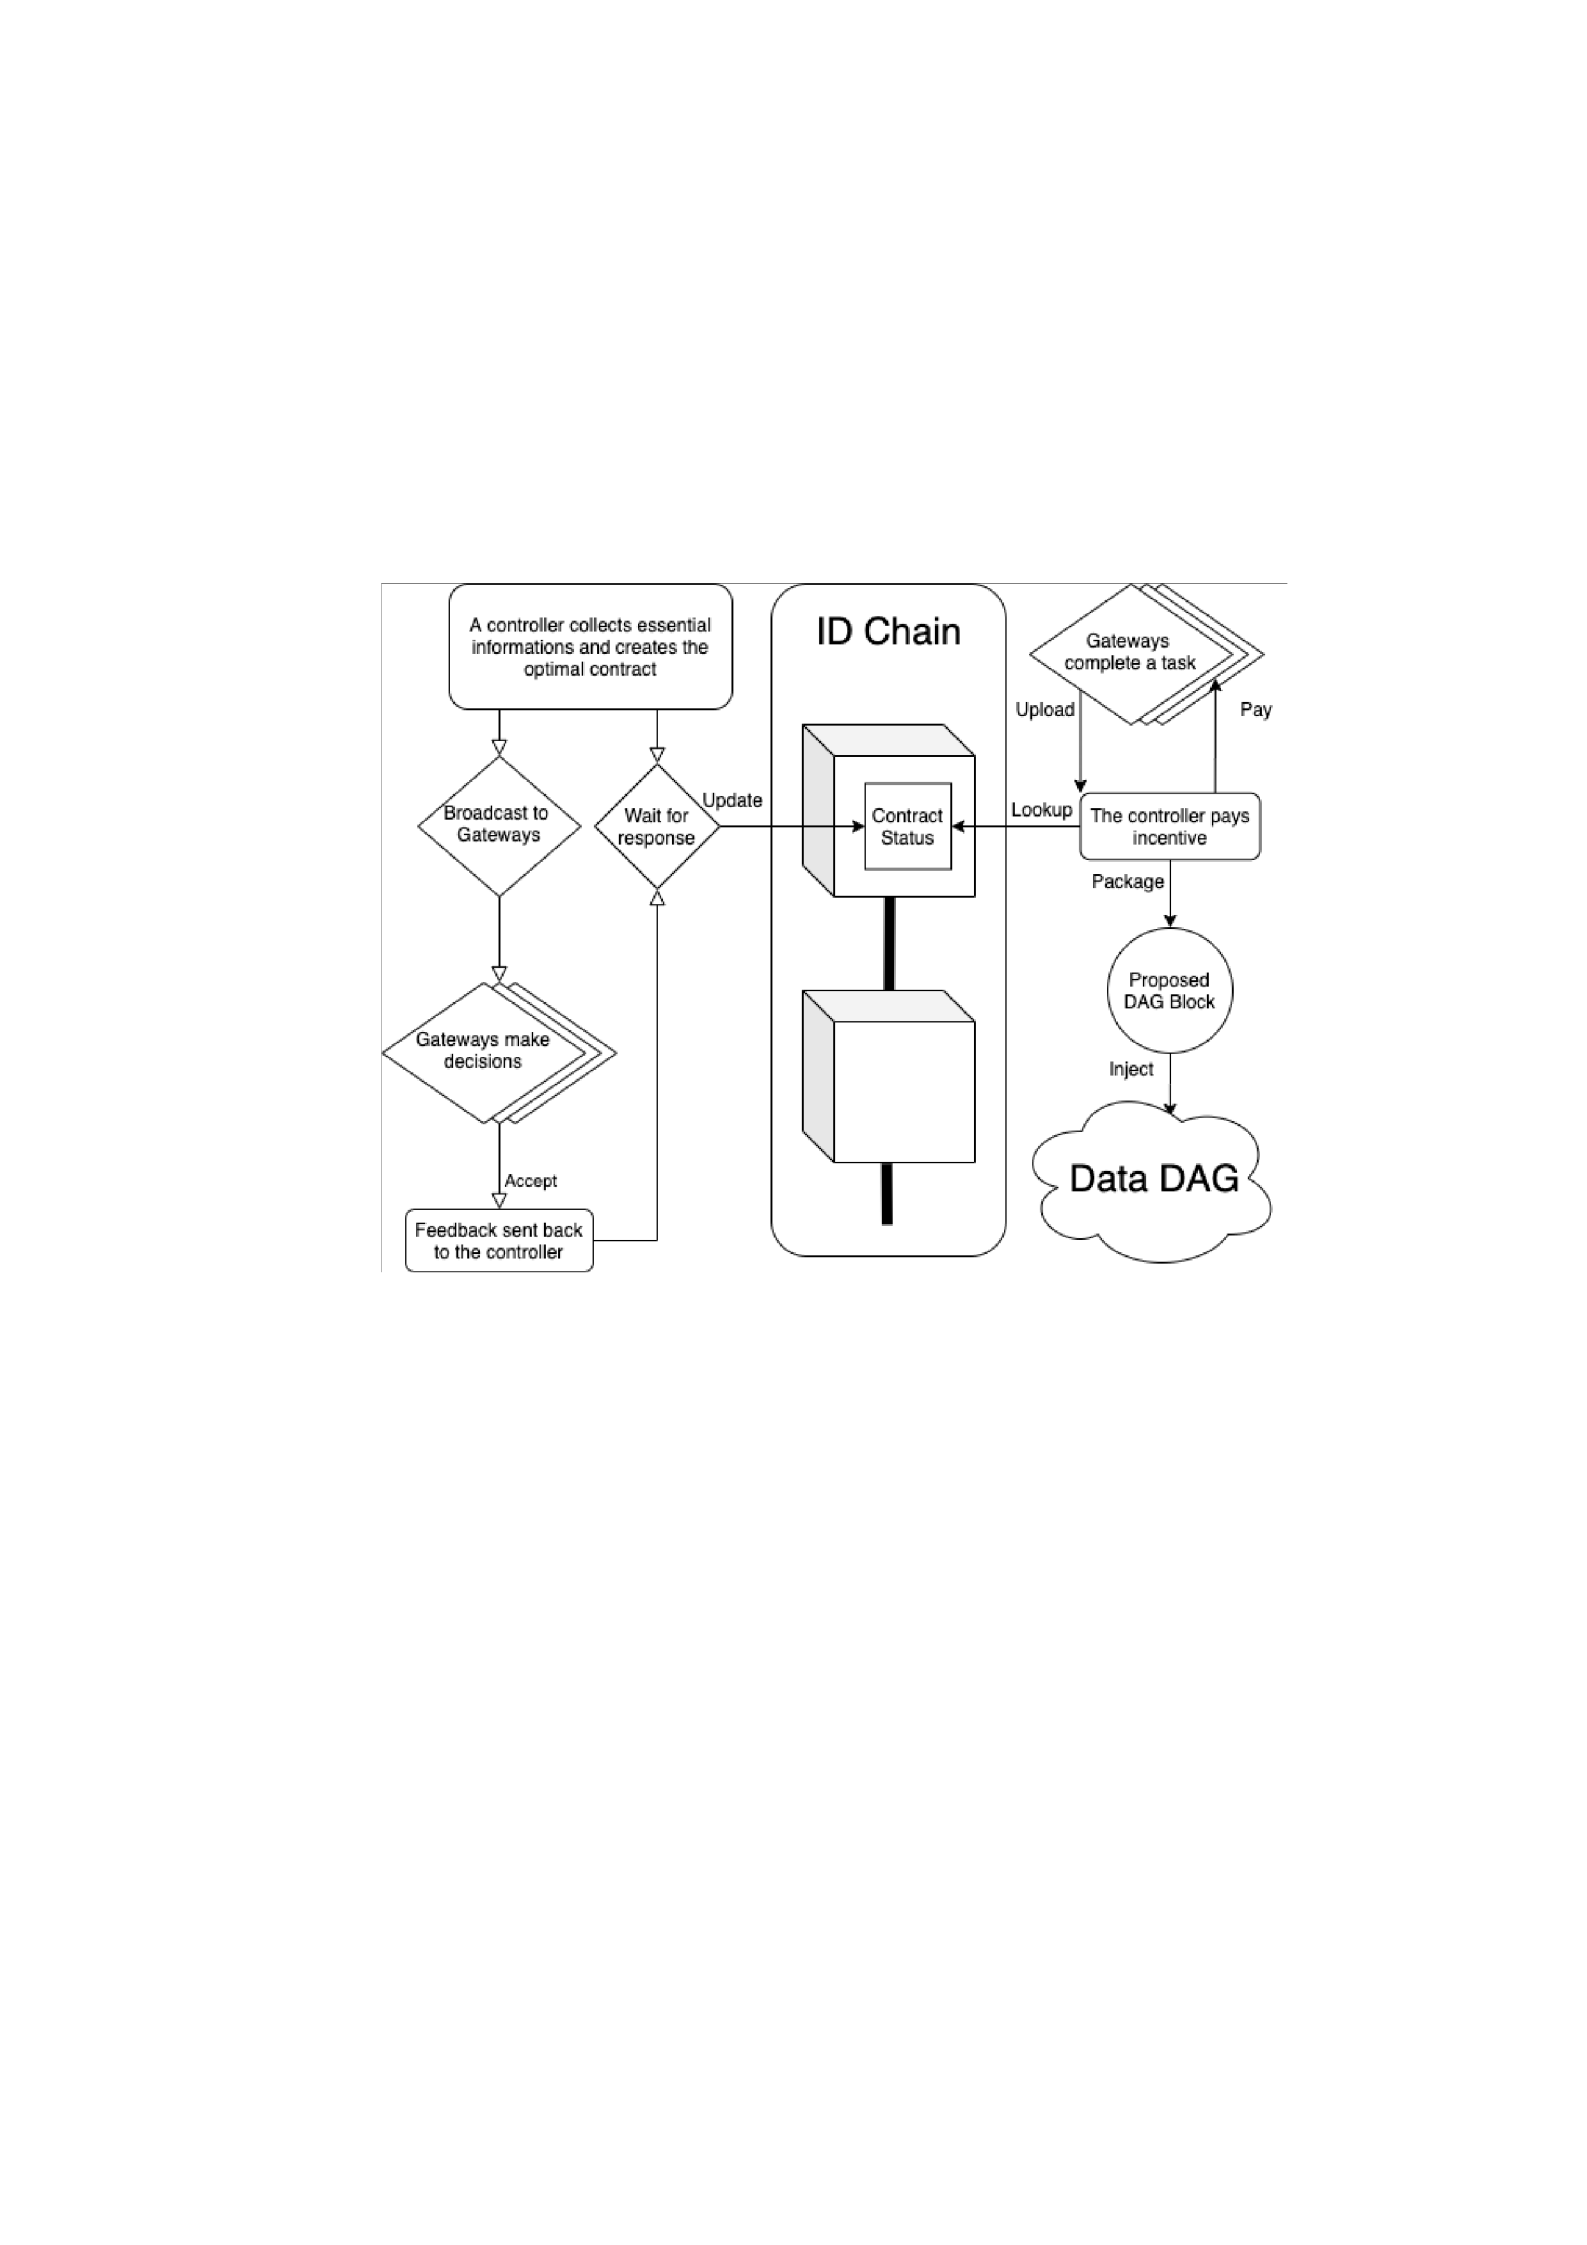
gateways establish the task to forward the LoRa data from the end-devices to the
controller with the agreed value of significant uploading data size, the controller
proposes a new DAG block. Therein, the preconcerted incentive to each type of
gateways can be paid based on the corresponding contractual obligation recorded in
the contract of ID Chain.
Figure 6.2 : The flow chart of practical implementation of the contract-theoretic incentive
mechanism to relieve the information asymmetry
6.3 Simulation and Discussion
We carry out Monte-Carlo simulations in Python-3.8 to evaluate the impact on a
LoRa network from the proposed flow control and incentive mechanism in a
systematic view. We hereby define the following three terms:
(Un)weighted Scoring: Excessive duplicated data severely degrades the
throughput of Data DAG [107]. Specifically, transmitting a message to n di erent↵
congested gateways results in the throughput of the Data DAG being reduced by n. In
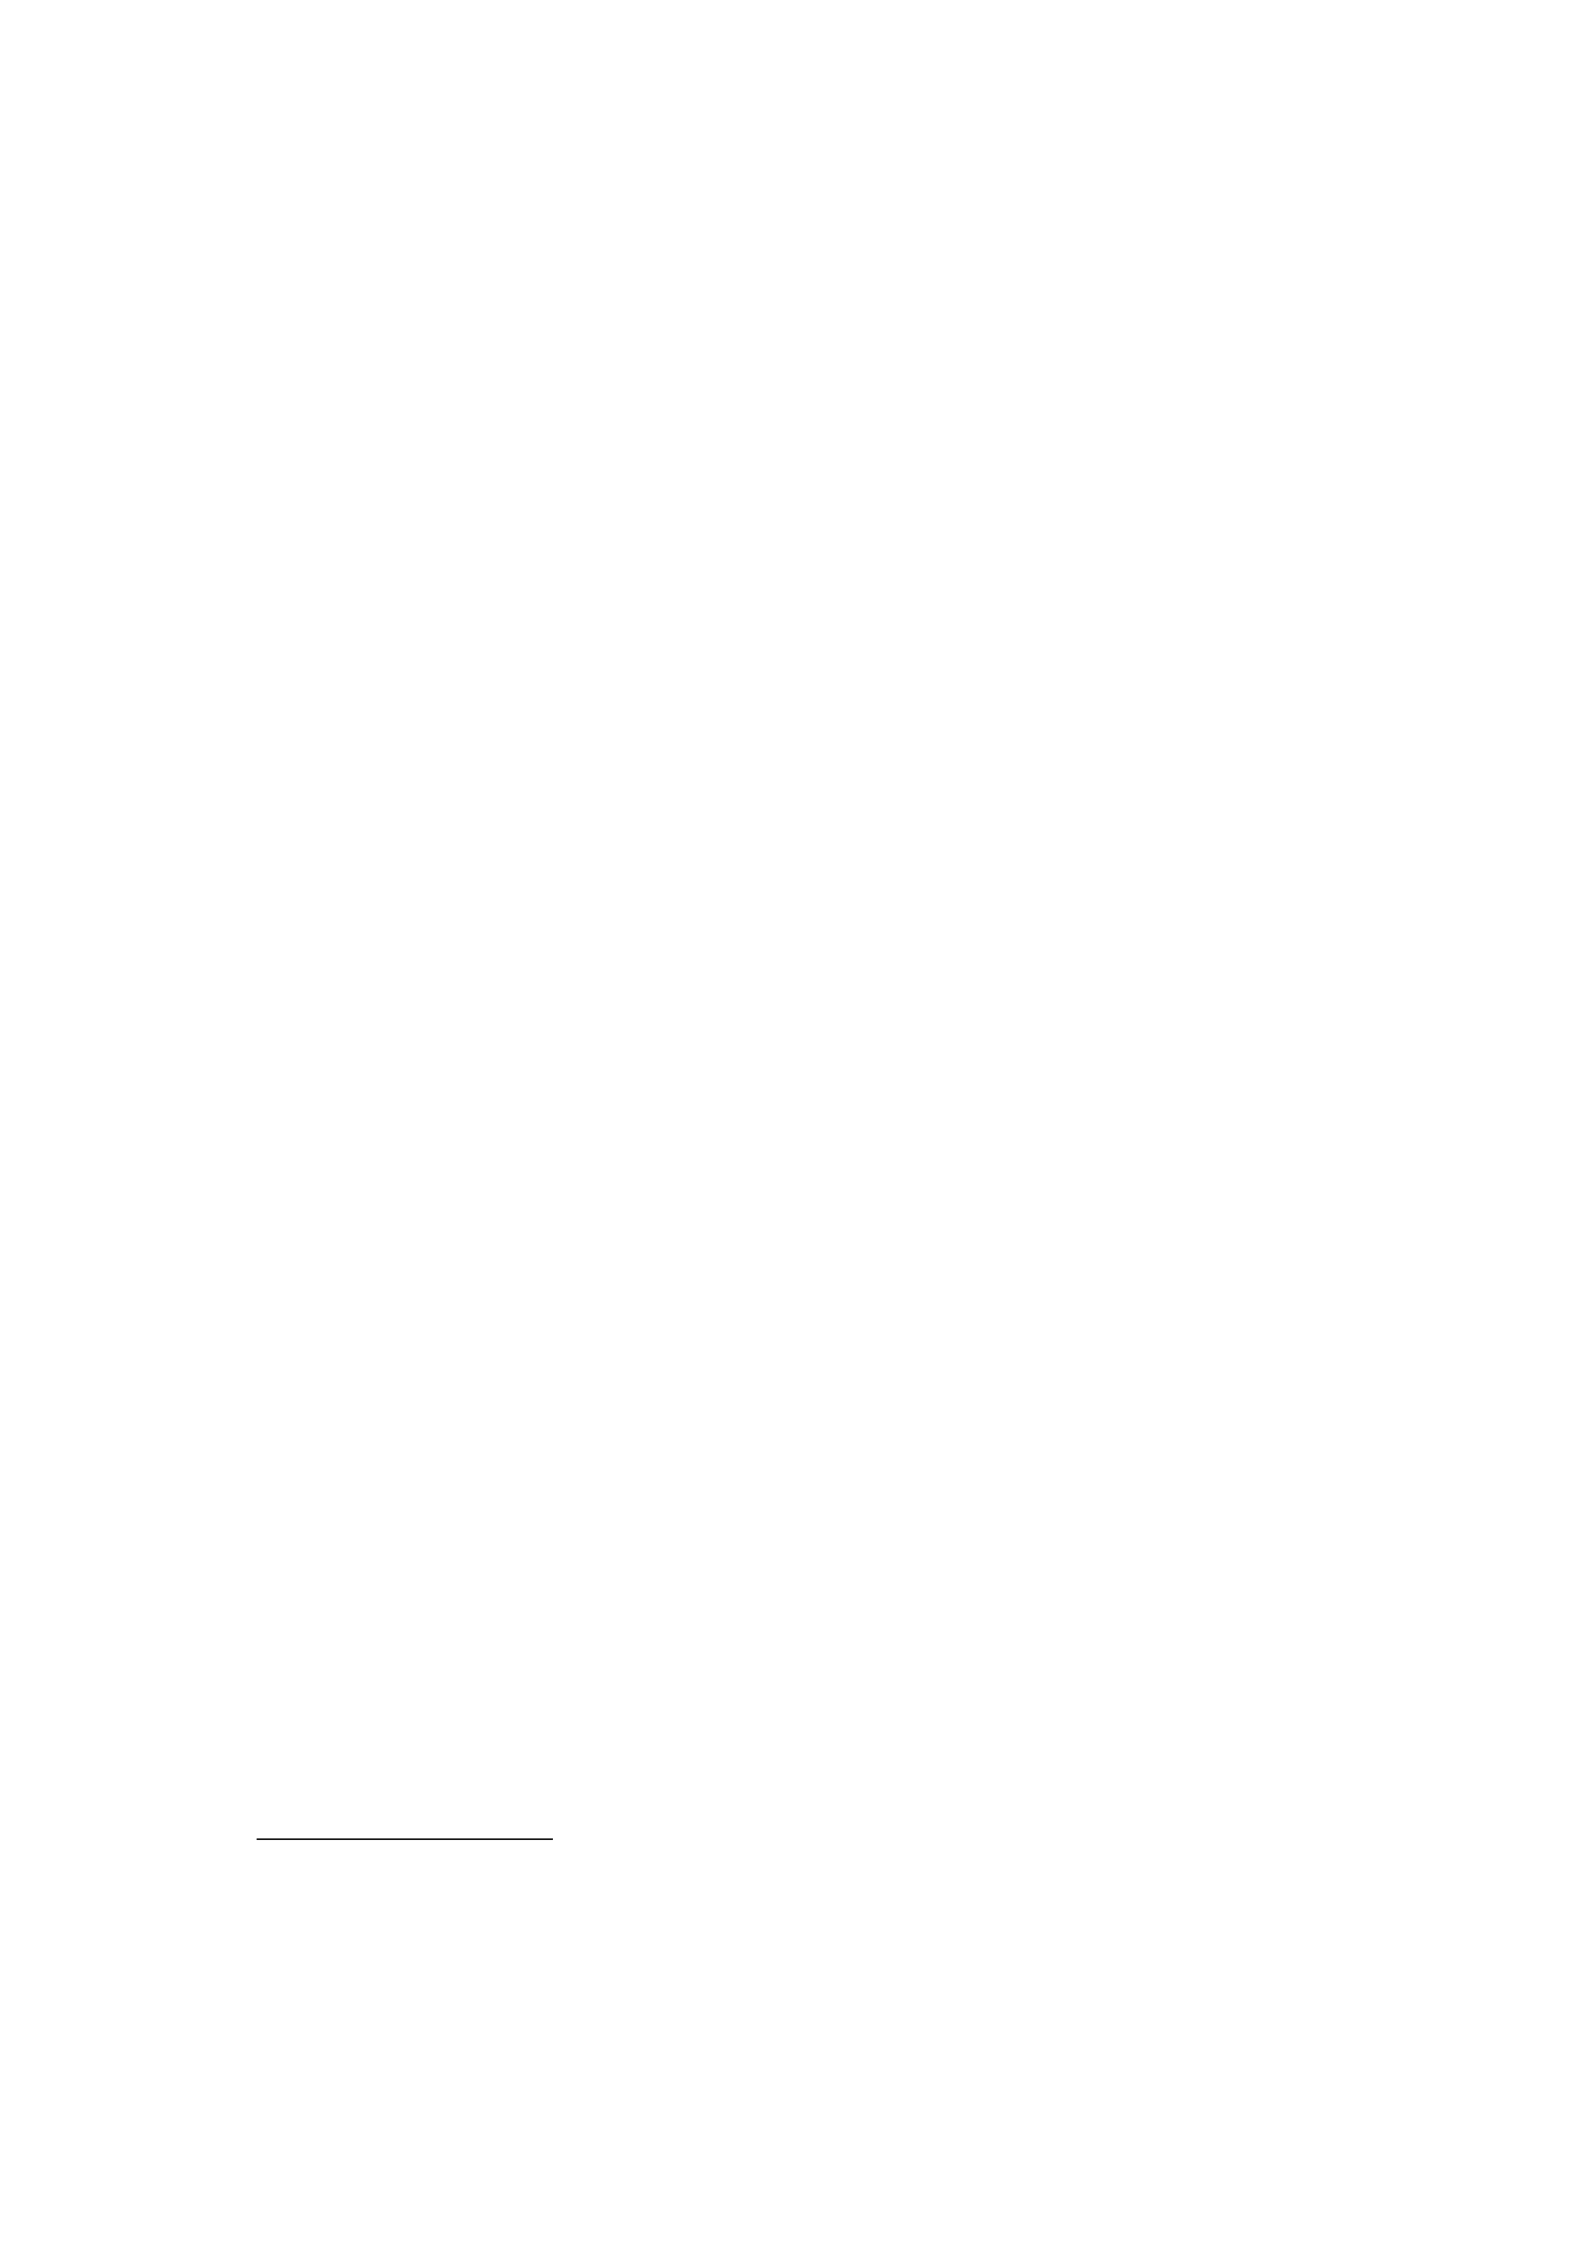
order to mitigate the loss, weighted scoring is introduced to assess the overall system
by taking into account an expected loss rate associated with the overlapping coverage
area among congested gateways, i.e., the total profit of the whole system. Accordingly,
unweighted scoring is also introduced to represent the area utilization of a specific
region managed by a single controller, i.e., the total coverage ratio.
Expected Loss Rate: The expected loss rate is the average loss rate applied to
the gateways sending duplicated data to the controller. It is used to assess the
impact of the proposed incentive mechanism applied to the overlapping coverage
area in order to mitigate the throughput loss on the Data DAG. The overlapping
coverage area is multiplied by the loss rate, which reflects a rapid decline in the
overall weighted scoring because of the possible overlapping coverage areas of
more than two gateways. A zero loss rate indicates that the negative impacts of the
overlapping coverage area are not considered20. A lower loss rate implies a larger
impact of the incentive mechanism applied to the overlapping coverage area.
Ideal Overlapped Proportion: The maximum overlapping coverage area
which can be accepted by a gateway being deployed in the case where there is
enough leftover space within the region. Any owners will prefer to deploy their
own gateways apart from an existing one in order to achieve the ideal overlapped
proportion, until the gateways cannot be situated in such a position anymore due
to the insu cient space. Gateways distributed in an overlapping coverage area have
to comply with the flow control protocol conducted by the corresponding
controller. A gateway tends to carefully maintain an overlapping coverage area with
others such that it can enjoy more exclusive use of the significant throughput while
20 An expected loss rate = 1 indeed results in the overlook of negative e ects of the overlapping↵
coverage area. This is because, intuitively, the existing LoRa network designs take the data
redundancy into account while rarely considering the throughput loss in a Blockchain-based LoRa
network.
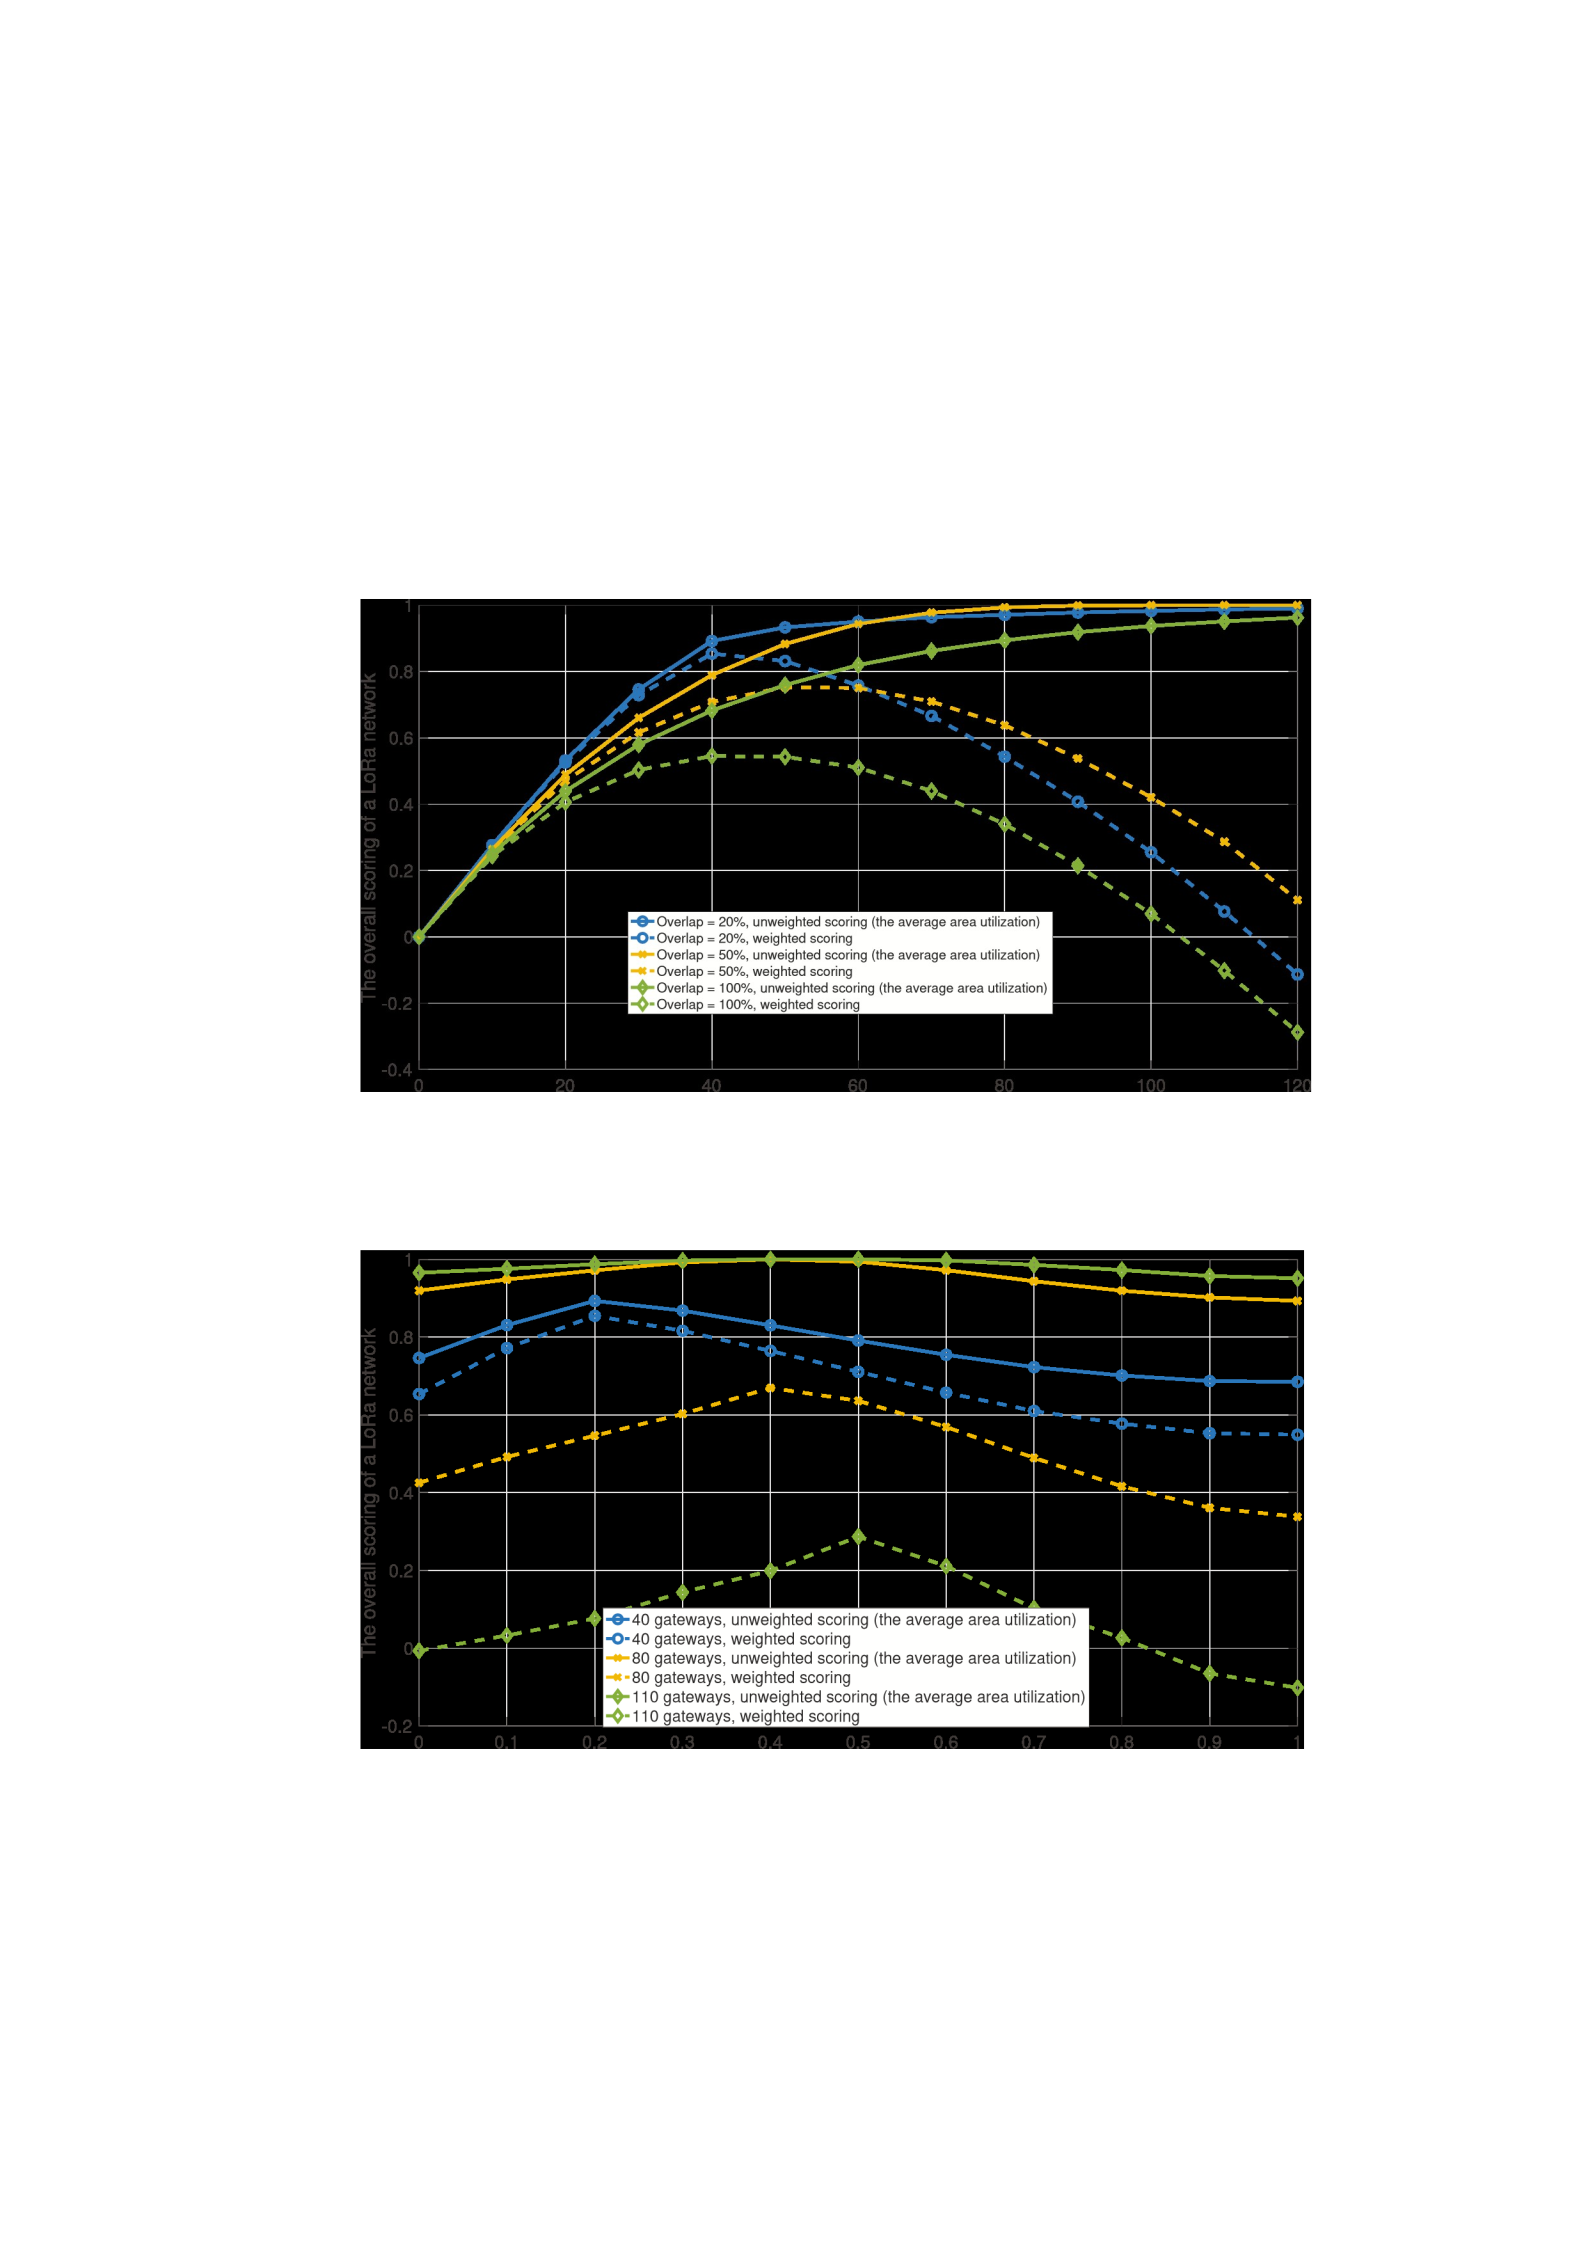
still having a chance to compete with others. As such, tra c congestion can be
relieved without having an excessive amount of duplicated data.
We consider an expected loss rate = 80% in the simulations. Figs. 6.3(a) and
6.3(b) show the trajectory of the overall (un)weighted scoring with the increasing
number of gateways and the percentage of overlapping coverage area in a
The number of LoRa Gateways charged by a LoRa Controller
(a)
The percentage of overlapped area
(b)

Figure 6.3 : (Left) The trajectory of the overall scoring along with the increasing number of LoRa
Gateways changed by a LoRa Controller. (Right) The trajectory of the overall scoring along with the
increasing percentage of the overlapping coverage area among gateways.
specific region, respectively. Every single scenario determined by the overlapping
coverage area or the number of gateways is illustrated in a specific color, with the
unweighted scoring and weighted scoring plotted as solid curve and dotted curve,
respectively.
It is concluded in Fig. 6.3(a) that the unweighted scoring of overlap of 20% (the
solid blue curve) reaches 90% area utilization the fastest at around 40 gateways
while its weighted scoring (the dotted blue curve) remains the highest. In contrast,
overlap of 100% (the solid green curve) implies the system takes no consideration
about the negative e ects of the overlapping coverage area. It reaches 90% area↵
utilization at around 80 gateways and incurs the fastest decline of the weighted
scoring (the dotted green curve). The unweighted scoring of overlap of 50% (the
solid orange curve) reaches 90% area utilization by having only around 10
gateways more (at around 50 gateways) with the longest tail (the dotted orange
curve). The longest tail implies that the scenario can a ord the most number of↵
gateways within the region while having the slowest decline of the weighted
scoring (in other words, the total profit of the whole system). This encourages an
energetic ecosystem where more users are willing to participate.
Fig. 6.3(b) reveals the same concept from another perspective. The scenario
with 40 gateways exhibits the peaks on both the unweighted scoring (the solid blue
curve) and weighted scoring (the dotted blue curve) at overlap of 20%. As the
percentage of overlapping coverage area increases to around overlap of 50%, the
peaks gradually shift to the point with overlap of 50% wherein there is an
increasing number of participating gateways (from the orange curve to the green
curve).

Along with the findings in Fig. 6.3, we can conclude that, introducing our new
flow control and incentive mechanism can satisfy a Dual-Chain-based LoRa
network requesting high throughput and flexibility. A smaller upper-bound of the
overlapping coverage area which needs to comply with the flow control (a more
strict flow control) can result in a fast convergence to high area utilization while
the total profit of the whole system remains high. On the other hand, if the goal is to
encourage more gateways to participate, an upper-bound of the overlapping
coverage area approaching 50% can balance the area utilization and the system
profit very well.
6.3.1 Security Analysis
The security analysis focuses on the dual-chain-based structure and the
proposed new PoTO protocol.
6.3.1.1 Dual-Chain Structure: Why Splitting Functions?
We split the functions between the Data DAG and ID Chain, respectively. The
Data DAG is only responsible for the data storage, while the ID Chain is responsible
for contract operations and payment functions. The proposed dual-chain strategy is
di erent from those IOTA-like DAG-based structures where the payment functions↵
is inherently supported. The strategy is particularly important in the context of
LoRa. The reason is that a malicious controller may collude with all its gateways by
sharing gateways’ private keys, or simply generate a set of private keys and pretend
to manage some gateways. As such, the controller can bypass the preconcerted
incentive rule of the contract theory, and maximize its average block rate in the
Data DAG, compared to other honest controllers which only initiate the
transmission after collecting some data. As a result, the attacker can broadcast
blocks which contain double-spending payment at the highest rate to induce the

growth of Data DAG in its favour, thus breach the transaction order finality and
compromise the balance system. It is thus significant to introduce a dual-chain
structure that splits the payment function (whose physical meaning matters) out
from the Data DAG and let the ID Chain handle the payment.
6.3.1.2 Dual-Chain Structure: The Performance Gap
The performance gap between a scalable DAG-based structure and an
nonscalable chain-based structure may lead to network bottlenecks, data
inconsistency, and corruption. Our proposed system enable the consistency
between the Data DAG and ID Chain, even with an increasing number of end-
devices and gateways. This can be achieved due to:
•The scarcity of smart contract operations on the ID Chain: Any smart
contract operations on an ID Chain related to the devices
registration/monitoring and contract initialization/status records are
conducted much less frequently than publishing a single contract-theoretic
task on an Data DAG. This is because these operations mostly send small data
to update the status on smart contracts, and closely depend on the type-
classification which can be conducted once and serve multiple tasks.
Likewise, the randomness generated on the ID Chain can also be reused
conservatively for multiple tasks during the self-driven flow control process.
•The limited amounts of data transmitted on the Data DAG: The
block rate of Data DAG in LoRa networks is restrained by the task period, the
data size of a task, and the number of gateways involved in a task.
– Limited task period: The period of any smart contract operations
related to incentive payment and balance records correspond to the unit
period of a published task, as the functionality is in the charge of the ID

Chain. Such period is restrained by an upper-bounded frequency of
publishing new blocks to the Data DAG based on the anti-spam features,
i.e., PoTO protocol.
– Limited data size: The data size uploaded by a gateway during a task is
restrained by the physical channel resource according to Equations (6.1)
and (6.2), including spreading factor, bandwidth, code rate, duty cycle,
etc.
– Limited number of gateways: It is found in Figure 4 that the number of
self-deployed gateways in a region tends to fall into a certain range and
maximize the utility of the LoRa network, considering that the
(un)weighted scoring takes e ect for the penalty of the uploaded data↵
size.
•The advanced technologies implemented to improve the ID Chain: The
performance gap can be eliminated by implementing advanced technologies
to improve the performance of the ID Chain, such as the HotStu consensus↵
algorithm that enables high transaction rate among large communities, and
the sharding technology that enables the horizontal scalability. Moreover,
requesting a higher security level on the Data DAG needs each node to
download as deep Data DAG as possible for more secure validation. This
makes the Data DAG no better than the improved ID Chain, and stops the Data
DAG from being scaled out. One feasible solution is to implement the sharding
technology (as suggested in Chapter 4) to both the Data DAG and ID Chain.
6.3.1.3 PoTO Protocol: The Improved Spam Protection
The proposed system inherently enables the spam protection which, otherwise,
would have to be achieved by a typical PoW process in IOTA. The PoW used in

IOTA is not a typical PoX-based consensus algorithm (as suggested in Chapter 3). It
is a comparably simple computational operation which di ers from the expensive↵
PoW conducted in many miner-based Blockchains. Instead of racing for the winner
of each consensus round, the defense to DDoS attacks and spam protection are the
key goals of the PoW in IOTA. Our proposed PoTO protocol can deliver the same
protection without need of additional computational operations required by the
PoW used in IOTA, as clarified below from the perspectives of system restriction
and attack motivation.
From the perspective of system restriction,
•Limited data source: Each LoRa Gateway needs to be registered on the ID
Chain and generate the unique private key for digital signature, prior to
granting permission to participate in the LoRa networks. The controllers can
mutually verify each of the identities of transactions in a DAG block to ensure
the transactions are indeed sourced from a certain and finite gateway set.
•Limited data size and number of gateways: The data size uploaded by a
gateway during a task is restrained by the physical channel resource
according to Equations (6.1) and (6.2). Also, the number of self-deployed
gateways in a region falls into a certain range to maximize the entire utility.
In our system, the controllers incentivize the self-deployment of gateways. The
controllers and gateways maximize the utilities, i.e., Equations (6.5) and (6.7). A
controller would not be able to spam the network unless it colludes with all its
gateways. In the worst-case scenario where the collusion happens, the system
restriction can extend a period of time before a task is finalized, thus significantly
reducing the risk of DDoS attacks with a compulsory minimum size of payloads.

This leads to a controllable growth rate of the DAG , since the block rate depends
on the data source, data size, and the number of gateways.
From the perspective of attack motivation, as suggested in Section 6.2, the
function of incentive payment is conducted on the ID Chain in our proposed dual-
chain system. This leads to independence among controllers, and the controllers
are only responsible for the validity of on-chain LoRa data stored on the Data DAG,
and not for the validity of the metadata. Each individual controller aims to enhance
the quality of local LoRa business. Spending time and consuming communication
(downloading/uploading) and computation (verifying/smart contract operations)
resources to upload local corrupted LoRa data do not a ect the interests of others↵
and reap no profits for itself. Therefore, for LoRa Controllers, the communication
and computation overhead is enough to be the amount of “work” done during the
data collection and validation process, i.e., PoTO, without need of additional
computation operations.
6.4 Conclusions
Remark that the increasing number of studies which presented simple and
stilted integration between Blockchain and IoT technologies without dedicated
optimization has hindered the adoption of Blockchain-based IoT applications. As a
solid study to demonstrate how the optimizations can be designed, in this chapter,
we proposed a new Dual-Chain-based LoRa system where the state-of-the-art
contracttheoretic incentive mechanism for self-driven deployment, and data
storing service can be secured by a decentralized global cross-validation with the
tamper-resistance of Blockchain. The contract-theoretic incentive mechanism
consists of a new selfdriven flow control protocol that mitigates the tra c
congestion and throughput loss of the Blockchain due to uploading the duplicated

data, scaling the Dual-Chain system to achieve high throughput. As a result, each
gateway is motivated to be deployed in its appropriate place to maximize the entire
system throughput while reducing the data replication without the need to modify
existing LoRaWAN pro-
tocols.
Chapter 7
Contributions and Future Work
This chapter summarizes the research in this thesis ahead of the contributions of
each chapter. Finally, we point out the future work that potentially improves and
extends our current work.
7.1 Contributions
In regard to the four highlighted aspects, this thesis has presented the
corresponding novel achievements ranged from new analytic models to new
system architecture designs. A new unified analytical model for PoX consensus
scheme in large-scale networks was proposed in Chapter 3, while a comprehensive
comparison and evaluation among existing major sharding mechanisms was
presented in Chapter 4. This thesis also introduced new system architecture
designs for Blockchainbased fine-grained access control and Blockchain-based
LoRa networks in Chapters 5 and 6, respectively. To be specific, the novelty and
contributions of the thesis is summarized as follows.
A new unified analytical model was proposed to fill in some piece of gaps in the
literature of PoX consensus scheme used in large-scale IoT networks. The new
unified analytical model was able to quantify the profit of individual miners in any
of the popular permissionless PoX-based Blockchains. The new model captured

proposed changes in the system resource distribution of PoX schemes by designing
an infinite-dimensional Markov chain. A set of expressions was established to e
ciently evaluate the mining probability of a miner, given the amount of system
resource owned by the miner. The type and distribution of system resources could
be customized in line with system requirements. As revealed by our analysis, in
PoXbased consensus algorithms where the monopoly of block generation is
prevented and diversity is maintained, miners can maximize the profits with strong
doublespending-resistance and controllable cost-risk assessment, thereby
contributing to a healthy and sustainable mining ecosystem.
The sharding technology has proven its importance solving the scalibility issue
of Blockchains. A comprehensive comparison and evaluation was presented to
summarize the pros and cons of existing major sharding mechanisms, as well as the
possible future improvements. To be specific, Nakamoto-based sharding
mechanism (Monoxide) stands on the stage, for the first time pointing out a
di erent direction compared with the BFT-based sharding mechanisms.↵
OmniLedger, Rapidchain, and Ethereum 2.0 attempted to implement scalable or
high-FT BFT-based consensus algorithms rather than the traditional PBFT for the
intra-consensus safety. Also, a smartcontract-oriented sharding mechanism was
proposed by Chainspace, for the first time supporting the complicated conditional
transactions. All considered sharding mechanisms also introduced the
optimizations to address the new challenges their proposed schemes pose to the
system, e.g., latency, storage, fair randomness generator, and replay-attack defense,
but further improvements are necessary. Finally, we pointed out the common
pitfalls in existing sharding mechanisms, including the use of a global chain, the
needs for validators to store unrelated records, and businessoriented members
allocation. We also pointed out the future trend, including the scaling of
randomness generator, extending Nakamoto-based sharding to general PoX

schemes, balancing the uses of stochastic and biased members allocation, and
enabling more e ective scheme for smart contracts.↵
A novel multi-layer Blockchain-IoT data service system was proposed to enable
secure attribute updates in an ABE-based fine-grained access control mechanism
for Blockchains. We developed a redactable key chain along with a standard data
chain to secure and control the access to the data chain. Empowered by redactable
hash functions, the redactable key chain allowed the access policies of ABE to be
updated by key chain miners. The data chain could be any existing Blockchain with
any scalable structure and preserves the immutability of the IoT data. Collectively,
these crytographic primitives addressed the inherent incompatibility between the
immutability of Blockchains and the indispensable need of updating attributes to
manage the access to Blockchains. The system was compatible with the major
types of cryptographic primitives, consensus algorithms, and cross-chain protocols
in Blockchains. The analysis and simulation results showed that our proposed
mechanism is able to outperform existing solutions in terms of overhead, searching
complexity, and security.
A novel Dual-Chain-based LoRa system was proposed as a case study of
optimizing Blockchain-based IoT system architecture. The system took advantage
of the DAG structure along with a typical chain-based structure that provides
identity registration and protocol monitoring in smart contracts. By interacting
with both the DAG and identity chain and leveraging decentralized global cross-
validation, the processing of any incentive mechanisms (including the proposed
contract-theoretic incentive mechanism) can be secured. The contract-theoretic
incentive mechanism featured a new self-driven flow control protocol that scales
the LoRa network by relieving tra c congestion, and improves the throughput of the
Blockchain, scaling the Dual-Chain system. As a result, the system enables: 1)

strong compatibility with typical LoRaWAN protocols; 2) the PoTO, a new spam
protection dedicated for LoRa networks that wastes fewer resource; 3) e cient and
flexible data storage services at any time with high throughput; and 4) the
transparency and fairness of incentive mechanism and data storage services
because of the tamper-resistance property of the decentralized cross-validation
protocol. As revealed by our analysis and simulation results, the proposed Dual-
Chain-based LoRa system can significantly improve the throughput of the
Blockchain, while maintaining a high area
utilization.
7.2 Future Work
With a series of proposed models, surveys, and designs, this thesis has analyzed
key stages of Blockchain-based IoT systems and deduces significant results.
However, extensions and improvements are seen as the future work to cover more
aspects in
this field.
The unified PoX schemes analytical model cannot capture the non-negligible
delay. In the future, we will optimize the margin of error of the model and study the
short-term impact of the accumulated resource of each miner upon the entire
system. Moreover, we will involve more existing PoX schemes in the analysis and
investigate new PoX schemes based on the benchmark to meet diversified contexts.
The sharding technology has been well developed for the past years and still
being rapidly evolved. Our proposed survey needs to consider more perspectives,
such as the sharding-related replay attacks and defenses, the pros and cons of
using businessdriven member allocation, etc. We will also investigate new sharding
mechanisms based on the trends/suggestions to meet diversified contexts.

Current proposed ABE-based fine-grained access control mechanism for
Blockchains still relies on a centralized TA. One potential solution is to decentralize
the TAs in the system such as investigating new decentralized key generation and
distribution dedicated for Blockchain contexts.
Several studies regarding the decentralized TA have been proposed to avoid the
reliance on a centralized TA in conventional ABE-based fine-grained access control
mechanisms [108, 78, 79, 44]. All of them follow similar concepts that multiple
authorities can independently issue keys to users without needs of knowing other
authorities and cooperate with others, while users can encrypt data in terms of any
boolean formula over attributes issued from any chosen set of authorities.
However, none of them are able to tackle the issue of exposing the secret
information of a TA. If one assigned with only one attribute that comes from a
single TA, the TA exposing the secret information risks the user being attacked,
which would not be capable of Blockchain contexts. One potential Blockchian-
driven solution is to decentralize any TAs by using secure Multi-Party Computation
(sMPC) to split a TA’s secret information among multiple parties, and conduct
functions without exposing the actual information [88], which desires for more
future studies and investigation.
For optimizing Blockchain-based IoT architecture, our Blockchain-based LoRa
system can be applied to a concrete application and evaluate its performance in the
future. Our system can also be extended to more generalized LPWAN networks. In
addition, the overhead would have to increase to O(n) (a network sized of n nodes)
as the Data DAG grows. Possible optimization of computation, communication, and
storage complexity by using sharding technologies discussed in Chapter 4 can be
integrated to the system. However, any potential implications of the cross-shard
transactions in a DAG-driven sharding mechanisms are still desperate for further

studies.

